The KV Cache Tax: Why Inference Servers Run Out of Reminiscence Earlier than Compute
The Mannequin Matches, the Requests Do notVRAM was once a training-time fear. You sized your cluster for the weights, the ...
The Mannequin Matches, the Requests Do notVRAM was once a training-time fear. You sized your cluster for the weights, the ...

An Adaptive Mannequin Router in entrance of your LLM pipeline can lower inference prices by as much as 90%, with ...
There are various methods to get extra from the fashions and GPU infrastructure you have already got. Quantization, optimized kernels, ...

If in case you have carried out a transformer mannequin in PyTorch, you should utilize the identical code for each ...

On this article, you'll learn the way static, dynamic, and steady batching work in LLM inference, and why the variations ...
Whenever you optimize the inference efficiency of an LLM, that you must know find out how to measure it. With ...
The issue that made me search for an alternate . My work entails taking fashions of the Universe – darkish ...
I bear in mind watching the Hollywood thriller thriller Knives Out, leaning in the direction of the display screen, as ...
I’ve seen loads once I’m working with enterprise AI groups: they almost at all times blame the mannequin when one ...
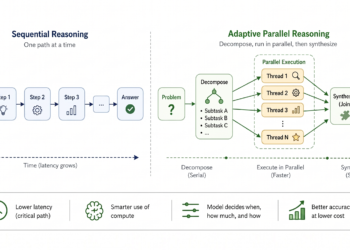
Overview of adaptive parallel reasoning. What if a reasoning mannequin might determine for itself when to decompose and parallelize unbiased ...