The Mannequin Matches, the Requests Do not
VRAM was once a training-time fear. You sized your cluster for the weights, the optimizer states, and the gradients, and as soon as the mannequin was educated, the reminiscence math felt settled. Serving regarded low-cost by comparability: load the weights, run ahead passes, executed.
Then you definately put the mannequin behind actual visitors, and it fell over at a load that made no sense.
I used to be sizing an inference deployment for a mid-sized mannequin on a shared GPU pool. The weights match with room to spare, and the server ran tremendous in testing. Below concurrent visitors, it returned CUDA out-of-memory errors whereas GPU compute utilization sat far under saturation.
The primary intuition was that the mannequin was too huge. It wasn’t. The important thing-value cache was consuming the headroom, and it grew with each concurrent request. I turned on paged allocation and prefix caching earlier than including a single GPU, and the ceiling lifted. Shopping for {hardware} would have papered over a memory-layout downside.
That’s the tax most serving guides underprice. A vLLM evaluation discovered that naive KV cache administration wastes 60 to 80 p.c of the reminiscence it reserves. The cache isn’t a hard and fast price you pay as soon as. It scales with what number of requests you serve on the identical time, which suggests the factor that pushes you over the reminiscence cliff is a visitors spike, not an extended immediate.
The VRAM Funds Equation: Why Reminiscence Scales With Concurrency
Three issues share GPU reminiscence throughout serving: the mannequin weights, transient activations, and the KV cache. The weights are mounted. The KV cache is the variable that strikes.
The per-token dimension comes from 4 components multiplied collectively:
-
Two bytes every for the important thing and the worth saved per token.
-
Layers: each transformer layer retains its personal key/worth pair.
-
Key/worth heads occasions head dimension: the width of every cached vector.
-
Bytes per component: the precision you retailer the cache in.
Grouped-query consideration shrinks the important thing/worth head rely, the time period that issues most. That is why trendy architectures lean on it, and NVIDIA’s inference information walks by the identical arithmetic.
Put Llama 3.1 70B by it at BF16. With 80 layers, 8 key/worth heads, and a head dimension of 128, every token prices roughly 320 KB of cache (2 x 80 x 8 x 128 x 2 bytes). With out grouped-query consideration, at 64 heads, that determine could be eight occasions bigger.
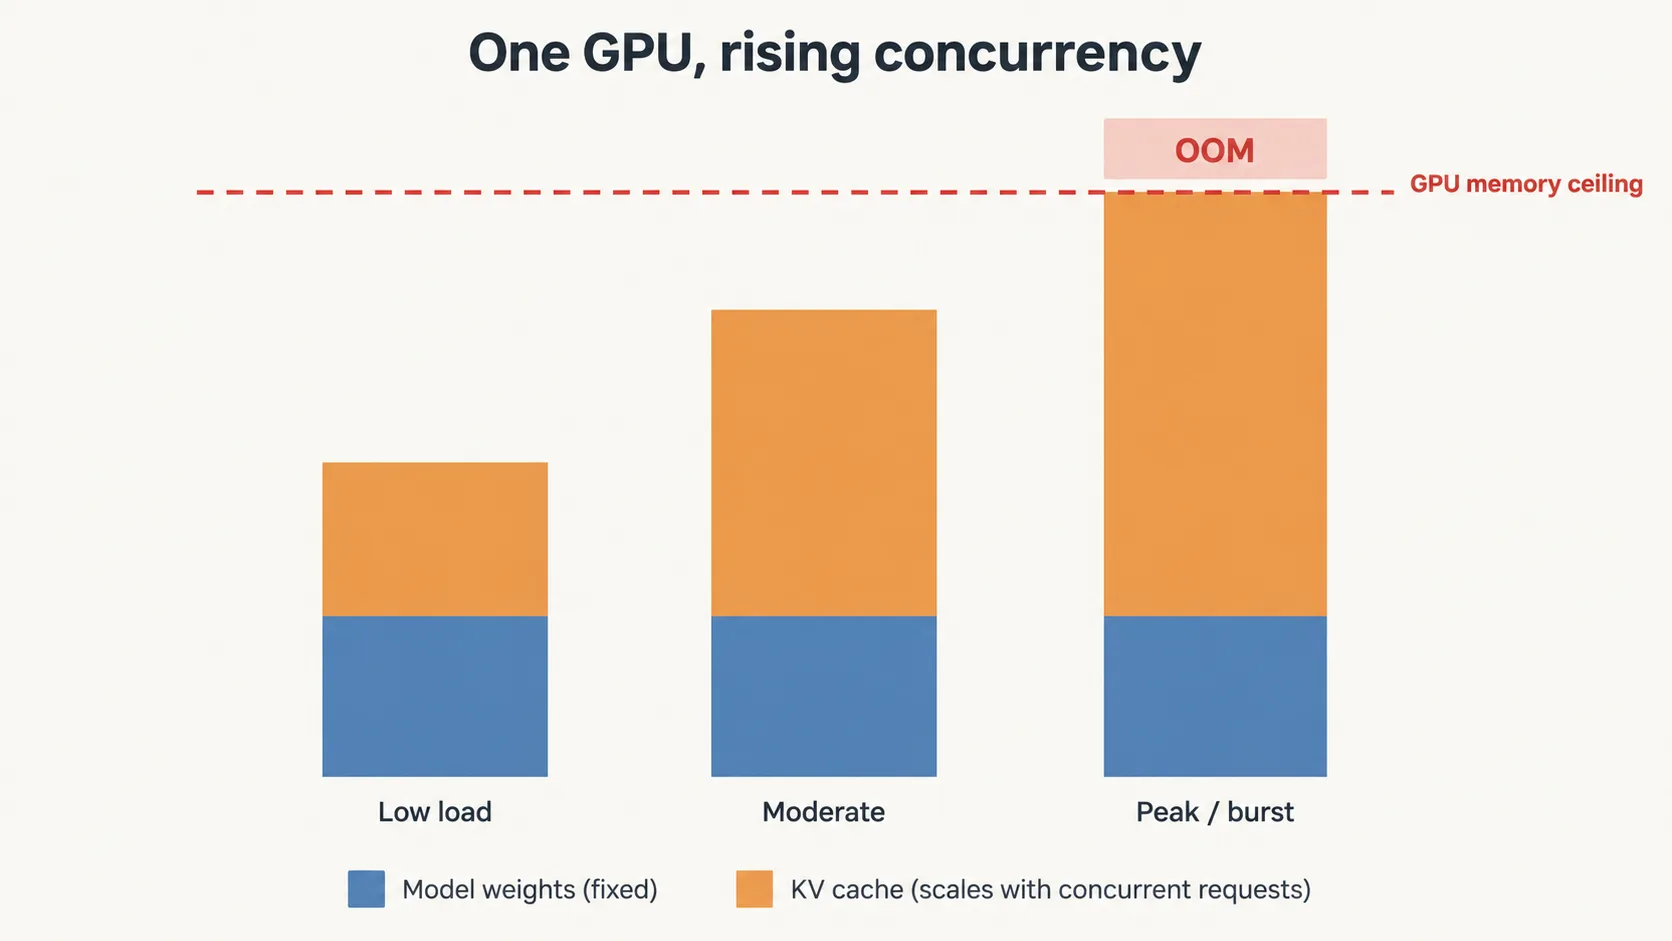
Now multiply by visitors. At 128 concurrent requests holding 4K tokens of context every, the KV cache alone wants about 160 GB. The 70B weights want 140 GB at BF16. The cache has outgrown the mannequin. You’ll be able to serve that mannequin on a single 80 GB card till the second concurrency climbs, after which no quantity of spare compute helps, as a result of the ceiling you hit is reminiscence.
Right here is the reframe. Your KV finances is a operate of concurrent requests, not immediate size in isolation. vLLM sizes its cache as max concurrent sequences occasions max sequence size, so elevating both one multiplies the reservation. Practitioners hit this as a cryptic startup error earlier than a single request lands, as a result of the server pre-allocates the entire cache up entrance.
The chart under exhibits the identical GPU below rising concurrency: weights keep mounted whereas the cache climbs into the reminiscence ceiling and triggers the OOM on the spike.
Naive Allocation: The 60 to 80 P.c You By no means Use
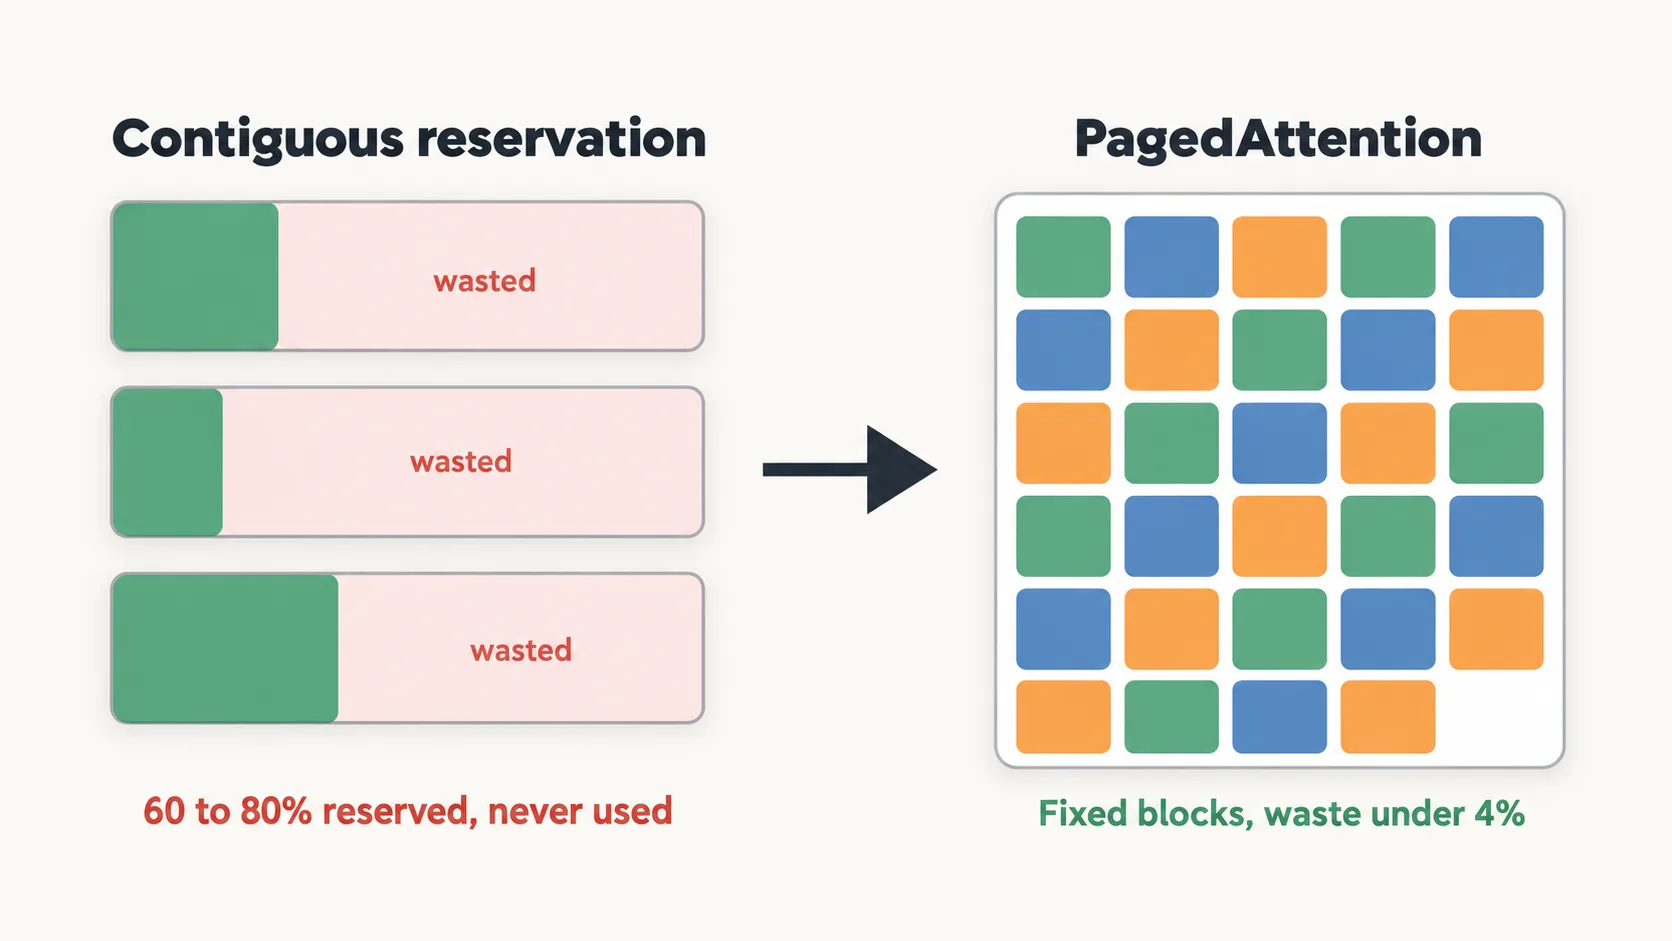
Early serving stacks reserved KV reminiscence in a single contiguous block per request, sized for the utmost attainable sequence size. A request that generated 200 tokens towards a 4,096-token reservation left the remaining parked and unusable.
The vLLM weblog measured the harm: 60 to 80 p.c of allotted KV reminiscence wasted to fragmentation and over-reservation. That waste is the explanation you run out of reminiscence at low utilization. The GPU has the capability; the allocator has fenced it off.
Consider operating-system digital reminiscence. Applications tackle reminiscence as if it had been one steady area, whereas the OS maps these addresses to scattered bodily pages behind the scenes. Nothing wants a large contiguous block, so nothing will get stranded. The repair for the KV cache borrows precisely this concept.
PagedAttention: Digital Reminiscence for the KV Cache
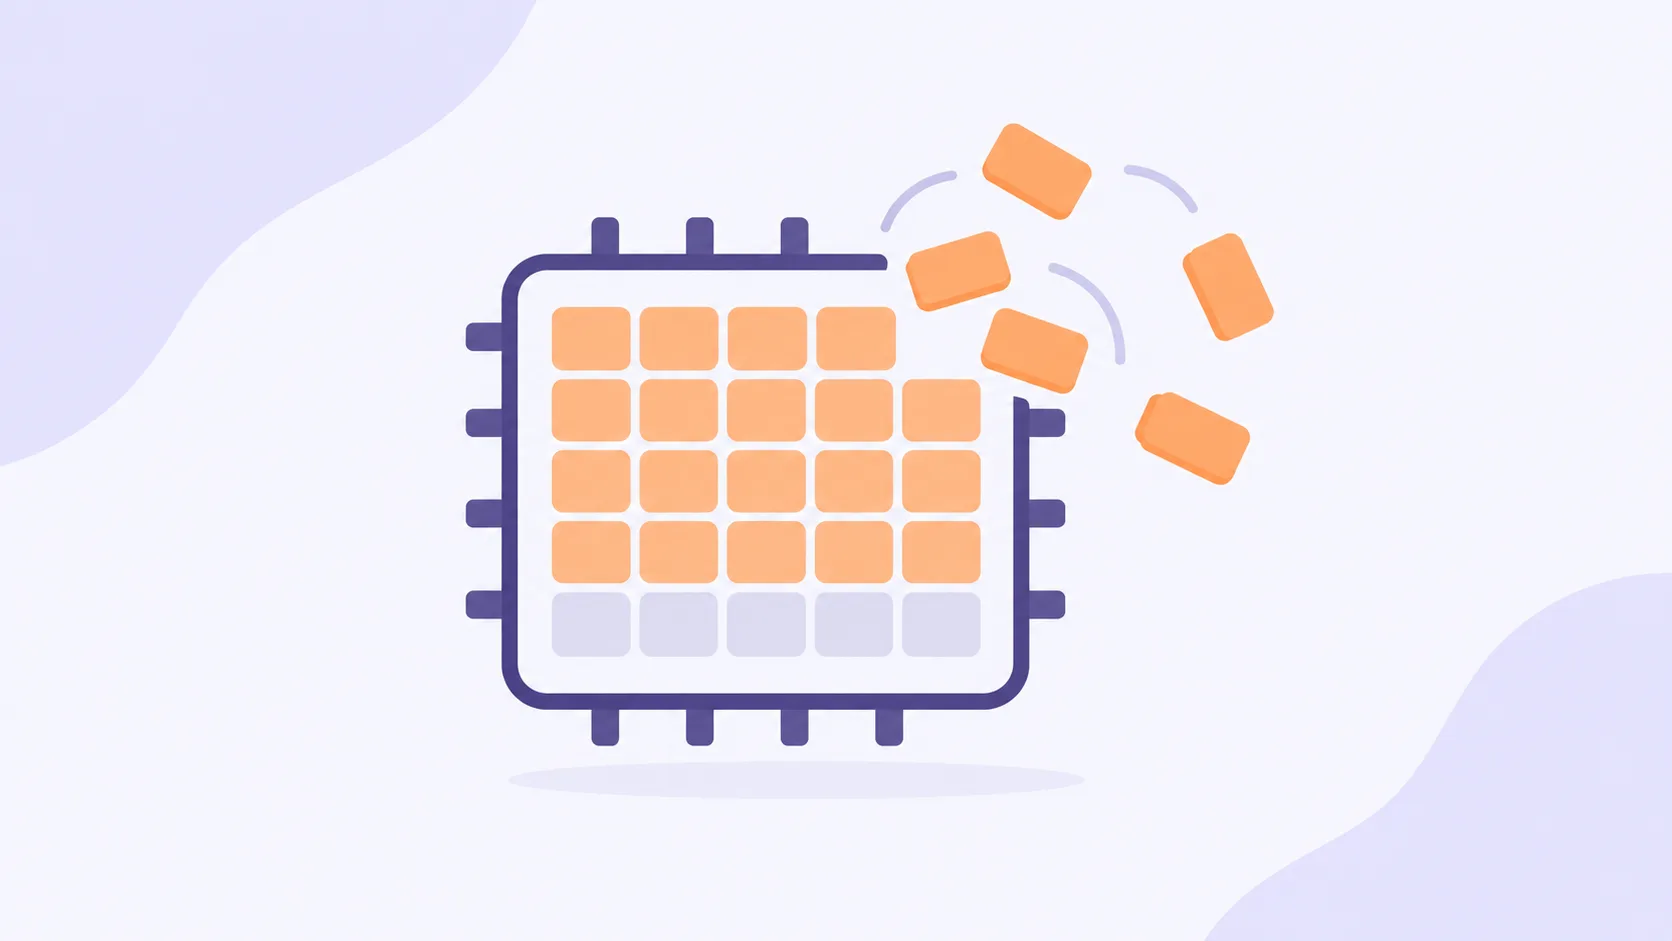
PagedAttention shops the KV cache in fixed-size blocks that needn’t be contiguous, the identical method an OS pages reminiscence. Every request attracts blocks because it generates tokens and returns them when it finishes, so reservations monitor precise utilization as a substitute of the worst case.
The payoff is direct. The vLLM crew reviews waste dropping to below 4 p.c, and throughput rising as much as 24 occasions over a naive Hugging Face pipeline as a result of the reclaimed reminiscence lets extra requests batch collectively. Extra resident requests per GPU means larger throughput from the identical {hardware}.
The price is bookkeeping. Non-contiguous blocks imply the eye kernel has to assemble scattered reminiscence, and the block desk provides a layer of indirection. In observe that overhead is small towards the reminiscence you win again. For any manufacturing serving stack in 2026, that is the baseline each deployment ought to begin from.
Prefix Caching: Amortizing the Shared Immediate
Many workloads ship the identical tokens again and again. A shared system immediate, a few-shot preamble, an extended doc that each query in a session refers again to. Recomputing that prefix for every request burns compute and re-stores an identical KV entries.
Prefix caching retains the KV for a shared prefix as soon as and reuses it throughout each request that begins with the identical tokens. SGLang’s RadixAttention organizes cached prefixes in a radix tree so overlapping prompts share state mechanically. The SGLang crew reviews as much as 5 occasions larger throughput on workloads with heavy prefix reuse.
The profit is conditional, and that is the place groups misjudge it. Reuse solely helps when requests truly share prefixes. On visitors with out shared prefix construction the hit price stays low, and the cache spends effort on lookups that largely miss.
Earlier than enabling it, monitor your cache hit price; it is the quantity that tells you whether or not the characteristic earns its preserve. A chat product with a hard and fast system immediate will see excessive reuse. A service fielding distinctive one-off prompts will not, and there the cache is overhead.
KV Quantization: Buying and selling Precision for Capability
If paging and prefix caching nonetheless go away you memory-constrained, retailer the cache in fewer bits. FP8 KV cache halves the per-token price and roughly doubles the tokens you may maintain.
Going additional, the KIVI work quantizes to 2 bits for about 2.6 occasions much less peak reminiscence, enabling roughly 4 occasions bigger batches and a 2.3 to three.5 occasions throughput acquire.
The price is high quality, and it is not uniform. For a lot of duties the drop is small. On long-context retrieval it could possibly fall off a cliff. vLLM documented a needle-in-a-haystack rating collapsing from 91 p.c at BF16 to 13 p.c below naive FP8, then recovering to 89 p.c as soon as they amassed in larger precision.
The lesson: KV quantization is secure solely whenever you validate it by yourself long-context workload earlier than you belief any mixture benchmark.
It is like saving photographs at a decrease decision. Every one takes much less area, most look tremendous, and those with tremendous element are the place you discover the loss. Lengthy-context retrieval is that tremendous element.
There’s a additional wrinkle value realizing. High quality affect is architecture-specific: smaller reasoning fashions are inclined to degrade greater than bigger ones, and a few consideration variants break on uncalibrated scales. Deal with the capability acquire as actual and the standard as one thing you need to measure.
The Choice Matrix: Mapping Site visitors to Technique
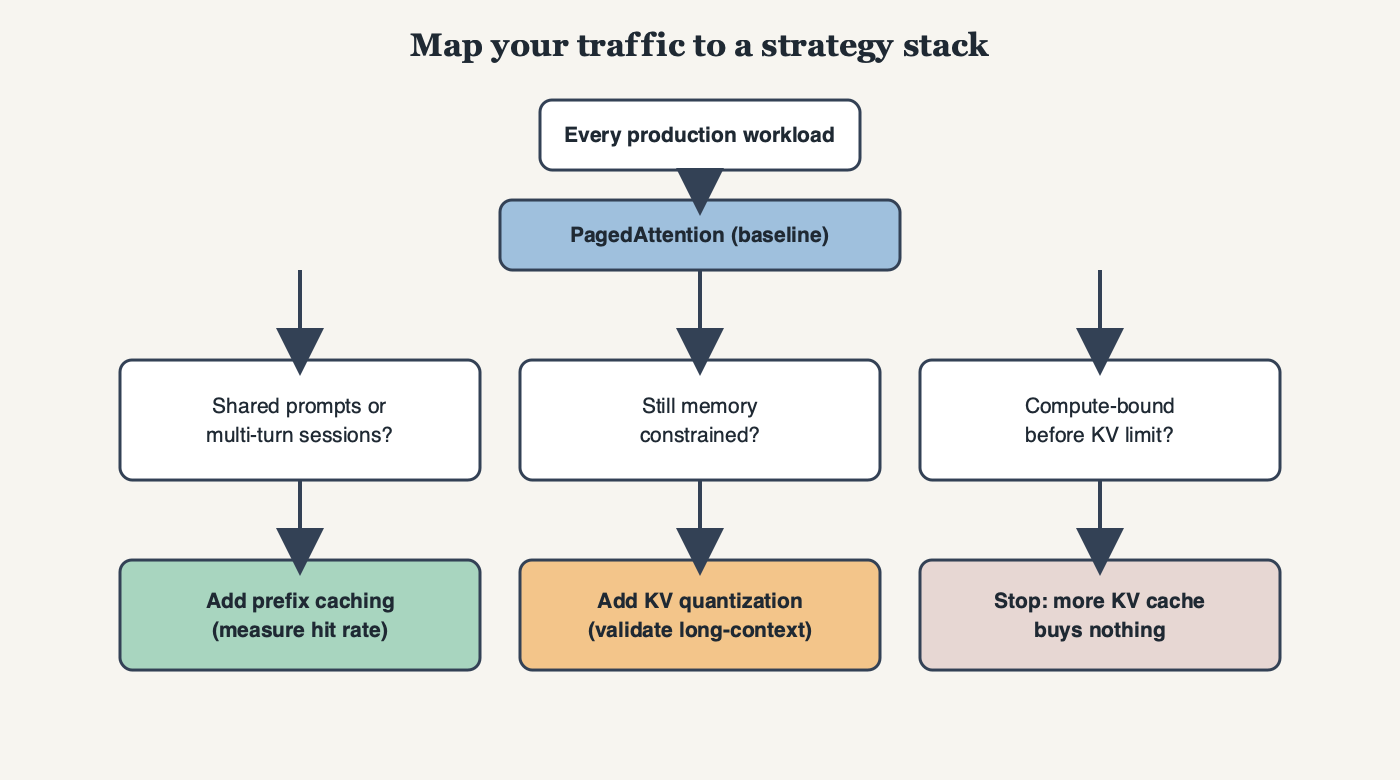
Don’t decide methods from a diagram. Profile your visitors first: peak concurrency, immediate construction, context size, and the way a lot your prompts truly overlap. The precise stack follows from the visitors form. The movement under maps the widespread branches.
|
Technique |
Finest Site visitors Sample |
Capability Impact |
Fundamental Value |
|
PagedAttention |
Any manufacturing workload |
Waste below 4% vs 60-80% |
Kernel and block-table overhead |
|
Prefix caching |
Shared system prompts, multi-turn classes |
Skips recompute on cache hits |
Wasted lookups when hit price is low |
|
KV quantization |
Capability-constrained, tolerant of high quality threat |
2x (FP8) to 4x (INT4) extra tokens |
High quality drop on long-context retrieval |
Layer the methods on this order:
-
Begin right here: PagedAttention on each deployment, no exceptions.
-
Add when prompts overlap: prefix caching, after you have confirmed an actual hit price.
-
Add when nonetheless memory-bound: KV quantization, after you have validated long-context high quality.
One caveat earlier than you optimize. The “reminiscence earlier than compute” thesis isn’t common. Some workloads grow to be compute-bound earlier than they exhaust KV reminiscence, and previous a workload-specific level, including cache capability buys nothing. Measure which wall you hit first. In case your p95 latency is climbing whereas reminiscence sits idle, extra KV headroom is the fallacious repair.
Conclusion
Activate PagedAttention and prefix caching on day one. Paging is desk stakes, and prefix caching is near free when your visitors has shared construction. Collectively they resolve the reminiscence strain most serving workloads even have.
Attain for KV quantization solely whenever you’re nonetheless capacity-constrained after these two, and solely after you validate high quality by yourself long-context visitors. Measurement your deployment round peak concurrency, not common load, as a result of the OOM arrives on the spike. The mannequin becoming in reminiscence was by no means the query that mattered.
Additional Studying
-
Environment friendly Reminiscence Administration for LLM Serving with PagedAttention (SOSP 2023, the founding vLLM paper on KV cache paging)
-
Mastering LLM Methods: Inference Optimization (NVIDIA’s reference on KV math, GQA, and MQA)
-
SGLang and RadixAttention (prefix reuse through a radix tree)
-
KIVI: Plug-and-play 2bit KV Cache Quantization (low-bit KV quantization and its throughput positive factors)
-
FP8 KV Cache Accuracy (vLLM’s long-context regression and the repair)
-
KV Cache Calculations (per-token labored examples throughout mannequin households)
···
Thanks for studying. I am Mostafa Ibrahim, founding father of Codecontent, a developer-first technical content material company. I write about agentic programs, RAG, and manufacturing AI. If you would like to remain in contact or talk about the concepts on this article, you will discover me on LinkedIn right here.