

There are various methods to get extra from the fashions and GPU infrastructure you have already got. Quantization, optimized kernels, and higher inference engines can all assist, however speculative decoding is particularly helpful as a result of it could possibly improve technology velocity with out merely including extra GPUs.
There are actually a number of approaches to speculative decoding. Conventional strategies use a smaller draft mannequin, whereas Multi-Token Prediction (MTP) predicts a number of future tokens directly. Strategies resembling Medusa and EAGLE enhance how these drafts are produced, whereas DFlash generates blocks of candidate tokens in parallel.
DSpark takes one other method by combining parallel drafting with a light-weight sequential element. This helps later draft tokens use info from earlier predictions whereas preserving a lot of the velocity benefit of parallel technology.
On this information, we’ll take a look at DSpark with Qwen3-8B and llama.cpp. We are going to benchmark the mannequin usually, allow DSpark with an identical draft mannequin, and evaluate the technology speeds to see how a lot efficiency we are able to acquire from the identical GPU.
How DSpark Works
DeepSeek’s DSpark improves the drafting a part of speculative decoding.
Parallel draft fashions can predict a complete block of tokens in a single cross, which is quick, however later predictions can change into much less correct as a result of they don’t totally rely on the tokens predicted earlier within the block. DSpark combines a parallel spine with a light-weight sequential element, permitting later draft positions to include info from earlier predicted tokens whereas retaining a lot of the velocity of parallel technology.
In simplified phrases:

DSpark may also estimate how doubtless draft tokens are to outlive verification, permitting low-confidence components of a block to be dropped as a substitute of losing verification compute. llama.cpp exposes this by means of its DSpark implementation and elective confidence threshold.
DeepSeek experiences that DSpark improved per-user technology velocity by 60–85% in contrast with its earlier MTP-1 manufacturing baseline when deployed with DeepSeek-V4. These numbers shouldn’t be handled as anticipated outcomes for our small native mannequin, so we’re going to measure the distinction ourselves.
1. Constructing llama.cpp and Downloading the Fashions
We are going to construct the most recent llama.cpp from supply so we are able to use its present DSpark implementation with CUDA acceleration.
Set up the required instruments:
apt-get replace
apt-get set up -y git cmake build-essential
Clone the official llama.cpp repository:
cd /workspace
git clone https://github.com/ggml-org/llama.cpp
Construct it with CUDA assist enabled:
cmake llama.cpp -B llama.cpp/construct
  -DBUILD_SHARED_LIBS=OFF
  -DGGML_CUDA=ON

cmake --build llama.cpp/construct
  --config Launch
  -j
  --clean-first
  --target llama-cli llama-mtmd-cli llama-server llama-gguf-split
This creates the binaries we want whereas permitting the fashions to run on the GPU.
Subsequent, create a listing for the mannequin information:
mkdir -p /workspace/fashionsWe are going to obtain the GGUF information manually utilizing the Hugging Face CLI so the obtain time doesn’t have an effect on our benchmarks.
Set up the CLI:
pip set up -U huggingface_hubIn case your Hugging Face token is saved in HF_TOKEN, authenticate with:
hf auth login --token "$HF_TOKEN"Obtain the Qwen3-8B Q4_K_M goal mannequin:
hf obtain
  Qwen/Qwen3-8B-GGUF
  Qwen3-8B-Q4_K_M.gguf
  --local-dir /workspace/fashions
Then obtain the matching DSpark Q8_0 draft mannequin:
hf obtain
  ggml-org/Qwen3-8B-GGUF
  dspark-Qwen3-8B-Q8_0.gguf
  --local-dir /workspace/fashions
The primary file is the primary mannequin that generates the ultimate output. The smaller DSpark mannequin will generate speculative draft tokens for the goal mannequin to confirm.
Affirm that each information can be found:
ls -lh /workspace/fashionsYou must see one thing just like:
4.7G  Qwen3-8B-Q4_K_M.gguf
1.2G  dspark-Qwen3-8B-Q8_0.gguf
With llama.cpp constructed and each fashions downloaded, we are able to first measure the conventional Qwen3-8B technology velocity earlier than enabling speculative decoding.
2. Measuring the Baseline Pace
Earlier than enabling DSpark, we want a baseline. We are going to run Qwen3-8B usually and file its technology velocity so we are able to evaluate it in opposition to the speculative-decoding run.
Transfer into the llama.cpp listing:
cd /workspace/llama.cppRun Qwen3-8B with out speculative decoding:
./construct/bin/llama-cli
  -m /workspace/fashions/Qwen3-8B-Q4_K_M.gguf
  -ngl all
  -fa on
  --temp 0
  --top-k 1
  -n 512
  -st
  -p "Write an entire Python implementation of merge kind. Clarify the way it works and embrace its time and area complexity. /no_think"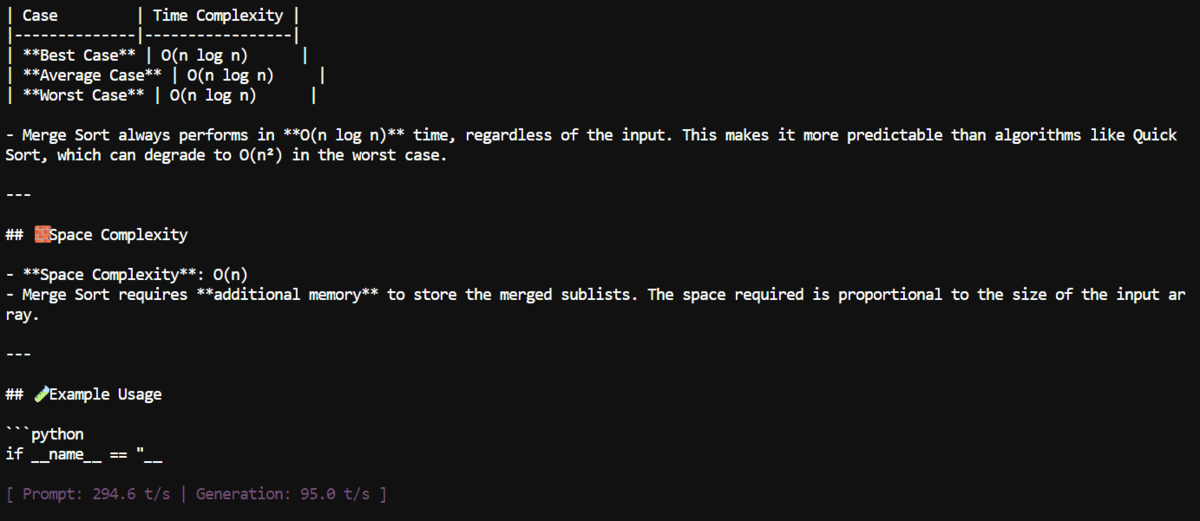
Right here, -ngl all offloads all mannequin layers to the GPU, whereas -fa on permits Flash Consideration.
We additionally use deterministic decoding:
--temp 0 --top-k 1That is necessary as a result of we’ll use the similar immediate, token restrict, and decoding settings when testing DSpark, giving us a cleaner apples-to-apples comparability.
When technology finishes, search for the benchmark abstract printed by llama.cpp:
[ Prompt: 294.6 t/s | Generation: 95.0 t/s ]For this information, the necessary quantity is Era: 95.0 tokens/s. We are going to use this as our baseline when measuring the DSpark speedup.
3. Operating the Similar Take a look at With DSpark
Now we’ll repeat the benchmark with DSpark enabled. The objective is to maintain the goal mannequin, immediate, token restrict, and decoding settings the identical so we are able to immediately measure the impact of speculative decoding.
Run the identical Qwen3-8B mannequin, this time with the DSpark draft mannequin connected:
./construct/bin/llama-cli
  -m /workspace/fashions/Qwen3-8B-Q4_K_M.gguf
  -md /workspace/fashions/dspark-Qwen3-8B-Q8_0.gguf
  --spec-type draft-dspark
  --spec-draft-n-max 3
  -ngl all
  -ngld all
  -fa on
  --temp 0
  --top-k 1
  -n 512
  -st
  -p "Write an entire Python implementation of merge kind. Clarify the way it works and embrace its time and area complexity. /no_think"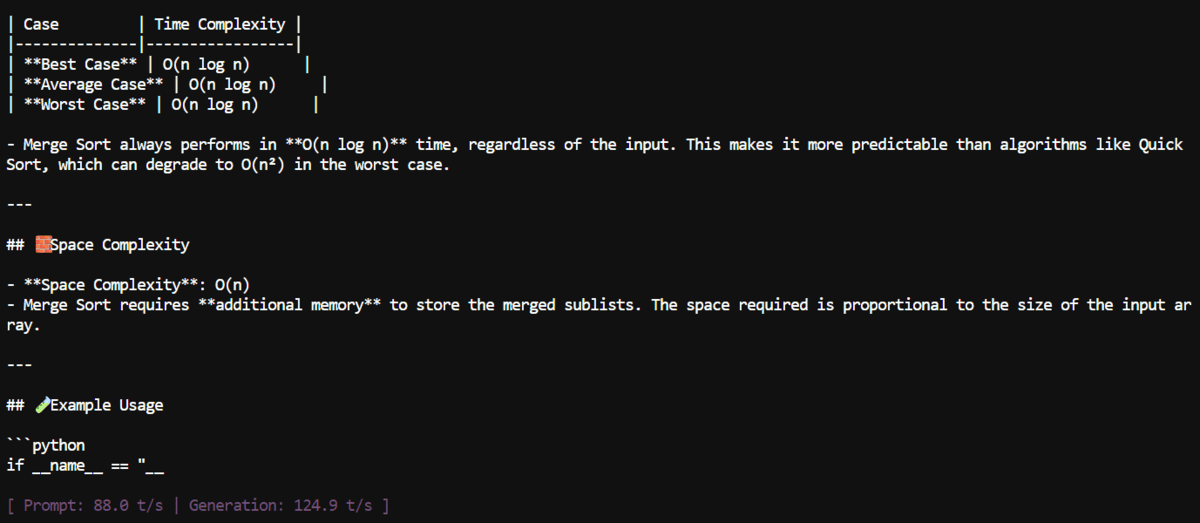
Right here, -md masses the DSpark draft mannequin, whereas --spec-type draft-dspark permits DSpark speculative decoding. --spec-draft-n-max 3 permits DSpark to draft as much as three tokens at a time, and -ngld all offloads the draft mannequin to the GPU.
When the run finishes, file the technology velocity:
[ Prompt: 88.0 t/s | Generation: 124.9 t/s ]Now evaluate it with our baseline:
| Configuration | Immediate Pace | Era Pace |
|---|---|---|
| Qwen3-8B baseline | 294.6 t/s | 95.0 t/s |
| Qwen3-8B + DSpark | 88.0 t/s | 124.9 t/s |
DSpark will increase technology throughput from 95.0 to 124.9 tokens/s. That’s a couple of 1.31× speedup, or roughly 31.5% quicker technology, utilizing the identical goal mannequin and GPU.
The prompt-processing velocity is decrease within the DSpark run, however the primary profit we’re measuring is autoregressive technology velocity. For workloads that generate longer responses, the upper token-generation throughput can have a a lot bigger influence on total inference time.
Ultimate Ideas
For native LLM acceleration, I nonetheless suppose MTP is commonly the extra sensible choice, particularly as a result of it’s less complicated and out there throughout a wider vary of fashions. Nonetheless, DSpark can have an edge over fundamental multi-token prediction in circumstances the place higher draft high quality results in extra accepted speculative tokens.
The great factor is that DSpark may be very straightforward to arrange in llama.cpp. The larger limitation is mannequin assist: solely a small variety of fashions at present have appropriate DSpark draft fashions out there.
Assist in llama.cpp can be nonetheless comparatively new, so chances are you’ll run into bugs or instability relying on the mannequin and construct you’re utilizing. For now, DSpark is an fascinating acceleration method to experiment with, however MTP stays the extra broadly helpful choice for native inference.
Abid Ali Awan (@1abidaliawan) is an authorized information scientist skilled who loves constructing machine studying fashions. At present, he’s specializing in content material creation and writing technical blogs on machine studying and information science applied sciences. Abid holds a Grasp’s diploma in expertise administration and a bachelor’s diploma in telecommunication engineering. His imaginative and prescient is to construct an AI product utilizing a graph neural community for college kids scuffling with psychological sickness.
There are various methods to get extra from the fashions and GPU infrastructure you have already got. Quantization, optimized kernels, and higher inference engines can all assist, however speculative decoding is particularly helpful as a result of it could possibly improve technology velocity with out merely including extra GPUs.
There are actually a number of approaches to speculative decoding. Conventional strategies use a smaller draft mannequin, whereas Multi-Token Prediction (MTP) predicts a number of future tokens directly. Strategies resembling Medusa and EAGLE enhance how these drafts are produced, whereas DFlash generates blocks of candidate tokens in parallel.
DSpark takes one other method by combining parallel drafting with a light-weight sequential element. This helps later draft tokens use info from earlier predictions whereas preserving a lot of the velocity benefit of parallel technology.
On this information, we’ll take a look at DSpark with Qwen3-8B and llama.cpp. We are going to benchmark the mannequin usually, allow DSpark with an identical draft mannequin, and evaluate the technology speeds to see how a lot efficiency we are able to acquire from the identical GPU.
How DSpark Works
DeepSeek’s DSpark improves the drafting a part of speculative decoding.
Parallel draft fashions can predict a complete block of tokens in a single cross, which is quick, however later predictions can change into much less correct as a result of they don’t totally rely on the tokens predicted earlier within the block. DSpark combines a parallel spine with a light-weight sequential element, permitting later draft positions to include info from earlier predicted tokens whereas retaining a lot of the velocity of parallel technology.
In simplified phrases:
DSpark may also estimate how doubtless draft tokens are to outlive verification, permitting low-confidence components of a block to be dropped as a substitute of losing verification compute. llama.cpp exposes this by means of its DSpark implementation and elective confidence threshold.
DeepSeek experiences that DSpark improved per-user technology velocity by 60–85% in contrast with its earlier MTP-1 manufacturing baseline when deployed with DeepSeek-V4. These numbers shouldn’t be handled as anticipated outcomes for our small native mannequin, so we’re going to measure the distinction ourselves.
1. Constructing llama.cpp and Downloading the Fashions
We are going to construct the most recent llama.cpp from supply so we are able to use its present DSpark implementation with CUDA acceleration.
Set up the required instruments:
apt-get replace
apt-get set up -y git cmake build-essential
Clone the official llama.cpp repository:
cd /workspace
git clone https://github.com/ggml-org/llama.cpp
Construct it with CUDA assist enabled:
cmake llama.cpp -B llama.cpp/construct
  -DBUILD_SHARED_LIBS=OFF
  -DGGML_CUDA=ON

cmake --build llama.cpp/construct
  --config Launch
  -j
  --clean-first
  --target llama-cli llama-mtmd-cli llama-server llama-gguf-split
This creates the binaries we want whereas permitting the fashions to run on the GPU.
Subsequent, create a listing for the mannequin information:
mkdir -p /workspace/fashionsWe are going to obtain the GGUF information manually utilizing the Hugging Face CLI so the obtain time doesn’t have an effect on our benchmarks.
Set up the CLI:
pip set up -U huggingface_hubIn case your Hugging Face token is saved in HF_TOKEN, authenticate with:
hf auth login --token "$HF_TOKEN"Obtain the Qwen3-8B Q4_K_M goal mannequin:
hf obtain
  Qwen/Qwen3-8B-GGUF
  Qwen3-8B-Q4_K_M.gguf
  --local-dir /workspace/fashions
Then obtain the matching DSpark Q8_0 draft mannequin:
hf obtain
  ggml-org/Qwen3-8B-GGUF
  dspark-Qwen3-8B-Q8_0.gguf
  --local-dir /workspace/fashions
The primary file is the primary mannequin that generates the ultimate output. The smaller DSpark mannequin will generate speculative draft tokens for the goal mannequin to confirm.
Affirm that each information can be found:
ls -lh /workspace/fashionsYou must see one thing just like:
4.7G  Qwen3-8B-Q4_K_M.gguf
1.2G  dspark-Qwen3-8B-Q8_0.gguf
With llama.cpp constructed and each fashions downloaded, we are able to first measure the conventional Qwen3-8B technology velocity earlier than enabling speculative decoding.
2. Measuring the Baseline Pace
Earlier than enabling DSpark, we want a baseline. We are going to run Qwen3-8B usually and file its technology velocity so we are able to evaluate it in opposition to the speculative-decoding run.
Transfer into the llama.cpp listing:
cd /workspace/llama.cppRun Qwen3-8B with out speculative decoding:
./construct/bin/llama-cli
  -m /workspace/fashions/Qwen3-8B-Q4_K_M.gguf
  -ngl all
  -fa on
  --temp 0
  --top-k 1
  -n 512
  -st
  -p "Write an entire Python implementation of merge kind. Clarify the way it works and embrace its time and area complexity. /no_think"
Right here, -ngl all offloads all mannequin layers to the GPU, whereas -fa on permits Flash Consideration.
We additionally use deterministic decoding:
--temp 0 --top-k 1That is necessary as a result of we’ll use the similar immediate, token restrict, and decoding settings when testing DSpark, giving us a cleaner apples-to-apples comparability.
When technology finishes, search for the benchmark abstract printed by llama.cpp:
[ Prompt: 294.6 t/s | Generation: 95.0 t/s ]For this information, the necessary quantity is Era: 95.0 tokens/s. We are going to use this as our baseline when measuring the DSpark speedup.
3. Operating the Similar Take a look at With DSpark
Now we’ll repeat the benchmark with DSpark enabled. The objective is to maintain the goal mannequin, immediate, token restrict, and decoding settings the identical so we are able to immediately measure the impact of speculative decoding.
Run the identical Qwen3-8B mannequin, this time with the DSpark draft mannequin connected:
./construct/bin/llama-cli
  -m /workspace/fashions/Qwen3-8B-Q4_K_M.gguf
  -md /workspace/fashions/dspark-Qwen3-8B-Q8_0.gguf
  --spec-type draft-dspark
  --spec-draft-n-max 3
  -ngl all
  -ngld all
  -fa on
  --temp 0
  --top-k 1
  -n 512
  -st
  -p "Write an entire Python implementation of merge kind. Clarify the way it works and embrace its time and area complexity. /no_think"
Right here, -md masses the DSpark draft mannequin, whereas --spec-type draft-dspark permits DSpark speculative decoding. --spec-draft-n-max 3 permits DSpark to draft as much as three tokens at a time, and -ngld all offloads the draft mannequin to the GPU.
When the run finishes, file the technology velocity:
[ Prompt: 88.0 t/s | Generation: 124.9 t/s ]Now evaluate it with our baseline:
| Configuration | Immediate Pace | Era Pace |
|---|---|---|
| Qwen3-8B baseline | 294.6 t/s | 95.0 t/s |
| Qwen3-8B + DSpark | 88.0 t/s | 124.9 t/s |
DSpark will increase technology throughput from 95.0 to 124.9 tokens/s. That’s a couple of 1.31× speedup, or roughly 31.5% quicker technology, utilizing the identical goal mannequin and GPU.
The prompt-processing velocity is decrease within the DSpark run, however the primary profit we’re measuring is autoregressive technology velocity. For workloads that generate longer responses, the upper token-generation throughput can have a a lot bigger influence on total inference time.
Ultimate Ideas
For native LLM acceleration, I nonetheless suppose MTP is commonly the extra sensible choice, particularly as a result of it’s less complicated and out there throughout a wider vary of fashions. Nonetheless, DSpark can have an edge over fundamental multi-token prediction in circumstances the place higher draft high quality results in extra accepted speculative tokens.
The great factor is that DSpark may be very straightforward to arrange in llama.cpp. The larger limitation is mannequin assist: solely a small variety of fashions at present have appropriate DSpark draft fashions out there.
Assist in llama.cpp can be nonetheless comparatively new, so chances are you’ll run into bugs or instability relying on the mannequin and construct you’re utilizing. For now, DSpark is an fascinating acceleration method to experiment with, however MTP stays the extra broadly helpful choice for native inference.
Abid Ali Awan (@1abidaliawan) is an authorized information scientist skilled who loves constructing machine studying fashions. At present, he’s specializing in content material creation and writing technical blogs on machine studying and information science applied sciences. Abid holds a Grasp’s diploma in expertise administration and a bachelor’s diploma in telecommunication engineering. His imaginative and prescient is to construct an AI product utilizing a graph neural community for college kids scuffling with psychological sickness.