On this article, you’ll discover ways to get a small language mannequin operating regionally by yourself machine in underneath quarter-hour utilizing Ollama.
Subjects we are going to cowl embody:
- Why Ollama has turn out to be the usual device for operating native AI fashions.
- The three-step course of to put in Ollama, obtain a mannequin, and begin chatting completely offline.
- What quantization is, and the right way to diagnose the commonest first-run issues.
Let’s not waste any extra time.
The Native Scene
In our Introduction to Small Language Fashions, we coated how a brand new technology of environment friendly AI fashions is shifting workloads away from large, costly cloud APIs. We adopted that up with a breakdown of the High 7 Small Language Fashions You Can Run on a Laptop computer, overlaying compact fashions like Meta’s Llama 3.2 3B and Google’s Gemma 2 9B.
Understanding the idea and choosing a mannequin is just half the story. The actual payoff is seeing a completely succesful mannequin operating regionally by yourself machine: utterly offline, personal, and free per token. That’s precisely what we’re going to do right here.
Traditionally, organising native AI meant preventing with CUDA drivers, configuring Python digital environments, and untangling dependency conflicts. Ollama has modified that completely.
This information walks the one “completely happy path” to get your first small language mannequin (SLM) operating regionally in underneath quarter-hour. No distractions, no platform fragmentation, simply native inference.
Why Ollama Works So Nicely for Native AI
Earlier than we get into the setup steps, it’s price spending a second on why Ollama is the device we’re utilizing, as a result of it’s not the one choice, and understanding what units it aside will show you how to get extra out of it.
Ollama has turn out to be the go-to device for native AI as a result of it packages complicated mannequin architectures right into a clear, light-weight background service. It handles mannequin downloads, manages {hardware} acceleration natively, and exposes a easy native API.
Consider it as Docker, however constructed particularly for language fashions. As a substitute of wrangling uncooked mannequin weights, you work together with it via a handful of simple instructions. With that context in place, let’s put it to work.
The Blissful Path: Set up, Pull, and Chat
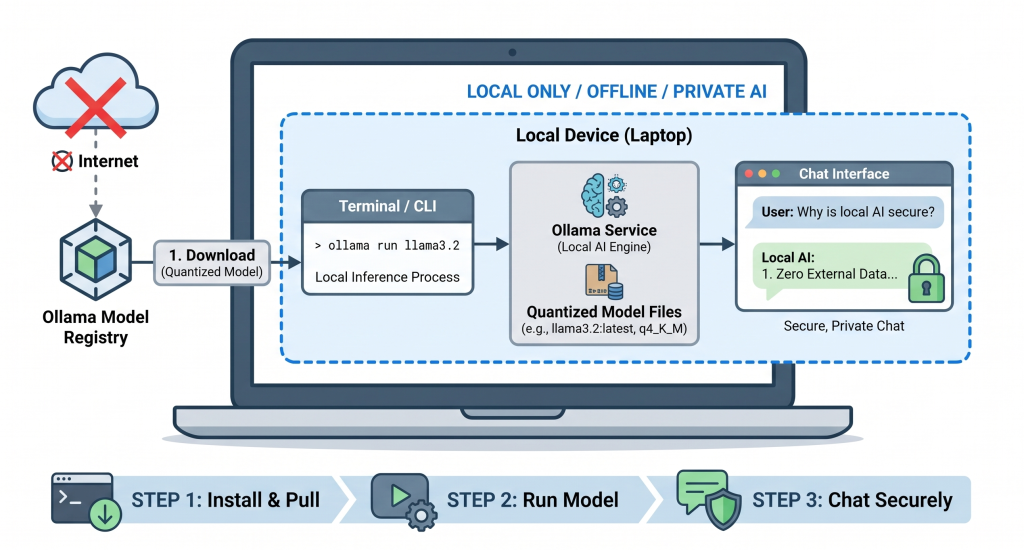
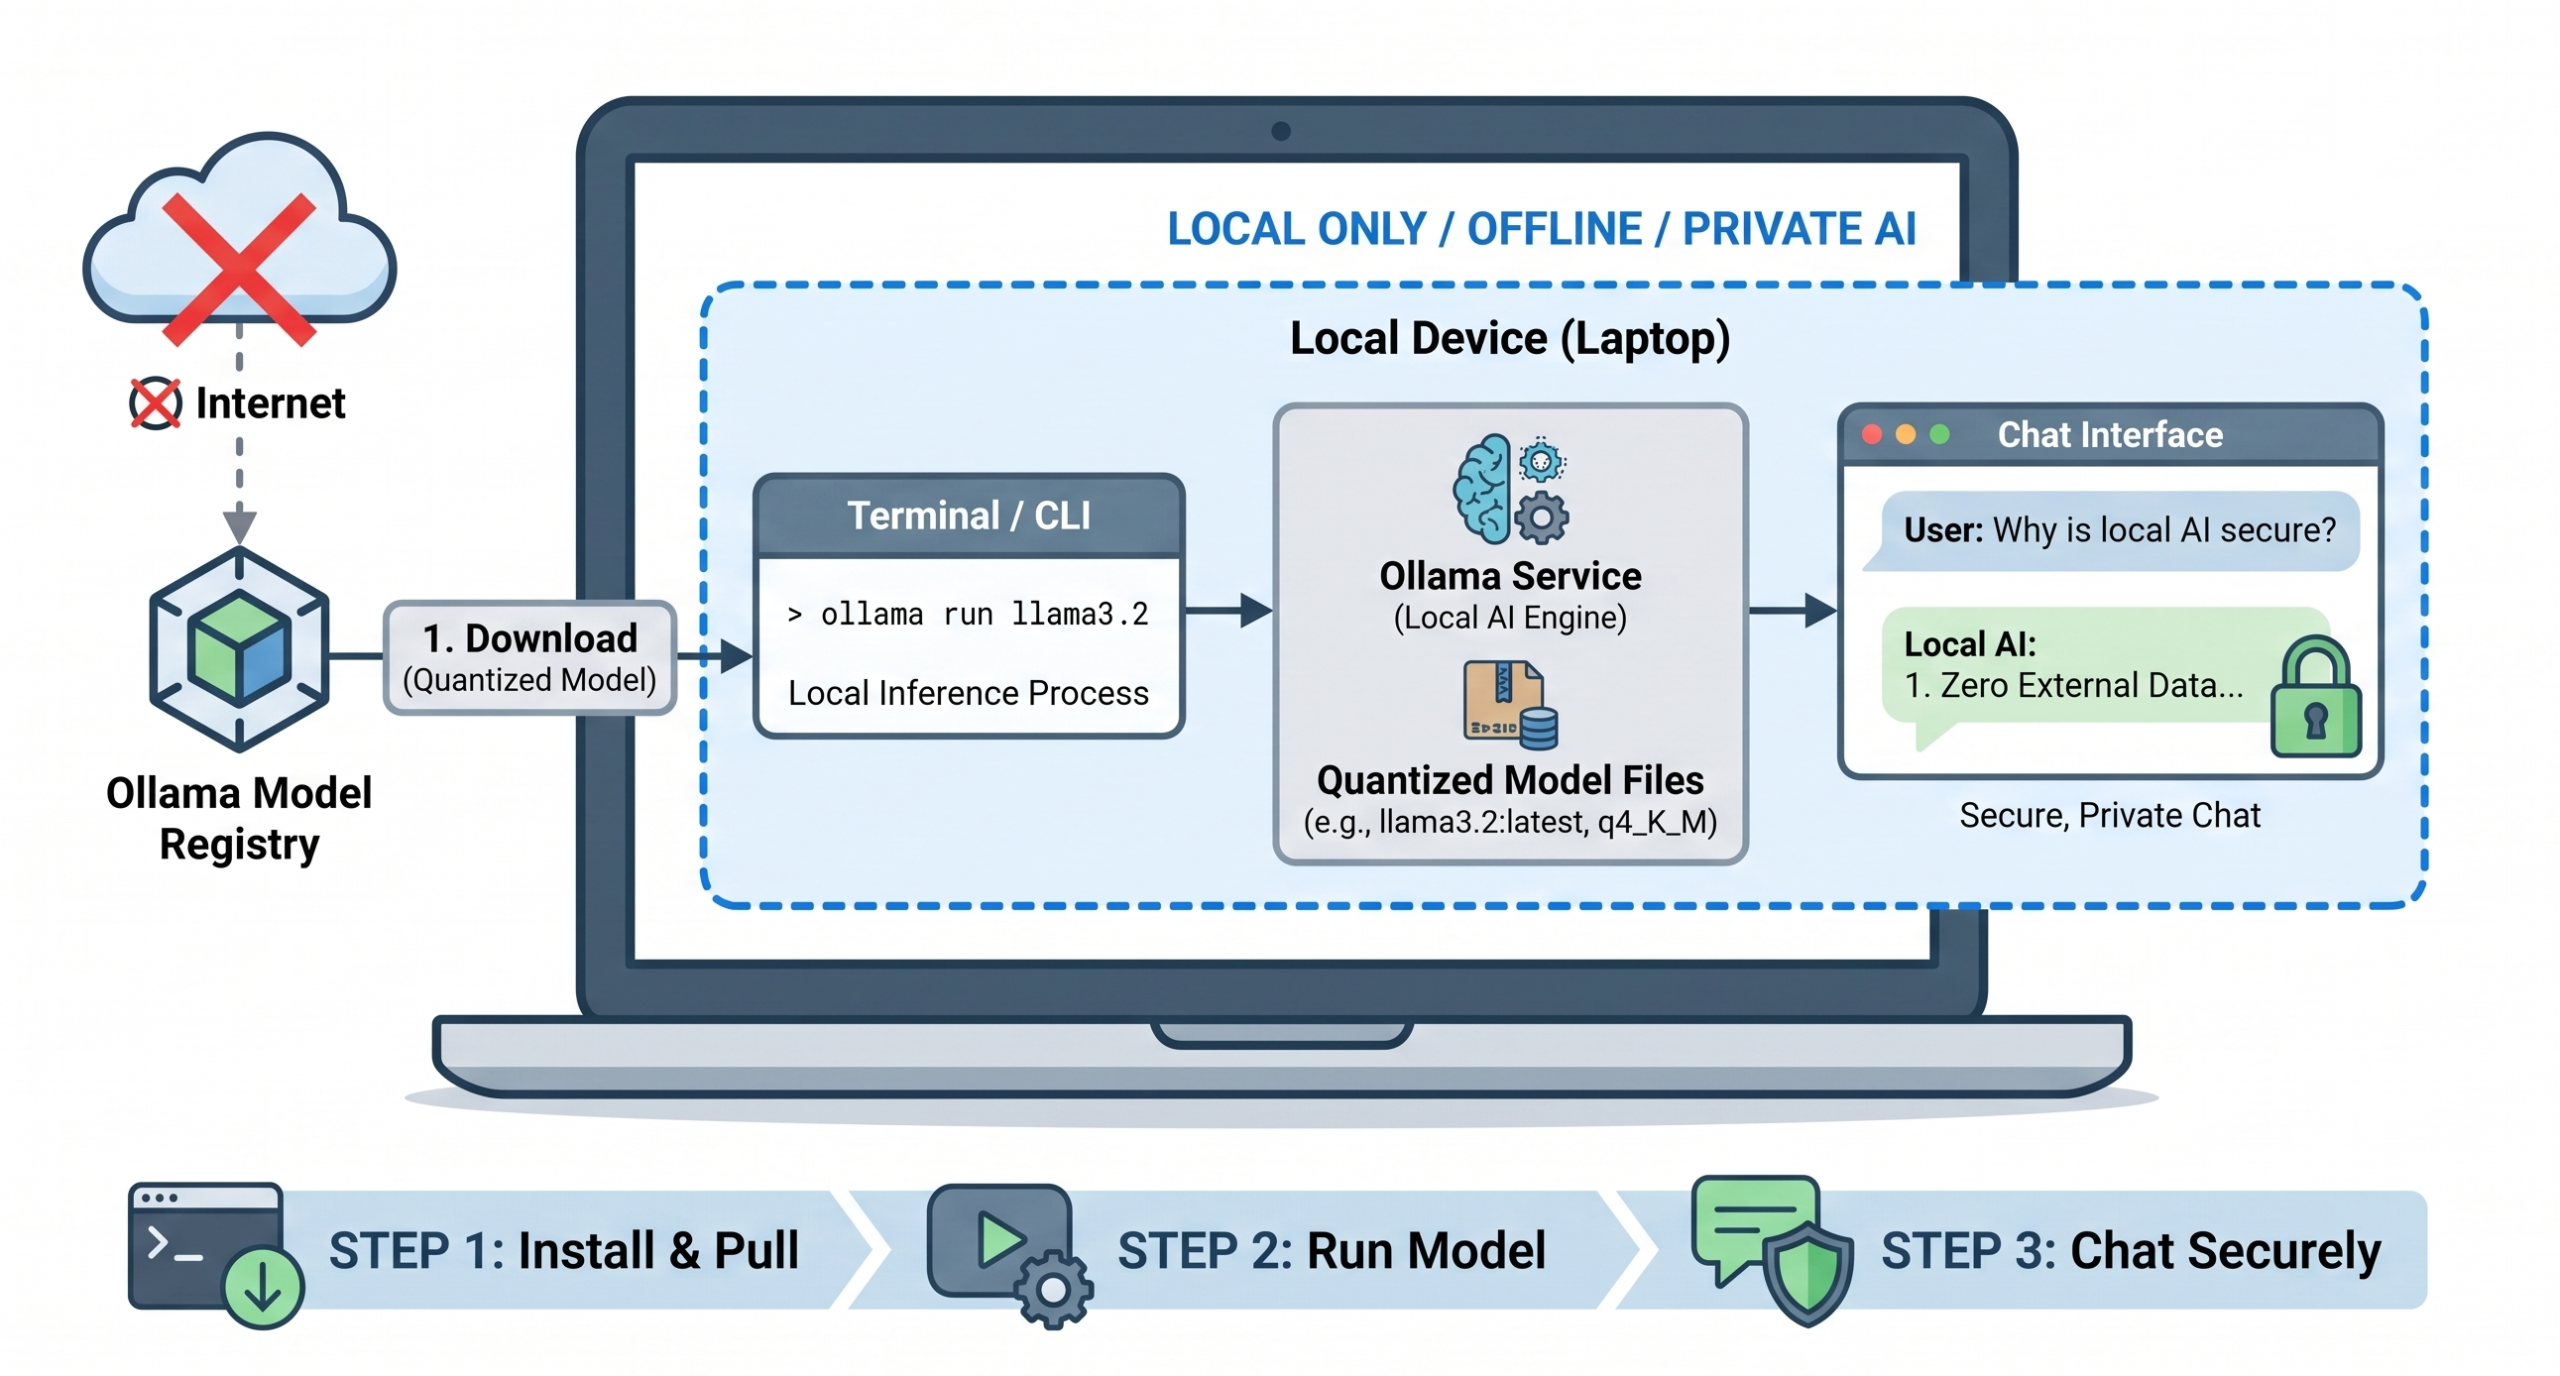
Now that we all know what Ollama is doing underneath the hood, let’s get it operating. We’ll observe a unified, cross-platform circulate. Whether or not you’re on macOS, Home windows, or Linux, the underlying setup behaves precisely the identical manner: three steps from zero to a working AI chat session.
Step 1: Putting in Ollama
First, seize the installer on your working system:
- macOS & Home windows: Head to the official Ollama web site, obtain the native installer, and run it. On Home windows, it units itself up as a system tray software. On macOS, it provides a menu bar icon.
- Linux: Open your terminal and run the official one-liner:
curl -fsSL https://ollama.com/set up.sh | sh
Step 2: Downloading Your First Mannequin
With Ollama put in and operating quietly within the background, it’s time to tug down an precise mannequin. Open your terminal (or Command Immediate/PowerShell on Home windows) and run the next. We’ll obtain Llama 3.2 3B, one of many best-balanced fashions for on a regular basis laptop computer use.
|
# Confirm Ollama is operating by checking the model ollama —model
# Pull and instantly run the Llama 3.2 3B mannequin ollama run llama3.2 |
Ollama will begin downloading the mannequin layers. As a result of Llama 3.2 3B is well-optimized, the obtain is available in at roughly 2.0 GB, underneath three minutes on a typical broadband connection.
Step 3: Your First Chat Session
As soon as the obtain hits 100%, your terminal turns into an interactive chat interface. You’re now speaking to an AI operating completely by yourself {hardware}, no web required, no information leaving your machine. Do this immediate to kick issues off:
|
>>> Write a three–bullet–level abstract explaining why native AI is safe. – **Zero Exterior Knowledge Transmission**: Your prompts and information by no means go away your native machine, eliminating the threat of cloud–based mostly information leaks or third–celebration logging. – **Full Offline Performance**: As a result of the mannequin runs completely on your native {hardware}, it requires no web connection, stopping community–based mostly interception. – **Complete Infrastructure Management**: You retain absolute possession over the {hardware} and setting, permitting you to implement strict entry controls and compliance insurance policies.
>>> /bye |
To exit at any time, sort /bye and hit enter.
What You Really Downloaded
That three-step course of felt easy, and it was. However fairly a bit occurred behind the scenes if you ran ollama run llama3.2. Understanding what’s now sitting in your laborious drive will show you how to make smarter selections about fashions, reminiscence, and efficiency going ahead.
Mannequin Tags and Defaults
In the event you don’t specify a tag, Ollama robotically appends :newest. For Llama 3.2, that tag factors to the 3-billion parameter variant, a stable stability of velocity and functionality for client {hardware}.
Understanding Quantization
Right here’s one thing price pausing on: a 3-billion parameter mannequin at customary 16-bit floating-point precision (fp16) ought to want about 6 GB of VRAM simply to carry the weights. Your obtain was round 2.0 GB. So what provides?
Ollama defaults to 4-bit quantization (particularly, q4_K_M). This compresses the mannequin’s weights from full-precision floats all the way down to 4-bit integers, chopping the reminiscence footprint by over 60% and dashing up inference noticeably, with solely a small hit to accuracy. It’s the explanation a succesful language mannequin can comfortably match on a laptop computer.
Output Sanity Verify: Good vs. Degraded
As a result of 3B fashions are compact, they will present indicators of pressure when system sources are tight. Right here’s what to observe for thus you possibly can inform instantly whether or not issues are working as anticipated:
- What Good Appears to be like Like: Quick, coherent textual content technology, usually 40+ tokens per second on fashionable Apple Silicon or a devoted Nvidia GPU. Logic stays crisp, and formatting directions get adopted.
- What Degraded Appears to be like Like: Extreme hallucinations (gibberish output), damaged syntax, repetitive loops, or technology speeds under 5 tokens per second. This often means the mannequin’s weights have spilled out of quick VRAM into slower system RAM or a web page file.
In case your output appears to be like degraded, the subsequent part has you coated.
When Issues Go Incorrect: The First-Run Symptom Desk
Ollama’s set up often goes easily, however {hardware} variations could cause hiccups. Relatively than digging via log recordsdata, use this fast reference to diagnose the three most typical first-run failures at a look.
| Symptom / Error | Root Trigger | The Instant Repair |
|---|---|---|
| Chat response takes minutes to begin, or textual content prints one phrase each few seconds. | Inadequate VRAM/RAM. The mannequin is simply too heavy on your GPU, so Ollama falls again to slower CPU/system reminiscence. | Shut RAM-heavy apps like Chrome or your IDE. Or drop to a lighter mannequin: ollama run smollm2:1.7b. |
| Error: “Didn’t contact GPU driver” or Ollama defaults to CPU on a high-end gaming laptop computer. | GPU driver mismatch. Ollama can’t hook up with your devoted GPU, which is widespread with outdated Nvidia CUDA or AMD ROCm drivers. | Replace your GPU drivers to the newest model. On Home windows/Linux, verify that CUDA_VISIBLE_DEVICES isn’t by chance blocking entry. |
| Error: “handle already in use” or “Error: pay attention tcp 127.0.0.1:11434: bind: handle already in use” | Port battle. One other Ollama occasion is already operating as a background service, blocking the terminal from opening a brand new connection. | Don’t relaunch the app. Simply run your command immediately (ollama run llama3.2), the background daemon is already listening on port 11434. |
Subsequent Steps with Native AI
With a working native inference setup in place, you now have a non-public AI engine that’s completely yours: no API keys, no charge limits, no subscriptions, and no information leaving your machine. That’s a significant functionality, and it’s simply the start line.
From right here, exploring the opposite fashions from our High 7 checklist is so simple as swapping the title in your terminal: ollama run gemma2:9b, ollama run phi3.5, and so forth. Every mannequin has completely different strengths, some excel at reasoning, others at code technology or long-context duties, so attempting a couple of will shortly present you what matches your workflow finest.
As you get comfy, think about constructing on prime of Ollama’s native API (it runs on localhost:11434 and is OpenAI-compatible), which opens the door to integrating native fashions into your individual scripts, instruments, and functions. That basis, mixed with what you now find out about quantization and {hardware} necessities, will serve you effectively as you progress into extra superior native AI work.
On this article, you’ll discover ways to get a small language mannequin operating regionally by yourself machine in underneath quarter-hour utilizing Ollama.
Subjects we are going to cowl embody:
- Why Ollama has turn out to be the usual device for operating native AI fashions.
- The three-step course of to put in Ollama, obtain a mannequin, and begin chatting completely offline.
- What quantization is, and the right way to diagnose the commonest first-run issues.
Let’s not waste any extra time.
The Native Scene
In our Introduction to Small Language Fashions, we coated how a brand new technology of environment friendly AI fashions is shifting workloads away from large, costly cloud APIs. We adopted that up with a breakdown of the High 7 Small Language Fashions You Can Run on a Laptop computer, overlaying compact fashions like Meta’s Llama 3.2 3B and Google’s Gemma 2 9B.
Understanding the idea and choosing a mannequin is just half the story. The actual payoff is seeing a completely succesful mannequin operating regionally by yourself machine: utterly offline, personal, and free per token. That’s precisely what we’re going to do right here.
Traditionally, organising native AI meant preventing with CUDA drivers, configuring Python digital environments, and untangling dependency conflicts. Ollama has modified that completely.
This information walks the one “completely happy path” to get your first small language mannequin (SLM) operating regionally in underneath quarter-hour. No distractions, no platform fragmentation, simply native inference.
Why Ollama Works So Nicely for Native AI
Earlier than we get into the setup steps, it’s price spending a second on why Ollama is the device we’re utilizing, as a result of it’s not the one choice, and understanding what units it aside will show you how to get extra out of it.
Ollama has turn out to be the go-to device for native AI as a result of it packages complicated mannequin architectures right into a clear, light-weight background service. It handles mannequin downloads, manages {hardware} acceleration natively, and exposes a easy native API.
Consider it as Docker, however constructed particularly for language fashions. As a substitute of wrangling uncooked mannequin weights, you work together with it via a handful of simple instructions. With that context in place, let’s put it to work.
The Blissful Path: Set up, Pull, and Chat
Now that we all know what Ollama is doing underneath the hood, let’s get it operating. We’ll observe a unified, cross-platform circulate. Whether or not you’re on macOS, Home windows, or Linux, the underlying setup behaves precisely the identical manner: three steps from zero to a working AI chat session.
Step 1: Putting in Ollama
First, seize the installer on your working system:
- macOS & Home windows: Head to the official Ollama web site, obtain the native installer, and run it. On Home windows, it units itself up as a system tray software. On macOS, it provides a menu bar icon.
- Linux: Open your terminal and run the official one-liner:
curl -fsSL https://ollama.com/set up.sh | sh
Step 2: Downloading Your First Mannequin
With Ollama put in and operating quietly within the background, it’s time to tug down an precise mannequin. Open your terminal (or Command Immediate/PowerShell on Home windows) and run the next. We’ll obtain Llama 3.2 3B, one of many best-balanced fashions for on a regular basis laptop computer use.
|
# Confirm Ollama is operating by checking the model ollama —model
# Pull and instantly run the Llama 3.2 3B mannequin ollama run llama3.2 |
Ollama will begin downloading the mannequin layers. As a result of Llama 3.2 3B is well-optimized, the obtain is available in at roughly 2.0 GB, underneath three minutes on a typical broadband connection.
Step 3: Your First Chat Session
As soon as the obtain hits 100%, your terminal turns into an interactive chat interface. You’re now speaking to an AI operating completely by yourself {hardware}, no web required, no information leaving your machine. Do this immediate to kick issues off:
|
>>> Write a three–bullet–level abstract explaining why native AI is safe. – **Zero Exterior Knowledge Transmission**: Your prompts and information by no means go away your native machine, eliminating the threat of cloud–based mostly information leaks or third–celebration logging. – **Full Offline Performance**: As a result of the mannequin runs completely on your native {hardware}, it requires no web connection, stopping community–based mostly interception. – **Complete Infrastructure Management**: You retain absolute possession over the {hardware} and setting, permitting you to implement strict entry controls and compliance insurance policies.
>>> /bye |
To exit at any time, sort /bye and hit enter.
What You Really Downloaded
That three-step course of felt easy, and it was. However fairly a bit occurred behind the scenes if you ran ollama run llama3.2. Understanding what’s now sitting in your laborious drive will show you how to make smarter selections about fashions, reminiscence, and efficiency going ahead.
Mannequin Tags and Defaults
In the event you don’t specify a tag, Ollama robotically appends :newest. For Llama 3.2, that tag factors to the 3-billion parameter variant, a stable stability of velocity and functionality for client {hardware}.
Understanding Quantization
Right here’s one thing price pausing on: a 3-billion parameter mannequin at customary 16-bit floating-point precision (fp16) ought to want about 6 GB of VRAM simply to carry the weights. Your obtain was round 2.0 GB. So what provides?
Ollama defaults to 4-bit quantization (particularly, q4_K_M). This compresses the mannequin’s weights from full-precision floats all the way down to 4-bit integers, chopping the reminiscence footprint by over 60% and dashing up inference noticeably, with solely a small hit to accuracy. It’s the explanation a succesful language mannequin can comfortably match on a laptop computer.
Output Sanity Verify: Good vs. Degraded
As a result of 3B fashions are compact, they will present indicators of pressure when system sources are tight. Right here’s what to observe for thus you possibly can inform instantly whether or not issues are working as anticipated:
- What Good Appears to be like Like: Quick, coherent textual content technology, usually 40+ tokens per second on fashionable Apple Silicon or a devoted Nvidia GPU. Logic stays crisp, and formatting directions get adopted.
- What Degraded Appears to be like Like: Extreme hallucinations (gibberish output), damaged syntax, repetitive loops, or technology speeds under 5 tokens per second. This often means the mannequin’s weights have spilled out of quick VRAM into slower system RAM or a web page file.
In case your output appears to be like degraded, the subsequent part has you coated.
When Issues Go Incorrect: The First-Run Symptom Desk
Ollama’s set up often goes easily, however {hardware} variations could cause hiccups. Relatively than digging via log recordsdata, use this fast reference to diagnose the three most typical first-run failures at a look.
| Symptom / Error | Root Trigger | The Instant Repair |
|---|---|---|
| Chat response takes minutes to begin, or textual content prints one phrase each few seconds. | Inadequate VRAM/RAM. The mannequin is simply too heavy on your GPU, so Ollama falls again to slower CPU/system reminiscence. | Shut RAM-heavy apps like Chrome or your IDE. Or drop to a lighter mannequin: ollama run smollm2:1.7b. |
| Error: “Didn’t contact GPU driver” or Ollama defaults to CPU on a high-end gaming laptop computer. | GPU driver mismatch. Ollama can’t hook up with your devoted GPU, which is widespread with outdated Nvidia CUDA or AMD ROCm drivers. | Replace your GPU drivers to the newest model. On Home windows/Linux, verify that CUDA_VISIBLE_DEVICES isn’t by chance blocking entry. |
| Error: “handle already in use” or “Error: pay attention tcp 127.0.0.1:11434: bind: handle already in use” | Port battle. One other Ollama occasion is already operating as a background service, blocking the terminal from opening a brand new connection. | Don’t relaunch the app. Simply run your command immediately (ollama run llama3.2), the background daemon is already listening on port 11434. |
Subsequent Steps with Native AI
With a working native inference setup in place, you now have a non-public AI engine that’s completely yours: no API keys, no charge limits, no subscriptions, and no information leaving your machine. That’s a significant functionality, and it’s simply the start line.
From right here, exploring the opposite fashions from our High 7 checklist is so simple as swapping the title in your terminal: ollama run gemma2:9b, ollama run phi3.5, and so forth. Every mannequin has completely different strengths, some excel at reasoning, others at code technology or long-context duties, so attempting a couple of will shortly present you what matches your workflow finest.
As you get comfy, think about constructing on prime of Ollama’s native API (it runs on localhost:11434 and is OpenAI-compatible), which opens the door to integrating native fashions into your individual scripts, instruments, and functions. That basis, mixed with what you now find out about quantization and {hardware} necessities, will serve you effectively as you progress into extra superior native AI work.