On October 9, Vals AI revealed a check of whether or not a crew of coding brokers is definitely worth the worth [1]. That they had GPT 6 Sol and Claude Opus 5.5 construct 50 net apps from specs, every mannequin alone and as a crew wherein a lead arms components of the construct to subagents, at medium and at most reasoning effort. The groups price 1.8 to five.1 instances as a lot. Of the 4 team-versus-single comparisons, one was statistically vital: Sol at medium effort, which gained 7.3 factors. For Sol, elevating the only agent’s reasoning effort from medium to max added 11.4 factors, greater than the 7.3 a crew added at medium effort [1].
That research is about splitting a job into components, so it says nothing immediately about whether or not brokers make the identical errors. It did go away me with a query a mathematician can assault. Once you add one other mannequin to a vote, what number of unbiased opinions do you really add?
The plan is to take a look at what a vote guarantees, simulate the way it can fail, put a formulation on the failure, after which measure it on six actual fashions.
What a vote is meant to purchase
The classical reply is Condorcet’s jury theorem, from 1785 [2]. Suppose each voter is correct with chance p > 1/2 and the voters are unbiased. The prospect that almost all of ok voters is correct is
and it climbs towards 1 as ok grows. With p = 0.7, three voters are proper 78.4% of the time, 5 83.7%, 9 90.1%, and twenty-five 98.3%.
Determine 1 plots the formulation for 3 ranges of particular person accuracy.
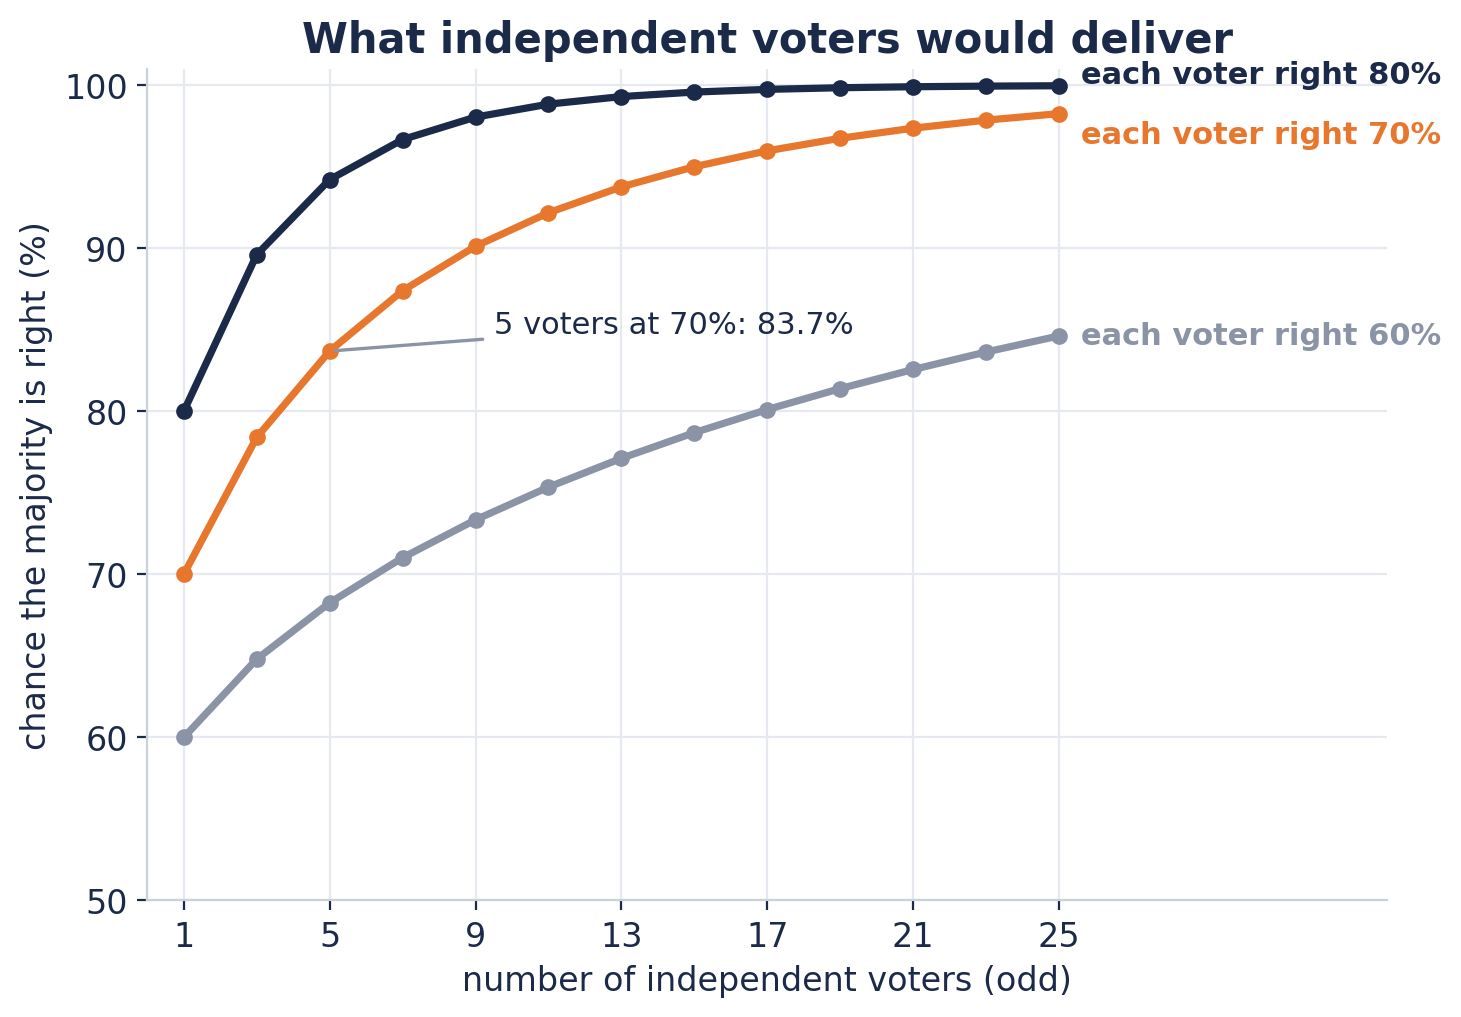
Each quantity in that paragraph leans on the phrase unbiased. Two fashions that make the identical mistake solid one vote between them, regardless of the poll depend says.
The catch: buddies who studied from the identical notes
Think about asking 5 buddies a trivia query and going with the bulk. In the event that they know various things, one pal’s improper guess is prone to be outvoted by the others. Now suppose all 5 studied from the identical notes, and the notes comprise a mistake. Everybody repeats it, and the bulk is improper with whole confidence. 5 folks, one supply, one vote.
Language fashions aren’t buddies, however the fear carries over. Fashions skilled on overlapping textual content, with comparable designs, may plausibly share blind spots. Whether or not they do is an empirical query, and it’s the one this text measures.
A small simulation
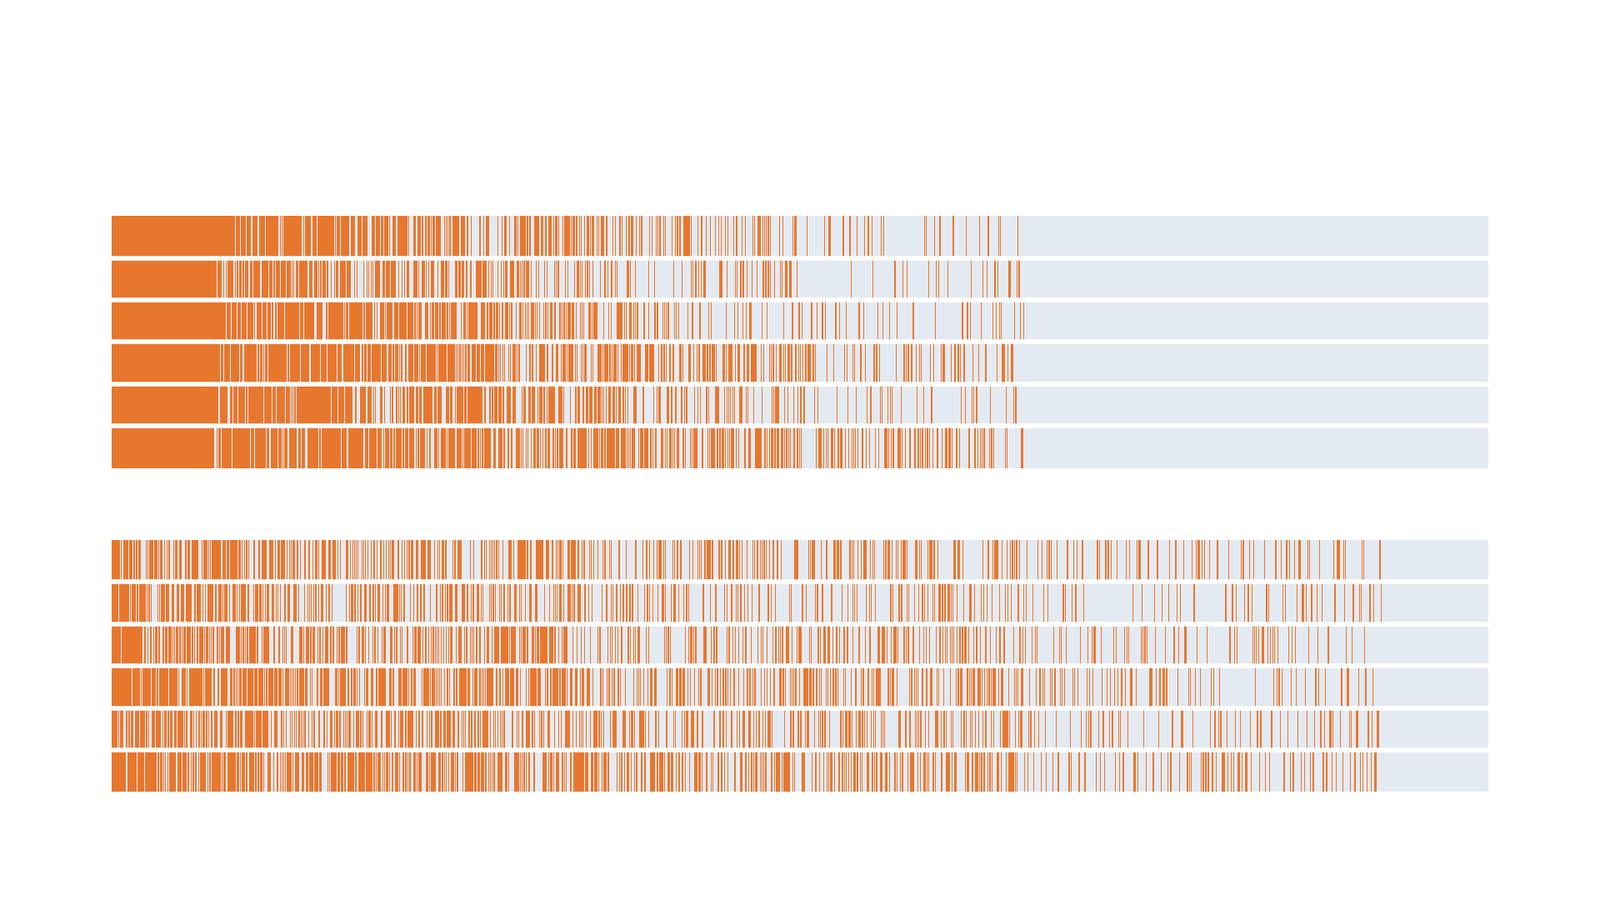
To see the distinction, I simulated two panels of 5 fashions. Each mannequin is correct 70% of the time. Within the first panel every mannequin’s errors land on questions independently of the others. Within the second the errors overlap: some questions are arduous for everybody, so the fashions are likely to fail on them collectively. Determine 2 exhibits 40 questions from every panel. Every row is a mannequin, every column is a query, and orange means improper. The underside row is almost all vote.
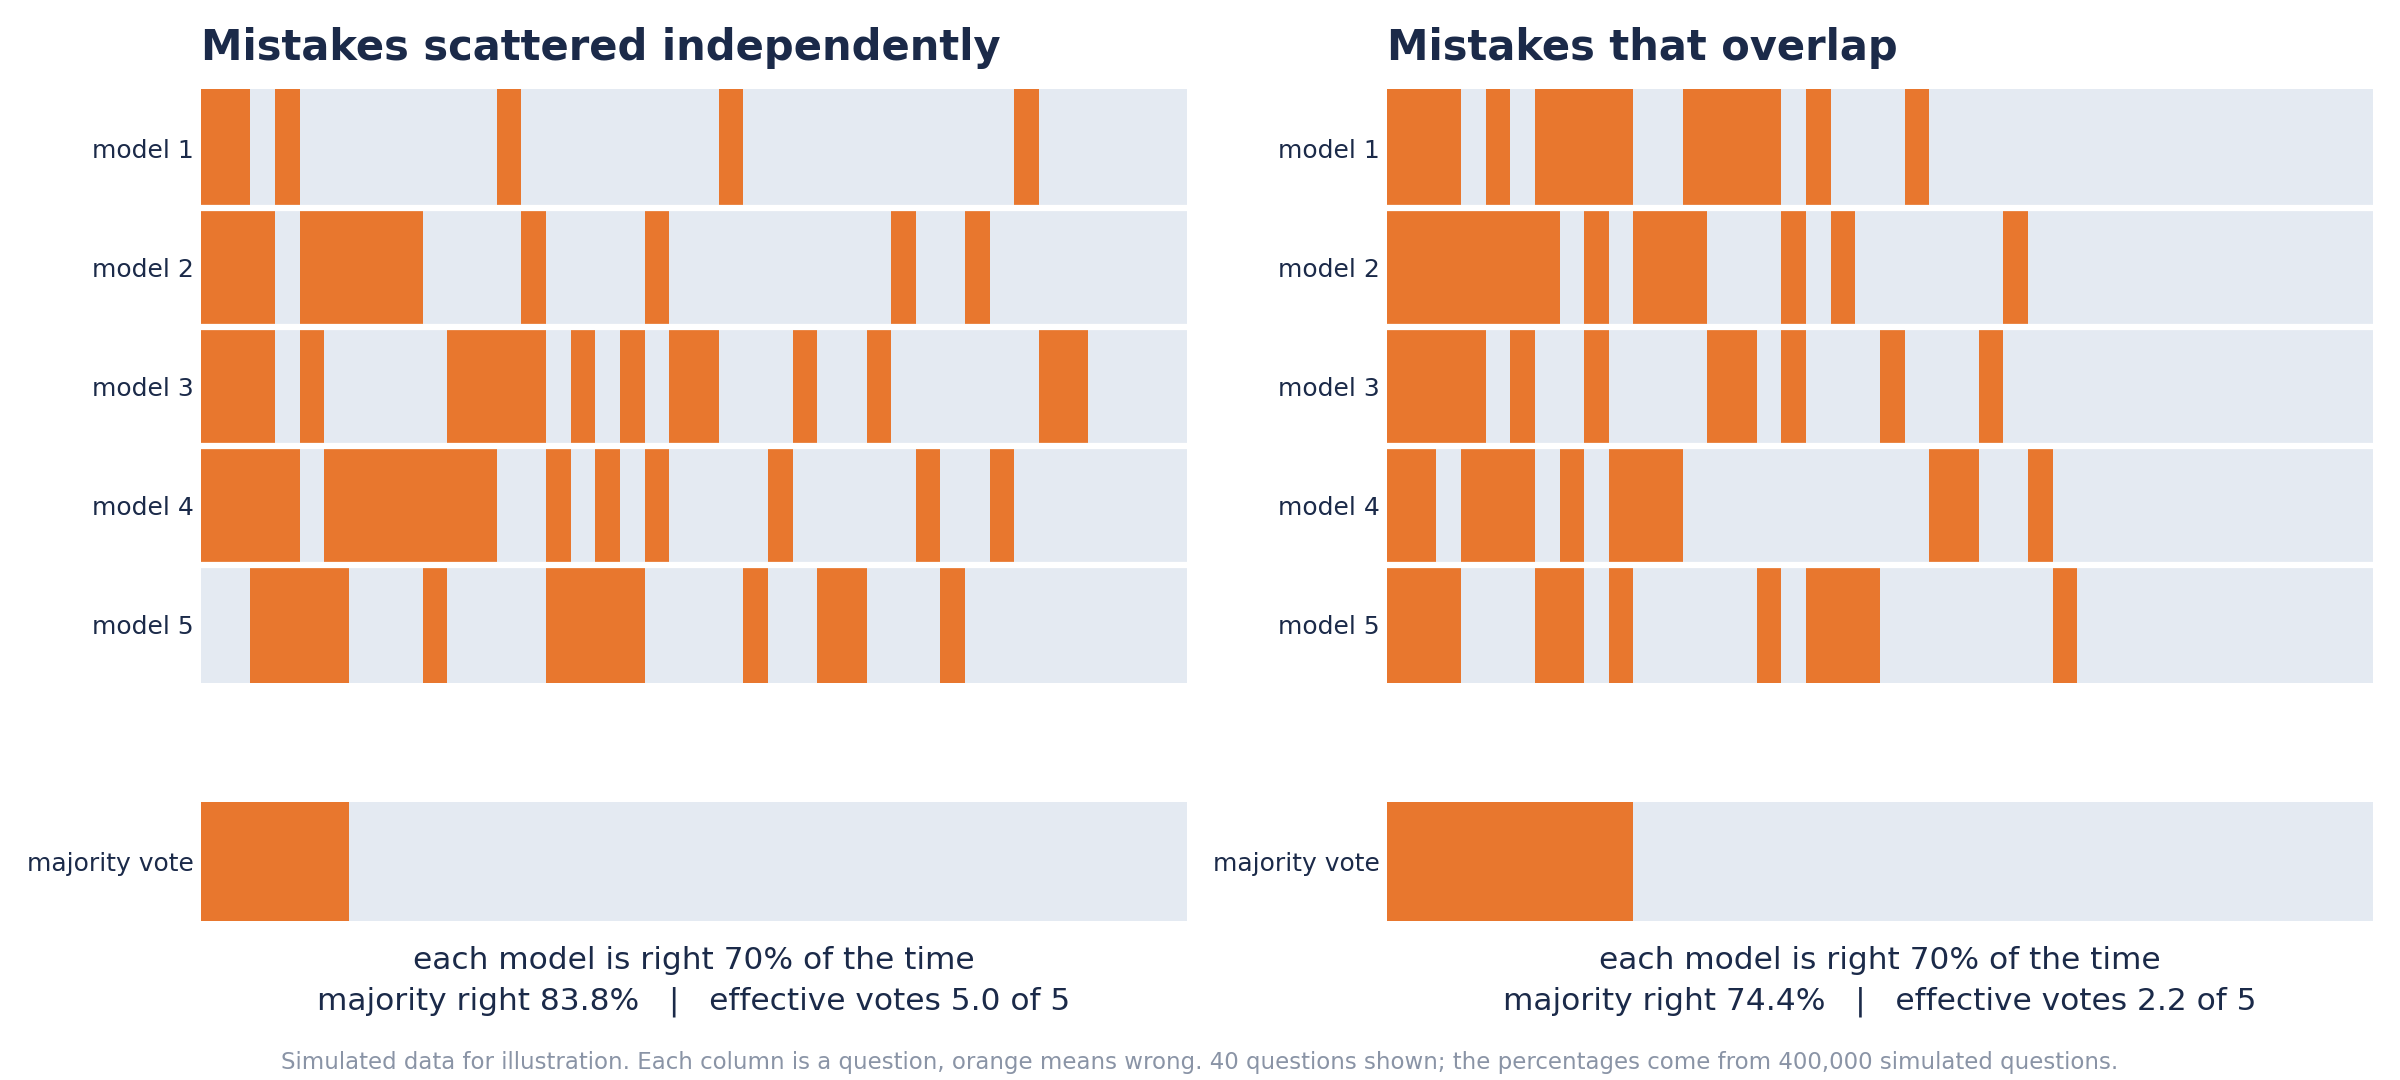
Per mannequin, the 2 panels are similar. The bulk vote shouldn’t be. With unbiased errors it’s proper 83.8% of the time, which is what Condorcet’s formulation predicts (83.7%). With overlapping errors it’s proper 74.4% of the time. Greater than 9 factors of accuracy disappear with none single mannequin getting worse, and the panel is value fewer opinions than it has members: 5.0 efficient votes within the first case, 2.2 within the second. The subsequent part explains the place these two numbers come from.
From an image to a quantity
An image shouldn’t be a measurement, so right here is the usual solution to put a quantity on it. For every mannequin and every query, document a 1 if the mannequin obtained it improper and a 0 if it obtained it proper. The correlation between two such columns is the phi coefficient, . It’s 0 when two fashions’ errors are unrelated and 1 once they fail on precisely the identical questions.
Take ok voters whose error indicators every have variance and whose pairs all have correlation . The variance of their common error is
Impartial voters would give for n of them, so outline the efficient variety of votes because the n that matches:
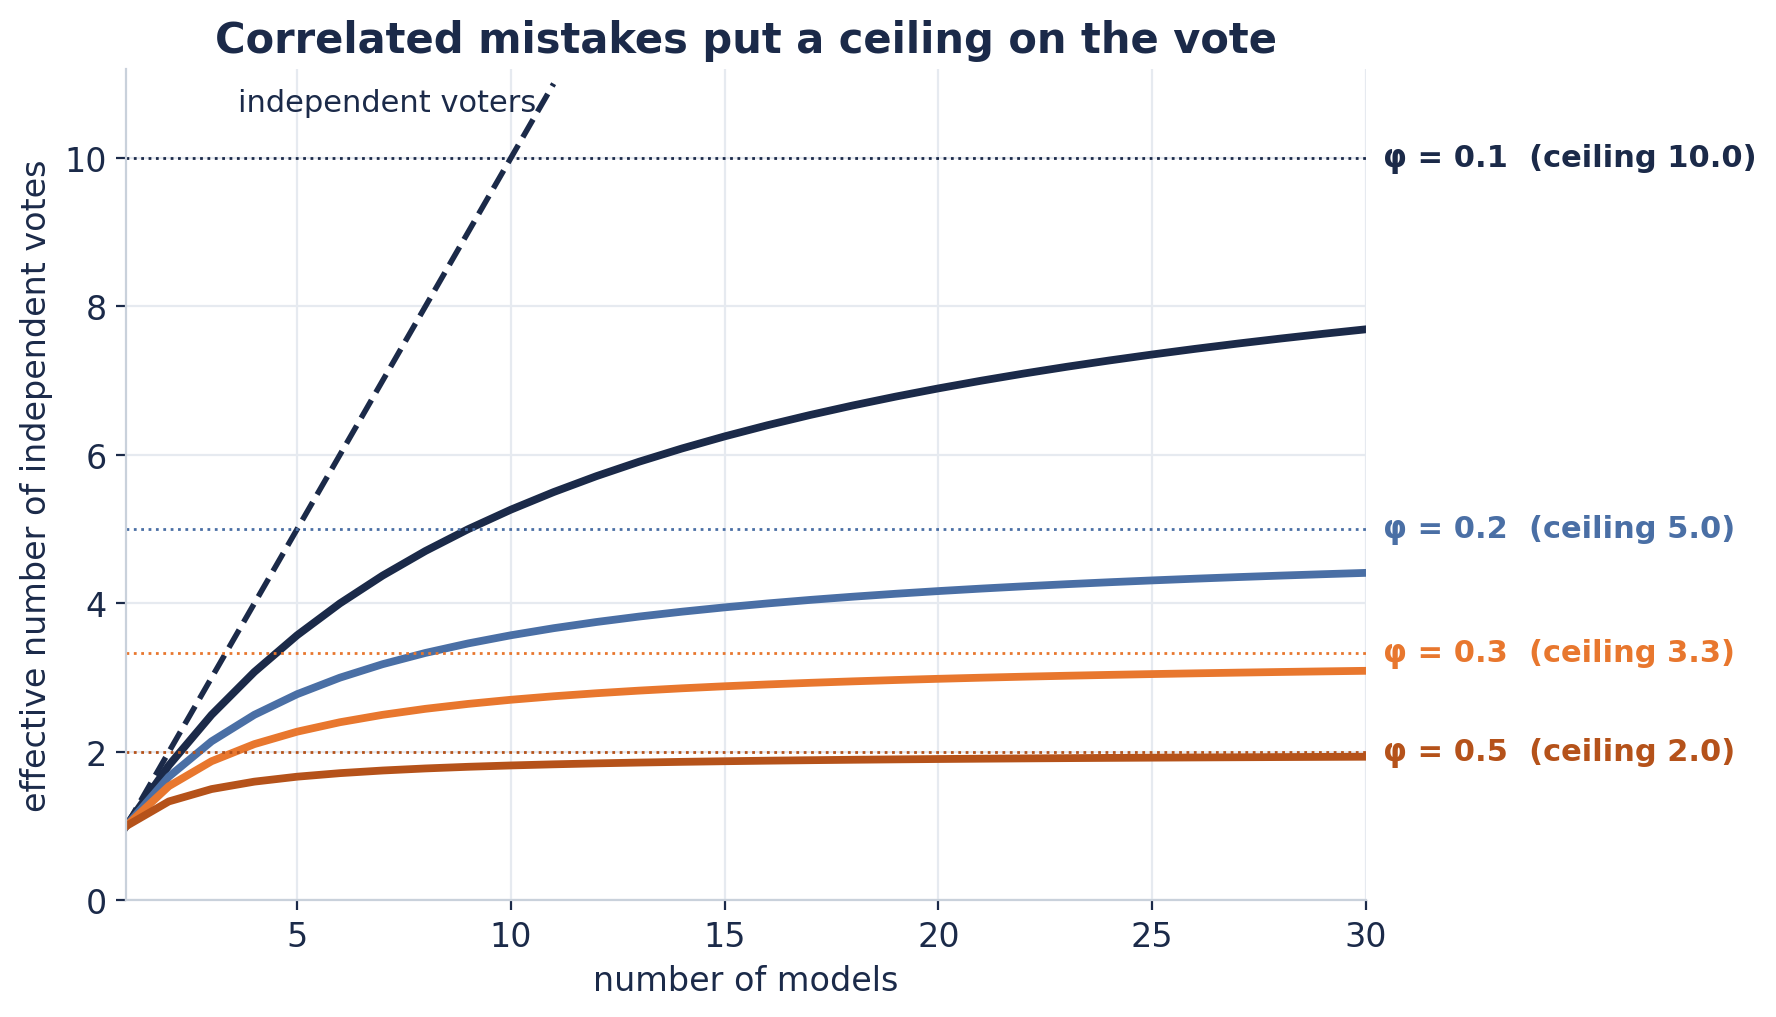
If and each voter counts. As ok grows, and stops there. With , seven fashions are value 2.5 votes, and no variety of further fashions like them could be value greater than 3.3. Survey statisticians use the identical arithmetic for clustered samples, the place is what Kish referred to as the design impact [3].
What a given correlation is value
The formulation is simple to use, so right here it’s as a lookup desk. Rows are the common error correlation, columns are the variety of fashions, and every cell is the variety of efficient votes. The final column is the ceiling that no variety of further fashions can beat.
|
Common error correlation |
3 fashions |
5 fashions |
10 fashions |
Ceiling |
|---|---|---|---|---|
|
0.05 |
2.7 |
4.2 |
6.9 |
20 |
|
0.1 |
2.5 |
3.6 |
5.3 |
10 |
|
0.2 |
2.1 |
2.8 |
3.6 |
5 |
|
0.3 |
1.9 |
2.3 |
2.7 |
3.3 |
|
0.5 |
1.5 |
1.7 |
1.8 |
2 |
A correlation of 0.3 sounds modest, but it makes ten fashions behave like fewer than three. Within the simulation above, the overlapping panel has a median correlation of 0.31, which places its 5 fashions at 2.2 efficient votes.
Determine 3 attracts the identical desk as curves. Each bends towards its ceiling, and the upper the correlation, the earlier it flattens.
What has already been measured
Two current papers measured this on language fashions. Kim et al. in contrast greater than 350 fashions and located that, on one leaderboard dataset, two fashions agree 60% of the time when each are improper, and that bigger, extra correct fashions have extremely correlated errors even throughout builders [4]. Kohli measured panels of LLM judges with a Kish efficient pattern dimension and located that 9 frontier fashions from seven households carried about two unbiased votes’ value of knowledge on natural-language inference [5]. A current put up repeated that measurement with 5 judges on 300 sentence pairs and landed inside Kohli’s vary [6].
I wished a model anybody can rerun and get the identical numbers, as much as floating-point noise, so I used open fashions and browse their solutions as chances as an alternative of sampling them. I additionally added a management for one bias that may pretend settlement: each mannequin will get its personal random order of the reply choices.
The setup
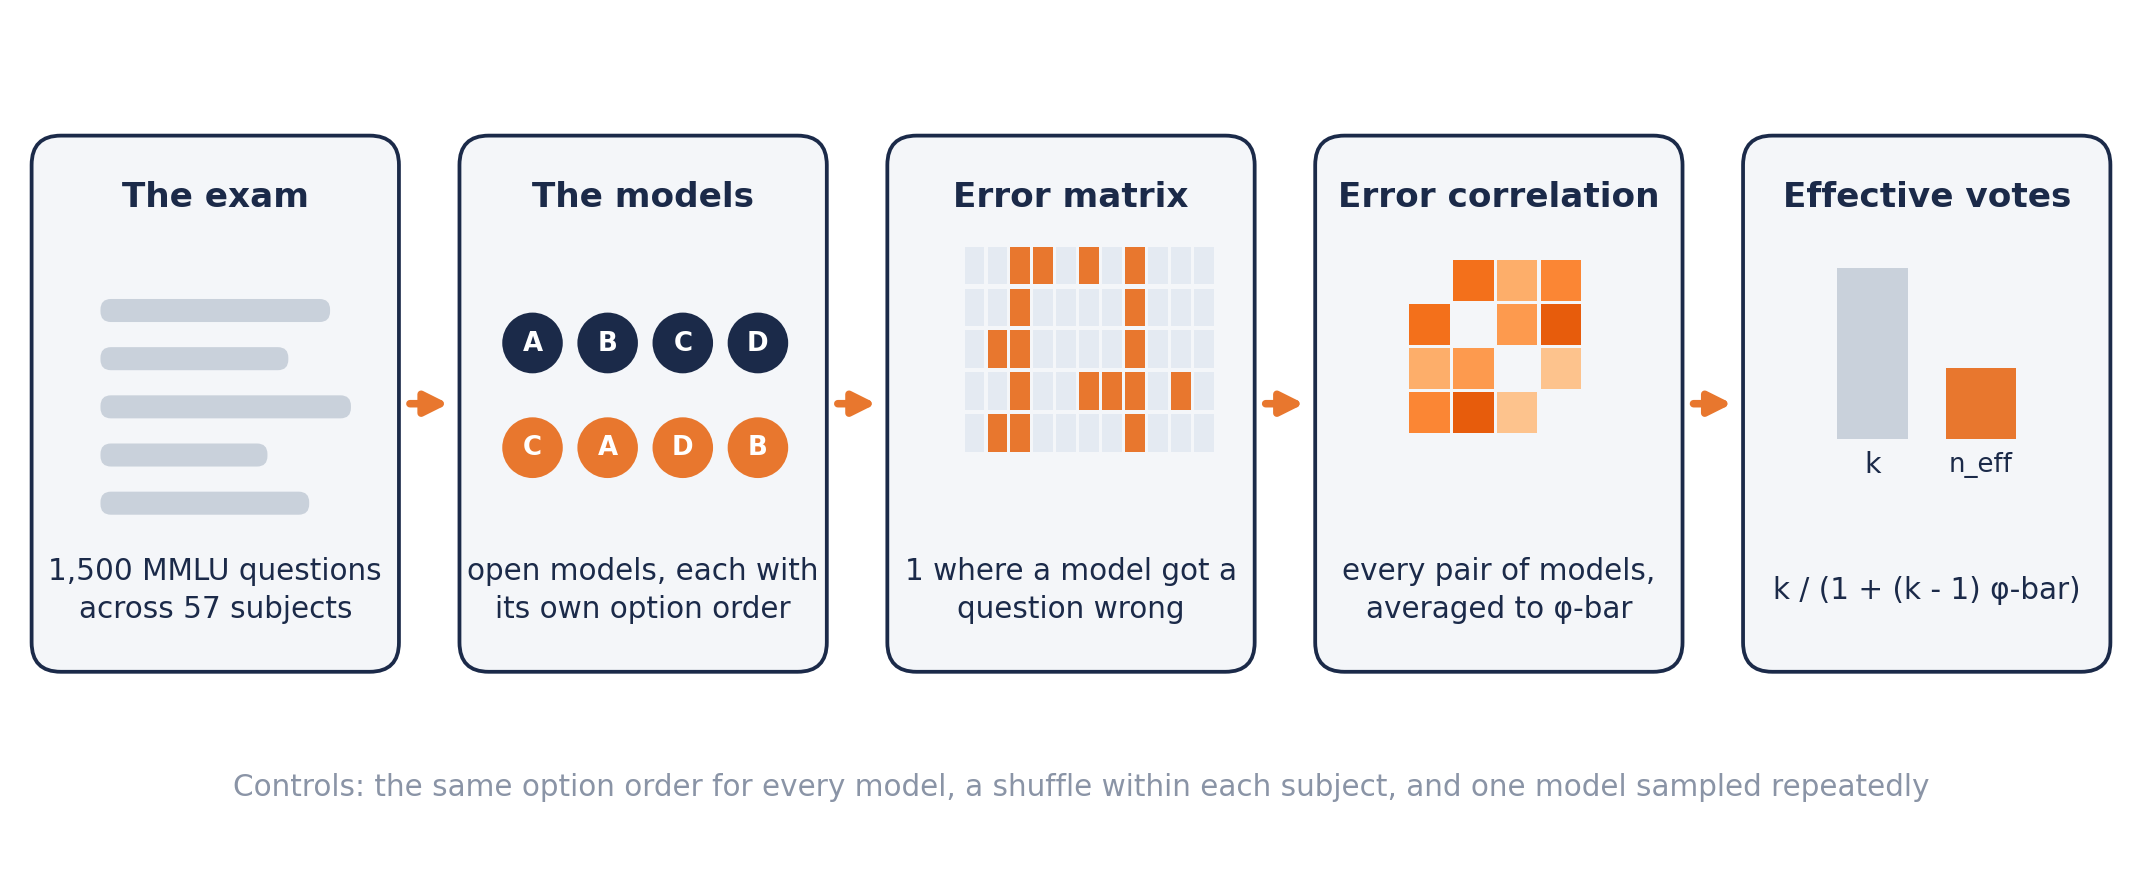
Determine 4 lays out the entire experiment earlier than the main points.
The examination
The check is MMLU, 57 multiple-choice topics that vary from elementary arithmetic to legislation [7]. I drew 1,500 questions unfold evenly over the themes and put aside the questions whose choices refer to one another (‘all the above’), as a result of shuffling the choices would break them.
The fashions
The panel is six open fashions of three to 4 billion parameters from 5 builders (Desk 1). I additionally deliberate to incorporate Llama 3.2 3B, however its gated obtain failed, so it isn’t within the panel. Open weights let me learn precise chances as an alternative of sampling solutions.
Studying solutions with out sampling
Every mannequin will get the usual five-shot MMLU immediate (three or 4 examples for about 3.5% of questions the place 5 wouldn’t slot in 2,048 tokens), and I learn the chance it assigns to the following token being A, B, C or D. Nothing in the primary experiment is sampled, so a rerun ought to give the identical solutions, as much as floating-point noise on near-ties. Precise ties between two choices are uncommon and go to the sooner one.
Eradicating the letter bias
One element issues greater than it seems. Earlier work discovered that LLMs choose explicit possibility letters, largely as a result of the mannequin assigns extra chance to sure letter tokens a priori [8]. Two fashions that each lean towards A would agree on improper solutions for causes unrelated to what they know. To take that out, each mannequin sees every query with its personal random ordering of the choices, and I map its reply again to the unique possibility earlier than evaluating something. The weakest mannequin I attempted exhibits why this issues: a 1-billion-parameter mannequin from AI2 put 74% of its solutions on A or B, regardless that the proper reply was equally prone to land on any letter. As a management, I additionally ran everybody on the unique order.
The measurement
The measurement itself is a couple of traces:
The perform does 4 issues. It marks each improper reply, correlates these marks for each pair of fashions, averages the pair correlations, and places that common into the formulation. Every little thing else I ran (the prompts, the choice shuffling, the bootstrap intervals) is plumbing round it.
How usually do they fail collectively?
Desk 1. Accuracy on 1,500 MMLU questions, with every mannequin proven its personal random possibility order. Intervals are 95% Wilson intervals. The final row was neglected of the panel evaluation as a result of it scored beneath 50%.
|
Mannequin |
Developer |
Accuracy |
95% interval |
|---|---|---|---|
|
Qwen3-4B |
Qwen |
72.7% |
70.4 to 74.9 |
|
Phi-4-mini-instruct |
Microsoft |
67.5% |
65.1 to 69.8 |
|
Qwen2.5-3B-Instruct |
Qwen |
67.3% |
64.9 to 69.6 |
|
Granite 4.1 3B |
IBM |
66.5% |
64.0 to 68.8 |
|
SmolLM3-3B |
Hugging Face |
60.9% |
58.4 to 63.3 |
|
Falcon3-3B-Instruct |
TII |
58.3% |
55.8 to 60.7 |
|
OLMo-2-0425-1B-Instruct |
AI2 |
40.0% |
37.5 to 42.5 |
Essentially the most correct mannequin within the panel scores 72.7% and the least correct 58.3%, in opposition to 25% for guessing amongst 4 choices. Determine 5 is a seating chart of the panel: every cell is one pair of fashions, and the darker it’s, the extra usually these two miss the identical questions.
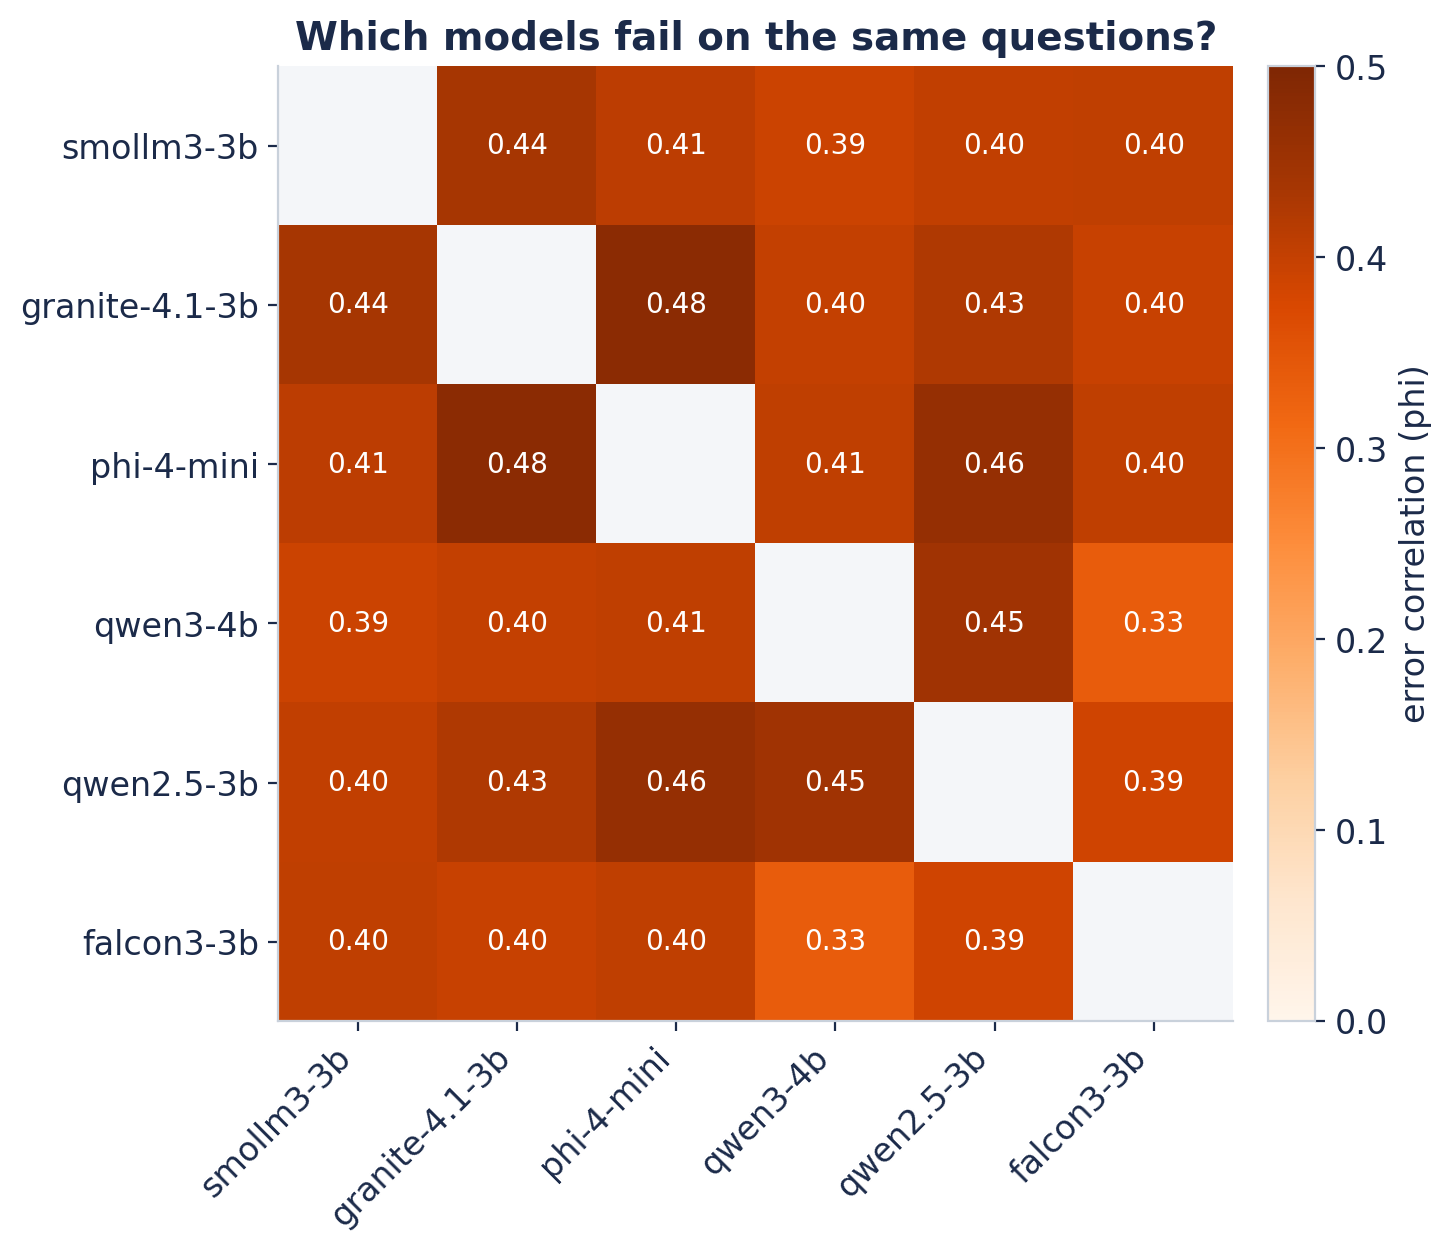
The common pairwise error correlation, which I’ll write as , is 0.41 (95% bootstrap interval 0.39 to 0.44), the place 0 would imply the errors are unrelated. No pair is wherever close to 0: all 15 fall between 0.33 and 0.48. The one pair from the identical developer, Qwen2.5 and Qwen3, sits at 0.45, and the 14 pairs from totally different builders common 0.41. When two fashions are each improper, they select the identical improper reply 59% of the time, near the 60% that Kim et al. report for one leaderboard dataset [4]. Random improper solutions would agree a couple of third of the time.
What number of votes did the panel solid?
Placing into the formulation, the six fashions are value unbiased votes (95% interval 1.88 to 2.04). A second estimate that doesn’t assume each pair is equally correlated, ok divided by the most important eigenvalue of the correlation matrix, offers 1.96 as nicely. Determine 6 exhibits for each panel dimension, with the ceiling = 2.4 because the dotted line. Every added mannequin contributes lower than the one earlier than: going from one mannequin to 2 provides 0.4 efficient votes, and going from 5 to 6 provides 0.07.
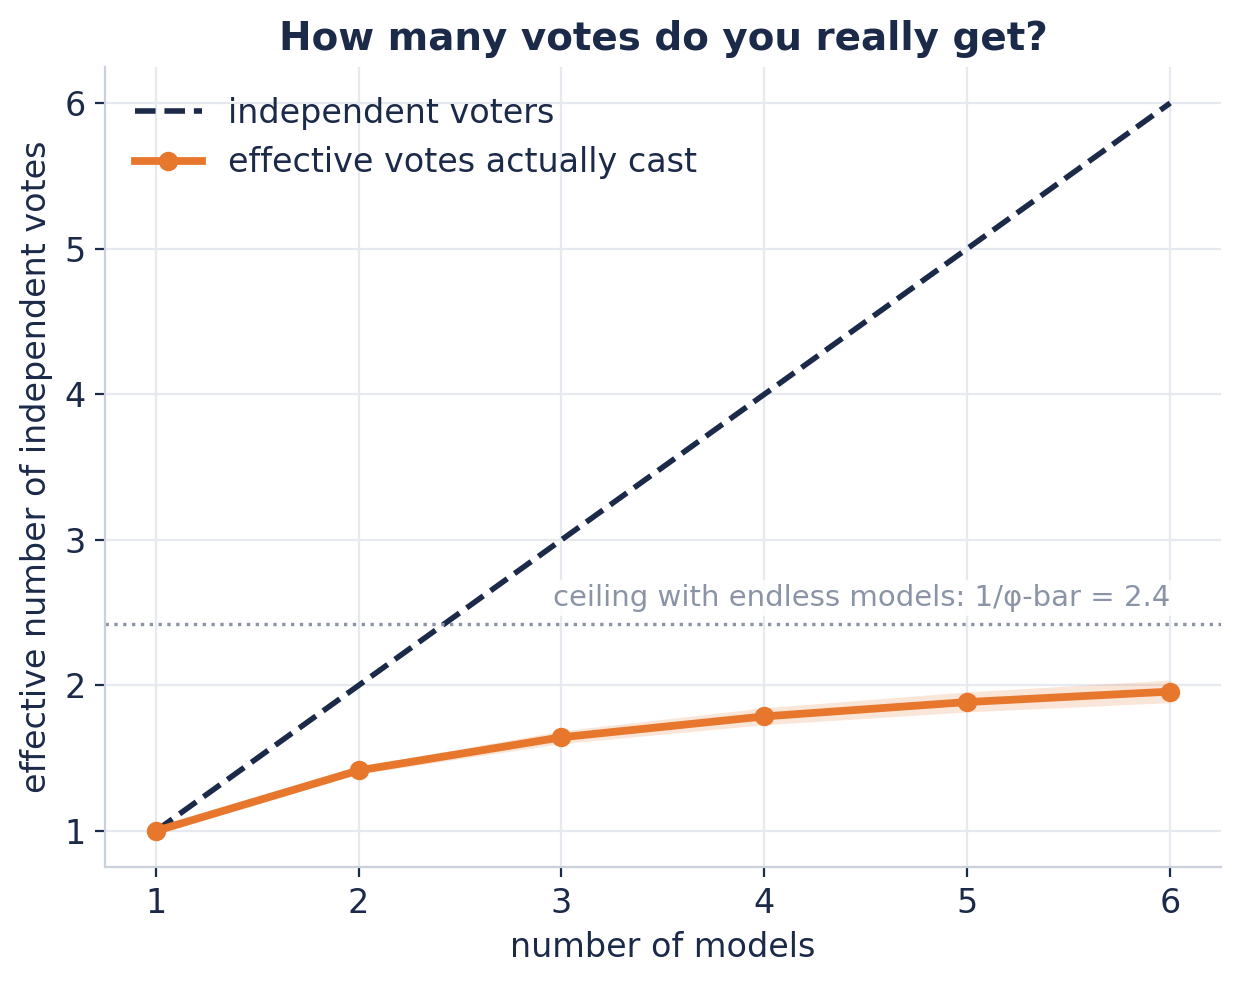
Votes solely matter if they alter the reply, so I additionally ran the vote. For each potential panel of every dimension I took the commonest reply and in contrast its accuracy with what unbiased voters of the identical particular person accuracy would rating. I computed that baseline precisely, assuming a voter who’s improper picks uniformly among the many three improper choices, and I used odd panel sizes in order that ties don’t blur the image.
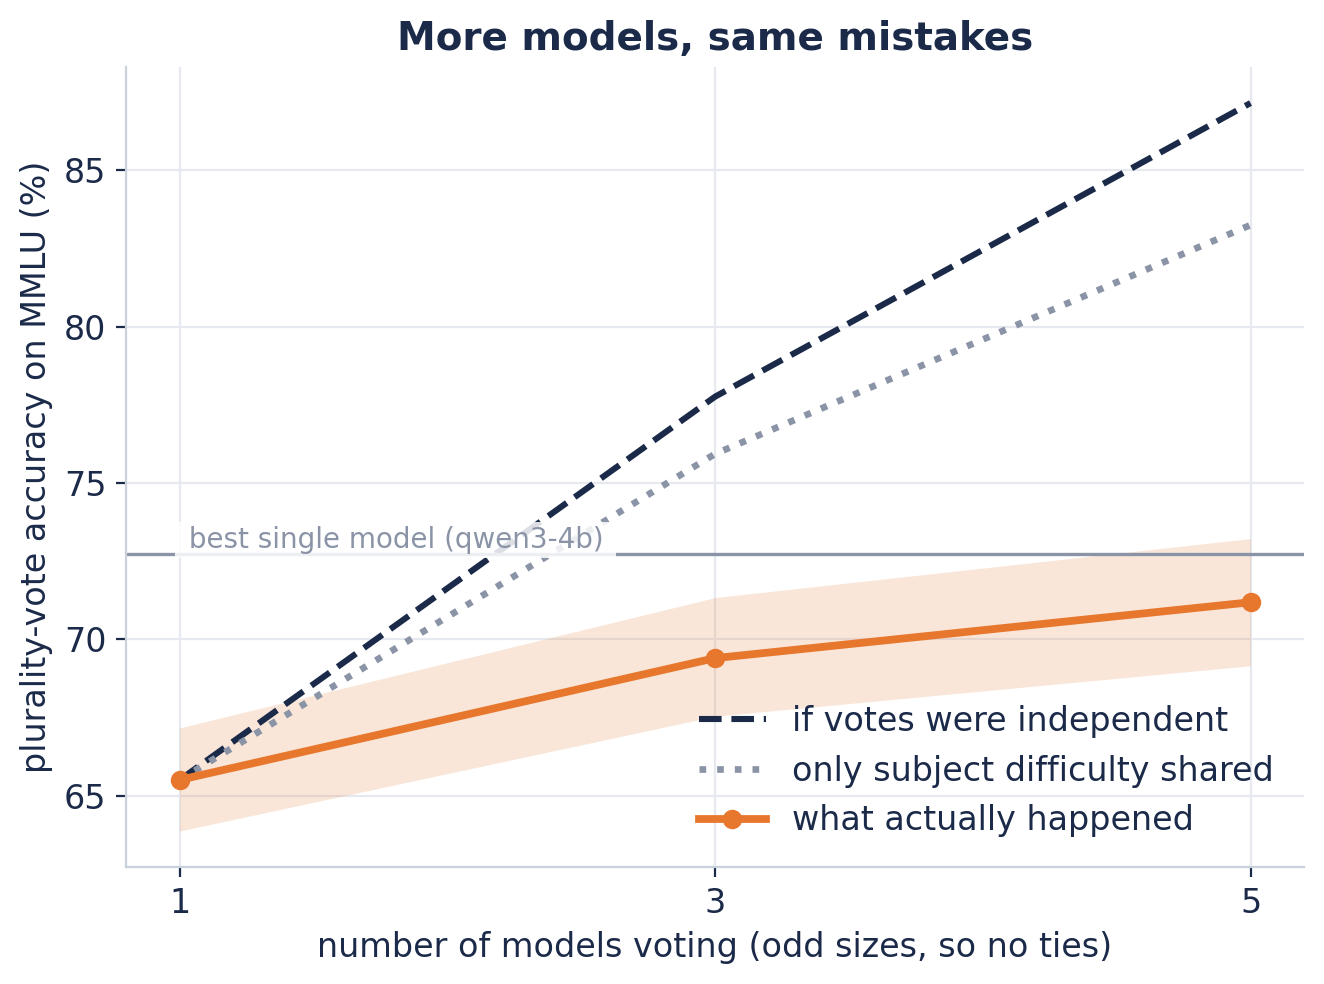
With 5 fashions the unbiased baseline is 87.1% and the actual vote scored 71.2% (95% interval 69.2 to 73.2), a niche of about 16 factors. All six fashions collectively scored 71.8%, in opposition to 90.3% for unbiased voters.
The very best single mannequin, Qwen3-4B, scored 72.7%, and not one of the 57 potential panels of two to 6 fashions beat it when every mannequin casts one vote. The very best panel, three fashions, tied it at 1,091 of 1,500 questions.
Counting solely every mannequin’s best choice throws info away, so I additionally tried averaging the fashions’ chances. That does higher: all six collectively attain 73.8%, a achieve of 1.1 factors over Qwen3-4B with a 95% interval of -0.8 to three.0 factors, and the very best of the 57 panels, picked after the actual fact, reaches 74.1%. Neither is distinguishable from the very best mannequin alone, and each fall nicely in need of the 90% that unbiased voters would attain by plain voting.
All six fashions agreed on 35.8% of the questions, and once they did the shared reply was improper 5.8% of the time (31 of 537 questions). Impartial voters would agree on solely 7.8% of the questions, and could be improper 0.008% of the time once they did. All six fashions had been improper on 112 questions (7.5%), which unbiased voters with the identical accuracies would handle on about two.
The place the shared error comes from
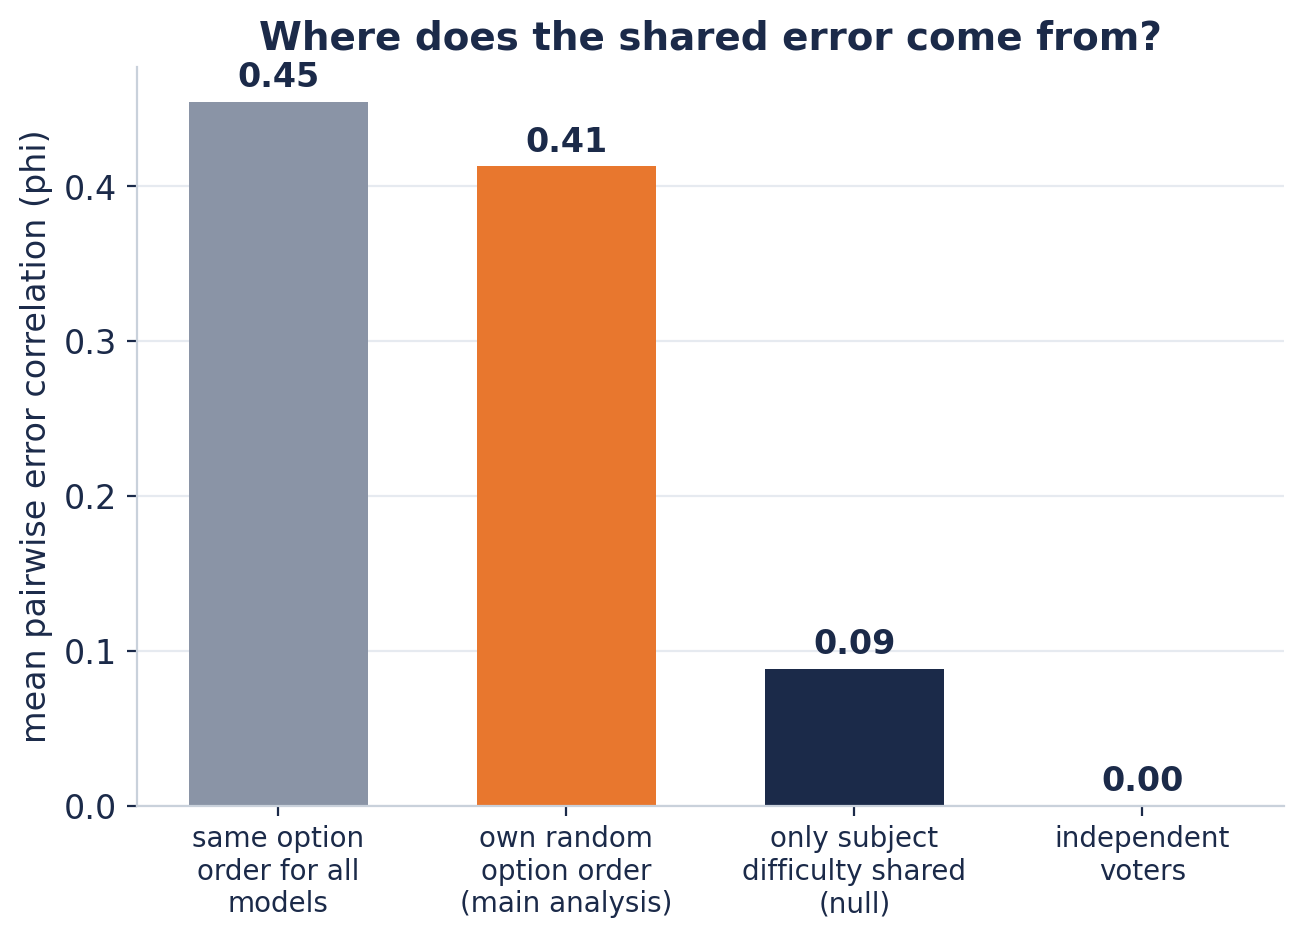
A few of this correlation is no surprise. A tough topic is tough for each mannequin, and that alone produces correlated errors. To see how a lot, I shuffled every mannequin’s outcomes throughout questions inside every topic, individually for each mannequin. That retains each mannequin’s precise accuracy in each topic and destroys any settlement on particular person questions. With solely topic issue left, the common error correlation falls from 0.41 to 0.09, so topic issue accounts for a couple of fifth of it and many of the relaxation sits on the stage of particular person questions.
Determine 8 places that subsequent to the letter-bias management. With a shared possibility order the common correlation is 0.45, in opposition to 0.41 when every mannequin sees its personal random order. The hole between these two bars is what sharing the choice order provides, about 0.04, and a paired bootstrap places that distinction between 0.02 and 0.06. Letter preferences had been delicate contained in the panel: no mannequin put greater than 30% of its solutions on anyone letter, the place a good break up is 25%.
What this can’t do is separate a shared blind spot from a query that’s merely arduous for everybody, as a result of each seem like a number of fashions failing on the identical merchandise. The benchmark provides its personal noise: an estimated 6.49% of MMLU questions comprise errors [9], and a improper reply key marks each mannequin that is aware of higher as improper collectively.
What in the event you ask one mannequin many instances?
Self-consistency samples a number of solutions from one mannequin and retains the commonest one [10]. An affordable stand-in is to attract the reply letter from every mannequin’s personal chances, a number of instances, and vote. Determine 9 compares that with voting throughout totally different fashions.
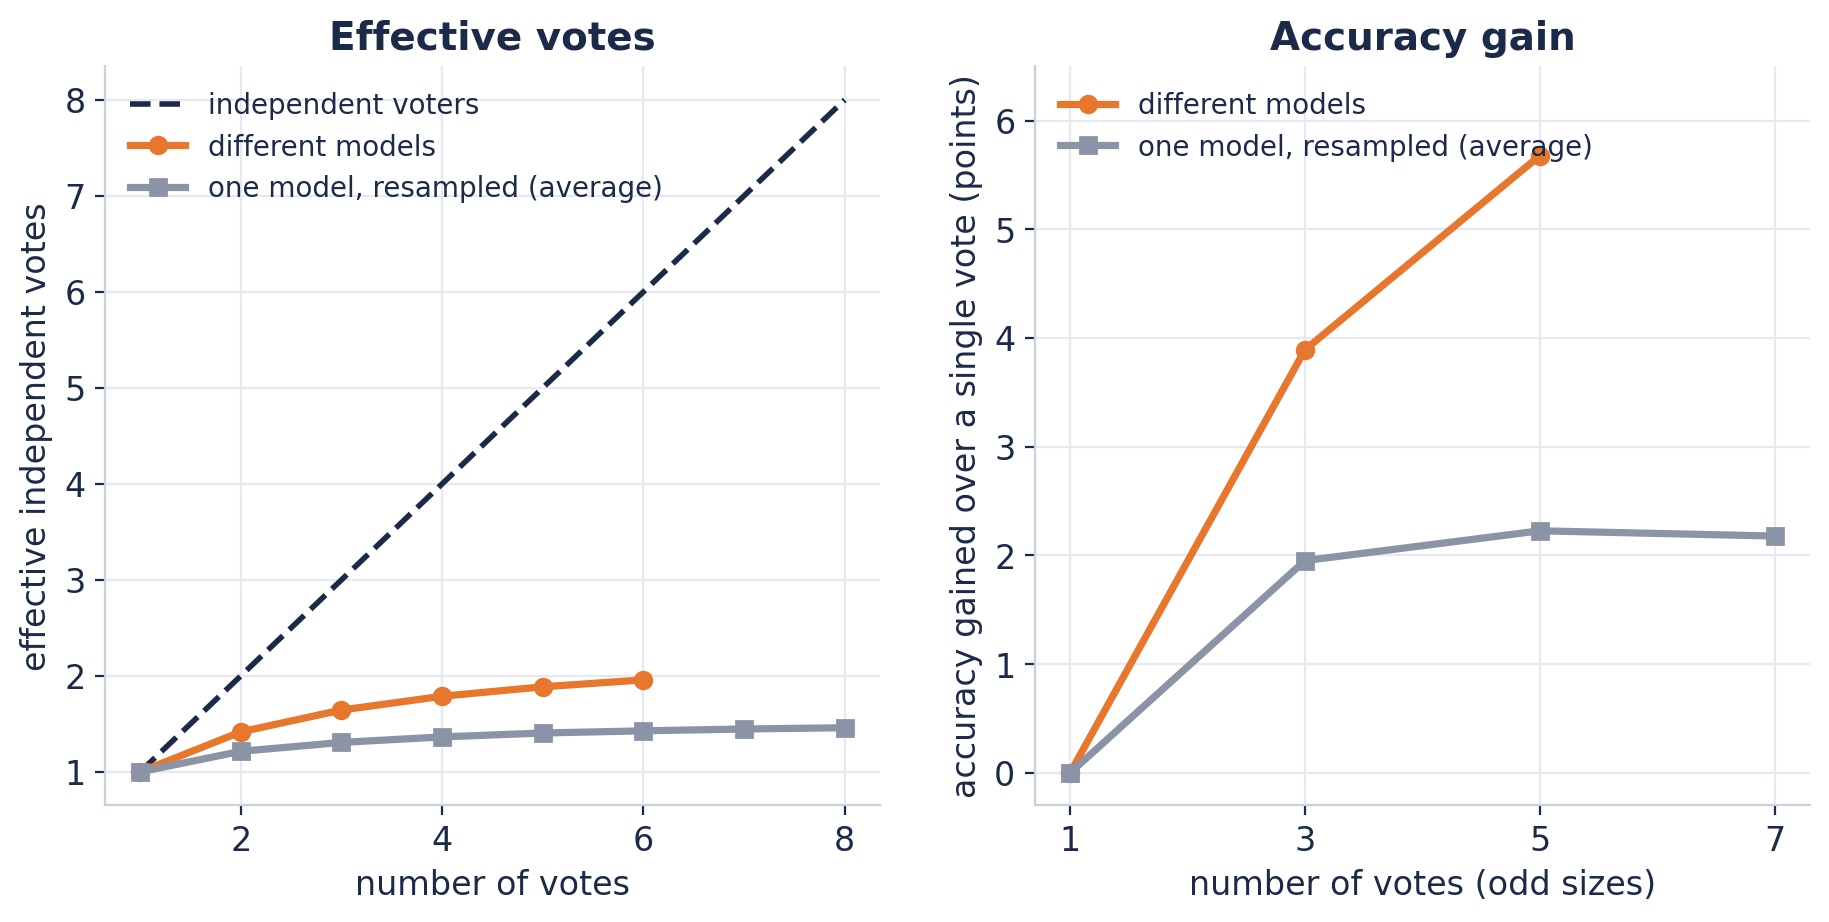
Six samples from one mannequin are value 1.4 efficient votes on common (vary 1.3 to 1.7), and eight samples are value 1.5, in opposition to 2.0 for six totally different fashions. The accuracy achieve tells the identical story. A vote of 5 samples from one mannequin positive factors 2.2 factors over a single pattern’s anticipated accuracy on common (vary 1.3 to three.6), whereas 5 totally different fashions achieve 5.7 factors over the common single mannequin. The best panel of Determine 9 exhibits positive factors moderately than accuracy ranges, as a result of a sampled reply is much less correct than a mannequin’s best choice and the 2 traces would in any other case begin somewhere else.
A letter drawn from a chance shouldn’t be a sampled chain of thought, and actual self-consistency samples reasoning paths. This comparability says little about how nicely actual self-consistency works. It solely compares two sources of votes beneath the identical plain readout.
What this does and doesn’t say about agent groups
Vals examined groups that break up a job into components [1]. I examined voters who reply the identical query, on multiple-choice exams, with small open fashions. None of it is a verdict on agent groups. What carries over is the arithmetic: a vote is definitely worth the unbiased info behind it, and the quantity that measures that may be computed on any labeled set the place every mannequin’s errors are recorded.
When you run a panel of judges, or a crew wherein brokers examine one another’s work, compute on a couple of hundred gadgets with recognized solutions earlier than including a member. A brand new mannequin from a distinct developer shouldn’t be routinely a brand new opinion. On this panel, switching builders lowered the error correlation solely just a little (0.45 for the one same-developer pair, 0.41 on common throughout builders), and no pair of fashions fell beneath 0.33. One same-developer pair is simply too few to say how far that generalizes. The ceiling additionally says the place to cease including voters and begin including one thing else: a software name, a retrieval step, a check that may really be run, an individual.
Frontier fashions behind APIs, chain-of-thought solutions rather than letter chances, and the manually re-checked subset of MMLU [9] would every change these numbers in methods I am unable to predict from this run.
Counting fashions is simple. Counting what number of of them might be improper in several methods takes one correlation matrix, and it’s value computing earlier than the following mannequin joins the panel.
···
References
[1] Katrina Drozdov, Do Agent Groups Pay Off? A Case Research on Vibe Code Bench (2026), Vals AI. https://www.vals.ai/blogs/multi-agent-vibe-code-bench
[2] Marquis de Condorcet, Essai sur l’software de l’analyse à la probabilité des décisions rendues à la pluralité des voix (1785), Imprimerie Royale
[3] Leslie Kish, Survey Sampling (1965), John Wiley & Sons
[4] Elliot Myunghoon Kim, Avi Garg, Kenny Peng, Nikhil Garg, Correlated Errors in Massive Language Fashions (2025), ICML 2025. https://arxiv.org/abs/2506.07962
[5] Guneet Kohli, 9 Judges, Two Efficient Votes: Correlated Errors Undermine LLM Analysis Panels (2026), arXiv. https://arxiv.org/abs/2605.29800
[6] David J. Knudson, My 4 AI Judges Have been Price 1.6 Votes (2026), Stage Up Coding. https://levelup.gitconnected.com/my-four-ai-judges-were-worth-1-6-votes-96a84e337405
[7] Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Daybreak Music, Jacob Steinhardt, Measuring Huge Multitask Language Understanding (2021), ICLR 2021. https://arxiv.org/abs/2009.03300 (MIT license)
[8] Chujie Zheng, Hao Zhou, Fandong Meng, Jie Zhou, Minlie Huang, Massive Language Fashions Are Not Strong A number of Selection Selectors (2024), ICLR 2024. https://arxiv.org/abs/2309.03882
[9] Aryo Pradipta Gema et al., Are We Carried out with MMLU? (2025), NAACL 2025. https://arxiv.org/abs/2406.04127
[10] Xuezhi Wang et al., Self-Consistency Improves Chain of Thought Reasoning in Language Fashions (2023), ICLR 2023. https://arxiv.org/abs/2203.11171