Information is essentially the most priceless half of machine studying. The extra various, task-specific information you will have, the higher you possibly can match a mannequin to your goal. However it’s not all the time straightforward to gather this information and/or label it in response to your necessities. You would possibly must manually seize information whereas ensuring to not introduce any biases into your dataset or confirm annotations from a 3rd social gathering, or these days somewhat confirm the annotations of the VLM you used for pre-annotating.
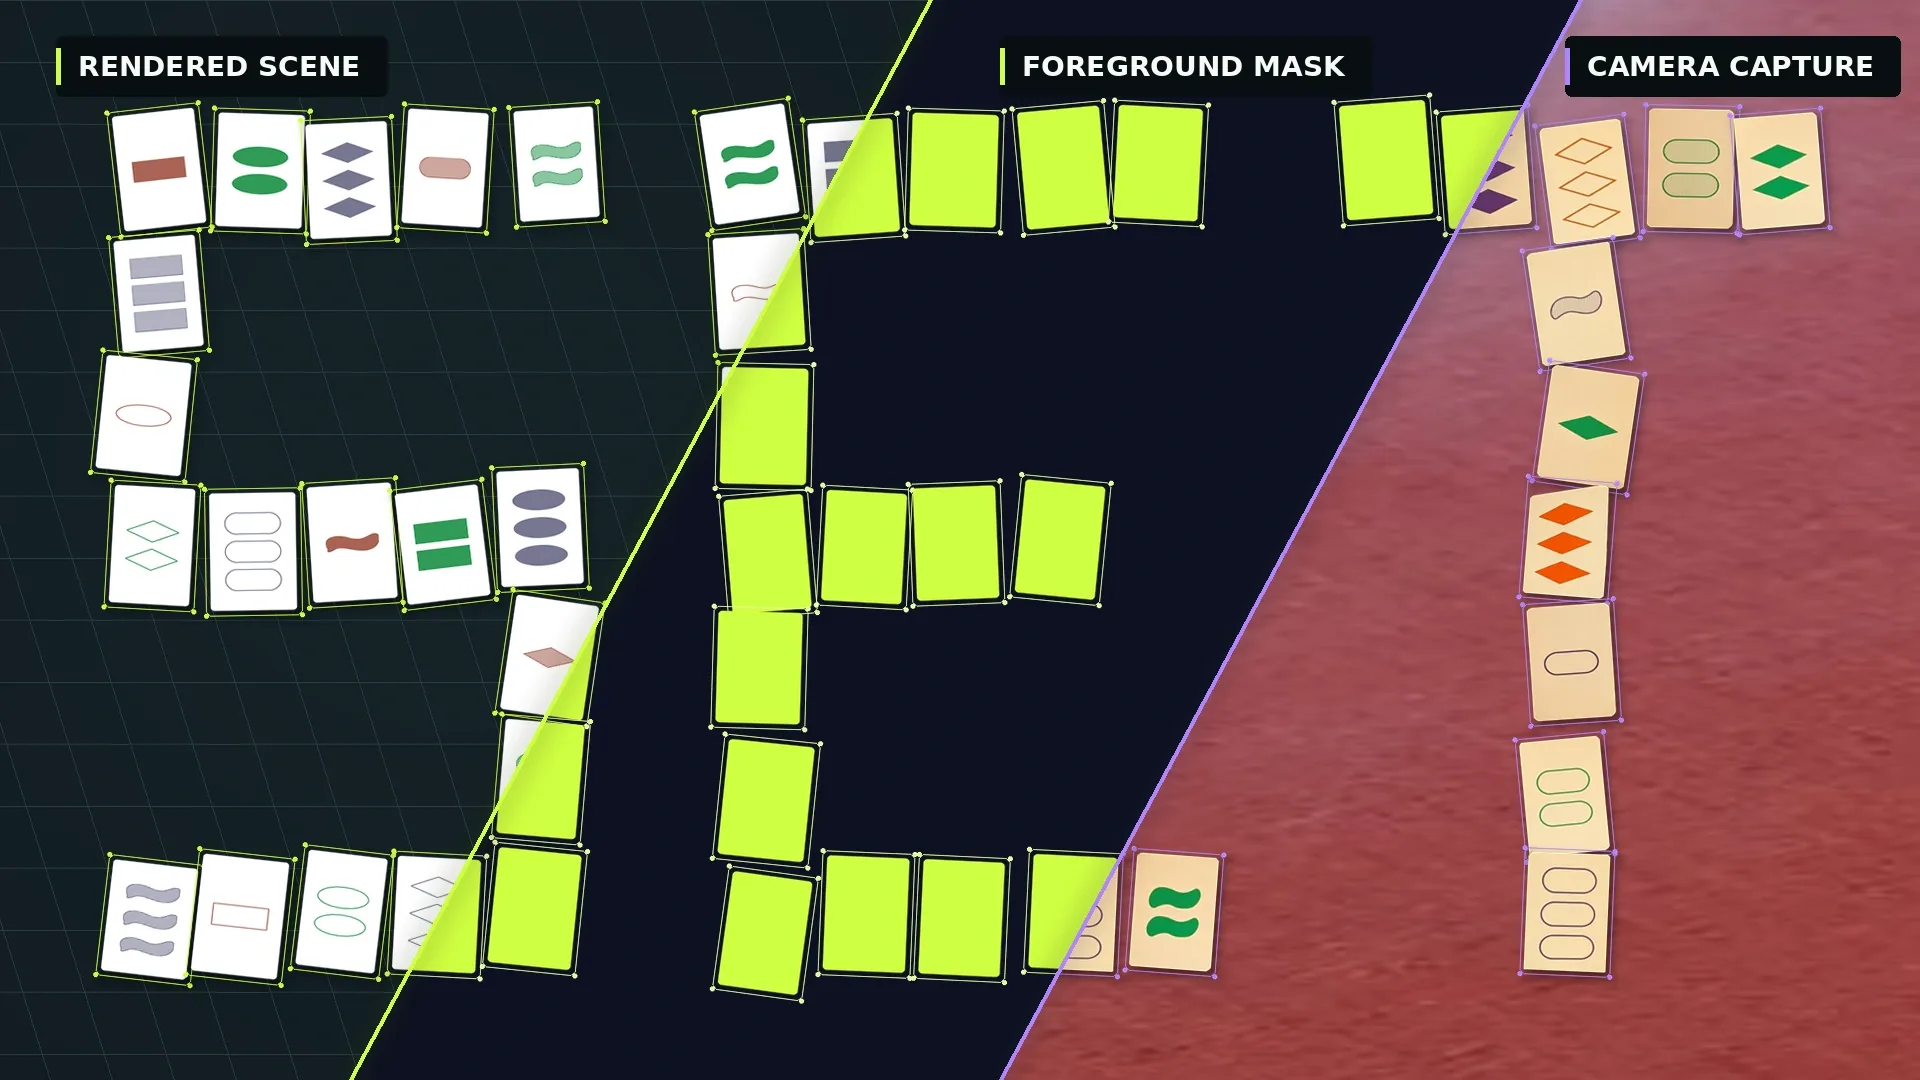
An effective way to get to a whole lot of information with excellent labels is to synthetically generate the info. This manner, you possibly can have already got the bottom fact annotation by design. An enormous problem with doing this for pc imaginative and prescient duties is how properly this artificial information can be utilized to coach fashions that generalize to real-world information. On this mission, I needed to discover if we are able to use a state-of-the-art pre-trained function extractor that generates wealthy function representations and practice completely different heads on solely artificial information that then generalize to actual information.
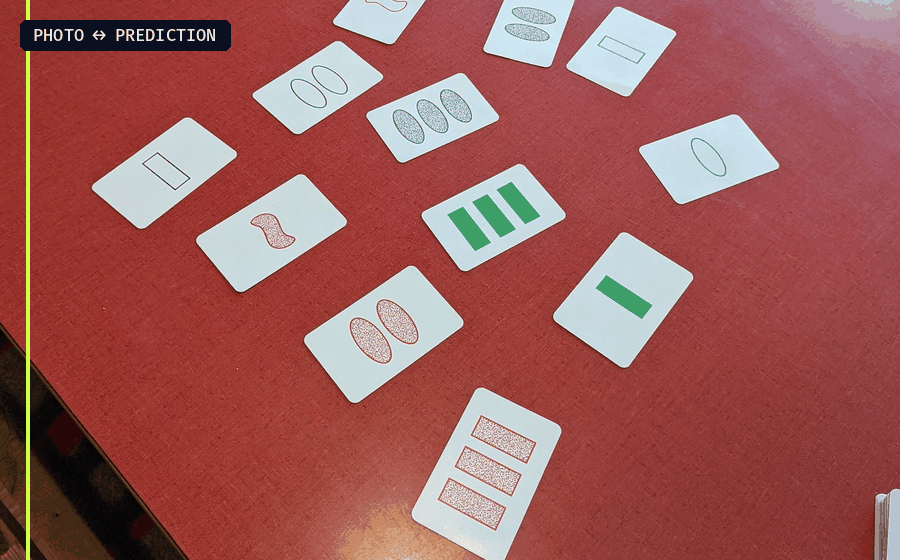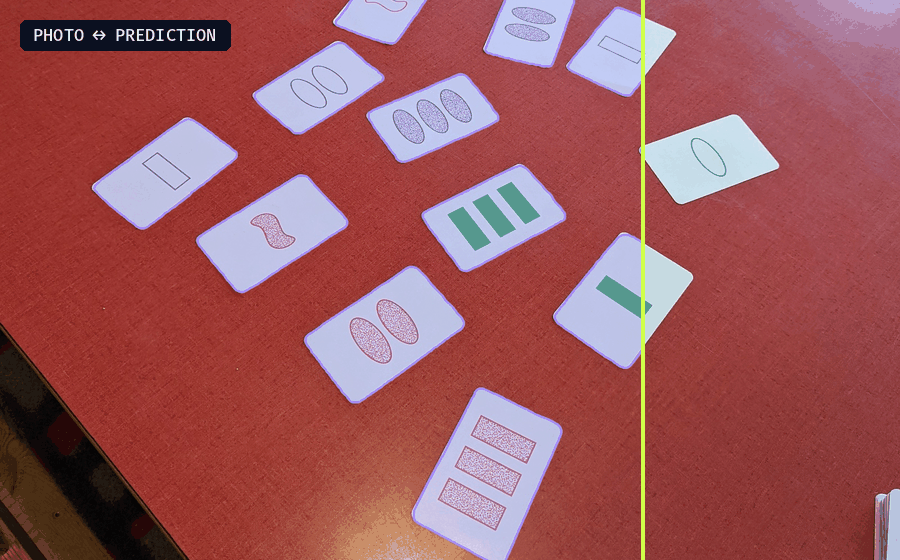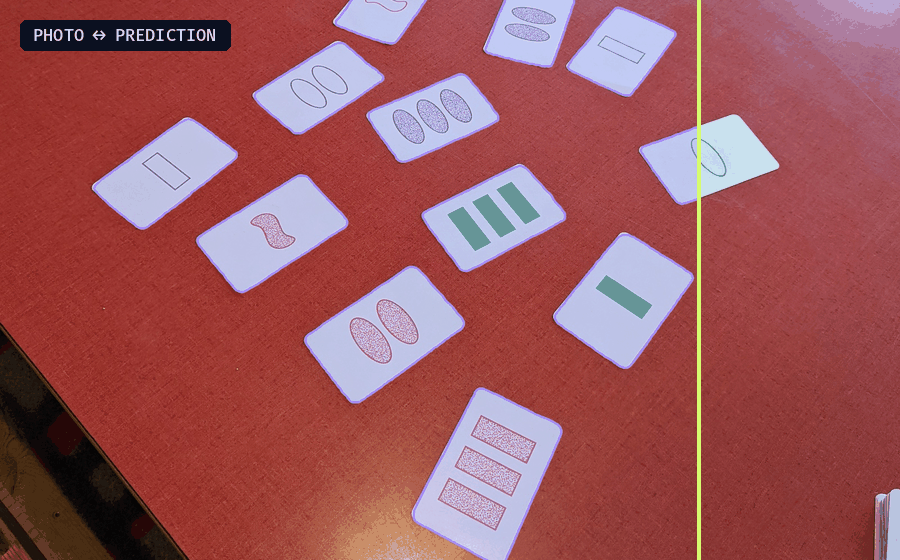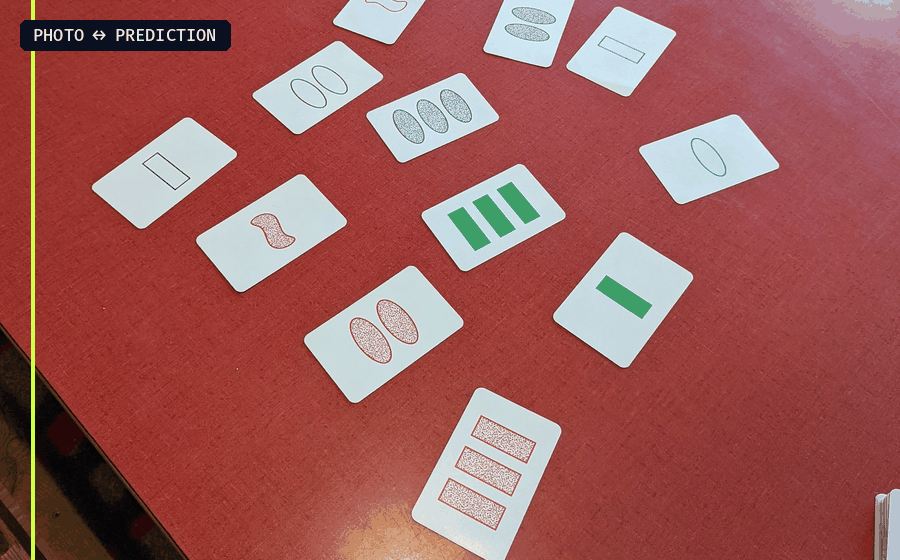
Process
I wanted a website the place producing the objects of curiosity is just not too sophisticated, however I additionally needed to maintain it considerably fascinating. So I discovered a pleasant center floor, these enjoying playing cards from this sport known as SET. The aim of the sport is to detect triplets of playing cards (known as units) in a sport subject of 4×3, the place each function (form, colour, shading and depend) must be both equivalent throughout all three playing cards or completely different on each card.
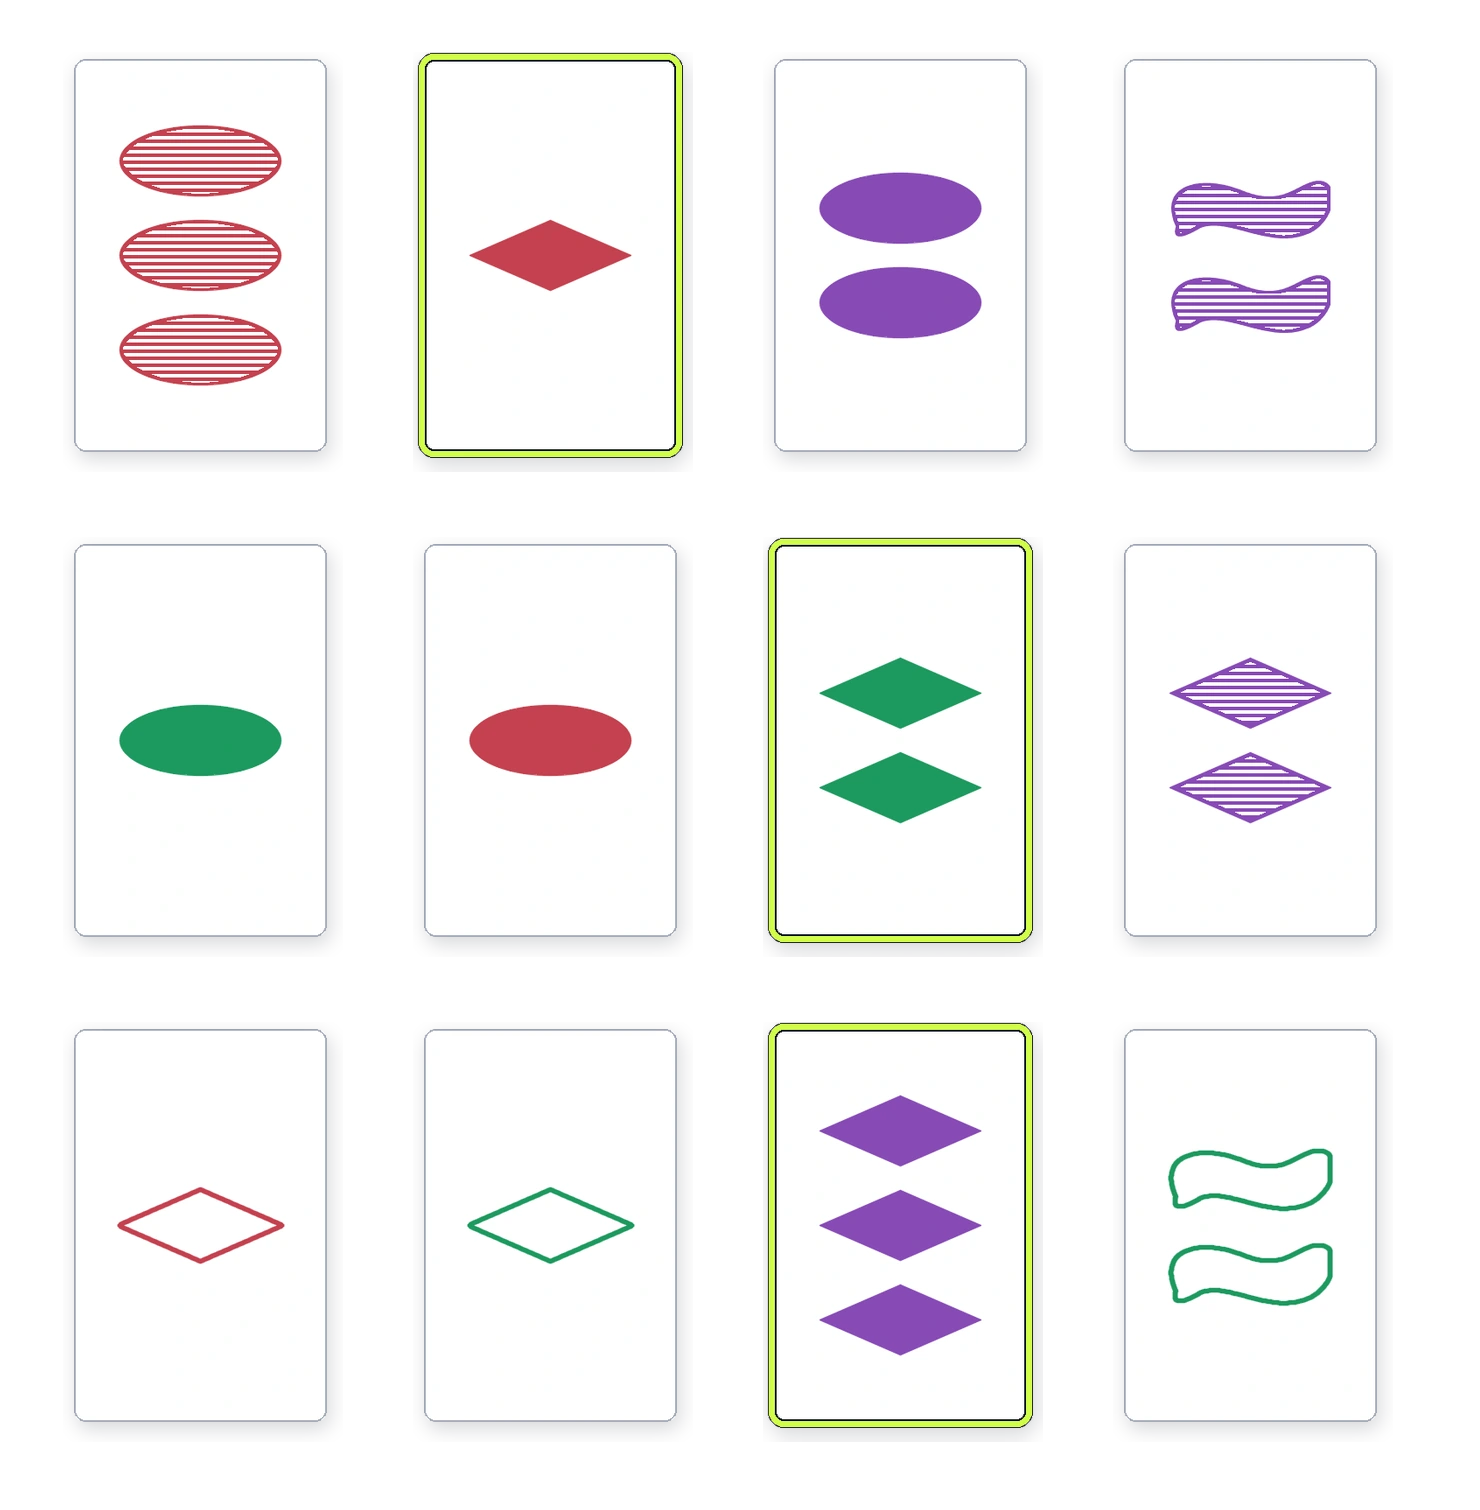
One other instance of a triplet set, the place all properties are completely different
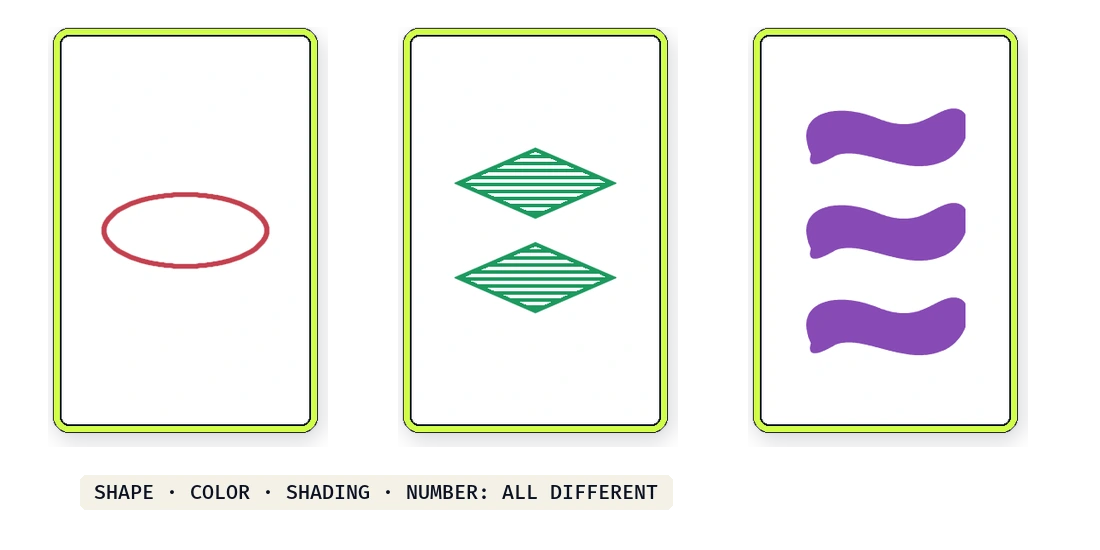
Throughout the sport, the primary participant to identify a triplet set first yells “SET” after which collects these 3 playing cards, whereas they get changed with three new playing cards from the deck, till there are not any extra playing cards left. The participant with essentially the most playing cards wins.
Mannequin Structure
I needed to make use of a small mannequin for this mission so I can practice it by myself PC’s GPU, however I nonetheless needed a wealthy function illustration. I ended up selecting the newest DINOv3 mannequin from Meta, because it has the most effective localized function extraction performances and has a few distilled smaller variations. Utilizing their distillation methodology, they have been even in a position to distill the information realized by the massive transformer mannequin into convolutional architectures:
ConvNeXt fashions pretrained on internet dataset (LVD-1689M):
|
Mannequin |
Parameters |
Pretraining |
Obtain |
|---|---|---|---|
|
ConvNeXt Tiny |
29M |
LVD-1689M |
https://towardsdatascience.com/synthetic-to-real-transfer-with-frozen-dinov3-features/ |
|
ConvNeXt Small |
50M |
LVD-1689M |
https://towardsdatascience.com/synthetic-to-real-transfer-with-frozen-dinov3-features/ |
|
ConvNeXt Base |
89M |
LVD-1689M |
https://towardsdatascience.com/synthetic-to-real-transfer-with-frozen-dinov3-features/ |
|
ConvNeXt Massive |
198M |
LVD-1689M |
https://towardsdatascience.com/synthetic-to-real-transfer-with-frozen-dinov3-features/ |
I went with the smallest convolutional mannequin ConvNeXt Tiny, on account of restricted {hardware} and the nonetheless distinctive efficiency of even this tiniest distilled mannequin.
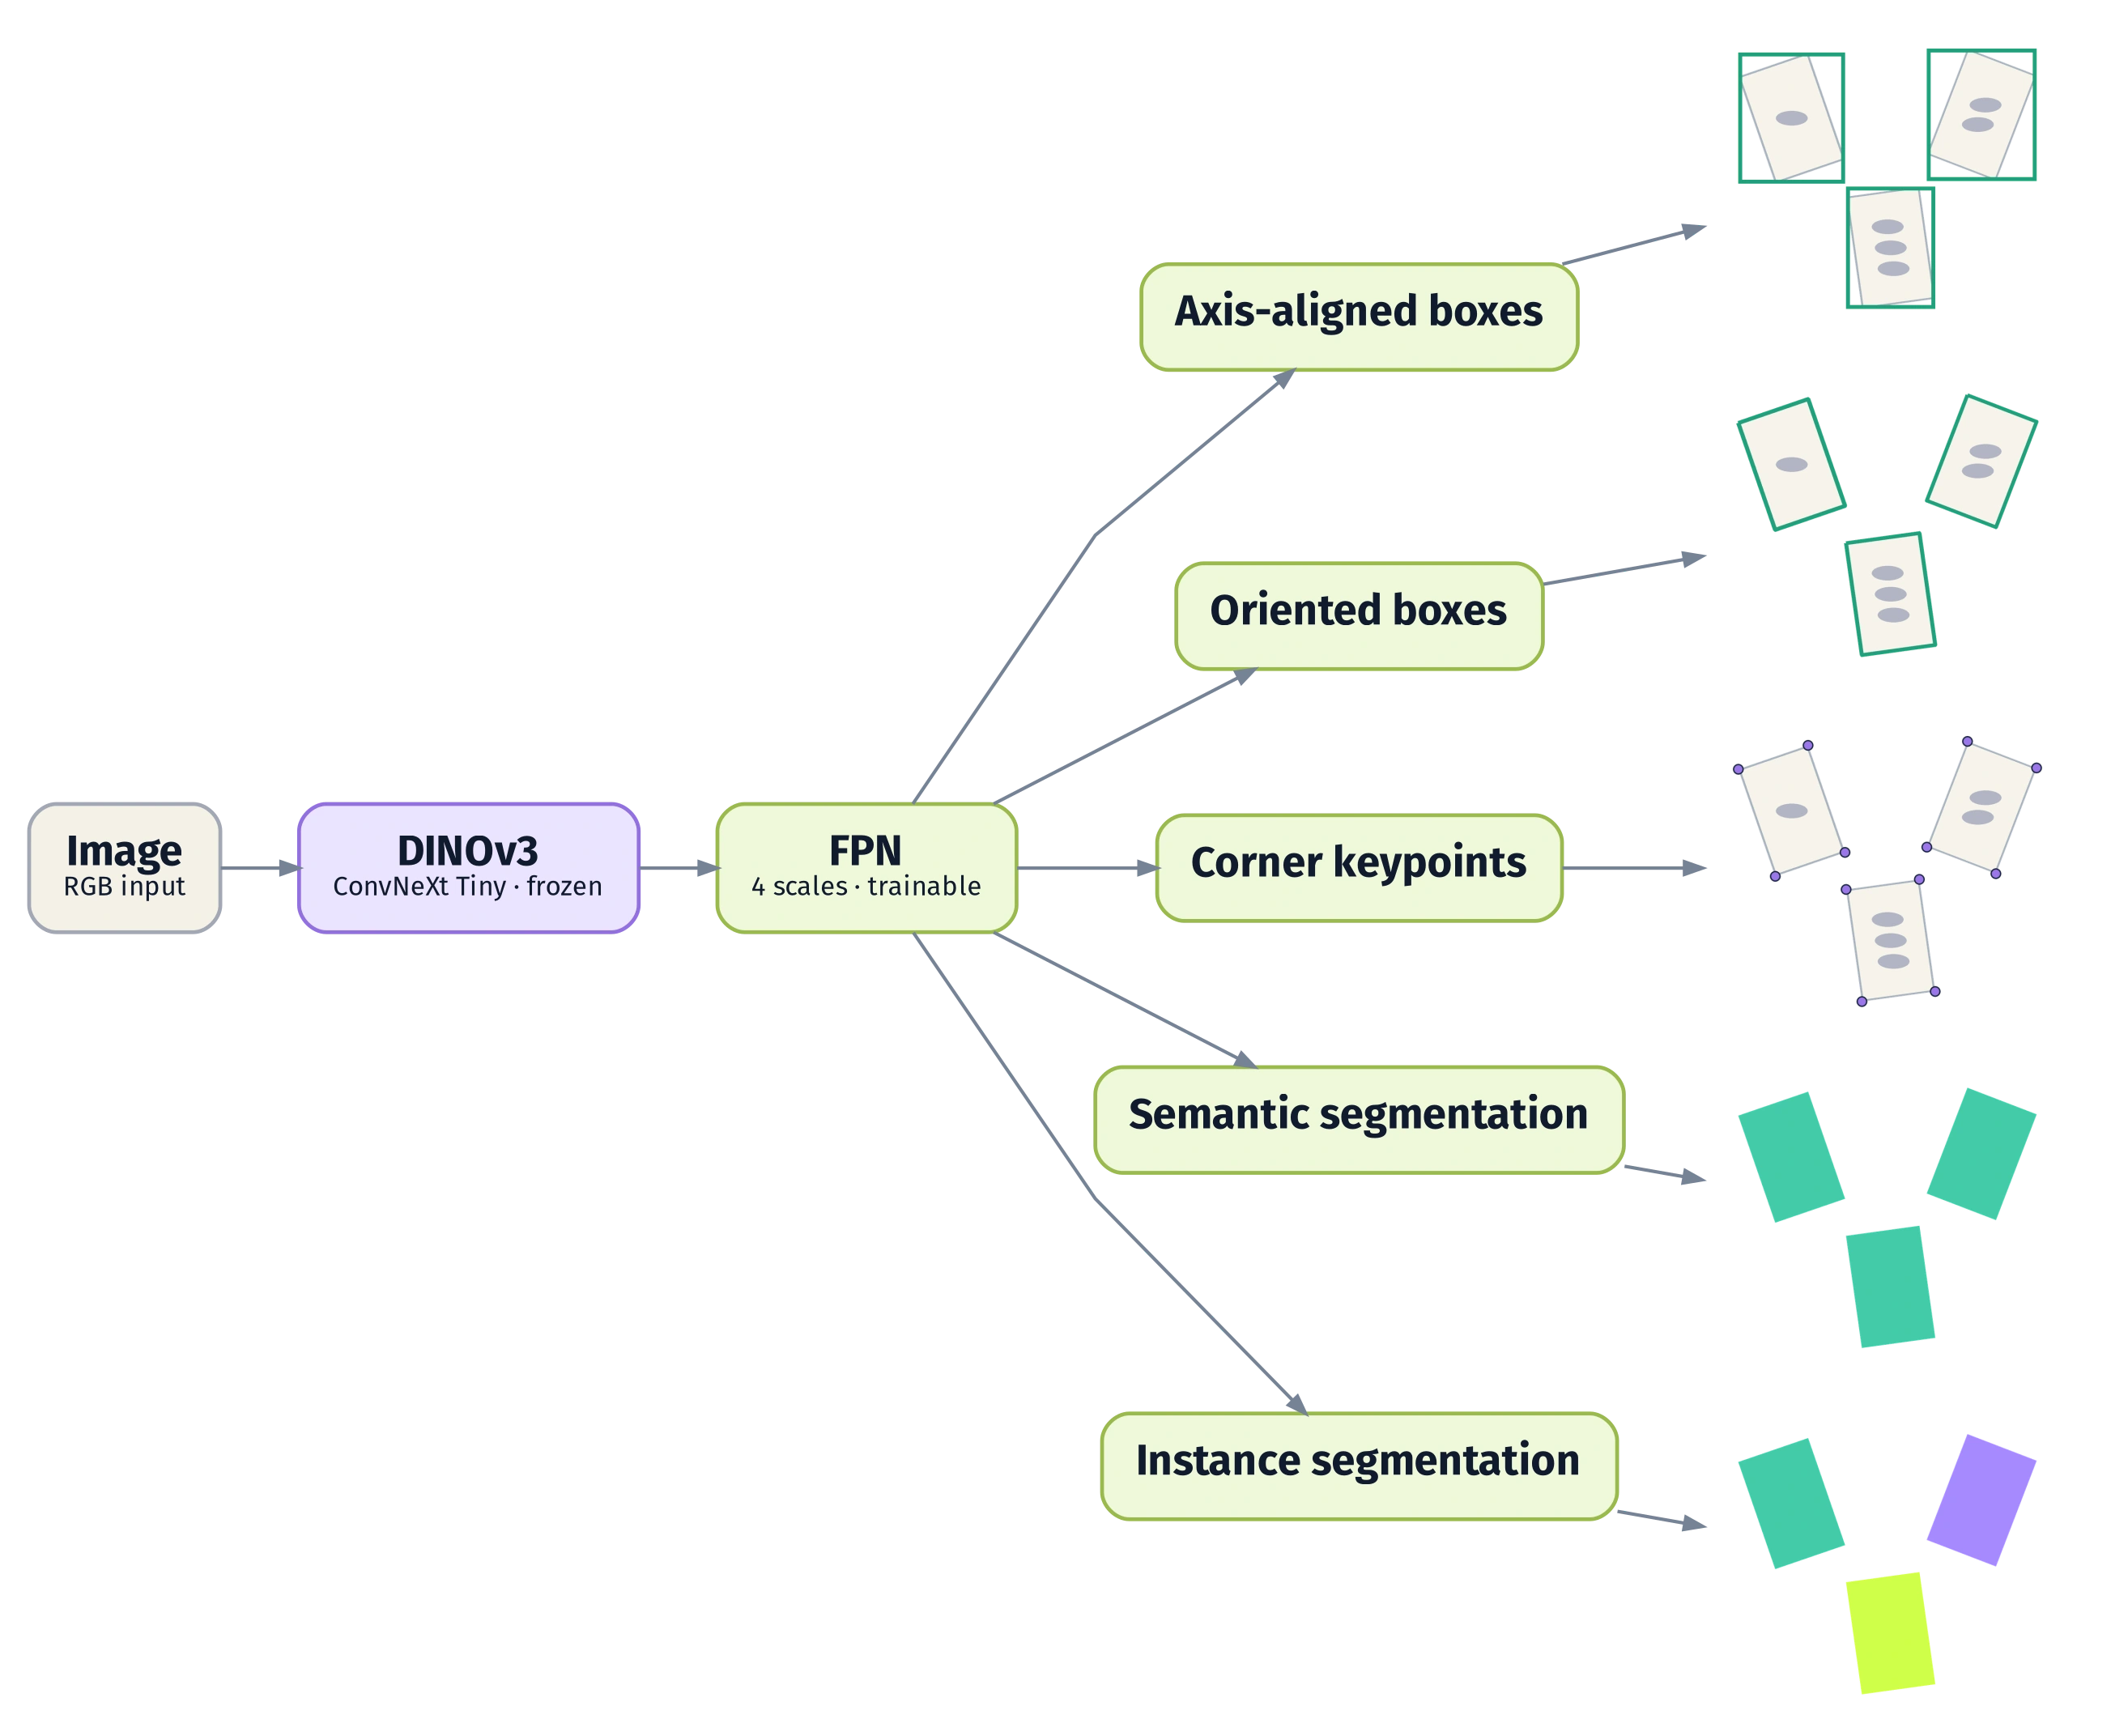
To foretell task-specific outputs like bounding packing containers, keypoints, or segmentation masks I added completely different task-specific heads. One of many fundamental objectives of this mission was to experiment with completely different targets and find out about their particular challenges. As a primary step, we’re not going to detect the kind of card but, however solely localize the playing cards within the picture.
Card Era
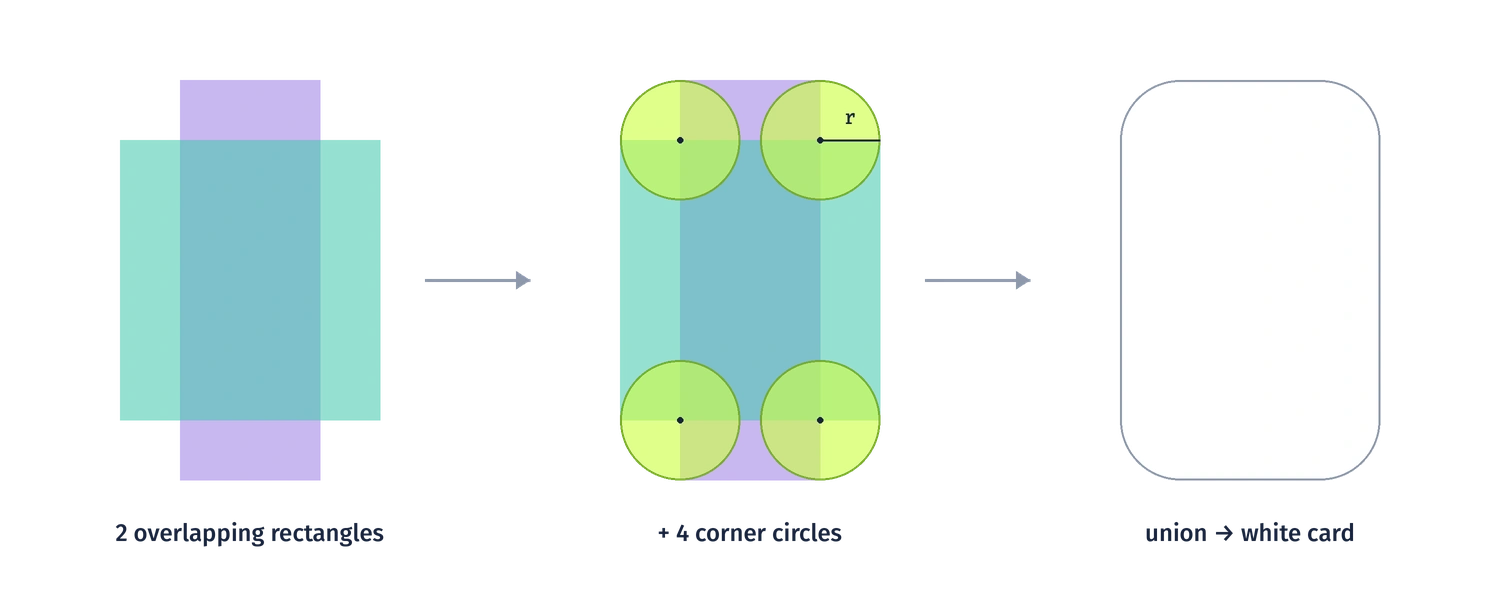
For the artificial information era, I used OpenCV to attract primary shapes, ranging from the white rounded rectangle to the person shapes. For instance for the cardboard form, we use a composite of two rectangles and 4 circles:
The fantastic thing about procedural information is that now we have limitless management over how the playing cards appear like. You’ll be able to simply get misplaced by enjoying round with these values, very mesmerizing.
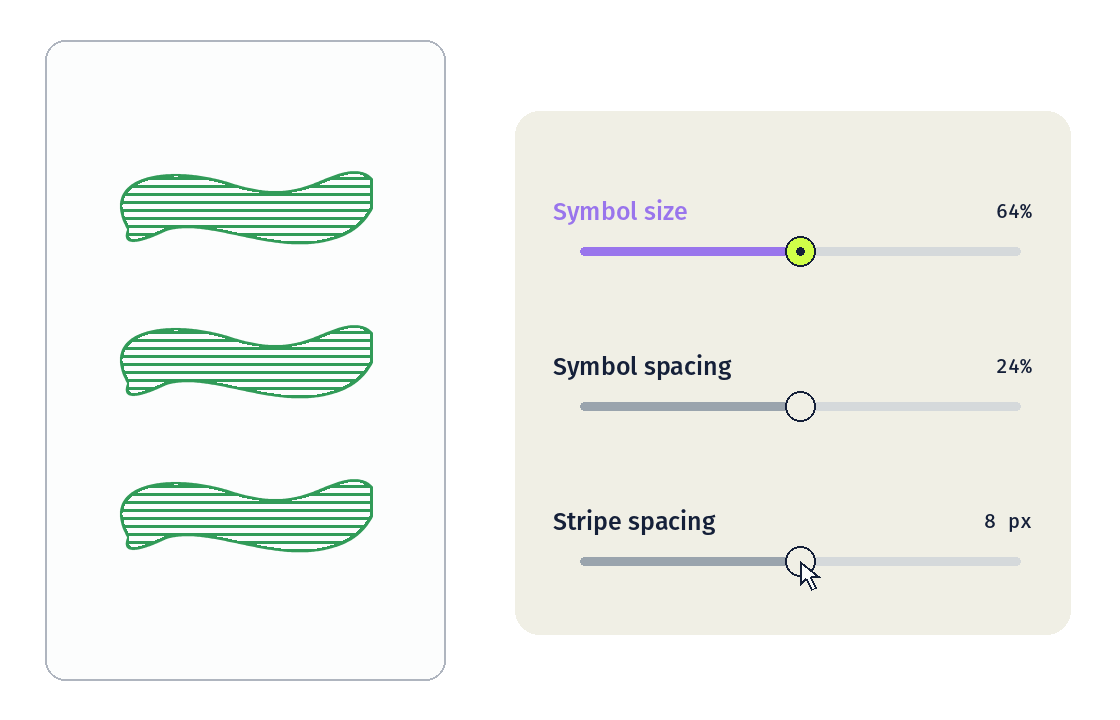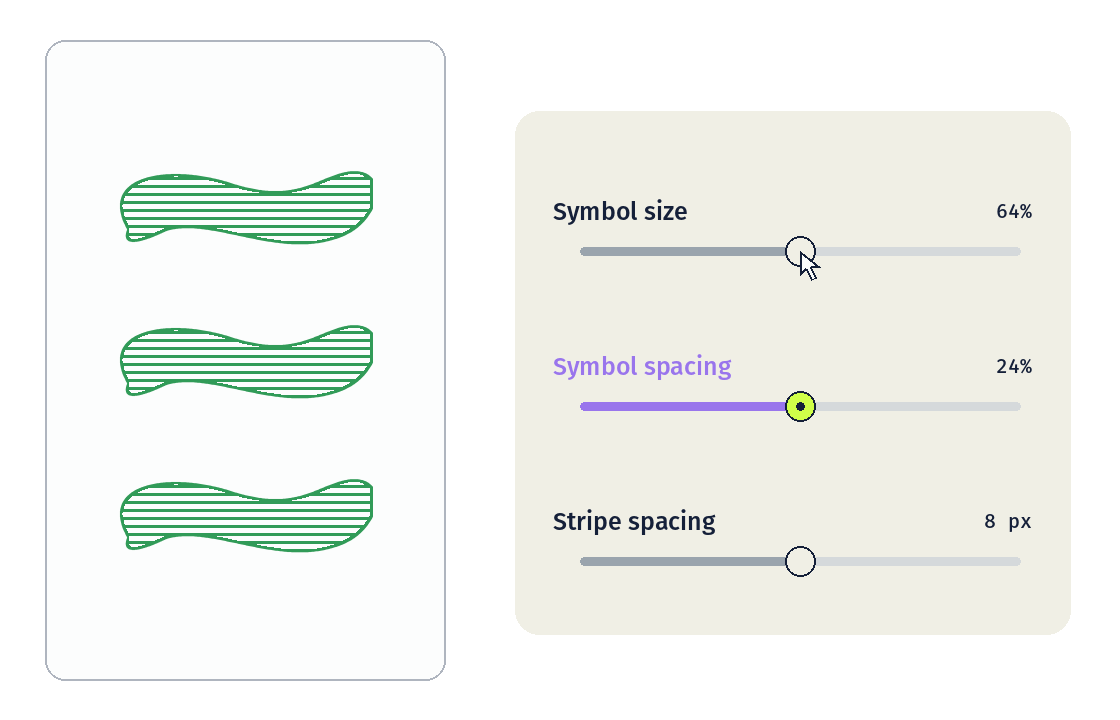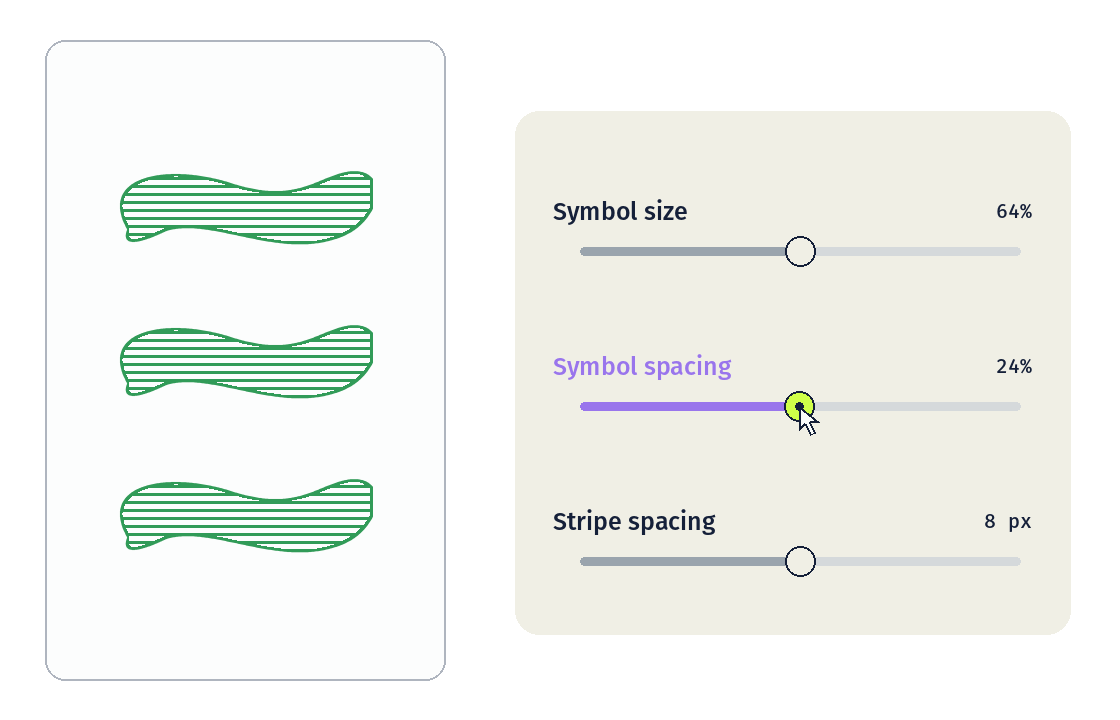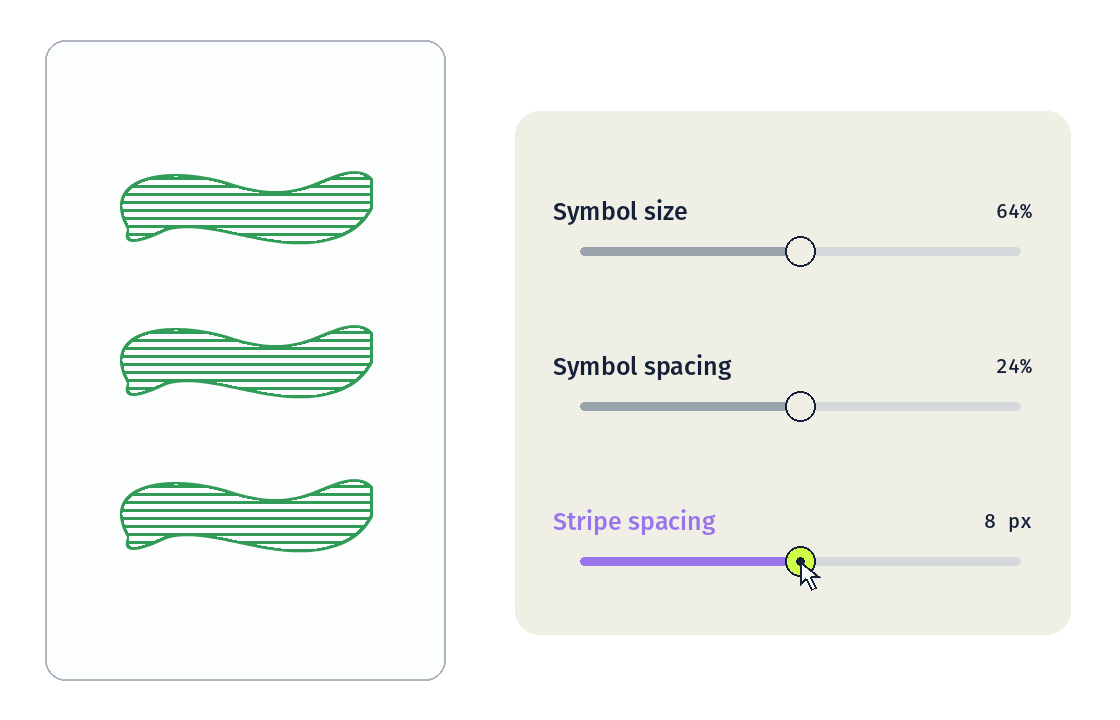
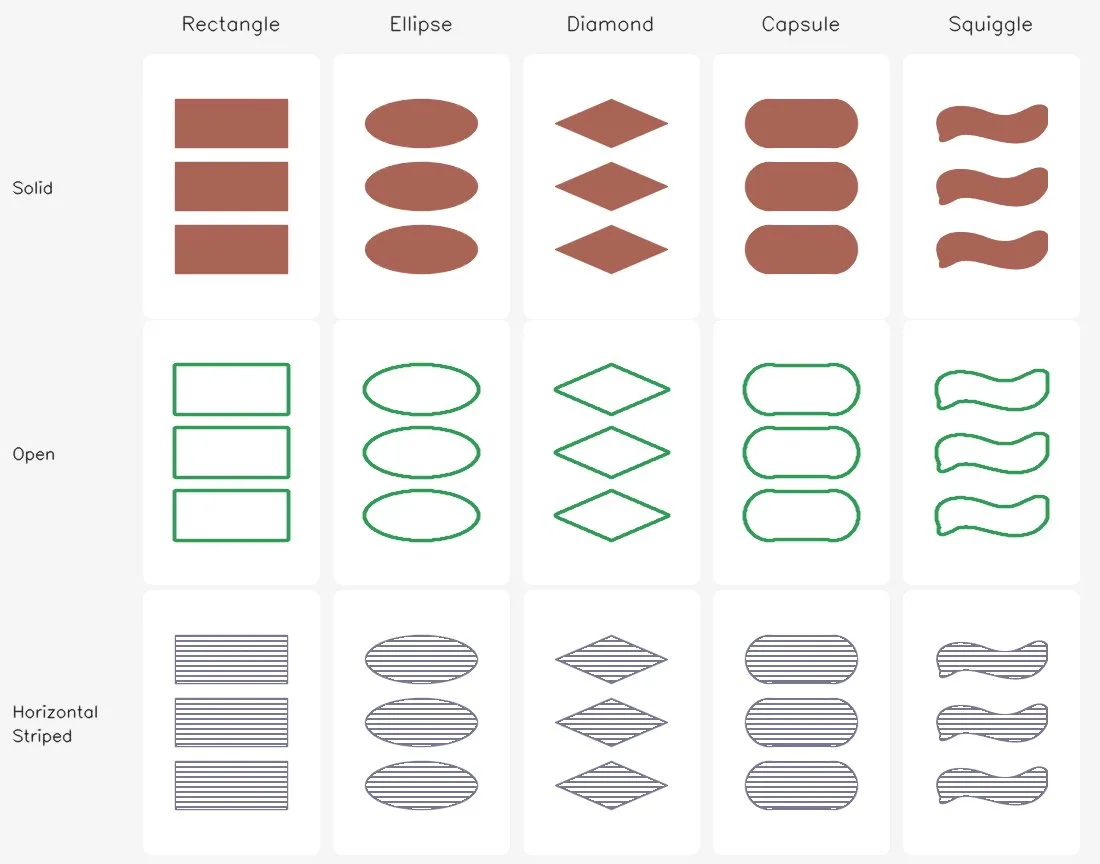
I generated some primary playing cards; often within the sport there are solely three shapes, however relying on the model of the sport the shapes can range a bit, so I selected to generate 5 distinct shapes to cowl the commonest ones.
Card Format
Producing particular person top-down seen playing cards is sweet, however ultimately we would like a dataset that’s just like our real-world examples, the place playing cards lie on a desk floor. I first began with drawing a number of playing cards at random onto a black floor, which didn’t look very reasonable.
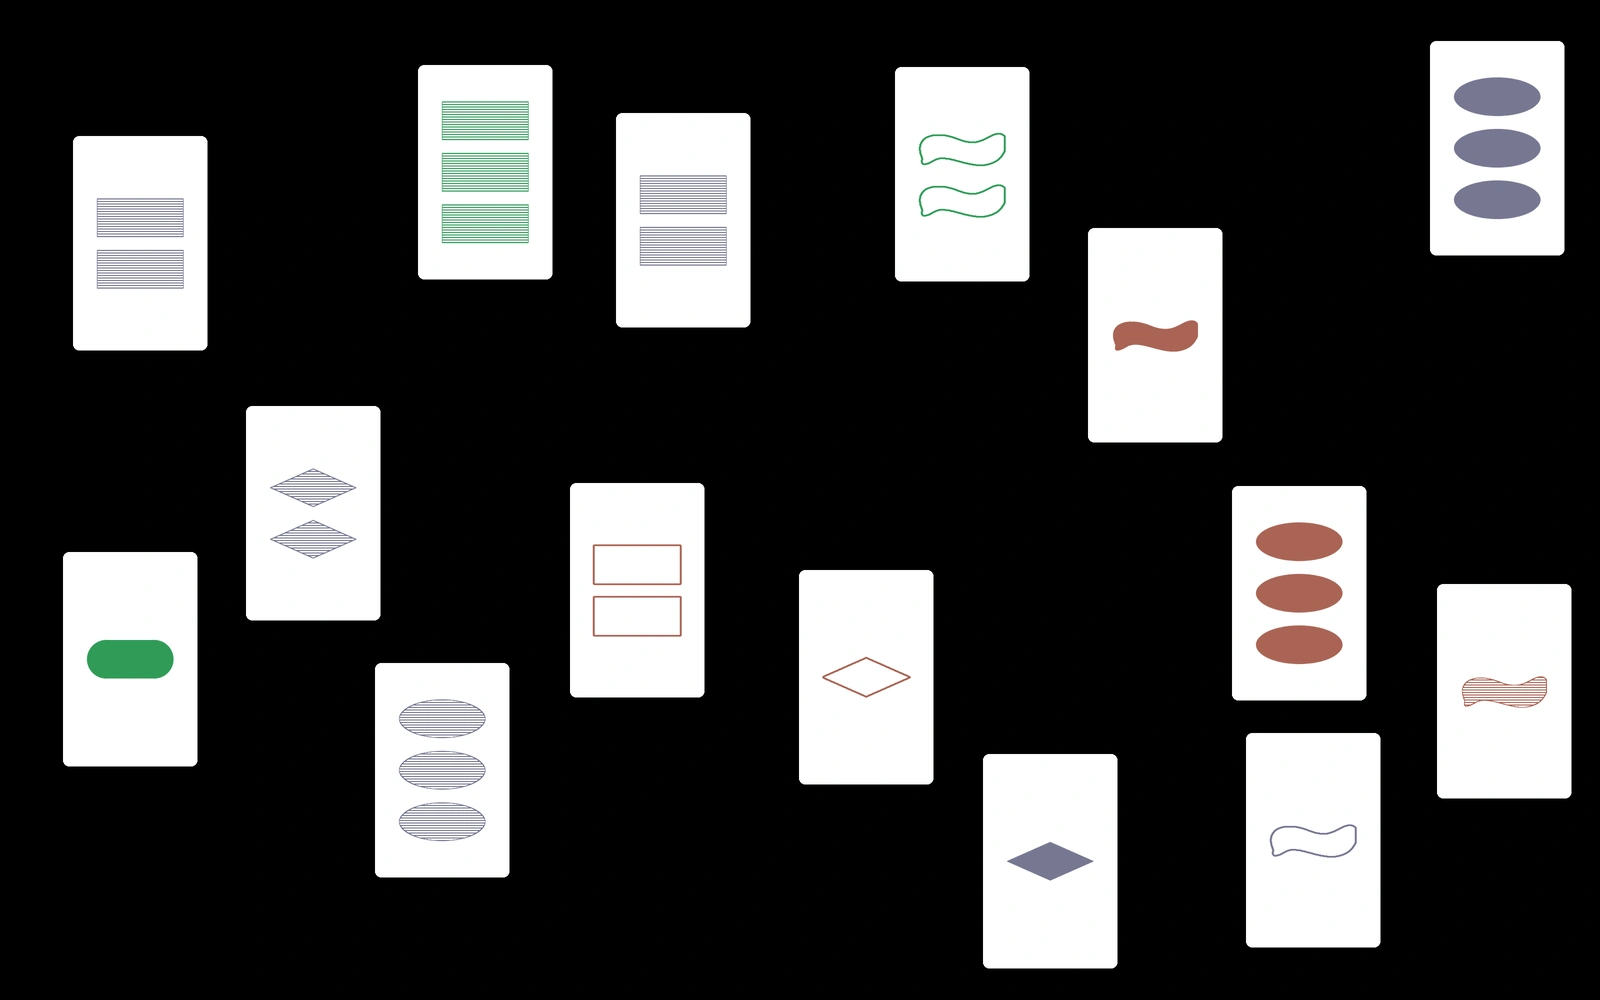
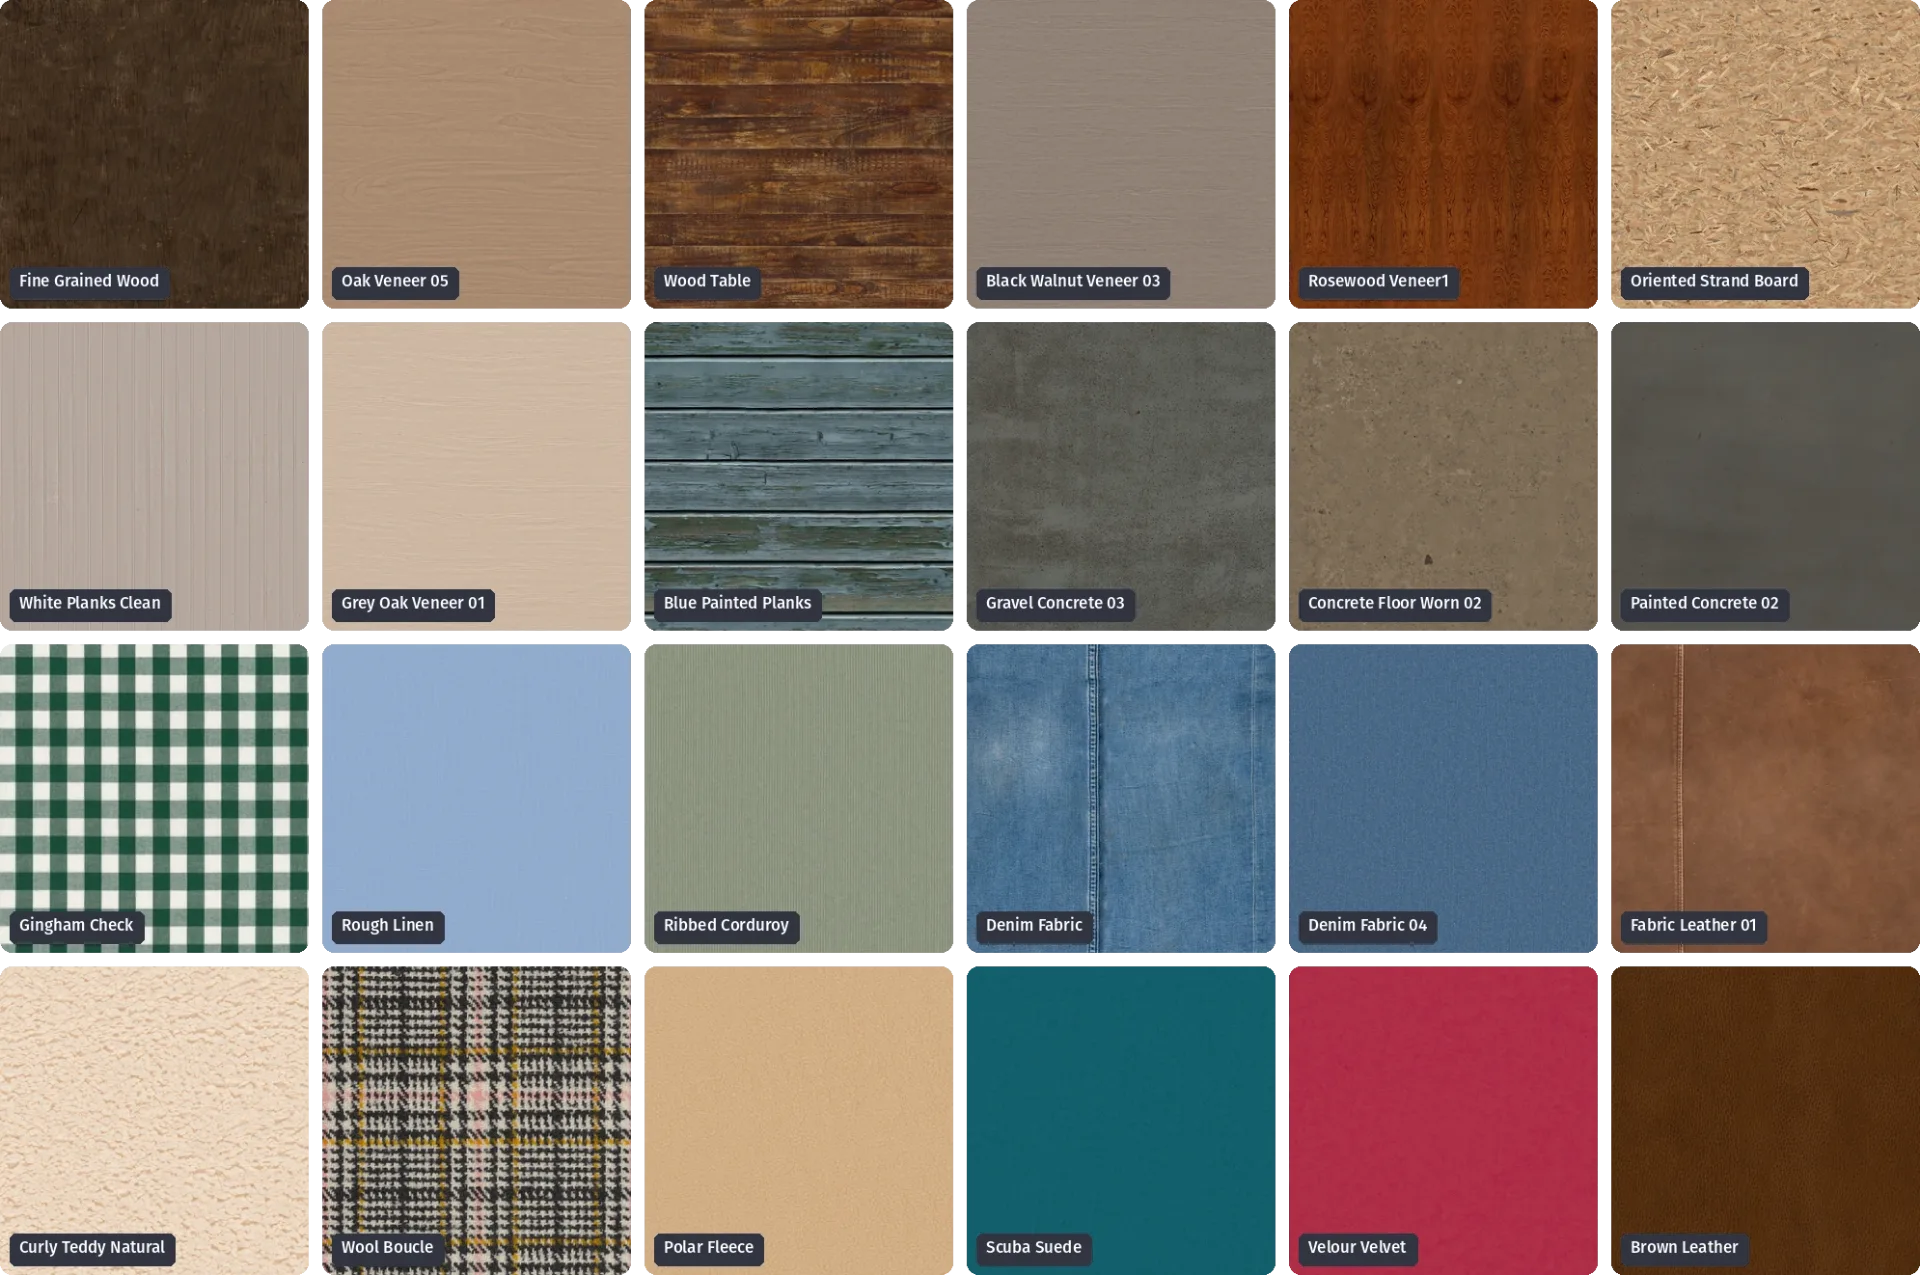
To repair this, I discovered some free high-quality textures from Poly Haven, licensed beneath CC0. Utilizing these, I created a small library of textured backgrounds to enhance the realism of the generated pictures.
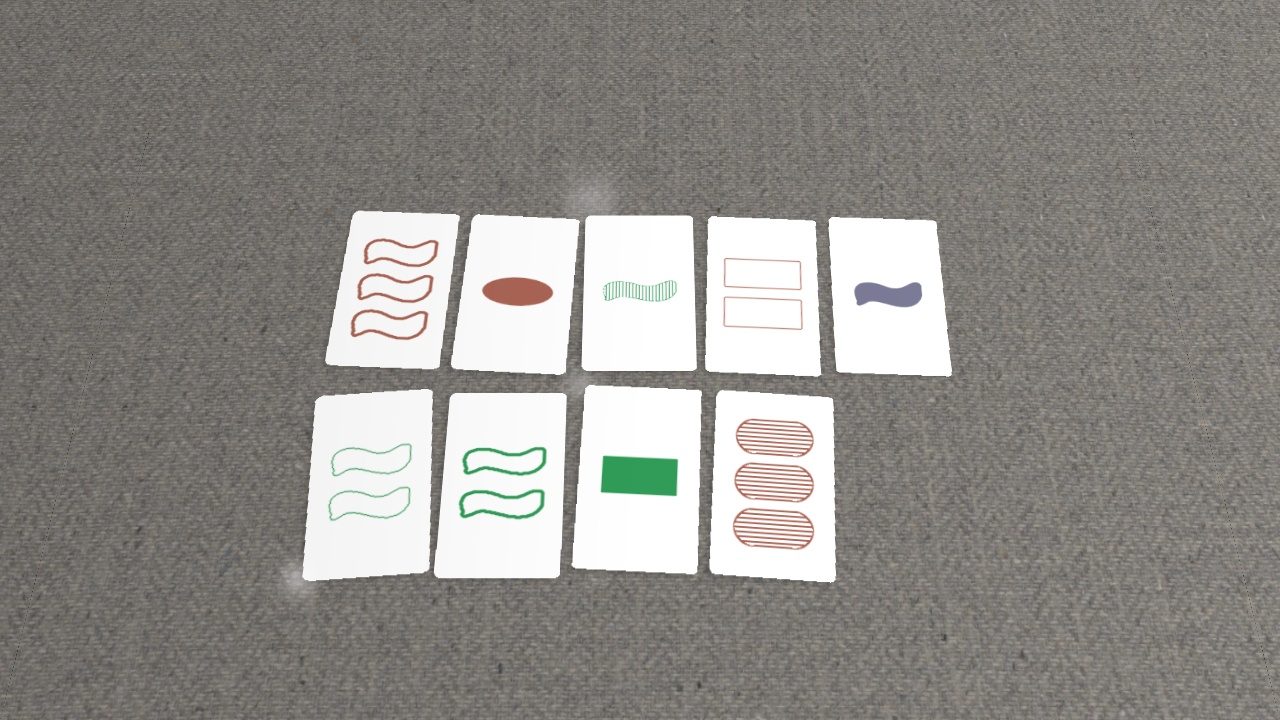
Including slight perspective skew, mushy drop shadows, and delicate highlights makes the playing cards really feel like they’re resting on a floor. Small variations of their place, rotation, and spacing break up the proper grid, whereas textured backgrounds and mild lighting variations give the scene a extra pure look.
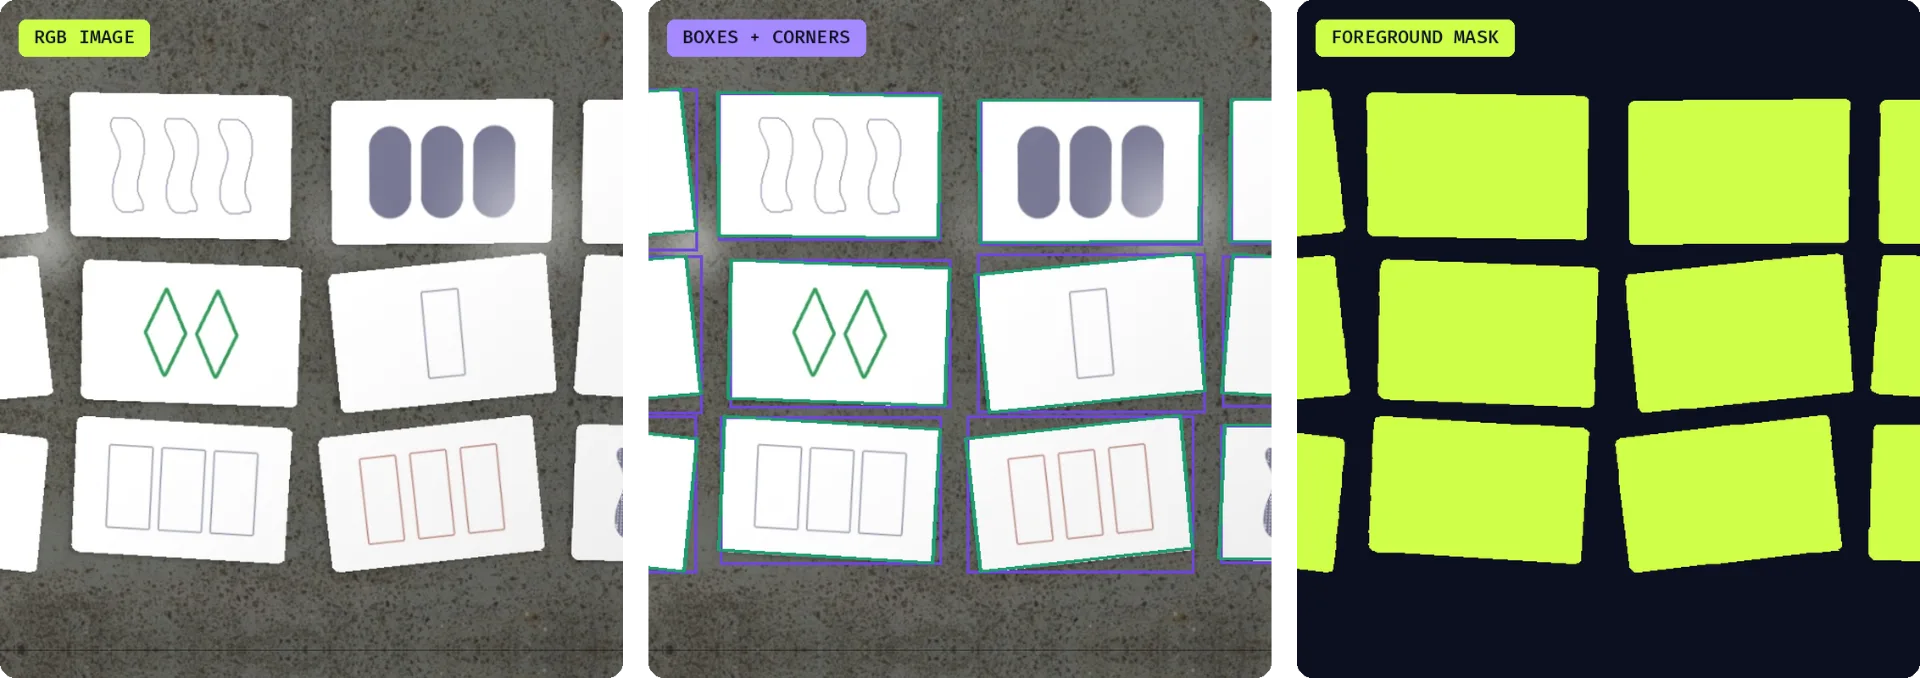
After all, since we generate the pictures ourselves, we additionally get the bottom fact annotations without spending a dime, in whichever kind we’d like them. We all know precisely the place every card is positioned and might apply the identical perspective transformation to its nook coordinates. From these, we are able to generate bounding packing containers, oriented packing containers, or keypoint annotations. We will additionally render a masks for every card, giving us each semantic segmentation masks, the place all playing cards belong to the identical foreground class, and occasion segmentation masks, the place every card is labeled individually. This lets us strive completely different duties on the identical dataset with out having to manually annotate all the things once more.
Actual-World Information
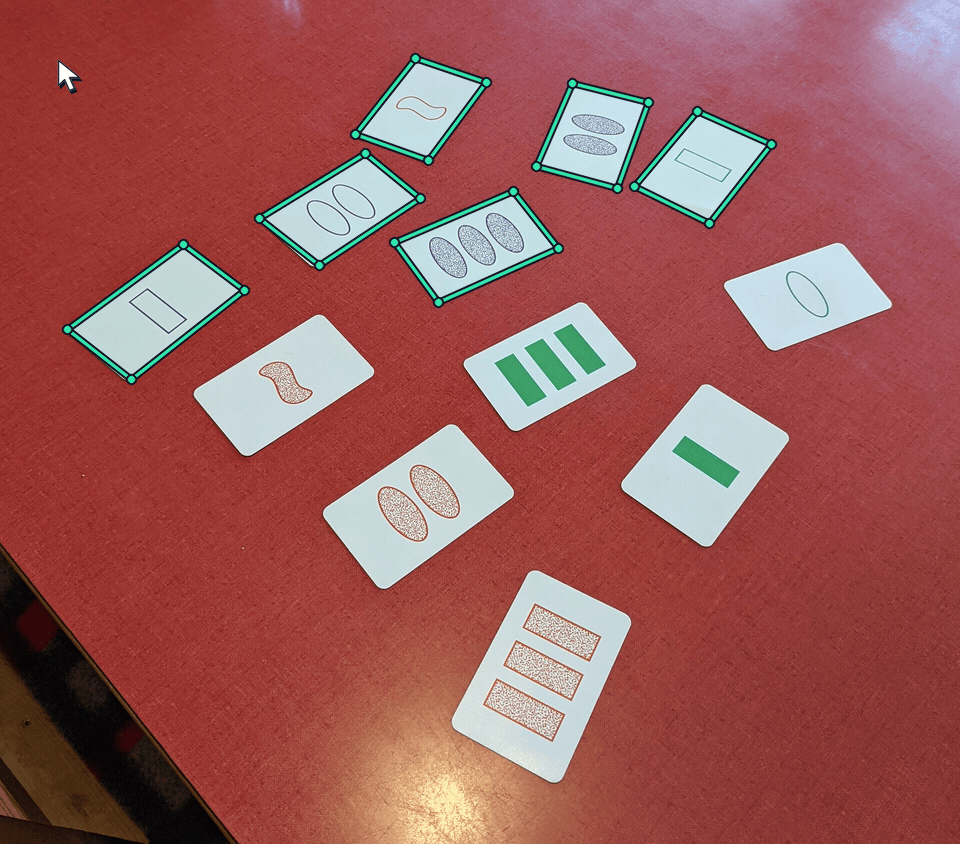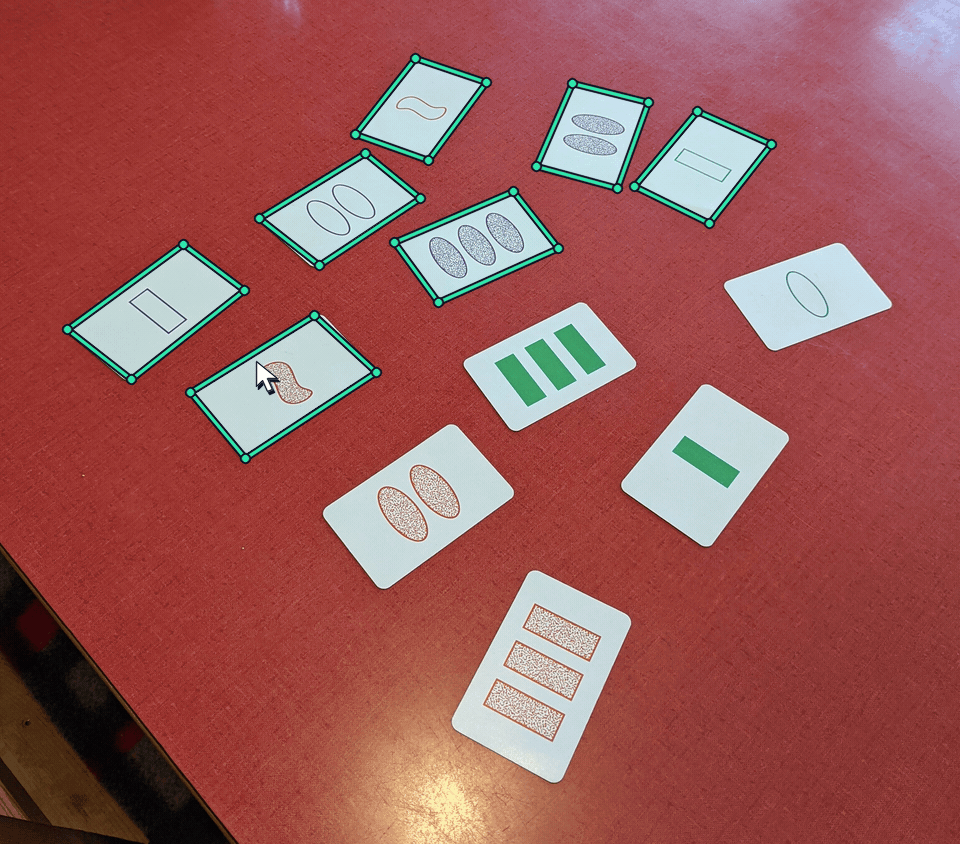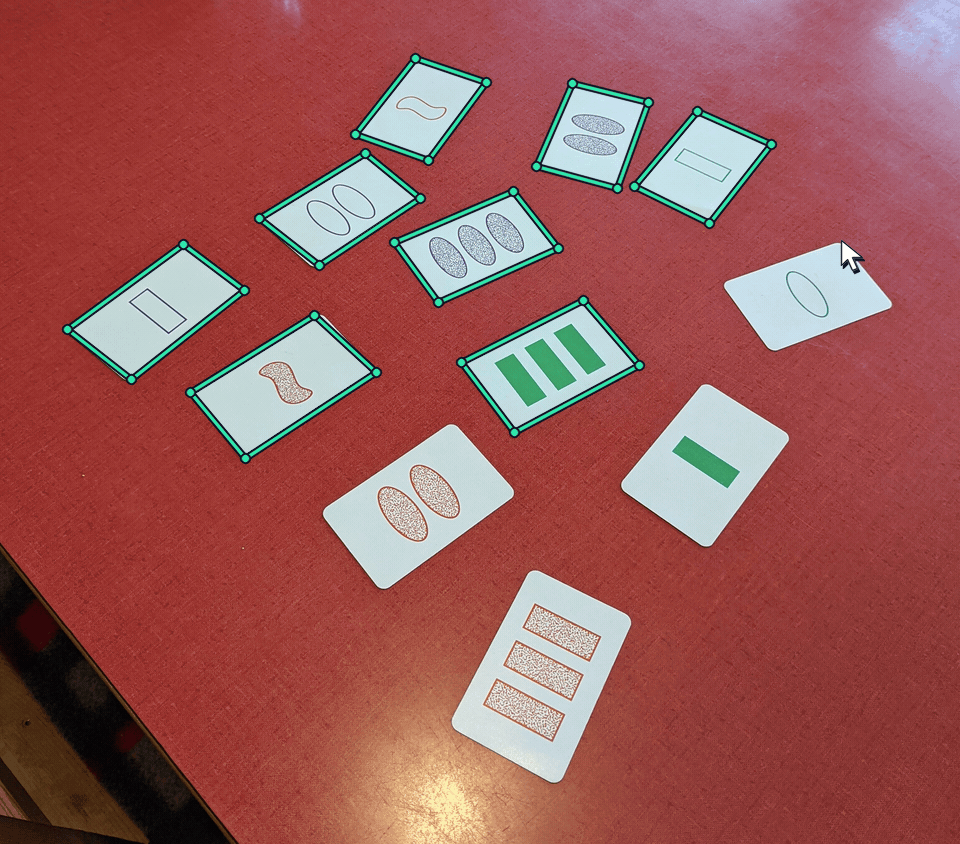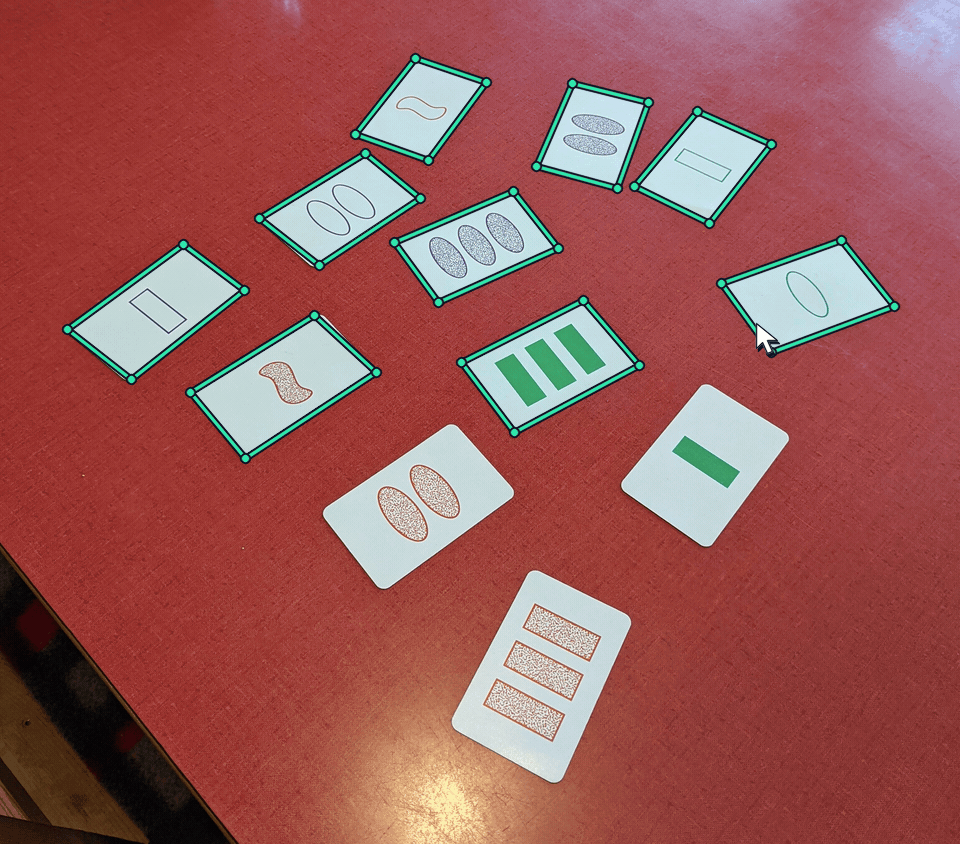
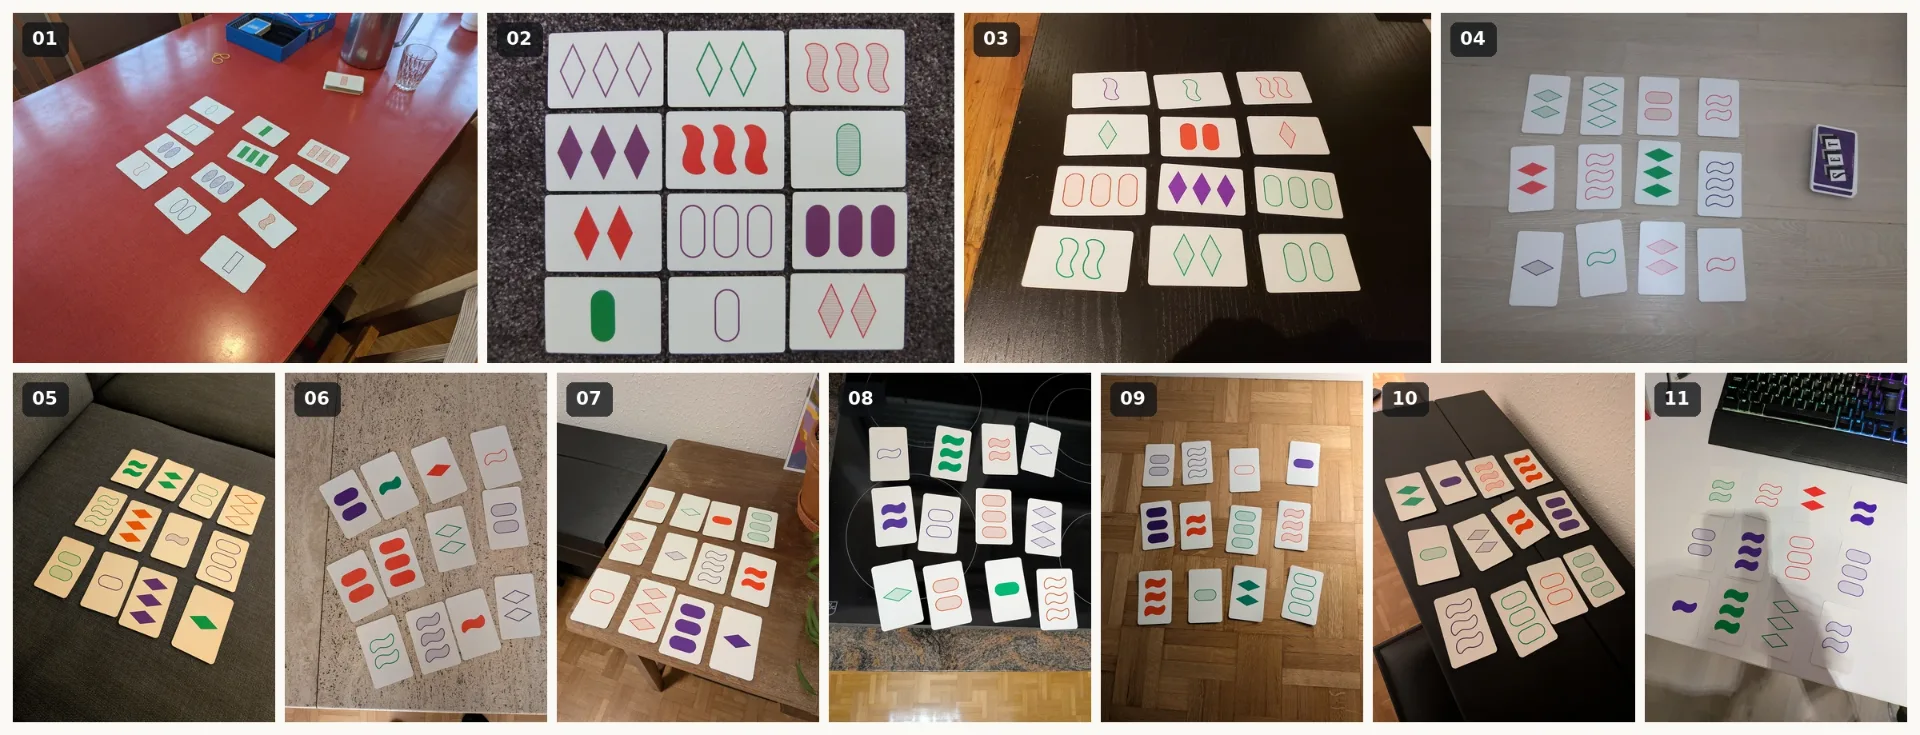
As a reference for the artificial card era and as a take a look at set for the mannequin coaching, I captured actual photographs of playing cards mendacity on a desk with my telephone digicam at completely different angles. The aim was to not create an intensive, various take a look at set however somewhat a easy benchmark to see how this method performs qualitatively. I simply went round the home and captured layouts of units on completely different surfaces with completely different lighting circumstances and ranging angles. I didn’t add any examples the place the playing cards are overlapping to maintain it easy.
|
Property |
Depend |
|---|---|
|
Pictures |
40 |
|
Scenes |
11 |
|
Complete playing cards |
480 |
Coaching
Now that we are able to generate pictures along with their annotations, we are able to begin coaching our fashions. For this experiment, I stored the DINOv3 spine frozen and solely skilled the function pyramid and the task-specific heads. This lets us reuse the pretrained options whereas studying learn how to flip them into card detections or segmentation masks. I assume because of the giant pretraining and generalization functionality of the DINO options that we are able to zero-shot switch them from our coaching dataset to our actual information. So we solely use the artificial dataset throughout coaching after which consider on the true pictures.
For coaching I take advantage of the PyTorch framework Lightning. I actually like this framework because it abstracts among the decrease degree PyTorch code so I want much less boilerplate code, however you possibly can nonetheless use torch the identical manner you’ll use it in any other case.
For the spine, we are able to outline the DINOv3 mannequin, loading the weights from a customized pretrained checkpoint file and add a function pyramid community layer that shall be skilled.
Then we are able to construct our task-specific fashions primarily based on this, for instance for the detector mannequin:
Most of those hyperparameters have been probably not tuned, because the aim right here is to not practice the very best mannequin however to realize zero-shot switch from the artificial dataset to the true pictures.
To assist the switch and add some variation to our coaching information, we add a bunch of picture augmentations like flip, perspective skew, distinction, brightness, blur and so forth.
Outcomes
I skilled these fashions on the artificial datasets, utilizing 2000 pictures for coaching and 200 pictures for validation from this artificial set. These pictures are 1280 × 720, with 5–15 playing cards per scene. Every coaching epoch samples 500 coaching pictures with augmentations, and I ran all these for 10 epochs and chosen the run with the best validation rating.
|
Break up |
Pictures |
Playing cards |
|---|---|---|
|
Coaching |
2,000 |
20,011 |
|
Validation |
200 |
1,948 |
|
Complete |
2,200 |
21,959 |
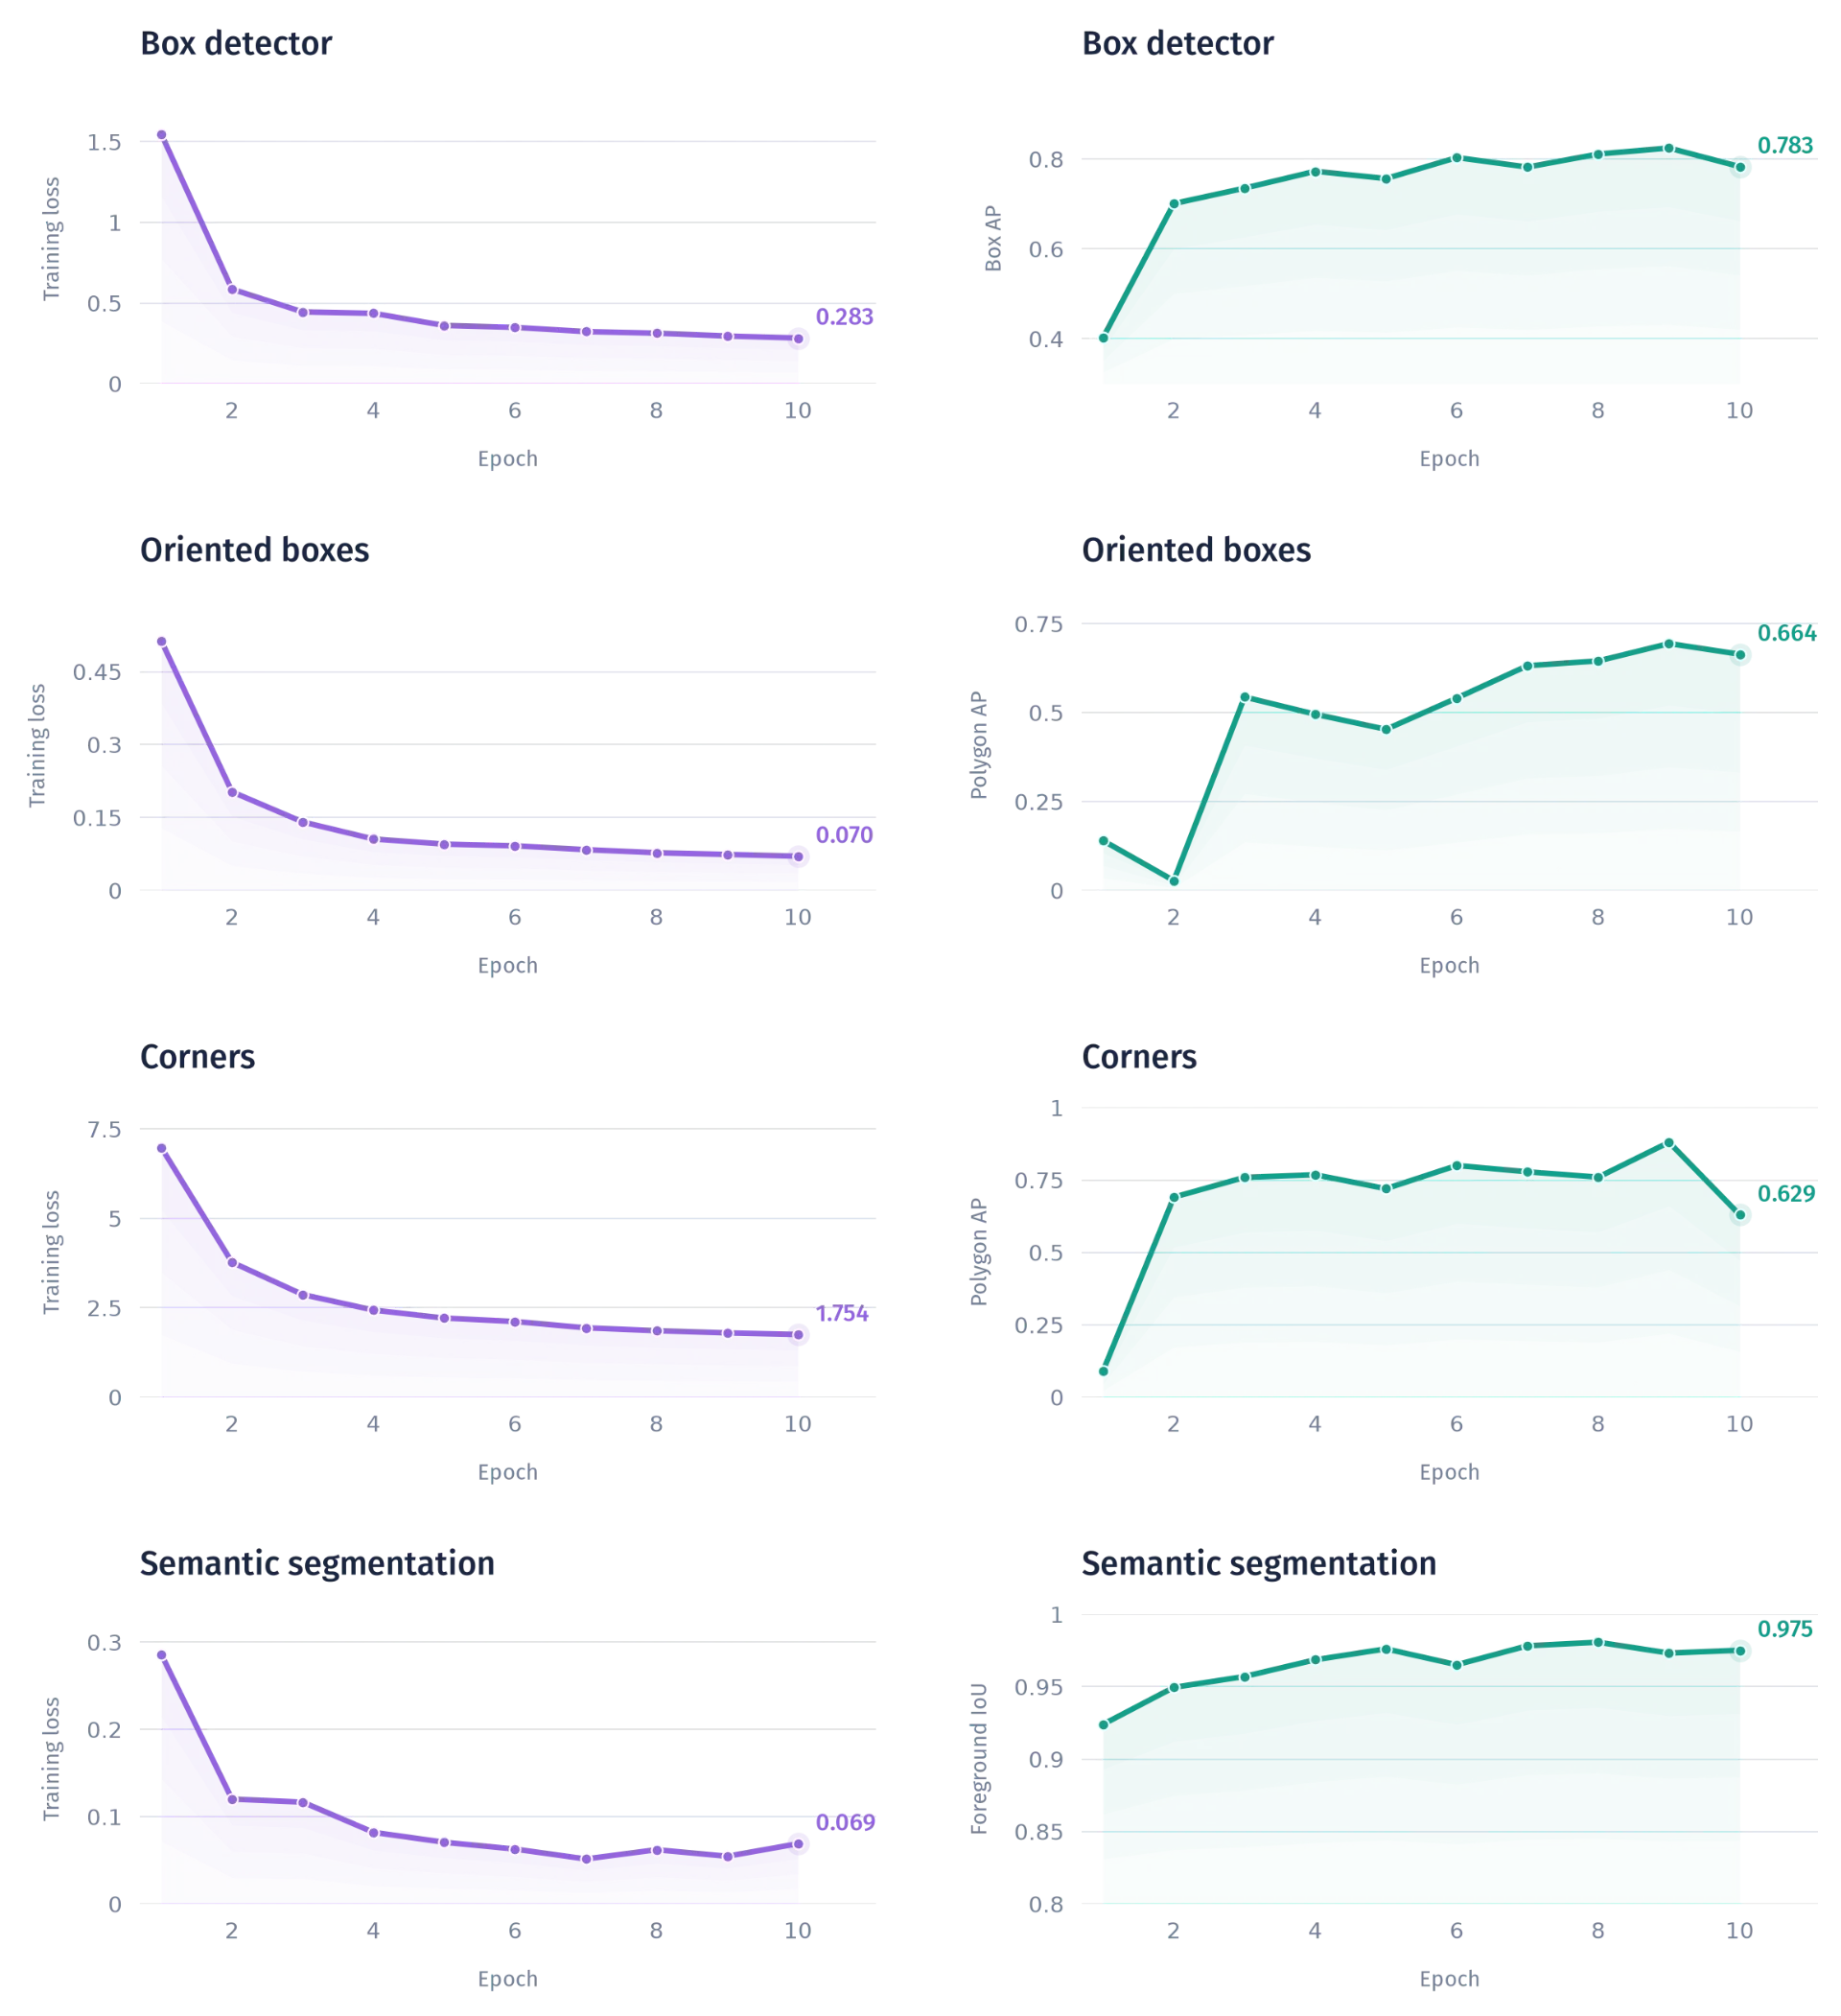
To guage the fashions, I used the actual pictures I captured with my telephone as a take a look at set. There are some threshold parameters we have to set to run an analysis. I didn’t spend a lot time optimizing these thresholds on the real-image take a look at set, as I needed to maintain it easy. Ideally we’d tweak these values just like different hyperparameters on a validation set after which measure the ultimate efficiency on one other separate take a look at dataset. However for this mission, I’m happy with utilizing a qualitative benchmark, primarily based on the next parameter choice:
I used a confidence threshold of 0.75 to filter out much less assured detections. A better threshold usually reduces false positives however can miss extra playing cards, whereas a decrease threshold can get well extra playing cards at the price of further false positives. For semantic segmentation, I additionally used a threshold of 0.75 and solely stored linked areas masking a minimum of 0.1% of the picture space, filtering out small mispredictions. The precision, recall, and F1 scores beneath use axis-aligned bounding-box matching at IoU ≥ 0.50 for all 4 duties. Utilizing these values, we find yourself with the next outcomes:
|
Process |
Precision |
Recall |
F1 |
|---|---|---|---|
|
Detector |
0.950 |
0.998 |
0.974 |
|
Oriented packing containers |
0.973 |
0.683 |
0.803 |
|
Corners |
0.978 |
0.925 |
0.951 |
|
Semantic |
0.881 |
0.944 |
0.911 |
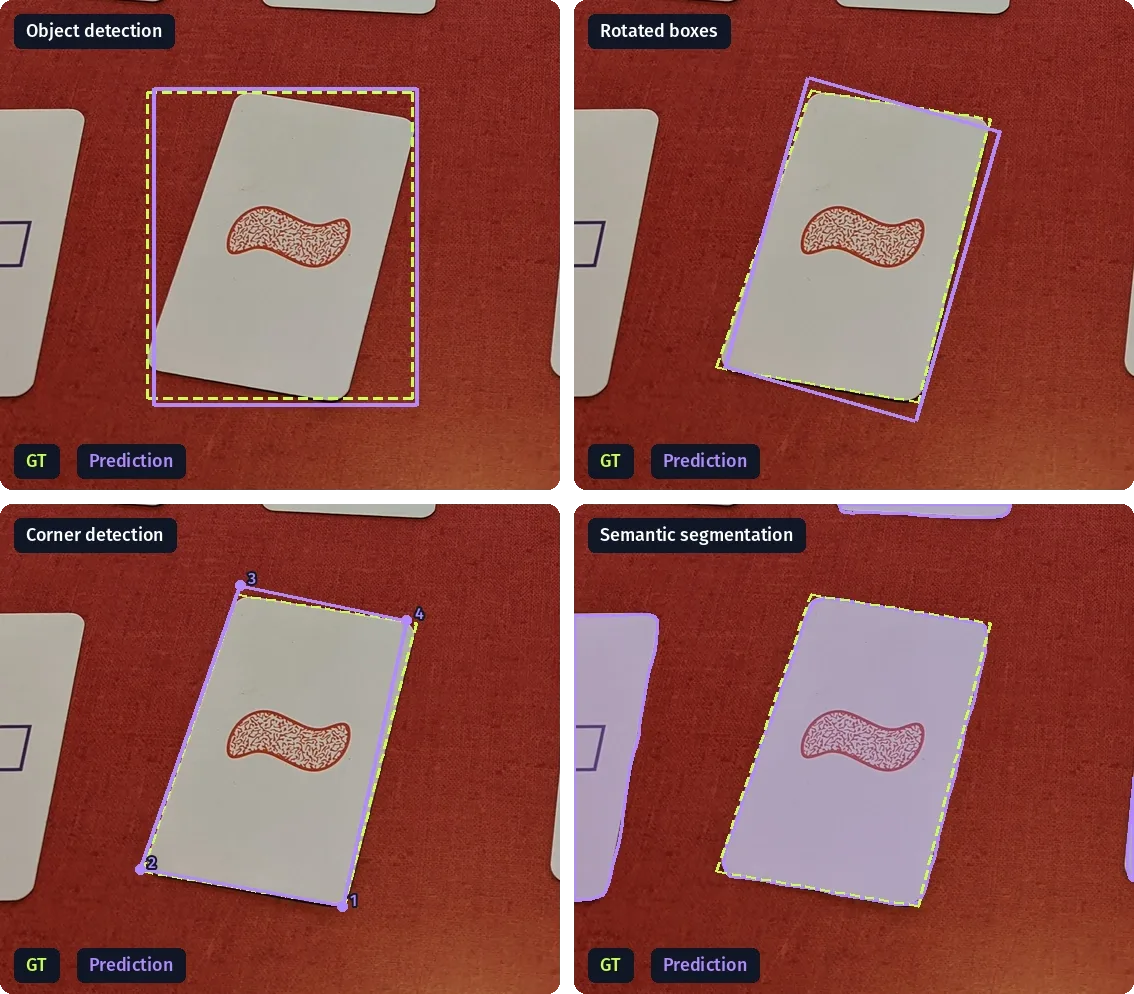
General I’m extraordinarily pleased with these outcomes, the mannequin has not seen a single actual picture and transfers fairly properly onto these pictures. The article detection run appeared to carry out the very best primarily based on the F1 rating. Let’s take a deeper have a look at some challenges with every of those duties.
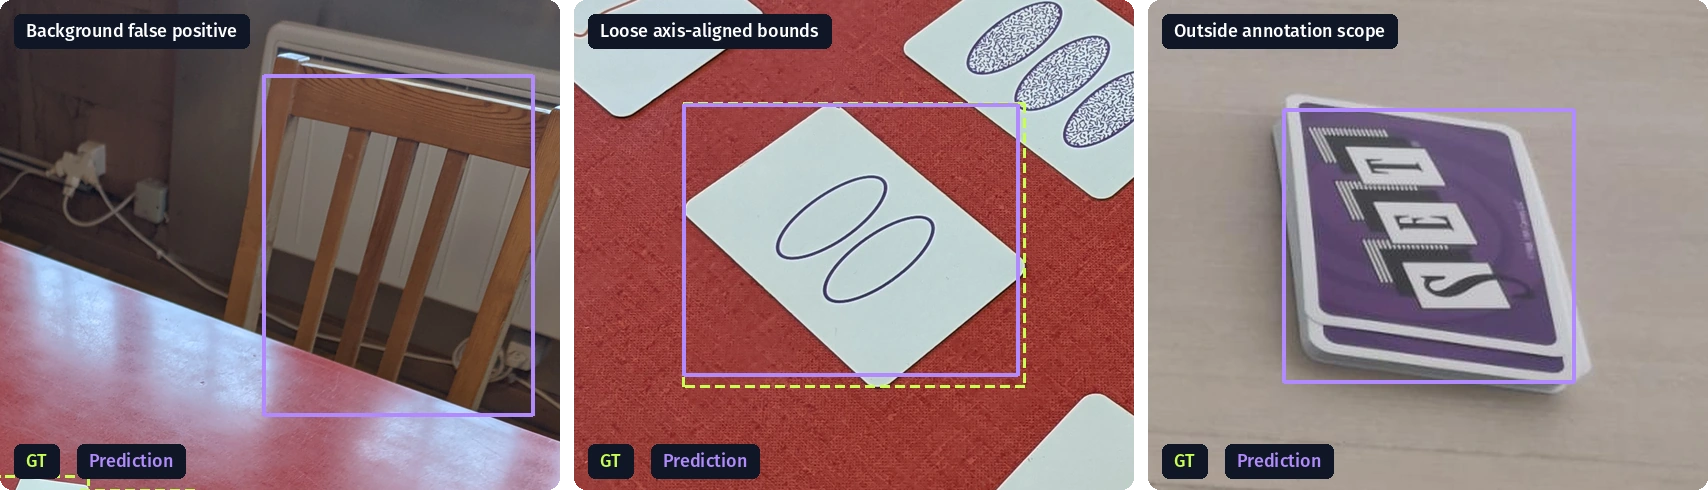
A recurring theme in these experiments is that we get detections on the background and/or on the set deck. Since our pictures use a flat background with the playing cards on it, the mannequin has not realized on these extra various objects that seem within the background, just like the chair with the white heater behind that it errors for a card. Particular to the oblong bounding field prediction process is the issue of rotated/skewed playing cards, since they match poorly contained in the orthogonal rectangle. That is the principle motivation of including rotation to the bounding packing containers for higher alignment.
-
Rotated Bounding Field Detection
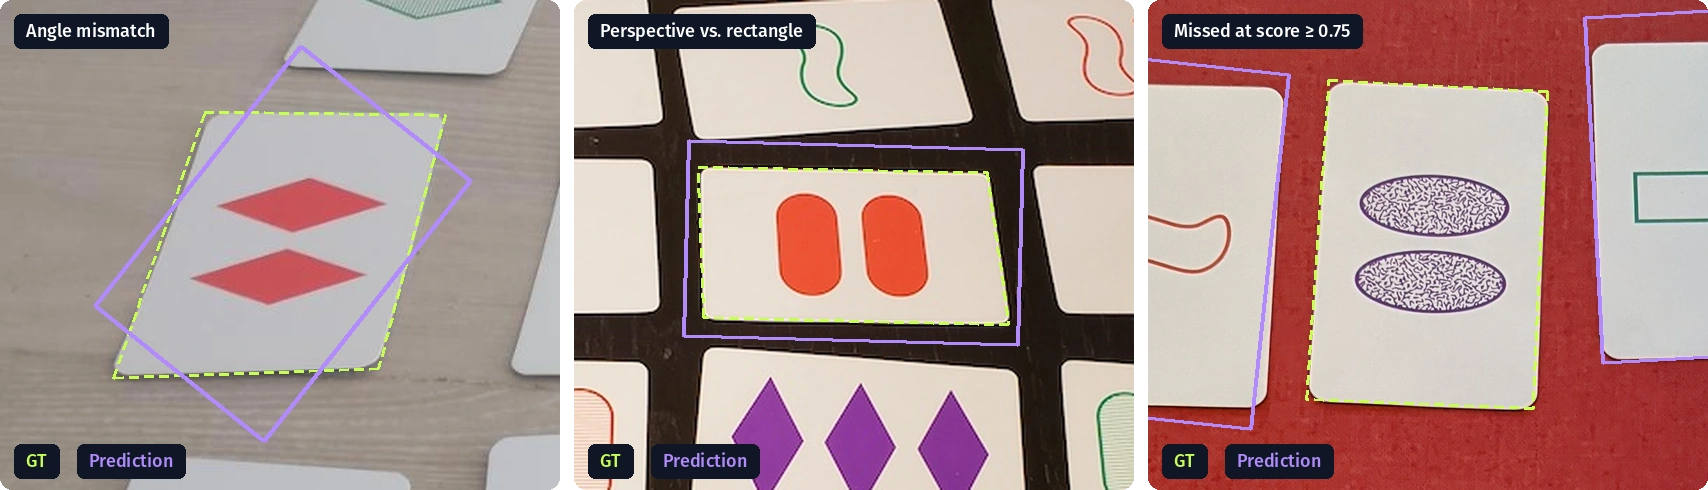
For the rotated packing containers we see some completely different failure modes. Some skewed playing cards are nonetheless not properly captured by the rotated rectangle. It appears like the educational sign for the rotation of the bounding field was not superb, there may be actually room for enchancment on this process. There’s some ambiguity between +-180 levels on the packing containers that might have added to this. It additionally missed some playing cards, so including this rotation goal made it much less assured on some playing cards.
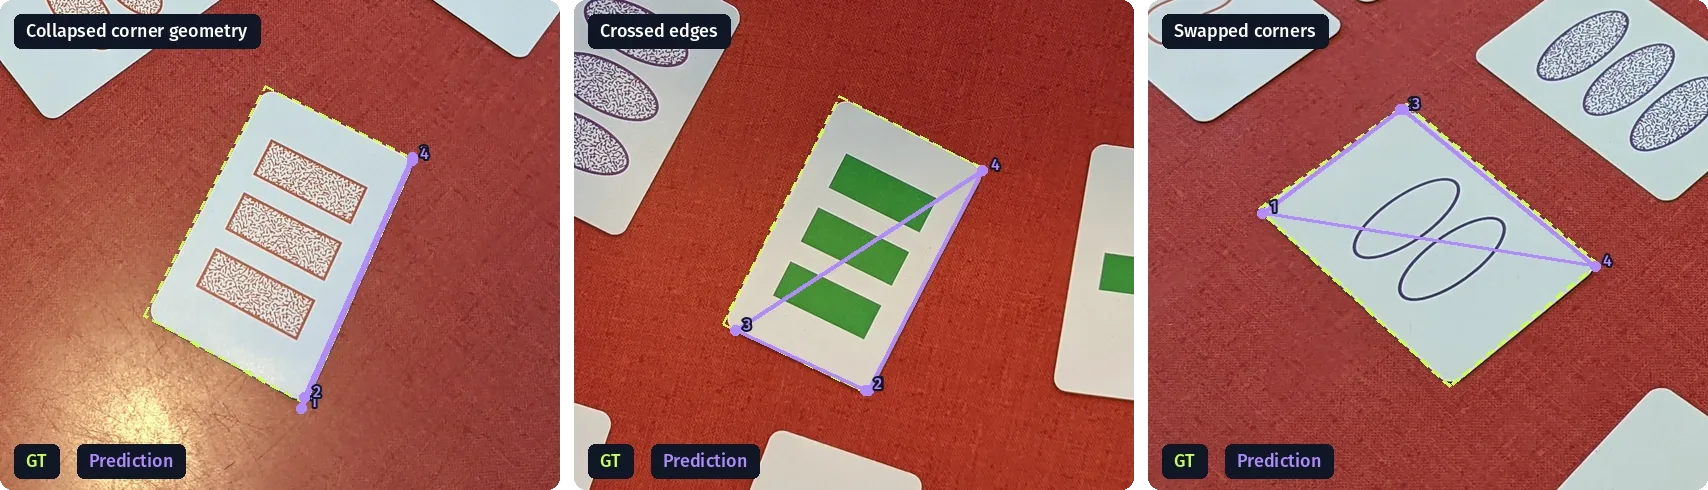
The nook detection struggled fairly a bit with the ordering of the factors. Within the examples above, some predictions are near the precise corners, however connecting them within the predicted order offers us crossed edges. In one other case, two factors find yourself close to the identical nook, leaving us with a collapsed polygon. Predicting 4 factors offers us extra flexibility to suit playing cards beneath perspective, however we additionally want a constant task of these factors. A small rotation can change which nook comes first within the sorting, though the cardboard seems to be nearly equivalent.
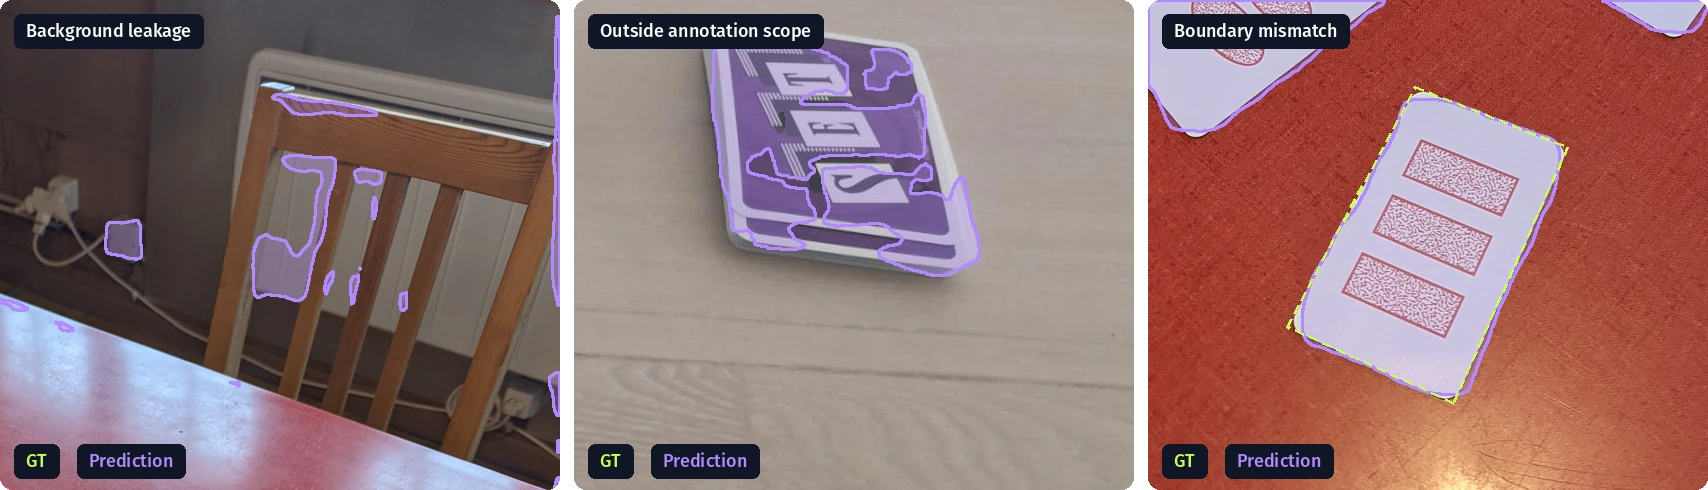
With semantic segmentation, we keep away from the nook ordering downside by predicting which pixels belong to a card. This labored surprisingly properly on the true pictures. We see some acquainted issues right here: elements of the chair are categorised as foreground, and the mannequin additionally responds to the cardboard deck, though with some gaps within the masks. The anticipated boundaries don’t all the time observe the cardboard edges precisely both. One other limitation is that each one playing cards share the identical foreground class. If two playing cards contact or overlap, they’ll kind a single linked area, so we would want a further step to separate them into particular person playing cards, which is the place occasion segmentation would are available.
Abstract
On this mission, we generated an artificial dataset of set playing cards with annotations for a number of pc imaginative and prescient duties and skilled completely different heads on a frozen DINOv3 spine. We noticed that the selection of prediction goal brings its personal challenges, from becoming rotated playing cards into rectangles to constantly ordering corners or separating playing cards in a foreground masks. I’m very pleased with how properly these fashions transferred to actual pictures with out utilizing any task-specific real-world information for coaching. There’s a whole lot of room for enchancment on the mannequin coaching to shut the hole between the completely different duties. An fascinating follow-up problem can be to deal with partial occlusions of playing cards, at the moment we explicitly do not generate overlapping playing cards. One other pure subsequent step can be to acknowledge the cardboard options as properly, so we are able to go from discovering particular person playing cards to discovering precise set triplets, truly letting the pc “play” the sport.
···
For extra particulars and the total implementation together with the code for the dataset era, augmentation, mannequin coaching and analysis, try the supply code of this mission on GitHub.
···
All visualizations on this publish have been created by the writer.