This text was co-authored by Jacob Cybulski
Introduction
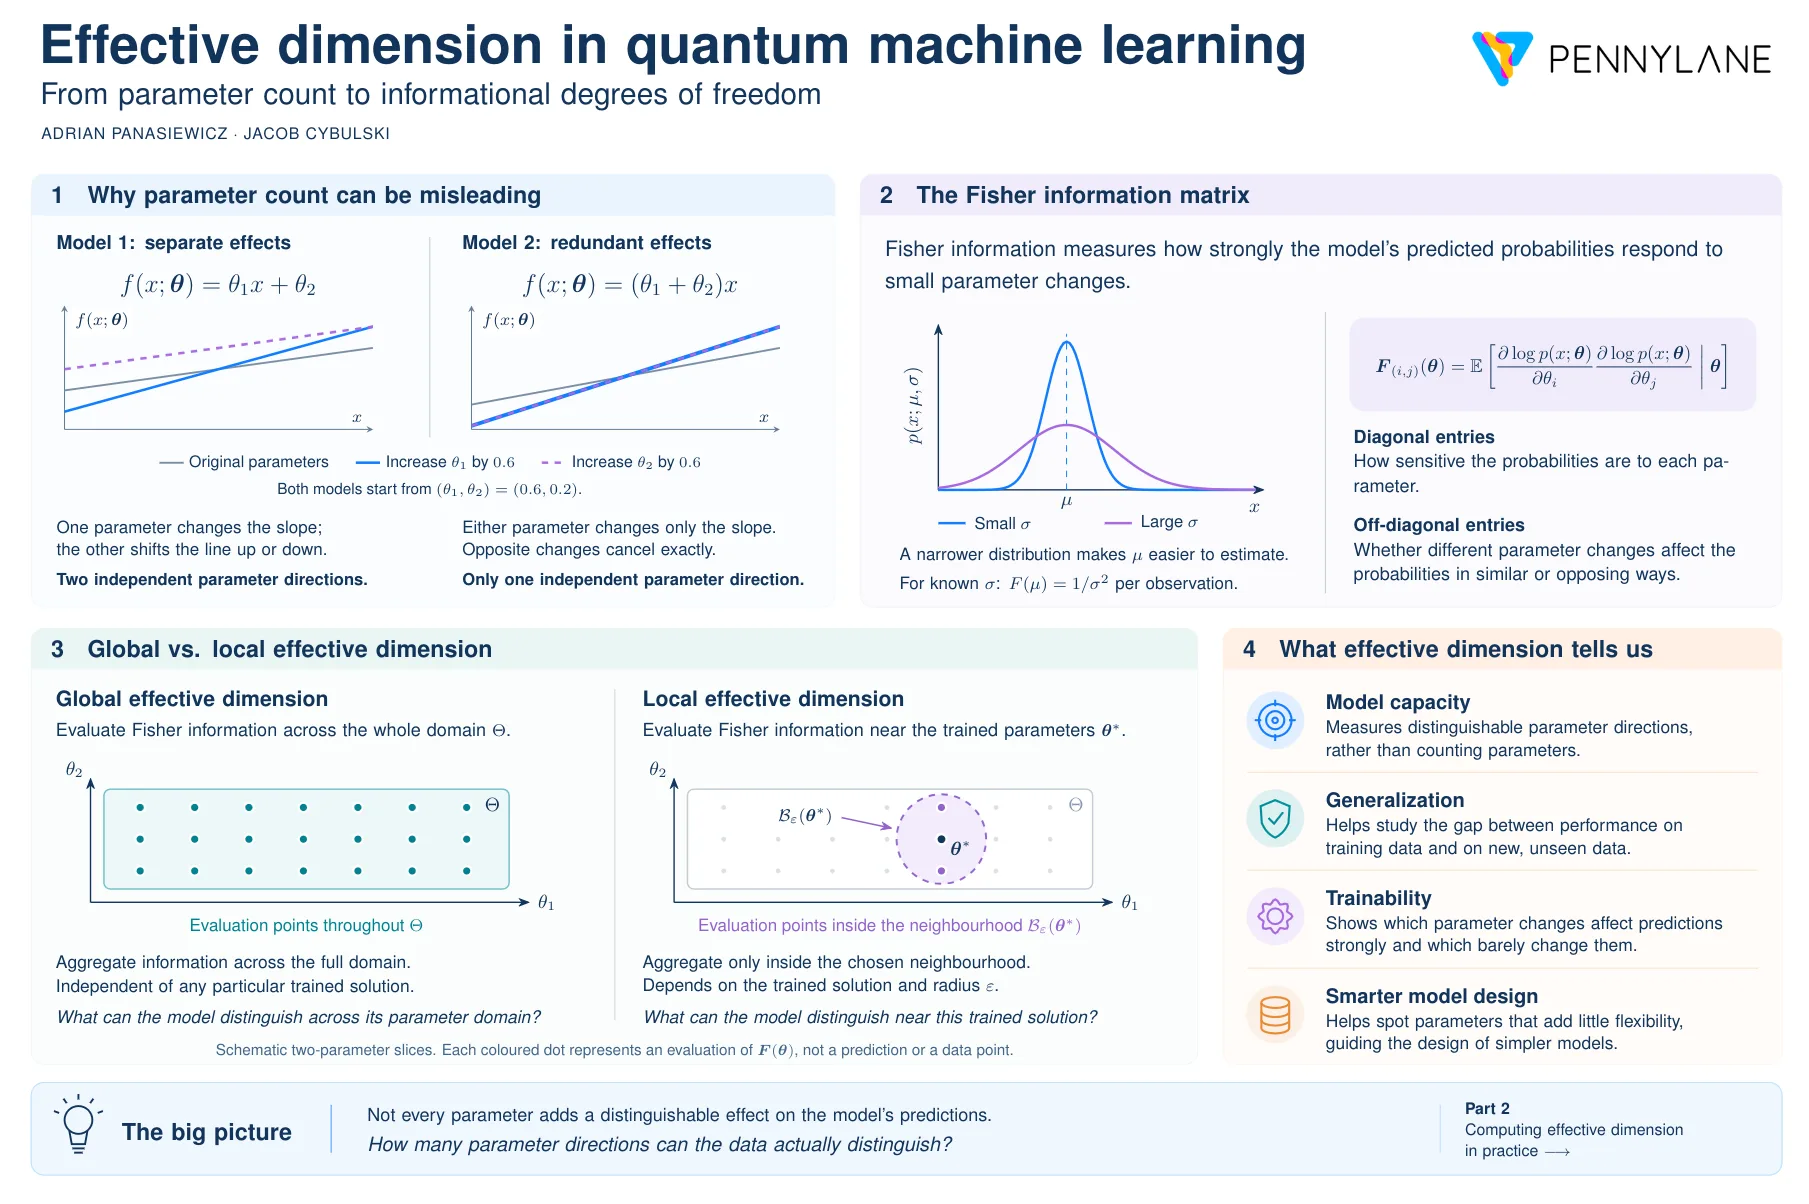
This text is the primary in a two-part sequence on efficient dimension. Right here, we develop the instinct and principle behind the metric and introduce its major elements. In Half 2, we’ll present tips on how to implement efficient dimension calculation in machine-learning experiments.
The vast majority of machine-learning fashions are described by the variety of their trainable parameters. Whereas the variety of parameters is a helpful mannequin property, it may be deceptive.
A mannequin might include many parameters that don’t create genuinely impartial methods of influencing its output. Conversely, a compact mannequin might use practically each parameter in a definite and significant means. Efficient dimension is a means of quantifying that distinction.
Extra parameters don’t suggest extra capability
Think about a easy instance (see Determine 1). Think about two fashions with parametersand.
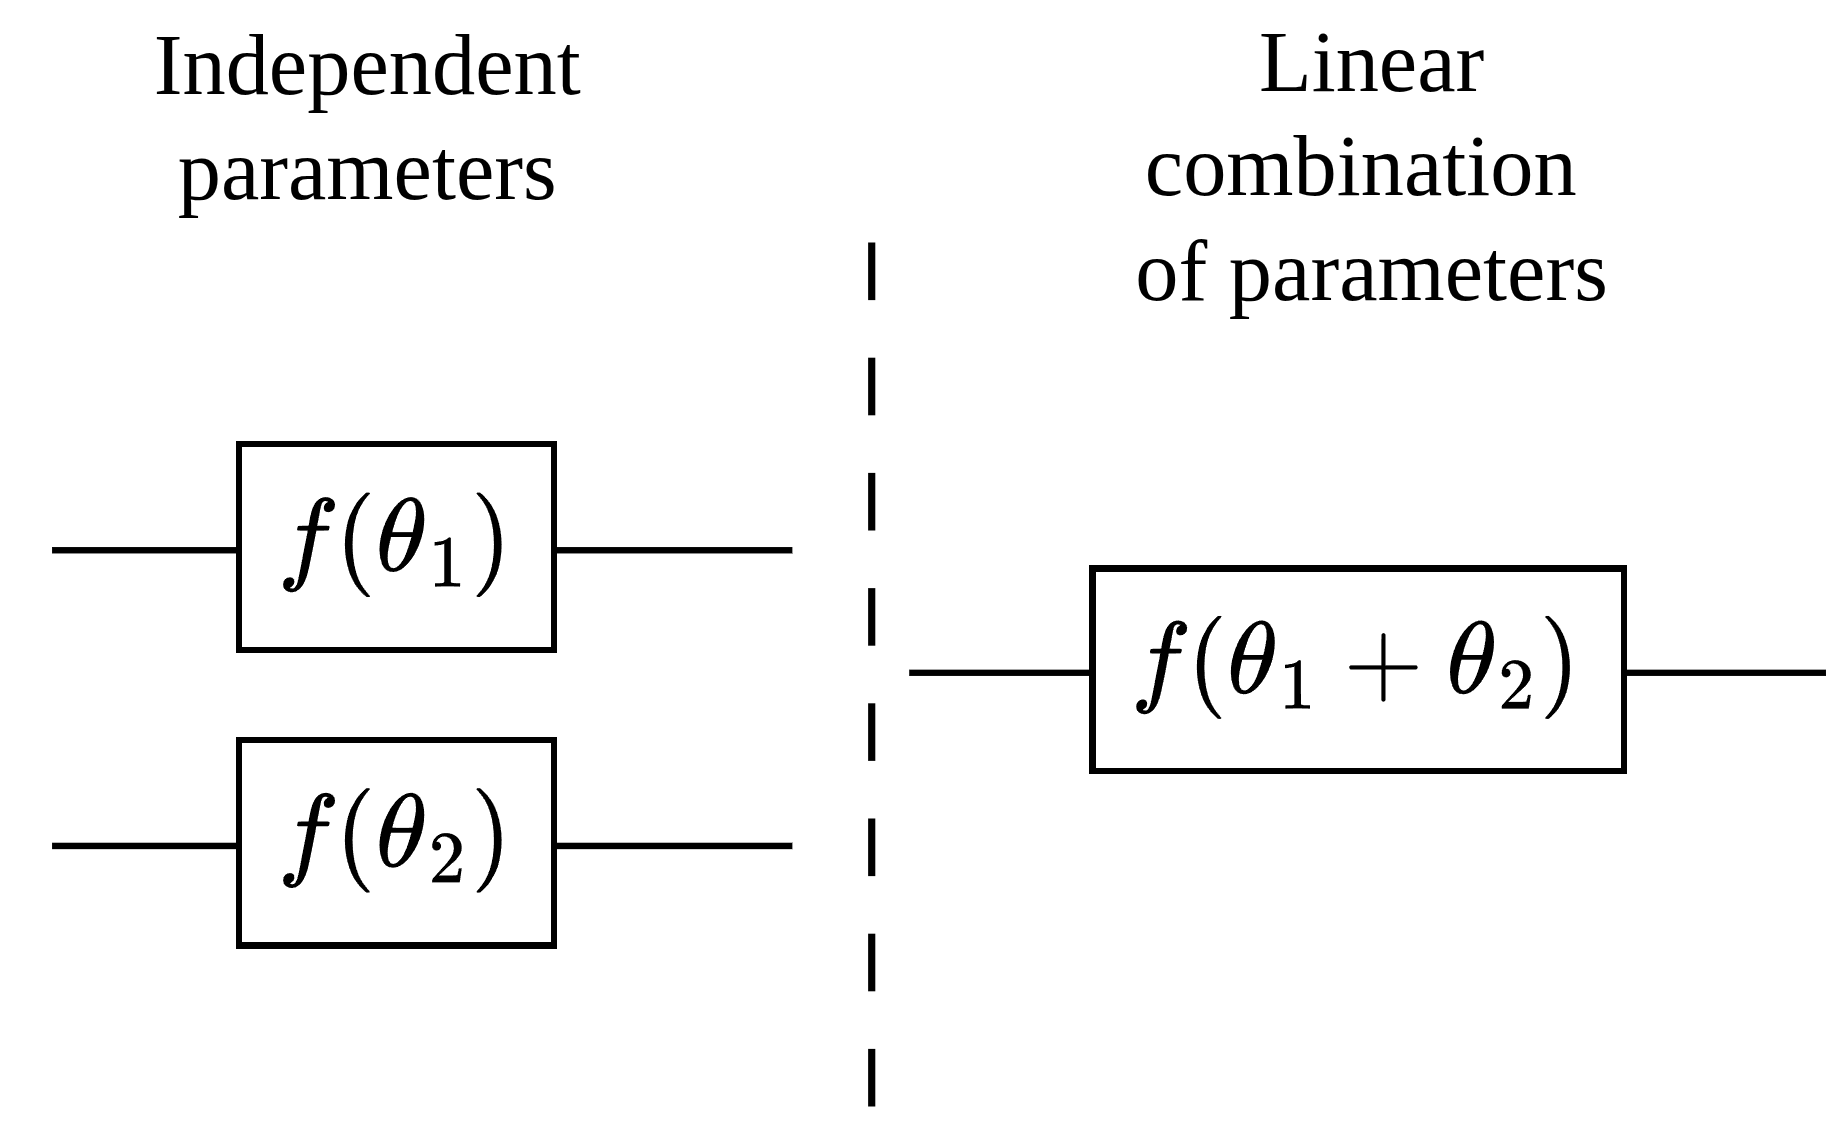
Within the first mannequin, the parameters have an effect on the output independently. Altering produces an impact that can’t, generally, be reproduced by altering . This mannequin can fluctuate in two impartial parameter “instructions”.
Within the second mannequin, the output relies upon solely on their sum:
Right here, many parameter pairs produce precisely the identical operate. For example, growing by and lowering by leaves the output unchanged. Though the mannequin formally has two parameters, it has just one diploma of freedom:
This instance illustrates the central thought: parameter rely doesn’t essentially symbolize the mannequin purposeful complexity.
What efficient dimension measures
Efficient dimension is a scale-dependent measure of knowledge complexity [1]. Initially developed in statistical info principle to quantify the variety of really lively parameters in a mannequin, it transforms the coordinate system to get rid of redundant parameter combos primarily based on the dimensions of accessible information. It has since been adopted in classical and quantum machine studying to exactly consider a mannequin’s expressivity, trainability, and talent to generalize to new information.
At a excessive stage, efficient dimension asks:
Throughout a selected parameter area and information distribution, what number of distinguishable and informational instructions does this mannequin have?
This query differs from the questions that may very well be answered by counting on the ideas of mannequin accuracy, loss, or the uncooked parameter rely.
|
Amount |
What it could actually inform us |
What it could actually miss |
|---|---|---|
|
Parameter rely |
The nominal measurement of the parameter vector |
Redundant or functionally inactive parameters |
|
Coaching loss |
How nicely optimization suits the coaching information |
Whether or not poor efficiency comes from optimization, mannequin mismatch, or initialization |
|
Check loss / accuracy |
Possible (generalization) efficiency on the inhabitants information |
If the mannequin may very well be nonetheless improved by additional coaching utilizing a special optimization strategy |
|
Efficient dimension |
The variety of distinguishable parameter instructions that may be derived from information |
It nonetheless is determined by the info distribution, parameter area, and pattern scale |
Importantly, efficient dimension is said to generalization. Below the assumptions of the framework, it could actually present a complexity-dependent sure on generalization efficiency [2]. Intuitively, a mannequin with fewer distinguishable parameter instructions ought to be much less efficient at becoming arbitrary fluctuations in a finite dataset.
It may possibly additionally assist analyse trainability. Extremely expressive fashions usually are not routinely straightforward to coach: some parameter instructions might have virtually no detectable impact on the output distribution, whereas others could also be strongly correlated. These results could make optimization poorly conditioned or successfully flat [3]. Moreover, such fashions might also be extra prone to overfitting, the place a mannequin captures noise or idiosyncrasies within the coaching information moderately than patterns that switch to unseen information, resulting in poor generalization.
Coaching and check losses are nonetheless important diagnostics, however they depend upon the optimization trajectory. A poor initialization, an unsuitable studying charge, or a weak optimizer could make a trainable structure look untrainable in a selected run. Efficient dimension as an alternative characterizes the mannequin’s parameter geometry relative to information, making it a complementary diagnostic moderately than a substitute for empirical coaching curves [4].
Past these diagnostics, efficient dimension issues as a result of parameter rely can misrepresent how complicated a mannequin actually is. Each extra parameter has a value: extra circuit evaluations for gradients, extra gates uncovered to noise, and a bigger search house to optimize. This value is worth it provided that the parameter provides a route wherein the mannequin can really change its habits. Efficient dimension estimates what number of such instructions exist, and so signifies whether or not a mannequin’s measurement is getting used. When two fashions carry out equally, the one with fewer efficient instructions is normally the higher alternative, because it achieves the identical outcome with much less complexity. That is Occam’s razor: favor the less complicated clarification when it accounts for the observations equally nicely. The purpose is to not decrease complexity in any respect prices, however to discover a mannequin whose complexity fits the issue.
The important thing device utilized in calculating the efficient dimension is the Fisher info matrix.
Fisher info: the instinct
The Fisher info matrix describes how delicate a distribution of mannequin predictions is within the face of modifications to its parameters. Put in a different way, it quantifies how a lot the noticed information can inform us concerning the parameters of the mannequin’s statistical profile.
Think about samples drawn from a Gaussian distribution with an unknown imply and identified customary deviation
Suppose we wish to estimate from samples. Examine two circumstances (see Determine 2):
-
A slim Gaussian, with small ,
-
A large Gaussian, with giant .
When is small, sampled factors cluster tightly across the imply. Even a modest dataset provides robust proof about the place lies.
When is giant, samples are far more dispersed. The identical variety of observations provides a much less exact estimate of , as a result of many close by imply values stay believable.
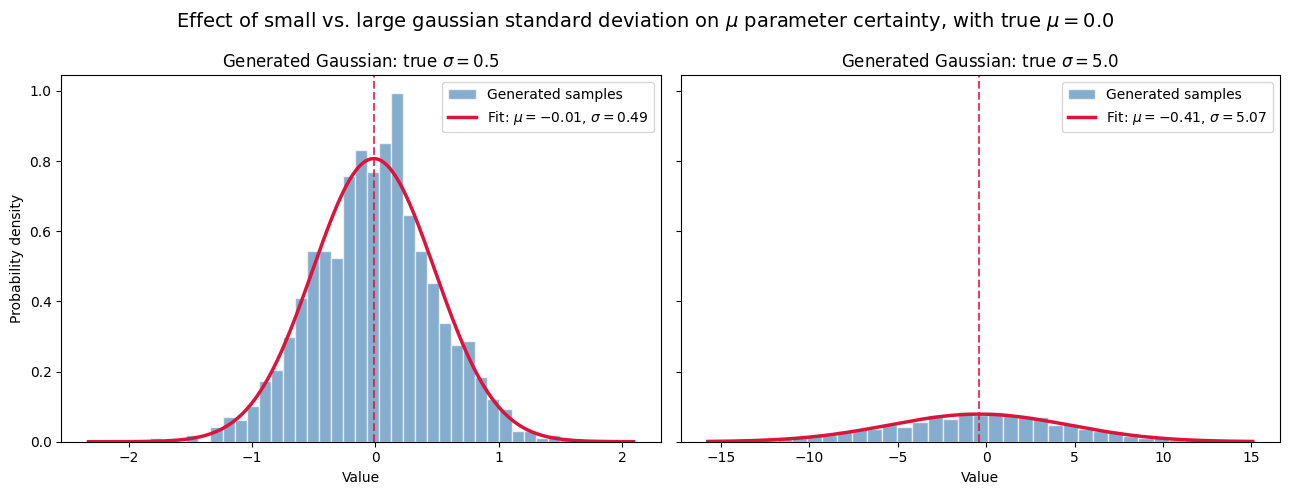
That is precisely what Fisher info captures. For a single remark from the Fisher details about is
forimpartial observations, info provides:
Extra information will increase info linearly. Extra noise decreases it.
From probability to Fisher info
To formalize this instinct, repair an noticed information leveland think about the chance density as a operate of the parameter That is the probability operate.
A probability tells us which parameter values make the noticed information roughly believable. It isn’t a chance distribution over until we introduce a previous and normalize it, as in Bayesian inference.
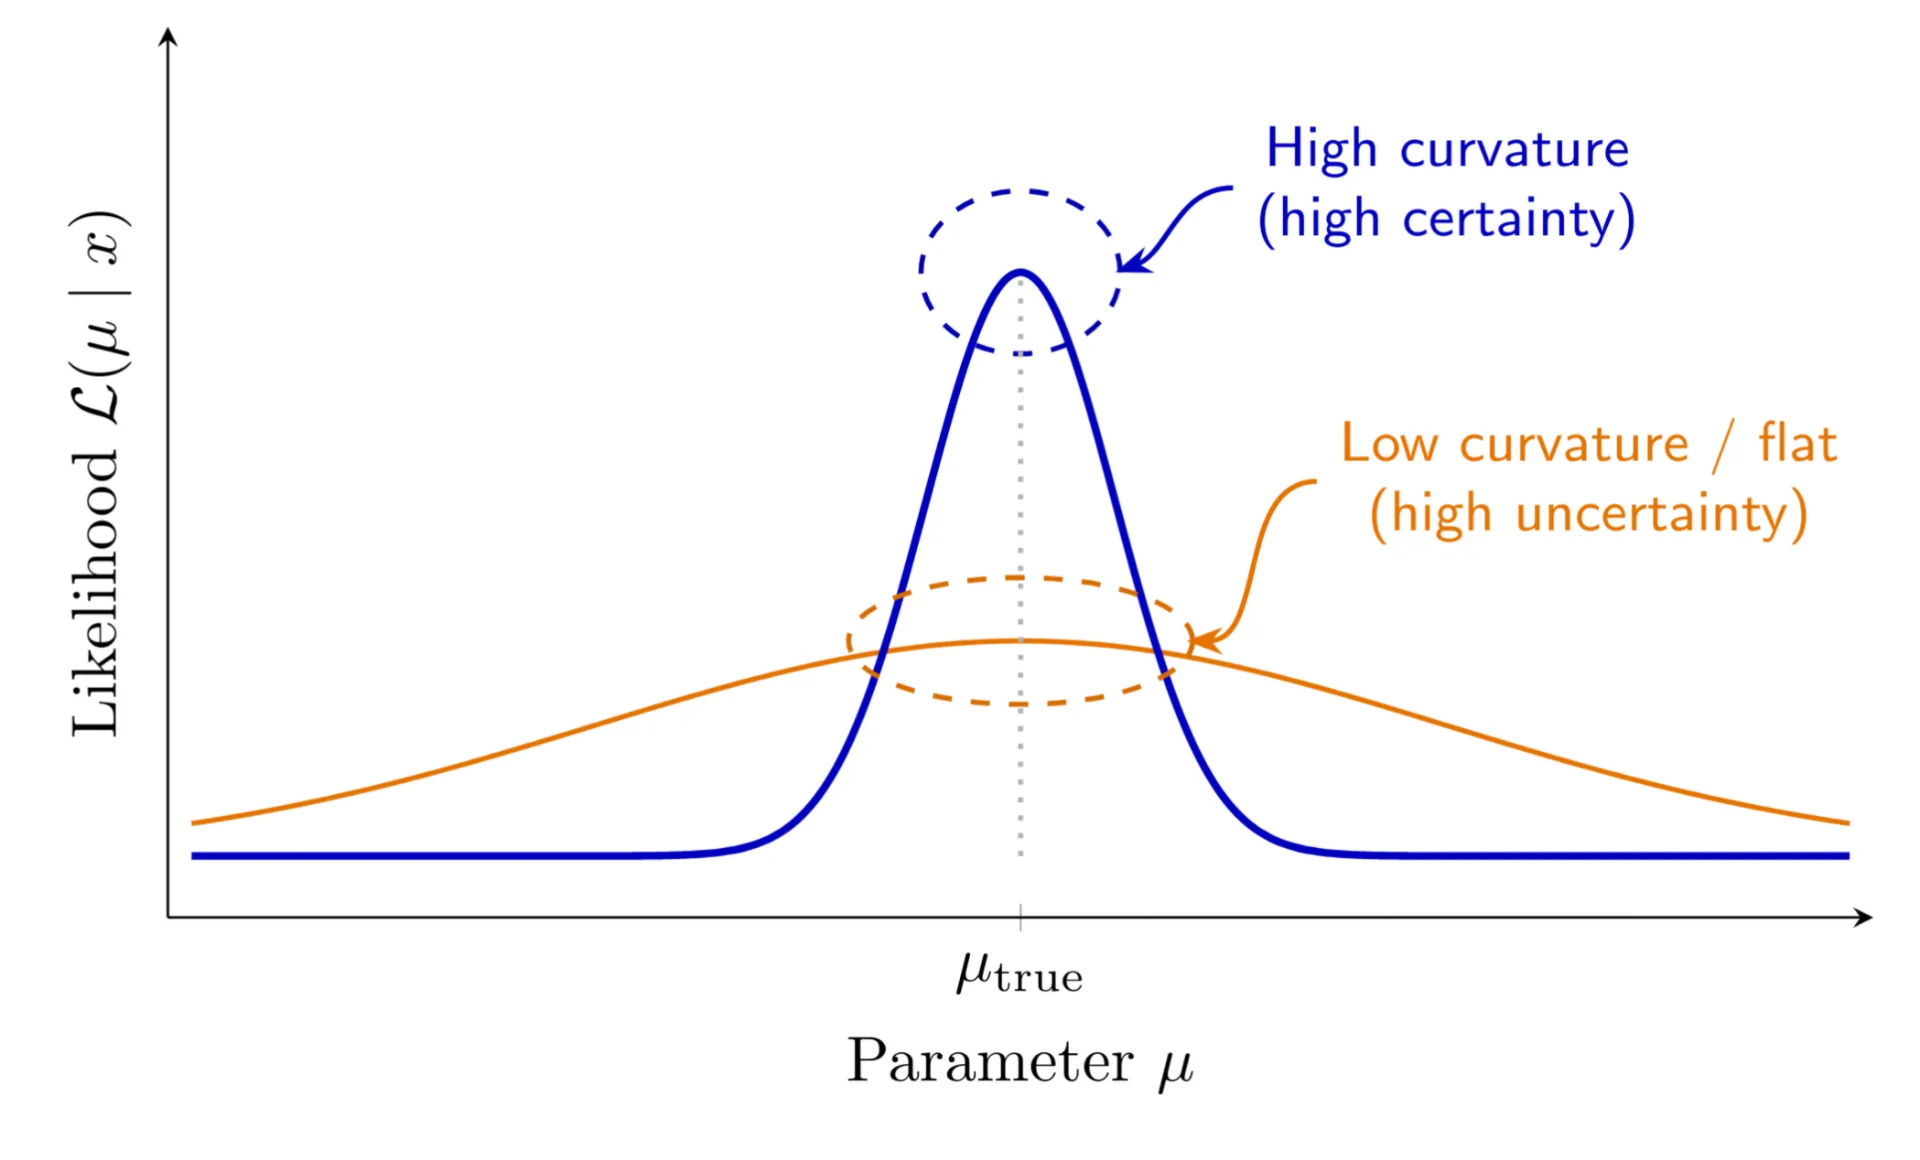
Now contemplate two probability curves (see Determine 3):
-
A flat probability: close by parameter values clarify the info virtually equally nicely.
-
A pointy probability: small modifications within the parameter make the remark a lot much less believable.
A pointy probability means the remark is informative concerning the parameter. A flat probability implies that it’s not.
The native sensitivity of the chances are captured by differentiating its logarithm with respect to the parameter:
This amount known as the rating operate, which gives the gradient (the vector of partial derivatives).
We use the logarithm for a sensible and mathematical motive. Merchandise of possibilities grow to be sums, and the by-product turns into a relative change:
The rating might be optimistic or unfavourable, relying on the route wherein the probability modifications. Fisher info ought to measure magnitude moderately than route, so we sq. the rating and common over all doable observations generated by the mannequin:
For a steady random variable, this expectation turns into
That is the Fisher info for a mannequin with one parameter.
Gaussian instance
Allow us to calculate the Fisher info for the imply of a Gaussian distribution with identified (see Determine 4).
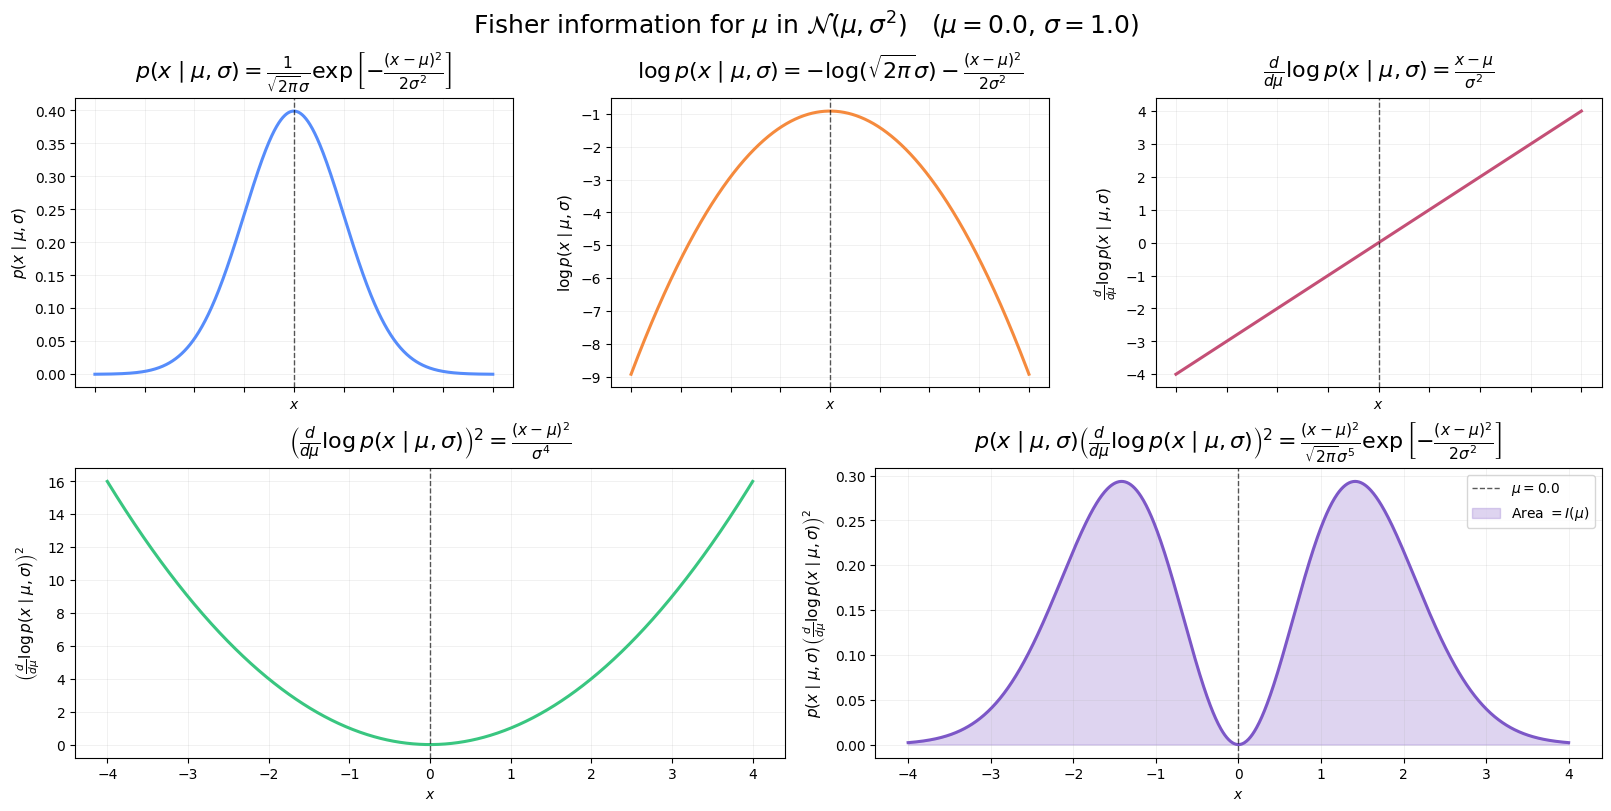
The Gaussian distribution might be represented as:
Taking the logarithm provides the log-likelihood:
Differentiating with respect to produces the rating:
Squaring it provides:
Lastly, taking the expectation with respect to yields
The outcome matches our instinct. A small variance makes the imply simpler to estimate, so the Fisher info is giant. A big variance makes the imply tougher to estimate, so the Fisher info is small.
From a scalar to a matrix
Actual machine-learning fashions have many parameters:
For a mannequin with a number of parameters, the Fisher info is a matrix whose entry is the anticipated product of the corresponding rating capabilities:
The diagonal entries measure sensitivity to particular person parameters. The off-diagonal entries measure how parameter results are “directionally” coupled, thus defining the geometry of the mannequin parameters.
This coupling is essential. If two parameters have an effect on the output in practically the identical means, the Fisher info matrix turns into near singular alongside one route. That’s the multivariate model of the sooner instance wherein solely mattered.
Efficient dimension makes use of this Fisher-information geometry to maneuver past uncooked parameter rely. It asks not what number of parameters the mannequin incorporates, however what number of instructions in parameter house the info can really resolve.
With the Fisher info matrix in hand, we will now outline and estimate efficient dimension.
The intuitive image of efficient dimension
Thus far, we’ve motivated the central query behind efficient dimension:
What number of informationally distinct instructions does a mannequin have?
The Fisher info matrix tells us how delicate a mannequin’s predictions are to modifications in its parameters. Nevertheless, to show that native sensitivity right into a measure of mannequin complexity, we first must outline what we imply by a mannequin.
A statistical mannequin might be written as a household of chance distributions listed by its trainable parameters:
Right here, is a parameter vector and is the parameter house. Relying on the machine-learning setting, might describe a joint distribution or, extra generally for supervised studying, a conditional predictive distribution .
The vital level is that each worth of defines a probably completely different predictive distribution. Collectively, all of those distributions type the mannequin household .
There are two helpful methods to check the efficient dimension of this household:
-
World efficient dimension, which considers your entire parameter house [1].
-
Native efficient dimension, which considers a neighborhood round a selected parameter configuration, normally one reached throughout or after coaching [2].
Native or world?
The worldwide efficient dimension asks what number of informational parameter instructions the mannequin has on common throughout the total parameter house .
This makes it helpful for architecture-level comparisons. For instance, if we wish to examine a variational quantum circuit with a classical neural community whereas controlling for different elements, world efficient dimension can reveal whether or not one structure has extra distinguishable purposeful levels of freedom than the opposite.
As a result of it averages over your entire parameter house, world efficient dimension shouldn’t be tied to 1 particular initialization or one optimization trajectory. That is useful when making managed, ceteris paribus comparisons between mannequin courses.
Nevertheless, world efficient dimension shouldn’t be interpreted as utterly impartial of knowledge. The Fisher info matrix is determined by the mannequin’s predictive distribution and, in supervised studying, usually on the distribution of enter information. What world efficient dimension removes is the dependence on a single educated resolution or a selected area visited by one optimizer run.
That broad perspective can be its major limitation.
A mannequin might include extremely informational areas of parameter house which can be by no means reached in apply. Maybe these areas are troublesome to optimize, maybe the initialization locations coaching distant from them, or maybe regularization prevents the mannequin from getting into them. In such circumstances, world efficient dimension might describe the theoretical capability of the mannequin household with out precisely reflecting the capability utilized by a selected educated mannequin.
This motivates the native efficient dimension.
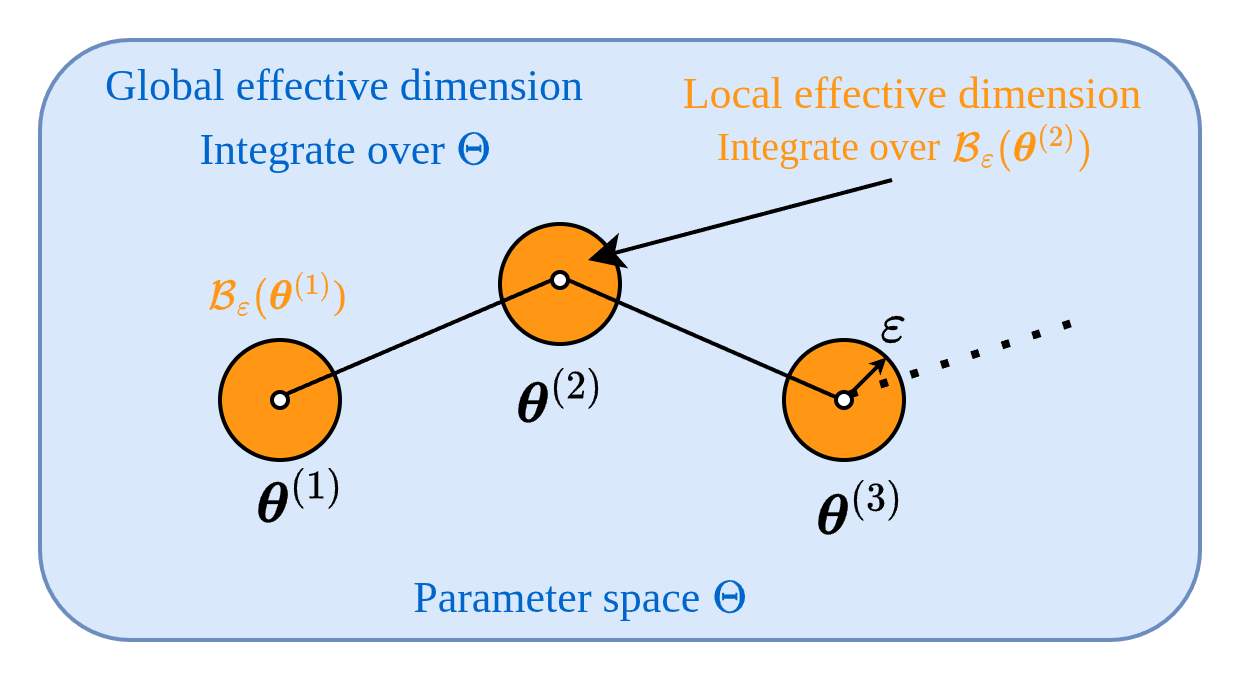
As an alternative of integrating over all of , native efficient dimension restricts the evaluation to a neighborhood round a reference parameter vector , usually the parameters obtained after coaching:
The native measure due to this fact asks a extra sensible query:
Close to the answer that coaching really discovered, what number of parameter instructions are distinguishable from the out there information?
On this sense, native efficient dimension can mirror the interplay between the structure, the dataset, initialization, and optimization process. It’s particularly helpful after we wish to perceive the complexity and generalization habits of a educated mannequin moderately than the theoretical capability of your entire structure. Moreover, native efficient dimension might help with verifying if the educated mannequin nonetheless has any unused studying capability.
To calculate native efficient dimension, we prohibit the evaluation to a small -ball round a particular parameter configuration. Though this can be a native approximation, the Fisher info matrix captures the sensitivity and correlations of the mannequin’s output distribution inside that neighborhood. This makes it doable to analyze broader questions concerning the mannequin’s native complexity and generalization habits.
The next diagram illustrates this distinction within the strategy to efficient dimension.
The effective-dimension system
We are able to now introduce the worldwide efficient dimension. Within the formulation utilized by Abbas et al. [1], it’s outlined as
There may be plenty of notation right here, however the primary thought is to take a look at the Fisher info all through a selected area of parameter house and mix what we discover right into a single quantity. Right here, is the variety of trainable parameters, is the id matrix, is the pattern measurement, and is a continuing within the development. The integral runs over the parameter area ; dividing by its quantity, , turns the integral into a median.
The unfamiliar object is . That is the Fisher info matrix , however with its general scale adjusted. To see how, first take the hint of , which provides up its eigenvalues. Then common that hint over the parameter area. The normalized matrix for the factor turns into:
The denominator is computed as soon as utilizing the entire area . Each Fisher matrix in that area is then multiplied by the identical issue. Why select this specific issue? It makes the common hint of the normalized Fisher matrix equal to :
In different phrases, the typical Fisher eigenvalue is ready to 1. This provides the matrices a typical reference scale, however it doesn’t make each eigenvalue equal to 1. For instance, in a two-parameter mannequin, eigenvalues of and have the identical hint as eigenvalues of and . The normalization treats their complete scale equally whereas retaining the vital distinction between two equally informative instructions and one dominant route.
For native efficient dimension, the identical expression is used, however is changed by an area ball , and is changed by the quantity of that ball.
That distinction enters the efficient dimension by way of the determinant:
That is the place the Fisher-information geometry enters the definition.
Studying the Fisher spectrum
To see what this determinant does, outline the size issue
This issue is similar at each parameter worth and is used to attain fascinating asymptotic properties of efficient dimension.
Now diagonalize the normalized Fisher info matrix:
The eigenvectors in establish impartial instructions in parameter house. The corresponding eigenvalues quantify how strongly modifications alongside these instructions have an effect on the mannequin’s output distribution.
As a result of determinants are invariant underneath rotations, we acquire
The sq. root within the effective-dimension system then provides
At a set level , taking the logarithm turns this product right into a sum:
That is the important thing expression for understanding efficient dimension. Every Fisher eigen-direction contributes in accordance with
The contribution is determined by whether or not the eigenvalue is giant or small relative to the decision scale .
Practically invisible instructions
First, contemplate a route with
Utilizing the first-order Taylor approximation,
This contribution is small.
Such an eigen-direction corresponds to a parameter mixture that hardly modifications the mannequin’s predictive distribution on the chosen decision. The information can’t reliably distinguish motion in that route, so it ought to contribute little to the mannequin’s efficient complexity.
Informational instructions
Now contemplate the alternative regime:
Then the turns into negligible:
Utilizing the logarithm rule provides:
Within the effective-dimension definition, the numerator is normalized by . Within the large- regime, the scale-dependent time period dominates:
The remaining eigenvalue-dependent correction,
turns into comparatively small when is giant and the eigenvalue stays finite.
That is why efficient dimension behaves like a gentle, resolution-dependent rely of informational parameter instructions.
It doesn’t merely ask, “What number of parameters are within the mannequin?”
As an alternative, it asks:
On the decision set by , what number of parameter instructions can the info distinguish?
Within the large- restrict, the efficient dimension approaches the maximal rank of the Fisher info matrix underneath the assumptions of the development.
Why the size issues
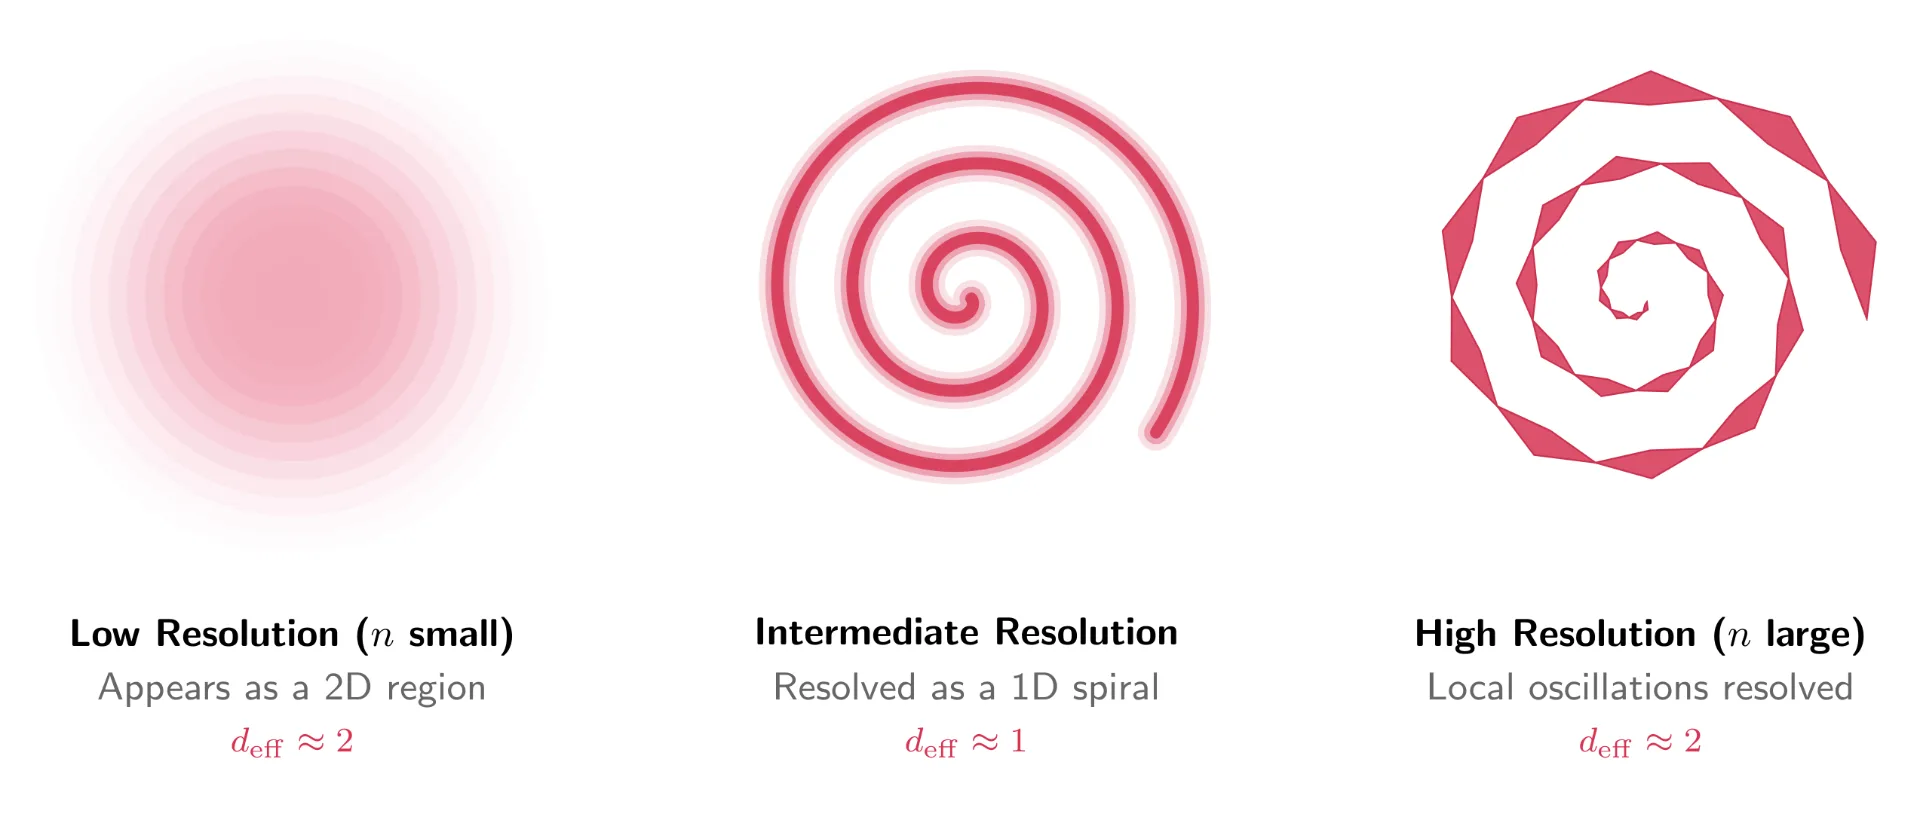
The parameter is commonly described because the dataset measurement. That’s broadly appropriate, as a result of the effective-dimension framework connects to finite-sample generalization. However it is usually useful to interpret as a decision scale.
A bigger dataset can distinguish smaller variations between two close by predictive distributions. As will increase, instructions that have been beforehand too weak to watch might grow to be informative.
The geometric analogy is helpful right here.
Think about inspecting an object at completely different magnifications. At a rough scale, it might appear like a easy two-dimensional floor. At a finer scale, you could uncover that the floor is definitely a slim curve winding by way of house. At a good finer scale, that curve might reveal small oscillations or extra construction.
That is why it’s good apply to guage efficient dimension throughout a spread of values moderately than reporting just one quantity. In an actual utility, essentially the most related values are these close to the dimensions of the datasets on which the mannequin will really be educated.
Ultimate phrases
Efficient dimension is a complexity measure primarily based on the geometry of the mannequin’s statistical profile. It goes past uncooked parameter rely by figuring out what number of parameter instructions are literally distinguishable from information.
Its worth comes from connecting a number of concepts which can be usually studied individually:
-
Mannequin capability and expressivity.
-
Parameter redundancy and identifiability.
-
Fisher-information geometry.
-
Finite-data generalization.
-
Trainability and optimization landscapes.
Below the assumptions of the underlying principle, efficient dimension can be utilized to derive bounds on generalization error. It shouldn’t be learn as a direct prediction of check accuracy, however it gives a principled complexity amount that may complement empirical coaching curves and validation outcomes.
Importantly, efficient dimension quantifies studying capability by way of parameter house, a perspective that applies equally to classical and parameterized quantum fashions. In quantum machine studying, different frameworks characterize capability straight over the Hilbert house of quantum states, which this metric doesn’t explicitly handle.
On this article, we launched the motivation for efficient dimension and the Fisher-information geometry behind it. We then noticed how the Fisher spectrum determines which parameter instructions contribute to the complexity of a mannequin at a selected information scale.
The following article on this sequence will transfer from principle to apply: tips on how to implement the Fisher info matrix and efficient dimension calculation for a machine-learning mannequin.
Bibliography
[1] A. Abbas, D. Sutter, C. Zoufal, A. Lucchi, A. Figalli, and S. Woerner, “The facility of quantum neural networks,” Nat. Comput. Sci., vol. 1, no. 6, pp. 403–409, Jun. 2021, doi: 10.1038/s43588-021-00084-1.
[2] A. Abbas, D. Sutter, A. Figalli, and S. Woerner, “Efficient dimension of machine studying fashions,” Dec. 09, 2021, arXiv: arXiv:2112.04807. doi: 10.48550/arXiv.2112.04807.
[3] E. Grant, L. Wossnig, M. Ostaszewski, and M. Benedetti, “An initialization technique for addressing barren plateaus in parametrized quantum circuits,” Quantum, vol. 3, p. 214, Dec. 2019, doi: 10.22331/q-2019-12-09-214.
[4] S. Amari and H. Nagaoka, Strategies of Info Geometry, vol. 191. in Translations of Mathematical Monographs, vol. 191. Windfall, Rhode Island: American Mathematical Society, 2007. doi: 10.1090/mmono/191.