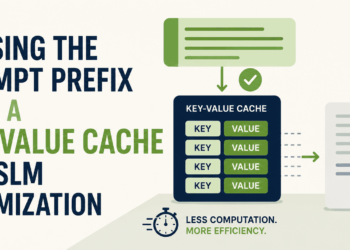
Reusing the Immediate Prefix with a Key-Worth Cache for SLM Optimization
In a earlier article we mentioned constraining output house for small language mannequin (SLM) slim automation optimization. We talked about ...
In a earlier article we mentioned constraining output house for small language mannequin (SLM) slim automation optimization. We talked about ...
The Mannequin Matches, the Requests Do notVRAM was once a training-time fear. You sized your cluster for the weights, the ...
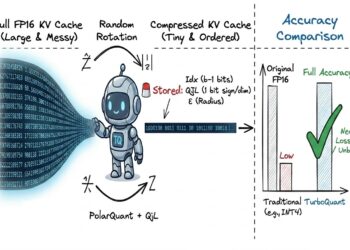
any time with Transformers, you already know consideration is the mind of the entire operation. It's what lets the mannequin ...
, we talked intimately about what Immediate Caching is in LLMs and the way it can prevent some huge cash ...

On this article, you'll discover ways to add each exact-match and semantic inference caching to giant language mannequin functions to ...