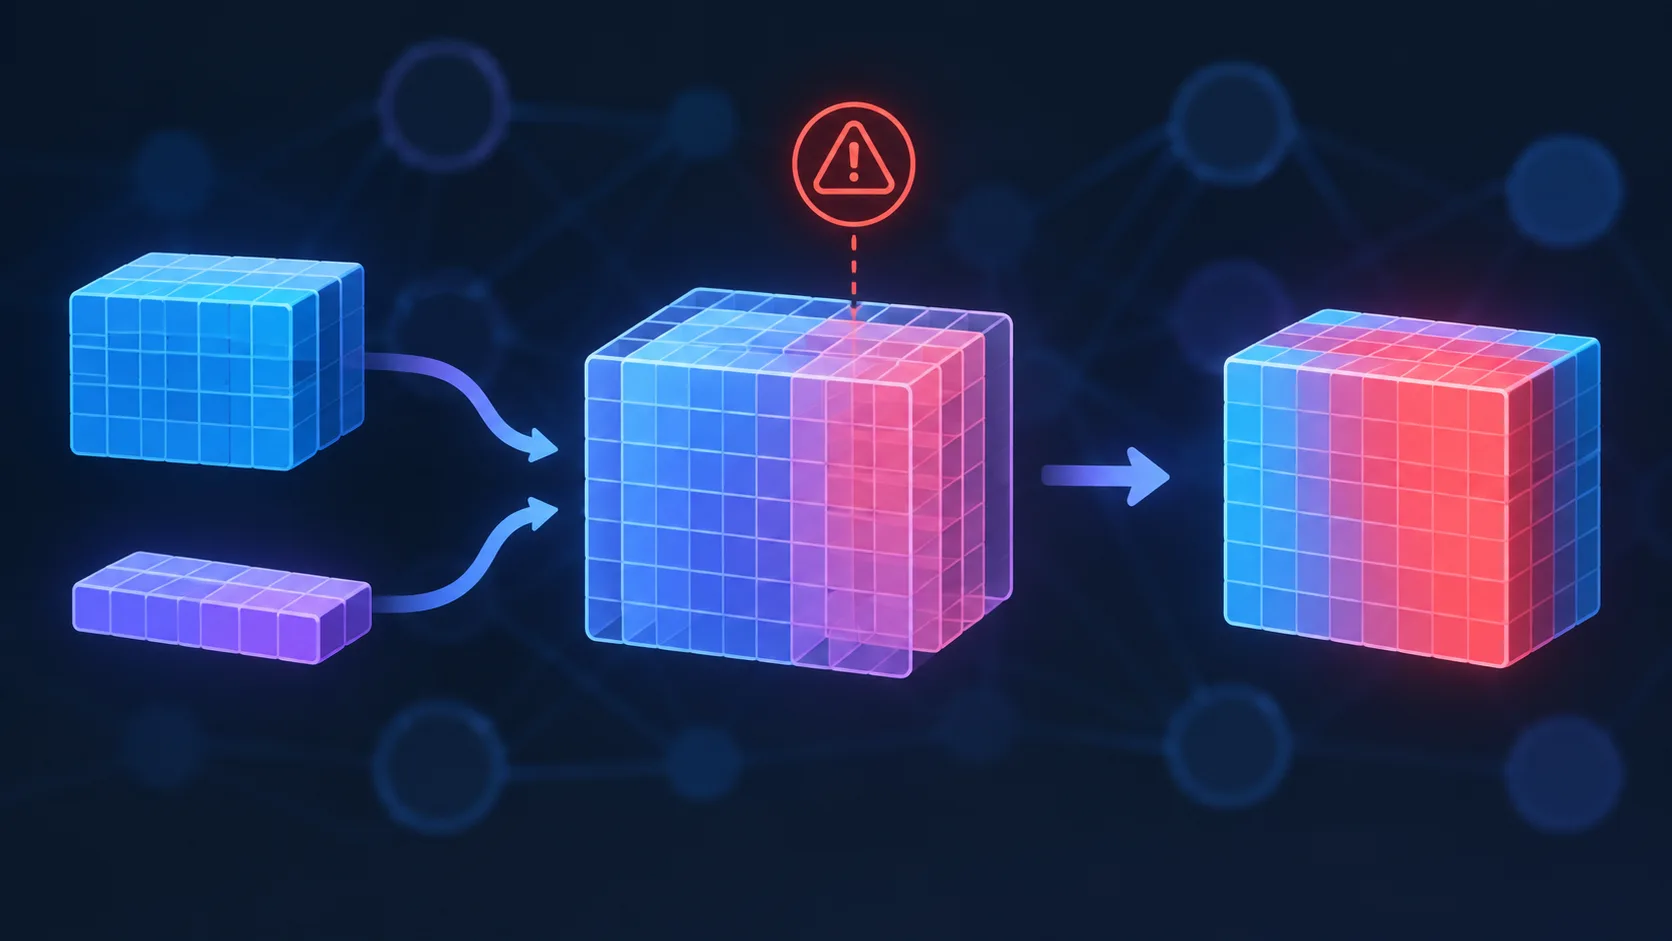
Full disclosure: I simply wasted ~$4,000 in compute prices final month due to this very silent, very actual bug that I’ve possible been sufferer to many instances over my profession and by no means even knew it.
In case you are an ML practitioner, or work in deep studying, I can assure this has already occurred to you, and you probably by no means even realized it.
It’d even be derailing your work proper now.
On this article I spotlight how a single mismatched tensor dimension can silently rewrite your loss operate, intestine your gradients, or poison your challenge, with out PyTorch or TensorFlow ever elevating an error. Particularly:
-
What silent broadcasting is
-
Actual world examples of how silent broadcasting destroys fashions
-
Stopping silent broadcasting errors in your coaching pipeline
This downside is infamous, not often spoken about, and a severe menace to your modeling pipeline. Suppose I am being overly dramatic? It is possible that one (or extra) of the fashions you have tried to coach in your profession has suffered from this quite common bug.
What silent broadcasting is
Broadcasting is usually helpful. It permits you to do elementwise math on tensors of various shapes with out writing tedious loops or reshapes.
It really works like so:
-
If two dimensions are equal, they match.
-
If one among them is
1, it will get “stretched” to match the opposite. -
If a tensor is lacking a dimension completely, it is handled as
1. -
If not one of the above holds, you lastly get an error.
Broadcasting was designed to make (N, D) + (D,), ops like including a bias vector to each row of a batch, easy.
This identical rule that makes that op handy additionally makes (N, 1) and (N,) “appropriate,” although one is a column vector and the opposite is a flat vector. Combining them produces an (N, N) matrix that may be very possible not what both tensor was imagined to characterize.
This (N, 1) and (N,) compatibility is the hidden killer that exists in all tensor frameworks.
For instance:
The hazard right here is that if you happen to supposed an elementwise (4,) + (4,) operation, there is no such thing as a error. You simply forgot to squeeze or unsqueeze a superbly legitimate mathematical operation in each frameworks.
The failure mode is: this op runs, silently.
The loss goes down and the gradients circulation. However your mannequin is coaching in the direction of rubbish.
Let me clarify in additional element with some actual world examples.
Actual world examples of how silent broadcasting destroys fashions
Instance 1: Your regression loss quietly optimizes for the imply, not the enter
That is the only most typical model of the bug, and it is brutal as a result of loss curves look fully regular.
In PyTorch:
Identical for Tensorflow/Keras:
pred - goal broadcasts to (N, N), computing goal[i] - pred[j] for each pair (i, j) as a substitute of the N variations you supposed. The “loss” you are minimizing is definitely:
Take the spinoff with respect to any single prediction and set it to zero, and each converges to the identical worth: the batch imply of the targets.
The true minimal of this damaged goal is a mannequin that ignores its enter completely and simply memorizes . Coaching would not crash, and the loss drops quick, as a result of collapsing to a relentless is a brilliant simple factor to optimize for.
You simply find yourself with a mannequin that has discovered nothing concerning the relationship between x and y. I take into consideration what number of instances I’ve truly encountered this within the wild and I cringe.
Here is an ideal instance from /r/deeplearning:
The solutions: New fashions, new options. Not a single point out of the commonest motive for this error. Actually, I am constructive that you’re going to see fashions skilled like this in manufacturing as a result of the loss seems so asymptomatic and the imply worth answer can truly produce cheap efficiency.
One other within the wild instance:
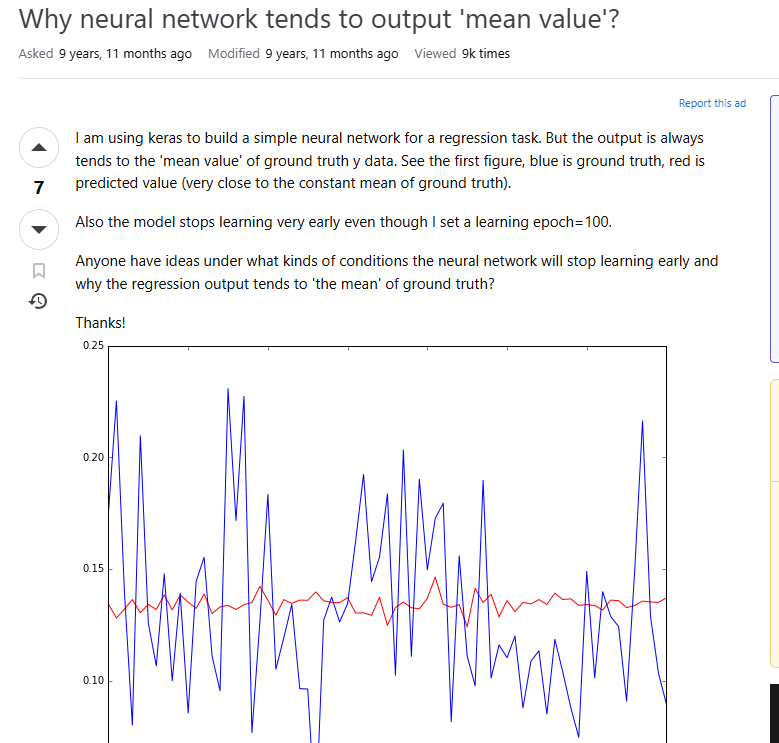
Once more, the solutions fail to pinpoint the precise downside, as a result of it is so notoriously hidden. The output is a linear layer, batched: (N, 1), whereas the targets are (N,). Regardless that this publish is aged, the reason for this error is nowhere within the feedback. I assert that the issue remains to be plaguing the machine studying group and nobody is speaking about it.
Instance 2: Coverage-gradient loss destroys credit score project in RL
Identical form mismatch, worse penalties, as a result of the entire level of coverage gradients is per-sample credit score project. This value me precise cash.
log_probs * benefits broadcasts to (N, N). As soon as you’re taking the imply, the algebra collapses to -mean(log_probs) * imply(benefits), a single scalar benefit utilized uniformly to each motion within the batch, as a substitute of every motion being strengthened or punished by its personal benefit.
This may be notably damaging when benefits are normalized to roughly zero imply. In that case, the broadcasted product can produce a particularly weak or practically zero policy-gradient sign although the person benefits comprise substantial info.
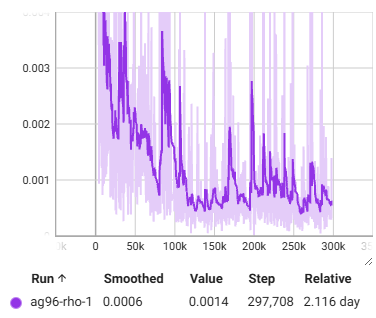
The complete mechanism of “enhance the likelihood of actions that turned out properly, lower those that did not” is gone. The agent would not clearly fail as a result of RL coaching is noisy by nature. RL insurance policies plateau for a large number of causes, so one which’s caught as a result of its gradient sign has been averaged seems an identical to a coverage thats misperforming due to a foul hyperparameters or a poorly tuned reward operate.
Seems, weeks of reward shaping might have been changed by including a .squeeze(-1) op on a worth head.
Here is an instance proper out of my very own tensorboard.
So, how may one forestall this “characteristic” from killing your coaching course of?
Stopping silent broadcasting errors in your coaching pipeline
The repair for all of the examples above is similar one line behavior, utilized on the two locations broadcasting usually errs: loss computation and masks utility.
This prices nothing at runtime and turns each silent broadcast right into a loud, quick AssertionError at precisely the road that brought on it.
In TensorFlow, tf.debugging.assert_shapes([(pred, target.shape)]) or tf.ensure_shape does the identical job and, in contrast to a naked Python assert, nonetheless fires inside a compiled tf.operate graph.
For coaching code, that is typically extra worthwhile than trusting the framework to resolve whether or not two tensors are broadcast-compatible. Do not depend on the framework to reply the query: “is that this semantically appropriate?”
By no means belief an implicit squeeze
Favor pred.squeeze(-1) over naked pred.squeeze() (which silently drops each size-1 dimension, together with your batch dimension if N == 1), and like libraries like einops for something with greater than two axes:
einops operations fail on form mismatches as a substitute of broadcasting by way of them. That is the complete worth proposition for this use case.
Add adversarial form unit checks, not simply correctness checks.
Write checks that intentionally go in an (N, 1) the place an (N,) is anticipated and assert that your loss operate raises, not that it returns a quantity:
Use static form typing (if accessible)
Instruments like jaxtyping or torchtyping allow you to annotate anticipated shapes Float[Tensor, "batch seq"]) and catch mismatches through runtime checks or static evaluation earlier than the tensors ever attain an op that will silently broadcast them.
When loss goes to NaN, bisect the ahead go, do not simply decrease the educational charge
Hook into intermediate activations register_forward_hook in PyTorch and verify for the first tensor that comprises a NaN. Chasing NaNs by shrinking the educational charge or clipping gradients treats the symptom; discovering the precise op that produced the primary NaN finds masks bugs in minutes.
Wrapping up
Do not waste time on this bug. Know that it exists, and catch it earlier than it occurs with some very simple to implement one line assertions. I guarantee you, it should present up in your coaching pipeline sooner or later or one other and baffle you.
Thanks for studying!