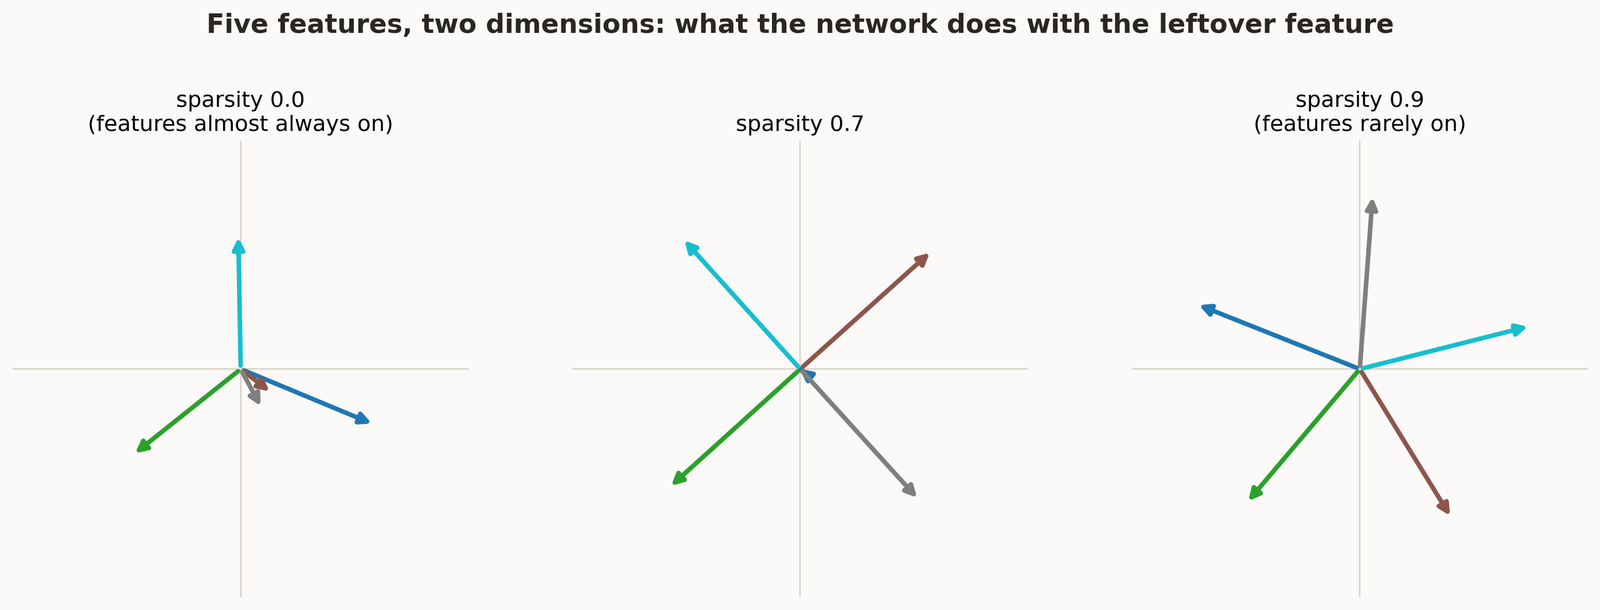
I wasn’t anticipating geometry to indicate up. I used to be reproducing a small piece of Anthropic’s 2022 interpretability paper, “Toy Fashions of Superposition” [1], largely as a result of the central declare sounded implausible sufficient that I wished to verify it myself quite than take it on religion. The declare: a neural community can symbolize extra options than it has dimensions to work with, by packing them in at angles to one another and tolerating a little bit of interference. Ask it to compress 5 issues into two dimensions beneath the suitable circumstances, and it does not decide two winners and quit on the remainder. It arranges all 5 into an ideal pentagon.
I did not have PyTorch or any autograd library obtainable, and no web entry to put in one both, so every part beneath is obvious NumPy, and I derived the backward move by hand. That turned out to be the proper of annoying. Deriving the gradients your self forces you to truly perceive what the mannequin is doing to the information, quite than trusting a .backward() name you’ve got by no means had to consider. If in case you have a math background and you have by no means hand-derived backprop by way of even a tiny community, I would genuinely suggest it as an train. It is ten minutes of chain rule that makes every part downstream click on.
All the information on this submit is artificial. I generate it myself in code, there isn’t any exterior dataset concerned, which can be how the unique paper does it. All pictures, until in any other case famous, are by the creator.
The issue that is attempting to clarify
This is the motivating puzzle, and it is an actual one in interpretability analysis. For those who look inside a educated neural community hoping to search out particular person neurons that cleanly symbolize particular person ideas, one neuron for “is that this a canine,” one for “is that this crimson,” you largely do not discover that. As a substitute you discover neurons that appear to reply to a number of unrelated issues without delay, a neuron that fires for each cat faces and the entrance ends of vehicles, say. That is referred to as polysemanticity, and it makes interpretability a lot tougher, as a result of you’ll be able to’t simply learn off what a community “believes” by inspecting particular person models.
The paper’s proposal is that polysemanticity is not noise or failure. It is an actual technique the community makes use of on goal, as a result of it has extra ideas to symbolize than it has neurons to symbolize them with, and most of these ideas are hardly ever lively on the similar time. If two options are virtually by no means “on” concurrently, the community can afford to allow them to share a route in activation area, for the reason that interference solely prices one thing on the uncommon events each occur to fireplace collectively. This packing technique is what the paper calls superposition, and its toy mannequin is designed to be the only potential setting the place you’ll be able to watch it occur and really measure it.
The mannequin, and the maths I needed to work out to coach it
The setup is small on goal. You’ve got n artificial options, each a quantity between 0 and 1 that is zero more often than not (that is the sparsity) and nonzero the remainder of the time. You compress them down by way of a bottleneck of m hidden dimensions, the place m is smaller than n, after which attempt to reconstruct the unique options on the way in which again out by way of a ReLU.
Concretely, with a single weight matrix W of form (m, n) used for each the compression and the reconstruction:
Coaching minimizes a weighted squared error between and , the place every function i will get an significance weight , so the community is informed some options matter extra to get proper than others:
Since I did not have autograd, I wanted and by hand. This is not unhealthy when you set it up as two matrix multiplications sharing the identical weights. Let be the pre-ReLU output. Commonplace backprop by way of the squared error and the ReLU provides a delta vector:
the place is elementwise multiplication and is the ReLU masks. Then, as a result of W seems twice, as soon as within the compression step and as soon as within the reconstruction step, the 2 contributions to the gradient simply add:
That second equation is the one half that took me a minute to get proper, and it is a good small reminder of why tied weights are slightly extra attention-grabbing to distinguish than they give the impression of being.
This is the total implementation, batched over samples, with Adam written out explicitly since I did not have that free of charge both:
Each outcome beneath got here from really working this, not from the paper’s numbers.
Experiment one: the community quietly provides up on the options that do not matter
First verify: does the compression even work, and what occurs to the options that matter much less? I educated with 20 options going into 5 hidden dimensions, sparsity 0.9 (every function is zero 90 p.c of the time), and significance decaying geometrically throughout the 20 options, so function 0 issues most and have 19 issues least.
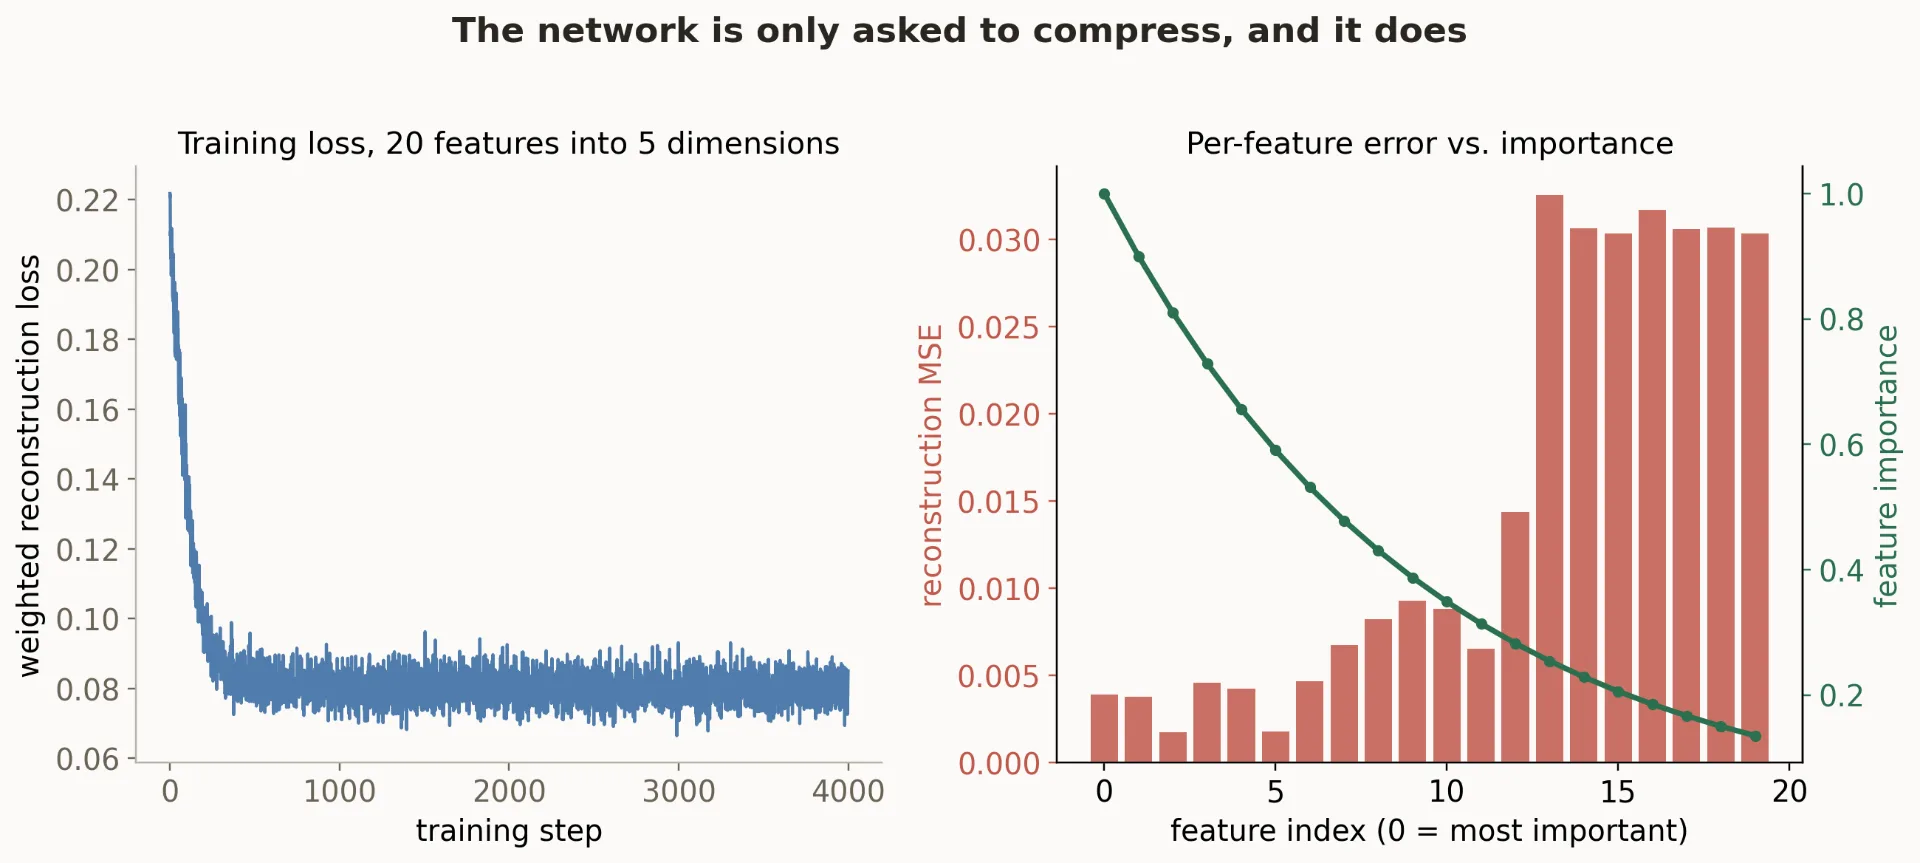
The correct panel is the one I discovered genuinely satisfying to see seem from actual numbers as a substitute of an outline in a paper. The community is not reconstructing all 20 options with mediocre accuracy. It is making a transparent choice: symbolize the essential options nicely, and previous a reasonably sharp threshold, simply cease bothering with the remainder. No person informed it to try this. It fell out of gradient descent on a plain weighted MSE loss.
Experiment two: 5 options, two dimensions, and the pentagon
That is the outcome that received me to write down this up. Squeeze 5 equally essential options into simply 2 hidden dimensions, and watch what the 5 realized function vectors really appear to be as arrows in that 2D area, at three completely different sparsity ranges.
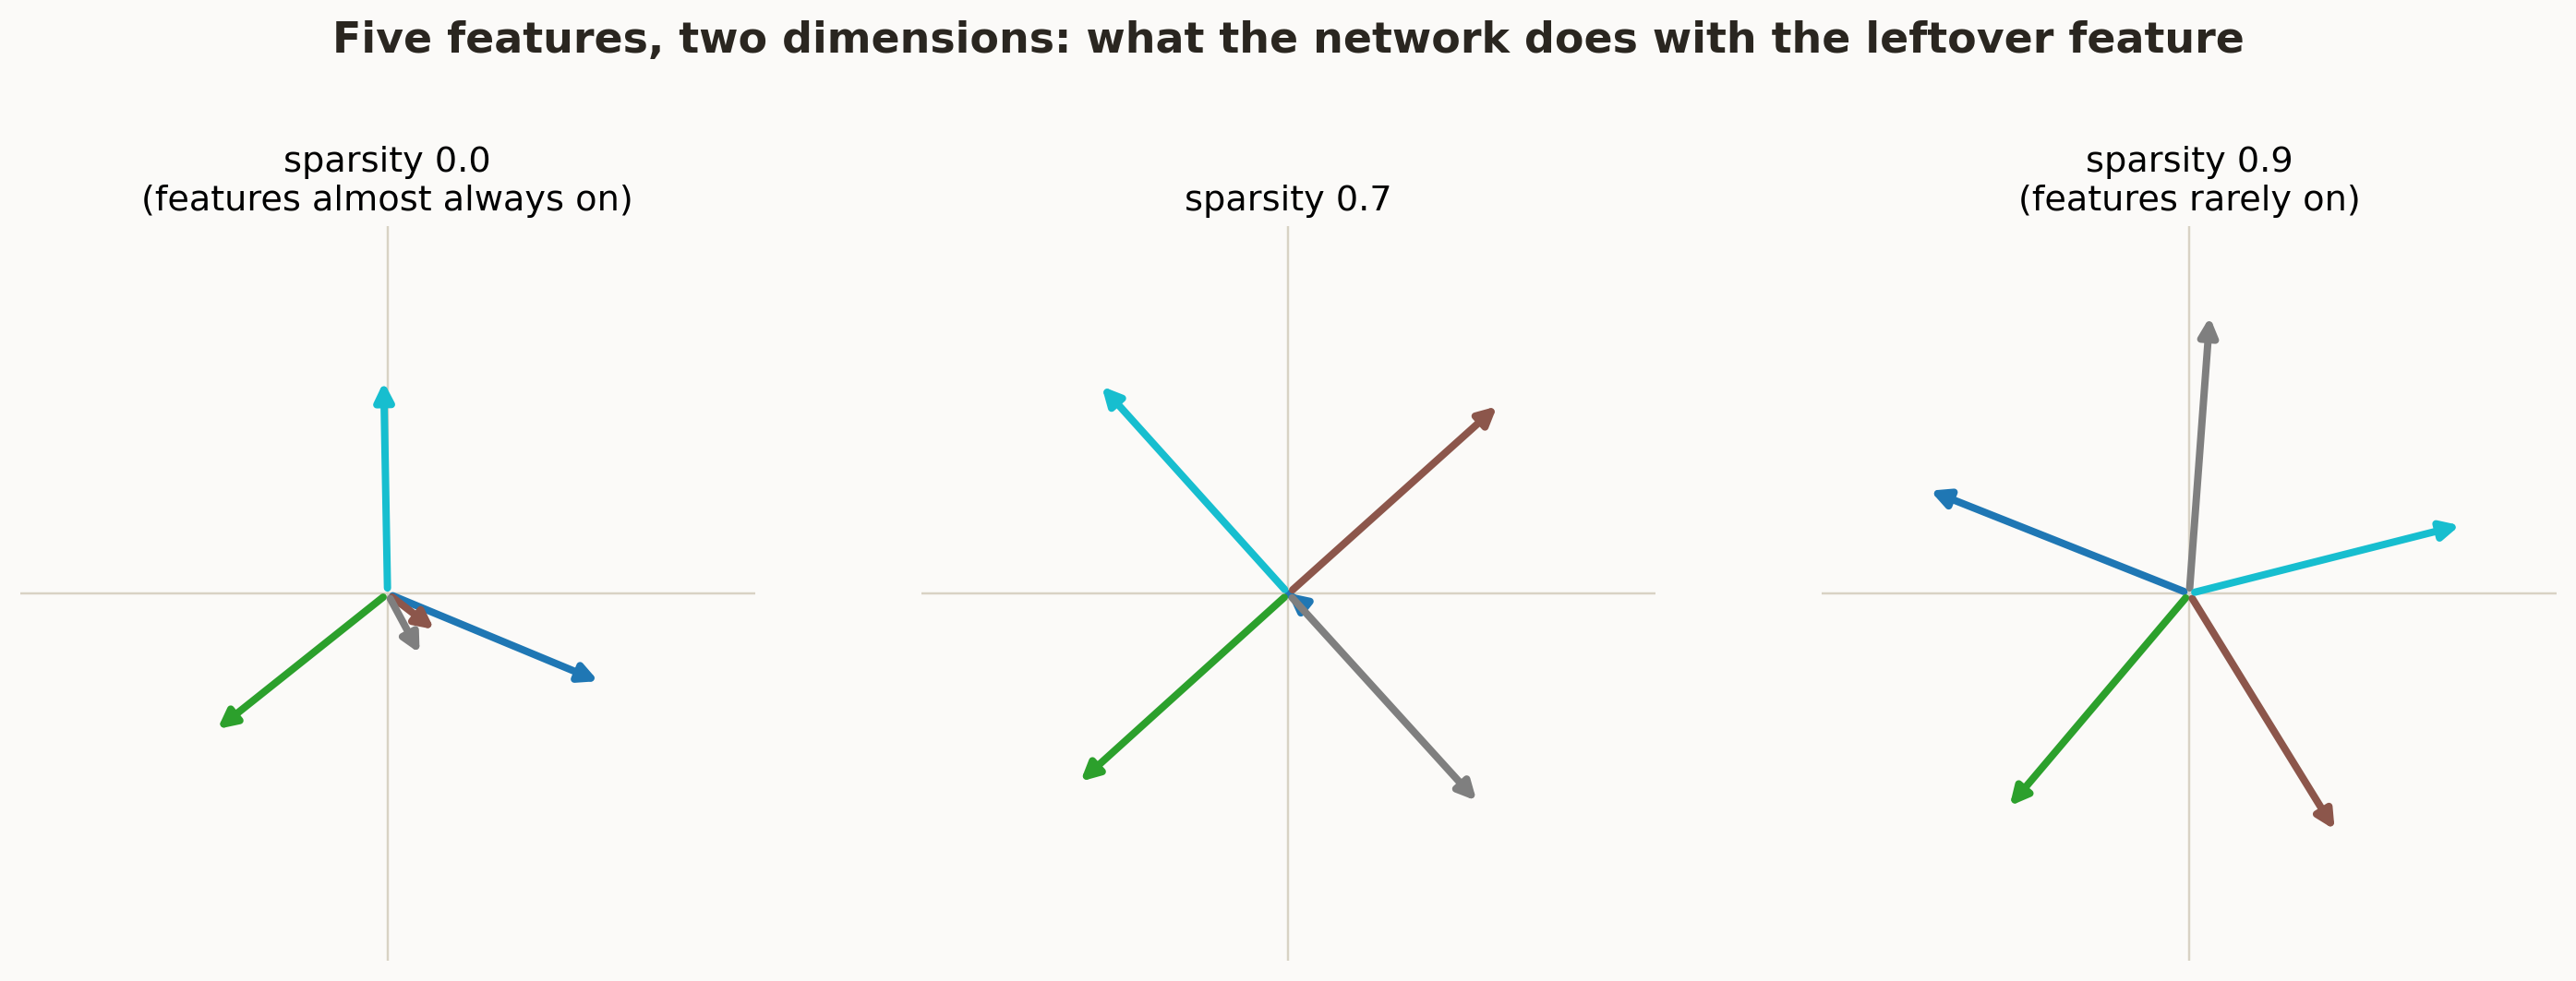
I checked that final declare numerically quite than eyeballing it: the 5 angles within the high-sparsity run got here out at 14.2, 85.8, 158.3, 229.8, and 301.6 levels, that are 71.5 to 72.5 levels aside, basically an ideal common pentagon, correct to about half a level. There is no such thing as a time period within the loss perform that rewards symmetry. A pentagon is simply probably the most environment friendly technique to place 5 factors on a circle so that each pair is as far aside as each different pair, which minimizes the worst-case interference between any two options. Gradient descent discovered that association by itself as a result of it is genuinely the optimum packing, not as a result of anybody informed it what a pentagon was.
Experiment three: what interference really appears to be like like
The pentagon image is good for five options in 2 dimensions as a result of you’ll be able to really see it. With extra options you’ll be able to’t draw the image anymore, however you’ll be able to look straight at how a lot any two options are stepping on one another’s toes, by computing , whose diagonal tells you the way nicely every function reconstructs itself and whose off-diagonal entries let you know how a lot reconstructing one function corrupts one other.
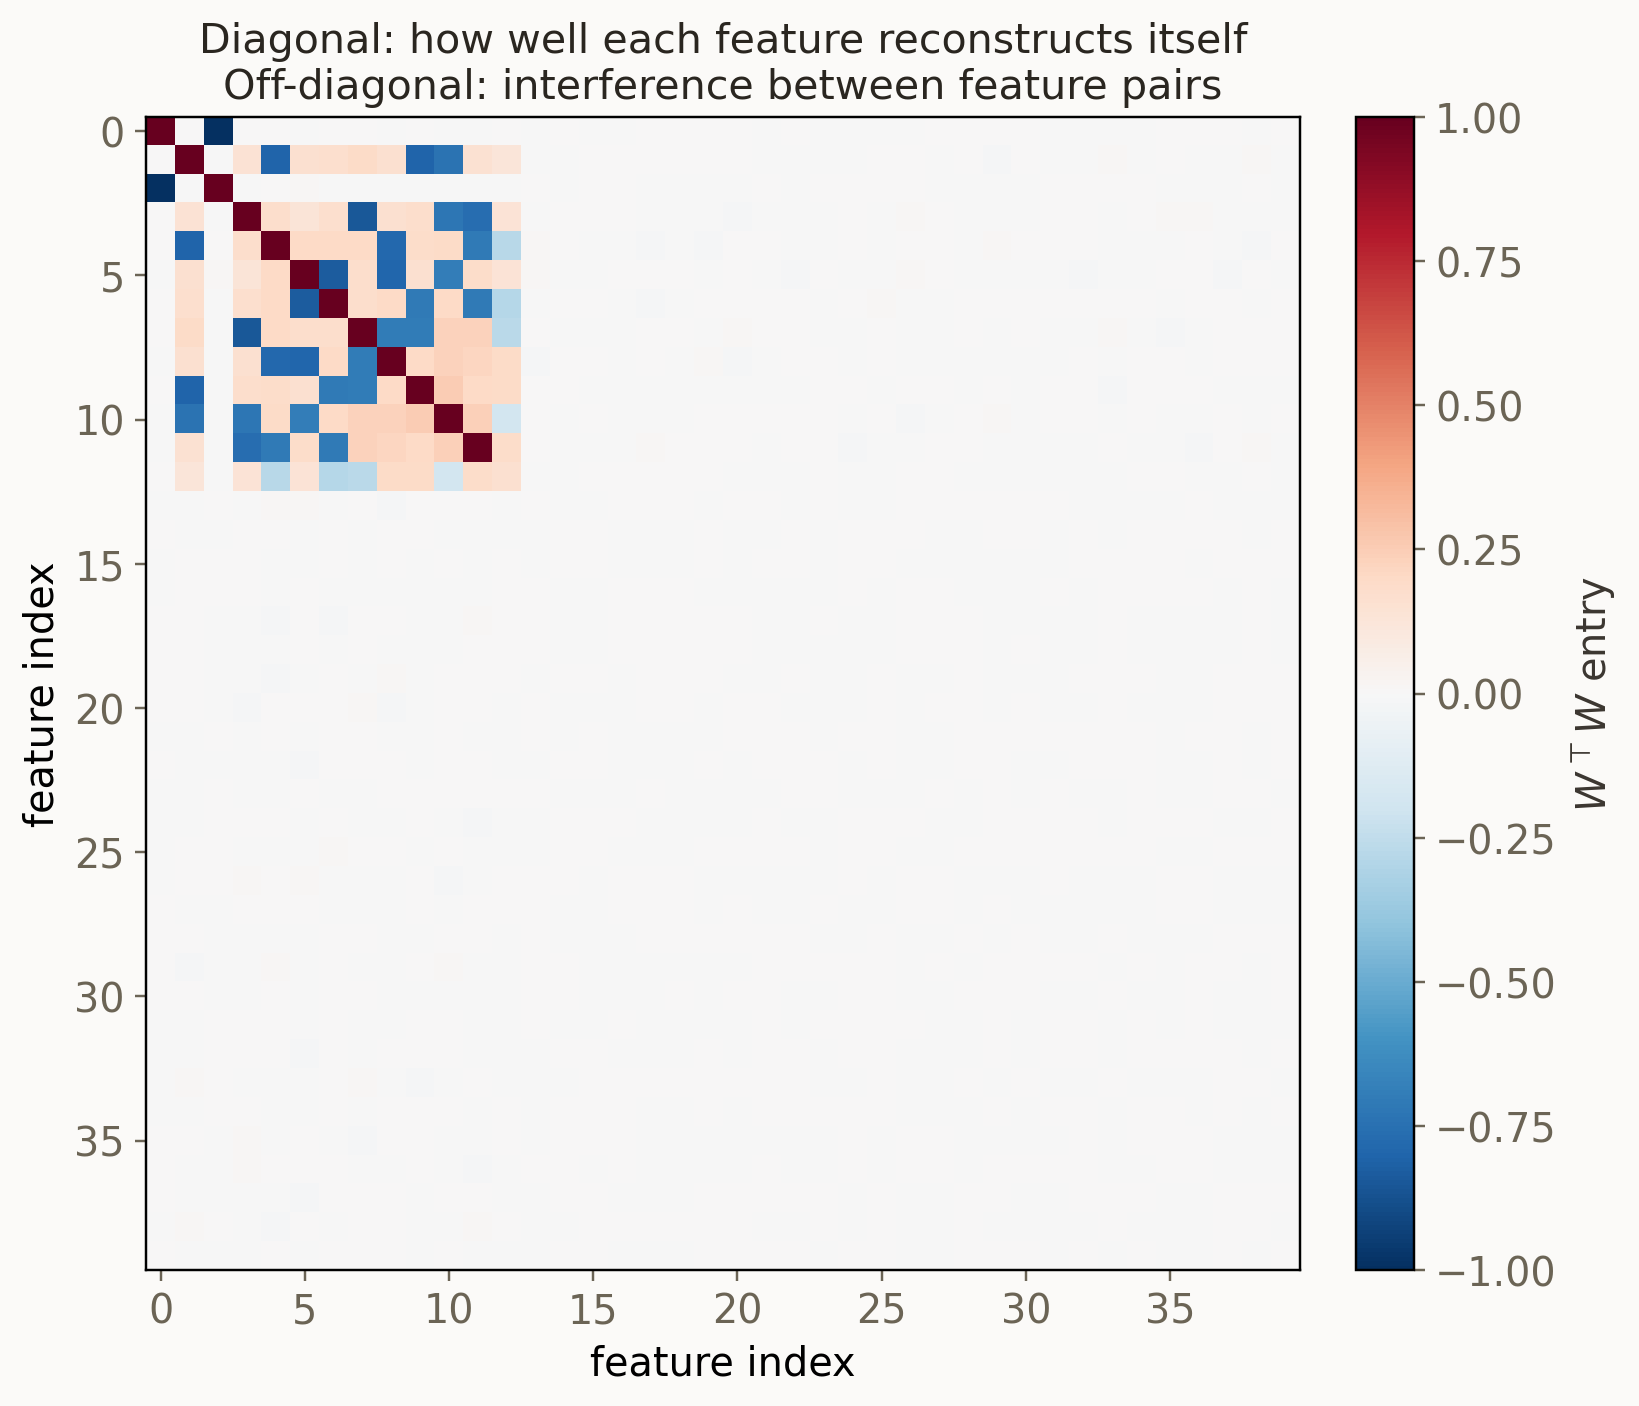
This strains up with experiment one virtually precisely. The identical cutoff round function 12 or 13 exhibits up independently in each, which is an efficient sanity verify that that is measuring an actual impact and never an artifact of 1 explicit plot.
Experiment 4: turning the sparsity dial
The final experiment is the one that truly earns the phrase “section transition,” a time period the paper makes use of and that I used to be skeptical of till I noticed it myself. Repair 30 options and 5 hidden dimensions, and sweep sparsity from 0 (options are virtually at all times lively) as much as 0.99 (options are lively just one p.c of the time), retraining from scratch at every stage.
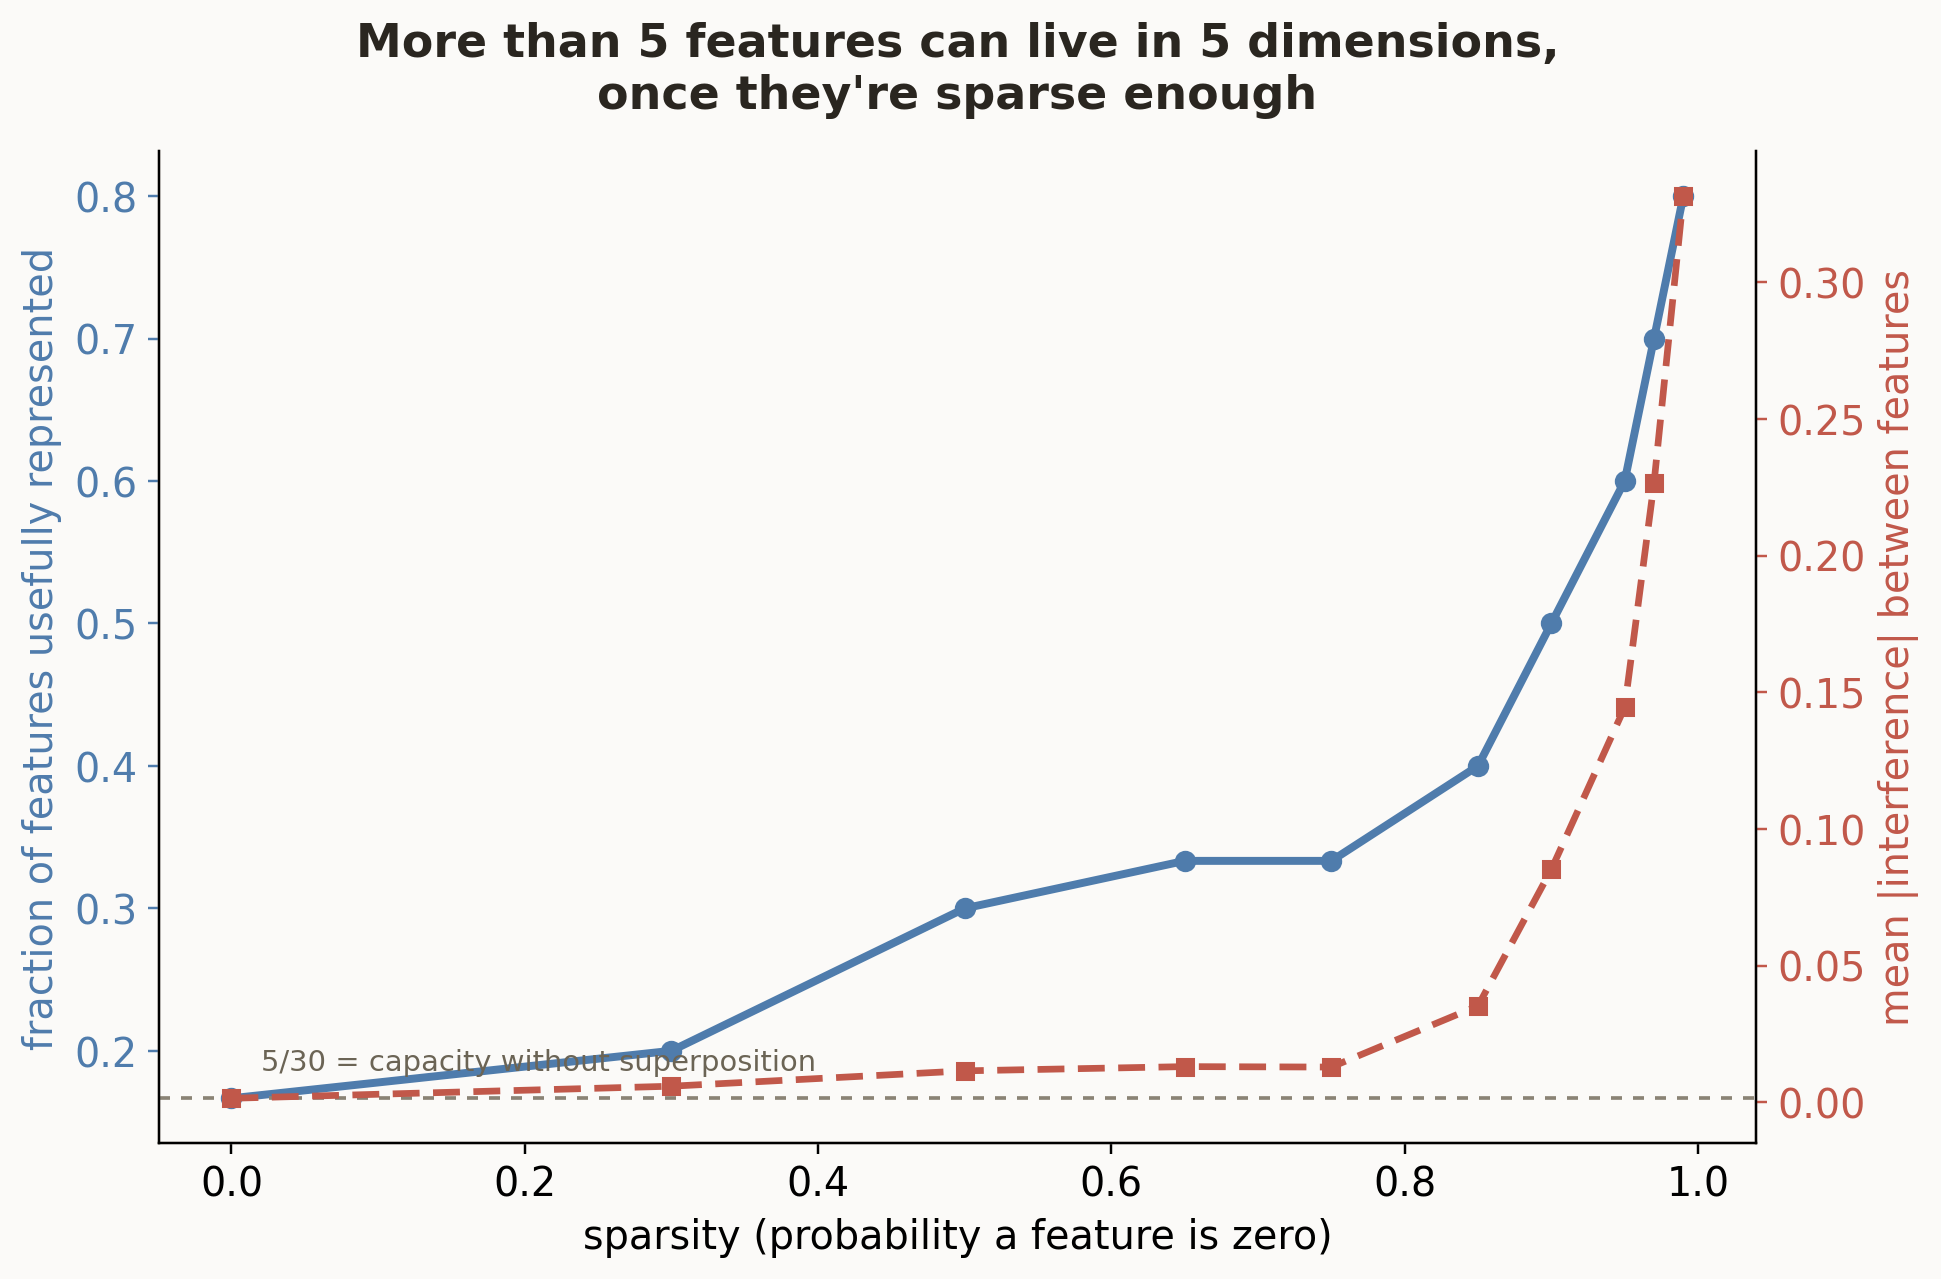
The flat stretch at low sparsity and the sharp climb after roughly 0.8 is what makes this a section transition quite than a easy tradeoff. There’s an actual regime change within the technique the community adopts, not only a gradual dial turning. Under some threshold, superposition prices extra in interference than it is value. Above it, it is clearly value it, and the community commits to utilizing it.
What this really tells you
None of this required a big mannequin, a GPU, or a real-world dataset. Thirty artificial numbers and a day have been sufficient to look at an actual occasion of a phenomenon that is at present central to how individuals take into consideration decoding a lot larger fashions. The headline declare survives contact with precise code: networks actually do symbolize extra ideas than they’ve neurons, they do it by exploiting sparsity, and the geometry they land on to do it, antipodal pairs, common polygons, is not ornamental. It is the mathematically environment friendly packing for the quantity of interference the loss perform is keen to tolerate.
The sensible stakes are larger than a pentagon. If a big language mannequin is representing hundreds of ideas inside just a few thousand neurons, and it virtually actually is, then polysemanticity is not a bug you’ll be able to repair by staring tougher at particular person neurons. It is the predictable consequence of compression beneath sparsity, and it is a huge a part of why mechanistic interpretability has needed to develop instruments, like sparse autoencoders, particularly designed to undo this packing and pull particular person options again out. Having now watched superposition occur in a system sufficiently small to totally see, I perceive why that line of analysis exists in a means I do not suppose I might have from studying about it alone.
···
References:
[1] N. Elhage, T. Hume, C. Olsson, N. Schiefer, T. Henighan, S. Kravec, Z. Hatfield-Dodds, R. Lasenby, D. Drain, C. Chen, R. Grosse, S. McCandlish, J. Kaplan, D. Amodei, M. Wattenberg and C. Olah, Toy Fashions of Superposition (2022), Transformer Circuits Thread