

Over the previous three years, Retrieval-Augmented Era (RAG) has advanced from easy vector similarity search over chunked paperwork to incorporate advanced, graph-native architectures often known as GraphRAG. By leveraging Data Graphs (KGs), the place nodes signify real-world entities and edges signify semantic relationships, GraphRAG permits massive language fashions (LLMs) to carry out multi-hop reasoning, discover relational lineage, and compose advanced contextual solutions that naive vector databases are inclined to battle at.
Nonetheless, enterprise practitioners implementing GraphRAG techniques in manufacturing are confronted with the micro-decision bottleneck, particularly when the KG turns into massive sufficient to have hundreds of thousands of nodes and edges. The reason is {that a} KG is a deterministic knowledge construction and constructing, sustaining, and querying a big graph requires tens of hundreds of probabilistic micro-decisions akin to:
-
Is “Alphabet Inc.” in doc chunk A the very same node as “Google LLC” in node 40812?
-
Is the connection predicate
[:WORKS_FOR]an identical in intent to[:EMPLOYED_BY]underneath our graph ontology? -
Out of two,500 nodes retrieved in a 3-hop traversal neighborhood, which 15 nodes are genuinely related to the consumer’s particular question?
Traditionally, engineers have defaulted to calling general-purpose, autoregressive LLMs (akin to gpt, claude and many others) for making these micro-decisions. The provides important latency and value to routine and repetitive ingestion, upkeep and retrieval duties. Additionally, LLMs are tuned to generate unstructured textual content. Forcing them to output legitimate JSON or Cypher queries, in a near-deterministic trend, requires strict immediate engineering, temperature tuning, and fragile regex/pydantic parsing logic that occassionally fail underneath edge circumstances.
System 1 AI: The Worth Proposition
In Considering, Quick and Sluggish, Daniel Kahneman demarcated human cognition into two techniques: System 1 (quick, instinctual, easy, associative) and System 2 (gradual, deliberate, sequential, logical reasoning).
Extending the idea to AI, probabilistic micro-decision must be a System 1 downside, that may be carried out with out a lot latency and energy. In Machine Studying phrases, this resembles a classification or scoring downside, for which quick, dependable and light-weight fashions are the business customary.
Nonetheless, autoregressive LLMs are constructed as System 2 engines. They excel at deep reasoning, textual content synthesis, and complicated code era. Forcing them to carry out high-frequency System 1 micro-decisions on graph constructions is subsequently, not an optimum structure.
Not too long ago, TypeSafe AI launched Jev, a specialised “System 1” AI mannequin designed from the bottom as much as remedy this architectural hole. In contrast to conventional generative LLMs, Jev is a non-autoregressive, calibrated resolution mannequin. It doesn’t stream tokens or produce conversational prose. As a substitute, it ingests state and executes typed, probabilistic micro-decisions in a parallel execution mode with sub-500ms latency and at a fraction of the price of LLMs.
On this article, I’ll discover how combining TypeSafe Jev’s System 1 resolution engine with System 2 autoregressive LLMs may end up in extremely scalable, low-cost, high-precision Data Graphs and GraphRAG pipelines.
Decoupling the Determination Engine: Understanding TypeSafe Jev
To successfully combine Jev right into a graph structure, it helps to know its mathematical design and native primitives. Normal autoregressive language fashions predict the subsequent token ti conditioned on earlier tokens t1, …., ti-1:
This sequential dependency is what creates era latency.
TypeSafe Jev discards the next-token prediction goal. As a substitute, it’s skilled by way of Reinforcement Studying for Calibrated Choices (RLCD) to straight estimate calibrated chance distributions over structured output schemas in a single request / parallel analysis
, the place represents a closed set of typed schema choices, and is the enter context state.
The Three Core Jev Primitives
Jev engineering shifts the paradigm from immediate engineering to schema declaration. In our structure, all graph micro-decisions are mapped to Jev’s three elementary primitives:
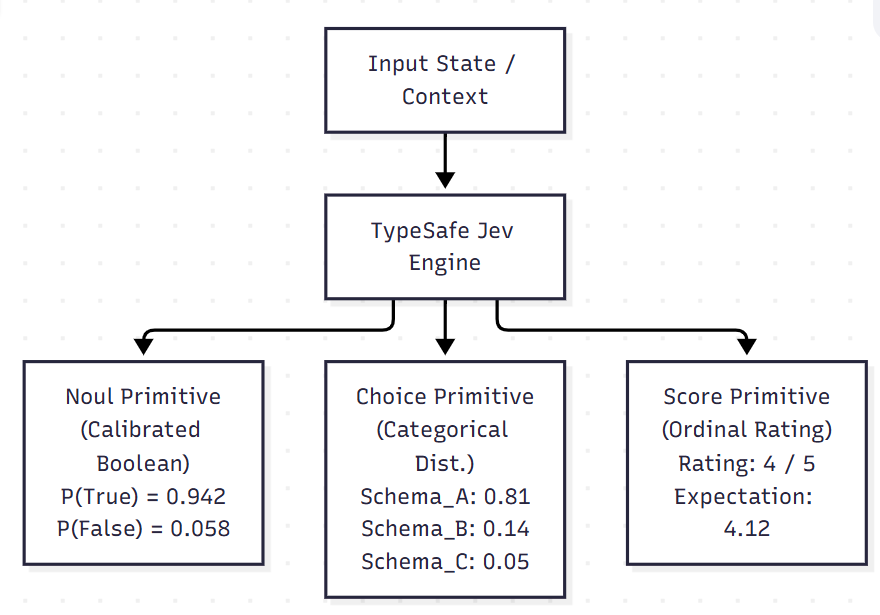
Noul (Calibrated Boolean)
Returns a calibrated chance for a binary assertion. In contrast to customary LLM logit outputs, which are sometimes uncalibrated and vulnerable to overconfidence, Jev’s noul outputs signify calibrated possibilities/confidence estimates. If a mannequin is nicely calibrated, predictions assigned a chance of 0.92 must be right roughly 92% of the time over a sufficiently massive, consultant set of comparable predictions.
Selection (Categorical Distribution)
Given a predefined record of discrete categorical targets , selection evaluates the enter and returns the chance mass distribution throughout all candidates.
Rating (Ordinal Score)
Given an ordinal scale (e.g., 1 to five, or 1 to 10), rating calculates an anticipated ordinal worth together with the boldness, serving as a dependable numerical evaluator for steady properties.
The Twin-Engine Graph Structure
Following is the overarching architectural blueprint of Jev and LLM collaborating in a Twin-Engine Sample for Graph Techniques.
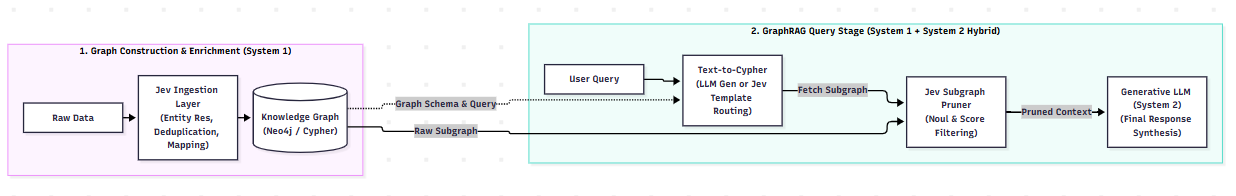
Graph Development & Enrichment Stage (System 1 pushed)
Entity Decision & Deduplication (Noul): Throughout uncooked doc ingestion, Jev evaluates extracted entity pairs and relationship predicates in parallel, stopping duplicate nodes and fragmented edges from getting into the graph.
Cross-Ontology Schema Mapping (Selection): Maps incoming unstandardized file fields to canonical graph properties (eg; HQ_CITY_LOC key from Salesforce maps to Corporate_headquarters property of graph).
Steady Edge Weighting & Property Tagging (Rating / Selection): Evaluates unstructured logs in background streams to assign dynamic weight scores (e.g. threat stage, relationship power) straight onto graph edges and nodes.
GraphRAG Question Stage (System 1 + System 2 Hybrid)
Textual content-to-Cypher Era: Relying on question complexity, both an Autoregressive LLM generates dynamic Cypher from open-ended schemas, or Jev’s Selection primitive quickly maps the question to pre-compiled parameterized Cypher templates.
Jev Subgraph Pruning (Noul / Rating): Evaluates the candidate nodes returned by Cypher traversal, aggressively pruning irrelevant subgraphs and decreasing context token bloat by as much as 90%.
Autoregressive LLM (System 2 Synthesis): Synthesizes the ultimate pure language reply utilizing strictly the verified, high-relevance subgraph context.
Use Circumstances & Implementation Patterns
Allow us to see seven use circumstances the place TypeSafe Jev can remodel Data Graph building, upkeep, and retrieval.
Stage 1: Ingestion & Insertion (Constructing the Graph)
Entity Decision & Duplicate Detection (Noul)
When ingesting hundreds of unstructured enterprise paperwork, entity extractions produce large duplication. “Google LLC”, “Google Inc.”, “Google”, and “Alphabet (Google)” may be extracted as distinct nodes. Conventional string-distance algorithms (e.g., Levenshtein distance, Jaro-Winkler) aren’t correct when entity types differ considerably, whereas vector embedding cosine similarity continuously confuses unrelated entities (e.g., complicated “Apple Inc.” with “Apple Financial institution”).
Utilizing Jev’s noul primitive, we carry out pairwise contextual verification with calibrated confidence scores:
In an enterprise company construction graph, resolving Alphabet Inc. (Context: Mountain View holding firm) and Google LLC (Context: Search and Cloud division) returns P(True) = 0.961. Conversely, evaluating Apple Inc. (Tech) and Apple Financial institution (Finance) returns P(True) = 0.003.
At an execution time of ~100 ms, Jev processes entity candidate batches orders of magnitude quicker than a gpt-mini at a fraction of the API value.
Semantic Relationship Deduplication (Noul)
Throughout open-relations extraction, LLMs produce tons of of synonymous edge predicates: [:IS_EMPLOYED_BY], [:WORKS_AT], [:STAFF_OF], [:EMPLOYEE_OF]. Permitting unstandardized predicates causes relational fragmentation within the graph, severely degrading Cypher question efficiency.
Jev evaluates new incoming relationships towards current schema predicates utilizing noul:
By catching synonymous relationship predicates earlier than they enter the graph, Cypher queries do not want costly OR situations (e.g., MATCH ()-[r:WORKS_AT|IS_EMPLOYED_BY|STAFF_OF]-()), which improves index lookup occasions and simplifies downstream traversal algorithms.
Cross-Ontology Mapping (Selection)
When ingesting heterogeneous enterprise databases (SQL tables, Salesforce CRM, Jira tickets, legacy SAP schemas), property key names differ lots akin tobirthplace, city_of_origin, born_in, location_of_birth).
Jev’s selection primitive acts as an automatic schema alignment layer, deciding on the matching canonical ontology key from a closed enumeration:
In enterprise environments the place departments use disjointed software program (e.g., Salesforce vs Jira), Jev quickly normalizes incoming properties right into a single grasp schema, making certain node properties are constantly accessible with out advanced regex guidelines.
Stage 2: Upkeep & Enrichment (Refining the Graph)
As soon as a Data Graph is constructed, it should not stay static. It requires steady background upkeep, weight calculations, and state tagging as new enterprise occasions happen.
Steady Relationship Arbitrator & Edge Weighting (Rating)
Graph algorithms akin to Dijkstra’s shortest path, Customized PageRank, and Louvain group detection rely closely on numeric edge weights. Nonetheless, real-world relationships are hardly ever binary, as a substitute, they possess various levels of belief, interplay frequency, sentiment, or monetary threat.
Jev’s rating primitive ingests unstructured interplay logs (e.g., buyer help chats, e-mail exchanges, commerce transactions) and computes calibrated float weights that may be added onto graph edges.
A monetary threat graph can now weigh a enterprise relationship dynamically primarily based on interplay severity. This may then be used to routinely regulate traversal prices so downstream GraphRAG algorithms flag the weakest hyperlinks in a partnership.
Actual-Time Node Property Tagging (Selection / Rating)
In real-time fraud detection and buyer intelligence graphs, node properties should react rapidly to incoming stream occasions. If a node abruptly displays anomalous transaction hops, Jev can fast-classify the node’s threat standing in milliseconds:
For fraud-detection, a consumer account node constantly adjustments states. Jev computes these state adjustments quick sufficient to be executed straight inside an occasion stream (like Kafka), immediately tagging a node as SUSPICIOUS_FRAUD the second anomalous velocity happens. Entities akin to individuals, corporations transacting with this account will be flagged for enhanced supervision additionally.
Stage 3: GraphRAG Querying (Retrieving from the Graph)
Integrating Jev throughout GraphRAG question execution can effectively management the “Graph Explosion Downside”, whereby, traversing 2 or 3 hops from a question beginning node can simply return hundreds of context nodes, bloating the downstream generative LLM context with irrelevant noise.
Subgraph Pruning & Noise Filtering(Noul)
Earlier than passing retrieved graph neighborhoods right into a System 2 LLM immediate, Jev evaluates every candidate node’s factual relevance to the consumer’s particular question. Nodes under the brink are aggressively pruned.
Contemplate a consumer querying a provide chain GraphRAG system: “Which European suppliers are impacted by the current semiconductor scarcity?” Traversing a 3-hop graph across the “Semiconductor” node might yield hundreds of candidate nodes (~50,000 tokens). Jev’s noul evaluates every node towards the question. A node representing a “German Microchip Fab” is retained (P=0.98). Then again, a linked node representing the fab’s “Workplace Furnishings Provider”, which is structurally shut however factually irrelevant to the question, is aggressively pruned (P=0.04). This reduces the context set to say 10 extremely related nodes (~1,200 tokens) in <500 ms complete batch time, decreasing downstream GPT era value by >95%.
Weighted Pathfinding & Algorithmic Steering (Rating)
(Observe: This sample leverages the continual edge weights generated in Steady Relationship Arbitrator & Edge Weighting sample talked about above)
When answering advanced multi-hop questions (e.g., “What’s the provide chain dependency threat between Semiconductor Plant X and Buyer Y?”), there might exist tons of of legitimate graph paths.
By combining Jev-computed Rating weights (up to date onto edges through the upkeep section) with customary graph algorithms (akin to NetworkX shortest_path or Neo4j Cypher gds.shortestPath.dijkstra), we dynamically information pathfinding algorithms towards essentially the most logically sound paths.
By scoring the enterprise relationship power between all suppliers and distributors, GraphRAG does not simply discover the geographic path with the fewest hops between Semiconductor Plant X and Buyer Y. As a substitute, it makes use of these relationship weights as inverse traversal prices to map the trail of highest dependency, main the System 2 LLM straight to essentially the most vital provide chain bottleneck the place a single failure would affect even essentially the most trusted partnerships.
Architectural Finest Practices for Practitioners
As with every comparatively new expertise, integrating TypeSafe Jev inside Data Graph or GraphRAG manufacturing stacks would require following architectural pointers for optimum efficiency. A couple of of which I be aware under:
Implement Strict Operational Separation
Jev shouldn’t be a alternative for LLM. It can’t be used for open-ended textual content summarization, consumer dialogue, or inventive code era. Use Jev strictly for micro-decisions: boolean assertions (noul), discrete schema routing (selection), and ordinal scoring (rating). Jev may be very a lot a background element, having little interplay with the end-user. As is the present norm, autoregressive LLMs are for use for macro-synthesis on the user-facing response step.
Set Empirical Thresholds on Calibrated Possibilities
As a result of Jev’s (noul) possibilities are strictly calibrated, keep away from arbitrary guessing for acceptance thresholds. It willl be useful to run a small calibration validation set of 200 labeled pairs from the related area, plot the Precision-Recall curve towards Jev’s (noul) outputs, and choose operational cutoff primarily based heading in the right direction enterprise metrics. As an example:
-
Excessive Precision / Zero False Positives (Entity Merging): Set
noulthreshold to >=0.92. -
Excessive Recall / Zero Data Loss (GraphRAG Pruning): Set
noulthreshold to >= 0.65.
Parallelize Batch Ingestion
Jev’s non-autoregressive structure permits large parallel analysis. When processing 10,000 entity decision pairs throughout batch doc ingestion, dispatch requests utilizing async HTTP connection swimming pools. In contrast to autoregressive endpoints that rapidly hit fee limits or context bottlenecks, Jev can deal with high-concurrency micro-decision analysis.
Persist Jev Scores as Graph Metadata
Retailer Jev analysis metrics straight on graph nodes and edges as native properties (jev_confidence, jev_risk_score, last_verified_timestamp). This transforms Data Graph right into a self-describing, probability-aware construction that simplifies downstream Cypher filtering. As an example, having this metadata can allow pruning irrelevant noise with out dynamically performing the classification on a lot of nodes for each comparable question.
Conclusion: The Way forward for Graph AI is Hybrid
Constructing and sustaining enterprise Data Graphs requires balancing structural integrity with computational overhead. Relying completely on autoregressive language fashions to handle the requisite quantity of probabilistic micro-decisions introduces measurable latency and value constraints that may restrict system scalability.
Adopting a specialised, non-autoregressive resolution mannequin like TypeSafe Jev supplies a realistic various for managing these localized graph operations. By decoupling discrete classification duties, akin to entity decision, property mapping, and subgraph pruning from the first generative pipeline, engineering groups can obtain extra predictable execution occasions and scale back pointless token consumption.
Nonetheless, the deployment of GraphRAG in manufacturing environments calls for rigorous architectural separation. Delegating high-frequency, low-complexity evaluations to a calibrated resolution mannequin, whereas reserving autoregressive fashions for last textual content synthesis, represents a vital structural optimization for sustaining reliably performing graph-native functions.
For extra on GraphRAG structure, learn my article GraphRAG: A Practitioner’s Information to six Superior Architectural Patterns.
Join with me and share your feedback at www.linkedin.com/in/partha-sarkar-lets-talk-AI
Pictures used on this article are generated utilizing Google Gemini. Code developed by me.