Of their 2024 Worldwide Convention on Machine Studying paper, Monitoring AI-Modified Content material at Scale: A Case Research on the Impression of ChatGPT on AI Convention Peer Critiques, Weixin Liang, Zachary Izzo, and their coauthors constructed a statistical methodology for estimating how a lot textual content in a big assortment had been considerably written or rewritten by a big language mannequin, a man-made intelligence system that generates textual content. They utilized the strategy to see critiques submitted to 4 main synthetic intelligence conferences after ChatGPT launched. They estimated that 6.5 % to 16.9 % of the evaluate textual content confirmed indicators of considerable AI modification. These had been peer critiques written by researchers making cautious technical judgments in settings with actual submission penalties. That estimate is restricted to convention critiques. It reveals that considerably AI modified writing appeared in consequential peer evaluate, not how widespread it’s in product critiques, boards, or surveys.
That issues past the critiques themselves. A separate 2024 Nature paper, AI Fashions Collapse When Educated on Recursively Generated Information, by Ilia Shumailov and coauthors, discovered that repeatedly coaching a mannequin on output generated by different fashions could make it lose uncommon examples from the unique knowledge and produce narrower outcomes. The examine paperwork this failure mode underneath repeated coaching on generated textual content.
For years, the usual grievance about knowledge science work has been that the majority of it’s cleansing messy knowledge. A more recent downside is that the mess can embody fluent textual content written by a mannequin to sound human. Most knowledge cleansing checks catch lacking values, repeated entries, and fields exterior an anticipated vary. They don’t set up who wrote a paragraph. I needed to know whether or not cheap checks might flag generated textual content, and whether or not eradicating the critiques they flagged would assist a mannequin type critiques as optimistic or destructive.
I ran two assessments utilizing a film evaluate assortment printed by Mendeley in 2019. First, I checked which critiques the detectors marked as probably AI written. A evaluate obtained that label when its rating crossed the chosen cutoff. Then I added 400 critiques generated by two language fashions to 200 IMDb critiques from the gathering. I handled the IMDb critiques as human-written references as a result of the gathering identifies IMDb as their supply and was printed in 2019, earlier than ChatGPT’s public launch. I examined three checks on the 600 critiques, measured what number of generated and supply critiques they flagged, and measured how filtering affected the sentiment mannequin. At a setting that caught 80 % of generated critiques, embedding density, which measures how intently a evaluate resembles others, additionally flagged 47 % of the supply critiques. Filtering with the mixed rating, the common of all three checks, lowered accuracy from 67.5 % to 57.5 % on a separate set of 200 critiques. The gathering doesn’t confirm particular person authorship, so this human-written label is an inference from the supply and publication date.
What did I really construct?
I first checked the complete 1,000 evaluate archive for textual content that regarded AI written. Then I examined three checks on 600 critiques. Perplexity measures how predictable the wording is to a language mannequin. Close to duplicate similarity seems for an additional evaluate with related wording or which means. Embedding density measures how shut a evaluate is to its 5 closest matches. The pattern included 400 generated critiques with identified origins. For every test, I counted what number of generated critiques it caught and what number of Mendeley critiques, handled as human references, it additionally marked as probably AI written. I then measured what filtering did to the sentiment classifier.
For the supply critiques, I used 1000 Film Critiques for Repute Era, printed by Abdessamad Benlahbib on Mendeley Information on 9 March 2019. The gathering description says the critiques had been extracted from IMDb, the Web Film Database. Since they got here from IMDb and the gathering was printed earlier than ChatGPT launched publicly in November 2022, I deal with these critiques as human-written. The dataset doesn’t confirm every reviewer’s identification, so that is an inference from the supply and date, not an author-by-author test. The gathering is licensed underneath Inventive Commons Attribution 4.0 Worldwide (CC BY 4.0), which allows reuse and adaptation with attribution and a hyperlink to the license. I present that attribution within the sources. This text makes use of a subset and doesn’t indicate that IMDb endorsed the experiment.
The gathering accommodates 1,000 critiques of 10 movies, every with a manually assigned optimistic or destructive sentiment label. I used 200 as human-written reference critiques for coaching, cut up evenly between optimistic and destructive, from 2012, A Stunning Thoughts, Amadeus, Avatar, and Conflict of the Titans. I saved one other 200 critiques from 5 totally different movies separate from coaching so I might check the mannequin afterward. These check critiques had been additionally cut up evenly by sentiment and got here from Les Miserables, Star Wars Episode I: The Phantom Menace, The Expendables I, The Godfather, and The Matrix Revolutions. Conserving the movies separate meant the classifier couldn’t see critiques of a check movie throughout coaching.
I generated 400 recent critiques with two language fashions, gpt-6-astra and gpt-5-nano. 100 optimistic and 100 destructive critiques got here from every mannequin. The immediate requested every mannequin to invent a film and write a brief evaluate with the requested sentiment. It didn’t present the fashions supply examples or ask them to mimic a specific reviewer. The ultimate coaching set due to this fact contained 600 rows: 200 supply critiques handled as human references and 400 newly generated artificial critiques, which means critiques written by a mannequin.
I take advantage of “artificial” to imply written by a language mannequin. These outcomes apply to the 2 fashions, prompts, evaluate assortment, and experiment run used right here.
How did I attempt to spot the AI critiques?
I gave every evaluate three scores, then checked what number of generated critiques every rating caught and what number of supply critiques it flagged.
First, I measured perplexity with GPT-2. Perplexity measures how predictable a textual content is to a language mannequin. AI writing can obtain a decrease perplexity rating as a result of it typically makes use of acquainted phrase patterns, however human writing may be predictable too. I handled low perplexity as a warning signal, not proof of AI authorship.
Subsequent, I transformed every evaluate into an embedding, an inventory of numbers that represents a few of its which means and wording. I used the all-MiniLM-L6-v2 sentence embedding mannequin. Close to duplicate similarity compares a evaluate with its closest match in that numerical house. A excessive similarity rating means one other evaluate has related wording or which means.
Embedding density asks a distinct query. It measures how shut a evaluate is to its 5 nearest neighbors, which means the 5 critiques with the closest numerical representations. If AI critiques collect in a decent group, their common distance to these neighbors could also be shorter than the space for diverse human critiques.
I additionally mixed the three scores. First, I transformed every one to a price between zero and one, with greater values all the time pointing towards a attainable AI flag. Perplexity runs in the other way, so I reversed it earlier than combining the scores. For close to duplicate similarity and embedding density, the next worth means the evaluate is nearer to different critiques. I then added the three adjusted scores and divided by three. That common is the mixed rating. It’s a warning rating, not the chance {that a} mannequin wrote the evaluate. I used it to check whether or not averaging a number of checks labored higher than utilizing one by itself.
To check the strategies, I diversified the rating cutoff and measured recall and the false optimistic fee. A cutoff is the rating above which a evaluate will get flagged. Recall is the share of generated critiques the detector catches. Right here, the false optimistic fee is the share of supply critiques handled as human references that it flags. For the reason that assortment doesn’t confirm authorship, this fee is determined by that assumption. I selected the cutoff that caught at the very least 80 % of generated critiques whereas flagging the fewest of the 200 supply critiques within the coaching set.
What did the audit flag within the authentic assortment?
The mixed rating marked 444 of the 594 remaining archive critiques, which weren’t used for coaching or testing, as probably AI written. It additionally marked 158 of the 200 critiques put aside for testing. These are detector flags, not affirmation {that a} mannequin wrote the critiques.
The mixed rating averages three checks. They’re perplexity, close to duplicate similarity, and embedding density.
I selected the cutoff utilizing the 600 evaluate experiment. It was set to catch at the very least 80 % of the identified AI generated critiques whereas flagging as few Mendeley reference critiques as attainable. I used the identical choice rule for the archive audit. Of the 594 remaining archive critiques, 444 scored above the cutoff and the opposite 150 scored under it.
I downloaded all 1,000 entries within the Mendeley archive. Six had been duplicate copies, leaving 994 totally different critiques. I used 200 critiques for coaching and saved one other 200 separate to check the mannequin. Subtracting these 400 critiques from the 994 distinct critiques left 594 for the audit.
For every test, I selected a rating cutoff that caught at the very least 80 % of the 400 generated critiques whereas flagging as few as attainable of the 200 supply critiques used for coaching. I then utilized the checks to the separate 200 supply critiques put aside for testing and the 594 remaining archive critiques, which weren’t used for coaching or testing. I scored all 1,394 critiques collectively as a result of the similarity and density checks evaluate every evaluate with different critiques. I selected new cutoffs for this bigger group. The 0.548 cutoff used later to filter the 600 evaluate coaching set can’t be reused right here. The scores had been rescaled throughout the complete group of 1,394 critiques, so the identical cutoff would flag a distinct share of critiques.
|
Test |
Held out supply critiques flagged |
Unused supply critiques flagged |
|---|---|---|
|
Perplexity |
193 of 200 (96.5%) |
571 of 594 (96.1%) |
|
Close to duplicate similarity |
143 of 200 (71.5%) |
386 of 594 (65.0%) |
|
Embedding density |
153 of 200 (76.5%) |
420 of 594 (70.7%) |
|
Mixed rating |
158 of 200 (79.0%) |
444 of 594 (74.7%) |
The 200 check critiques got here from the identical Mendeley assortment and had been handled as human-written references underneath the source-and-date assumption described above. The mixed rating marked 158 of them as probably AI written. This reveals that the cutoff is unsuitable for labeling or routinely deleting critiques from the archive.
Which detector flagged the fewest supply critiques?
None did nicely on this assortment. Embedding density had the bottom supply evaluate flag fee, however it nonetheless flagged 47 % of the critiques handled as human to catch 80 % of the generated critiques.
Perplexity flagged 98.5 % of the supply critiques at that recall goal. Close to duplicate similarity flagged 52 %, and the mixed rating flagged 73 %. Averaging the indicators didn’t resolve the issue. It made the end result worse than utilizing embedding density alone.
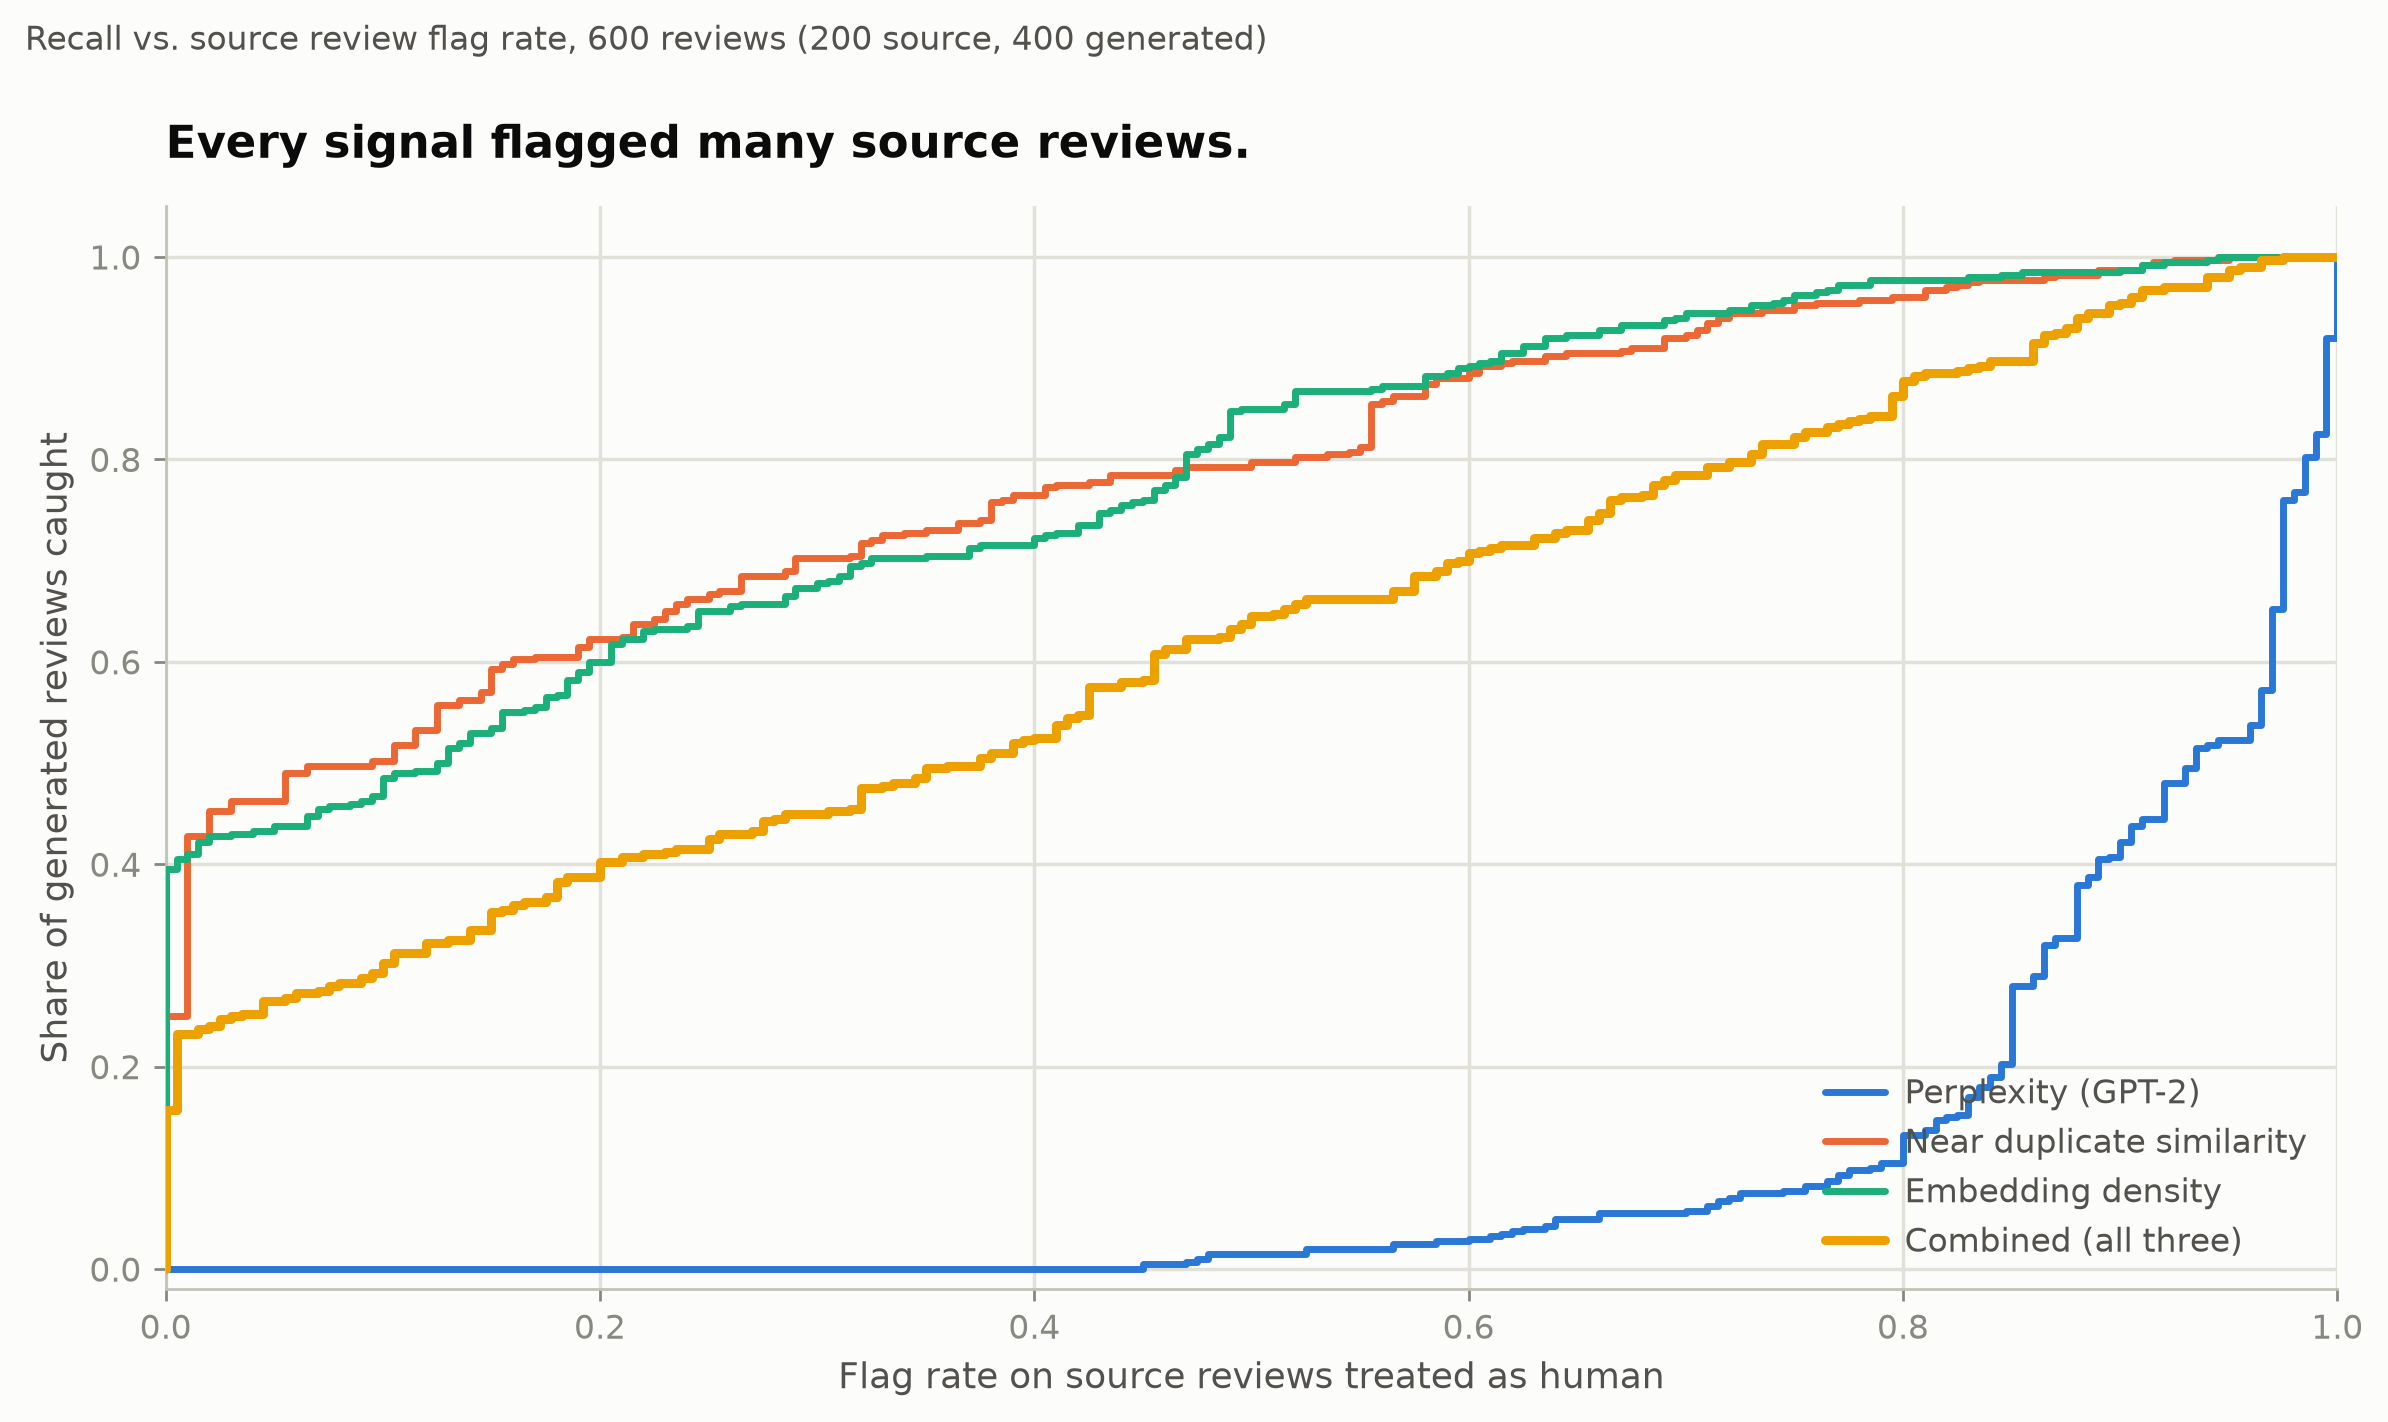
On the mixed rating cutoff used later within the experiment, the detector flagged 320 of the 400 generated critiques and 146 of the 200 supply critiques handled as human. It eliminated 466 rows from the 600 row coaching set and left 134. So “80 % recall” didn’t imply that the filter eliminated solely generated writing. It caught 80 % of the generated critiques whereas additionally flagging almost three quarters of the supply reference critiques.
Which supply evaluate scored highest?
The best scoring supply evaluate was a truth heavy entry about Amadeus, not a chunk of polished prose.
Right here is the complete evaluate.
Amadeus is a 1984 American interval drama movie directed by Milos Forman, written by Peter Shaffer, and tailored from Shaffer’s stage play Amadeus (1979). The story, set in Vienna, Austria, through the latter half of the 18th century, is a fictionalized biography of Wolfgang Amadeus Mozart. Mozart’s music is heard extensively within the soundtrack of the film.
The movie was nominated for 53 awards and obtained 40, which included eight Academy Awards (together with Finest Image), 4 BAFTA Awards, 4 Golden Globes, and a Administrators Guild of America (DGA) award. As of 2016, it’s the latest movie to have a couple of nomination within the Academy Award for Finest Actor class. In 1998, the American Movie Institute ranked Amadeus 53rd on its 100 Years… 100 Films checklist.
This evaluate summarizes the movie, lists awards, and offers its place on a film checklist. Its mixed detector rating was 0.796, above the 0.548 cutoff. The evaluate reads like a compact reference entry fairly than a private response. The rating displays textual content patterns, not the author’s identification.
This instance reveals why a detector rating alone is a poor cause to delete a evaluate. Factual, brief, formulaic writing can rating extremely with out revealing who wrote it.
Which AI evaluate slipped previous the detectors?
The detector additionally missed this AI generated evaluate a few failing house station.
Right here is the complete evaluate.
The Final Cease on Neptune by some means turns a homicide thriller aboard a collapsing house station into two hours of individuals arguing beside equivalent doorways. Its detective, Mara Voss, solves each clue by remembering a childhood lesson we’ve by no means heard earlier than, which is much less deduction than screenwriter-assisted dishonest. The results look costly, however the dialogue sounds prefer it was borrowed from a motivational calendar. By the point the killer revealed his plan to “homicide gravity,” I used to be rooting for the station to blow up. ★★☆☆☆
The mixed rating was 0.384, under the filtering cutoff of 0.548, so the evaluate was not flagged. The detector caught many generated critiques on this pattern however missed this one.
Did filtering make the sentiment classifier higher or worse?
On this one run, filtering made the classifier much less correct. Downweighting the flagged critiques additionally carried out worse than leaving the info alone.
The classifier was a logistic regression mannequin. In plain phrases, it realized from labeled examples how evaluate wording pertains to optimistic or destructive sentiment. It used the identical sentence embeddings as the 2 embedding primarily based checks. I measured accuracy on the 200 supply evaluate examples from movies excluded from coaching. Accuracy is the share of these reference critiques the classifier labeled accurately.
I in contrast 4 coaching units:
-
Untouched. All 600 critiques, with no cleansing.
-
Filtered. The 134 critiques left after eradicating each row at or above the mixed rating cutoff that caught 80 % of the AI critiques.
-
Downweighted. All 600 critiques, however critiques with greater mixed scores had much less affect throughout coaching.
-
Supply solely reference. The 200 Mendeley critiques handled as human examples. This can be a comparability level, not a sensible filter, as a result of the gathering doesn’t confirm authorship.
The untouched set reached 67.5 % accuracy, or 135 right predictions out of 200. The filtered set reached 57.5 %, or 115 right predictions. The downweighted set reached 63.5 %, or 127 right predictions. The supply solely reference reached 68.5 %, or 137 right predictions.
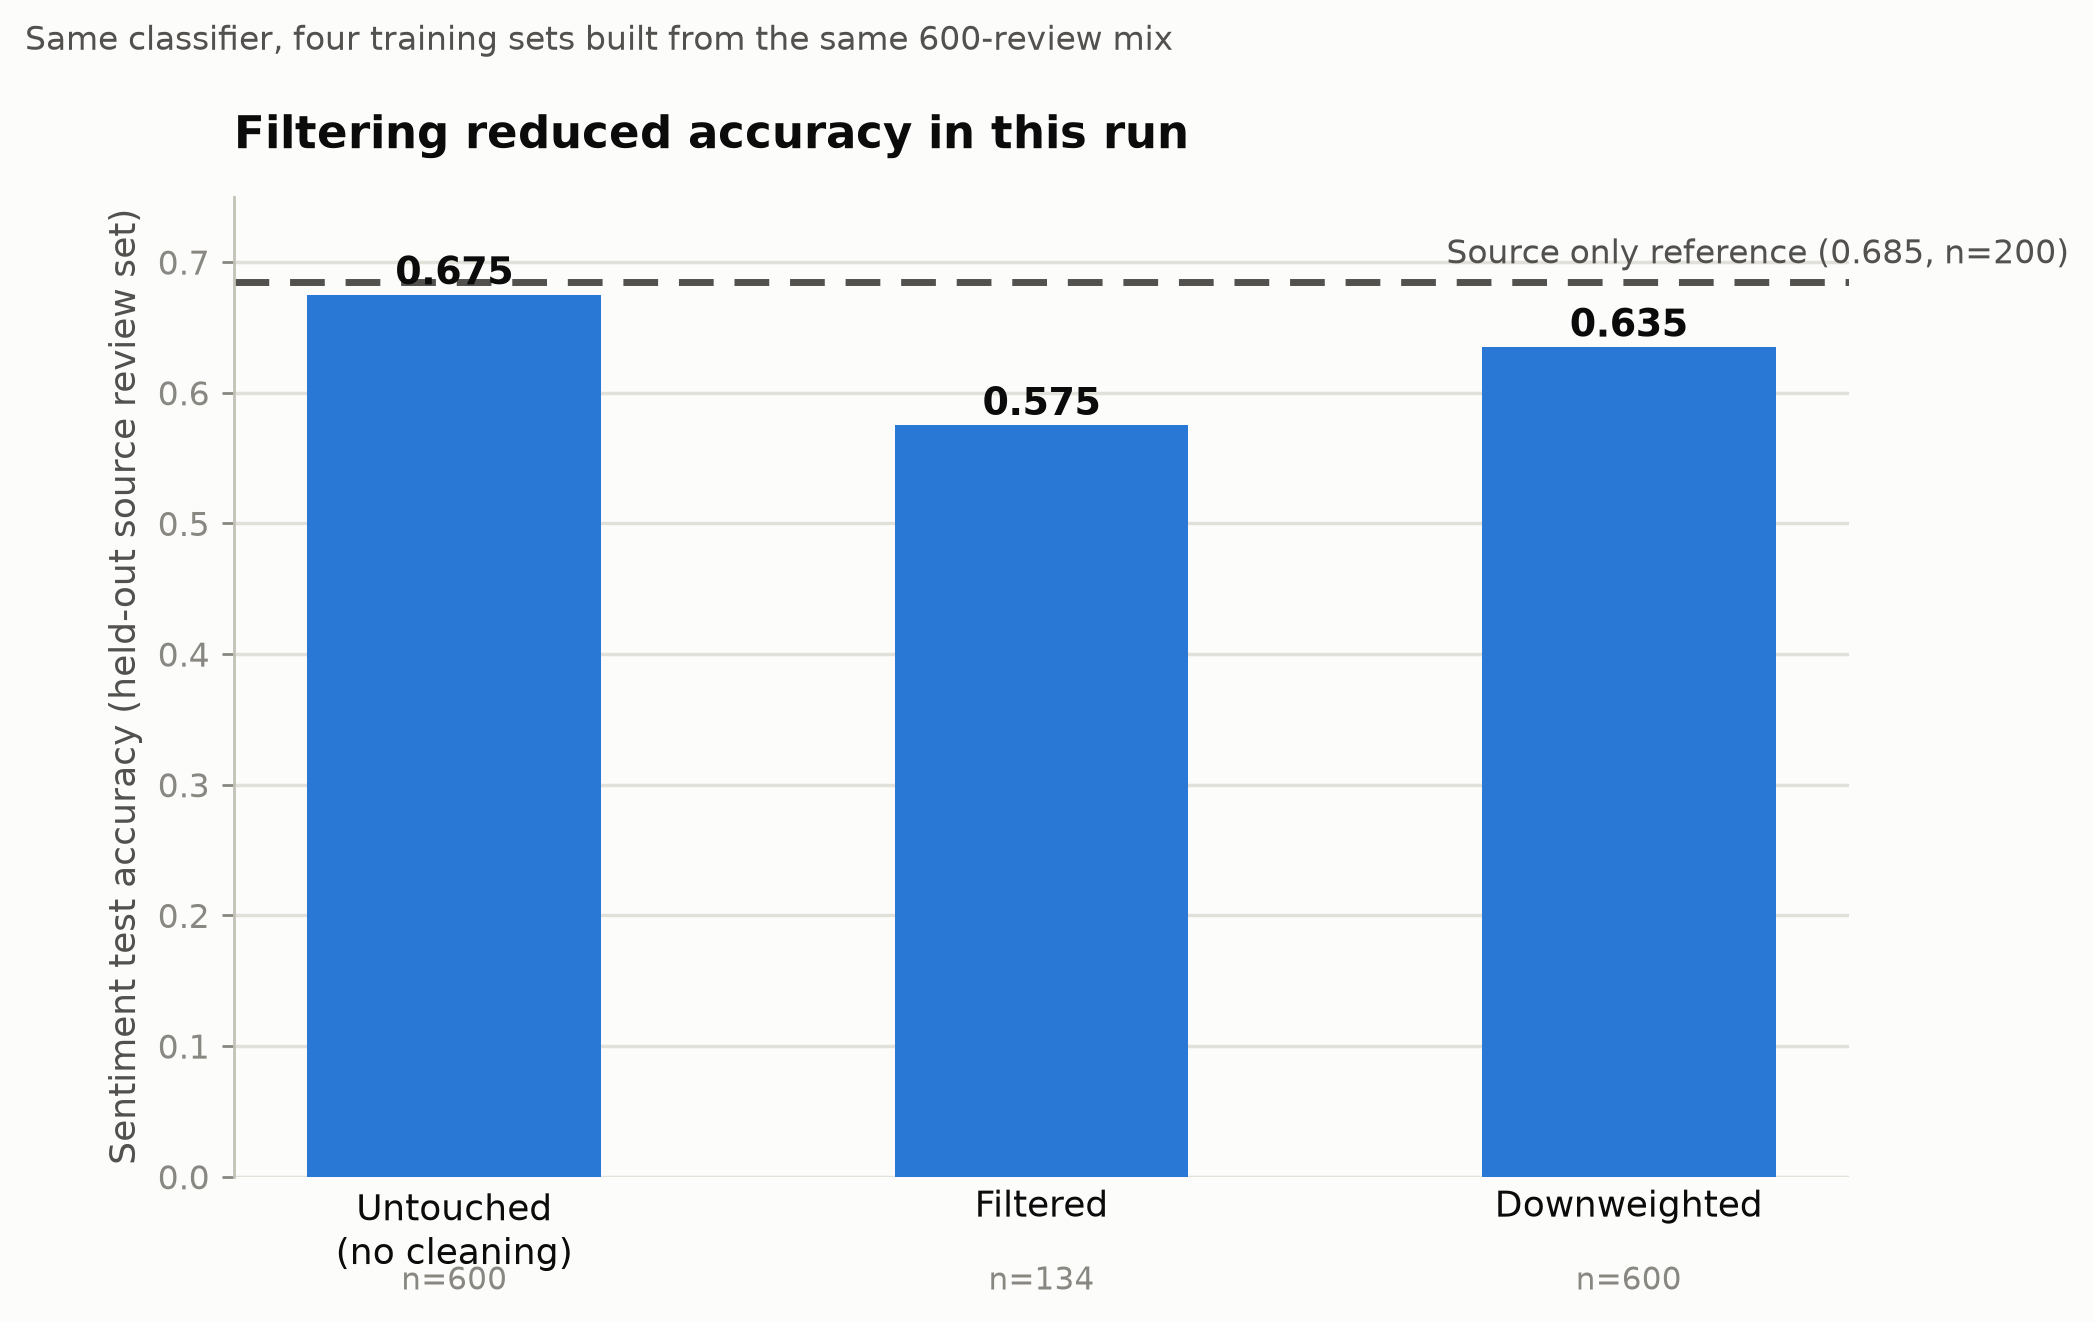
The filtered set shrank from 600 critiques to 134 as a result of the cutoff eliminated supply critiques in addition to generated ones. The experiment modified each the coaching knowledge and its dimension, so it can’t attribute the accuracy drop to eradicating generated textual content alone. It does present {that a} detector rating by itself will not be a cause to filter. Measure the impact on the duty the mannequin must carry out.
I ran the check as soon as with a hard and fast random seed, a quantity that makes the identical random choices repeatable. I didn’t repeat the check throughout a number of samples or calculate confidence intervals, ranges that present how a lot an estimate may differ throughout repeated samples. The accuracy figures due to this fact describe this run and its 200 check critiques. Repeated runs on new samples would present whether or not the identical sample holds.
Do you have to filter, flag, or downweight?
First check your detector on writing from the identical supply as your manufacturing knowledge, together with examples with verified authorship when attainable. Don’t take away critiques simply because a detector provides them a excessive rating.
On this pattern, the very best single sign nonetheless flagged almost half of the supply critiques handled as human on the chosen AI catch fee. The mixed rating carried out worse, and utilizing it to filter decreased the coaching knowledge from 600 critiques to 134. The downstream mannequin then made fewer right predictions than the mannequin skilled on all 600.
In case your dataset is giant sufficient, put aside examples with verified authorship and measure false alarms earlier than deploying a filter. Examine the mannequin skilled with no filtering towards the filtered and downweighted variations. If individuals can evaluate flagged examples, use that evaluate to determine which gadgets really need motion. If nobody will examine them, a flagging queue is simply an automated filter with an additional step.
What can this experiment inform us?
On this check, the very best detector caught 80 % of the generated critiques whereas flagging 47 % of the supply critiques handled as human. Eradicating the flagged critiques lower the sentiment classifier’s accuracy from 67.5 % to 57.5 %.
The sensible lesson is direct. On this experiment, embedding density caught generated critiques but additionally flagged many Mendeley critiques used as human references. Filtering with the mixed rating lower the sentiment mannequin’s accuracy from 67.5 % to 57.5 %. Take a look at detector flags towards examples with verified authorship, then measure whether or not filtering improves the duty your mannequin should carry out. These outcomes apply to this assortment, these two fashions, and this practice and check cut up. The archive audit identifies critiques the checks flagged; it doesn’t set up what number of had been written by AI.
Reproducing the experiment
The public replica repository accommodates the scripts, the precise 600 coaching critiques, the separate 200 evaluate check set, and the saved outcomes. Clone it on a pc with Python 3.11 or newer. The primary run downloads GPT-2 and the sentence embedding mannequin; each run domestically afterward. Clone the repository, enter its folder, set up the necessities, and run:
To repeat the audit of the complete Mendeley assortment, obtain model 1 from the Mendeley assortment web page, extract Dataset.rar, and level the audit script to the extracted folder:
The repository additionally contains the saved output information for comparability. Small numerical variations can happen throughout working techniques, {hardware}, and library variations. The Mendeley-derived critiques are an tailored subset of the gathering and are attributed within the repository. The audit experiences detector flags, not verified authorship.
Sources and dataset attribution
[1] W. Liang, Z. Izzo, et al., Monitoring AI-Modified Content material at Scale: A Case Research on the Impression of ChatGPT on AI Convention Peer Critiques (2024), Worldwide Convention on Machine Studying. Supply for the estimate of AI modification in convention peer critiques.
[2] I. Shumailov, Z. Shumaylov, Y. Zhao, N. Papernot, R. Anderson, Y. Gal, AI fashions collapse when skilled on recursively generated knowledge (2024), Nature. Background on the dangers of repeatedly coaching on mannequin generated textual content.
[3] Abdessamad Benlahbib, 1000 Film Critiques (Assessment + Hooked up score + Sentiment polarity) for Repute Era, Mendeley Information, model 1 (2019), DOI 10.17632/38j8b6s2mx.1. The document lists this dataset underneath CC BY 4.0. I used 400 supply critiques for coaching and testing, sampled by sentiment and separated by movie, and audited the opposite 594 distinct critiques. That is an adaptation of the printed dataset. The downloaded archive’s file timestamps are from 2017 to 2019, however the document provides no authentic posting date or authorship labels for particular person critiques.
[4] GPT-2, the open language mannequin used to calculate perplexity.
[5] all-MiniLM-L6-v2, the sentence embedding mannequin used for similarity, density, and sentiment classification.
[6] OpenAI, Introducing ChatGPT, 30 November 2022. Date of ChatGPT’s public launch.