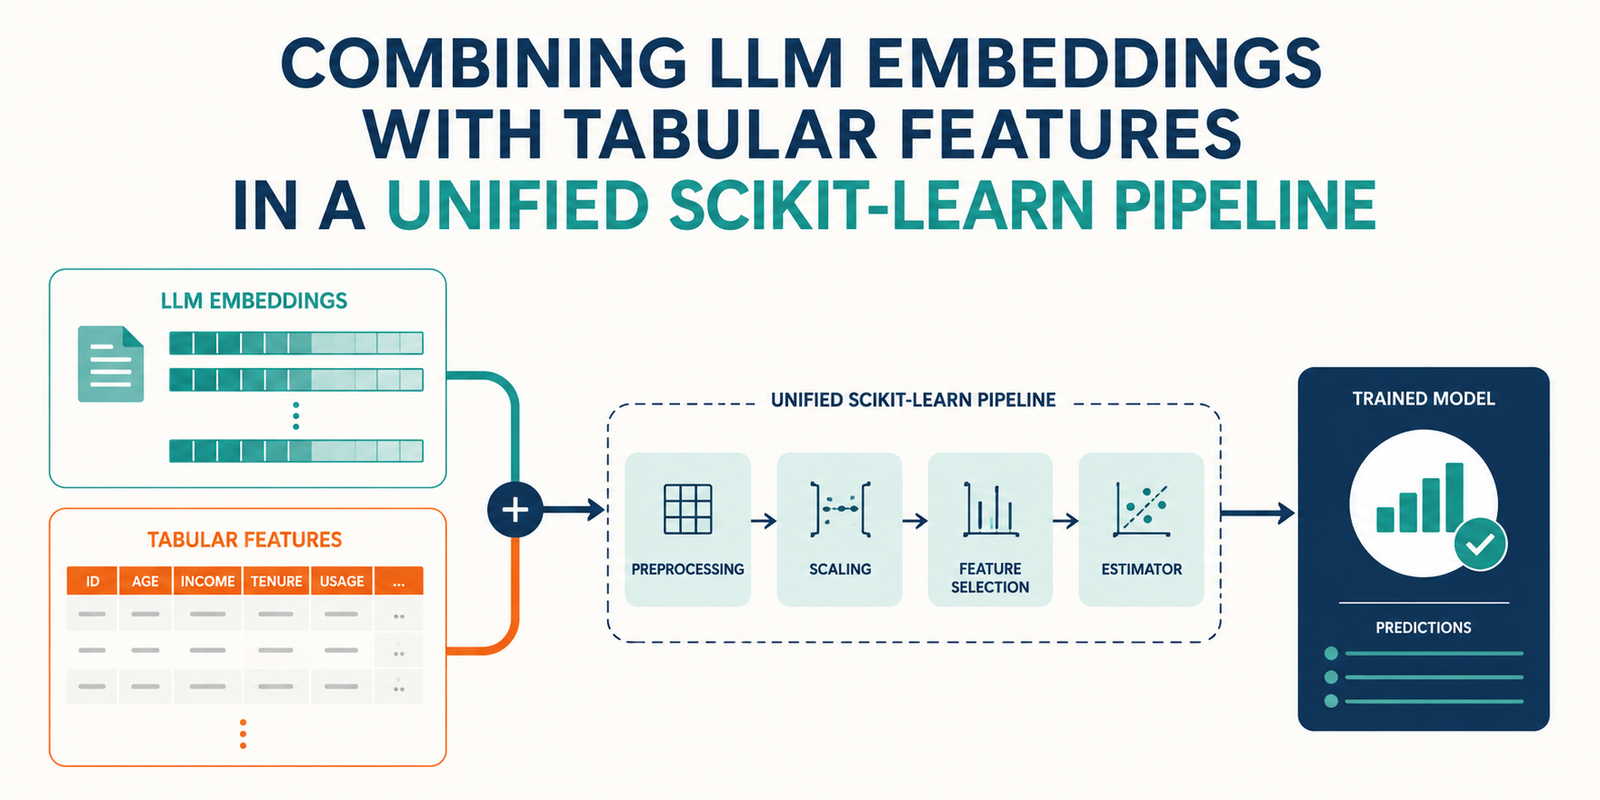
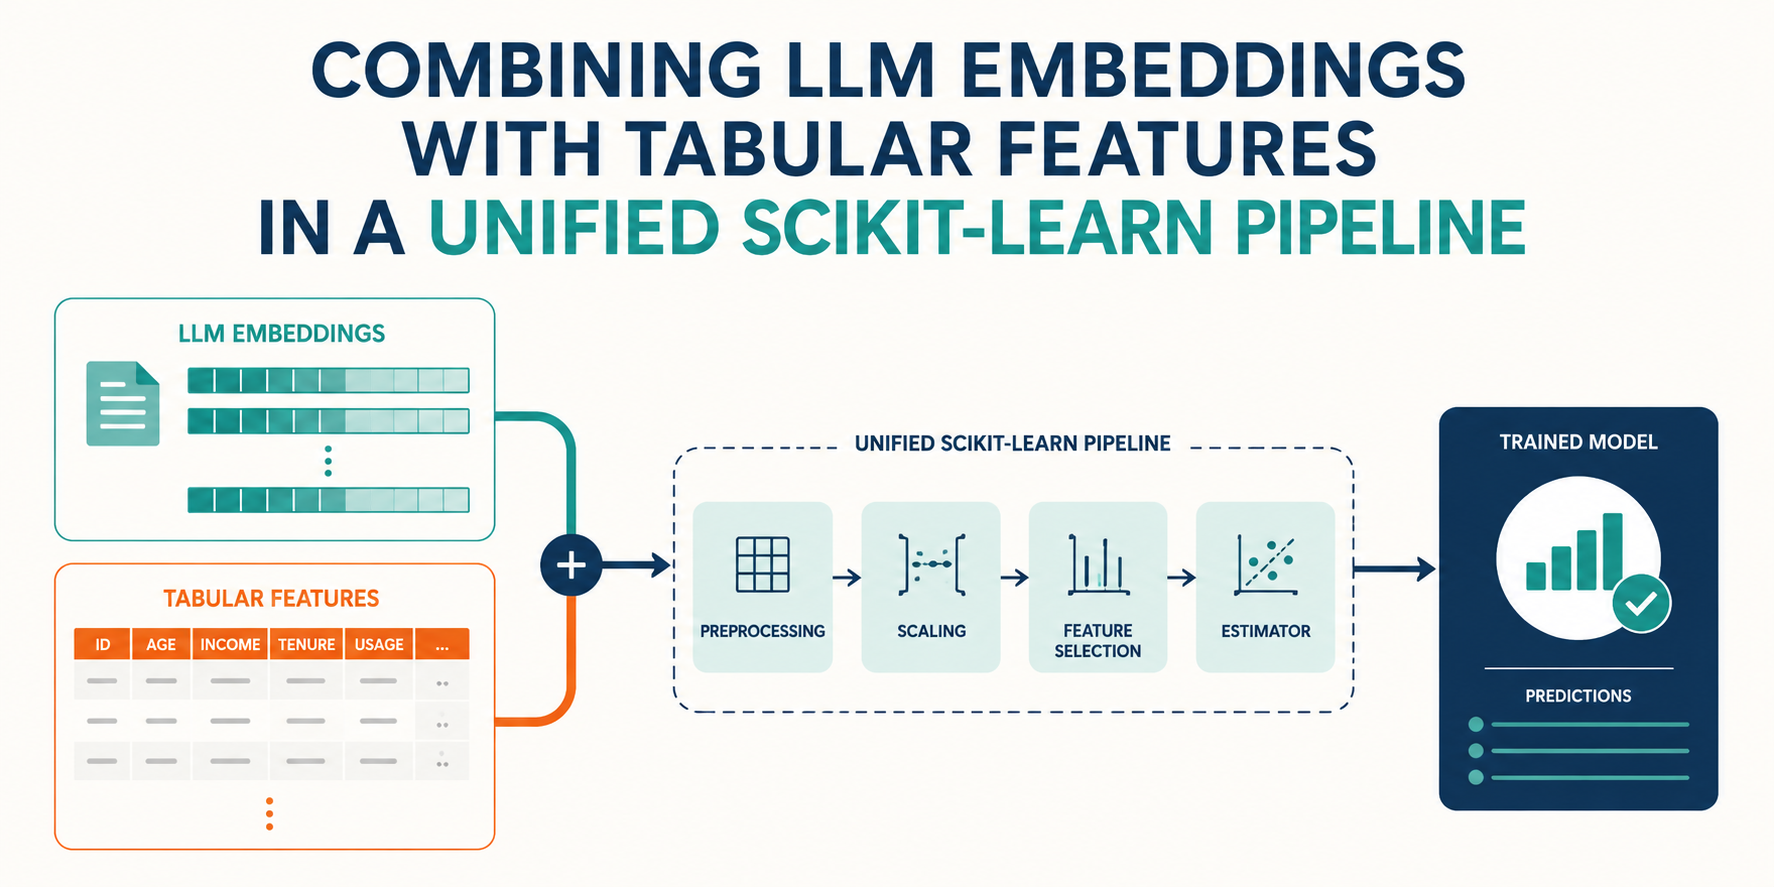
On this article, you’ll discover ways to construct a unified scikit-learn pipeline that mixes textual content embeddings generated by a light-weight open-source language mannequin with structured tabular options for classification duties.
Matters we are going to cowl embrace:
- Methods to generate textual content embeddings utilizing Hugging Face’s
sentence-transformerslibrary and wrap them in a customized scikit-learn transformer class. - Methods to use a
ColumnTransformerto run parallel preprocessing branches for textual content, numeric, and categorical options concurrently. - Methods to assemble and consider an entire, deployment-ready classification pipeline on a combined dataset combining actual textual content information with artificial tabular options.
Introduction
Actual-world duties like ticket triage or buyer churn prediction are sometimes addressed by constructing classification fashions. But, in an more and more data-pervaded period, the information used to assemble these fashions and carry out inference on them not often is available in a single taste. We are sometimes confronted with a mixture of tabular, structured information of numeric and qualitative nature, in addition to unstructured information like textual content — for example, ticket descriptions or buyer messages. Feeding these information sorts collectively into machine studying fashions requires efficient and unified pipelines that accommodate the newest information nuances and strategies to deal with them.
This text exhibits you how you can construct a clear, deployment-ready resolution that encapsulates embeddings generated by open-source LLMs (language fashions) right into a unified scikit-learn pipeline, bringing collectively textual content representations and tabular options of distinct sorts — all based mostly on using a ColumnTransformer. For instance its use, we are going to contemplate a classification situation for detecting spammer customers in a buyer base.
Stipulations
As an alternative of resorting to a paid API like OpenAI’s or Google Gemini’s, or a large open-source LLM like LLaMA 3, we are going to use a extra light-weight, CPU-friendly resolution to generate embeddings from a group of texts: Hugging Face’s sentence-transformers. Relying in your operating surroundings, all you could want is to put in the next libraries and dependencies:
|
!pip set up –q sentence–transformers scikit–be taught pandas numpy |
Take away the ! if you’re working in your personal Python IDE slightly than a cloud pocket book surroundings like Google Colab.
Step-by-Step Information
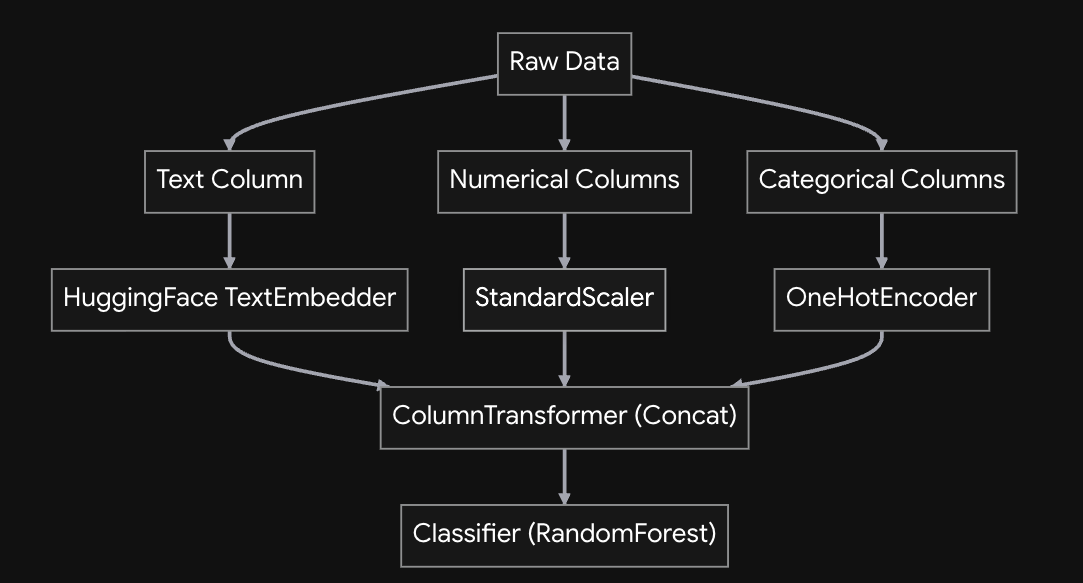
Right here’s what our meant, unified scikit-learn pipeline structure seems like:
However first, we want a combined dataset that appears fairly sensible. For this, we undertake a hybrid method: we pull an actual dataset accessible on GitHub — the well-known SMS Spam Assortment dataset containing customers’ textual content messages labeled as spam or not — and increase it with artificial tabular information options. Put collectively, the information will serve us to arrange a buyer churn/triage situation.
The code excerpt required for information technology is a bit massive, however there are many feedback that will help you perceive each choice behind the artificial information creation course of:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 |
import pandas as pd import numpy as np
# 1. Loading base textual content dataset from GitHub url = “https://uncooked.githubusercontent.com/justmarkham/pycon-2016-tutorial/grasp/information/sms.tsv” df = pd.read_csv(url, sep=‘t’, header=None, names=[‘label’, ‘message’])
# 2. Encoding authentic goal variable first (0 for regular/ham, 1 for spam) df[‘target’] = df[‘label’].map({‘ham’: 0, ‘spam’: 1})
# 3. Synthesising significant tabular options WITH sensible overlap (noise) # With out noise and some extent of overlap, the classifier we are going to construct would # simply obtain perfection: one thing not fairly sensible in apply. np.random.seed(42)
# Account Age: Regular customers may be model new, and spammers generally use older hacked accounts df[‘account_age_days’] = np.the place( df[‘target’] == 1, np.random.randint(1, 365, df.form[0]), # Spam: 1 to 12 months np.random.randint(1, 1500, df.form[0]) # Ham: 1 to 1500 days (Huge overlap) )
# Premium Standing: Including a bit extra noise right here df[‘is_premium’] = np.the place( df[‘target’] == 1, np.random.selection([‘no’, ‘yes’], df.form[0], p=[0.95, 0.05]), # Spam: 95% free np.random.selection([‘no’, ‘yes’], df.form[0], p=[0.80, 0.20]) # Ham: 80% free, 20% premium )
# Precedence Rating: Overlapping distributions so the mannequin cannot depend on this function alone to categorise prospects df[‘priority_score’] = np.the place( df[‘target’] == 1, np.random.uniform(0.4, 1.0, df.form[0]), # Spam: 0.4 to 1.0 np.random.uniform(0.0, 0.7, df.form[0]) # Ham: 0.0 to 0.7 (Overlap between 0.4 and 0.7) )
# Viewing a pattern of the logically cohesive combined information df.head(3) |
Instance output:
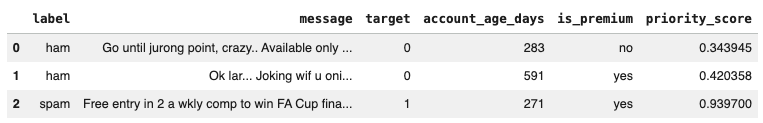
The subsequent step is essential, as that is the place we create the customized textual content transformer — see the leftmost department within the earlier diagram. In scikit-learn, that is executed by making a customized class that inherits from TransformerMixin and BaseEstimator. The requirement is to outline match() and remodel() strategies, similar to any pre-existing information transformation class within the library (e.g. commonplace scalers and one-hot encoders).
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 |
from sklearn.base import BaseEstimator, TransformerMixin from sentence_transformers import SentenceTransformer
class TextEmbedder(BaseEstimator, TransformerMixin): def __init__(self, model_name=‘all-MiniLM-L6-v2’): self.model_name = model_name self.mannequin = None
def match(self, X, y=None): # Initializing the mannequin in match() to adjust to sklearn cloning guidelines if self.mannequin is None: self.mannequin = SentenceTransformer(self.model_name) return self
def remodel(self, X, y=None): # Dealing with pandas DataFrame (extract the primary column as an inventory of strings) if isinstance(X, pd.DataFrame): texts = X.iloc[:, 0].astype(str).tolist() else: texts = pd.Sequence(X).astype(str).tolist()
# Utilizing the required LLM, generate and return embeddings as a 2D numpy array return self.mannequin.encode(texts, show_progress_bar=False) |
Discover that we specify the Hugging Face sentence-transformer mannequin to make use of — specifically all-MiniLM-L6-v2 — within the constructor technique, and name the mannequin in remodel() to map texts into embeddings.
Subsequent, as soon as we have now our embeddings, we apply the parallel information preprocessing required by the opposite options. Since this depends solely on already-implemented courses in scikit-learn, we will immediately assemble all of the type-specific preprocessing steps into an overarching, unified pipeline. We distinguish numerical columns from categorical ones, making use of commonplace scaling to the previous and one-hot encoding to the latter. Along with the beforehand carried out textual content embedding step, this provides us three processing branches that run in parallel. The way in which to implement that is by way of a ColumnTransformer object that accommodates an inventory of three “processing branches.” This mechanism retains the entire dataset collectively, with out the necessity to manually cut up and re-unify options.
After that, we add the ultimate stage: a random forest classifier. The whole course of seems as follows:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 |
from sklearn.compose import ColumnTransformer from sklearn.pipeline import Pipeline from sklearn.preprocessing import StandardScaler, OneHotEncoder from sklearn.ensemble import RandomForestClassifier from sklearn.model_selection import train_test_split from sklearn.metrics import classification_report
# Cut up information X = df[[‘message’, ‘account_age_days’, ‘priority_score’, ‘is_premium’]] y = df[‘target’] X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Outline column teams text_features = [‘message’] numeric_features = [‘account_age_days’, ‘priority_score’] categorical_features = [‘is_premium’]
# Construct the ColumnTransformer preprocessor = ColumnTransformer( transformers=[ (‘text’, TextEmbedder(), text_features), (‘num’, StandardScaler(), numeric_features), (‘cat’, OneHotEncoder(handle_unknown=‘ignore’), categorical_features) ], the rest=‘drop’ # Drop any columns not explicitly outlined )
# Assemble the ultimate pipeline pipeline = Pipeline(steps=[ (‘preprocessor’, preprocessor), (‘classifier’, RandomForestClassifier(n_estimators=100, random_state=42)) ]) |
Now that we have now assembled the whole pipeline, it’s time to attempt it out! The ultimate piece of code trains the mannequin — a course of that, due to the pipeline encapsulation, implicitly carries out all of the previous information preparations — and evaluates it on the take a look at set we put aside earlier:
|
# Coaching the mannequin (this can take a second to obtain the HF mannequin and embed the texts) print(“Coaching pipeline…”) pipeline.match(X_train, y_train)
# Evaluating on take a look at examples print(“Predicting and evaluating…”) y_pred = pipeline.predict(X_test) print(classification_report(y_test, y_pred)) |
Outcomes:
|
Predicting and evaluating... precision recall f1–rating help
0 0.99 1.00 0.99 966 1 1.00 0.91 0.95 149
accuracy 0.99 1115 macro avg 0.99 0.95 0.97 1115 weighted avg 0.99 0.99 0.99 1115 |
These outcomes are fairly respectable. A part of the reason being that the true dataset used for the labeled texts is thought for being simply class-separable and subsequently not laborious to categorise with excessive accuracy. We additionally deliberately added noise and overlap when creating the opposite artificial attributes to introduce a little bit of problem for our classifier — in any other case, it may need achieved 100% accuracy, which might not be very informative.
Conclusion
This text tackled an more and more widespread drawback within the AI and information science panorama: leveraging textual content information and mixing it with structured information options historically fed to downstream machine studying fashions for predictive duties like classification. We used scikit-learn’s transformer courses and a pre-trained language mannequin to construct a unified pipeline that cleanly and elegantly processes these combined information sorts, yielding a strong and simply reusable resolution.
On this article, you’ll discover ways to construct a unified scikit-learn pipeline that mixes textual content embeddings generated by a light-weight open-source language mannequin with structured tabular options for classification duties.
Matters we are going to cowl embrace:
- Methods to generate textual content embeddings utilizing Hugging Face’s
sentence-transformerslibrary and wrap them in a customized scikit-learn transformer class. - Methods to use a
ColumnTransformerto run parallel preprocessing branches for textual content, numeric, and categorical options concurrently. - Methods to assemble and consider an entire, deployment-ready classification pipeline on a combined dataset combining actual textual content information with artificial tabular options.
Introduction
Actual-world duties like ticket triage or buyer churn prediction are sometimes addressed by constructing classification fashions. But, in an more and more data-pervaded period, the information used to assemble these fashions and carry out inference on them not often is available in a single taste. We are sometimes confronted with a mixture of tabular, structured information of numeric and qualitative nature, in addition to unstructured information like textual content — for example, ticket descriptions or buyer messages. Feeding these information sorts collectively into machine studying fashions requires efficient and unified pipelines that accommodate the newest information nuances and strategies to deal with them.
This text exhibits you how you can construct a clear, deployment-ready resolution that encapsulates embeddings generated by open-source LLMs (language fashions) right into a unified scikit-learn pipeline, bringing collectively textual content representations and tabular options of distinct sorts — all based mostly on using a ColumnTransformer. For instance its use, we are going to contemplate a classification situation for detecting spammer customers in a buyer base.
Stipulations
As an alternative of resorting to a paid API like OpenAI’s or Google Gemini’s, or a large open-source LLM like LLaMA 3, we are going to use a extra light-weight, CPU-friendly resolution to generate embeddings from a group of texts: Hugging Face’s sentence-transformers. Relying in your operating surroundings, all you could want is to put in the next libraries and dependencies:
|
!pip set up –q sentence–transformers scikit–be taught pandas numpy |
Take away the ! if you’re working in your personal Python IDE slightly than a cloud pocket book surroundings like Google Colab.
Step-by-Step Information
Right here’s what our meant, unified scikit-learn pipeline structure seems like:
However first, we want a combined dataset that appears fairly sensible. For this, we undertake a hybrid method: we pull an actual dataset accessible on GitHub — the well-known SMS Spam Assortment dataset containing customers’ textual content messages labeled as spam or not — and increase it with artificial tabular information options. Put collectively, the information will serve us to arrange a buyer churn/triage situation.
The code excerpt required for information technology is a bit massive, however there are many feedback that will help you perceive each choice behind the artificial information creation course of:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 |
import pandas as pd import numpy as np
# 1. Loading base textual content dataset from GitHub url = “https://uncooked.githubusercontent.com/justmarkham/pycon-2016-tutorial/grasp/information/sms.tsv” df = pd.read_csv(url, sep=‘t’, header=None, names=[‘label’, ‘message’])
# 2. Encoding authentic goal variable first (0 for regular/ham, 1 for spam) df[‘target’] = df[‘label’].map({‘ham’: 0, ‘spam’: 1})
# 3. Synthesising significant tabular options WITH sensible overlap (noise) # With out noise and some extent of overlap, the classifier we are going to construct would # simply obtain perfection: one thing not fairly sensible in apply. np.random.seed(42)
# Account Age: Regular customers may be model new, and spammers generally use older hacked accounts df[‘account_age_days’] = np.the place( df[‘target’] == 1, np.random.randint(1, 365, df.form[0]), # Spam: 1 to 12 months np.random.randint(1, 1500, df.form[0]) # Ham: 1 to 1500 days (Huge overlap) )
# Premium Standing: Including a bit extra noise right here df[‘is_premium’] = np.the place( df[‘target’] == 1, np.random.selection([‘no’, ‘yes’], df.form[0], p=[0.95, 0.05]), # Spam: 95% free np.random.selection([‘no’, ‘yes’], df.form[0], p=[0.80, 0.20]) # Ham: 80% free, 20% premium )
# Precedence Rating: Overlapping distributions so the mannequin cannot depend on this function alone to categorise prospects df[‘priority_score’] = np.the place( df[‘target’] == 1, np.random.uniform(0.4, 1.0, df.form[0]), # Spam: 0.4 to 1.0 np.random.uniform(0.0, 0.7, df.form[0]) # Ham: 0.0 to 0.7 (Overlap between 0.4 and 0.7) )
# Viewing a pattern of the logically cohesive combined information df.head(3) |
Instance output:
The subsequent step is essential, as that is the place we create the customized textual content transformer — see the leftmost department within the earlier diagram. In scikit-learn, that is executed by making a customized class that inherits from TransformerMixin and BaseEstimator. The requirement is to outline match() and remodel() strategies, similar to any pre-existing information transformation class within the library (e.g. commonplace scalers and one-hot encoders).
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 |
from sklearn.base import BaseEstimator, TransformerMixin from sentence_transformers import SentenceTransformer
class TextEmbedder(BaseEstimator, TransformerMixin): def __init__(self, model_name=‘all-MiniLM-L6-v2’): self.model_name = model_name self.mannequin = None
def match(self, X, y=None): # Initializing the mannequin in match() to adjust to sklearn cloning guidelines if self.mannequin is None: self.mannequin = SentenceTransformer(self.model_name) return self
def remodel(self, X, y=None): # Dealing with pandas DataFrame (extract the primary column as an inventory of strings) if isinstance(X, pd.DataFrame): texts = X.iloc[:, 0].astype(str).tolist() else: texts = pd.Sequence(X).astype(str).tolist()
# Utilizing the required LLM, generate and return embeddings as a 2D numpy array return self.mannequin.encode(texts, show_progress_bar=False) |
Discover that we specify the Hugging Face sentence-transformer mannequin to make use of — specifically all-MiniLM-L6-v2 — within the constructor technique, and name the mannequin in remodel() to map texts into embeddings.
Subsequent, as soon as we have now our embeddings, we apply the parallel information preprocessing required by the opposite options. Since this depends solely on already-implemented courses in scikit-learn, we will immediately assemble all of the type-specific preprocessing steps into an overarching, unified pipeline. We distinguish numerical columns from categorical ones, making use of commonplace scaling to the previous and one-hot encoding to the latter. Along with the beforehand carried out textual content embedding step, this provides us three processing branches that run in parallel. The way in which to implement that is by way of a ColumnTransformer object that accommodates an inventory of three “processing branches.” This mechanism retains the entire dataset collectively, with out the necessity to manually cut up and re-unify options.
After that, we add the ultimate stage: a random forest classifier. The whole course of seems as follows:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 |
from sklearn.compose import ColumnTransformer from sklearn.pipeline import Pipeline from sklearn.preprocessing import StandardScaler, OneHotEncoder from sklearn.ensemble import RandomForestClassifier from sklearn.model_selection import train_test_split from sklearn.metrics import classification_report
# Cut up information X = df[[‘message’, ‘account_age_days’, ‘priority_score’, ‘is_premium’]] y = df[‘target’] X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Outline column teams text_features = [‘message’] numeric_features = [‘account_age_days’, ‘priority_score’] categorical_features = [‘is_premium’]
# Construct the ColumnTransformer preprocessor = ColumnTransformer( transformers=[ (‘text’, TextEmbedder(), text_features), (‘num’, StandardScaler(), numeric_features), (‘cat’, OneHotEncoder(handle_unknown=‘ignore’), categorical_features) ], the rest=‘drop’ # Drop any columns not explicitly outlined )
# Assemble the ultimate pipeline pipeline = Pipeline(steps=[ (‘preprocessor’, preprocessor), (‘classifier’, RandomForestClassifier(n_estimators=100, random_state=42)) ]) |
Now that we have now assembled the whole pipeline, it’s time to attempt it out! The ultimate piece of code trains the mannequin — a course of that, due to the pipeline encapsulation, implicitly carries out all of the previous information preparations — and evaluates it on the take a look at set we put aside earlier:
|
# Coaching the mannequin (this can take a second to obtain the HF mannequin and embed the texts) print(“Coaching pipeline…”) pipeline.match(X_train, y_train)
# Evaluating on take a look at examples print(“Predicting and evaluating…”) y_pred = pipeline.predict(X_test) print(classification_report(y_test, y_pred)) |
Outcomes:
|
Predicting and evaluating... precision recall f1–rating help
0 0.99 1.00 0.99 966 1 1.00 0.91 0.95 149
accuracy 0.99 1115 macro avg 0.99 0.95 0.97 1115 weighted avg 0.99 0.99 0.99 1115 |
These outcomes are fairly respectable. A part of the reason being that the true dataset used for the labeled texts is thought for being simply class-separable and subsequently not laborious to categorise with excessive accuracy. We additionally deliberately added noise and overlap when creating the opposite artificial attributes to introduce a little bit of problem for our classifier — in any other case, it may need achieved 100% accuracy, which might not be very informative.
Conclusion
This text tackled an more and more widespread drawback within the AI and information science panorama: leveraging textual content information and mixing it with structured information options historically fed to downstream machine studying fashions for predictive duties like classification. We used scikit-learn’s transformer courses and a pre-trained language mannequin to construct a unified pipeline that cleanly and elegantly processes these combined information sorts, yielding a strong and simply reusable resolution.