

Earlier article: When All You Have Are Decoders, Each Resolution Appears to be like Like Technology
TLDR
-
Jev-style fashions let brokers resolve with out producing solutions. For bounded decisions akin to routing or device choice, they rating the out there choices and return a typed resolution, giving brokers a direct different to producing and parsing a solution token by token.
-
Kev led on accuracy; Verdict additionally outperformed the LLM baseline. Kev reached 98% on each fastened routes and altering candidates. Verdict reached 89% on altering candidates, in contrast with 66% for LLM (baseline) Qwen3-0.6B, which reached 83% on fastened routes. JSON era nonetheless beat the three Qwen readout configurations.
-
Zero generated reply tokens, with decrease noticed latency for Kev and Verdict. Each generated no reply tokens, versus about 10 per request for Qwen JSON era. Recorded median request latency was 125–130 ms for Kev and 17–18 ms for Verdict, versus 331–357 ms for the LLM baseline throughout the 2 panels.
Obtain the starter package to strive a call mannequin, discover the benchmark, and evaluate JSON era with a direct readout.
Why we put resolution fashions to the check
In Half 1, we explored one thing that has by no means sat proper with us: utilizing a language mannequin to generate a solution token by token when the software program solely wants one selection. A banking buyer says, “I used to be charged twice for a similar switch.” The following step is to decide on a help route. Asking a mannequin to jot down {"route": "duplicate cost"} will get us there, nevertheless it additionally provides textual content era and parsing to a bounded resolution.
The concept of scoring the out there decisions instantly caught our consideration. We needed to know whether or not the open implementations may truly deal with the duty, and what we’d achieve or surrender through the use of them. May they select the appropriate route? May they nonetheless try this when the out there decisions modified? Would merely prompting a small language mannequin work simply as nicely?
A router could have a everlasting checklist of departments, whereas an agent’s out there instruments or actions can change with the workflow. We needed to know whether or not these resolution interfaces had been helpful in each conditions. We in contrast seven open initiatives and a Qwen JSON-generation baseline on banking requests with each secure route lists and altering candidate menus. Here’s what we discovered from operating these initiatives: how reliably they select a route, what modifications when the out there choices change, and what candidate scoring buys us over producing JSON.
Why runtime candidates change the issue
A candidate is one out there selection. A candidate-based interface lets the workflow provide the routes or instruments out there for the present request, and the mannequin scores that menu. The caller can change these decisions with out including a everlasting output slot for every route. For us, that flexibility is a serious purpose to discover these initiatives. A standard classifier with a everlasting output slot for every route wants adaptation when new routes are added.
One resolution contract, three query sorts
The identical help ticket can elevate a couple of bounded query. Conceptually, a call request may seem like this:
Every challenge has its personal wire format and supported query sorts. The shared concept is simple: present state, outline allowed solutions, obtain a typed consequence, and let deterministic code resolve the right way to use it. A caller can route, apply a examined threshold, or ship the case to an individual.
For a primary run, observe the Kev native fast begin, Verdict challenge README, Laya fast begin, OpenJev setup, AnyJev setup, Easy Jev server directions, or NanoJev CUDA fast begin. Every hyperlink goes to the challenge documentation retained on the revision used for the comparability. Examine the {hardware} and package deal necessities earlier than putting in.
Seven open initiatives to strive
The seven initiatives supply completely different routes into bounded choices. The overview separates their documented setup from measured banking accuracy. We added direct Qwen JSON era as a reference LLM baseline.
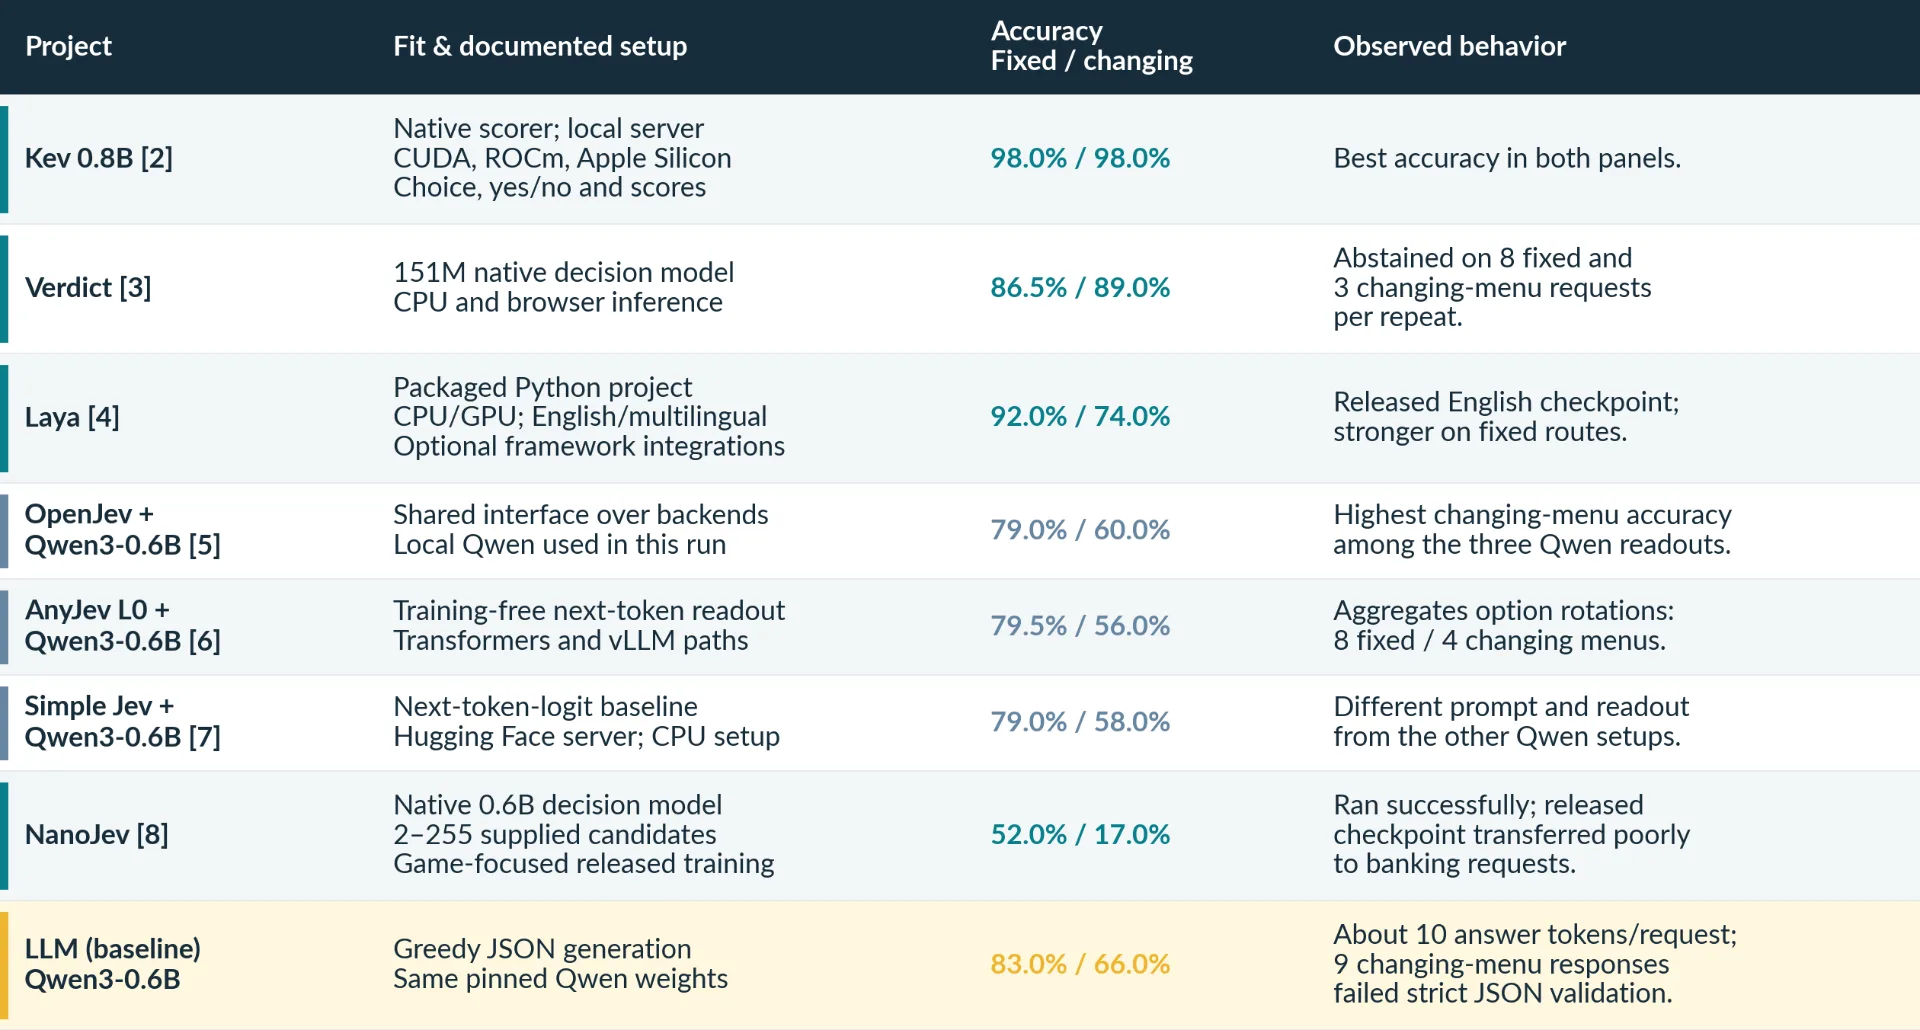
Comparability of Kev, Verdict, Laya, OpenJev, AnyJev, Easy Jev, NanoJev, and LLM (baseline) Qwen3-0.6B on banking request routing. Kev achieved 98% accuracy with each fastened routes and altering candidate menus. Verdict reached 86.5% and 89%, in contrast with 83% and 66% for the generative LLM baseline. The desk summarizes documented setup and noticed conduct; reference numbers determine challenge sources within the article. (Picture by Writer)
The beginning hyperlinks go to official READMEs pinned to the examined revisions. Examine their {hardware} and package deal necessities when selecting a runtime.
The initiatives fall into three broad teams. Educated scorers akin to Kev, Verdict, Laya, and NanoJev have a mannequin that instantly scores decisions. Coaching-free readouts akin to AnyJev and Easy Jev derive scores from language-model outputs. Serving layers akin to OpenJev expose a shared interface to a particular backend. The teams describe implementation decisions; the comparability nonetheless belongs to every particular challenge, checkpoint, and setup.
How we in contrast them
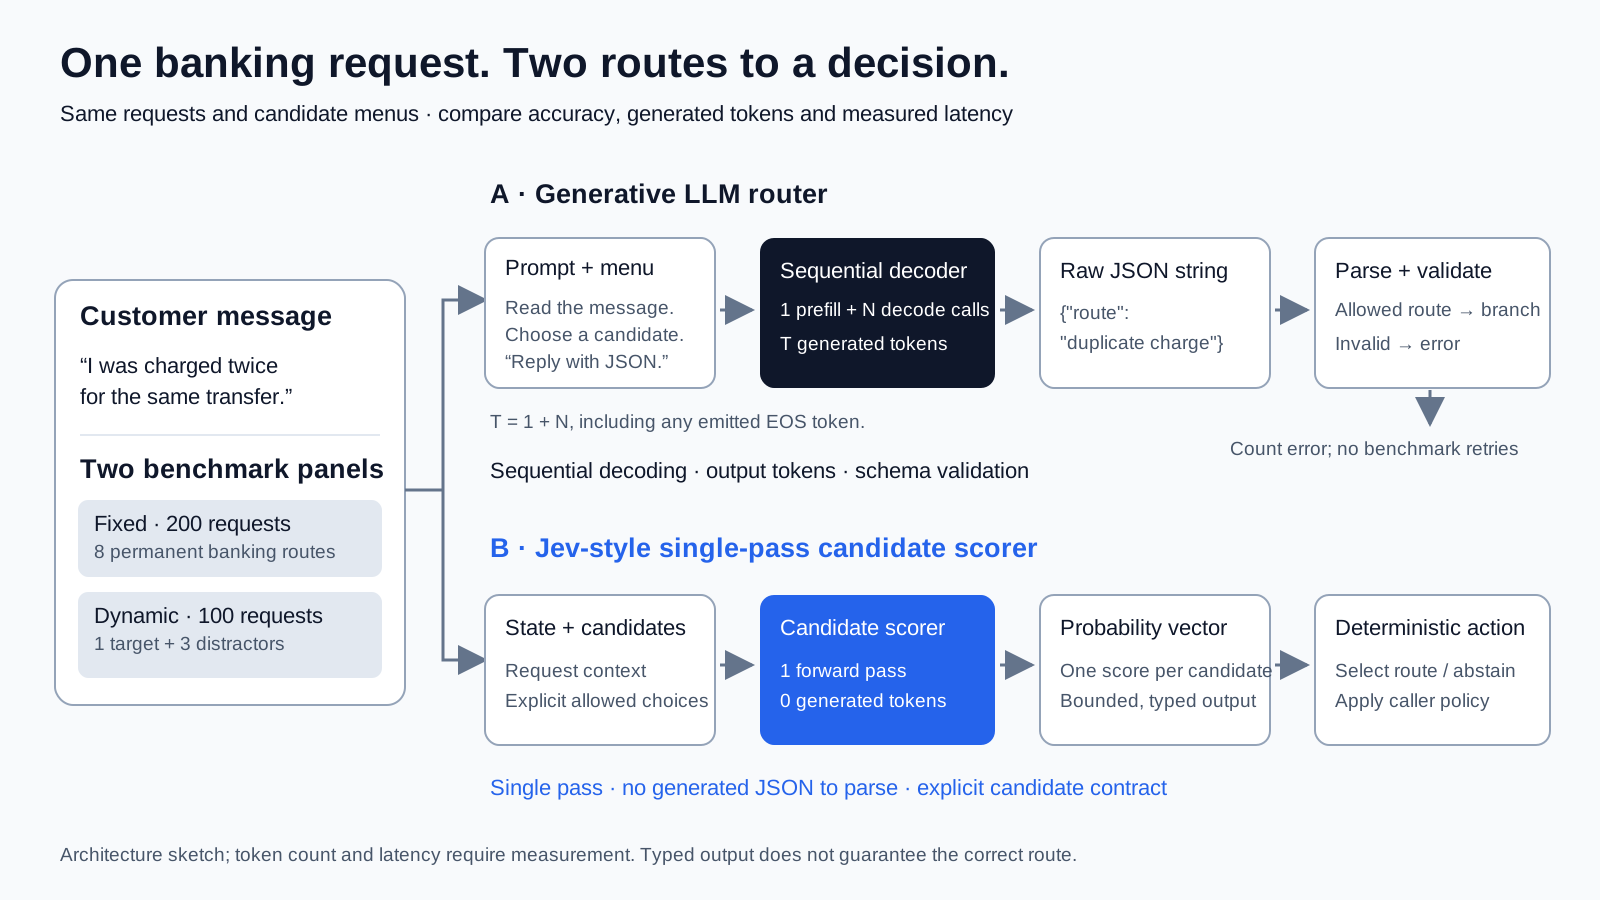
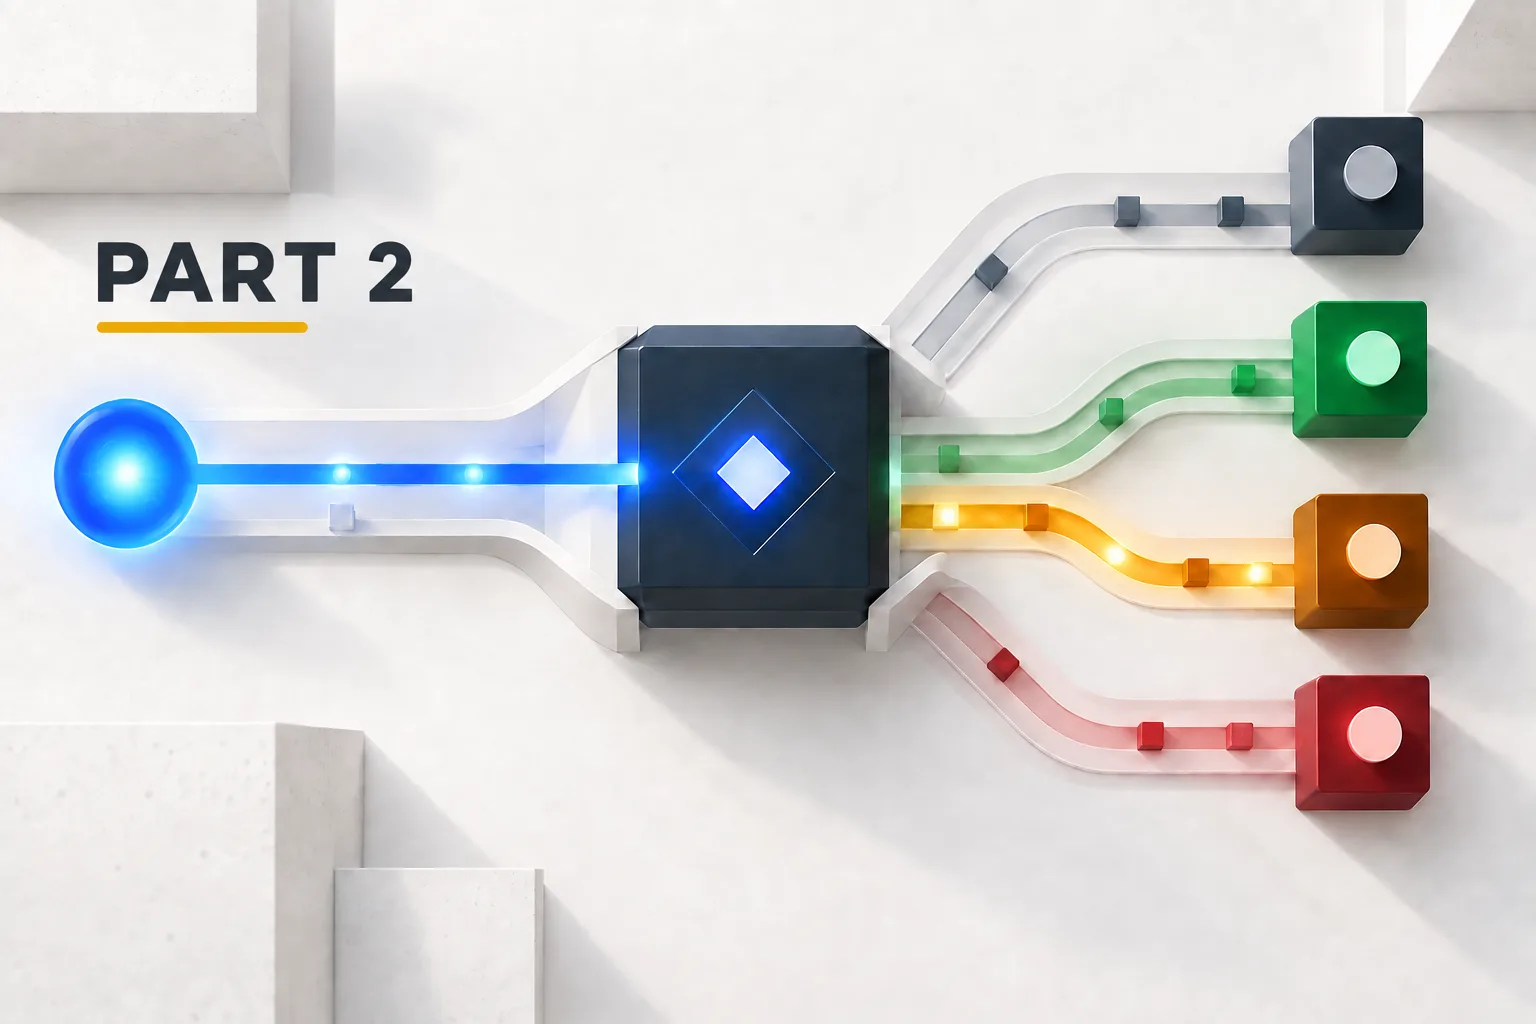
Comparability of generative LLM routing and single-pass candidate scoring for AI resolution duties. The generative path constructs a immediate, generates reply tokens, and validates JSON. The scoring path evaluates provided decisions and returns scores for route choice or abstention with out producing reply tokens. (Picture by Writer)
We used BANKING77, a dataset of brief banking requests labeled by intent, to check seven open initiatives. We additionally added a plain JSON-generation baseline utilizing the identical pinned Qwen3-0.6B checkpoint as AnyJev, Easy Jev, and OpenJev.
We chosen twelve intents and cut up the check into two settings. Mounted routes means each request will get the identical menu of eight banking routes. Dynamic candidates means every request will get its personal shuffled menu of 4 potential routes: the proper route and three distractors. The dynamic requests got here from 4 extra intents, and their distractors had been sampled from the complete pool of twelve.
Alongside routing accuracy, we recorded generated tokens, format failures, and request latency to see what every execution path concerned. Right here is how the requests had been divided:
|
Panel |
Requests in every repeat |
Sampling |
Query |
|---|---|---|---|
|
Mounted routes |
200 |
25 requests from every of eight intents |
Can the configuration select from the identical eight routes each time? |
|
Altering candidates |
100 |
25 requests from every of 4 different intents |
Can it select when every request provides 4 candidates, together with the proper route and three distractors? |
Mounted routes stored the menu unchanged. For “May you please activate my card,” the mannequin acquired these decisions, on this order:
The right route was activate my card, and the Qwen JSON baseline chosen it. Each different fixed-route request acquired that very same menu, whether or not the client wanted card activation, id verification, or assist with a failed top-up.
Dynamic candidates modified the menu with every request. The alternatives seem within the order provided to the mannequin:
|
Buyer request |
Candidate menu, in provided order |
Qwen chosen |
|---|---|---|
|
“There’s a cost on my card that I didn’t make” |
activate my card → unsuitable trade fee for money withdrawal → pending card cost → card cost not recognised |
card cost not recognised |
|
“There’s a cost that’s not mine within the app. Please advise” |
card cost not recognised → why confirm id → high up by card cost → contactless not working |
card cost not recognised |
Each requests have the identical right route: card cost not recognised. However the surrounding decisions change, and that route seems on the finish of 1 menu and the start of the opposite. It additionally belongs to the extra intents used for the dynamic panel, so it was absent from the fastened menu above. The mannequin had to select from the choices provided with the request; we didn’t retrain it between menus.
We sampled distractors and shuffled every dynamic menu, then gave each challenge the identical saved message and ordered menu. This exams routing with altering decisions and reply positions. To measure the impact of reordering alone, we would want to repeat the very same message and candidate set in numerous orders; this benchmark doesn’t isolate that impact.
Retaining the comparability constant
The examples are the primary 25 check data per chosen intent within the pinned BANKING77 revision. Each challenge acquired the identical saved candidate descriptions and order for every request, together with the shuffled menus within the dynamic panel. Every challenge stored its personal official immediate and readout coverage; the JSON baseline acquired the identical messages and menus.
We repeated every 300-request comparability twice, together with the brand new JSON baseline. Each configuration produced the identical particular person predictions throughout its two repeats. Accuracy is the fraction of right routes; specific abstentions and invalid generated responses depend as incorrect. Macro-F1 offers every goal route equal weight.
What occurred within the two panels
Can the mannequin select among the many identical routes?
For every of 200 requests, the mannequin noticed the identical eight routes. Kev led with 98.0% accuracy (196 right requests), adopted by Laya at 92.0% (184). Verdict reached 86.5% and abstained on eight requests. LLM (baseline) Qwen3-0.6B reached 83.0%; the opposite configurations ranged from 79.5% for AnyJev to 52.0% for NanoJev.
Desk 1. Mounted routes. Accuracy and macro-F1 are from both repeat; particular person predictions and displayed metrics matched throughout each repeats.
|
Configuration |
Accuracy |
Macro-F1 |
Abstentions |
|---|---|---|---|
|
Kev 0.8B |
98.0% |
0.980 |
0 |
|
Laya |
92.0% |
0.915 |
0 |
|
Verdict |
86.5% |
0.870 |
8 |
|
LLM (baseline) Qwen3-0.6B |
83.0% |
0.810 |
0 |
|
AnyJev L0 + Qwen3-0.6B |
79.5% |
0.771 |
0 |
|
Easy Jev + Qwen3-0.6B |
79.0% |
0.763 |
0 |
|
OpenJev + Qwen3-0.6B |
79.0% |
0.747 |
0 |
|
NanoJev |
52.0% |
0.486 |
0 |
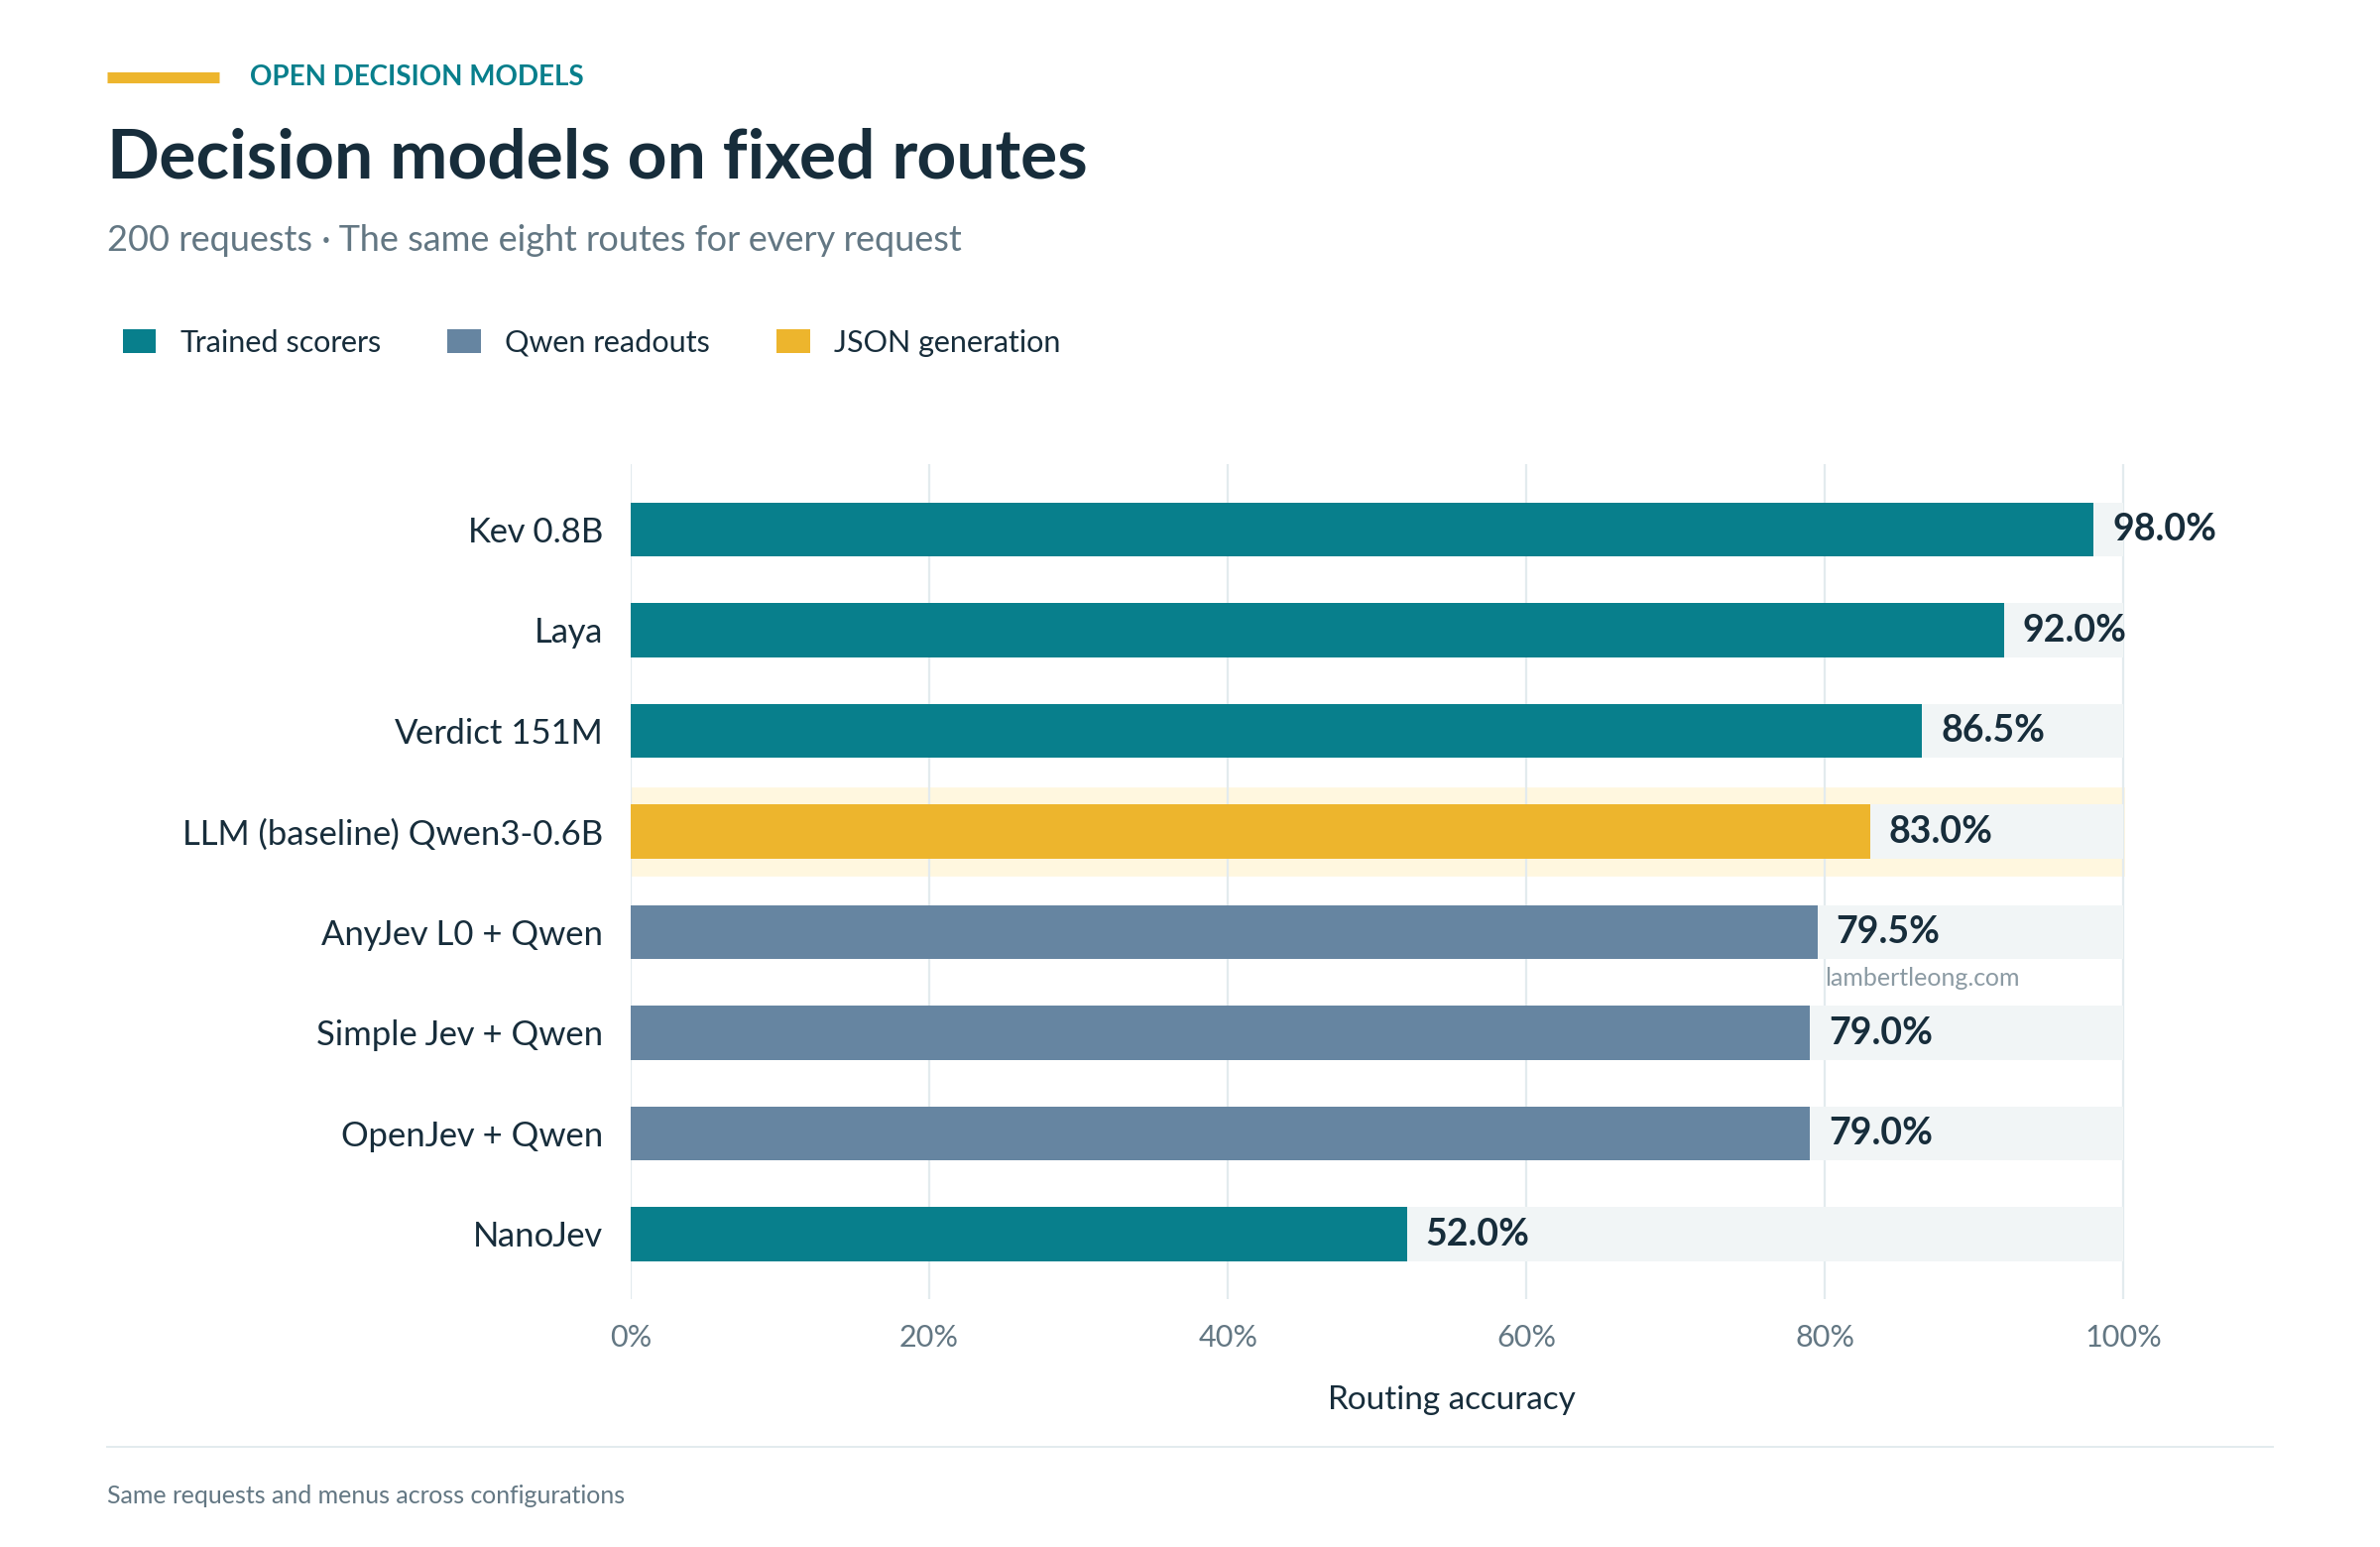
Accuracy comparability of seven open-source Jev-style configurations and LLM (baseline) Qwen3-0.6B on 200 banking requests with the identical eight routes out there for each request. Kev led at 98%, adopted by Laya at 92% and Verdict at 86.5%, versus 83% for the generative LLM baseline. Experiments used Colab GPU situations. (Picture by Writer)
What if the route checklist modifications?
Right here every request provided 4 candidates, together with the proper route from one of many 4 extra intents. Kev once more led with 98.0% accuracy (98 of 100 requests). Verdict got here subsequent at 89.0% (89 requests), regardless of having ranked under Laya on fastened routes. Laya reached 74.0%.
Desk 2. Altering candidates. Macro-F1 averages over the 4 goal intents; a prediction of one of many distractor routes is an error.
|
Configuration |
Accuracy |
Macro-F1 |
Abstentions |
|---|---|---|---|
|
Kev 0.8B |
98.0% |
0.990 |
0 |
|
Verdict |
89.0% |
0.929 |
3 |
|
Laya |
74.0% |
0.748 |
0 |
|
LLM (baseline) Qwen3-0.6B |
66.0% |
0.738 |
0 |
|
OpenJev + Qwen3-0.6B |
60.0% |
0.703 |
0 |
|
Easy Jev + Qwen3-0.6B |
58.0% |
0.690 |
0 |
|
AnyJev L0 + Qwen3-0.6B |
56.0% |
0.631 |
0 |
|
NanoJev |
17.0% |
0.249 |
0 |
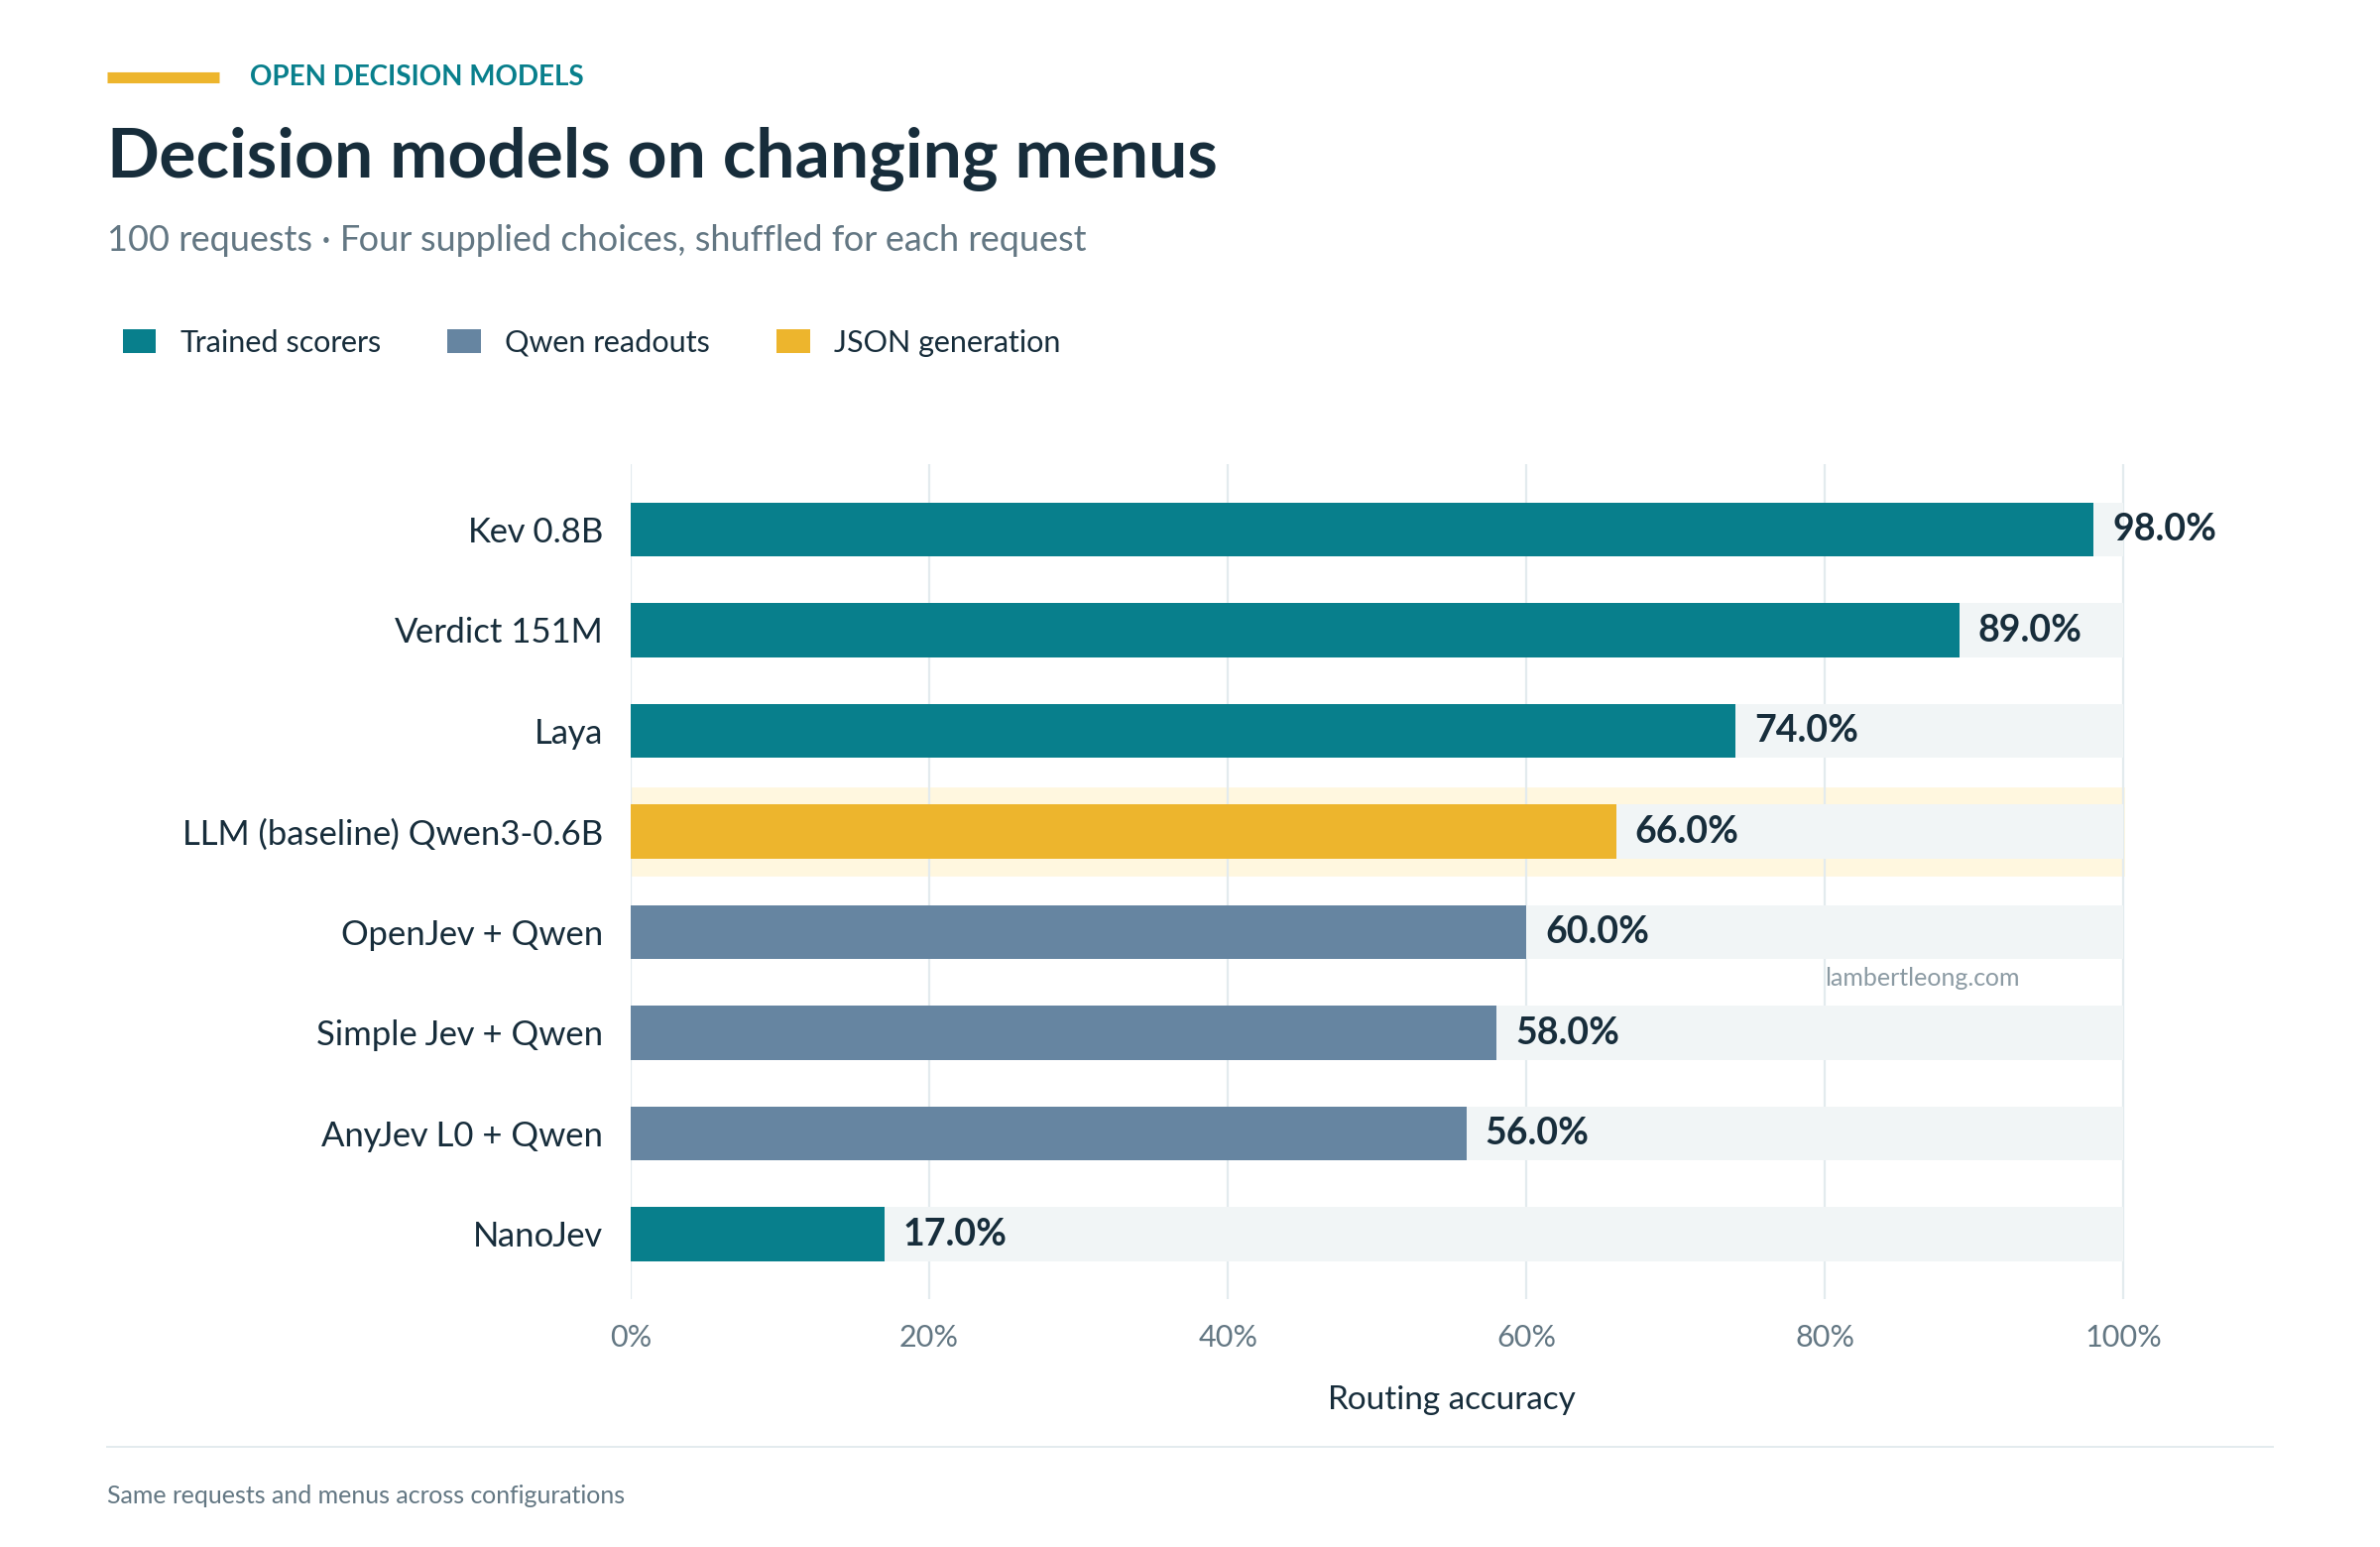
Accuracy comparability on 100 banking requests, every provided with 4 shuffled candidate routes: the proper route and three distractors. Kev reached 98% and Verdict 89%, in contrast with 66% for LLM (baseline) Qwen3-0.6B. This panel evaluates altering candidate menus and completely different goal intents from the fixed-route panel. (Picture by Writer)
The consequence that stood out to us is that accepting a brand new candidate checklist and selecting nicely from it are separate talents. NanoJev dealt with the changing-candidate interface, however its launched game-trained checkpoint reached solely 17% accuracy on these banking requests. Dynamic candidates make a brand new selection expressible; they don’t assure that the mannequin is aware of what to do with it.
The three Qwen readouts had been shut: 79.0–79.5% on fastened routes and 56–60% on altering candidates. Plain JSON era reached 83% and 66%. That stunned us: eradicating reply era didn’t enhance routing accuracy for these Qwen configurations. The immediate and readout coverage nonetheless matter.
The Generative Baseline: Why Not Simply Immediate an LLM?
Half 1 requested why brokers ought to generate tokens for small choices. Here’s what occurred after we stored the Qwen weights fastened and requested for JSON.
The baseline makes use of Qwen/Qwen3-0.6B at revision c1899de289a04d12100db370d81485cdf75e47ca, precisely as AnyJev, Easy Jev, and OpenJev do right here. It sees the identical BANKING77 check messages and candidate menus. Pondering is disabled, decoding is grasping, the restrict is 40 new tokens, and there aren’t any retries. The required response is a single JSON object with one route area naming an allowed route ID.
High quality first: era beat the three Qwen readout setups on each panels. It chosen the proper route on 166 of 200 fastened requests and 66 of 100 changing-candidate requests beneath the strict contract. Verdict’s compact native mannequin reached 89% on the altering panel, and Kev reached 98%.
Then the output contract: all 9 dynamic failures had been legitimate JSON objects wrapped in markdown fences. The strict JSON-only parser rejected these responses. This was a formatting failure, not damaged JSON syntax or an off-menu route. A wrapper that strips fences would change the coverage and must be measured as a separate configuration. Typed candidate output avoids this specific generated-string failure mode.
Lastly the work per request: the baseline emitted 9.71 tokens on common for fastened routes and 9.96 for altering candidates, together with EOS. In unusual grasping decoding, T emitted tokens require one prefill plus T−1 decode calls. The native scorers and logit readouts emitted zero autoregressive reply tokens. AnyJev L0 nonetheless evaluated eight choice rotations on the fastened panel and 4 on the altering panel; zero generated tokens doesn’t suggest one mannequin cross for each implementation.
The desk reveals heat request measurements from repeat one. Latency is descriptive of every recorded request path; the scope part under explains the timing boundaries.
|
Configuration |
Panel |
Generated tokens (imply) |
p50 (ms) |
p95 (ms) |
Schema failures |
Est. Price / 1k requests |
|---|---|---|---|---|---|---|
|
Kev 0.8B |
Mounted |
0.00 |
130.0 |
134.2 |
0.0% |
$0.091 |
|
Kev 0.8B |
Dynamic |
0.00 |
124.7 |
127.4 |
0.0% |
$0.087 |
|
Verdict 151M |
Mounted |
0.00 |
18.2 |
19.9 |
0.0% |
$0.013 |
|
Verdict 151M |
Dynamic |
0.00 |
16.9 |
19.5 |
0.0% |
$0.012 |
|
AnyJev L0 + Qwen |
Mounted |
0.00 |
370.7 |
378.6 |
0.0% |
$0.258 |
|
AnyJev L0 + Qwen |
Dynamic |
0.00 |
187.3 |
191.5 |
0.0% |
$0.131 |
|
LLM (baseline) Qwen3-0.6B |
Mounted |
9.71 |
330.7 |
507.2 |
0.0% |
$0.247 |
|
LLM (baseline) Qwen3-0.6B |
Dynamic |
9.96 |
356.8 |
471.2 |
9.0% |
$0.250 |
The GPU estimate assumes a reference compute fee of $2.50 per GPU-hour:
Analysis Scope & Measurement Boundaries
The seven-project run and the generative follow-up used Colab GPUs at batch measurement one in separate periods. Laya used bfloat16; the opposite configurations used float32. Current SDK timings and HTTP spherical journeys cowl completely different boundaries. The generative timer contains immediate building, tokenization, era, decoding and validation with CUDA synchronization. The noticed latency variations describe these configurations and request paths; they don’t isolate an architecture-only speedup. GPU estimates exclude mannequin loading, idle time, batching and extra manufacturing infrastructure overhead; the recorded request overhead stays included. Server-reported serialization tokens should not counted as autoregressive reply tokens.
The panels cowl twelve BANKING77 intents. 4 changing-panel intents had been excluded from the fastened choice; their absence from mannequin pretraining is unknown. Immediate insurance policies, mannequin sizes and coaching histories differ. This check doesn’t cowl all banking intents, various candidate counts, lengthy paperwork, multilingual conduct or manufacturing device use. It doesn’t validate calibration or an automation threshold. CPU, browser and integration capabilities within the overview come from challenge documentation. Check helpful candidate descriptions and a fallback coverage on held-out requests from your individual workflow.
Which challenge do you have to strive?
-
If you’d like the strongest measured start line in these two routing panels, strive Kev. Its outcomes had been greatest right here, and its README paperwork an area server and small-model choices. Its native server is a sensible entry level for testing your individual routes.
-
If runtime candidates matter and also you need a compact native mannequin, take a better take a look at Verdict. It was second on the changing-candidate panel and paperwork CPU and browser paths.
-
If you’d like a packaged Python challenge with integration choices, think about Laya. Its Python integrations could suit your stack; begin with the launched English checkpoint used right here.
-
If you wish to route the identical interface by way of completely different language-model backends, discover OpenJev. On this run, its Qwen setup had the very best changing-candidate rating among the many three shared-Qwen approaches, by a small descriptive margin.
-
If you’d like a training-free readout from a causal language mannequin, evaluate AnyJev and Easy Jev in your prompts. Their readout procedures differ, and neither outperformed the skilled scorers throughout each panels right here.
-
If you wish to research or prepare a local dynamic-candidate structure for recreation or motion choices, NanoJev is an fascinating challenge. Its launched checkpoint was a poor match for these banking requests, so we’d not select it for banking routing based mostly on this check.
So what does this all imply?
Open initiatives make the Jev-style resolution interface one thing we are able to discover domestically. On this small banking check, Kev was the strongest configuration on each panels. Verdict confirmed a stronger changing-candidate consequence than its fixed-route consequence, whereas NanoJev confirmed {that a} versatile candidate interface by itself doesn’t guarantee helpful accuracy. These findings give us results in check, not a common winner.
What we’d carry into a brand new challenge is a small comparability: a local scorer, direct JSON era, and a readout from a mannequin we have already got. Give them the identical requests and menus. Measure right routes, invalid outputs, latency and abstentions collectively. That makes the selection a workflow resolution you may examine.
Proof and references
The challenge capabilities and setup paths under come from the pinned challenge documentation. Benchmark percentages, macro-F1 values, and abstention counts come from the saved comparability described above. They’re completely different sorts of proof.
[1] TypeSafe AI. Introducing System One Fashions & Jev.
[2] Palmer, J. Kev. Pinned README and native fast begin.
[3] Heman10x. Verdict. Pinned README.
[4] NandhaKishorM. Laya. Pinned README and fast begin.
[5] lookski. OpenJev. Pinned README; the measured server used an area Qwen backend.
[6] Zhang et al. AnyJev. Pinned README.
[7] Featherless AI. Easy Jev. Pinned README.
[8] TianyuCodings. NanoJev. Pinned README and CUDA fast begin.