• Home
  • About Us
  • Contact Us
  • Disclaimer
  • Privacy Policy
Friday, October 9, 2026
newsaiworld
  • Home
  • Artificial Intelligence
  • ChatGPT
  • Data Science
  • Machine Learning
  • Crypto Coins
  • Contact Us
No Result
View All Result
  • Home
  • Artificial Intelligence
  • ChatGPT
  • Data Science
  • Machine Learning
  • Crypto Coins
  • Contact Us
No Result
View All Result
Morning News
No Result
View All Result
Home Data Science

AI Inference: NVIDIA Studies Blackwell Surpasses 1000 TPS/Consumer Barrier with Llama 4 Maverick

Admin by Admin
May 24, 2025
in Data Science
0
1748076721 nvidia logo 2 1 0525.png
0
SHARES
4
VIEWS
Share on FacebookShare on Twitter


NVIDIA stated it has achieved a document giant language mannequin (LLM) inference pace, asserting that an NVIDIA DGX B200 node with eight NVIDIA Blackwell GPUs achieved greater than 1,000 tokens per second (TPS) per person on the 400-billion-parameter Llama 4 Maverick mannequin.

NVIDIA stated the mannequin is the biggest and strongest within the Llama 4 assortment and that the pace was independently measured by the AI benchmarking service Synthetic Evaluation.

NVIDIA added that Blackwell reaches 72,000 TPS/server at their highest throughput configuration.

The corporate stated it made software program optimizations utilizing TensorRT-LLM and skilled a speculative decoding draft mannequin utilizing EAGLE-3 methods. Combining these approaches, NVIDIA has achieved a 4x speed-up relative to the most effective prior Blackwell baseline, NVIDIA stated.

“The optimizations described beneath considerably enhance efficiency whereas preserving response accuracy,” NVIDIA stated in a weblog posted yesterday. “We leveraged FP8 knowledge sorts for GEMMs, Combination of Specialists (MoE), and Consideration operations to cut back the mannequin measurement and make use of the excessive FP8 throughput doable with Blackwell Tensor Core know-how. Accuracy when utilizing the FP8 knowledge format matches that of Synthetic Evaluation BF16 throughout many metrics….”Most generative AI software contexts require a stability of throughput and latency, making certain that many purchasers can concurrently take pleasure in a “adequate” expertise. Nonetheless, for important functions that should make vital choices at pace, minimizing latency for a single consumer turns into paramount. Because the TPS/person document exhibits, Blackwell {hardware} is the only option for any process—whether or not it’s good to maximize throughput, stability throughput and latency, or decrease latency for a single person (the main focus of this submit).

Under is an outline of the kernel optimizations and fusions (denoted in red-dashed squares) NVIDIA utilized through the inference. NVIDIA applied a number of low-latency GEMM kernels, and utilized numerous kernel fusions (like FC13 + SwiGLU, FC_QKV + attn_scaling and AllReduce + RMSnorm) to ensure Blackwell excels on the minimal latency state of affairs.
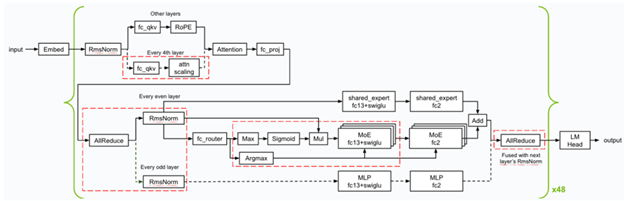
Overview of the kernel optimizations & fusions used for Llama 4 Maverick

NVIDIA optimized the CUDA kernels for GEMMs, MoE, and Consideration operations to realize the most effective efficiency on the Blackwell GPUs.

READ ALSO

Bridging Algorithmic Design and Regulatory Requirements in Enterprise AI

Finest Specialists for US Corporations

  • Utilized spatial partitioning (often known as warp specialization) and designed the GEMM kernels to load knowledge from reminiscence in an environment friendly method to maximise utilization of the large reminiscence bandwidth that the NVIDIA DGX system provides—64TB/s HBM3e bandwidth in complete.
  • Shuffled the GEMM weight in a swizzled format to permit higher format when loading the computation end result from Tensor Reminiscence after the matrix multiplication computations utilizing Blackwell’s fifth-generation Tensor Cores.
  • Optimized the efficiency of the eye kernels by dividing the computations alongside the sequence size dimension of the Ok and V tensors, permitting computations to run in parallel throughout a number of CUDA thread blocks. As well as, NVIDIA utilized distributed shared reminiscence to effectively scale back ‌outcomes throughout the thread blocks in the identical thread block cluster with out the necessity to entry the worldwide reminiscence.

The rest of the weblog could be discovered right here.


Tags: barrierBlackwellInferenceLlamaMaverickNVIDIAreportsSurpassesTPSUser

Related Posts

Guerrillabuzz 7hA2wqBcSF8 unsplash scaled.jpg
Data Science

Bridging Algorithmic Design and Regulatory Requirements in Enterprise AI

October 9, 2026
Vibe coding cleanup best specialists for us companies featured.png
Data Science

Finest Specialists for US Corporations

October 9, 2026
Kdn 7 best resources to learn about self evolving ai agents feature.png
Data Science

7 Greatest Assets to Study About Self-Evolving AI Brokers

October 8, 2026
Retail management not all stockouts cost the same featured.png
Data Science

Not All Stockouts Value the Identical

October 8, 2026
Rosidi ML Engineer AI Engineer LLM Engineer 1.png
Data Science

ML Engineer, AI Engineer, or LLM Engineer: Which Function Truly Builds What in 2026?

October 7, 2026
Saas pricing seat plus meter ai model.jpg
Data Science

SaaSpocalypse Actuality Examine: Distributors Maintain the Seat and Add a Meter

October 6, 2026
Next Post
Newasset blog.png

RIZE is obtainable for buying and selling!

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

POPULAR NEWS

Gemini 2.0 Fash Vs Gpt 4o.webp.webp

Gemini 2.0 Flash vs GPT 4o: Which is Higher?

January 19, 2025
Chainlink Link And Cardano Ada Dominate The Crypto Coin Development Chart.jpg

Chainlink’s Run to $20 Beneficial properties Steam Amid LINK Taking the Helm because the High Creating DeFi Challenge ⋆ ZyCrypto

May 17, 2025
Image 100 1024x683.png

Easy methods to Use LLMs for Highly effective Computerized Evaluations

August 13, 2025
Blog.png

XMN is accessible for buying and selling!

October 10, 2025
0 3.png

College endowments be a part of crypto rush, boosting meme cash like Meme Index

February 10, 2025

EDITOR'S PICK

Xrp etfs set to reach secs desk as billions ready to pour into xrp following ripple win against sec.jpg

Why XRP Worth Has Dropped Regardless of Huge Success This Week ⋆ ZyCrypto

September 27, 2025
11 4.webp.webp

5 Methods to Use ChatGPT’s Scheduled Process Characteristic

January 16, 2025
Bitcoin A4feb6.jpg

Bitcoin Might Rally In Q1 2025 Pushed By US Fed’s Cash Printing, Predicts Arthur Hayes

January 9, 2025
1pbuw0 19otzzd4f1qvotaw.png

How To: Forecast Time Sequence Utilizing Lags | by Haden Pelletier | Jan, 2025

January 14, 2025

About Us

Welcome to News AI World, your go-to source for the latest in artificial intelligence news and developments. Our mission is to deliver comprehensive and insightful coverage of the rapidly evolving AI landscape, keeping you informed about breakthroughs, trends, and the transformative impact of AI technologies across industries.

Categories

  • Artificial Intelligence
  • ChatGPT
  • Crypto Coins
  • Data Science
  • Machine Learning

Recent Posts

  • IMF Flags $300T Tokenization Hole, Warns 24/7 Markets Might Amplify Market Dangers
  • Bridging Algorithmic Design and Regulatory Requirements in Enterprise AI
  • Your Mannequin’s MSE Is Mendacity to You III: Time Collection Diffusion
  • Home
  • About Us
  • Contact Us
  • Disclaimer
  • Privacy Policy

© 2024 Newsaiworld.com. All rights reserved.

No Result
View All Result
  • Home
  • Artificial Intelligence
  • ChatGPT
  • Data Science
  • Machine Learning
  • Crypto Coins
  • Contact Us

© 2024 Newsaiworld.com. All rights reserved.

Are you sure want to unlock this post?
Unlock left : 0
Are you sure want to cancel subscription?