

Whereas conversational AI and agentic AI are actually distinct foundational use instances of generative AI, shifting an agent from a proof-of-concept to a dependable, production-ready enterprise workflow requires it to qualify on the measures of scalability, responsiveness, and cost-effectiveness.
To know methods to obtain this, we first must ask: Why are brokers wanted within the first place? As a result of conversational perception from information is commonly not sufficient. LLMs have the potential to plan, motive, and act. And brokers are the logical constructs across the LLM “mind,” utilizing instruments, interacting with exterior APIs, correcting their very own errors, and collaborating with different brokers. Agentic techniques depend on many high-frequency choices to finish the workflow, resembling what the subsequent step ought to be, which agent to delegate the subsequent step, which instrument to make use of, whether or not we’ve sufficient context to answer the consumer, and many others. A serious evolution is the arrival of low-cost calibrated resolution fashions resembling TypeSafe’s JEV. which shifts the deterministic workload from LLMs, leaving them to focus purely on deep reasoning and synthesis.
Simply as retrieval advanced past flat semantic search into specialised, deterministic topologies (as explored in my practitioner’s information to superior GraphRAG patterns), the broader agentic panorama is equally shifting away from naive “single agent loops” towards closely engineered multi-agent workflows and constrained architectures. As a substitute of dwelling on the fundamentals, this text offers a practitioner’s deep dive into six distinct architectural patterns for constructing agentic techniques. We’ll discover how they work, visualize the info move, the very important position of Context Engineering in managing the LLM’s working reminiscence, and precisely when to make use of these patterns in manufacturing.
Core Elements
Earlier than diving into particular architectures, let’s outline the baseline elements of an agent. An AI agent consists of 4 pillars:
-
The Core LLM (The Reasoning Engine): The foundational mannequin (e.g., GPT-5, Claude 5.5 Sonnet, Llama-4) that orchestrates the logic. In agentic techniques, the mannequin’s potential to natively assist
Device Calling(or Operate Calling) is essential. -
Instruments/Actions: Executable features the agent can name, starting from API wrappers (e.g.,
search_web,query_database,send_email) to code interpreters that execute Python scripts in a sandbox. -
Planning & Management Movement: The mechanism by which the agent decides what to do subsequent. This may be inflexible (a state machine or directed acyclic graph) or fluid (an open-ended reasoning loop).
-
Reminiscence: The system’s potential to retain info throughout steps and interactions. This contains short-term working reminiscence (the lively immediate window) and long-term episodic reminiscence (vector shops of previous interactions).
The Hidden Success Criterion: Context Engineering
In agentic techniques, Context Engineering is a key criterion for manufacturing readiness. In contrast to conventional prompts the place context is static, an agent’s context is extremely dynamic. As an agent takes actions, it accumulates observations, errors, and intermediate ideas. If we append each statement to the immediate, the context window will simply bloat, resulting in elevated latency and exorbitant prices. Additionally, the LLM might lose visibility of granular info in the course of a really giant block of textual content within the context, resulting in incorrect or incomplete responses from downstream brokers.
Context Engineering in agentic techniques includes a number of strategies:
-
State Projection: Solely injecting the context strictly mandatory for the present step of the workflow. If an agent has moved on from researching to writing, the uncooked analysis logs ought to be faraway from the lively context.
-
Reminiscence Pruning & Summarization: Utilizing secondary LLM calls (usually smaller, cheaper fashions like GPT-mini) to compress previous steps (e.g., “Summarize the final 5 search outcomes into key info”) earlier than appending them to the lively immediate.
-
Structured Scratchpads: Prompting the LLM to jot down its intermediate reasoning into designated JSON fields or XML tags (e.g.,
I ought to verify the API docs -
Semantic Reminiscence Retrieval: Treating previous agent actions as a vector database. As a substitute of loading all the dialog historical past, the agent retrieves solely its previous actions which can be semantically related to the present impediment.
-
Immediate Caching: A brand new function supplied by mannequin suppliers resembling Anthropic and OpenAI. In complicated agentic techniques, the system immediate and power definitions can simply exceed 5,000 tokens. Nonetheless, these are static directions that don’t change in the course of the lifecycle of the system. By organizing the context window in order that such static system directions sit on the prime, suppliers can cache these precomputed consideration states right into a Key-Worth (KV) cache. When the agent loops 10 instances, we solely pay for the newly appended observations, which might drastically scale back LLM inference prices.
Human-in-the-Loop (HITL)
Enterprise functions can’t belief autonomous brokers to execute with out human supervision. LLMs are inherently non-deterministic. Subsequently, something that’s not a learn operation, may very well be doubtlessly undesirable or dangerous. Examples may very well be external-facing actions resembling dropping a SQL desk, authorizing a cost, or emailing a consumer. Human-in-the-Loop (HITL) is a management move mechanism the place the agent pauses its execution state and waits for a human reviewer.
For example, in a State Graph implementation (like LangGraph), invoking a selected instrument (e.g., send_email_tool) interrupts the graph. The state is serialized to a database, and execution halts. A human evaluations the drafted electronic mail in a UI, edits it if mandatory, and clicks “Approve.” The orchestrator then resumes the graph execution with the permitted state.
With these elements and context engineering rules in thoughts, allow us to have a look at the six agentic architectural patterns.
Sample 1: The Normal ReAct (Cause + Act) Loop
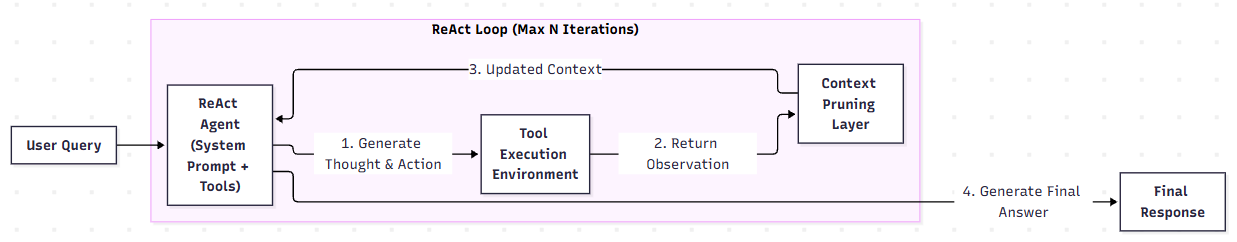
The ReAct (Cause + Act) sample is the foundational constructing block of agentic workflows. It makes the LLM alternate between “considering” (motive about what to do) then “appearing” (calling instruments and observing the outcome), then take into consideration the outcome and its relevance to the objective once more.
The way it Works
The agent is given a system immediate describing its persona, out there instruments, and the principles it ought to comply with. When a consumer offers a activity, the agent enters a whereas loop. In every iteration, it outputs a “Thought” explaining its logic, adopted by an “Motion” (a instrument name). The orchestration layer intercepts this motion, executes the instrument, and returns the “Remark” again to the LLM. The LLM then reassesses the state of affairs. This continues till the LLM decides it has sufficient info to output the “Last Response”.
Implementation Particulars and Knowledge Movement
A helpful Context Engineering facet right here is managing the “Agent Scratchpad”. Because the loop progresses, the immediate grows linearly: [System Prompt] + [User Query] + [Thought 1 + Action 1 + Obs 1] + [Thought 2 + Action 2 + Obs 2]...
To stop bloat, we are able to implement Remark Truncation. If a instrument returns a big HTML doc, the orchestration layer ought to truncate it or run a summarization script earlier than feeding it again to the agent. In any other case, a single net search might overwhelm the context window.
Execs and Cons
Execs:
-
Excessive Flexibility: It could actually deal with unpredictable duties as a result of the trail to the answer shouldn’t be hardcoded. It dynamically adapts primarily based on the observations it receives.
-
Error Restoration: If a instrument fails (e.g., a 404 error from an API), the statement feeds the error again to the LLM, which might “motive” its method round the issue (e.g., attempting a distinct URL, right the instrument parameters or falling again to a distinct instrument).
Cons:
-
Excessive Latency & Price: A single question may require 10 sequential LLM calls. Even with Immediate Caching, this takes time and consumes vital quantities of tokens.
-
Drift and Hallucination: For extremely complicated duties, the agent may overlook its authentic objective, coming into a sequence of irrelevant instrument calls or looping endlessly on a damaged instrument.
When to Use It
ReAct is greatest suited to open-ended, research-oriented duties the place the precise sequence of steps can’t be recognized prematurely. It’s nice for information evaluation, deep-dive net analysis, or debugging code in an remoted sandbox. It’s typically not beneficial for deterministic, low-latency, user-facing chat functions the place customers anticipate exact replies shortly.
Sample 2: The Sequential Multi-Agent Workflow
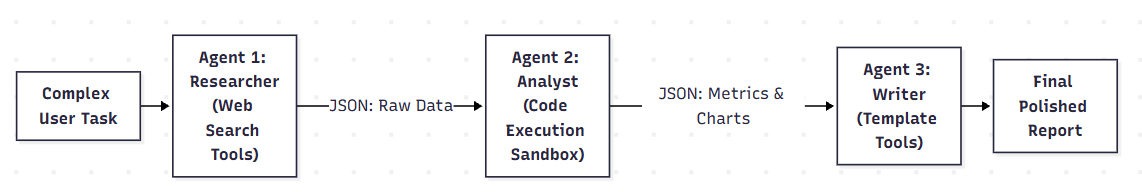
When a activity is simply too complicated for a single ReAct agent to deal with reliably, we should break it down. The Sequential Multi-Agent Workflow is sort of a manufacturing facility meeting line. As a substitute of 1 tremendous agent attempting to do all the pieces directly, we chain collectively extremely specialised brokers, passing the output of 1 because the structured enter to the subsequent.
The way it Works
Every agent within the sequence has a centered persona, a restricted set of instruments, and a really particular Context Window. For example:
-
The Researcher: Gathers uncooked information utilizing search instruments and scrapes net pages. It compiles a uncooked file.
-
The Analyst: Receives the file, processes the info, performs numerical calculations (usually by writing Python code), and extracts key metrics.
-
The Author: Takes the Analyst’s metrics and codecs them right into a ultimate, client-ready report.
Implementation Particulars and Knowledge Movement
This structure demonstrates Context Engineering by way of State Projection. The Author Agent does not have to see the 50 net pages the Researcher scraped, nor the 4 makes an attempt it took the Analyst to jot down a working Python script. The Author solely receives the finalized analytical temporary. This isolates the context home windows, outcome being that we forestall the “Misplaced within the Center” downside and considerably scale back token utilization.
That is carried out utilizing State Graphs (like LangGraph), passing a strict State object between nodes.
Execs and Cons
Execs:
-
Excessive Reliability: As in comparison with ReAct, specialised prompts yield considerably increased high quality outcomes than generic “do all the pieces” prompts. We will tune temperature and mannequin sizes individually (e.g., low cost mannequin for researching, costly mannequin for evaluation).
-
Token Effectivity: Context home windows are stored small and extremely related at every step.
-
Simple Debugging & Checkpointing: We will decide precisely which agent within the chain failed, and save the state after every node to renew later.
Cons:
-
Strict Linearity: It’s tough to deal with eventualities the place the Author realizes the Researcher missed one thing vital and must ship the workflow backward. Whereas cycles may be added to state graphs, they complicate the structure and danger infinite loops.
When to Use It
Use sequential workflows for well-defined, multi-stage pipelines: content material technology, information processing pipelines, ETL duties, or any workflow that mimics a standard human meeting line (e.g., Drafting -> Enhancing -> Formatting -> Publishing).
Sample 3: The Adaptive Router Agent
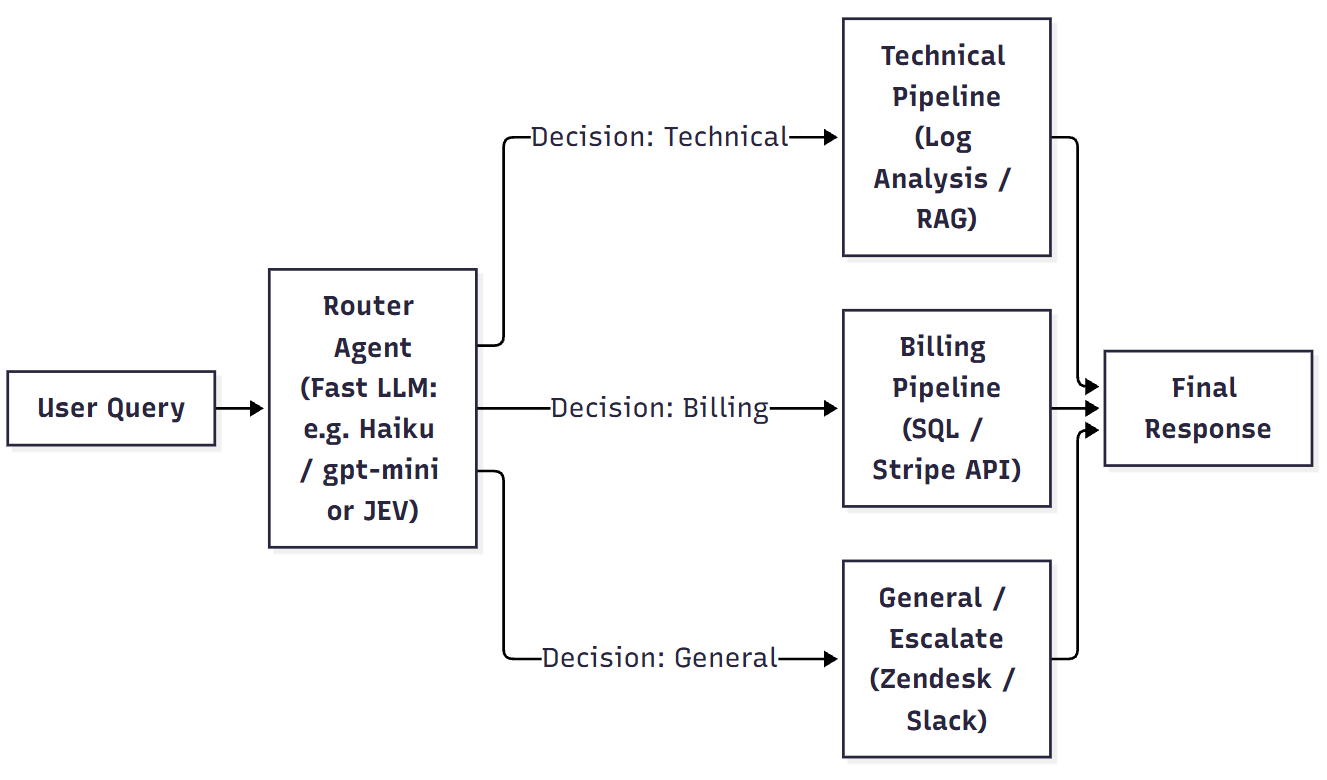
Not each question may be answered satisfactorily utilizing a linear, Sequential workflow. The Adaptive Router sample treats the agentic system not as an open-ended downside solver, however as an clever triage system. It analyzes the consumer’s intent and routes the execution to a sub-pipeline, specialised for the recognized question intent.
The way it Works
The Router Agent is often a quick, calibrated LLM (like GPT-mini or Claude Haiku) or a non autoregressive JEV mannequin. It’s introduced with a consumer question and an inventory of accessible pipelines (e.g., technical_support, billing_inquiry, general_escalation). Its solely job is to carry out intent classification and entity extraction, outputting a structured JSON resolution. As soon as the choice is made, the router’s job is finished, and conventional deterministic code takes over. It is usually attainable {that a} question has a combined intent; technical in addition to billing, wherein case, a number of pipelines are executed in parallel and the outputs mixed within the synthesizer step for ultimate response.
Composite Architectures: The downstream pipelines do not must be easy deterministic code or fundamental RAG scripts. For instance, if it routes to the Technical Pipeline, that pipeline may really be a totally unbiased Sample 2 (Sequential Workflow) containing a Researcher Agent and a Python Coder Agent. In enterprise implementations, the Router acts because the “entrance door” to a full agentic automation workflow spanning grasp information, transactional and analytics functions.
Implementation Particulars and Knowledge Movement
Context Engineering right here focuses on Immediate Compression. Because the router have to be very quick, the system immediate mustn’t include the total directions for each downstream pipeline. It ought to solely include the metadata, descriptions, and few-shot examples essential to make the routing resolution.
Execs and Cons
Execs:
-
Low Latency router: Just one quick router name is required earlier than deterministic execution begins.
-
Predictability & Security: The downstream pipelines are bounded in scope, it’s a lot simpler to check, monitor, and assure efficiency.
-
Price Effectivity: We will use micro-LLMs or non-autoregressive fashions for the routing step, making it price efficient.
Cons:
-
Dealing with Combined Queries: Actual-world consumer questions are often “combined” (e.g., “Why did my bank card fail, and the way do I restart the server?”). Whereas modifying the schema to return an inventory of pipelines (as proven above) helps, combining disjointed responses from a number of pipelines can really feel robotic (like billng response appended under the technical response and never addressing the question holistically). For extremely complicated overlapping duties, a Supervisor sample mentioned within the subsequent part is best.
-
Single Level of Failure: If the router misinterprets the intent, all the downstream execution is distributed to the mistaken system and could be very prone to fail.
When to Use It
The Router is the usual for contemporary multi-tenant enterprise chatbots and customer support automation. It ought to be used when the classes of consumer requests are recognized nicely sufficient that they are often resolved utilizing a set of inside instruments or workflows, that are largely unbiased of one another. For example, a contact middle bot for resolving technical or billing queries. Or an enterprise chatbot for a number of departments.
Sample 4: The Supervisor-Employee (Hierarchical) Structure
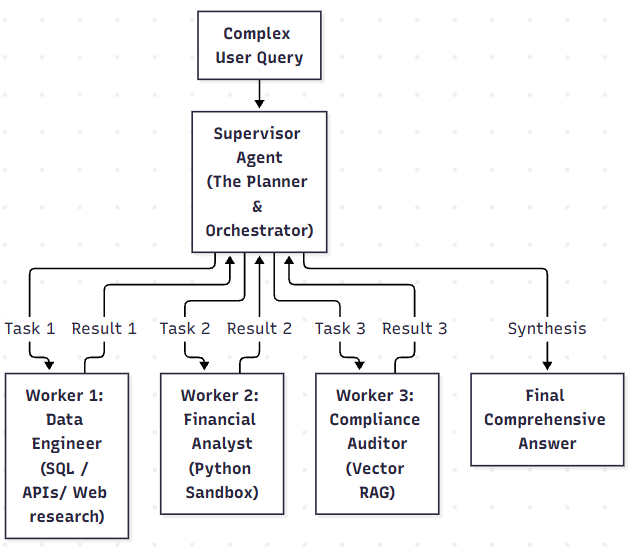
Whereas the Sequential and the Adaptive Router patterns are straight line(s), the Supervisor-Employee sample is a dynamic tree. It introduces a central “Supervisor” agent that dynamically plans the workflow, delegates sub-tasks to specialised employee brokers in parallel, and synthesizes the ultimate outcomes.
The way it Works
The consumer submits a posh, multi-faceted question. The Supervisor Agent analyzes it and breaks it into an execution plan containing sub-tasks. It then dispatches these sub-tasks to the suitable specialised Employee Brokers. These employees execute their duties, doubtlessly utilizing their very own inside ReAct loops, and report again to the Supervisor. The Supervisor evaluations the compiled work. If the info is incomplete, it points new directions to the employees. If full, it synthesizes the ultimate response.
Implementation Particulars and Knowledge Movement
Context Engineering on this sample is sort of complicated. The Supervisor should keep a World Context (the overarching plan, the state of the duty ledger, and the finalized summaries from the employees), whereas the Staff solely obtain Native Context (their particular remoted sub-task).
A greatest apply method right here is using a Activity Ledger within the Supervisor’s immediate. This ledger acts as a dynamic guidelines that’s up to date as employees full their jobs.
A degree to notice above is how the execute() strategies for the employees are solely handed activity.description. They do not obtain the overarching user_query or all the contents of the results_ledger. The Employee thread is closed on the finish of its execution, with any amassed native historical past deleted. Solely the result’s handed to the Supervisor. The Supervisor interprets the worldwide objective right into a slim, remoted instruction (e.g., “Extract Q3 income from the SQL database”). Or if the instruction requires earlier context, the Supervisor is clever sufficient to incorporate that whereas framing the brand new instruction (e.g. “You beforehand reported that the drug causes nausea and complications. Carry out a brand new deep-dive net search particularly in search of extreme, long-term opposed results past simply these gentle signs.”)
Execs and Cons
Execs:
-
Parallel Execution: As a result of sub-tasks are delegated concurrently, the general latency is decreased in comparison with sequential single-agent execution.
-
Excessive Scalability: We will simply add new specialised employee brokers to the group (e.g., an
Image_Generator_Worker) with out rewriting the Supervisor’s core logic. -
Divide and Conquer: It’s good at fixing composite queries that span a number of, unconnected domains.
Cons:
-
Excessive Complexity and Orchestration Overhead: Managing asynchronous calls, state reconciliation, and timeouts is a posh engineering activity. The Supervisor immediate must be elaborate and examined nicely sufficient to have the ability to deal with totally different eventualities utilizing a robust reasoning mannequin.
-
Single Level of Failure: The system is fully depending on the Supervisor’s intelligence. If the Supervisor creates a poor plan or misinterprets the consumer’s intent, all the system fails, no matter how succesful the person employees are.
When to Use It
This structure is customary for complicated chatbots, resembling enterprise analysis, complete monetary evaluation, multi-modal content material technology, or coding duties the place a composite reply have to be derived from a number of disjointed information sources concurrently.
Sample 5: The Reflection and Self-Correction Loop
LLMs are probabilistic engines. They make errors. They write buggy code, hallucinate info, and often misread the uncooked JSON outputs of their very own instruments. The Reflection sample intends to catch and proper the failings earlier than it reaches the consumer. It depends on self-critique, automated testing, and iterative self-correction to enhance the ultimate output.
The way it Works
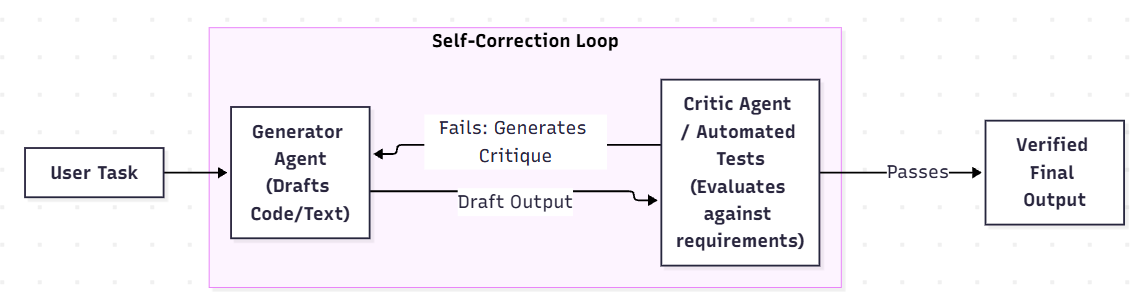
Structurally, this sample is actually a Sequential Workflow (Sample 2) with a suggestions loop. As a substitute of chaining fully totally different useful roles to maneuver a activity ahead, it sometimes includes two brokers devoted to the very same output (e.g., Coder ↔ Code Reviewer) till it reaches a suitable degree of high quality.
An agent (the Generator) produces an preliminary output (e.g., a Python script, a SQL question, or a authorized abstract). This output is then handed to an analysis layer. This layer generally is a second LLM (the Critic) appearing as a reviewer, or a deterministic automated take a look at (like a Python compiler, a SQL dry-run, or a factual consistency checker). The Critic evaluates the output towards the unique directions and generates a strict record of flaws. This critique is fed again into the Generator’s context window as an instruction to revise the output. This loop continues till the Critic approves the output or a most iteration restrict (e.g., 3 makes an attempt) is reached.
Implementation Particulars and Knowledge Movement
Context Engineering right here revolves round managing the errors which will creep right into a LLM output. If the agent fails 5 instances, and we append each failure, the immediate will include 5 units of failed drafts and critiques. This huge historical past confuses the LLM, inflicting it to hallucinate and often revert to earlier, damaged variations of the output.
An important greatest apply is Context Pruning by way of Diffing: As a substitute of passing all the historical past, the orchestration layer actively prunes the context. It passes solely the authentic activity, the newest failed draft, and the newest critique.
Execs and Cons
Execs:
-
Increased High quality: Iterative critique considerably improves logical coherence and factual accuracy in comparison with zero-shot technology.
-
Automated QA: It prevents the system from confidently returning flawed, non-compliant, or hallucinated outcomes to the consumer.
Cons:
-
Excessive Latency & Price: Producing, critiquing, and rewriting content material a number of instances inherently requires ready and consumes additional tokens.
-
Degradation Loops: Often, a Critic will hallucinate a flaw, forcing the Generator to spoil completely good work in a downward spiral.
When to Use It
Reflection loops are necessary for autonomous software program engineering (e.g., Agentic coding assistants/vibe coders), automated information science, and high-stakes content material drafting.
Nonetheless, Strategic Reflection is the trade greatest apply:
-
In Sample 2 (Sequential): Do not use LLM critics on each node (too gradual/costly). Use quick, deterministic checks (like JSON validation) for intermediate steps, and reserve LLM Reflection for the ultimate, high-stakes output.
-
In Sample 4 (Supervisor): Devoted LLM critics are not often wanted. The Supervisor naturally acts because the critic when evaluating a employee’s output.
Sample 6: The Autonomous Swarm (Decentralized Community)
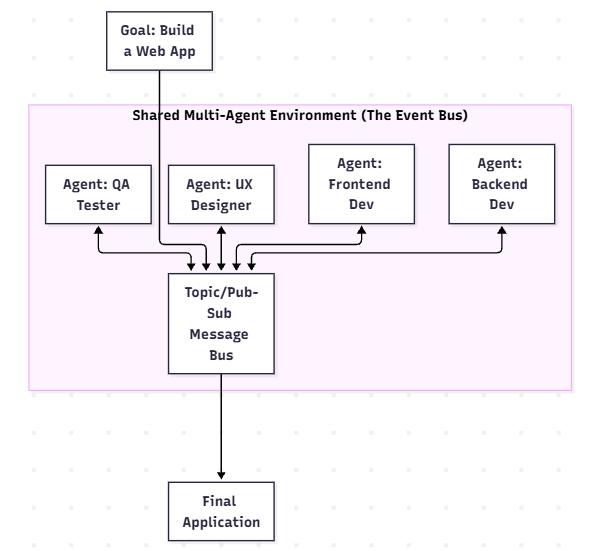
Probably the most superior, experimental, and chaotic sample is the Autonomous Swarm. In contrast to the Supervisor-Employee mannequin, which depends on a strict, top-down hierarchy and inflexible planning, a Swarm consists of a number of extremely specialised brokers present in a shared surroundings. They collaborate, negotiate, and execute instruments with out a central supervisor dictating their each transfer.
The way it Works
Brokers in a Swarm are outlined by their particular capabilities (their instruments), their persona, and their communication protocols. They’re given a high-level objective and positioned in a shared context (like a bunch chat, a shared digital file system, or a simulated world). When an issue arises or a message is broadcast, any agent able to contributing can “step up.” Brokers can ask one another questions, hand off duties, debate options dynamically, and execute instruments within the shared house.
Implementation Particulars and Knowledge Movement
Context Engineering in a Swarm is tough. A naive implementation locations each agent in a large shared chat room. If there are 5 brokers, they usually debate for 20 turns, appending each message to each agent’s immediate leads to huge token bloat and overwhelming context limits inside minutes.
Superior implementations (usually constructed utilizing frameworks like Microsoft AutoGen) make the most of Matter-Primarily based Pub/Sub Context. Brokers don’t learn all the chat historical past. They solely subscribe to messages tagged with related matters. Moreover, brokers talk by way of Structured Protocols (e.g., sending strict JSON payloads containing code blocks or API parameters to 1 one other) somewhat than utilizing unstructured conversational prose.
Execs and Cons
Execs:
-
Emergent Downside Fixing: The swarm can brainstorm organically and route round sudden obstacles that will break inflexible pipelines. An instance may very well be to show a tough mathematical theorem whose answer shouldn’t be recognized.
-
Modular Scalability: Including new capabilities is so simple as dropping a brand new agent into the shared surroundings.
Cons:
-
Unpredictability: Execution paths are non-deterministic, making debugging and enterprise compliance a problem. There is no such thing as a assure {that a} passable answer could be reached in a finite variety of iterations.
-
Infinite Chat Loops: With out strict orchestration and turn-taking guidelines, brokers can get caught in infinite conversational loops; both debating endlessly or just acknowledging one another with out making progress.
When to Use It
Swarms excel in open-ended analysis, artistic sandboxes, and simulation environments. Nonetheless, for strict enterprise automation, one ought to nearly all the time want the steadiness and predictability of Sequential or Supervisor patterns.
Evaluating Agentic Techniques
In customary RAG, frameworks like RAGAS use metrics like Context Precision and Faithfulness to guage a single output. Brokers, nonetheless, take a number of steps. If the ultimate reply is mistaken, we should work out why: Did the agent select the mistaken instrument? Did it hallucinate the instrument arguments? Did it ignore the instrument’s output? Or did it simply synthesize the ultimate reply poorly?
We consider brokers utilizing Trajectory Evaluation:
-
Device Choice Accuracy: Utilizing LLM-as-a-judge, consider if the agent selected the optimum instrument for the given state.
-
Schema Compliance: Monitoring how usually the agent generates invalid JSON or lacking arguments for a instrument name.
-
Iteration Depend: Monitoring the typical variety of steps it takes an agent to succeed in a conclusion. A sudden spike in iterations might recommend the agent is fighting a brand new instrument or getting caught in loops.
Logging each thought, motion, and statement to observability platforms like LangSmith or Arize Phoenix is the usual for debugging agent trajectories in manufacturing.
Challenges and Finest Practices for Implementation
Following greatest practices helps to improve an agent from a sandbox prototype to manufacturing:
-
Mitigating Infinite Loops
Brokers often get caught calling the identical failing instrument repeatedly. To stop this, implement strict circuit breakers. Hardcode a
max_iterationscap and use Context Engineering to inject aggressive warnings (e.g., “SYSTEM ALERT: You failed 3 instances. Use a distinct technique.”) if similar consecutive instrument calls are detected -
Brittle Device Parsing
A hallucinated JSON parameter can crash all the pipeline. Use strict structured pydantic outputs to ensure schema compliance. Wrap all instrument executions in
attempt/besidesblocks, and return parsing errors instantly again to the agent as a string statement so it might self-correct. -
Price Administration
Working each node in a multi-agent workflow on a frontier mannequin (like GPT-5) is financially unsustainable. Implement Adaptive Mannequin Routing (as explored in Optimizing LLM Inference Prices). Use low cost, quick fashions (Haiku, mini, or JEV) for routing and routine information extraction. Reserve frontier fashions for Supervisor planning, Reflection analysis, and ultimate output synthesis.
Conclusion
Agentic techniques characterize a basic shift in software program structure. We’re shifting away from writing express step-by-step deterministic code and towards orchestrating networks of probabilistic, clever entities.
The selection of structure is essential and dictates the success or failure of the product. If we want pace, low price, and predictability, use the Adaptive Router. If we’ve a transparent, multi-stage information course of, depend on the Sequential Workflow. And if we’re constructing a extremely autonomous software program engineer or information analyst, we should make investments the time to implement Reflection Loops and a Supervisor Hierarchy.
The key sauce on this new paradigm lies not simply in choosing the proper foundational mannequin, however in mastering Context Engineering, which is meticulously managing what the brokers see, keep in mind, and overlook. By combining strict architectural patterns with context pruning, practitioners can construct techniques that do not simply reply questions, however autonomously and reliably resolve issues in the true world.
Additional Studying
Join with me and share your feedback at www.linkedin.com/in/partha-sarkar-lets-talk-AI
Photographs used on this article are generated utilizing Google Gemini. Code developed by me.