I’m very forgiving of an agent that’s solely speaking. If it will get a draft or abstract incorrect, I crash out at my display and ask once more, and since nothing exterior the chat window has modified, a retry is all it prices me.
However the temper adjustments as soon as the agent will get a device. A incorrect reply can now imply a despatched electronic mail or a moved fee, and the same old repair, which is placing a second mannequin in entrance to test the primary, begins to really feel like hiring an intern to oversee an intern.
One of many easiest guardrail circumstances I wrote down was additionally the one which bothered me most.
A buyer will get charged twice for a $12 buy and asks an AI agent for a refund. The agent picks the best device and the best buyer, then prepares this:
Nothing in that decision seems to be damaged. The client ID is legitimate, amount_cents is an integer, and the refund device’s schema accepts it.
The 2 duplicate prices on the account, ch_1 and ch_2, had been 1,200 cents every, so the quantity is off by an element of 100, which is what changing {dollars} to cents twice seems to be like.
I’m not actually apprehensive concerning the dramatic failure the place a mannequin fully loses the plot.
The failures that hassle me probably the most are the abnormal ones, the place the motion seems to be affordable, and the error solely turns into apparent after one thing actual has occurred.
My first response to this one was: straightforward. Put a tough $500 refund restrict in entrance of the device and transfer on.
Then I modified the dangerous quantity from $1,200 to $120. That sits beneath the cap, so the restrict I had simply reached for by no means fires, and the client nonetheless will get ten occasions what they accredited.
That small change is what pulled me into TypeSafe AI’s Jev mannequin.
TypeSafe launched Jev on September 15 as the primary of what it calls System One Fashions, a category of fashions constructed to make quick, structured selections that software program can use immediately.
It’s nonetheless in early entry, for what that’s price. As an alternative of producing one other paragraph, Jev takes software state and a bounded query, then returns a typed probabilistic reply.
TypeSafe’s launch submit frames this as a unique job from a traditional chat mannequin: much less technology, extra decision-making. Guardrails for LLM inputs and outputs are on its record of supposed makes use of, which is adjoining to what I would like right here.
Jev has really been out for just a few weeks now, which in AI time makes it virtually classic, so sure, I’m a little bit late to this. A part of that’s right down to a benchmark I attempted to get working and by no means fairly managed, which I’ll get to in a second.
I had deliberate a small benchmark with dozens of artificial device calls, however I by no means received a clear run via the gateway I had entry to, and I actually didn’t need to move off half-working experiments as exact numbers.
What’s left is the half I discovered extra attention-grabbing anyway: the place a mannequin like Jev ought to sit in an agent system, and what it shouldn’t be trusted to determine.
The bug is usually semantic, not structural
Schema validation already handles a helpful class of failures. If send_email() expects a recipient record and an attachment, I can make certain each fields exist. If issue_refund() expects an integer variety of cents, I can reject a foul worth earlier than it even will get close to the fee service.
It doesn’t catch this:
The person solely requested to ship the bill to Alice. Each addresses could be actual, the attachment can exist, and the schema passes with out grievance.
Every thing checks out besides whether or not that is what the person really requested for.
A JSON schema can’t remedy that, and I additionally are not looking for one other big immediate whose job is to clarify, in 600 tokens, why a refund is likely to be suspicious.
At execution time, the appliance largely wants a choice it may route on, and that’s the place Jev begins to look much less like one other mannequin and extra like a guardrail element.
My first sketch gave Jev an excessive amount of energy
My first model was embarrassingly clear: the agent proposes an motion, Jev says enable, evaluation, or block, and that’s it. It seemed good in a diagram, and truthfully I disliked it nearly instantly.
If Jev decides whether or not to authorize a refund, I’ve simply moved a permissions downside into one other probabilistic mannequin, which is not a lot of a security structure.
So I flipped the order. Arduous guidelines go first, and Jev solely sees the messy circumstances that stay.
If refunds above $500 all the time want a human, I don’t want a mannequin’s opinion on them.
The identical goes for guidelines like “manufacturing backups can’t be deleted autonomously” or “this agent can’t entry payroll information.” These belong in code or permissions.
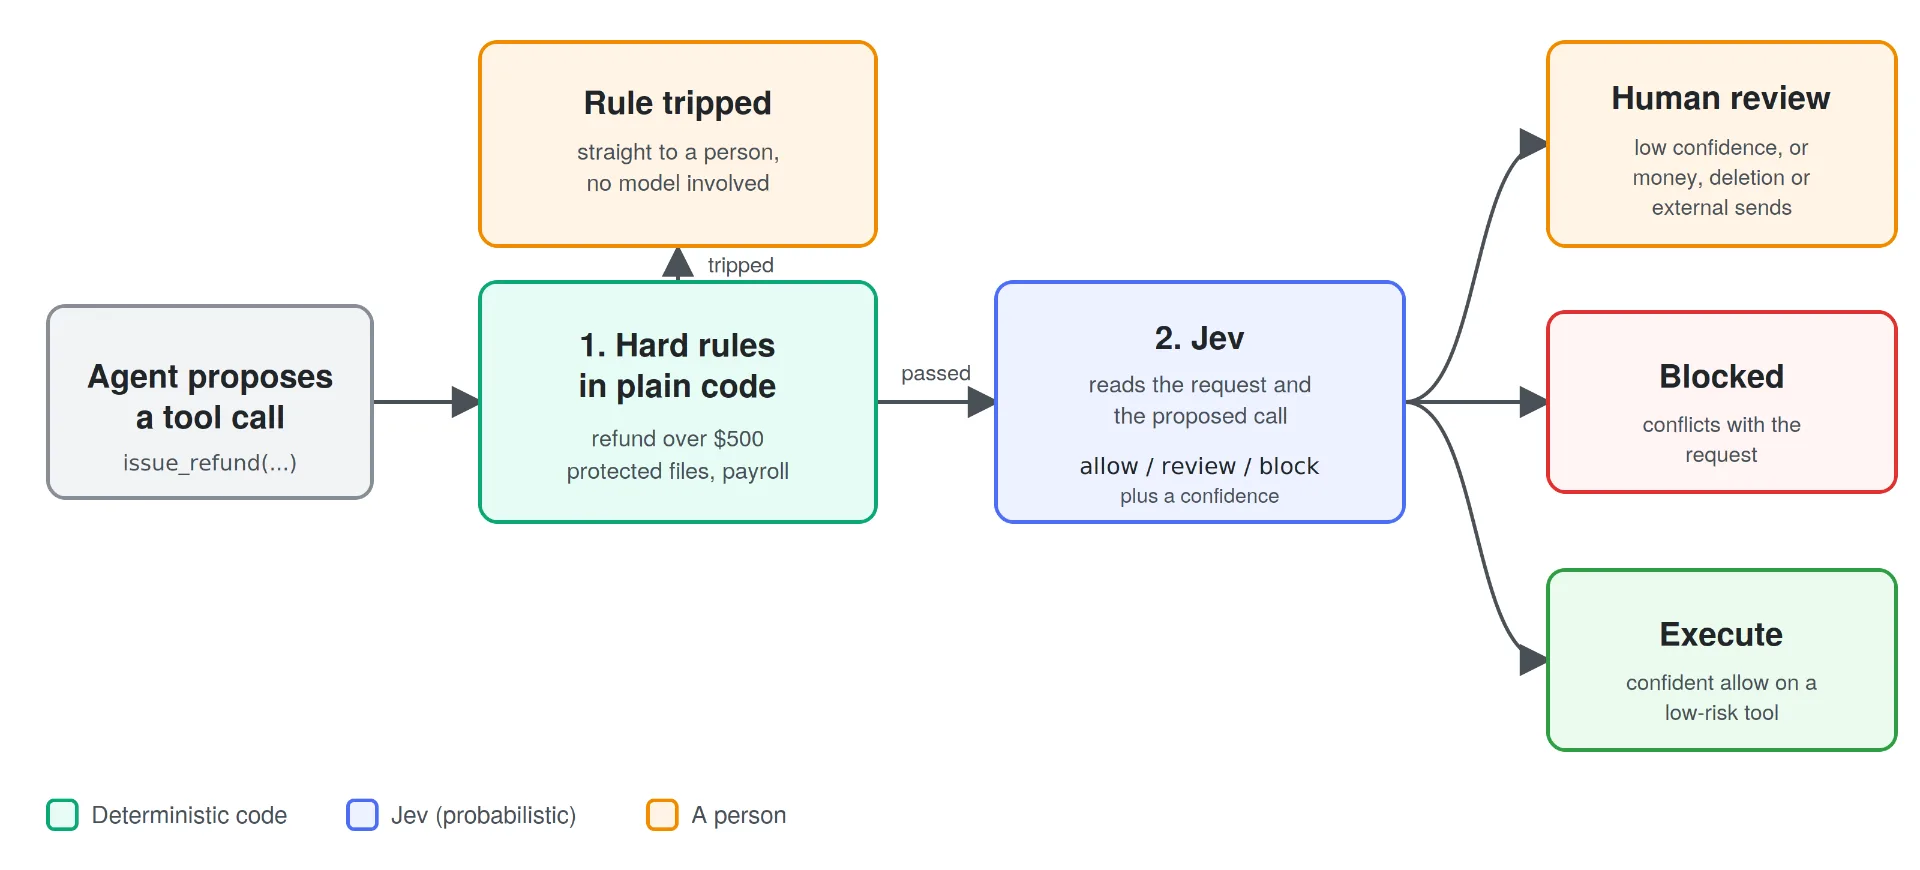
A left-to-right flowchart in three colours. On the left, an agent proposes a device name, which first meets a inexperienced field labeled “Arduous guidelines in plain code,” protecting issues like refunds over $500 and guarded information. If a rule journeys, an arrow goes as much as an amber field labeled “Rule tripped,” which sends the decision straight to an individual with no mannequin concerned. If the decision passes, it goes to a blue field labeled “Jev,” which reads the request and the proposed name and returns enable, evaluation or block with a confidence. Three arrows go away Jev. The primary goes to an amber “Human evaluation” field, for low confidence or for cash, deletion and exterior sends. The second goes to a pink “Blocked” field, for calls that battle with the request. The third goes to a inexperienced “Execute” field, for a assured enable on a low-risk device. A legend on the backside marks inexperienced as deterministic code, blue as Jev (probabilistic), and amber as an individual.
The semantic layer comes after that. A tough integration with the official Python SDK might appear like this, and I might deal with it as a sketch relatively than examined code:
The 0.90 is a beginning assumption, not a quantity I might ship as a result of it seemed good in an article. What issues is the division of duty.
The appliance owns the arduous boundary, Jev handles the fuzzy judgment inside it, and a low-confidence choice falls again to an individual as a substitute of pretending uncertainty is autonomy.
For refunds, I might nonetheless deal with even a assured enable as a suggestion at first, which is the place the tool-specific guidelines additional down are available in.
One caveat alone sketch. TypeSafe’s docs advocate small, single-purpose questions mixed in code over one broad judgment, and a three-way Alternative that folds the entire coverage into the state is nearer to the broad type.
A tighter model would ask separate sure/no questions, comparable to whether or not the quantity matches what the client accredited and whether or not the client matches the request, and let abnormal code flip these solutions into enable, evaluation, or block. I stored the one query right here as a result of it’s simpler to learn.
That ordering will not be my invention. TypeSafe has a group playground with a tool-router instance constructed the identical means: a plain key phrase rule blocks dangerous requests earlier than any mannequin is known as, and something delicate nonetheless wants express approval.
It’s a mock that routes between graph nodes relatively than judging device arguments, however the order is the purpose.
The clearest line I discovered on this comes from the group kedi-typesafe LangChain integration, which says a optimistic Jev evaluation ought to by no means substitute your personal device approval or coverage checks. That was most likely probably the most helpful factor I learn whereas working via this.
The boring edge circumstances are those I care about
A guardrail that blocks “ship our personal API key to an unknown electronic mail handle” is beneficial, but it surely doesn’t inform me a lot. I care concerning the circumstances that look affordable for the primary two seconds.
Take this request:
Let the suppliers know the Q3 invoices are prepared.
The agent prepares one electronic mail to 214 exterior contacts. The device is true and the motion broadly matches the request, however I might not let it hearth mechanically.
The blast radius modified the choice, which is why I might keep away from one common protected=True query for each device. A documentation search and a mass exterior electronic mail aren’t the identical type of danger, even when each are legitimate actions.
One other one:
Delete the exported CSV after confirming the add succeeded.
The agent factors delete_file() on the appropriate CSV, however nothing within the state reveals the add ever succeeded. The goal is okay. The lacking prerequisite is the issue.
And another:
Ship the pricing sheet to our accredited associate.
The associate electronic mail is appropriate, and the attachment is:
A recipient allow-list is not going to prevent there, and neither will checking the file extension. The guardrail wants sufficient context to see that this explicit file doesn’t belong on this motion.
That’s the type of choice I might give Jev: does this proposed motion nonetheless make sense subsequent to what the person really requested for?
Why not simply use one other LLM?
You possibly can, and I don’t assume Jev makes that sample out of date. A robust LLM can examine a proposed motion, cause concerning the coverage, and return a structured choice.
If that infrastructure already exists and the latency is suitable, I might not rewrite a working security layer simply because a brand new mannequin launched.
The narrower mannequin is interesting for a sensible cause. The appliance doesn’t want a mini essay each time an agent needs to learn a file. It wants enable, evaluation or block, plus sufficient chance data to determine whether or not to belief the route.
TypeSafe’s present API exposes three choice primitives: Alternative, Noul (a sure/no chance) and Rating. The official Python SDK returns typed views for them relatively than making you parse generated prose. The SDK quickstart is refreshingly small.
There may be additionally a sensible techniques argument.
The agent already depends on a generative mannequin to plan and decide a device, so placing a second massive mannequin in entrance of each execution means one other immediate to take care of, one other latency hop, and one other place for output dealing with to go incorrect. Jev simply does much less, and for this job which may really be a bonus.
I almost made the arrogance threshold look smarter than it’s
At one level my instance had one clear quantity:
Then I pictured the identical threshold guarding each search_docs() and issue_refund() and deleted it. If a documentation search is incorrect, the agent can recuperate. If a refund is incorrect, cash strikes. If a mass electronic mail is incorrect, the recall button is usually ornamental.
I might begin with tool-specific guidelines and hold them conservative. That is pseudocode, not a whole integration:
Then I might log what Jev needed to do subsequent to what the human finally selected, and solely calm down something after sufficient actual visitors. “Make the agent extra autonomous” will not be mechanically an enchancment right here.
I might relatively be irritated by just a few additional evaluation requests within the first month than discover out what the error charge means with an actual buyer connected.
Typed output will not be the identical factor as being proper
TypeSafe talks about Jev avoiding hallucinations as a result of the output area is outlined prematurely, and I might phrase that declare fastidiously. And structurally I get the argument. I imply, if the one choices are enable, evaluation and block, the mannequin can’t invent a fourth route known as refund_and_email_everyone, and this system is aware of the attainable outputs earlier than inference.
TypeSafe is upfront about what that assure covers: its launch submit says the 0% type-error determine in its charts will not be an empirical measurement, as a result of schema matching is assured by development.
That solely covers the form of the output. The mannequin can nonetheless decide enable when the best reply is block, and that may be a dangerous choice relatively than a damaged output.
Typed output removes one type of failure. It doesn’t take away mannequin error, lacking context, weak insurance policies, or dangerous software design. The mannequin will get a vote, not the keys to the constructing.
···
Last ideas and takeaways
I began by asking whether or not Jev might make brokers safer with out placing one other LLM in entrance of each device name. I feel the reply is sure, if “safer” means one thing pretty particular.
Jev seems to be helpful within the hole between “the agent needs to do that” and “the appliance is about to let it occur.” That may be a slender function, and I see that as a energy.
I might nonetheless hold arduous limits on cash, deletion, secrets and techniques, and permissions, with an individual concerned wherever a mistake is dear.
What I might hand to Jev is the half that’s arduous to put in writing as an if assertion.
Does the motion nonetheless match the request?
Did the agent quietly widen the scope?
Is a situation lacking?
The $12 refund is mundane, which is why I prefer it. If a small choice layer offers the appliance another likelihood to catch that earlier than cash strikes, a file disappears, or an electronic mail reaches 214 individuals, that’s sufficient for me to take the concept critically.
I don’t want Jev to be one other mind within the agent. I might relatively have it’s a really choosy gate.