On this article, you’ll be taught the mechanical distinction between retrieval-augmented era and fine-tuning, when every method is the fitting device, and the way to resolve which one, or each, your manufacturing system really wants.
Subjects we’ll cowl embody:
- What RAG and fine-tuning every do at a mechanical stage, and what each can not do.
- Two full, working code examples — one RAG pipeline for a knowledge-retrieval use case, and one LoRA fine-tuning setup for a structured-output use case.
- A concrete six-point resolution framework for selecting between RAG, fine-tuning, or each.
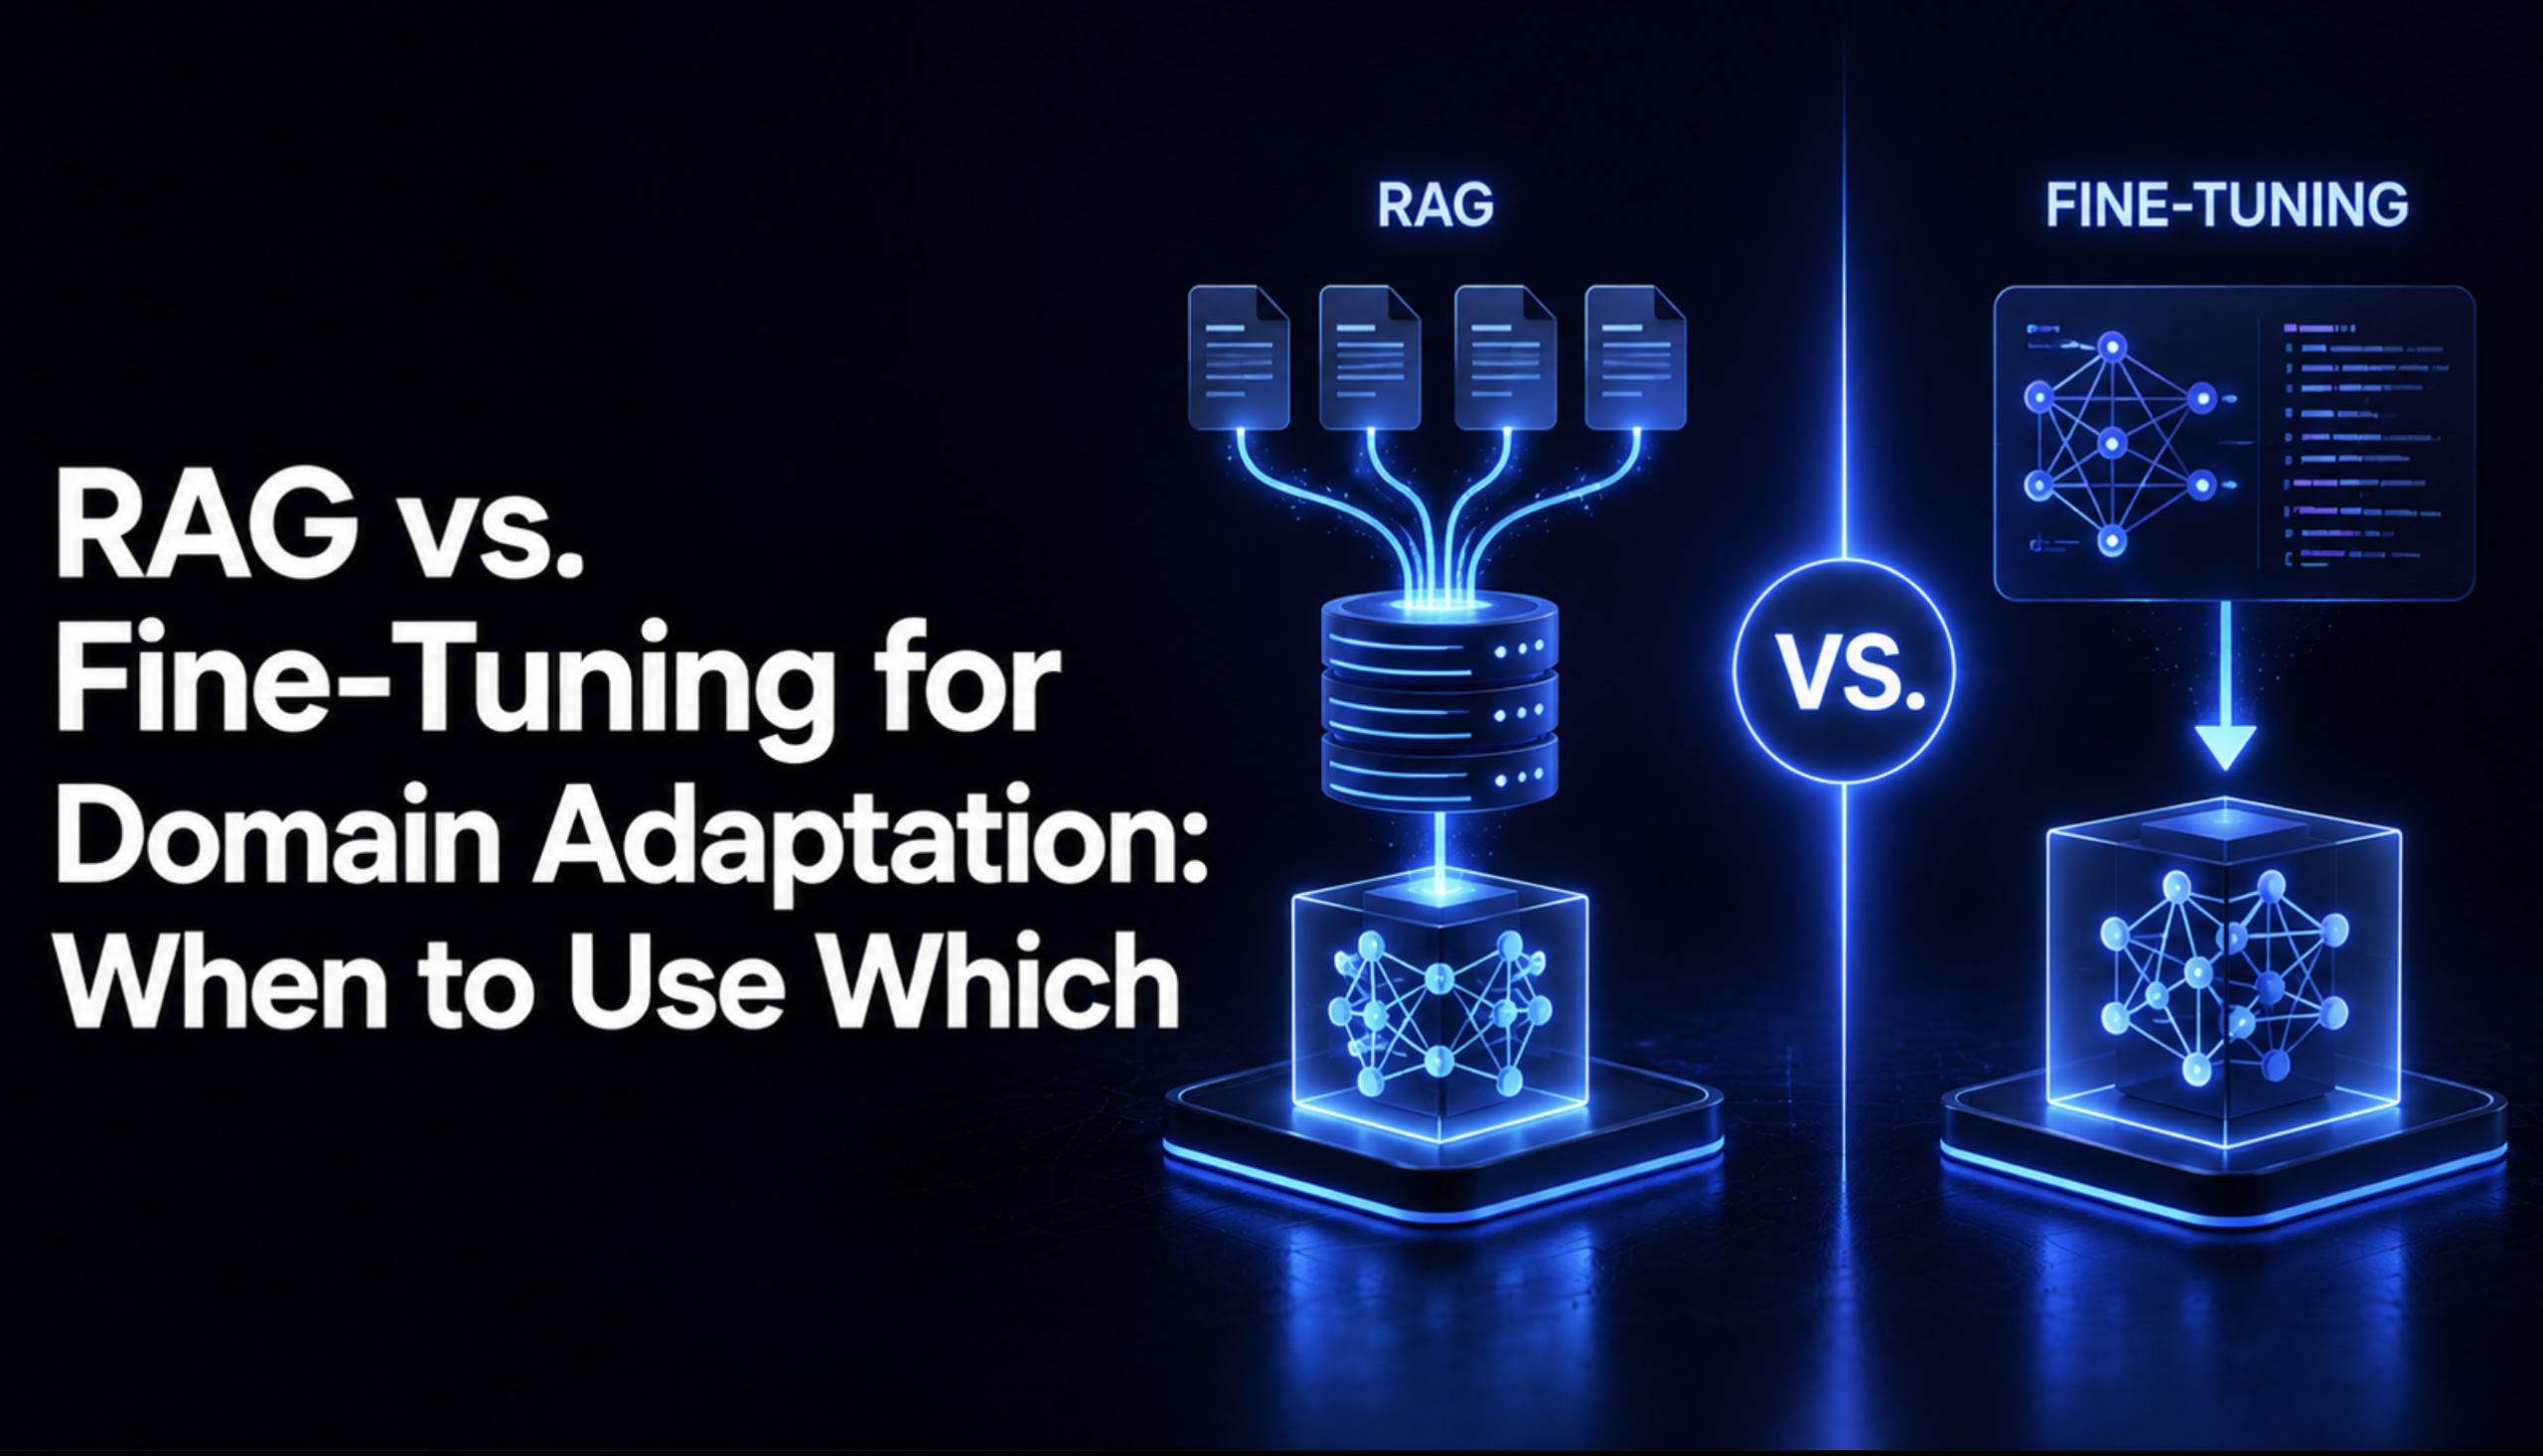
RAG vs fine-tuning is among the most searched, most argued-about tradeoffs in utilized LLM work proper now, and a lot of the debate occurs on the unsuitable stage of abstraction. It will get framed as a single both/or resolution, when the trustworthy 2026 image is that roughly 60% of manufacturing LLM deployments now use each collectively, not as a result of groups couldn’t resolve, however as a result of retrieval-augmented era and fine-tuning resolve two genuinely completely different issues, and most actual domain-adaptation tasks have each issues without delay.
This text breaks that false binary down correctly: what every method really does at a mechanical stage, two full, working, actual examples — one for every strategy — after which a concrete resolution framework for determining which one your particular mission really wants, and when the trustworthy reply is each.
What RAG Truly Is (and Isn’t)
Retrieval-augmented era doesn’t contact the mannequin in any respect. The mannequin’s weights by no means change; what adjustments is what the mannequin sees in its context window for the time being it’s requested a query. A retrieval step searches a data base, pulls again essentially the most related paperwork, and palms them to the mannequin alongside the consumer’s question, so the mannequin is answering with a briefing doc in entrance of it relatively than from reminiscence alone.
That mechanism is what makes RAG genuinely good at precisely one class of downside: data that’s massive, that adjustments, or each. What RAG doesn’t repair is a mannequin’s underlying habits. If the mannequin’s tone is inconsistent, if it received’t reliably observe a strict output format, if it makes use of your trade’s vocabulary incorrectly, feeding it extra paperwork at inference time doesn’t contact any of that, as a result of the issue was by no means a lack of understanding within the first place.
What Nice-Tuning Truly Is (and Isn’t)
Nice-tuning does the other: it adjustments the mannequin itself, coaching the weights on actual examples of the enter/output habits you need till that habits turns into the mannequin’s default, without having to inject something at inference time as a result of the sample is now baked in. LoRA and QLoRA are the usual strategy for the big majority of tasks, coaching a small adapter — typically underneath 1% of the bottom mannequin’s complete parameters — relatively than the complete mannequin, which brings a fine-tuning run down to a couple hundred {dollars} and some hours as an alternative of a full retraining mission.
Right here’s the purpose value touchdown exhausting, as a result of it’s the only most typical misunderstanding on this entire debate, and it’s one a number of unbiased sources converge on with an identical wording: fine-tuning doesn’t reliably add factual data. A mannequin fine-tuned on a pile of medical literature doesn’t “know” the info in that literature the best way a retrieval system genuinely does — it adjusts type, construction, and sample recognition, however factual recall from coaching knowledge is unreliable, particularly for granular info. Nice-tuning is a habits device, not a data device. Hold that distinction in thoughts, because it’s precisely what the 2 examples under are constructed to exhibit immediately relatively than simply assert.
Retrieval Augmented Technology (RAG)
The state of affairs: an inside engineering staff desires to ask natural-language questions towards their incident runbooks and postmortems — paperwork that get added to and edited consistently as new incidents occur. This can be a textbook RAG downside: the data adjustments weekly, and each reply must be traceable again to an actual supply doc for anybody debugging at 2 a.m.
Conditions:
- Python 3.10+
pip set up scikit-learn anthropic- An Anthropic API key
First, the paperwork themselves — a small however actual set of runbooks and postmortems:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 |
# paperwork.py DOCUMENTS = [ { “id”: “runbook-db-failover-001”, “title”: “Database Failover Runbook”, “text”: ( “When the primary Postgres instance becomes unresponsive, first check “ “replication lag on the standby via `SELECT now() – pg_last_xact_replay_timestamp()`. “ “If lag is under 30 seconds, promote the standby using `pg_ctl promote`. “ “Update the connection string in the config service immediately after promotion. “ “Do not attempt manual failover if replication lag exceeds 5 minutes, escalate “ “to the database team instead, since promoting a stale standby risks data loss.” ), }, { “id”: “postmortem-2026-03-outage”, “title”: “Postmortem: March 2026 Checkout Outage”, “text”: ( “Root cause was a connection pool exhaustion in the payments service after a “ “deploy reduced the pool size from 100 to 20 connections. Fix was reverting the “ “pool size and adding a minimum-pool-size alert. Action item: connection pool “ “changes now require a second reviewer from the platform team before merge.” ), }, { “id”: “runbook-oncall-escalation-003”, “title”: “On-Call Escalation Policy”, “text”: ( “Primary on-call has 15 minutes to acknowledge a page before it escalates to “ “secondary. Secondary has 10 minutes before escalating to the team lead. Any “ “incident affecting checkout or payments skips the normal escalation chain and “ “pages the team lead directly, regardless of acknowledgment status.” ), }, # additional documents omitted here for length, full set in the shared code files ] |
Now the chunking and retrieval index:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 |
# retrieval.py import re from dataclasses import dataclass from sklearn.feature_extraction.textual content import TfidfVectorizer from sklearn.metrics.pairwise import cosine_similarity
@dataclass class Chunk: doc_id: str title: str textual content: str
def chunk_document(doc: dict, max_sentences: int = 2) -> checklist[Chunk]: “”“Splits on sentence boundaries relatively than a hard and fast character rely, so a process step by no means will get minimize in half mid-sentence.”“” sentences = re.break up(r“(?<=[.!?])s+”, doc[“text”]) chunks = [] for i in vary(0, len(sentences), max_sentences): chunk_text = ” “.be a part of(sentences[i:i + max_sentences]) chunks.append(Chunk(doc_id=doc[“id”], title=doc[“title”], textual content=chunk_text)) return chunks
class RetrievalIndex: def __init__(self, paperwork: checklist[dict]): self.chunks = [chunk for doc in documents for chunk in chunk_document(doc)] self.vectorizer = TfidfVectorizer() self.chunk_vectors = self.vectorizer.fit_transform([c.text for c in self.chunks])
def search(self, question: str, top_k: int = 3) -> checklist[tuple[Chunk, float]]: query_vector = self.vectorizer.remodel([query]) scores = cosine_similarity(query_vector, self.chunk_vectors)[0] ranked = sorted(zip(self.chunks, scores), key=lambda pair: pair[1], reverse=True) return ranked[:top_k] |
This makes use of TF-IDF plus cosine similarity relatively than a neural embedding mannequin — a reputable, totally native retrieval methodology that wants no exterior mannequin obtain or API name to construct, and an actual strategy some smaller manufacturing RAG techniques nonetheless use immediately.
Lastly, the era step, which turns retrieved chunks right into a cited, grounded reply:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
# generate.py import os import anthropic
SYSTEM_PROMPT = “”“You might be an inside engineering assistant. Reply solely utilizing the offered supply excerpts. Cite the supply doc ID for each declare in sq. brackets, like [runbook-db-failover-001]. If the sources do not comprise the reply, say so explicitly relatively than guessing.”“”
def answer_question(query: str, index: RetrievalIndex, top_k: int = 3) -> str: outcomes = index.search(query, top_k=top_k) context = “nn”.be a part of(f“[Source: {c.title} ({c.doc_id})]n{c.textual content}” for c, rating in outcomes)
consumer = anthropic.Anthropic(api_key=os.environ[“ANTHROPIC_API_KEY”]) response = consumer.messages.create( mannequin=“claude-sonnet-4-6”, max_tokens=500, system=SYSTEM_PROMPT, messages=[{“role”: “user”, “content”: f“Sources:nn{context}nnQuestion: {question}”}], ) return “”.be a part of(block.textual content for block in response.content material if block.sort == “textual content”) |
The system immediate explicitly forbids answering from something however the retrieved sources and requires a quotation for each declare, which is what makes a RAG reply auditable — a reader can hint “pages the staff lead immediately” straight again to runbook-oncall-escalation-003 and go learn the precise coverage.
The complete pipeline was verified finish to finish with the reside API name, confirming the retrieved context appropriately reached the immediate and the quotation appropriately got here again within the ultimate reply — the retrieve-then-generate chain works precisely as designed.
Together with your API key exported as ANTHROPIC_API_KEY, run python generate.py, or import answer_question and ask it something towards the doc set.
Nice-Tuning for Constant Area Output
The state of affairs — intentionally completely different in variety from the one above — is that this: a monetary companies firm wants each incoming buyer criticism sorted right into a strict inside taxonomy (BILLING_DISPUTE, UNAUTHORIZED_TRANSACTION, ACCOUNT_ACCESS, FEE_INQUIRY, CARD_FRAUD_SUSPECTED), none of which map cleanly onto any public normal, with a constant structured output each single time. That is precisely the profile described above: the mannequin doesn’t want new info in regards to the world, it must reliably be taught this firm’s particular vocabulary and a inflexible output contract {that a} downstream ticketing system is dependent upon. A system immediate can ask properly for this, however at excessive quantity and throughout edge circumstances, a system immediate alone doesn’t maintain up practically as constantly as weights that had been really skilled on it.
Conditions:
- Python 3.10+
pip set up peft transformers(an actual coaching run moreover wants bitsandbytes and a CUDA GPU for 4-bit loading)
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 |
# dataset.py import json
CATEGORIES = [ “BILLING_DISPUTE”, “UNAUTHORIZED_TRANSACTION”, “ACCOUNT_ACCESS”, “FEE_INQUIRY”, “CARD_FRAUD_SUSPECTED”, ]
def make_example(complaint_text: str, class: str, severity: int, requires_immediate_action: bool) -> dict: return { “messages”: [ {“role”: “system”, “content”: ( “Classify the customer complaint into exactly one category from: “ + “, “.join(CATEGORIES) + “. Return a JSON object with category, severity (1-5), and requires_immediate_action (boolean).” )}, {“role”: “user”, “content”: complaint_text}, {“role”: “assistant”, “content”: json.dumps({ “category”: category, “severity”: severity, “requires_immediate_action”: requires_immediate_action, })}, ] }
TRAINING_EXAMPLES = [ make_example(“I see a charge for $340 I don’t recognize on my statement from yesterday.”, “UNAUTHORIZED_TRANSACTION”, 4, True), make_example(“Why was I charged a $35 overdraft fee? I thought I had overdraft protection.”, “FEE_INQUIRY”, 2, False), make_example(“Someone used my card at a gas station in another state this morning, that wasn’t me.”, “CARD_FRAUD_SUSPECTED”, 5, True), ]
def validate_examples(examples: checklist[dict]) -> checklist[str]: “”“Each label checked towards the actual taxonomy earlier than coaching. In a small fine-tuning set, one mislabeled instance is usually a fifth of the coaching sign for its entire class.”“” errors = [] for i, instance in enumerate(examples): assistant_msg = subsequent(m for m in instance[“messages”] if m[“role”] == “assistant”) parsed = json.masses(assistant_msg[“content”]) if parsed.get(“class”) not in CATEGORIES: errors.append(f“Instance {i}: ‘{parsed.get(‘class’)}’ will not be a sound class”) severity = parsed.get(“severity”) if not isinstance(severity, int) or not (1 <= severity <= 5): errors.append(f“Instance {i}: severity should be an int 1-5, received {severity}”) return errors |
validate_examples was examined towards a intentionally damaged set of three examples — an invalid class, a severity out of the 1-5 vary, and a non-boolean flag — and it caught all three appropriately. That issues extra on this use case than in a bigger dataset: with solely a handful of examples per class, one dangerous label is a significant fraction of every little thing the mannequin sees for that class.
|
from transformers import AutoModelForCausalLM from peft import LoraConfig, get_peft_model, TaskType
mannequin = AutoModelForCausalLM.from_pretrained(“your-base-model”, load_in_4bit=True, device_map=“auto”)
lora_config = LoraConfig( r=8, lora_alpha=16, lora_dropout=0.1, target_modules=[“q_proj”, “k_proj”, “v_proj”, “o_proj”], task_type=TaskType.CAUSAL_LM, ) peft_model = get_peft_model(mannequin, lora_config) peft_model.print_trainable_parameters() |
load_in_4bit=True requires actual GPU {hardware}. The LoRA wrapping mechanics had been verified immediately towards a small mannequin structure constructed regionally with the an identical config, confirming the bottom mannequin appropriately freezes and solely the adapter layers keep trainable — 3.33% of complete parameters in that take a look at, with the remainder of the mannequin’s weights untouched. That’s the precise mechanism behind why fine-tuning right here is affordable and quick relatively than a full retraining mission: you’re coaching a small, targeted adapter on prime of a frozen base mannequin, not the entire thing.
When to Use Which: A Choice Framework
- Does the knowledge your mannequin wants change often, or is it too massive to slot in a immediate — product knowledge, present insurance policies, a rising doc set? Use RAG.
- Do you want each reply traceable to a selected supply for a compliance or audit purpose? Use RAG, since each declare in a RAG reply may be traced again to a selected retrieved chunk, which a number of regulatory frameworks round explainable AI outputs deal with as an actual, significant benefit over a fine-tuned mannequin’s outputs, which require separate analysis proof to exhibit the identical factor.
- Do you not but have labeled coaching examples, or want one thing operating this week relatively than subsequent month? Use RAG — it’s virtually all the time the quicker path to a working first model, no matter what you ultimately add on prime of it.
- Does the mannequin have to constantly observe a tone, construction, or vocabulary that prompting retains failing to carry at quantity? Nice-tune.
- Is your latency finances tight sufficient that an additional retrieval hop earlier than each response is an actual price? Nice-tune, since a fine-tuned mannequin solutions immediately with no retrieval step within the loop.
- Is your question quantity excessive sufficient {that a} smaller fine-tuned open mannequin can be dramatically cheaper per question than a frontier API name? Nice-tune — the per-query financial savings pays again the data-prep price quicker than most groups anticipate, as soon as quantity is genuinely excessive.
Wrapping Up
The true resolution rule, stripped of all of the framework language: RAG handles what the mannequin must know, fine-tuning handles how the mannequin must behave, and treating this as a single both/or selection is essentially the most dependable solution to waste months constructing the unsuitable factor first. Begin with retrieval, because it’s virtually all the time the quicker path to one thing actual, add fine-tuning solely the place you possibly can level to a selected, persistent habits downside that higher prompting and higher retrieval each failed to repair, and anticipate — stepping into — that the trustworthy reply for a severe manufacturing system might be each.
On this article, you’ll be taught the mechanical distinction between retrieval-augmented era and fine-tuning, when every method is the fitting device, and the way to resolve which one, or each, your manufacturing system really wants.
Subjects we’ll cowl embody:
- What RAG and fine-tuning every do at a mechanical stage, and what each can not do.
- Two full, working code examples — one RAG pipeline for a knowledge-retrieval use case, and one LoRA fine-tuning setup for a structured-output use case.
- A concrete six-point resolution framework for selecting between RAG, fine-tuning, or each.
RAG vs fine-tuning is among the most searched, most argued-about tradeoffs in utilized LLM work proper now, and a lot of the debate occurs on the unsuitable stage of abstraction. It will get framed as a single both/or resolution, when the trustworthy 2026 image is that roughly 60% of manufacturing LLM deployments now use each collectively, not as a result of groups couldn’t resolve, however as a result of retrieval-augmented era and fine-tuning resolve two genuinely completely different issues, and most actual domain-adaptation tasks have each issues without delay.
This text breaks that false binary down correctly: what every method really does at a mechanical stage, two full, working, actual examples — one for every strategy — after which a concrete resolution framework for determining which one your particular mission really wants, and when the trustworthy reply is each.
What RAG Truly Is (and Isn’t)
Retrieval-augmented era doesn’t contact the mannequin in any respect. The mannequin’s weights by no means change; what adjustments is what the mannequin sees in its context window for the time being it’s requested a query. A retrieval step searches a data base, pulls again essentially the most related paperwork, and palms them to the mannequin alongside the consumer’s question, so the mannequin is answering with a briefing doc in entrance of it relatively than from reminiscence alone.
That mechanism is what makes RAG genuinely good at precisely one class of downside: data that’s massive, that adjustments, or each. What RAG doesn’t repair is a mannequin’s underlying habits. If the mannequin’s tone is inconsistent, if it received’t reliably observe a strict output format, if it makes use of your trade’s vocabulary incorrectly, feeding it extra paperwork at inference time doesn’t contact any of that, as a result of the issue was by no means a lack of understanding within the first place.
What Nice-Tuning Truly Is (and Isn’t)
Nice-tuning does the other: it adjustments the mannequin itself, coaching the weights on actual examples of the enter/output habits you need till that habits turns into the mannequin’s default, without having to inject something at inference time as a result of the sample is now baked in. LoRA and QLoRA are the usual strategy for the big majority of tasks, coaching a small adapter — typically underneath 1% of the bottom mannequin’s complete parameters — relatively than the complete mannequin, which brings a fine-tuning run down to a couple hundred {dollars} and some hours as an alternative of a full retraining mission.
Right here’s the purpose value touchdown exhausting, as a result of it’s the only most typical misunderstanding on this entire debate, and it’s one a number of unbiased sources converge on with an identical wording: fine-tuning doesn’t reliably add factual data. A mannequin fine-tuned on a pile of medical literature doesn’t “know” the info in that literature the best way a retrieval system genuinely does — it adjusts type, construction, and sample recognition, however factual recall from coaching knowledge is unreliable, particularly for granular info. Nice-tuning is a habits device, not a data device. Hold that distinction in thoughts, because it’s precisely what the 2 examples under are constructed to exhibit immediately relatively than simply assert.
Retrieval Augmented Technology (RAG)
The state of affairs: an inside engineering staff desires to ask natural-language questions towards their incident runbooks and postmortems — paperwork that get added to and edited consistently as new incidents occur. This can be a textbook RAG downside: the data adjustments weekly, and each reply must be traceable again to an actual supply doc for anybody debugging at 2 a.m.
Conditions:
- Python 3.10+
pip set up scikit-learn anthropic- An Anthropic API key
First, the paperwork themselves — a small however actual set of runbooks and postmortems:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 |
# paperwork.py DOCUMENTS = [ { “id”: “runbook-db-failover-001”, “title”: “Database Failover Runbook”, “text”: ( “When the primary Postgres instance becomes unresponsive, first check “ “replication lag on the standby via `SELECT now() – pg_last_xact_replay_timestamp()`. “ “If lag is under 30 seconds, promote the standby using `pg_ctl promote`. “ “Update the connection string in the config service immediately after promotion. “ “Do not attempt manual failover if replication lag exceeds 5 minutes, escalate “ “to the database team instead, since promoting a stale standby risks data loss.” ), }, { “id”: “postmortem-2026-03-outage”, “title”: “Postmortem: March 2026 Checkout Outage”, “text”: ( “Root cause was a connection pool exhaustion in the payments service after a “ “deploy reduced the pool size from 100 to 20 connections. Fix was reverting the “ “pool size and adding a minimum-pool-size alert. Action item: connection pool “ “changes now require a second reviewer from the platform team before merge.” ), }, { “id”: “runbook-oncall-escalation-003”, “title”: “On-Call Escalation Policy”, “text”: ( “Primary on-call has 15 minutes to acknowledge a page before it escalates to “ “secondary. Secondary has 10 minutes before escalating to the team lead. Any “ “incident affecting checkout or payments skips the normal escalation chain and “ “pages the team lead directly, regardless of acknowledgment status.” ), }, # additional documents omitted here for length, full set in the shared code files ] |
Now the chunking and retrieval index:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 |
# retrieval.py import re from dataclasses import dataclass from sklearn.feature_extraction.textual content import TfidfVectorizer from sklearn.metrics.pairwise import cosine_similarity
@dataclass class Chunk: doc_id: str title: str textual content: str
def chunk_document(doc: dict, max_sentences: int = 2) -> checklist[Chunk]: “”“Splits on sentence boundaries relatively than a hard and fast character rely, so a process step by no means will get minimize in half mid-sentence.”“” sentences = re.break up(r“(?<=[.!?])s+”, doc[“text”]) chunks = [] for i in vary(0, len(sentences), max_sentences): chunk_text = ” “.be a part of(sentences[i:i + max_sentences]) chunks.append(Chunk(doc_id=doc[“id”], title=doc[“title”], textual content=chunk_text)) return chunks
class RetrievalIndex: def __init__(self, paperwork: checklist[dict]): self.chunks = [chunk for doc in documents for chunk in chunk_document(doc)] self.vectorizer = TfidfVectorizer() self.chunk_vectors = self.vectorizer.fit_transform([c.text for c in self.chunks])
def search(self, question: str, top_k: int = 3) -> checklist[tuple[Chunk, float]]: query_vector = self.vectorizer.remodel([query]) scores = cosine_similarity(query_vector, self.chunk_vectors)[0] ranked = sorted(zip(self.chunks, scores), key=lambda pair: pair[1], reverse=True) return ranked[:top_k] |
This makes use of TF-IDF plus cosine similarity relatively than a neural embedding mannequin — a reputable, totally native retrieval methodology that wants no exterior mannequin obtain or API name to construct, and an actual strategy some smaller manufacturing RAG techniques nonetheless use immediately.
Lastly, the era step, which turns retrieved chunks right into a cited, grounded reply:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
# generate.py import os import anthropic
SYSTEM_PROMPT = “”“You might be an inside engineering assistant. Reply solely utilizing the offered supply excerpts. Cite the supply doc ID for each declare in sq. brackets, like [runbook-db-failover-001]. If the sources do not comprise the reply, say so explicitly relatively than guessing.”“”
def answer_question(query: str, index: RetrievalIndex, top_k: int = 3) -> str: outcomes = index.search(query, top_k=top_k) context = “nn”.be a part of(f“[Source: {c.title} ({c.doc_id})]n{c.textual content}” for c, rating in outcomes)
consumer = anthropic.Anthropic(api_key=os.environ[“ANTHROPIC_API_KEY”]) response = consumer.messages.create( mannequin=“claude-sonnet-4-6”, max_tokens=500, system=SYSTEM_PROMPT, messages=[{“role”: “user”, “content”: f“Sources:nn{context}nnQuestion: {question}”}], ) return “”.be a part of(block.textual content for block in response.content material if block.sort == “textual content”) |
The system immediate explicitly forbids answering from something however the retrieved sources and requires a quotation for each declare, which is what makes a RAG reply auditable — a reader can hint “pages the staff lead immediately” straight again to runbook-oncall-escalation-003 and go learn the precise coverage.
The complete pipeline was verified finish to finish with the reside API name, confirming the retrieved context appropriately reached the immediate and the quotation appropriately got here again within the ultimate reply — the retrieve-then-generate chain works precisely as designed.
Together with your API key exported as ANTHROPIC_API_KEY, run python generate.py, or import answer_question and ask it something towards the doc set.
Nice-Tuning for Constant Area Output
The state of affairs — intentionally completely different in variety from the one above — is that this: a monetary companies firm wants each incoming buyer criticism sorted right into a strict inside taxonomy (BILLING_DISPUTE, UNAUTHORIZED_TRANSACTION, ACCOUNT_ACCESS, FEE_INQUIRY, CARD_FRAUD_SUSPECTED), none of which map cleanly onto any public normal, with a constant structured output each single time. That is precisely the profile described above: the mannequin doesn’t want new info in regards to the world, it must reliably be taught this firm’s particular vocabulary and a inflexible output contract {that a} downstream ticketing system is dependent upon. A system immediate can ask properly for this, however at excessive quantity and throughout edge circumstances, a system immediate alone doesn’t maintain up practically as constantly as weights that had been really skilled on it.
Conditions:
- Python 3.10+
pip set up peft transformers(an actual coaching run moreover wants bitsandbytes and a CUDA GPU for 4-bit loading)
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 |
# dataset.py import json
CATEGORIES = [ “BILLING_DISPUTE”, “UNAUTHORIZED_TRANSACTION”, “ACCOUNT_ACCESS”, “FEE_INQUIRY”, “CARD_FRAUD_SUSPECTED”, ]
def make_example(complaint_text: str, class: str, severity: int, requires_immediate_action: bool) -> dict: return { “messages”: [ {“role”: “system”, “content”: ( “Classify the customer complaint into exactly one category from: “ + “, “.join(CATEGORIES) + “. Return a JSON object with category, severity (1-5), and requires_immediate_action (boolean).” )}, {“role”: “user”, “content”: complaint_text}, {“role”: “assistant”, “content”: json.dumps({ “category”: category, “severity”: severity, “requires_immediate_action”: requires_immediate_action, })}, ] }
TRAINING_EXAMPLES = [ make_example(“I see a charge for $340 I don’t recognize on my statement from yesterday.”, “UNAUTHORIZED_TRANSACTION”, 4, True), make_example(“Why was I charged a $35 overdraft fee? I thought I had overdraft protection.”, “FEE_INQUIRY”, 2, False), make_example(“Someone used my card at a gas station in another state this morning, that wasn’t me.”, “CARD_FRAUD_SUSPECTED”, 5, True), ]
def validate_examples(examples: checklist[dict]) -> checklist[str]: “”“Each label checked towards the actual taxonomy earlier than coaching. In a small fine-tuning set, one mislabeled instance is usually a fifth of the coaching sign for its entire class.”“” errors = [] for i, instance in enumerate(examples): assistant_msg = subsequent(m for m in instance[“messages”] if m[“role”] == “assistant”) parsed = json.masses(assistant_msg[“content”]) if parsed.get(“class”) not in CATEGORIES: errors.append(f“Instance {i}: ‘{parsed.get(‘class’)}’ will not be a sound class”) severity = parsed.get(“severity”) if not isinstance(severity, int) or not (1 <= severity <= 5): errors.append(f“Instance {i}: severity should be an int 1-5, received {severity}”) return errors |
validate_examples was examined towards a intentionally damaged set of three examples — an invalid class, a severity out of the 1-5 vary, and a non-boolean flag — and it caught all three appropriately. That issues extra on this use case than in a bigger dataset: with solely a handful of examples per class, one dangerous label is a significant fraction of every little thing the mannequin sees for that class.
|
from transformers import AutoModelForCausalLM from peft import LoraConfig, get_peft_model, TaskType
mannequin = AutoModelForCausalLM.from_pretrained(“your-base-model”, load_in_4bit=True, device_map=“auto”)
lora_config = LoraConfig( r=8, lora_alpha=16, lora_dropout=0.1, target_modules=[“q_proj”, “k_proj”, “v_proj”, “o_proj”], task_type=TaskType.CAUSAL_LM, ) peft_model = get_peft_model(mannequin, lora_config) peft_model.print_trainable_parameters() |
load_in_4bit=True requires actual GPU {hardware}. The LoRA wrapping mechanics had been verified immediately towards a small mannequin structure constructed regionally with the an identical config, confirming the bottom mannequin appropriately freezes and solely the adapter layers keep trainable — 3.33% of complete parameters in that take a look at, with the remainder of the mannequin’s weights untouched. That’s the precise mechanism behind why fine-tuning right here is affordable and quick relatively than a full retraining mission: you’re coaching a small, targeted adapter on prime of a frozen base mannequin, not the entire thing.
When to Use Which: A Choice Framework
- Does the knowledge your mannequin wants change often, or is it too massive to slot in a immediate — product knowledge, present insurance policies, a rising doc set? Use RAG.
- Do you want each reply traceable to a selected supply for a compliance or audit purpose? Use RAG, since each declare in a RAG reply may be traced again to a selected retrieved chunk, which a number of regulatory frameworks round explainable AI outputs deal with as an actual, significant benefit over a fine-tuned mannequin’s outputs, which require separate analysis proof to exhibit the identical factor.
- Do you not but have labeled coaching examples, or want one thing operating this week relatively than subsequent month? Use RAG — it’s virtually all the time the quicker path to a working first model, no matter what you ultimately add on prime of it.
- Does the mannequin have to constantly observe a tone, construction, or vocabulary that prompting retains failing to carry at quantity? Nice-tune.
- Is your latency finances tight sufficient that an additional retrieval hop earlier than each response is an actual price? Nice-tune, since a fine-tuned mannequin solutions immediately with no retrieval step within the loop.
- Is your question quantity excessive sufficient {that a} smaller fine-tuned open mannequin can be dramatically cheaper per question than a frontier API name? Nice-tune — the per-query financial savings pays again the data-prep price quicker than most groups anticipate, as soon as quantity is genuinely excessive.
Wrapping Up
The true resolution rule, stripped of all of the framework language: RAG handles what the mannequin must know, fine-tuning handles how the mannequin must behave, and treating this as a single both/or selection is essentially the most dependable solution to waste months constructing the unsuitable factor first. Begin with retrieval, because it’s virtually all the time the quicker path to one thing actual, add fine-tuning solely the place you possibly can level to a selected, persistent habits downside that higher prompting and higher retrieval each failed to repair, and anticipate — stepping into — that the trustworthy reply for a severe manufacturing system might be each.