In September 2025, Horace He and colleagues at Pondering Machines Lab ran a easy experiment. They despatched the immediate “Inform me about Richard Feynman” to Qwen3-235B 1,000 instances at temperature 0 and requested for 1,000 tokens every time. Temperature 0 means the mannequin at all times picks its most possible token, so you’d count on 1,000 an identical solutions. They acquired 80 distinctive completions.
What caught my eye is the place the solutions break up. All 1,000 completions have been an identical for the primary 102 tokens. At token 103, 992 of them continued with “Queens, New York” and eight with “New York Metropolis.” Eight runs in a thousand flipped at a single token, after 102 tokens the place none did.
Their submit explains why outputs differ in any respect. This text asks a special query: how usually ought to a token flip, and why does that danger arrive in sudden spikes? I will derive a one-line system, examine it with a simulation, and take a look at it on an actual mannequin. All the pieces runs on a laptop computer, and the code is within the article.
The place the noise comes from
At temperature 0 the mannequin picks the token with the best logit (its uncooked rating). That’s deterministic arithmetic, however your laptop computes logits in floating level, the place addition isn’t associative:
At scale it will get worse. I summed 100,000 random float32 numbers 3 ways. Ahead order gave −90.82497, reverse order gave −90.82674, and NumPy’s pairwise sum gave −90.82513 (a float64 reference provides −90.82508). Similar numbers, three solutions.
A neural community is billions of such sums, so the order the {hardware} makes use of issues. A preferred clarification blames GPU threads that end in random order. He et al. present that this is not the primary trigger: a typical LLM ahead go accommodates primarily no atomic provides, and the identical kernel on the identical enter returns the identical bits each time. The true perpetrator is that many kernels aren’t batch-invariant. Their discount order adjustments with the batch measurement, and on a shared server the batch measurement is dependent upon what number of different persons are sending requests at that second. Your reply is dependent upon strangers.
The authors be aware that this is not particular to GPUs, and that with batch-invariant kernels all 1,000 Feynman completions got here out an identical. The repair has a worth: of their serving take a look at (Qwen-3-8B on one GPU), the unoptimized deterministic model took 55 seconds in opposition to 26 for default vLLM, and 42 after an improved consideration kernel.
Solely near-ties matter
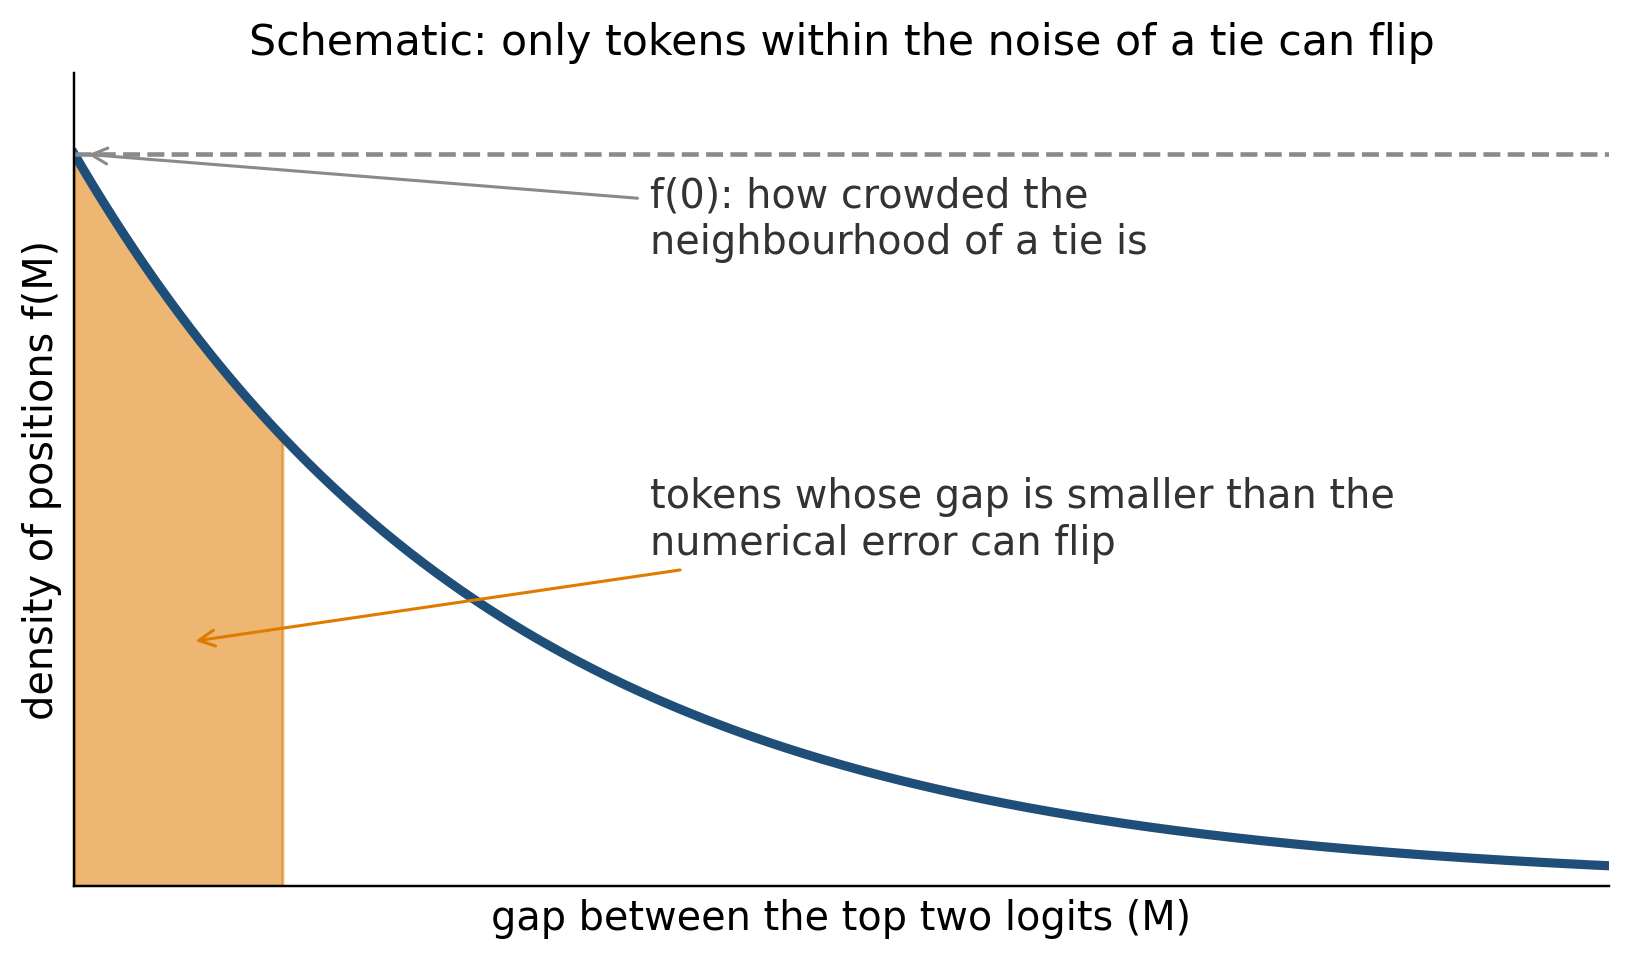
Right here is the half that pursuits me as a mathematician. Let z₁ and z₂ be the 2 largest logits, and name their distinction the hole, . Numerical noise adjustments that hole by a small error Δ, and the argmax flips provided that .
A token with a niche of 8 logits won’t ever flip, nonetheless noisy the kernel. Solely near-ties are in danger. Averaging over all positions, with f the density of gaps, the flip chance is
p = ∫ P(Δ < −m) f(m) dm
If the noise is small, f is roughly fixed, equal to f(0), over the slim vary the place is not negligible. The integral of over is the anticipated detrimental a part of the error, which is for symmetric noise. So
p ≈ f(0) · E|Δ| / 2
The flip chance per token is how crowded the neighbourhood of a tie is, instances how giant the noise is. The primary issue belongs to the mannequin and the textual content. The second belongs to your {hardware}, precision and kernels. That is an elementary small-noise argument, so I make no declare of novelty. A associated formalization, the “background temperature” of Messina and Scotta (TMLR, 2026), treats such perturbations as an efficient temperature.
Does the system maintain?
Earlier than touching an actual mannequin, I checked the system on simulated gaps with a identified density and Gaussian noise of identified measurement . The core is 9 traces:
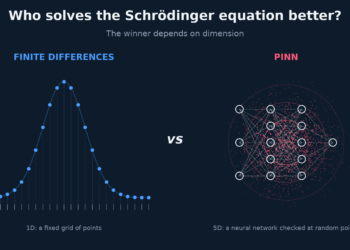
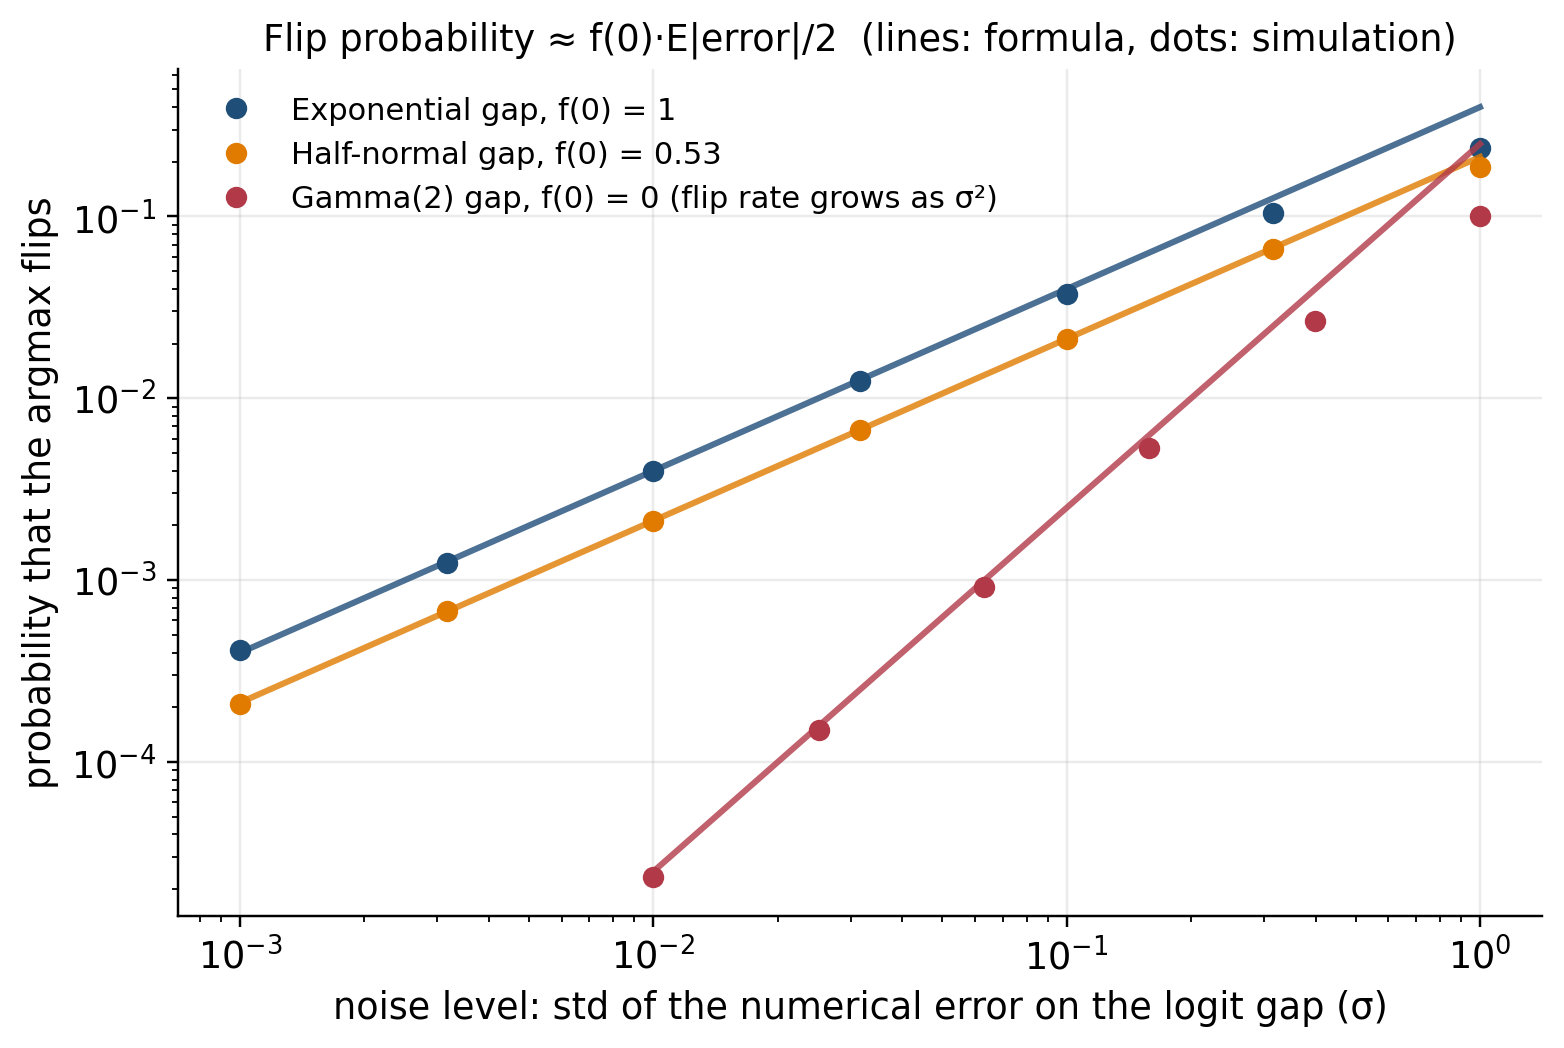
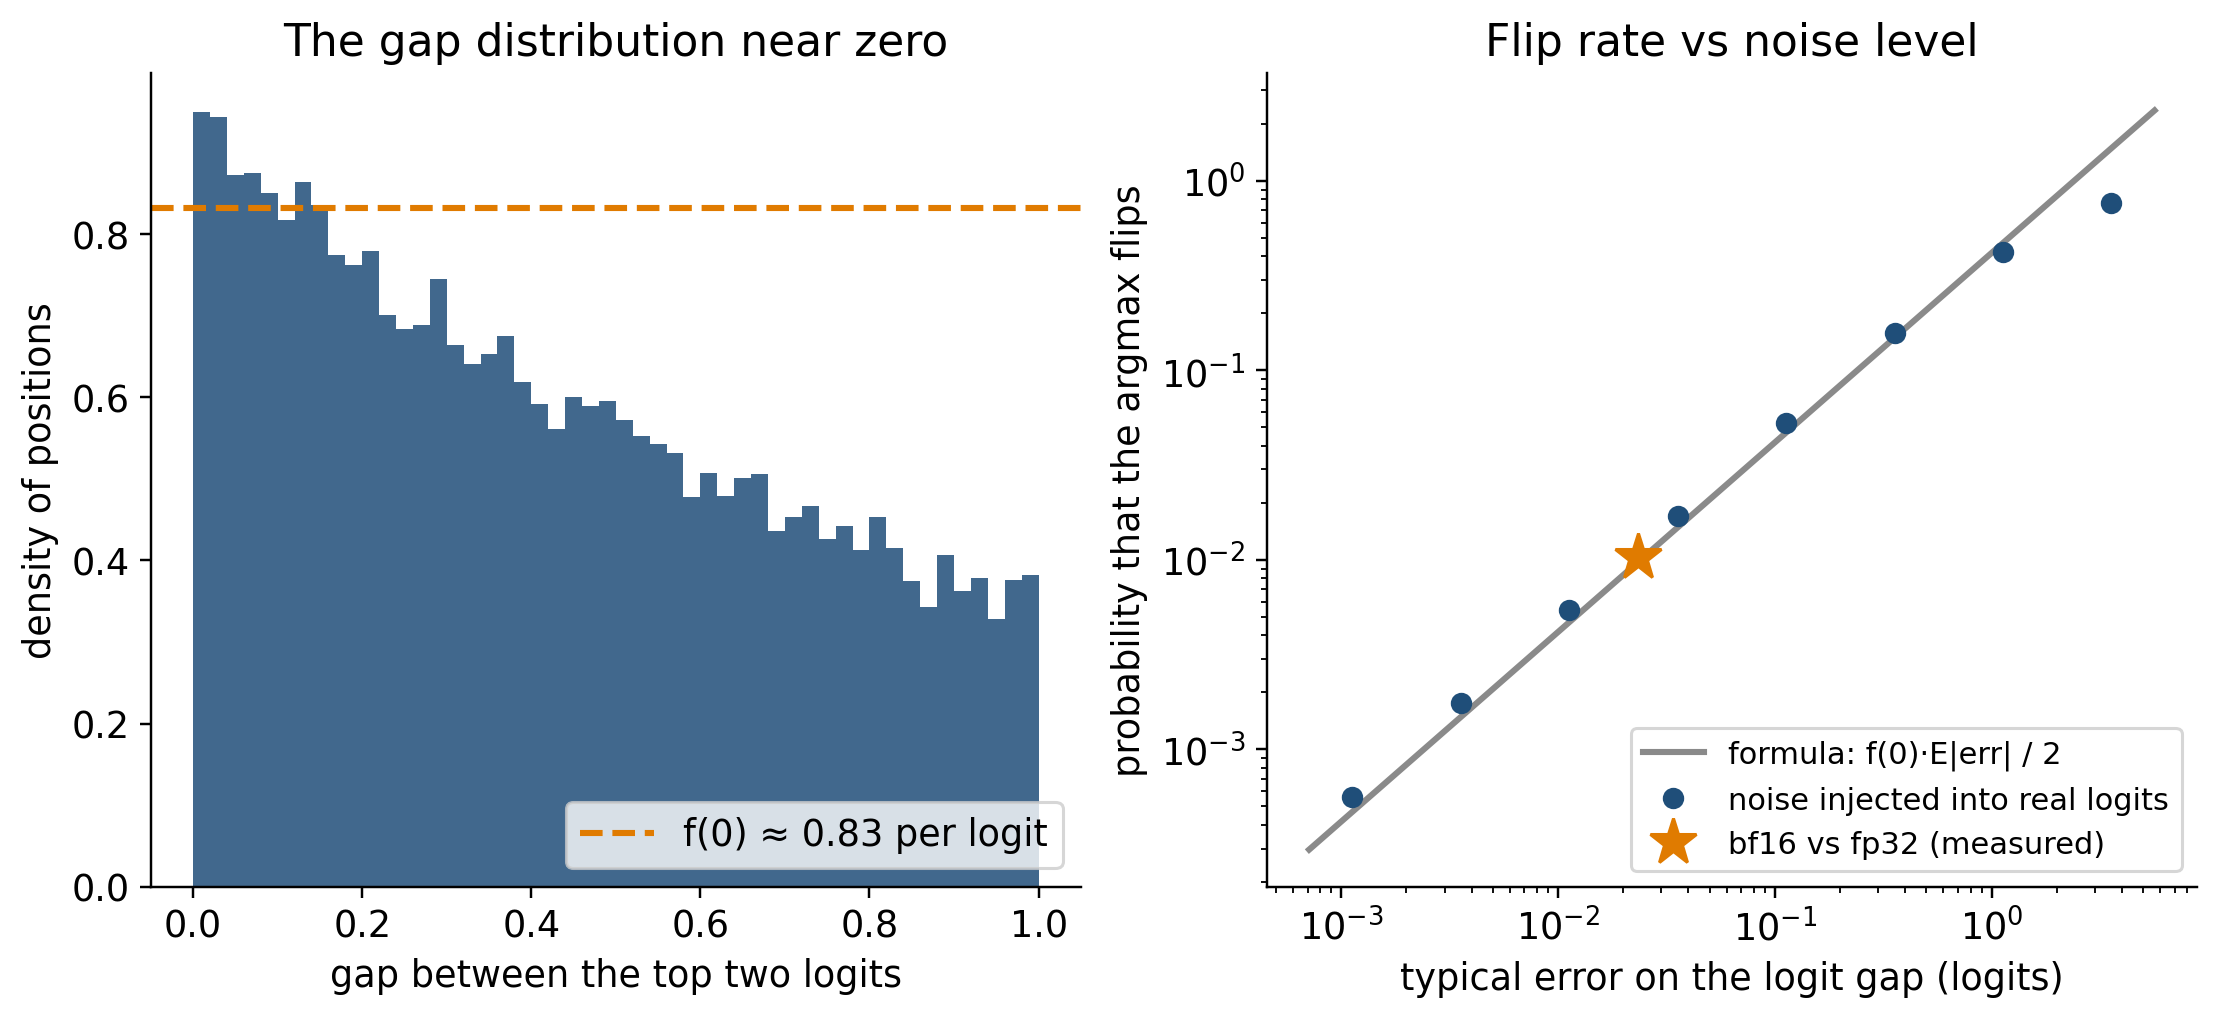
For an exponential and a half-normal hole, the simulation matches the system inside 4% for σ as much as 0.03, and the half-normal stays inside 2% even at σ = 0.3 (Determine 2). It breaks when the noise is as giant as the standard hole: at σ = 1 the exponential case flips 24% of the time in opposition to a predicted 40%, as a result of the density is not flat over the area that issues.
A 3rd case exhibits the system’s key assumption, . If the hole density vanishes at zero, the flip fee grows like as an alternative (it matches inside 8% for σ as much as 0.06), and noise issues far much less. So which regime does an actual mannequin reside in?
An actual mannequin
I ran GPT-2 on 256 home windows of 128 tokens from WikiText-2 and in contrast a ahead go with an one. It is a stand-in for lifelike serving noise: my laptop computer cannot reproduce the batch-size impact of a loaded GPU server, however it will probably measure the logit error a lower-precision kernel produces. I run the transformer physique in and the output projection in , so the ultimate logits aren’t rounded to ‘s coarse grid.
For each place I preserve the top-20 logits, the hole, the error on that hole within the run, and whether or not the argmax flipped. (Plotting code omitted.)
The density of the hole at zero is per logit, and of positions have a niche under 0.1 logits. The error on the hole close to ties averages logits, so the system predicts a flip fee of . I measured . Determine 3 (proper) repeats the comparability throughout noise ranges by injecting Gaussian noise of identified measurement into the actual logits.
From tokens to completions
For one completion, survival is a product of per-token survival possibilities, . If each token carried the identical danger , that will be , and half of all completions would have break up by token ln . Actual textual content is not like that.
Take the Feynman numbers (that is my arithmetic on their printed counts). Over the primary 102 tokens, 1,000 runs produced zero disagreements. That’s about 102,000 token selections with no flip, so the common per-token flip fee over that stretch is at most about 3×10⁻⁵ (the “rule of three” 95% certain). At token 103 the speed was 8 in 1,000, or 0.8%. That’s greater than 250 instances larger, at a single token. Danger is not unfold evenly. It sits on just a few knife-edge tokens, with lengthy stretches of near-zero hazard in between.
Prompts additionally differ in what number of knife-edge tokens they comprise. To see what that does to survival, I simulated a imply per-token flip fee of 0.005 with fragility various throughout prompts (lognormal, log-sd 1):
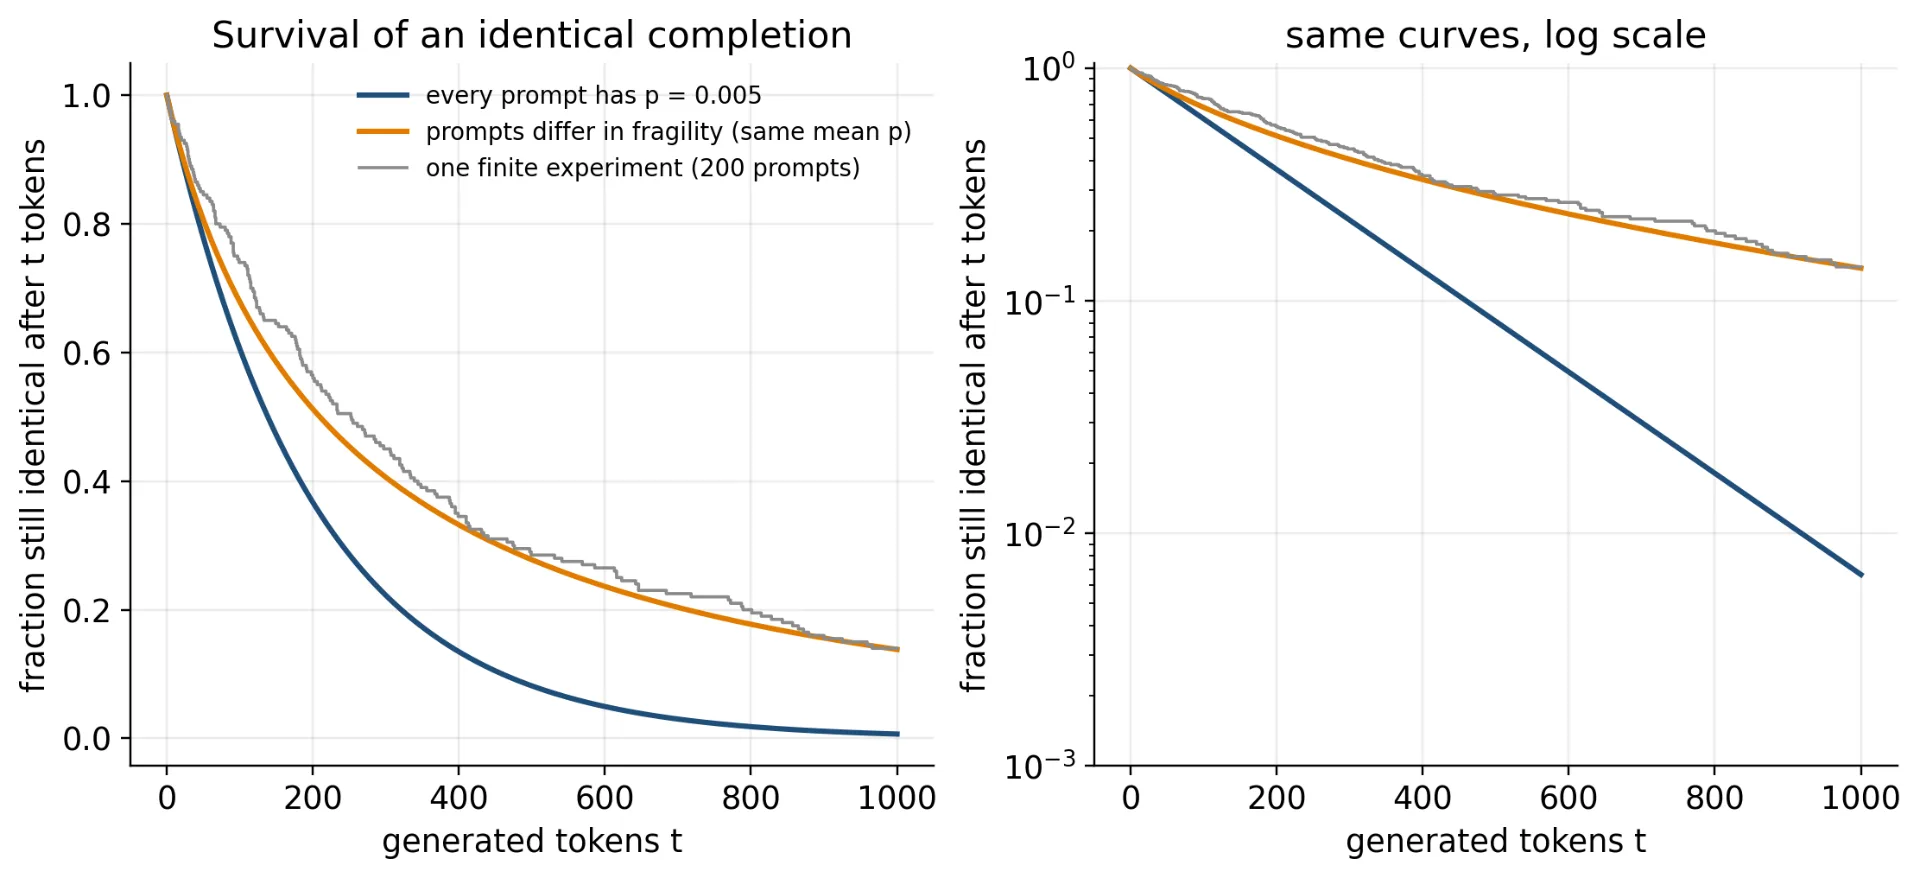
If each immediate had p = 0.005, half of the completions would break up by token 139 and eight% would nonetheless match at token 500. With the identical imply however various fragility, the median strikes to token 210 and 28% nonetheless match at token 500. The common flip fee alone would not inform you how lengthy a completion survives. The unfold of fragility issues too.
The place this breaks
-
My noise is not your server’s noise.
bf16in opposition tofp32on a laptop computer reproduces the scale of a precision error, not the batch-size mechanism of a loaded GPU cluster. These numbers describe the mannequin, not any hosted API. -
Two tokens solely. The system ignores the third-best token and assumes the error is symmetric and unbiased of the hole.
-
A flip is not an error. Many flips swap near-equivalent phrasings. The system says how usually outputs differ, not how usually they worsen.
What to do with it
Predict your flake fee. In case your stack has a per-token flip fee p, a completion of L tokens differs between runs with chance about . With p = 10⁻³ and 500-token solutions, that’s about 39%. Measure f(0) in your mannequin and the noise in your stack, and you may estimate it earlier than transport an eval.
Do not assert actual equality on temperature-0 outputs. Evaluate with a tolerance, or grade semantically. Should you management inference, batch-invariant kernels take away the impact for a throughput worth. Should you do not, assume two an identical calls can differ.
Takeaways
-
Temperature 0 is deterministic within the arithmetic, not within the arithmetic.
-
Solely near-ties matter: the per-token flip chance is about the crowding of ties instances the noise degree.
-
Danger is spiky. A number of knife-edge tokens carry most of it, which is why completions keep an identical for a stretch after which break up.
···
Sources and credit
-
He, Horace and Pondering Machines Lab, “Defeating Nondeterminism in LLM Inference”, Pondering Machines Lab: Connectionism, September 10, 2025. https://thinkingmachines.ai/weblog/defeating-nondeterminism-in-llm-inference/ (supply of the Feynman experiment and its counts, the batch-invariance clarification, and the serving timings).
-
Messina, Alberto and Scotta, Stefano, “Introducing Background Temperature to Characterise Hidden Randomness in Massive Language Fashions”, Transactions on Machine Studying Analysis, 2026. https://openreview.web/discussion board?id=bz0he4bARF
-
Radford et al., “Language Fashions are Unsupervised Multitask Learners” (GPT-2), 2019, and Merity et al., “Pointer Sentinel Combination Fashions” (WikiText-2), 2016, each used by Hugging Face Transformers and Datasets.
-
The flip-probability system, simulations, real-model experiment, figures and the arithmetic on the Feynman counts are the writer’s personal.