TypeSafe.AI not too long ago launched its first mannequin, Jev. They declare it’s the primary mannequin of a brand new form (a System One mannequin) that’s basically completely different from the LLMs we’ve been working with (and hyping up) over the past a number of years.
This new mannequin appears to be like notably nicely suited to many on a regular basis use circumstances, similar to classification (e.g. matter modelling for NPS feedback) or LLM-as-a-judge duties. So, naturally, I made a decision I needed to strive it out.
On this article, we’ll take a look at what makes System One fashions completely different from LLMs and put a few of TypeSafe.AI’s claims to the take a look at in apply, utilizing intent classification for buyer help requests for example.
How System One fashions differ from LLMs
Whereas LLMs are educated to foretell the subsequent token and generate the long-form textual content and conversations we’ve all been having fun with, System One fashions are constructed to judge a state and produce structured solutions. Much like LLMs, System One fashions can take pure language as enter, so there’s no actual distinction there.
You will discover extra particulars in regards to the coaching course of in the documentation. The attention-grabbing half about Jev is its post-training method. LLMs are principally post-trained with RLHF (Reinforcement Studying from Human Suggestions), which teaches them to align with human preferences. However this may additionally result in sycophancy and confident-sounding hallucinations that we’ve all seen in apply. That works nicely for chatbots, however to be used circumstances that contain decision-making, TypeSafe suggests a distinct method.
For Jev, they use RLCD (Reinforcement Studying for Calibrated Selections), which trains the mannequin to return each selections and possibilities.
Let’s take a look at how the mannequin works and what its enter and output appear like.
The enter to the mannequin is named a state. The state defines the context you need to present to the mannequin along with the questions you need it to reply. It may be so simple as a single message, for instance a buyer request like “Is it attainable for me to alter my PIN quantity?”, or it may be a JSON object.
-
a map with a number of fields, similar to
{"message": "Is it attainable for me to alter my PIN quantity?", "user_id": 123} -
an array representing a sequence of messages or information, similar to
["Hello! How can I help you?", "Is it possible for me to change my PIN number?"]
The perfect apply is to make use of an object for the state with clear area names, so it’s simpler for the mannequin to cause in regards to the context.
Together with the context, we will additionally go one or a number of inquiries to the mannequin. Since System One fashions don’t generate free-form responses, we have to specify the anticipated sort of reply utilizing one of many obtainable primitives:
-
Selection works when the reply ought to be certainly one of a number of predefined choices. For instance: what is that this buyer request about — supply, billing, or account entry?
-
Rating can be utilized when the reply comes from an ordered set of values. For instance: what’s the sentiment of this buyer message — unfavorable, impartial, or optimistic?
-
Noul can be utilized for sure/no questions. For instance: has the shopper’s downside been solved on this chat?
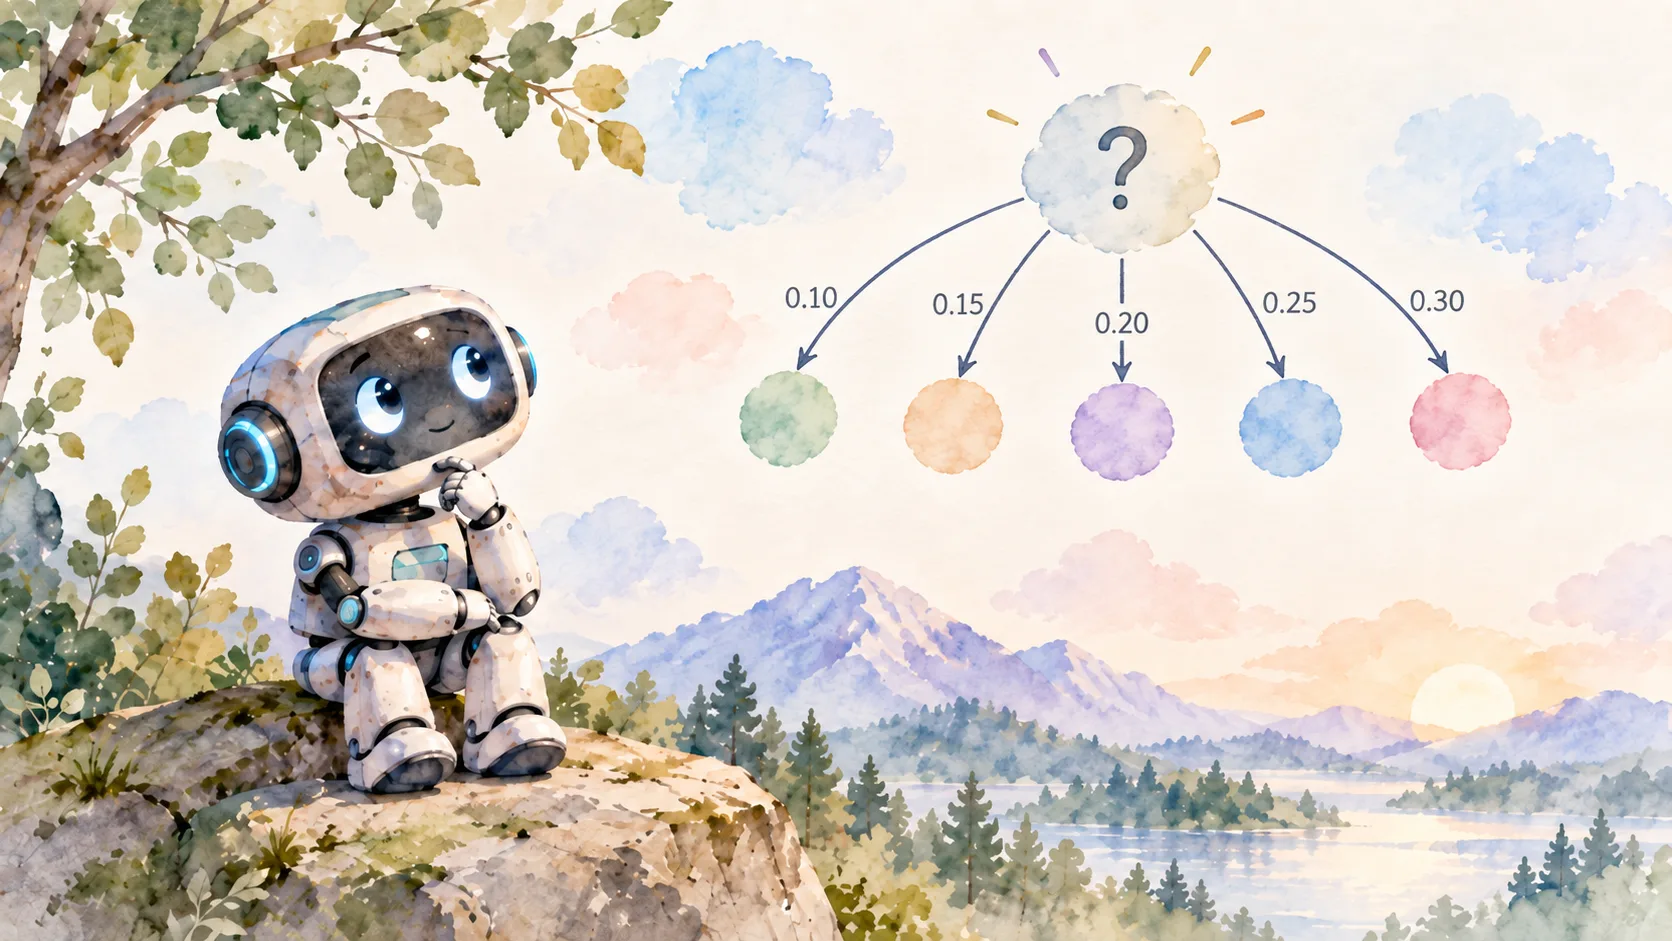
In all of those circumstances, we get not solely the reply itself, but in addition possibilities for all attainable values. Confidence is a crucial a part of Jev, as a result of it tells us whether or not the mannequin is assured in its resolution (for instance, when a lot of the chance is focused on one worth) or unsure, when a number of choices have roughly related possibilities.
These confidence ranges will be notably helpful when we have to make selections primarily based on the mannequin output. Take auto-replies to buyer questions for example: if the mannequin can classify a buyer request into one of many identified classes with excessive confidence, we will ship an computerized reply. In any other case, we will route the message to a human help agent.
Follow
Jev claims to be 193.6× sooner, 444.6× cheaper, and fewer vulnerable to hallucinations. Let’s see how these claims maintain up in apply by evaluating it with our good outdated LLMs.
For this experiment, I selected OpenAI, since TypeSafe’s benchmark exhibits Jev acting on par with OpenAI’s Terra mannequin.
I additionally determined to make use of a publicly obtainable dataset of banking intents launched by PolyAI below the CC BY 4.0 licence. It’s fairly an attention-grabbing classification downside, with 77 completely different intent lessons (which is rather a lot).
Right here’s a pattern of the information.

Utilizing Jev
Let’s begin by making a name to the Jev mannequin. To get entry, you’ll have to register (there’s at the moment a waitlist) and acquire an API key. In my case, it took about half a day to obtain an invitation.
For our classification process, we’ll use the Selection primitive for the query. We don’t have any further descriptions for the classes, so we’ll go away these as null.
From there, we simply have to make an HTTP request and go all of the required info (the state and the query primitive).
Consequently, we get a JSON object containing the reply and the chances for all attainable choices. On this case, we will see that the mannequin is totally assured that the right reply is card_linking.
Utilizing OpenAI
For comparability, we’ll use OpenAI’s Luna and Terra fashions. To make the setup comparable, we’ll additionally specify an output schema for the OpenAI fashions, so their responses are constrained to the identical structured format.
Sadly, OpenAI fashions don’t at the moment return log possibilities, so there’s no easy approach for us to get a confidence rating from the mannequin and evaluate it immediately with Jev.
Comparability
TypeSafe positions Jev as roughly on par with Terra and barely forward of Luna, whereas being considerably sooner and cheaper, particularly for workflows involving a number of selections or mannequin calls.
Let’s see how that interprets to our use case, regardless that this process is pretty easy and requires only a single name. On accuracy, Jev performs noticeably worse than each OpenAI fashions: 79.0%, in contrast with 83.9% for Terra and 86.2% for Luna. The distinction is statistically important.

We will additionally see that Jev makes use of considerably extra tokens (about 2× extra enter tokens and 40× extra output tokens) largely as a result of it returns possibilities for all 77 intents. So even with the decrease per-token pricing, I’m not satisfied it finally ends up being dramatically cheaper than Luna for this specific use case.
Nonetheless, the pace enchancment is critical certainly: Jev is nearly 2× sooner.


What’s actually spectacular is how nicely calibrated the boldness scores are: accuracy constantly will increase for higher-confidence buckets.

I additionally experimented a bit to grasp why Jev wasn’t performing as nicely on this process. My finest guess is that the massive variety of lessons was the principle problem. Once I decreased the duty from 77 labels to simply 7, the outcomes improved considerably and had been roughly on par with the OpenAI fashions.

You will discover all of the code on GitHub.
We’ve checked out how this new mannequin works and put it into apply, so it’s time to wrap up and summarise the expertise.
Abstract
I actually just like the path System One fashions are taking, as a result of I can see them being helpful for fairly a couple of duties I cope with at work, similar to LLM-as-a-judge evaluations or intent classification.
As we’ve seen, the standard isn’t at all times on par with LLMs, however the well-calibrated confidence scores are an enormous benefit. They might make it attainable to make use of a quick and low-cost mannequin for simpler circumstances, whereas routing extra unsure ones to frontier fashions. I’d be very excited by making an attempt this sort of setup in an actual manufacturing workflow.
On the similar time, TypeSafe’s headline claims make these fashions sound nearly miraculous (100×+ cheaper and sooner). I can consider that that is achievable for some workflows, particularly these involving many small selections and repeated calls, however I’d nonetheless count on the real-world features to fluctuate rather a lot by use case. So it’s value testing by yourself process reasonably than assuming the benchmark numbers will translate immediately.
Thanks for studying. I hope this text was insightful. Keep in mind Einstein’s recommendation: “The vital factor is to not cease questioning. Curiosity has its personal cause for current.” Could your curiosity lead you to your subsequent nice perception.