

Introduction
Few selections within the design of a neural community have attracted as a lot consideration, and as a lot revision, as the selection of activation operate. On the floor it is a slender technical query, however the activation operate is the place the comparability with biology is most literal, because it decides what it means for a synthetic neuron to fireside. That makes it the pure place for an outdated query to resurface: how intently ought to a synthetic neuron resemble an actual one?
The early reply was an important deal. Warren McCulloch and Walter Pitts proposed the primary formal mannequin of the neuron in 1943[1], a binary threshold gadget that fired at any time when its inputs crossed a crucial worth. Frank Rosenblatt’s perceptron added adjustable weights in 1957[2], turning a static logical unit into one thing that might study from knowledge. These fashions had been overtly organic of their inspiration, for the reason that ambition was not merely to compute however to assume. That goal carried by to the sigmoid operate, whose clean, saturating curve was taken to reflect the graded firing of actual neurons, and for many years organic plausibility served as each a design precept and a supply of status.
Within the early 2010s, the Rectified Linear Unit (ReLU) displaced the sigmoid as a result of it made deep networks trainable the place the sigmoid had not, and it seemed like the sphere had settled the matter in favour of pragmatism. The story is much less tidy than that, nevertheless, and following it by calls into query how a lot weight biology ever carried.
The sigmoid and the vanishing gradient
From the Nineteen Eighties into the early 2000s, the sigmoid was the activation operate of alternative for hidden layers. Its attraction was partly mathematical, because it’s clean and differentiable in all places, however its S-shaped curve additionally supplied a pure neural interpretation, with the output learn because the likelihood {that a} neuron fires given its enter,
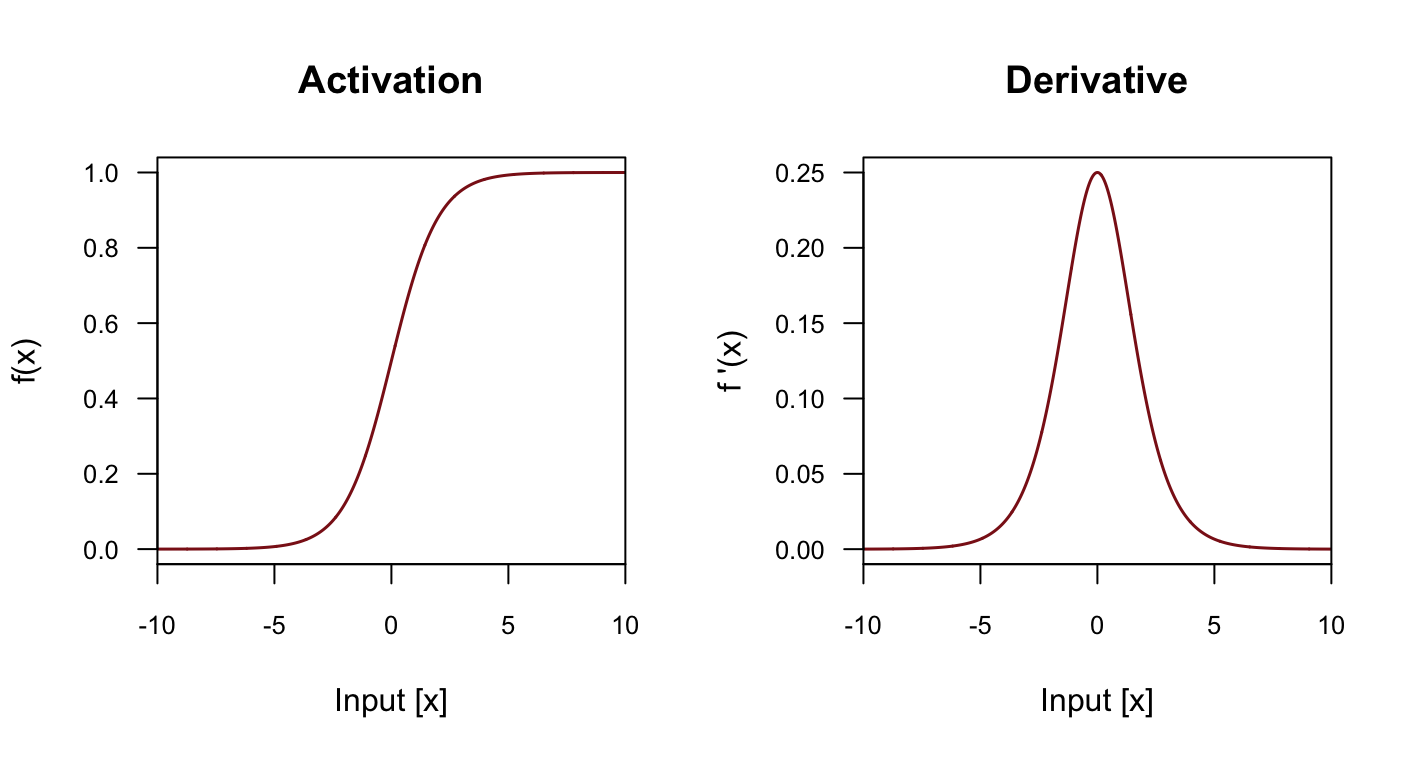
Weak inputs produce outputs close to zero, whereas robust inputs drive the neuron towards saturation (see left panel in determine under). It was, in different phrases, a mannequin of graded neural firing.
The sigmoid’s limitations surfaced in how networks study. Coaching adjusts every weight in proportion to the gradient of the loss with respect to that weight, and backpropagation computes these gradients by passing a sign backward from the output layer, one layer at a time. As a result of every step applies the chain rule, the gradient for a weight in layer l is a product of derivatives by each layer above it:
the place is the activation of layer .
This multiplicative construction means the by-product of the activation operate largely decides whether or not the gradient survives the journey. When the derivatives are constantly small, the product shrinks with each layer, and the gradient vanishes earlier than it reaches the earliest layers, leaving them to study slowly or by no means. When the derivatives are giant, the alternative occurs: gradients explode and coaching destabilises. Studying wants a regime between the 2, wherein gradients are giant sufficient to hold significant info however not so giant as to overwhelm it.
The sigmoid falls firmly on the vanishing aspect. Its by-product takes a easy kind:
and even at its peak, when , it reaches solely (see proper panel in determine above). Every sigmoid layer subsequently contributes an element of at most 0.25 to the product, and much much less as soon as a unit saturates. In shallow networks that is manageable, however as depth will increase, the sign decays quickly and studying slows to a crawl. The hyperbolic tangent was usually most popular in hidden layers as a result of its outputs centre on zero, but it surely eased the issue with out fixing it. Its by-product peaks at one, but it nonetheless falls away because the unit saturates. Cautious weight initialisation and layer-wise pre-training may mitigate the decay, however saturating activation capabilities remained a major barrier to constructing deep networks.
The shift to ReLU
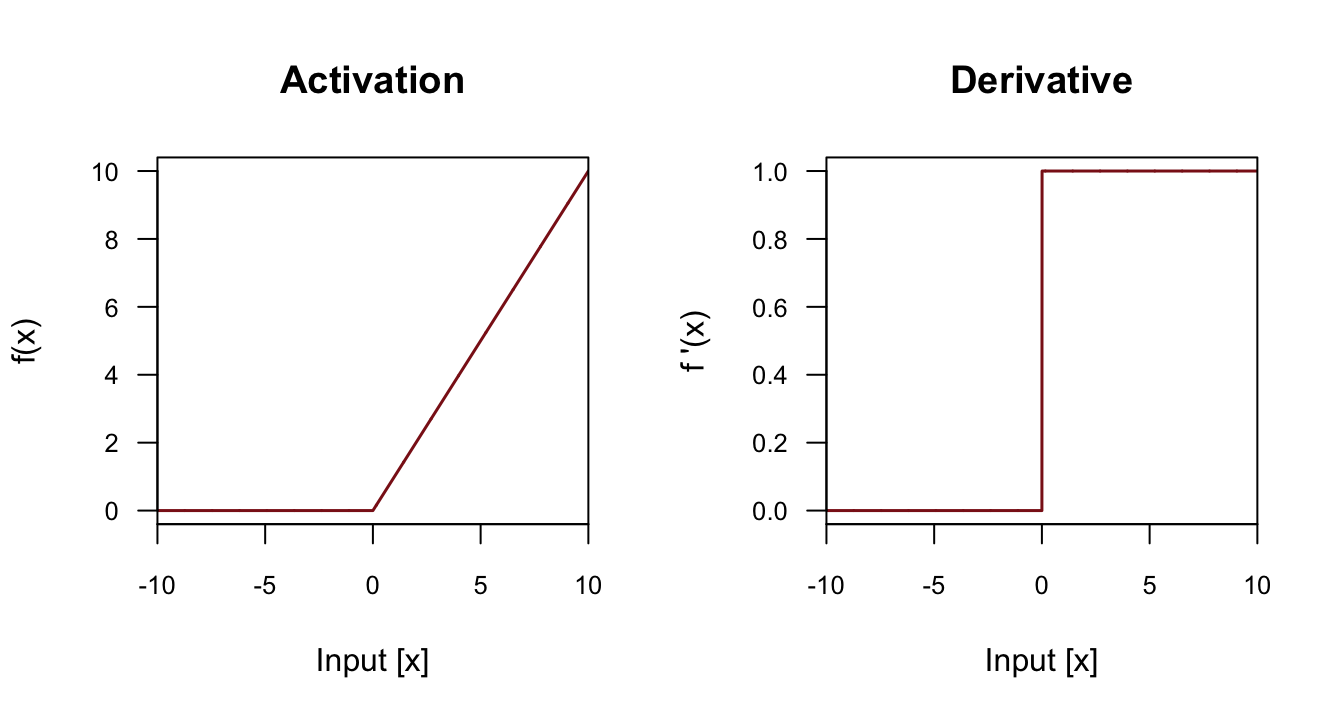
Within the early 2010s, an answer emerged that was so disarmingly easy it seemed wholly unimpressive on paper (see, for instance, Nair and Hinton[3]; Glorot, Bordes, and Bengio[4]). Moderately than a clean, S-shaped curve that compresses the whole lot right into a slender vary, ReLU returns its enter unchanged when it’s constructive and outputs zero in any other case. Its definition matches on a single line:
What made ReLU so efficient is its by-product. For any constructive enter it’s precisely one (if then ; see proper panel in determine under), so a gradient passing again by an energetic unit is neither diminished nor amplified by the activation itself. Every sigmoid layer contributed an element of at most 0.25 to the chain of derivatives, whereas an energetic ReLU contributes an element of 1, which permits gradients to achieve the earliest layers of a deep community largely intact. For destructive inputs, the by-product is zero, a price we are going to return to.
The kink at zero additionally modifications what a community can signify. Every unit behaves as a change, passing a linear response when energetic and nothing when not, so a layer of ReLUs carves its enter house into areas, every with its personal linear map. Stacking layers lets later ones subdivide the partitions made by earlier ones, and the variety of areas can develop exponentially with depth[5]. That goes some solution to explaining how networks constructed from such plain items can seize extremely non-linear patterns.
These outcomes got here later, nevertheless. ReLU was adopted as a result of deep networks constructed with it skilled, usually significantly quicker than their sigmoid counterparts, and to most practitioners it seemed just like the second the sphere traded organic constancy for outcomes. An unbounded, piecewise-linear operate bore little apparent likeness to the graded, saturating response of an actual neuron.
However what of biology?
There may be an irony buried on this story, as a result of the organic case for rectification arrived on the similar second as ReLU itself. In 2011, Xavier Glorot and colleagues introduced a paper arguing that rectified models had been a greater mannequin of cortical neurons than the sigmoid had ever been[4]. As they identified, actual neurons are silent for a lot of the time and hearth sparsely after they do, with a firing charge of zero under threshold, whereas a sigmoid unit receiving no enter idles at half its most output. By that measure, the operate the sphere had prized for its realism was the much less life like of the 2.
Nor was the thought new to neuroscience. A decade earlier, Richard Hahnloser and collaborators had constructed rectification right into a cortex-inspired circuit, drawing on the brink behaviour of excitatory neurons, and confirmed that networks of rectified models may each choose amongst competing inputs and reply to them in a graded manner[6].
The case in opposition to ReLU as a organic analogue rests primarily on its unbounded output. That case is honest, since an actual neuron can not hearth quicker than its refractory interval permits and its exercise should finally saturate, however it’s narrower than ReLU’s fame for artificiality suggests. It additionally is not what determined issues. ReLU unfold as a result of it materially improved the coaching of deep networks, and the organic argument, though made in print in the intervening time of its adoption, largely dropped out of the sphere’s narrative. A neighborhood that had as soon as chosen its activation capabilities for his or her biology was handed a winner with higher organic credentials than the incumbent, and it remembered that winner as a practical hack.
The price of simplicity
ReLU’s arduous zero got here at a value. As a result of the operate outputs zero for any destructive enter, a unit can drift right into a state the place it outputs zero for each instance within the coaching knowledge, and its gradient is then zero too. The weights feeding into it cease updating. Modifications elsewhere within the community can sometimes push its inputs again into the constructive regime, however in observe such a unit hardly ever recovers. This turned referred to as the dying ReLU drawback, and in deep networks skilled with excessive studying charges it may declare a major fraction of a community’s capability[7].
The variants that adopted (see determine under) share a typical compromise, a negotiated steadiness between preserving what made ReLU efficient and repairing the factors of failure. Leaky ReLU retains a small slope for destructive inputs in order that gradients by no means fairly change off[8]. ELU replaces the arduous zero with a clean exponential curve, which additionally pulls imply activations towards zero[9]. SELU fixes ELU’s constants in order that activations have a tendency to remain normalised as they go by the community[10]. Softplus, Swish, and GELU[11] clean out the kink itself. In every case, a few of ReLU’s simplicity is traded for stability. For many feedforward and convolutional networks, plain ReLU stays a smart default, with these variants as an easy treatment when its limitations floor.
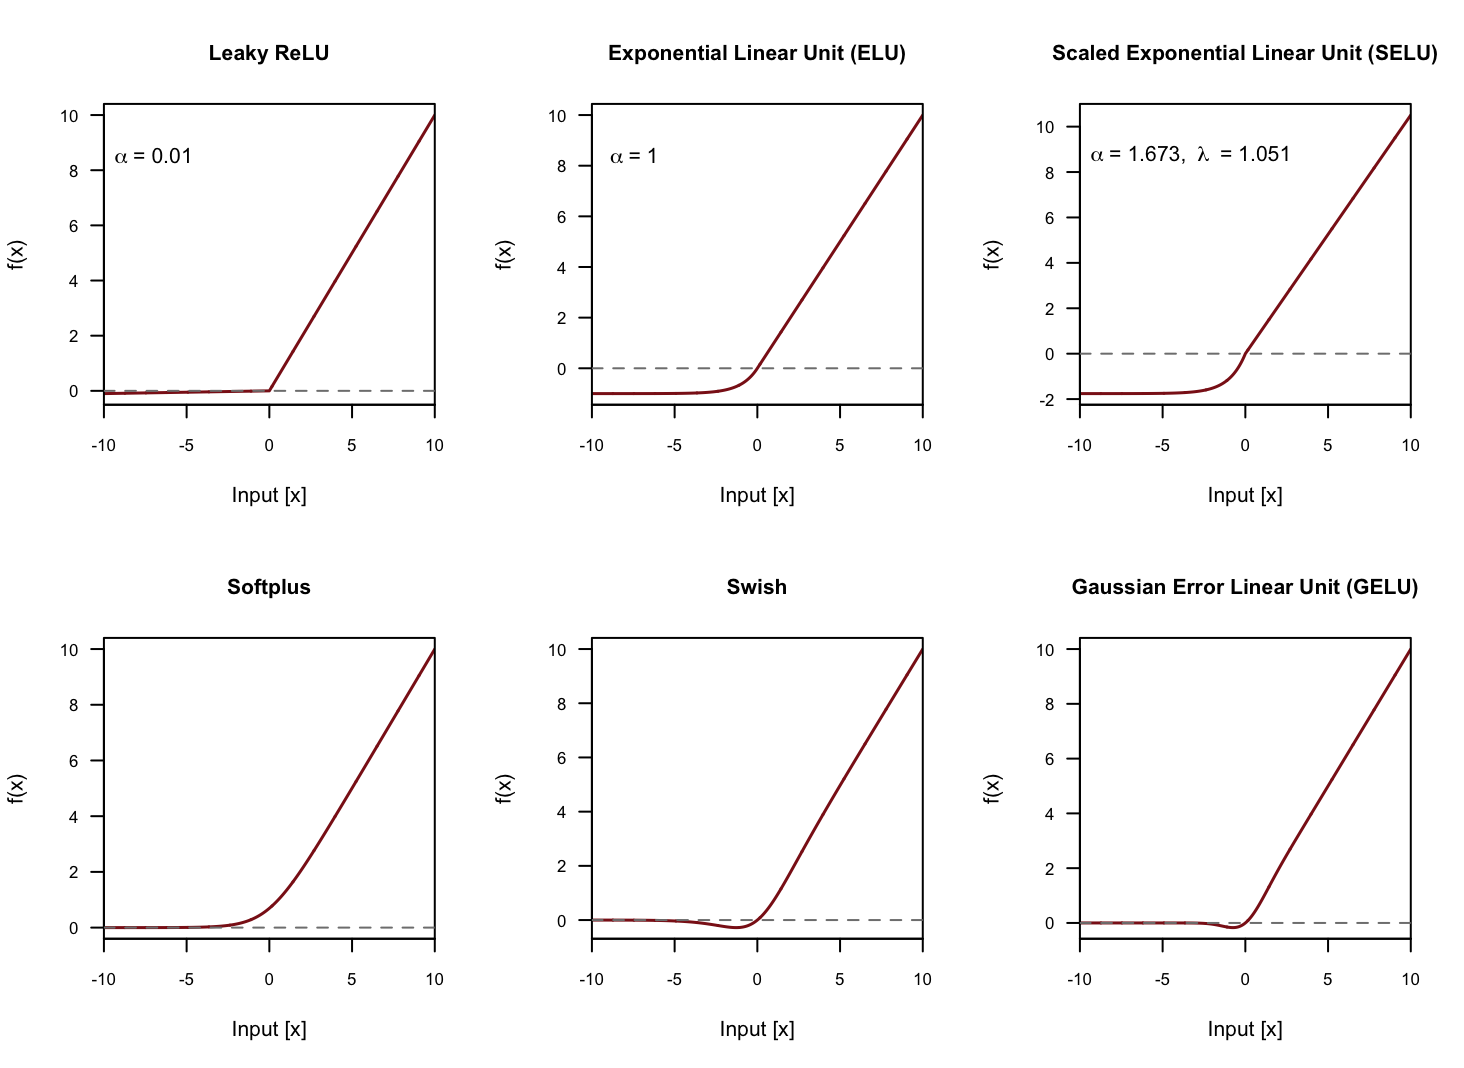
What these variants additionally share is the character of their justification. Every was motivated by gradient behaviour, coaching dynamics, or benchmark efficiency, and none by a more in-depth resemblance to actual neurons. Swish makes the purpose most plainly, because it was discovered not by reasoning about neurons however by an automatic search over candidate capabilities[12]. By this stage, the query of what a neuron ought to appear to be had shifted to a query of what trains finest.
After ReLU
In a single studying, ReLU gained. It dethroned the sigmoid in hidden layers so fully that returning to it’s now virtually unthinkable. But on the frontier it has itself been displaced. The unique transformer used ReLU[13], however its successors quickly settled on GELU[14], and lots of latest giant language fashions have since moved to gated variants equivalent to SwiGLU[15,16]. Noam Shazeer supplied no idea for why these variants work and, with some wit, attributed their success to “divine benevolence”[16]. It will be arduous to discover a extra candid assertion of the place the sphere’s priorities now lie.
The sample is a well-recognized one. The sigmoid gave solution to ReLU as a result of depth uncovered its limitations, and ReLU gave solution to GELU and its successors as a result of scale and new architectures uncovered its personal. There is no such thing as a explicit motive to assume the method has reached an finish.
What this development reveals is that the activation operate has by no means been a set organic dedication however a working speculation revised below empirical stress. The unreal neuron endures, however what it means for one to fireside has been renegotiated with every technology of architectures. Organic plausibility, it seems, was much less a design precept than a unfastened inspiration, invoked when handy and put aside when the numbers demanded it, and the story of ReLU means that was true even within the sigmoid period.
That ReLU has been displaced on the frontier doesn’t diminish what it made doable. The deep networks it enabled had been the precondition for the architectures that finally outdated it. In that sense the revolution was self-consuming: ReLU eliminated the barrier to progress, and progress, in flip, revealed its limits. That isn’t a demotion however exactly the mark of a foundational thought.
···
References
[1] Warren S. McCulloch and Walter Pitts, A logical calculus of the concepts immanent in nervous exercise (1943), Bulletin of Mathematical Biophysics.
[2] Frank Rosenblatt, The perceptron: a perceiving and recognizing automaton (1957), Cornell Aeronautical Laboratory, Inc. Report (No. 85-460-1).
[3] Vinod Nair and Geoffrey Hinton, Rectified linear models enhance restricted Boltzmann machines (2010), Proceedings of the twenty seventh Worldwide Convention on Machine Studying.
[4] Xavier Glorot, Antoine Bordes, and Yoshua Bengio, Deep sparse rectifier neural networks (2011), Proceedings of the Fourteenth Worldwide Convention on Synthetic Intelligence and Statistics.
[5] Guido Montúfar, Razvan Pascanu, Kyunghyun Cho, and Yoshua Bengio, On the variety of linear areas of deep neural networks (2014), arXiv:1402.1869 [stat.ML].
[6] Richard H. R. Hahnloser, Rahul Sarpeshkar, Misha A. Mahowald, Rodney J. Douglas, and H. Sebastian Seung, Digital choice and analogue amplification coexist in a cortex-inspired silicon circuit (2000), Nature.
[7] Lu Lu, Yeonjong Shin, Yanhui Su, and George Em Karniadakis, Dying ReLU and initialization: idea and numerical examples (2019), arXiv:1903.06733 [stat.ML].
[8] Andrew Maas, Awni Hannun, and Andrew Ng, Rectifier nonlinearities enhance neural community acoustic fashions (2013), ICML 2013 Workshop on Deep Studying for Audio, Speech and Language Processing.
[9] Djork-Arné Clevert, Thomas Unterthiner, and Sepp Hochreiter, Quick and correct deep community studying by exponential linear models (ELUs) (2015), arXiv:1511.07289 [cs.LG].
[10] Günter Klambauer, Thomas Unterthiner, Andreas Mayr, and Sepp Hochreiter, Self-normalizing neural networks (2017), arXiv:1706.02515 [cs.LG].
[11] Dan Hendrycks and Kevin Gimpel, Gaussian error linear models (GELUs) (2016), arXiv:1606.08415 [cs.LG].
[12] Prajit Ramachandran, Barret Zoph, and Quoc V. Le, Looking for activation capabilities (2017), arXiv:1710.05941 [cs.NE].
[13] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Łukasz Kaiser, and Illia Polosukhin, Consideration is all you want (2017), arXiv:1706.03762 [cs.CL].
[14] Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova, BERT: pre-training of deep bidirectional transformers for language understanding (2018), arXiv:1810.04805 [cs.CL].
[15] Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, Aurelien Rodriguez, Armand Joulin, Edouard Grave, and Guillaume Lample, LLaMA: open and environment friendly basis language fashions (2023), arXiv:2302.13971 [cs.CL].
[16] Noam Shazeer, GLU variants enhance transformer (2020), arXiv:2002.05202 [cs.LG].