

I’ve had to consider carefully about how technical outcomes are phrased, particularly when a sentence will get rewritten to sound cleaner. One straightforward mistake I’ve seen is popping a 20% discount in error right into a 20% enchancment in accuracy. A 20% lower in error shrinks a small remaining quantity, so accuracy itself can barely transfer. The quantity survives the rewrite, however what it describes modifications fully.
That type of mistake is adequately subtle to outlive a fast learn, as a result of nothing within the sentence seems misplaced. Recall can quietly develop into accuracy, a determine can drift by ten factors, or an noticed affiliation can decide up a causal verb on its method to a tidier sentence. It’s the type of mistake I needed Proof Desk to assist catch.
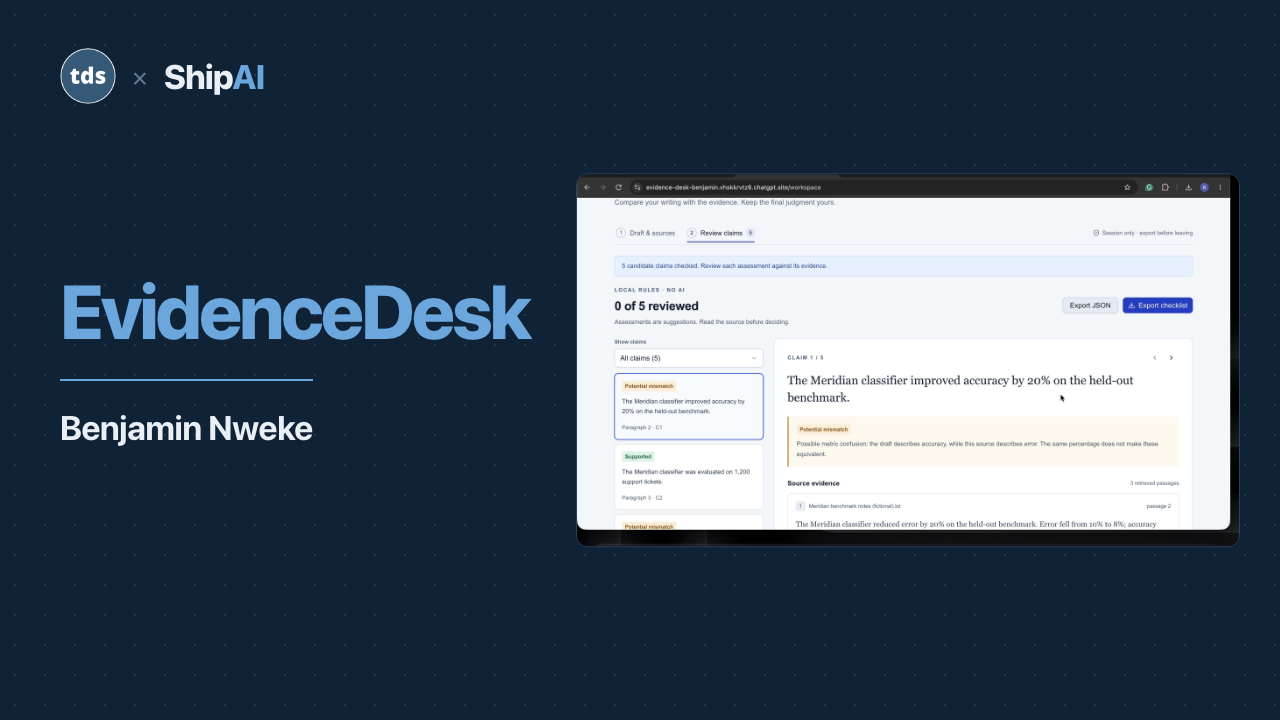
Proof Desk is a browser software I constructed with Codex. You give it a draft together with the supply information the draft got here from, and it breaks the draft into claims. For every declare, it finds the closest passage within the sources and runs a number of express checks in opposition to it; it returns considered one of three labels: Supported, Potential mismatch, or Inadequate proof.
I used Codex to assist implement the interface, the checking logic, the assessments, and the remainder of the applying across the workflow I already had in thoughts. My half was deciding what the software ought to verify and reviewing whether or not its conduct matched that objective.
The error-versus-accuracy instance above comes from the software’s built-in fictional pattern, which facilities on a made-up classifier known as Meridian and in addition seems to be the clearest image of the place a software like this stops being dependable.
Checking is a unique job from writing
A mannequin that writes properly is aiming at believable textual content. Checking asks a couple of relationship: does this physique of proof really say what the declare says? That could be a smaller query than whether or not the declare is true. A supply may be unsuitable whereas a declare stays trustworthy to it, and for technical writing the faithfulness half is normally the one which bites first.
You might ask a second mannequin to overview the primary, and that may work properly. I’m not arguing in opposition to it. The trade-off I see is that the reviewer is generative too, and its verdict could arrive with no cause you possibly can argue with. Proof Desk takes the narrower highway as an alternative, and each warning comes with the passage it’s primarily based on and a cause, so the author has one thing particular to push again on.
The pipeline
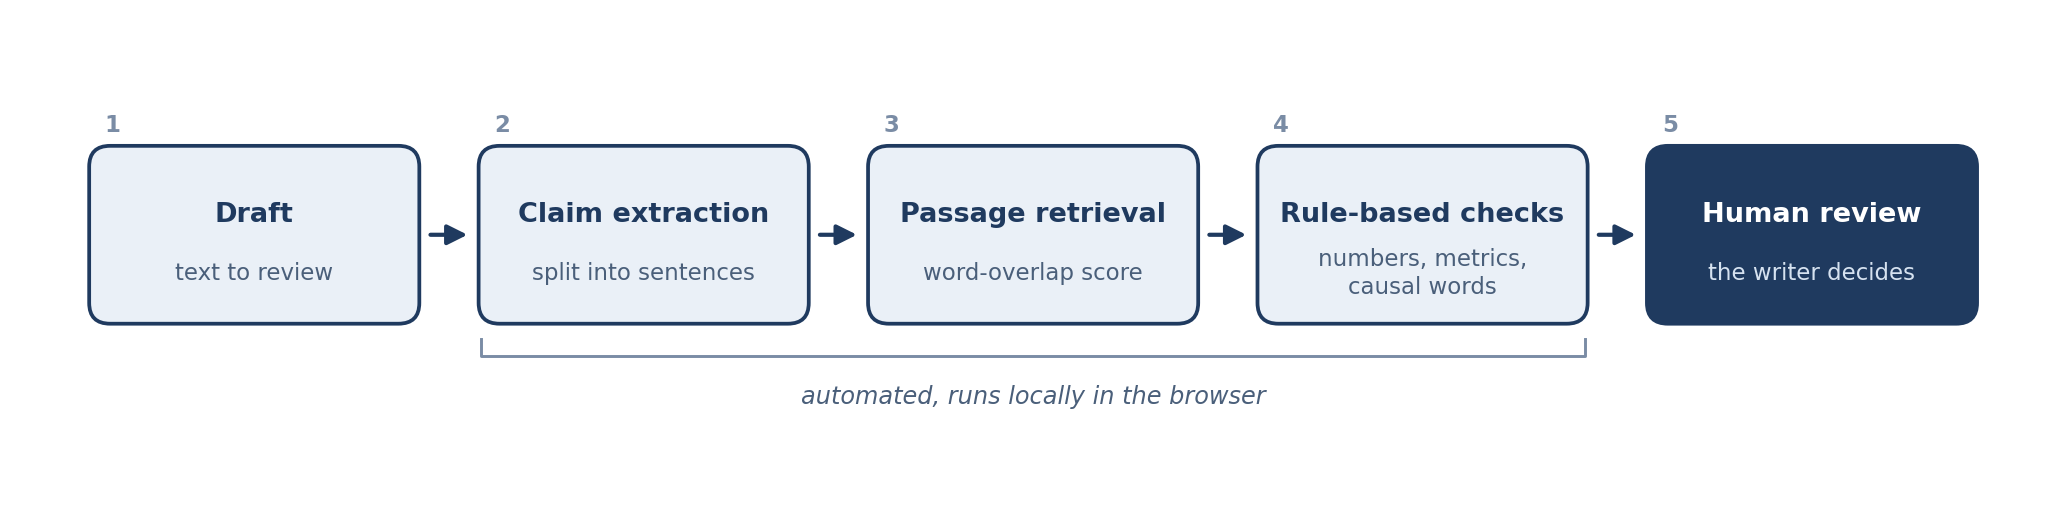
Declare extraction is intentionally crude. It splits on sentence boundaries and clean traces, drops headings and something below 5 phrases, and retains at most 40 candidates. All of it runs within the browser, and the overview path makes no community requests.
A excessive rating proves little or no
Retrieval is apparent lexical overlap, brief sufficient to point out right here (condensed from proof.ts, conduct unchanged):
At 0.25 a passage counts as proof in any respect, and at 0.48 a declare may be known as Supported. Each thresholds are hand-set, not calibrated. It’s a phrase ratio, not semantic similarity, and it’s definitely not the likelihood that the declare is true.
The Meridian accuracy declare exhibits why that issues. In opposition to the error passage, it scores 86, the best of any passage, as a result of the draft was written from that passage. A excessive rating tells you ways carefully a sentence was derived from its supply, and a distorted rewrite is a detailed derivation by definition. Retrieval discovered the proper paragraph. It had no method to discover that the paragraph disagreed.
What the checks add, and what they miss
Three checks sit on high. The numeric verify pulls figures out of the declare and the retrieved passage, strips commas and areas, and complains about any declare determine the passage doesn’t comprise. The metric verify seems for mixed-up analysis phrases. The causal verify seems for phrases like “induced” and “led to” within the declare and expects the passage to have one too.
The numeric verify pays for itself. The declare that the classifier achieved a recall of 95% retrieves the sentence reporting 85%, and the warning that 95% seems nowhere within the proof is right. Actual matching is blunt, but it surely catches a modified quantity.
That bluntness cuts each methods, although, as a result of the identical verify can overreach on a declare that’s really effective.
After I examined the software in opposition to an article, a sentence containing each 84% and 60% got here again with a numeric warning, and the rationale was fairly easy: the retrieved passage solely held a type of figures. The verify treats a lacking determine as a mismatch, full cease, with out permitting for the truth that the proof could have been cut up throughout two passages, and the rule within the repository nonetheless works that manner.
What I might slightly see is a software that claims it can’t set up a determine than one which flags it with confidence. I care a bit much less about whether or not the interface fingers again a verdict and much more about whether or not I can defend the reasoning behind it.
The metric verify is the place the design runs out. Right here it’s, condensed from proof.ts with conduct unchanged:
It fires solely when the declare’s first metric phrase is lacking from the retrieved passage. The Meridian passage mentions accuracy in its second sentence, so it stays quiet, as does the numeric verify, which sees 20% on each side.
Working the engine on the pattern draft returns Supported, with a rating of 86, for the accuracy declare. Nothing ties the determine to the amount it measures. Within the supply the 20% belongs to error, within the draft it belongs to accuracy, and each checks deal with the passage as a bag of phrases and numbers.
I anticipated the pattern to be a fast method to see whether or not the checker was doing its job. As an alternative, the consequence on the display was not what the engine returned for a similar declare and supply. The pattern carries a saved overview, so it exhibits Potential mismatch for the accuracy declare, whereas operating the identical textual content by way of the precise checking logic returns Supported.
That was a clumsy factor to find in a software whose entire objective is to assist folks confirm claims. The interface was exhibiting the consequence I needed to see, and it was not exhibiting that the engine may produce it.
The causal verify has a blind spot of its personal. Within the pattern, the declare that utilizing the research assistant induced larger examination scores pulls up the passage concerning the rating distinction, which has no causal phrase in it, so the declare will get flagged. That appears just like the verify working.
The sentence that really issues is within the subsequent passage, and it says the consequence doesn’t set up that the assistant induced the distinction. So the phrase “induced” is there, simply inside a negation. Reword the declare as “The assistant induced the rating distinction between college students,” and retrieval lands on precisely that sentence, so the declare comes again Supported at 50.
Key phrase matching has no thought what a negation is, and the pattern solely catches its causal declare due to which passage occurred to rank first.
A candidate repair, which isn’t but within the repository, would make three small modifications: strip trailing punctuation when tokenizing, require every matched determine to take a seat in the identical sentence because the declare’s metric phrase, and deal with a causal key phrase inside a negated clause as absent.
A prototype of that clears each failure described right here, and the three present assessments nonetheless move. It will nonetheless be a heuristic, as a result of a determine and its metric can simply sit in several sentences.
Saying “not sufficient proof”
Supported means the strongest retrieved passage cleared the checks. Potential mismatch means a verify fired or the overlap was weak. Inadequate proof means no passage reached 0.25, and it ought to by no means be learn as “false.”
The declare {that a} mannequin obtained higher at recognizing uncommon circumstances scores zero in opposition to a supply saying recall on the minority class rose from 0.41 to 0.58. The software experiences that it discovered nothing, which is the sincere output for a paraphrase it can’t learn.
For every declare the interface exhibits the retrieved passage, the highest three candidates, and the rationale. It may well nonetheless mislead you. A Potential mismatch with overlap between 25 and 48 arrives with no cause in any respect, as a result of the weak-overlap rule doesn’t give one.
The place it breaks
Lexical matching misses paraphrase fully, as that zero exhibits, and the tokenizer retains a trailing interval connected to the final phrase of a sentence. A declare ending in “college students.” doesn’t match “college students” mid-passage, which is how the declare that the pilot included 84 college students retrieves the doc title and earns a numeric warning for the unsuitable cause.
The engine has no overstatement verify in any respect, so “all the time achieved a recall of 85%” passes as Supported. Claims are single sentences, so a pronoun or determine outlined earlier loses its context, and the 40-claim cap drops the remainder of an extended draft.
The assessments set up lower than the interface suggests. There are three, and none of them touches the metric verify, the causal verify, or the thresholds. There isn’t a benchmark for the way usually the warnings are proper, and I’m not going to faux there’s one.
A trustworthy declare checked in opposition to a unsuitable supply passes cleanly too, as a result of the software compares claims with the equipped materials and nothing else.
···
What I might take from this
Writing a sentence and checking its proof are separate steps, they usually fail in separate methods.
A excessive overlap rating solely exhibits {that a} draft was constructed from a passage, so retrieval can land on the proper paragraph and nonetheless miss that it disagrees.
Matching numbers just isn’t sufficient both, as a result of a determine must be tied to the factor it measures earlier than a swap like error for accuracy exhibits up. I might slightly ship a checker that’s clear about these limits than one which returns a assured verdict.
Used as an inspection help, a software like this earns its place by narrowing a draft to the claims price rereading. It stops being helpful the second anybody reads its verdict as the reality.
The code is on GitHub, and the ShipAI walkthrough exhibits the interface in use.