On this article, you’ll be taught what software calling and code execution are as agent motion primitives, how they differ mechanically, and when to decide on one over the opposite.
Subjects we are going to cowl embrace:
- How software calling works beneath the hood, and why it stays the precise alternative for single, time-sensitive lookups.
- How code execution by way of Programmatic Instrument Calling differs from normal software calling, and what measurable advantages it gives for fan-out and aggregation duties.
- A sensible determination framework for selecting between the 2 primitives based mostly on name rely, information sensitivity, latency, infrastructure, and auditability wants.
Image an agent asking one simple-sounding query: which of twenty staff went over their Q3 journey finances. To reply it, the agent wants every individual’s expense line gadgets, each flight, lodge, and meal receipt, in contrast in opposition to a finances restrict tied to their degree. Constructed the plain method, with the mannequin calling a software for every individual’s bills one by one, that’s twenty separate software calls, every returning fifty to 100 line gadgets, and each single a kind of gadgets has to cross by the mannequin’s context simply so it may be added up. That’s over 2,000 line gadgets and greater than 50KB of uncooked information the mannequin by no means really wanted to learn — it wanted a sum.
That’s the actual price hiding behind a design determination most agent tutorials skip previous fully: how does an agent really take motion on this planet. There are two actual solutions, software calling and code execution, and which one you attain for isn’t a mode choice — it’s an architectural alternative with measurable penalties for price, latency, and accuracy. This text breaks down each motion primitives for AI brokers intimately, builds an actual, runnable instance of every utilizing the identical underlying software, and closes with an sincere, numbers-backed framework for selecting between them. In the event you haven’t constructed a fundamental tool-calling agent but, try this text, Simple Agentic Instrument Calling with Gemma 4 — it’s the pure place to start out earlier than this one.
What Is an Motion Primitive, and Why Does the Selection Matter?
An motion primitive is the elemental mechanism by which a language mannequin turns a call into an actual impact on this planet — a database write, an API name, a file learn. Each agent framework, no matter else it does, is constructed on prime of certainly one of these primitives at its core.
Instrument calling is the primitive most individuals be taught first: the mannequin produces one structured request at a time, a bunch software executes it, and the consequence comes again into the dialog earlier than the mannequin decides what to do subsequent. Code execution is the newer various: as an alternative of requesting one motion and ready, the mannequin writes an precise program — in Python or TypeScript — that performs a number of actions in sequence or in parallel, and solely this system’s ultimate output returns to the mannequin.
Neither one is a wrapper across the different, and neither has quietly changed the opposite. They’re genuinely completely different mechanisms with completely different failure modes, completely different infrastructure necessities, and completely different price profiles, and the remainder of this text is about understanding each properly sufficient to choose accurately.
Instrument Calling
It’s value understanding what’s really occurring beneath a software name, as a result of the mechanics clarify each its strengths and its actual limitations. Based on Cloudflare’s detailed breakdown of the method, a mannequin producing a software name doesn’t produce strange textual content. It’s been particularly educated to output a pair of particular tokens — one signaling “the next is a software name” and one other marking its finish — with a JSON payload describing the software title and arguments sitting between them. The appliance working the mannequin watches for these tokens, pauses technology the second it sees the closing one, parses the JSON in opposition to a schema you outlined, really executes the decision, and feeds the consequence again into the dialog as if it had been the subsequent factor the person mentioned.
That’s a clear, auditable, one-step-at-a-time loop, and it’s precisely why software calling grew to become the default. Each motion is a discrete, loggable occasion. Each result’s one thing the mannequin immediately sees and might cause about in pure language earlier than deciding what occurs subsequent.
Code Execution
Code execution takes a distinct beginning place fully: as an alternative of asking the mannequin to explain an motion in a constrained JSON format, you let it write precise code that performs the motion, working in a sandboxed atmosphere separate from the mannequin itself. Anthropic’s authentic code-execution-with-MCP sample frames this exactly as presenting your instruments as a code API moderately than a set of immediately callable features, so the mannequin can write a script that imports precisely the instruments it wants and calls them the way in which it could name every other operate.
The mechanism that makes this genuinely completely different — not only a relabeled software name — is what Anthropic now calls Programmatic Instrument Calling, launched alongside two companion options in November 2025. Fairly than every software consequence flowing again by the mannequin one by one, you mark particular instruments as callable from code by including an allowed_callers subject to their definition, and add a code_execution software to the request. When the mannequin needs to behave, it writes a full script — loops, conditionals, error dealing with, and all — that calls these instruments immediately inside a sandboxed execution atmosphere. Every particular person software name the script makes nonetheless executes precisely the way in which it could in strange software calling; you continue to obtain a request and return a consequence, however that result’s intercepted and processed by the working script moderately than being pushed into the mannequin’s context. Solely when the script finishes does its ultimate output — and nothing else — return to the mannequin.
That’s the whole distinction in a single sentence: software calling places each intermediate lead to entrance of the mannequin; code execution lets the mannequin resolve, by the code it writes, precisely what makes it again.
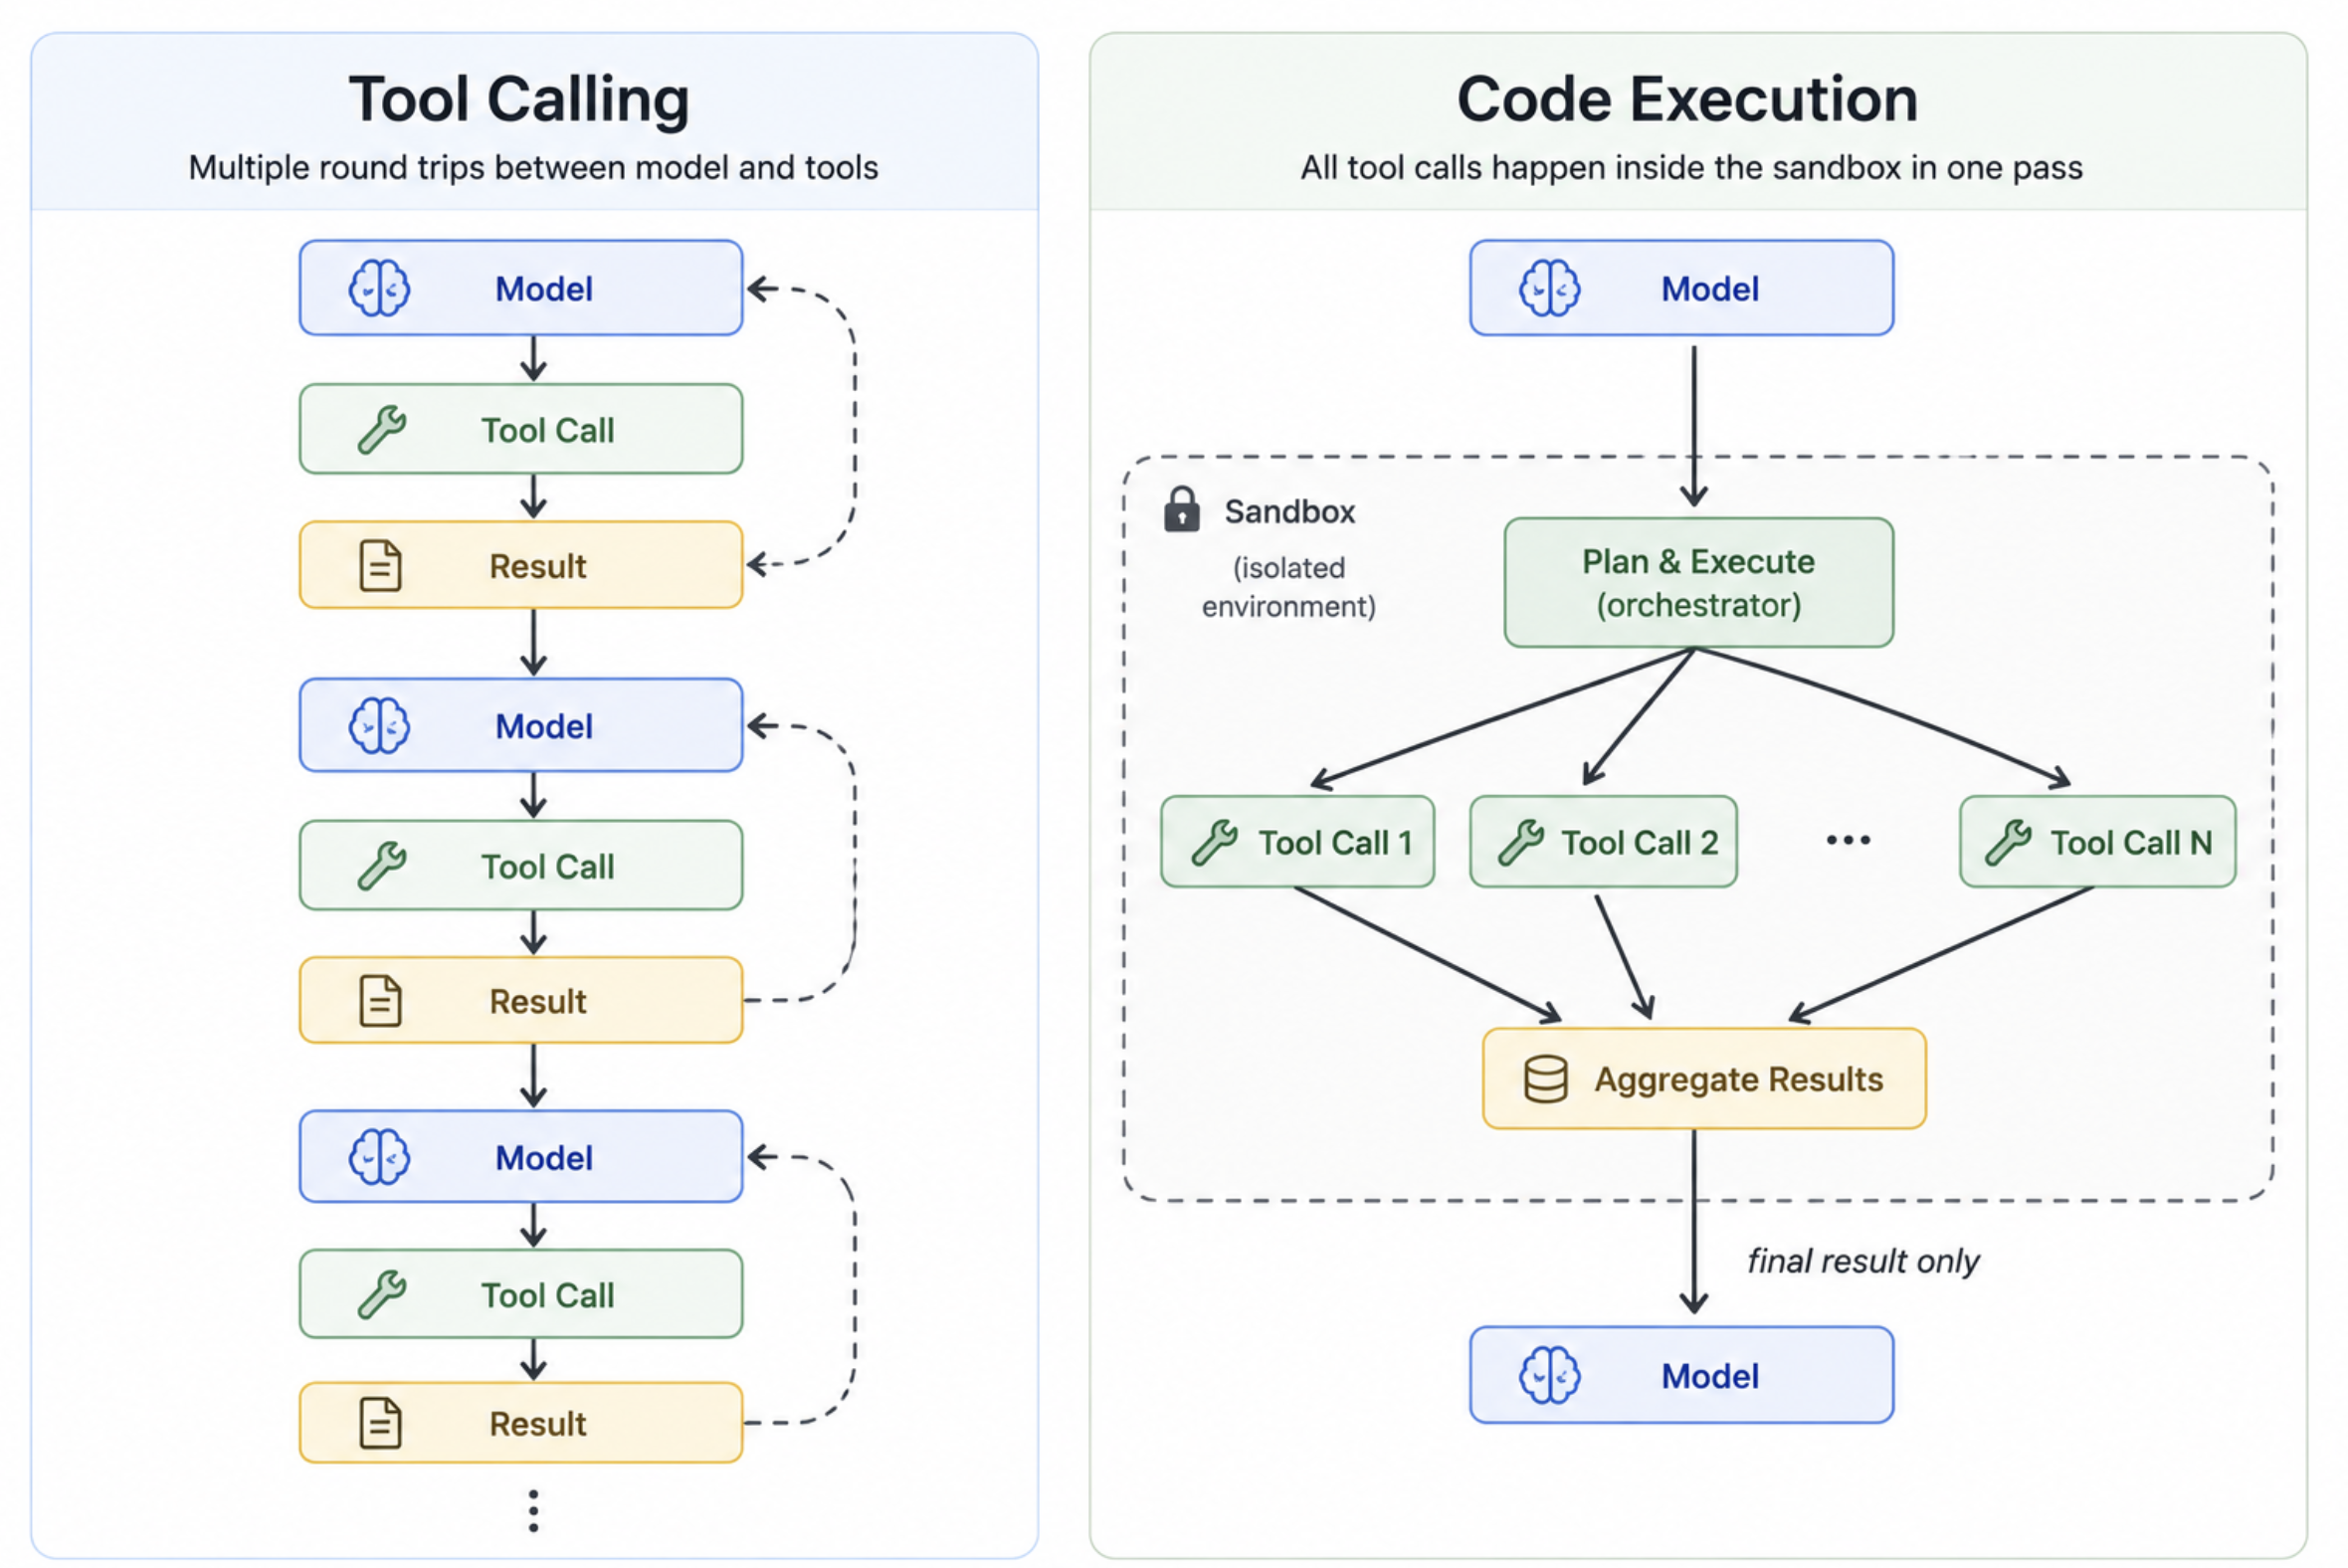
A side-by-side movement diagram of Instrument Calling and Code Execution (click on to enlarge)
Instrument Calling for a Single, Time-Delicate Lookup
Idea is simpler to belief as soon as it’s working in opposition to an actual API, so each examples on this article use the identical software — a get_weather operate backed by Open-Meteo, a free climate API that wants no API key in any respect, solely an Anthropic API key to run the agent itself.
Begin with the case software calling is clearly proper for: a single query that wants one lookup and a natural-language reply — “what’s the climate like in London proper now.”
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 |
import json import requests from anthropic import Anthropic
consumer = Anthropic() # reads ANTHROPIC_API_KEY from the atmosphere
def get_weather(metropolis: str) -> dict: “”“Lookup a metropolis’s coordinates, then fetch its present temperature and this week’s every day highs from Open-Meteo’s free, keyless API.”“” geo = requests.get( “https://geocoding-api.open-meteo.com/v1/search”, params={“title”: metropolis, “rely”: 1}, ).json() if not geo.get(“outcomes”): return {“error”: f“Couldn’t discover a location named ‘{metropolis}'”} lat = geo[“results”][0][“latitude”] lon = geo[“results”][0][“longitude”]
forecast = requests.get( “https://api.open-meteo.com/v1/forecast”, params={ “latitude”: lat, “longitude”: lon, “present”: “temperature_2m”, “every day”: “temperature_2m_max”, “timezone”: “auto”, }, ).json()
return { “metropolis”: metropolis, “current_temp_c”: forecast[“current”][“temperature_2m”], “week_high_temps_c”: forecast[“daily”][“temperature_2m_max”], “unit”: “celsius”, }
weather_tool = { “title”: “get_weather”, “description”: ( “Get the present temperature and this week’s every day excessive “ “temperatures for a metropolis. Returns JSON with metropolis, “ “current_temp_c, week_high_temps_c (7 every day highs), and unit.” ), “input_schema”: { “sort”: “object”, “properties”: { “metropolis”: {“sort”: “string”, “description”: “Metropolis title, e.g. ‘Lagos'”} }, “required”: [“city”], }, }
messages = [{“role”: “user”, “content”: “What’s the weather like in London right now?”}]
response = consumer.messages.create( mannequin=“claude-sonnet-5”, max_tokens=1024, instruments=[weather_tool], messages=messages, )
# Preserve resolving software calls till Claude produces a ultimate textual content reply whereas response.stop_reason == “tool_use”: messages.append({“position”: “assistant”, “content material”: response.content material}) tool_results = []
for block in response.content material: if block.sort == “tool_use” and block.title == “get_weather”: consequence = get_weather(**block.enter) tool_results.append({ “sort”: “tool_result”, “tool_use_id”: block.id, “content material”: json.dumps(consequence), })
messages.append({“position”: “person”, “content material”: tool_results}) response = consumer.messages.create( mannequin=“claude-sonnet-5”, max_tokens=1024, instruments=[weather_tool], messages=messages, )
for block in response.content material: if block.sort == “textual content”: print(block.textual content) |
Strolling by what issues right here: get_weather itself is strange Python — nothing agent-specific about it — it geocodes a metropolis title and pulls each the present temperature and the week’s every day highs in a single request. The weather_tool dictionary is the schema Claude really sees, and the outline issues greater than it appears to be like — a imprecise description is among the most typical causes of a mannequin calling a software with the unsuitable arguments. The whereas response.stop_reason == “tool_use” loop is the actual mechanical coronary heart of normal software calling: each time Claude requests the software, your code has to really run it, wrap the consequence as a tool_result block, append it to the dialog, and name the API once more — and this repeats for as many software calls as the duty wants. For a single lookup like this one, that’s one cross by the loop and carried out, which is strictly why software calling suits this case properly: one name, one consequence, and a consequence small and related sufficient that Claude genuinely advantages from seeing it immediately earlier than writing a natural-language reply.
Code Execution for Fan-Out and Aggregation
Now change the query, utilizing the very same get_weather operate — utterly unchanged: “given these fifteen cities, which one may have the coldest excessive temperature this week, and what’s the typical weekly excessive throughout all of them?”
Run that by the tool-calling loop above and also you’d get fifteen separate software calls, fifteen full JSON payloads of every day temperatures pushed into Claude’s context, and Claude would then need to manually evaluate and common them in pure language — sluggish, token-expensive, and precisely the form of arithmetic a mannequin is extra error-prone at than a for-loop is. That is exactly the case Programmatic Instrument Calling was constructed for.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 |
import json from anthropic import Anthropic
consumer = Anthropic()
# Identical get_weather operate from the earlier instance, unchanged
weather_tool = { “title”: “get_weather”, “description”: ( “Get the present temperature and this week’s every day excessive “ “temperatures for a metropolis. Returns JSON with metropolis, “ “current_temp_c, week_high_temps_c (7 every day highs), and unit.” ), “input_schema”: { “sort”: “object”, “properties”: { “metropolis”: {“sort”: “string”, “description”: “Metropolis title, e.g. ‘Lagos'”} }, “required”: [“city”], }, # That is the one line that adjustments the primitive: it opts the software # into being known as from inside generated code, not solely immediately # by the mannequin “allowed_callers”: [“code_execution_20250825”], }
code_execution_tool = {“sort”: “code_execution_20250825”, “title”: “code_execution”}
cities = [ “Lagos”, “Nairobi”, “Cairo”, “Accra”, “Kigali”, “Casablanca”, “Addis Ababa”, “Dakar”, “Tunis”, “Kampala”, “Harare”, “Lusaka”, “Maputo”, “Windhoek”, “Gaborone”, ]
messages = [{ “role”: “user”, “content”: ( f“Given these cities: {‘, ‘.join(cities)}, which one will have “ “the coldest high temperature this week, and what’s the average “ “weekly high across all of them? Use the get_weather tool.” ), }]
response = consumer.beta.messages.create( betas=[“advanced-tool-use-2025-11-20”], mannequin=“claude-sonnet-5”, max_tokens=2048, instruments=[code_execution_tool, weather_tool], messages=messages, )
# The loop appears to be like just like normal software calling, however now some # tool_use blocks carry a “caller” subject, which means the request got here # from inside Claude’s generated script moderately than from Claude immediately whereas response.stop_reason == “tool_use”: messages.append({“position”: “assistant”, “content material”: response.content material}) tool_results = []
for block in response.content material: if block.sort == “tool_use” and block.title == “get_weather”: consequence = get_weather(**block.enter) tool_results.append({ “sort”: “tool_result”, “tool_use_id”: block.id, “content material”: json.dumps(consequence), })
if tool_results: messages.append({“position”: “person”, “content material”: tool_results})
response = consumer.beta.messages.create( betas=[“advanced-tool-use-2025-11-20”], mannequin=“claude-sonnet-5”, max_tokens=2048, instruments=[code_execution_tool, weather_tool], messages=messages, )
for block in response.content material: if block.sort == “textual content”: print(block.textual content) |
The only most essential line on this complete script is “allowed_callers”: [“code_execution_20250825”]. With out it, the software behaves precisely because it did within the earlier instance — callable solely immediately by the mannequin. With it added, Claude features the choice to jot down a script that calls get_weather fifteen occasions itself, doubtless in parallel utilizing asyncio.collect, sum and type the outcomes, and print solely the ultimate reply — the coldest metropolis and the typical — to plain output. Your Python code doesn’t change the way it responds to particular person software calls in any respect; that a part of the loop appears to be like practically an identical to the tool-calling instance. What adjustments is invisible out of your aspect of the API: fourteen of these fifteen climate lookups, and each intermediate comparability between them, by no means contact Claude’s context.
Claude solely ever sees the 2 numbers it really requested for. Since this makes use of a beta characteristic, it’s value double-checking the precise beta header string and block-handling particulars in opposition to Anthropic’s present documentation earlier than counting on it in manufacturing, as beta APIs are the a part of any platform most probably to shift.
Why Code Execution Wins at Scale
The climate instance makes the mechanism seen, but it surely’s value backing this up with actual, printed figures moderately than instinct alone. Anthropic’s authentic code-execution-with-MCP sample took an actual Google Drive-to-Salesforce workflow from 150,000 tokens all the way down to 2,000 — a 98.7% discount — just by retaining a full assembly transcript contained in the execution atmosphere as an alternative of routing it by the mannequin twice.
Programmatic Instrument Calling’s personal inner benchmarking, reported immediately by Anthropic, discovered common token utilization on complicated analysis duties dropped from 43,588 to 27,297 — a 37% discount — whereas accuracy on the GAIA benchmark really improved, rising from 46.5% to 51.2%, and inner data retrieval accuracy rose from 25.6% to twenty-eight.5%. That final element issues greater than the token financial savings alone: this isn’t purely a price optimization. Offloading orchestration logic to precise code moderately than asking a mannequin to trace it by pure language measurably reduces the form of errors that come from a mannequin shedding observe of a dozen intermediate values it’s making an attempt to check in its head.
The tutorial consequence beneath all of this predates Anthropic’s personal tooling. The unique CodeAct paper from Wang and colleagues in 2024 discovered that brokers taking motion by executable code, moderately than JSON-formatted software calls, succeeded as much as 20% extra typically on complicated, multi-step duties. Code execution isn’t a latest product characteristic bolted onto an present concept — it’s a research-backed sample that the most important labs have spent the previous two years turning into manufacturing infrastructure.
The place Instrument Calling Nonetheless Wins
The numbers above could make code execution seem like an unconditional improve, and it isn’t one. There’s an actual, sincere case for sticking with plain software calling in a significant set of conditions.
Single-call duties are the clearest case. The Lagos climate instance earlier on this article features nothing from a sandbox — one name, one small consequence, and the overhead of spinning up a code execution atmosphere provides latency with out including any actual profit. Duties the place the mannequin genuinely must cause over an intermediate lead to pure language are the second case: if the precise level of a step is for the mannequin to note one thing refined in a doc or a dataset and reply to it conversationally, filtering that information away in a sandbox defeats the aim. Easier infrastructure is an actual, sensible issue too — a group with out an present safe sandboxing setup takes on actual operational price standing one up, and that price must be weighed in opposition to the financial savings, not assumed away. And auditability issues greater than it will get credit score for: a software name is one clear, loggable occasion with a reputation and a set of arguments, whereas reasoning about precisely what a generated script did internally — particularly after the actual fact, throughout an incident — is a genuinely more durable debugging downside.
Resolution Framework: Selecting the Proper Primitive
Pulling all the pieces above into one sensible reference:
| Issue | Favors software calling | Favors code execution |
|---|---|---|
| Variety of calls wanted | One, or a small, fastened few | A number of, particularly with fan-out or aggregation |
| What occurs to outcomes | The mannequin must learn and cause over them immediately | They simply must be filtered, summed, or in contrast |
| Information sensitivity | Low — nothing problematic concerning the mannequin seeing it | Excessive — PII or massive payloads higher saved out of context |
| Latency tolerance | Tight — sandbox startup isn’t value paying for | Workflow already includes a number of round-trips anyway |
| Crew infrastructure | No present sandboxing setup | Sandbox or code-execution tooling already in place |
| Auditability wants | Each discrete motion should be individually logged | Mixture final result issues greater than every inner step |
The Hybrid Actuality: Most Manufacturing Brokers Use Each
It’s value closing this out by pushing again gently on the framing of the article’s personal title. In apply, this isn’t a everlasting, once-and-for-all architectural determination — it’s a per-task judgment name, and Anthropic’s personal steering treats it precisely that method. Their superior software use launch shipped Programmatic Instrument Calling alongside two companion options particularly meant to be layered collectively as wanted: a Instrument Search Instrument for locating the precise software out of a giant library with out loading each definition upfront, and Instrument Use Examples for educating a mannequin the conventions a schema alone can’t categorical. Their very own advice is to start out with whichever bottleneck is definitely limiting a given agent — context bloat from too many software definitions, massive intermediate outcomes polluting context, or parameter errors — and add the matching characteristic, moderately than reaching for each functionality on day one.
A single well-built agent, in apply, tends to make use of plain software calling for its easy, single-shot lookups and change to code execution the second a process requires fan-out, aggregation, or dealing with information too massive or delicate to place in entrance of the mannequin immediately. The precise ability value constructing isn’t choosing a primitive as soon as — it’s recognizing, process by process, which one the work in entrance of you really wants.
Conclusion
An motion primitive is infrastructure, not a choice, and the 2 examples constructed on this article show it with the identical fifteen strains of software definition beneath each. Get it proper and an agent handles a fan-out process throughout fifteen cities — or two thousand expense line gadgets — in a single clear cross. Get it unsuitable — attain for software calling on a process that wants code execution — and nothing crashes. The agent nonetheless solutions. It simply does it slower, extra expensively, and with a context window quietly stuffed with information no one really wanted to learn.
On this article, you’ll be taught what software calling and code execution are as agent motion primitives, how they differ mechanically, and when to decide on one over the opposite.
Subjects we are going to cowl embrace:
- How software calling works beneath the hood, and why it stays the precise alternative for single, time-sensitive lookups.
- How code execution by way of Programmatic Instrument Calling differs from normal software calling, and what measurable advantages it gives for fan-out and aggregation duties.
- A sensible determination framework for selecting between the 2 primitives based mostly on name rely, information sensitivity, latency, infrastructure, and auditability wants.
Image an agent asking one simple-sounding query: which of twenty staff went over their Q3 journey finances. To reply it, the agent wants every individual’s expense line gadgets, each flight, lodge, and meal receipt, in contrast in opposition to a finances restrict tied to their degree. Constructed the plain method, with the mannequin calling a software for every individual’s bills one by one, that’s twenty separate software calls, every returning fifty to 100 line gadgets, and each single a kind of gadgets has to cross by the mannequin’s context simply so it may be added up. That’s over 2,000 line gadgets and greater than 50KB of uncooked information the mannequin by no means really wanted to learn — it wanted a sum.
That’s the actual price hiding behind a design determination most agent tutorials skip previous fully: how does an agent really take motion on this planet. There are two actual solutions, software calling and code execution, and which one you attain for isn’t a mode choice — it’s an architectural alternative with measurable penalties for price, latency, and accuracy. This text breaks down each motion primitives for AI brokers intimately, builds an actual, runnable instance of every utilizing the identical underlying software, and closes with an sincere, numbers-backed framework for selecting between them. In the event you haven’t constructed a fundamental tool-calling agent but, try this text, Simple Agentic Instrument Calling with Gemma 4 — it’s the pure place to start out earlier than this one.
What Is an Motion Primitive, and Why Does the Selection Matter?
An motion primitive is the elemental mechanism by which a language mannequin turns a call into an actual impact on this planet — a database write, an API name, a file learn. Each agent framework, no matter else it does, is constructed on prime of certainly one of these primitives at its core.
Instrument calling is the primitive most individuals be taught first: the mannequin produces one structured request at a time, a bunch software executes it, and the consequence comes again into the dialog earlier than the mannequin decides what to do subsequent. Code execution is the newer various: as an alternative of requesting one motion and ready, the mannequin writes an precise program — in Python or TypeScript — that performs a number of actions in sequence or in parallel, and solely this system’s ultimate output returns to the mannequin.
Neither one is a wrapper across the different, and neither has quietly changed the opposite. They’re genuinely completely different mechanisms with completely different failure modes, completely different infrastructure necessities, and completely different price profiles, and the remainder of this text is about understanding each properly sufficient to choose accurately.
Instrument Calling
It’s value understanding what’s really occurring beneath a software name, as a result of the mechanics clarify each its strengths and its actual limitations. Based on Cloudflare’s detailed breakdown of the method, a mannequin producing a software name doesn’t produce strange textual content. It’s been particularly educated to output a pair of particular tokens — one signaling “the next is a software name” and one other marking its finish — with a JSON payload describing the software title and arguments sitting between them. The appliance working the mannequin watches for these tokens, pauses technology the second it sees the closing one, parses the JSON in opposition to a schema you outlined, really executes the decision, and feeds the consequence again into the dialog as if it had been the subsequent factor the person mentioned.
That’s a clear, auditable, one-step-at-a-time loop, and it’s precisely why software calling grew to become the default. Each motion is a discrete, loggable occasion. Each result’s one thing the mannequin immediately sees and might cause about in pure language earlier than deciding what occurs subsequent.
Code Execution
Code execution takes a distinct beginning place fully: as an alternative of asking the mannequin to explain an motion in a constrained JSON format, you let it write precise code that performs the motion, working in a sandboxed atmosphere separate from the mannequin itself. Anthropic’s authentic code-execution-with-MCP sample frames this exactly as presenting your instruments as a code API moderately than a set of immediately callable features, so the mannequin can write a script that imports precisely the instruments it wants and calls them the way in which it could name every other operate.
The mechanism that makes this genuinely completely different — not only a relabeled software name — is what Anthropic now calls Programmatic Instrument Calling, launched alongside two companion options in November 2025. Fairly than every software consequence flowing again by the mannequin one by one, you mark particular instruments as callable from code by including an allowed_callers subject to their definition, and add a code_execution software to the request. When the mannequin needs to behave, it writes a full script — loops, conditionals, error dealing with, and all — that calls these instruments immediately inside a sandboxed execution atmosphere. Every particular person software name the script makes nonetheless executes precisely the way in which it could in strange software calling; you continue to obtain a request and return a consequence, however that result’s intercepted and processed by the working script moderately than being pushed into the mannequin’s context. Solely when the script finishes does its ultimate output — and nothing else — return to the mannequin.
That’s the whole distinction in a single sentence: software calling places each intermediate lead to entrance of the mannequin; code execution lets the mannequin resolve, by the code it writes, precisely what makes it again.
A side-by-side movement diagram of Instrument Calling and Code Execution (click on to enlarge)
Instrument Calling for a Single, Time-Delicate Lookup
Idea is simpler to belief as soon as it’s working in opposition to an actual API, so each examples on this article use the identical software — a get_weather operate backed by Open-Meteo, a free climate API that wants no API key in any respect, solely an Anthropic API key to run the agent itself.
Begin with the case software calling is clearly proper for: a single query that wants one lookup and a natural-language reply — “what’s the climate like in London proper now.”
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 |
import json import requests from anthropic import Anthropic
consumer = Anthropic() # reads ANTHROPIC_API_KEY from the atmosphere
def get_weather(metropolis: str) -> dict: “”“Lookup a metropolis’s coordinates, then fetch its present temperature and this week’s every day highs from Open-Meteo’s free, keyless API.”“” geo = requests.get( “https://geocoding-api.open-meteo.com/v1/search”, params={“title”: metropolis, “rely”: 1}, ).json() if not geo.get(“outcomes”): return {“error”: f“Couldn’t discover a location named ‘{metropolis}'”} lat = geo[“results”][0][“latitude”] lon = geo[“results”][0][“longitude”]
forecast = requests.get( “https://api.open-meteo.com/v1/forecast”, params={ “latitude”: lat, “longitude”: lon, “present”: “temperature_2m”, “every day”: “temperature_2m_max”, “timezone”: “auto”, }, ).json()
return { “metropolis”: metropolis, “current_temp_c”: forecast[“current”][“temperature_2m”], “week_high_temps_c”: forecast[“daily”][“temperature_2m_max”], “unit”: “celsius”, }
weather_tool = { “title”: “get_weather”, “description”: ( “Get the present temperature and this week’s every day excessive “ “temperatures for a metropolis. Returns JSON with metropolis, “ “current_temp_c, week_high_temps_c (7 every day highs), and unit.” ), “input_schema”: { “sort”: “object”, “properties”: { “metropolis”: {“sort”: “string”, “description”: “Metropolis title, e.g. ‘Lagos'”} }, “required”: [“city”], }, }
messages = [{“role”: “user”, “content”: “What’s the weather like in London right now?”}]
response = consumer.messages.create( mannequin=“claude-sonnet-5”, max_tokens=1024, instruments=[weather_tool], messages=messages, )
# Preserve resolving software calls till Claude produces a ultimate textual content reply whereas response.stop_reason == “tool_use”: messages.append({“position”: “assistant”, “content material”: response.content material}) tool_results = []
for block in response.content material: if block.sort == “tool_use” and block.title == “get_weather”: consequence = get_weather(**block.enter) tool_results.append({ “sort”: “tool_result”, “tool_use_id”: block.id, “content material”: json.dumps(consequence), })
messages.append({“position”: “person”, “content material”: tool_results}) response = consumer.messages.create( mannequin=“claude-sonnet-5”, max_tokens=1024, instruments=[weather_tool], messages=messages, )
for block in response.content material: if block.sort == “textual content”: print(block.textual content) |
Strolling by what issues right here: get_weather itself is strange Python — nothing agent-specific about it — it geocodes a metropolis title and pulls each the present temperature and the week’s every day highs in a single request. The weather_tool dictionary is the schema Claude really sees, and the outline issues greater than it appears to be like — a imprecise description is among the most typical causes of a mannequin calling a software with the unsuitable arguments. The whereas response.stop_reason == “tool_use” loop is the actual mechanical coronary heart of normal software calling: each time Claude requests the software, your code has to really run it, wrap the consequence as a tool_result block, append it to the dialog, and name the API once more — and this repeats for as many software calls as the duty wants. For a single lookup like this one, that’s one cross by the loop and carried out, which is strictly why software calling suits this case properly: one name, one consequence, and a consequence small and related sufficient that Claude genuinely advantages from seeing it immediately earlier than writing a natural-language reply.
Code Execution for Fan-Out and Aggregation
Now change the query, utilizing the very same get_weather operate — utterly unchanged: “given these fifteen cities, which one may have the coldest excessive temperature this week, and what’s the typical weekly excessive throughout all of them?”
Run that by the tool-calling loop above and also you’d get fifteen separate software calls, fifteen full JSON payloads of every day temperatures pushed into Claude’s context, and Claude would then need to manually evaluate and common them in pure language — sluggish, token-expensive, and precisely the form of arithmetic a mannequin is extra error-prone at than a for-loop is. That is exactly the case Programmatic Instrument Calling was constructed for.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 |
import json from anthropic import Anthropic
consumer = Anthropic()
# Identical get_weather operate from the earlier instance, unchanged
weather_tool = { “title”: “get_weather”, “description”: ( “Get the present temperature and this week’s every day excessive “ “temperatures for a metropolis. Returns JSON with metropolis, “ “current_temp_c, week_high_temps_c (7 every day highs), and unit.” ), “input_schema”: { “sort”: “object”, “properties”: { “metropolis”: {“sort”: “string”, “description”: “Metropolis title, e.g. ‘Lagos'”} }, “required”: [“city”], }, # That is the one line that adjustments the primitive: it opts the software # into being known as from inside generated code, not solely immediately # by the mannequin “allowed_callers”: [“code_execution_20250825”], }
code_execution_tool = {“sort”: “code_execution_20250825”, “title”: “code_execution”}
cities = [ “Lagos”, “Nairobi”, “Cairo”, “Accra”, “Kigali”, “Casablanca”, “Addis Ababa”, “Dakar”, “Tunis”, “Kampala”, “Harare”, “Lusaka”, “Maputo”, “Windhoek”, “Gaborone”, ]
messages = [{ “role”: “user”, “content”: ( f“Given these cities: {‘, ‘.join(cities)}, which one will have “ “the coldest high temperature this week, and what’s the average “ “weekly high across all of them? Use the get_weather tool.” ), }]
response = consumer.beta.messages.create( betas=[“advanced-tool-use-2025-11-20”], mannequin=“claude-sonnet-5”, max_tokens=2048, instruments=[code_execution_tool, weather_tool], messages=messages, )
# The loop appears to be like just like normal software calling, however now some # tool_use blocks carry a “caller” subject, which means the request got here # from inside Claude’s generated script moderately than from Claude immediately whereas response.stop_reason == “tool_use”: messages.append({“position”: “assistant”, “content material”: response.content material}) tool_results = []
for block in response.content material: if block.sort == “tool_use” and block.title == “get_weather”: consequence = get_weather(**block.enter) tool_results.append({ “sort”: “tool_result”, “tool_use_id”: block.id, “content material”: json.dumps(consequence), })
if tool_results: messages.append({“position”: “person”, “content material”: tool_results})
response = consumer.beta.messages.create( betas=[“advanced-tool-use-2025-11-20”], mannequin=“claude-sonnet-5”, max_tokens=2048, instruments=[code_execution_tool, weather_tool], messages=messages, )
for block in response.content material: if block.sort == “textual content”: print(block.textual content) |
The only most essential line on this complete script is “allowed_callers”: [“code_execution_20250825”]. With out it, the software behaves precisely because it did within the earlier instance — callable solely immediately by the mannequin. With it added, Claude features the choice to jot down a script that calls get_weather fifteen occasions itself, doubtless in parallel utilizing asyncio.collect, sum and type the outcomes, and print solely the ultimate reply — the coldest metropolis and the typical — to plain output. Your Python code doesn’t change the way it responds to particular person software calls in any respect; that a part of the loop appears to be like practically an identical to the tool-calling instance. What adjustments is invisible out of your aspect of the API: fourteen of these fifteen climate lookups, and each intermediate comparability between them, by no means contact Claude’s context.
Claude solely ever sees the 2 numbers it really requested for. Since this makes use of a beta characteristic, it’s value double-checking the precise beta header string and block-handling particulars in opposition to Anthropic’s present documentation earlier than counting on it in manufacturing, as beta APIs are the a part of any platform most probably to shift.
Why Code Execution Wins at Scale
The climate instance makes the mechanism seen, but it surely’s value backing this up with actual, printed figures moderately than instinct alone. Anthropic’s authentic code-execution-with-MCP sample took an actual Google Drive-to-Salesforce workflow from 150,000 tokens all the way down to 2,000 — a 98.7% discount — just by retaining a full assembly transcript contained in the execution atmosphere as an alternative of routing it by the mannequin twice.
Programmatic Instrument Calling’s personal inner benchmarking, reported immediately by Anthropic, discovered common token utilization on complicated analysis duties dropped from 43,588 to 27,297 — a 37% discount — whereas accuracy on the GAIA benchmark really improved, rising from 46.5% to 51.2%, and inner data retrieval accuracy rose from 25.6% to twenty-eight.5%. That final element issues greater than the token financial savings alone: this isn’t purely a price optimization. Offloading orchestration logic to precise code moderately than asking a mannequin to trace it by pure language measurably reduces the form of errors that come from a mannequin shedding observe of a dozen intermediate values it’s making an attempt to check in its head.
The tutorial consequence beneath all of this predates Anthropic’s personal tooling. The unique CodeAct paper from Wang and colleagues in 2024 discovered that brokers taking motion by executable code, moderately than JSON-formatted software calls, succeeded as much as 20% extra typically on complicated, multi-step duties. Code execution isn’t a latest product characteristic bolted onto an present concept — it’s a research-backed sample that the most important labs have spent the previous two years turning into manufacturing infrastructure.
The place Instrument Calling Nonetheless Wins
The numbers above could make code execution seem like an unconditional improve, and it isn’t one. There’s an actual, sincere case for sticking with plain software calling in a significant set of conditions.
Single-call duties are the clearest case. The Lagos climate instance earlier on this article features nothing from a sandbox — one name, one small consequence, and the overhead of spinning up a code execution atmosphere provides latency with out including any actual profit. Duties the place the mannequin genuinely must cause over an intermediate lead to pure language are the second case: if the precise level of a step is for the mannequin to note one thing refined in a doc or a dataset and reply to it conversationally, filtering that information away in a sandbox defeats the aim. Easier infrastructure is an actual, sensible issue too — a group with out an present safe sandboxing setup takes on actual operational price standing one up, and that price must be weighed in opposition to the financial savings, not assumed away. And auditability issues greater than it will get credit score for: a software name is one clear, loggable occasion with a reputation and a set of arguments, whereas reasoning about precisely what a generated script did internally — particularly after the actual fact, throughout an incident — is a genuinely more durable debugging downside.
Resolution Framework: Selecting the Proper Primitive
Pulling all the pieces above into one sensible reference:
| Issue | Favors software calling | Favors code execution |
|---|---|---|
| Variety of calls wanted | One, or a small, fastened few | A number of, particularly with fan-out or aggregation |
| What occurs to outcomes | The mannequin must learn and cause over them immediately | They simply must be filtered, summed, or in contrast |
| Information sensitivity | Low — nothing problematic concerning the mannequin seeing it | Excessive — PII or massive payloads higher saved out of context |
| Latency tolerance | Tight — sandbox startup isn’t value paying for | Workflow already includes a number of round-trips anyway |
| Crew infrastructure | No present sandboxing setup | Sandbox or code-execution tooling already in place |
| Auditability wants | Each discrete motion should be individually logged | Mixture final result issues greater than every inner step |
The Hybrid Actuality: Most Manufacturing Brokers Use Each
It’s value closing this out by pushing again gently on the framing of the article’s personal title. In apply, this isn’t a everlasting, once-and-for-all architectural determination — it’s a per-task judgment name, and Anthropic’s personal steering treats it precisely that method. Their superior software use launch shipped Programmatic Instrument Calling alongside two companion options particularly meant to be layered collectively as wanted: a Instrument Search Instrument for locating the precise software out of a giant library with out loading each definition upfront, and Instrument Use Examples for educating a mannequin the conventions a schema alone can’t categorical. Their very own advice is to start out with whichever bottleneck is definitely limiting a given agent — context bloat from too many software definitions, massive intermediate outcomes polluting context, or parameter errors — and add the matching characteristic, moderately than reaching for each functionality on day one.
A single well-built agent, in apply, tends to make use of plain software calling for its easy, single-shot lookups and change to code execution the second a process requires fan-out, aggregation, or dealing with information too massive or delicate to place in entrance of the mannequin immediately. The precise ability value constructing isn’t choosing a primitive as soon as — it’s recognizing, process by process, which one the work in entrance of you really wants.
Conclusion
An motion primitive is infrastructure, not a choice, and the 2 examples constructed on this article show it with the identical fifteen strains of software definition beneath each. Get it proper and an agent handles a fan-out process throughout fifteen cities — or two thousand expense line gadgets — in a single clear cross. Get it unsuitable — attain for software calling on a process that wants code execution — and nothing crashes. The agent nonetheless solutions. It simply does it slower, extra expensively, and with a context window quietly stuffed with information no one really wanted to learn.