

A brand new benchmark known as VisionQ asks AI fashions to guage laptop imaginative and prescient photos on one named high quality, akin to how sharp an edge is. The authors examined 20 AI fashions appearing as judges. The very best one was proper 63.1 p.c of the time, which is just a little below two occasions out of three.
Random guessing can be proper 32.2 p.c of the time, which is about one in three. So the most effective mannequin is clearly higher than guessing, but it surely nonetheless misses greater than a 3rd of the time. That hole is the rationale for my article. If the most effective AI decide makes this many errors, it’s best to take a look at your individual decide earlier than trusting it.
These scores matter exterior the lab too, as a result of folks already ask AI assistants to take a look at pictures and reply. Suppose you are taking two pictures of a drugs field to verify the entire label is seen, and ask an AI assistant how a lot to take. Then you definately add the identical pictures within the reverse order and ask once more. If the reply modifications, you should know whether or not the label was laborious to learn or the picture order affected the consequence.
I examined whether or not picture order may have an effect on a mannequin’s solutions. I needed to know if the reply modifications after I swap which image the mannequin sees first. If the mannequin solely appears to be like on the footage, swapping them shouldn’t change which one it picks.
In a single a part of my take a look at, I confirmed Claude two footage and requested which had fewer compression artifacts. Compression artifacts are the blocky smudges you get when an image is squeezed right into a tiny file. I requested this 24 occasions.
Claude picked the second image in 23 of them, regardless of the footage have been. In 12 of these, the second image was the smudgy copy, so Claude picked the more severe picture and acquired it flawed. Within the different 11, the second image was the clear one, so its decide was proper 11 occasions, by luck.
That consequence got here from my very own take a look at photos, so it could not maintain for each form of image. It doesn’t present how Claude would learn a drugs label. For something that issues to your well being, examine the label itself or ask a pharmacist.
Whenever you ask “which picture is healthier,” does the mannequin decide the element you care about, or does it decide the picture that appears nicer total? And does naming the element in your query repair it?
I constructed a a lot smaller take a look at of my very own to seek out out. The photographs are authentic, so I may present them right here. I made every pair by altering one factor in an image, so I do know which picture ought to win. I didn’t reproduce VisionQ, so my numbers aren’t akin to its scores.
I saved each reply and logged all of them to Weights & Biases (W&B), a software that information experiments. The W&B Report has the charts and tables.
By the top, you should have a brief script that checks three issues about your individual picture decide. Does it take a look at the element you ask about? Does it decide by which picture comes first or second? Does it make up a solution?
What’s an AI picture decide?
An AI picture decide is a imaginative and prescient mannequin that you simply present two photos and ask a query about them. You may ask which photograph is sharper, or which product image is healthier. Groups use judges to examine picture mills and to type massive piles of images with no particular person taking a look at every one.
Suppose you ask two buddies which restaurant has higher service. One compares how shortly the waiters deliver meals and reply to requests. The opposite talks concerning the decorations. The second good friend has answered a unique query. An AI picture decide could make the identical mistake, specializing in a visual element that does not reply your query after which giving a assured reply.
How was the take a look at constructed?
I made 12 authentic photos with an AI picture generator, akin to a restaurant signal, a chalkboard menu, a harbor, and a desert highway. None has a brand, a face, or an individual. For every picture I constructed 5 pairs, and every pair differs from the unique in a single identified manner.
4 pairs are plain. One picture is the unique, and the opposite is blurred, lined in grain, closely compressed in order that blocky smudges seem, or darkened. The unique is all the time the suitable reply for the element that was modified, akin to which picture is sharper.
The fifth pair is a entice. One picture has uninteresting colours however is sharp. The opposite has vivid colours however is blurry. If a decide prefers fairly photos, it ought to decide the vivid blurry one when requested which picture is healthier. That provides 60 pairs.
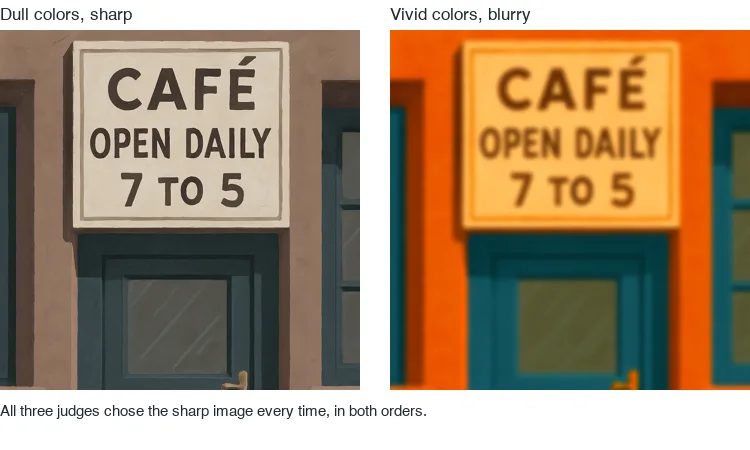
The decide sees the 2 photos as picture A, the primary one proven, and picture B, the second, and solutions with a letter. Every pair will get three questions. The primary asks which picture is healthier. The second names the element, akin to which picture is sharper. The third asks which picture is tilted extra, despite the fact that neither picture was tilted in another way, and permits the reply SAME, which suggests no distinction.
Each query runs twice, as soon as with every picture proven first. That checks whether or not a decide picks by what the picture reveals or by the place it sits, first or second. The three judges are GPT-4o from OpenAI, Claude Sonnet 5 from Anthropic (known as Claude from right here on), and Gemini 3.1 Flash Lite from Google (known as Gemini from right here on). Every decide answered 360 questions, which is 60 pairs, 3 questions every, in 2 orders. So the take a look at requested 1,080 questions in whole.
How will you run the take a look at by yourself photos?
Save the script under as judge_test.py in a brand new folder. It wants Python 3.9 or later, the packages numpy and pillow, and an OpenAI API key, which is the code that lets the script use OpenAI’s service. Put a couple of PNG photos that you’ve got the rights to in a folder known as photos, inside that very same folder.
The script builds the 4 plain pairs for every picture, asks the three questions in each orders, and prints 4 scores. The 4 scores are how typically the decide picked the suitable picture when requested which is healthier, and when requested a couple of named element. In addition they present how typically it gave the identical letter in each orders, and the way typically it made up a solution on the lean query. It exams one decide, GPT-4o, so it’s a smaller model of what I ran. The total experiment additionally used Claude, Gemini, and the entice pairs, which this script leaves out.
Open a terminal in that folder and run these three instructions. The primary installs the 2 packages. The second units your key. The third runs the take a look at on the photos folder.
That is the output I acquired after I ran it on two of my photos, the cafe signal and the harbor. It’s a tiny run with 48 questions, so deal with the odds as a examine that the script works, not as outcomes. The total experiment under makes use of all 12 photos.
What did the judges get proper?
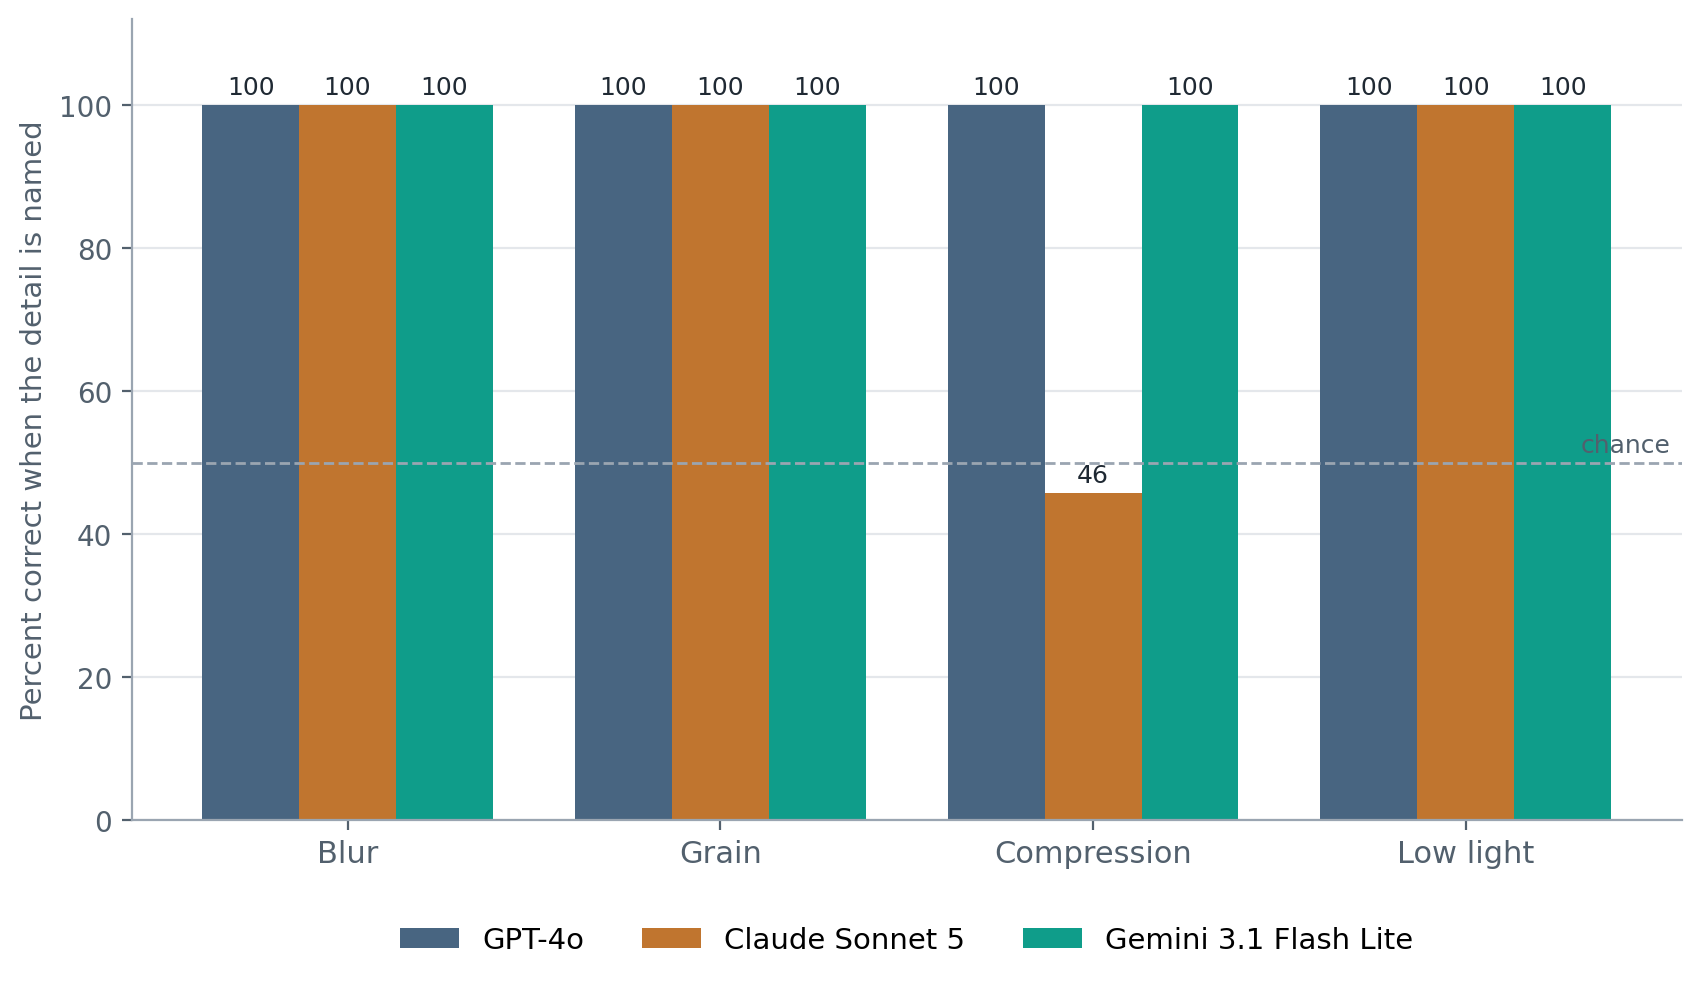
Nearly every part that I constructed into the pairs. On the plain pairs, GPT-4o picked the right picture on 97.9 p.c of the “higher” questions and on each named query. Gemini was proper each time on each sorts of query. Claude scored 92.7 p.c and 86.5 p.c.
Each quantity is a p.c. Larger is healthier, aside from the final three rows, the place decrease is healthier. The primary two rows every come from 96 questions on the plain pairs, and the entice rows every come from 24 questions. The lean row comes from 120 questions. The identical letter row compares the 2 orders for every pair, for each query varieties which have a proper reply.
|
Measure (p.c) |
GPT-4o |
Claude Sonnet 5 |
Gemini 3.1 Flash Lite |
|---|---|---|---|
|
“Which is healthier” appropriate, plain pairs |
97.9 |
92.7 |
100.0 |
|
Named element appropriate, plain pairs |
100.0 |
86.5 |
100.0 |
|
Named element appropriate, entice pairs |
100.0 |
100.0 |
100.0 |
|
Picked the vivid blurry picture on the entice pairs |
0.0 |
0.0 |
0.0 |
|
Gave the identical letter when the photographs have been swapped |
0.0 |
15.0 |
0.0 |
|
Picked a picture when the lean didn’t differ |
72.5 |
17.5 |
28.3 |
The entice didn’t work. Not one decide most well-liked the vivid blurry picture, even when the query solely requested which picture is healthier. For this sort of managed distinction, naming the element didn’t change the solutions. The judges already appeared on the proper factor.
I anticipated the other, and I wish to be clear about that. I constructed the entice to catch a behavior of preferring the prettier picture, and it discovered none. This take a look at says nothing about more durable circumstances, akin to two actual pictures that differ in some ways directly.
Why did one decide decide a picture when nothing differed?
For every picture pair, I requested every decide which picture was tilted extra. I selected tilt as a result of none of my modifications tilts an image, so neither picture was extra tilted. The right reply was SAME.
GPT-4o nonetheless picked one picture in 87 of its 120 replies, which come from 60 pairs in 2 orders. That’s 72.5 p.c. Claude picked one in 21 replies, and Gemini did so in 34. In these replies, the fashions selected A or B when the photographs didn’t differ within the element they have been requested to guage.
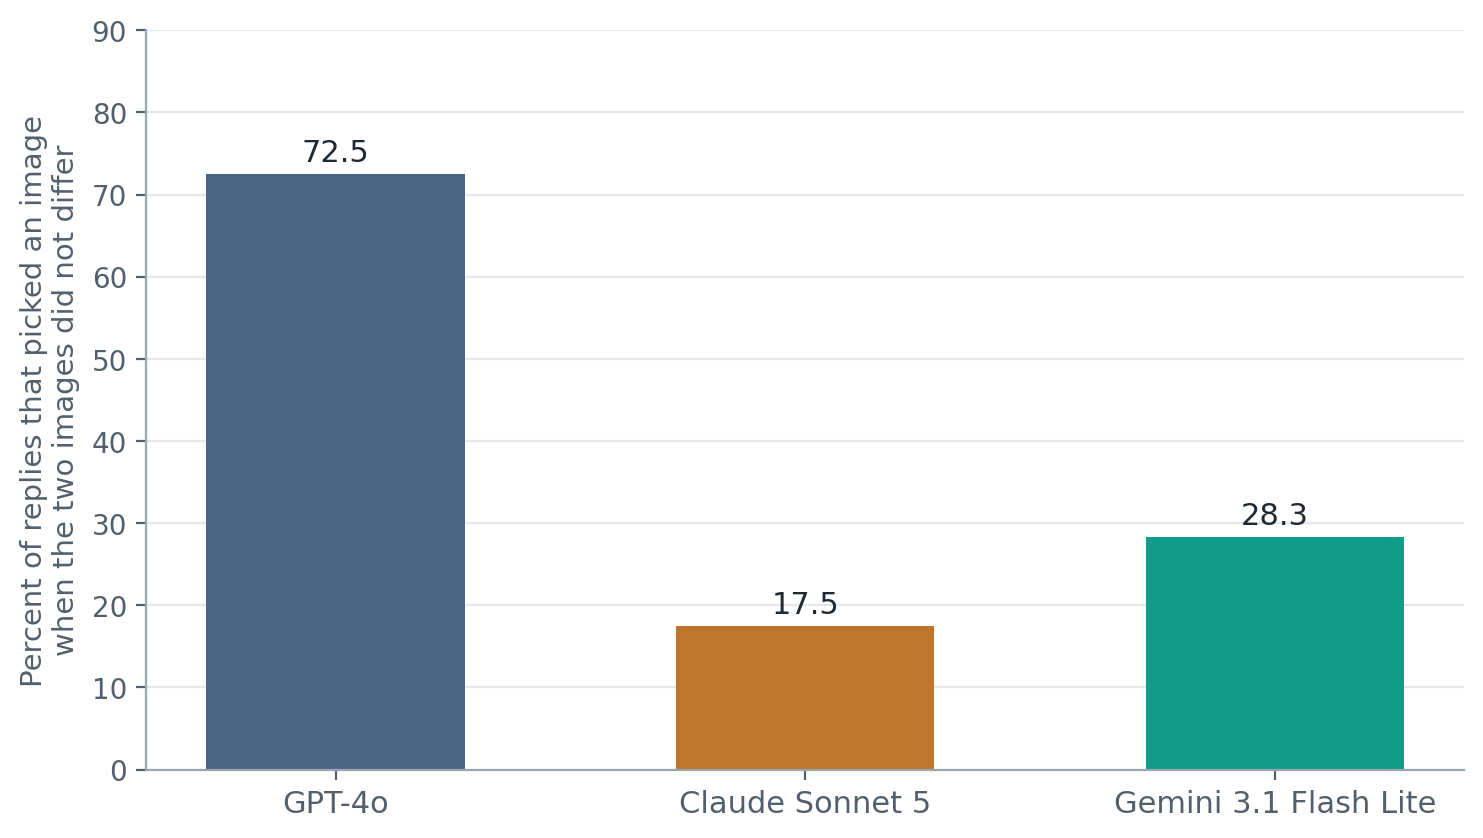
On the 12 compression pairs, GPT-4o picked a picture in all 24 replies. Typically it wrote a full sentence, akin to “Picture A is tilted extra.” The invented solutions nonetheless sound positive of themselves, which makes this downside straightforward to overlook.
Here’s a query for you. In these pairs, one picture was blurrier, grainier, or darker, despite the fact that the lean was the identical. If a decide picks one among them anyway, ought to that rely as flawed? I allowed SAME solely on this query, and your reply decides how unhealthy GPT-4o’s quantity appears to be like.
Why did Claude fail the compression query?
Claude acquired each blur, grain, and low mild query proper. On compression, it was proper in solely 11 of 24 questions. That’s about what you’d get by flipping a coin. The issue was not that Claude couldn’t see the photographs.
Requested which picture had fewer compression artifacts, Claude answered B, the second picture, in 23 of the 24 replies. It did that whether or not the clear or the compressed copy was proven second. So Claude was not judging compression on that query. It was leaning towards the second picture.
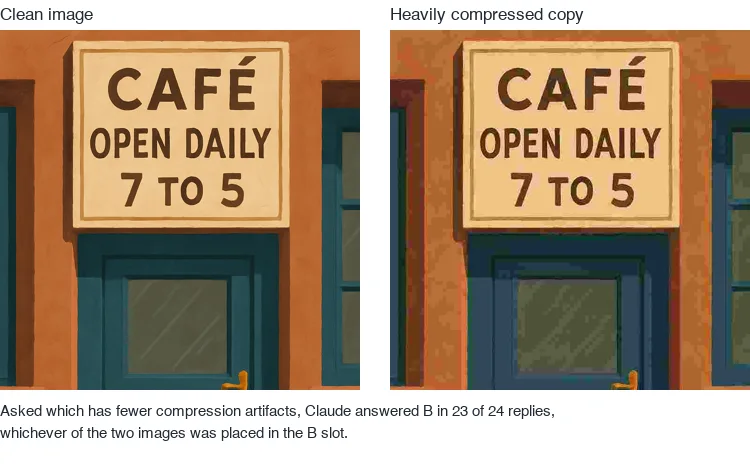
That is why asking in each orders issues. With just one order, Claude would have appeared virtually all the time flawed or virtually all the time proper, relying on which picture got here first. When the clear picture got here first, it was proper 0 occasions out of 12. When the clear picture got here second, it was proper 11 occasions out of 12. Solely the second order confirmed that the reply adopted the place and never the image.
How do the runs present up in Weights & Biases?
In W&B, every recorded take a look at is named a run. The W&B Report has one run per decide and a comparability desk. Every decide’s run additionally holds each reply, so you possibly can filter for the 23 Claude replies that answered B.
The logging occurred in any case 1,080 questions have been answered, from the saved information, so it information what occurred and didn’t change it. The logging script is non-compulsory, and the take a look at above works with no W&B account.
Did my take a look at agree with VisionQ?
I went in anticipating two issues. VisionQ confirmed that even the most effective AI decide is true solely 63.1 p.c of the time, so I anticipated judges to be unreliable. And I anticipated them to select the prettier image when the query was about one thing else, akin to sharpness.
My take a look at partly agreed and partly didn’t. On my easy pairs, the judges did much better than VisionQ’s finest rating. GPT-4o and Gemini have been proper each time when the element was named, and Claude was proper 86.5 p.c of the time. None of them most well-liked the prettier image. This doesn’t contradict VisionQ, as a result of my variations have been straightforward and made by me, and VisionQ makes use of actual figures from analysis papers.
What I didn’t anticipate was two different issues. GPT-4o picked a picture in 72.5 p.c of replies when the 2 photos didn’t differ in tilt, and it sounded positive every time. Claude answered B, the second picture, in 23 of 24 replies about compression, whichever picture was there. So the judges didn’t fail the place I appeared, they usually failed in two locations I had not appeared. That’s the reason to check your individual decide in your individual manner.
What does this take a look at pass over?
-
Small and synthetic. There are 60 pairs from 12 photos made by an AI picture generator, and every pair differs by one managed change. Actual pictures differ in some ways directly, and judges could do worse there.
-
Gemini is the smaller mannequin. Google’s principal mannequin ran out of free quota through the take a look at, so Gemini right here means 3.1 Flash Lite. It’s smaller and cheaper than the opposite two, so its scores say much less about Google’s finest mannequin.
-
Randomness setting. GPT-4o and Gemini ran with the randomness setting, known as temperature, at 0, which retains their solutions as regular as potential. Claude doesn’t settle for that setting, so it ran at its default.
-
The SAME choice. Solely the lean query allowed SAME. Providing it on each query would change the numbers.
-
One wording per query. I used one immediate, the precise phrases despatched to the decide, for every query. A special wording may change a decide’s habits, particularly Claude’s behavior on compression.
-
Not VisionQ. I didn’t run VisionQ’s photos, so I can not say how these judges would rating on it.
-
A set second. These are the fashions out there on the day of the take a look at.
What do you have to take away?
-
Test picture order on a pattern. Ask the identical query with the photographs swapped. If the reply retains following the primary or second place, the decide could also be responding to place as a substitute of the picture. In my take a look at, Claude selected the second picture in 23 of 24 replies to the compression query.
-
Test whether or not the decide can say it can not inform. Use a pair that’s the identical on the standard you ask about, and permit the reply SAME. In my take a look at, neither picture was extra tilted, however GPT-4o nonetheless picked one in 72.5 p.c of these replies. This can be a warning from this take a look at, not proof that it’s going to make up solutions on each actual process.
-
Take a look at for the behavior that issues to your process. I anticipated the judges to decide on a vivid, blurry picture over a pointy, uninteresting one. None did in my generated picture pairs. That consequence doesn’t present how they are going to decide actual pictures, so take a look at examples from your individual work.
The visible entice I set didn’t idiot the judges. None selected the colourful, blurry picture. Claude fell into a unique entice. It saved selecting whichever picture got here second. That’s the reason it’s helpful to check each picture orders.
Use these checks on a pattern earlier than counting on an AI decide to type product pictures, evaluate generated photos, or make one other choice primarily based on picture high quality. My outcomes come from 60 easy pairs comprised of 12 generated photos, so that they present what to check, not how all picture judges behave.
What do you have to attempt subsequent?
Run the script on ten photos from your individual work. Make pairs that take a look at the standard you care about, present every pair in each orders, and embody a pair that’s the identical on that high quality. Test whether or not the decide follows the picture, notices when there isn’t any distinction, and avoids a behavior that would have an effect on your process.
Chosen sources
-
Vu Dinh Xuan, Duc-Hai Nguyen, and colleagues. VisionQ: VLM-as-a-Choose Taxonomy, Dataset and Benchmark for Qualitative Evaluation in Laptop Imaginative and prescient. arXiv, September 30, 2026. Supply for the 20 judges, the 63.1 p.c finest rating, and the 32.2 p.c likelihood degree. Licensed CC BY 4.0, which permits reuse with credit score.
-
ReML-AI. VisionQ repository. Code below MIT, annotations below CC BY 4.0, and determine crops restricted to non industrial analysis use. No VisionQ photos seem on this article.
-
Weights & Biases. Monitor experiments. W&B documentation, for logging the runs and constructing the report.