Retrieval-Augmented Technology (RAG) is probably the most extensively used LLM use case throughout organizations. By vectorizing paperwork and retrieving semantically related chunks at question time, RAG mitigates hallucinations, grounds responses and bypasses static information cutoffs imposed by mannequin pretraining. Nevertheless, in a real-life situation, customary vector-based RAG runs into limitations for advanced queries, corresponding to people who require international context, multi-hop reasoning, cross-document aggregation of numerical figures and so forth.
Customary RAG is nice at answering express, localized queries. But when we ask, “How does a delay in transport half A from provider B have an effect on the ultimate meeting of product C?”, it retrieves disconnected chunks primarily based on semantic overlap however fully misses the express, deterministic relationships connecting these entities. Equally, for a question such because the pattern in income throughout a sure product class for five years ending in 2025, it’s unlikely to carry out cross-document reasoning, fetch the best chunks from the related paperwork for 2021 to 2025 and reply the query appropriately. It’s because customary vector RAG sees a flat world of doc snippets or chunks.
The GraphRAG Shift
GraphRAG solves this by transitioning from retrieving flat paperwork to retrieving structured information. It integrates Data Graphs (KGs), the place information is saved as Nodes (Entities), Edges (Relationships), and Properties into the RAG pipeline. By doing so, it combines the semantic, fuzzy-matching capabilities of contemporary LLMs with the structured, deterministic reasoning of KGs.
As an alternative of explaining the fundamentals of GraphRAG, on this article, let’s take a look at six distinct architectural patterns of GraphRAG, together with execs, cons and use circumstances. We are going to discover how they work, the information movement, visualize the architectures, and precisely when to make use of them in manufacturing.
Core Parts of a GraphRAG Pipeline
Earlier than diving into the architectures, let’s take a look at the baseline parts of any GraphRAG system. Whatever the superior routing or retrieval logic we make use of, the system would require these foundational pillars:
-
Info Extraction: Uncooked unstructured textual content is handed by way of an LLM instructed to carry out Named Entity Recognition (NER) and Relationship Extraction. The LLM identifies nodes (e.g.,
Firm,Individual) and edges (e.g.,WORKS_FOR,SUPPLIES). This step is computationally costly and requires a well-defined ontology. -
Graph Storage: The extracted nodes and edges are loaded right into a Graph Database (like Neo4j, NebulaGraph, Memgraph and so forth). These databases use specialised question languages like Cypher to traverse nodes and relationships. As well as, nodes and relationships may be embedded to carry out a similarity primarily based search and traversal when precise matching fails to yield outcomes.
-
Retrieval: The mechanism by which a consumer question interacts with the graph. As we are going to see, the architectural patterns diverge considerably on this side.
-
Technology: The retrieved graph information is injected into the LLM’s context window to synthesize the ultimate, grounded response.
6 Architectural Patterns of GraphRAG
The time period “GraphRAG” is commonly used loosely, however in apply, it’s an umbrella for a number of essentially completely different architectural patterns, in a number of of which a KG isn’t the one information retailer. Selecting the best sample depends on consumer question patterns, system’s value, latency, and functionality.
Sample 1: Textual content-to-Cypher / Graph Question Technology
Probably the most direct and deterministic strategy to GraphRAG is the Textual content-to-Cypher sample. On this structure, the LLM acts strictly as a question translator fairly than a semantic search engine.
The way it Works
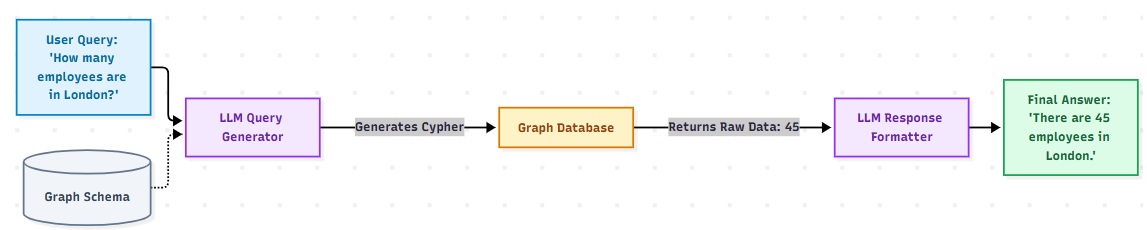
The consumer inputs a pure language question. The system offers a LLM with the graph database’s schema (node labels, edge sorts, and properties) by way of the system immediate. The LLM’s major job is to translate the pure language into a legitimate graph question language (e.g., Cypher for Neo4j, or Gremlin). This question is then executed immediately in opposition to the graph database. The precise, factual outcomes returned by the database are both introduced on to the consumer or handed to a second LLM to be formatted right into a pure language response.
Implementation Particulars and Information Circulation
To implement this efficiently, the immediate engineering have to be rigorous. We can’t merely go the question to the LLM; we should go the precise ontology.
-
Schema Injection: Extract the schema from our graph DB (e.g.,
CALL db.schema.visualization()in Neo4j) and format it as a string within the immediate. -
Few-Shot Prompting: Present the LLM with 5-10 examples of advanced pure language questions and their corresponding optimum Cypher queries. This helps in lowering syntax errors.
-
Execution & Fallback: Execute the generated Cypher. If the database throws a syntax error, catch the error, append it to the immediate, and ask the LLM to repair its question (a self-correction loop).
-
Formatting: Take the JSON/Tabular output from the database and feed it to a less expensive LLM (like a mini-gpt or Haiku) to say, “Given the consumer requested X, and the database returned Y, write a well mannered response.”
Execs and Cons
Execs:
-
Zero Hallucination Retrieval: The retrieval is 100% deterministic identical to querying a relational database utilizing SQL. The LLM doesn’t guess the relationships; the KG already has them.
-
Aggregations: That is the solely sample that natively handles counting, averaging, and mathematical aggregations (e.g., “What’s the common wage of engineers reporting to VP John?”).
Cons:
-
Brittleness (With out node and relation embeddings): If the consumer asks for a “software program developer” however the ontology makes use of “Engineer”, a strict Cypher question will return null. That is typically mitigated by embedding the graph nodes and relations (Vector Graph Search), permitting us to search out the beginning node by way of semantic similarity fairly than an actual string match earlier than executing the Cypher traversal. One must be cautious with this strategy. In contrast to the Cypher, semantic similarity is non-deterministic, and can at all times return nodes, even when they’re completely different (and subsequently incorrect) from the intent of the question.
-
No Unstructured Context: It solely retrieves what’s explicitly modeled as nodes and edges. It can’t retrieve paragraphs of textual content describing the nuances of the information.
When to Use It
This sample is finest fitted to extremely structured, operational information bases the place solutions depend upon precise traversals, counting, aggregations, or discovering shortest paths. Customers ought to concentrate on the ontology to successfully question the KG. This could possibly be the case for querying inside HR databases, provide chain logistics, or monetary transaction webs the place semantic ambiguity is low, precision is vital and customers are specialists within the area.
Sample 2: Parallel Hybrid RAG (Vector + Graph)
This structure represents the fact that vector databases and graph databases excel at various things, and might subsequently, successfully complement one another. Whereas vector databases are nice at semantic matching of unstructured textual content, graph databases are for traversing deterministic, structured relationships. This and the next patterns discover methods to mix their capabilities for grounded responses to quite a lot of queries.
The way it Works
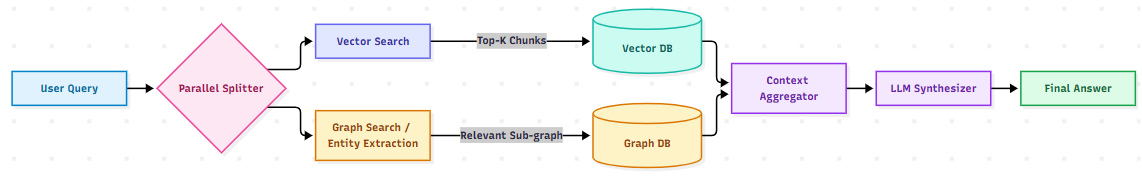
Within the Parallel Hybrid sample, the system maintains two separate databases: a vector index of the unique unstructured doc chunks, and a information graph of the extracted entities and relationships. When a consumer question arrives, the system queries each databases concurrently. This strategy acknowledges {that a} single, advanced question typically comprises some elements which are finest answered by the deterministic graph (e.g., “What was the income?”) and others higher answered by the vector database (e.g., “What had been the strategic priorities?”). The vector database retrieves the top-Ok semantically related chunks. Concurrently, the graph database retrieves related sub-graphs. The outcomes from each streams are mixed and injected into the LLM’s context window.
Implementation Particulars and Information Circulation
-
Twin Ingestion: When a doc is ingested, it’s chunked and embedded into the Vector DB. Concurrently, it’s handed by way of the extraction pipeline to populate the Graph DB. Additionally, the graph nodes should preserve a
source_document_idproperty. (This linkage permits the system to supply precise doc citations for graph info and safely delete stale graph nodes when a supply doc is eliminated). Word that storingsource_chunk_idsas node property might lead to a really massive array, as a node entity (corresponding to half quantity) could also be current in a whole bunch of chunks throughout many paperwork. That is subsequently, not advisable. -
Question Processing: The question is processed concurrently throughout each databases.
-
Vector Stream: The question is embedded, and the vector DB retrieves the top-Ok semantically related chunks.
-
Graph Stream: Entities and relations are extracted from the question. The system makes an attempt a strict Cypher traversal primarily based on these entities. If strict matching fails, it falls again to a Semantic Graph Search (looking immediately in opposition to node/relation embeddings) to search out the right entry nodes and extract their 1-hop or 2-hop ego graphs.
-
-
Context Meeting: We now have an inventory of textual content chunks and an inventory of JSON-formatted graph relationships. These are concatenated into the LLM immediate. For a question like “What are the strategic mitigation plans for delays on the Shanghai port, and which tier-2 suppliers are impacted?”:
Execs and Cons
Execs:
-
Excessive Recall: We get the perfect of each worlds. If the reply is hidden within the nuance of a paragraph, the vector search catches it. If the reply requires connecting two discrete info, the graph catches it.
-
Low Latency: As a result of the vector search and graph search run concurrently, the retrieval latency is determined by whichever is slower, fairly than the sum of each.
Cons:
-
Token Heavy: We’re injecting a considerable amount of context into the LLM. This provides to the inference prices and might generally result in the synthesizer LLM ignoring granular info or figures within the context.
-
Redundancy: It might occur that for some queries, the context gathered from both the graph or the vector database is adequate. Parallel retrieval finally ends up injecting redundancy and losing tokens.
When to Use It
That is the secure possibility for generalized enterprise search. It’s appropriate when one can’t predict whether or not a consumer’s question would require factual relational information or broad, unstructured context. If the queries are a mixture of semantic, relational or a mix, Parallel Hybrid is the way in which to go.
Sample 3: Sequential Hybrid (Graph-First)
In contrast to the parallel strategy, Sequential Hybrid architectures use the outcomes of 1 retrieval technique to explicitly inform and filter the opposite. This creates a extremely centered, exact context window, lowering the redundancy and excessive token prices of the parallel strategy. The primary variant of that is Graph-First RAG.
The way it Works
The system queries the Data Graph first to search out precise entity relationships. As earlier than, the graph nodes comprise metadata monitoring their source_document_ids. The system extracts these Doc IDs and makes use of them as onerous filters for a subsequent vector search. By doing this, it ensures that the unstructured textual content retrieved belongs solely to the paperwork that point out the entities satisfying the relational logic of the question.

Implementation Particulars and Information Circulation
Let’s suppose the question is “Discover the security warnings for all lithium parts provided by XYZ Corp.”
-
Graph Traversal: The system finds the entry node (e.g., ‘XYZ Corp’) from the question. Then, utilizing both a strict Cypher match or fall-back Semantic Graph Search on the node embeddings, it traverses the relationships to search out the related parts:
MATCH (c:Firm)-[:SUPPLIES]->(p:Part {sort: 'Lithium'}) RETURN p.source_document_ids. -
Doc ID Extraction: The graph database returns an inventory of Doc IDs the place these particular parts had been talked about (e.g.,
['DOC-12', 'DOC-45']). -
Filtered Vector Search: The system now executes a vector seek for the consumer question. However now it applies a metadata filter to the vector database:
WHERE chunk.document_id IN ['DOC-12', 'DOC-45']. This narrows the search area drastically, focusing retrieval and enhancing accuracy of context. -
Synthesis: The LLM is offered solely with the security warning textual content chunks discovered inside the precise paperwork. Similar to the Parallel Hybrid sample, the context may be augmented utilizing the retrieved graph relationships additionally for a richer context.
Execs and Cons
Execs:
-
Grounded Retrieval: Customary vector search may return security warnings for lithium parts provided by different corporations simply because the textual content is semantically related. Graph-First effectively constrains the search to related paperwork, thereby grounding the response.
-
Token Effectivity: As a result of we pre-filtered the vector search, we solely inject extremely related chunks into the synthesizer LLM.
Cons:
-
Latency: The steps are sequential. We should watch for the graph question to finish earlier than beginning the vector search.
-
Strict Dependency: If the graph is lacking the sting between XYZ Corp and the element, the downstream vector search will return nothing, even when the vector DB has the proper doc. In such circumstances, the search can fallback to a world vector solely search, with a caveat to the consumer to validate the response from the cited sources.
When to Use It
Graph-First RAG is good for extremely entity-centric queries the place you should definitively slender down the search area to a particular group of entities earlier than parsing the textual content. Reasonably than requiring the graph to carry each precise, nuanced relationship, it makes use of the graph’s structural information as a strong coarse filter. This ensures the downstream vector search solely appears at paperwork related to these particular entities. Typical use circumstances could possibly be for looking authorized textual content (isolating paperwork linked to a particular subsidiary) and manufacturing (filtering for manuals linked to particular sub-assemblies).
Corollary: The Sparse Graph Structure (Price-Environment friendly Graph-First RAG)
It’s price noting {that a} main barrier to adopting any type of GraphRAG is the immense value of extracting a dense information graph utilizing LLMs. The Sparse Graph Structure is a direct corollary to the Graph-First sample designed to alleviate this value drawback. As a result of Graph-First RAG depends closely on the downstream vector seek for nuance, we do not really want a dense graph to seize all relations. As an alternative of utilizing costly LLMs, the system can use quick, deterministic NLP strategies (like SpaCy), or smaller LLMs to construct a “sparse” skeletal graph of solely probably the most essential, high-level entities. The retrieval movement stays equivalent to Sample 3 (Traverse Sparse Graph -> Filtered Vector Search -> Synthesis). We rely totally on the vector chunks to fill within the lacking context and reply relation primarily based queries precisely.
Sample 4: Sequential Hybrid (Vector-First)
The inverse of the earlier sample. This structure acknowledges that generally a consumer’s question is simply too broad or fuzzy to start out with a inflexible graph traversal. As an alternative, we forged a large semantic web first, after which use the graph to sharpen the context.
The way it Works
The system performs a typical semantic vector search first to search out probably the most related doc chunks. It then examines these particular chunks, extracts the important thing entities talked about inside them, and makes use of these entities as entry factors to traverse the information graph. This pulls in deeper, multi-hop context about these entities that was not current within the authentic vector chunks.

Implementation Particulars and Information Circulation
Contemplate a question like: “What are the systemic dangers related to Undertaking X?”
-
Semantic Search: The system embeds the question and searches the Vector DB, returning 5 chunks of textual content describing Undertaking X’s quick delays and funds points.
-
Entity Grounding: The system runs a light-weight Entity Extractor (like a quick LLM or SpaCy) over the textual content of these 5 retrieved chunks to determine the important thing entities talked about. (e.g., “Undertaking X”, “Vendor Z”, “Supervisor Smith”).
-
Graph Enlargement: The system queries the graph utilizing these extracted entities as seed nodes. Additionally by utilizing Semantic Graph Search in opposition to the graph’s node embeddings, the system can gracefully deal with minor identify mismatches (e.g., matching “Vendor Z” from the textual content to “Vendor Z LLC” within the graph). It retrieves their 1-hop and 2-hop neighbors, discovering, for instance, that the seller additionally provides essential parts to a different associated challenge.
-
Synthesis: The LLM is given the unique textual content chunks plus the expanded relational context, permitting it to infer systemic dangers throughout a number of tasks.
Execs and Cons
Execs:
-
Discovering unknown patterns: It’s helpful at discovering “unknown unknowns”. By beginning fuzzy after which increasing by way of the graph, it uncovers connections the consumer did not take into account related to start out with.
-
Strong to Poor Schemas: In contrast to the Graph-First strategy, that is extra forgiving if the consumer’s question would not completely match the graph schema. The nodes and relations are extracted from the retrieved chunks.
Cons:
-
Sequential Latency: Once more, we’re operating two retrieval steps back-to-back.
-
Context Bloat: Increasing the graph from a number of seed nodes can rapidly lead to hundreds of irrelevant edges. We have to restrict the enlargement scope to crucial entities and relations.
When to Use It
Greatest for broad, open-ended, and semantic queries the place the preliminary intent is fuzzy, however subsequent relational context is required to floor the ultimate reply. Helpful in forensic evaluation, investigative journalism, and deep analysis functions.
Sample 5: The Adaptive Router Agent
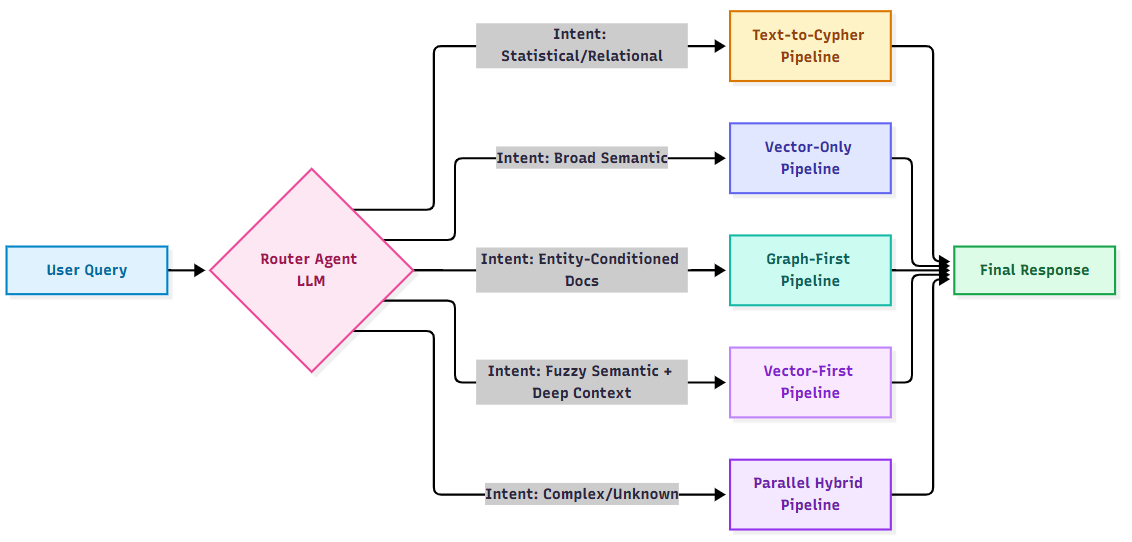
Because the above 4 patterns present, every has its strengths and hardcoding a single retrieval path for each question isn’t an optimum strategy. The Adaptive Router Agent introduces a decision-making layer on the very entrance of the pipeline.
The way it Works
An clever routing agent (which is usually a quick LLM or a fine-tuned classification mannequin) analyzes the consumer’s incoming question. It evaluates the question’s intent, entity density, and relational complexity, after which dynamically routes it down the optimum architectural path (Textual content-to-Cypher, Vector-Solely, Graph-First, Vector-First, or Parallel Hybrid).
Implementation Particulars and Information Circulation
To implement a Router Agent with out including a lot latency, we are able to use smaller, sooner fashions (like gpt-mini, gemini-flash and so forth).
-
The Routing Immediate: The LLM is supplied with a system immediate that outlines the obtainable instruments/pipelines and their particular use circumstances.
-
Execution: The router outputs the choice. The orchestration layer (e.g., LangChain or customized Python) catches this JSON and executes solely the chosen pipeline.
Execs and Cons
Execs:
-
Price and Latency Optimization: By routing easy semantic or entity/relation queries to a budget, quick Vector-Solely or Textual content-to-Cypher pipeline, we save the associated fee and latency of twin retrieval with massive context.
Cons:
-
Router Overhead: We’re including an LLM name to the start of each question. It provides just a little latency and value to a question.
-
Misclassification: Router wants a robust immediate with enough testing to keep away from misclassification. If the router misinterprets the question, it sends the question down a pipeline that may nearly actually fail to reply it appropriately.
When to Use It
This sample is lifelike for user-facing enterprise chatbots, generic search bars, or any software the place consumer queries fluctuate tremendously in construction and intent. If we can’t predict what the consumer will ask, we should use a Router.
Sample 6: Agentic GraphRAG
The sixth and last sample is Agentic GraphRAG. As an alternative of a single, predetermined retrieval go, this sample employs autonomous brokers that work together with the graph dynamically.
The way it Works
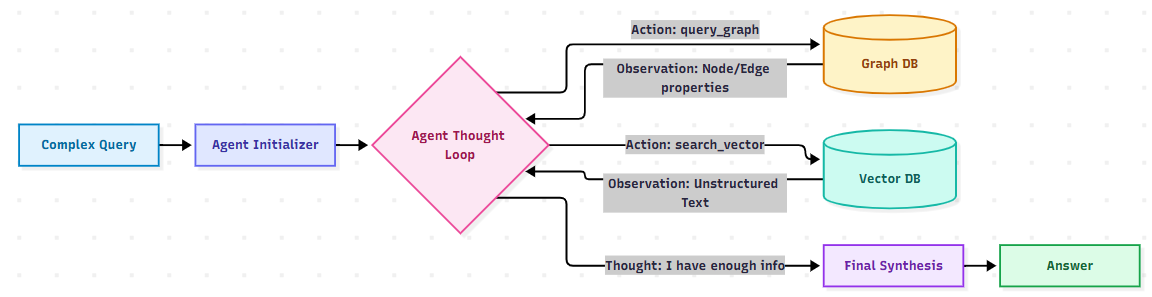
Given a posh question, an autonomous agent is provided with instruments to work together with each the graph database and the vector database. It’d begin by figuring out a beginning node within the graph, executing a question to view its neighbors. It evaluates this intermediate context and decides: “Do I have to traverse additional down this edge, or ought to I exploit the source_document_id of this node to learn the unstructured textual content within the vector database?” The agent iteratively navigates between structured relationships and unstructured textual content, gathering clues and backtracking if it hits a useless finish, till it varieties a whole reply.
Implementation Particulars and Information Circulation
This requires sturdy agent frameworks like LangGraph or AutoGen.
-
Software Provisioning: The agent is given a number of instruments, corresponding to
query_graph(cypher_statement)andsearch_documents(semantic_query, document_id_filter). -
The ReAct Loop: The agent operates in a Motive-Act-Observe loop. It causes about what it wants to search out, acts by querying both the graph or the vector DB, observes the consequence, and repeats.
-
Reminiscence: The agent maintains a “scratchpad” of info it has found alongside the traversal path.
Execs and Cons
Execs:
-
Unbounded Reasoning: It could probably reply extraordinarily advanced questions that require unpredictable traversal paths, one thing not attainable from the static pipelines mentioned earlier than.
-
Self-Correction: If the agent queries the mistaken node, it will possibly notice its mistake and take a look at a special path.
Cons:
-
Giant Latency: An agent may take 5, 10, or 20 sequential LLM calls to reply a single query. This interprets to response occasions measured in minutes, not seconds.
-
Price: Unbounded loops can probably equal unbounded token utilization. One potential optimization is adaptive mannequin routing, the place every LLM name is dynamically directed to a mannequin applicable for the complexity of that individual step.
When to Use It
Agentic GraphRAG is strictly reserved for offline, advanced, open-ended analytical queries requiring deep, multi-step reasoning. It’s splendid for researchers asking, “Examine the availability chain vulnerabilities of Product Y throughout all tier-3 distributors and summarize the geopolitical dangers.” It’s typically not appropriate for real-time consumer chatbots.
Customized Architectures vs. Microsoft’s GraphRAG
A typical level of comparability is Microsoft’s GraphRAG framework. It represents a special paradigm from the traversal-based architectures we mentioned above.
Microsoft’s strategy focuses closely on constructing a structured, hierarchical illustration of the corpus. Throughout ingestion, it extracts entities and relationships from the supply paperwork, applies hierarchical group detection utilizing algorithms corresponding to Leiden, and makes use of an LLM to generate studies summarizing these communities.
This design is especially related for international questions. International Search makes use of these pre-generated group studies in a map-reduce course of to reply questions corresponding to “What are the primary themes on this dataset?” Reasonably than attempting to retrieve a number of semantically related chunks, it will possibly cause throughout the summarized construction of the complete corpus.
There’s additionally Native Search, which is designed for extra particular, entity-centric questions. It combines related graph entities, relationships, group info, and related textual content from the unique paperwork. DRIFT Search additional combines international group info with native exploration.
It is a broader hierarchical structure by which group studies are particularly vital for international reasoning. For extremely localized relational questions corresponding to “Who does John report back to?”, a less complicated Graph-First or Textual content-to-Cypher strategy could also be extra direct and probably inexpensive, relying on the information and question workload.
In abstract, Microsoft’s implementation is especially differentiated by its emphasis on international corpus-level reasoning and hierarchical summarization, fairly than being a common answer for each sort of relational RAG drawback.
Challenges and Greatest Practices for Implementation
Simply as with all software and structure, there are a number of well-known challenges with Data Graphs and GraphRAG. Beneath, I’m noting the important thing ones and finest practices to navigate them.
As highlighted within the Sparse Graph corollary (Sample 3), operating LLMs to extract nodes and edges throughout gigabytes of textual content is kind of costly.
Greatest Observe: Begin with a Sparse Graph. Use conventional NLP (SpaCy, GLiNER) to map the skeletal construction of your information. Solely deploy dense LLM extraction on probably the most essential, high-value paperwork. For the remaining, depend on metadata connections and let Vector RAG deal with the heavy lifting.
Problem 2: Ontology Drift
If we extract information at the moment with the schema Firm and Worker, and subsequent month resolve it must be Group and Employees, the graph turns into a fragmented mess. In future, inserting new paperwork turns into a problem, requiring cautious analysis which nodes and relations really exist and what they’re named.
Greatest Observe: Deal with the ontology like a manufacturing database schema. It requires model management and strict governance. Begin with a minimal, inflexible ontology. When utilizing LLMs for extraction, it helps to supply the schema strictly within the immediate and use structured output (JSON mode or perform calling) to power compliance. The LLM must be restricted from inventing new node labels on the fly.
Problem 3: Graph Upkeep and Synchronization
In vector databases, updating a doc is simple: delete the previous chunks and embed the brand new ones. In a graph, deleting a doc means discovering each single node and edge that was generated solely by that doc and eradicating them, with out breaking the nodes which are shared with different legitimate paperwork.
Greatest Observe: Implement strict lineage monitoring. Each node and edge within the graph database should comprise an array property of source_document_ids. When a doc is deleted, question the graph for all components containing that ID. Take away the ID from the array. If the array turns into empty, delete the node/edge.
Problem 4: Evaluating the Retrieval Path
Customary RAG analysis frameworks (like Ragas) consider the ultimate reply. However in GraphRAG, if the reply is mistaken, we have to know if the vector search failed, if the graph traversal failed, or if the router agent made a foul choice.
Greatest Observe: Construct customized telemetry into the pipeline. Log the output of each intermediate step. Use LLM-as-a-judge to explicitly consider the Cypher generated by the Textual content-to-Cypher pipeline, independently of the ultimate reply technology.
Conclusion
GraphRAG represents a paradigm shift in how we construct AI programs. Vector RAG enabled semantic which means of textual content to be coded numerically into embeddings, thereby making it attainable to carry out semantic similarity search. A Data Graph appears on the textual content as a related net of data. Collectively, they symbolize completely different features of the identical information retailer and complement one another in mining insights from the textual content.
The target of this text has been to display that there isn’t a single solution to implement a GraphRAG. The selection is now not whether or not to make use of graphs, however which architectural sample, be it Parallel Hybrid, Adaptive Routing, or Sequential Graph-First, most closely fits the distinctive necessities, latency and funds constraints of a use case.
These architectural patterns can allow practitioners to construct retrieval programs that do not simply discover related paperwork, however cause over the related dimensions of enterprise information.
Additional Studying
Agentic GraphRAG can resolve what to do subsequent. However who decides which mannequin ought to do it?
Not each step in a multi-agent workflow wants the identical degree of reasoning. Routing each name to probably the most highly effective mannequin can rapidly drive up inference prices.
What if the system may dynamically select the mannequin that most closely fits every step?
I discover this strategy in Optimizing LLM Inference Prices in Multi-Agent Programs with Adaptive Mannequin Routing.
Join with me and share your feedback at www.linkedin.com/in/partha-sarkar-lets-talk-AI
Pictures used on this article are generated utilizing Google Gemini.