Earlier articles on this sequence mentioned constraining output house in addition to reusing the immediate prefix with a key-value cache, each framed as approaches to small language mannequin (SLM) slender automation optimization. Let’s end this sequence off with the third entry, targeted on batching by size as an alternative of looping merchandise by merchandise.
As in our earlier articles, all benchmarks beneath use Qwen2.5-0.5B-Instruct in float16 by means of Hugging Face Transformers, working on an M2 Macbook Air with 24GB RAM and a 16-core Neural Engine.
Remember to arrange a Python atmosphere and set up your necessities:
pip set up torch transformers speed upWe are going to proceed to make use of the assist ticket framing from our first article.
Why Batch by Size As an alternative of Looping Merchandise by Merchandise
Processing one ticket per ahead cross is the one largest supply of waste in the entire pipeline. At batch measurement 1, a small mannequin is memory-bandwidth sure somewhat than compute-bound: the {hardware} streams each weight out of reminiscence to be able to serve one sequence, then does it once more for the following one, and the arithmetic items sit principally idle in between. That is true on a GPU and it’s true on the CPU we now have been utilizing all through this sequence, which is the place a 0.5B mannequin most frequently truly runs.
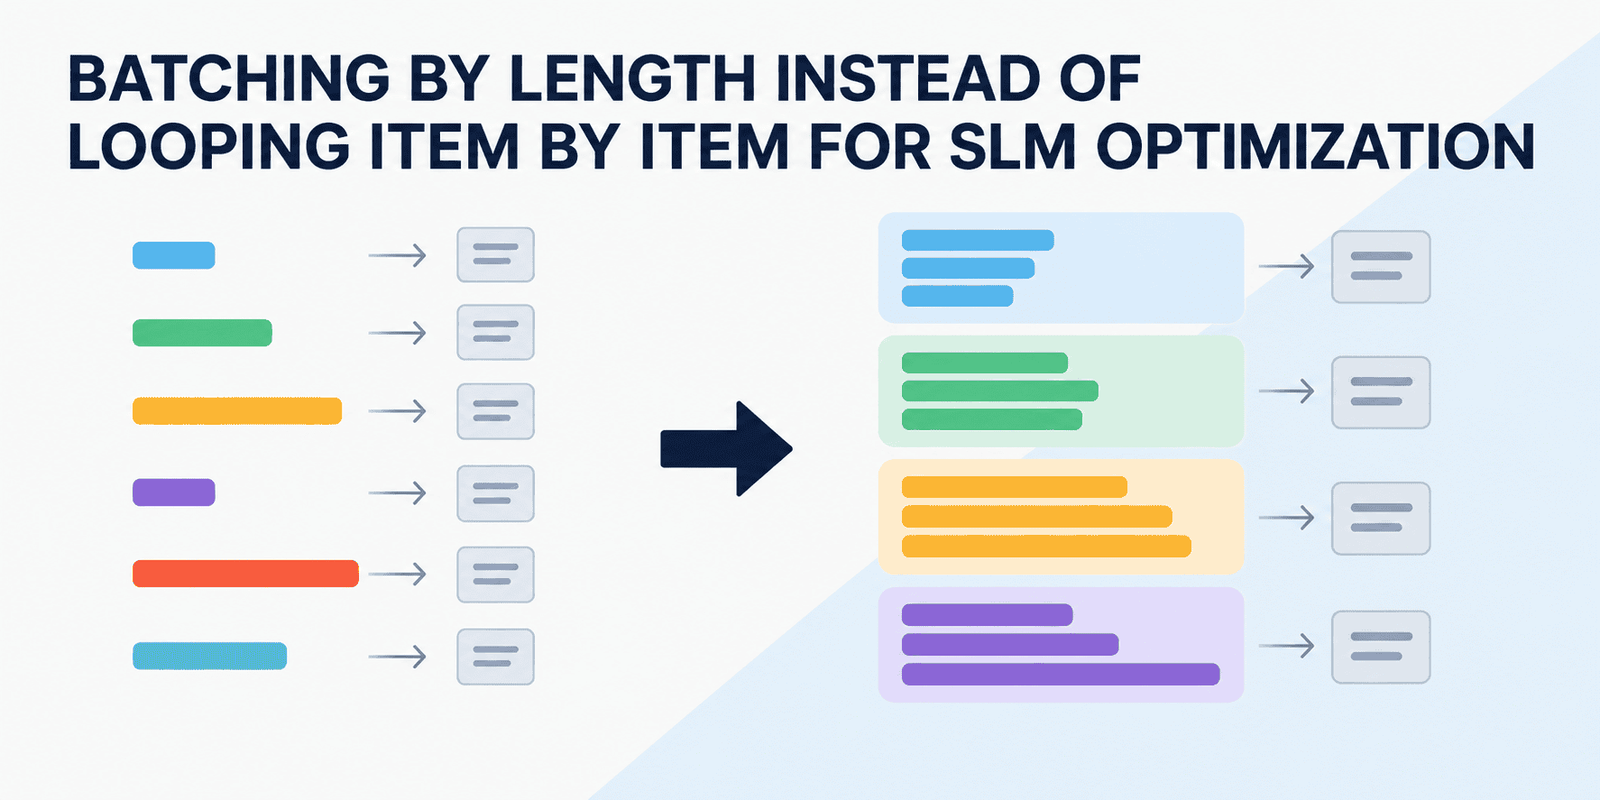
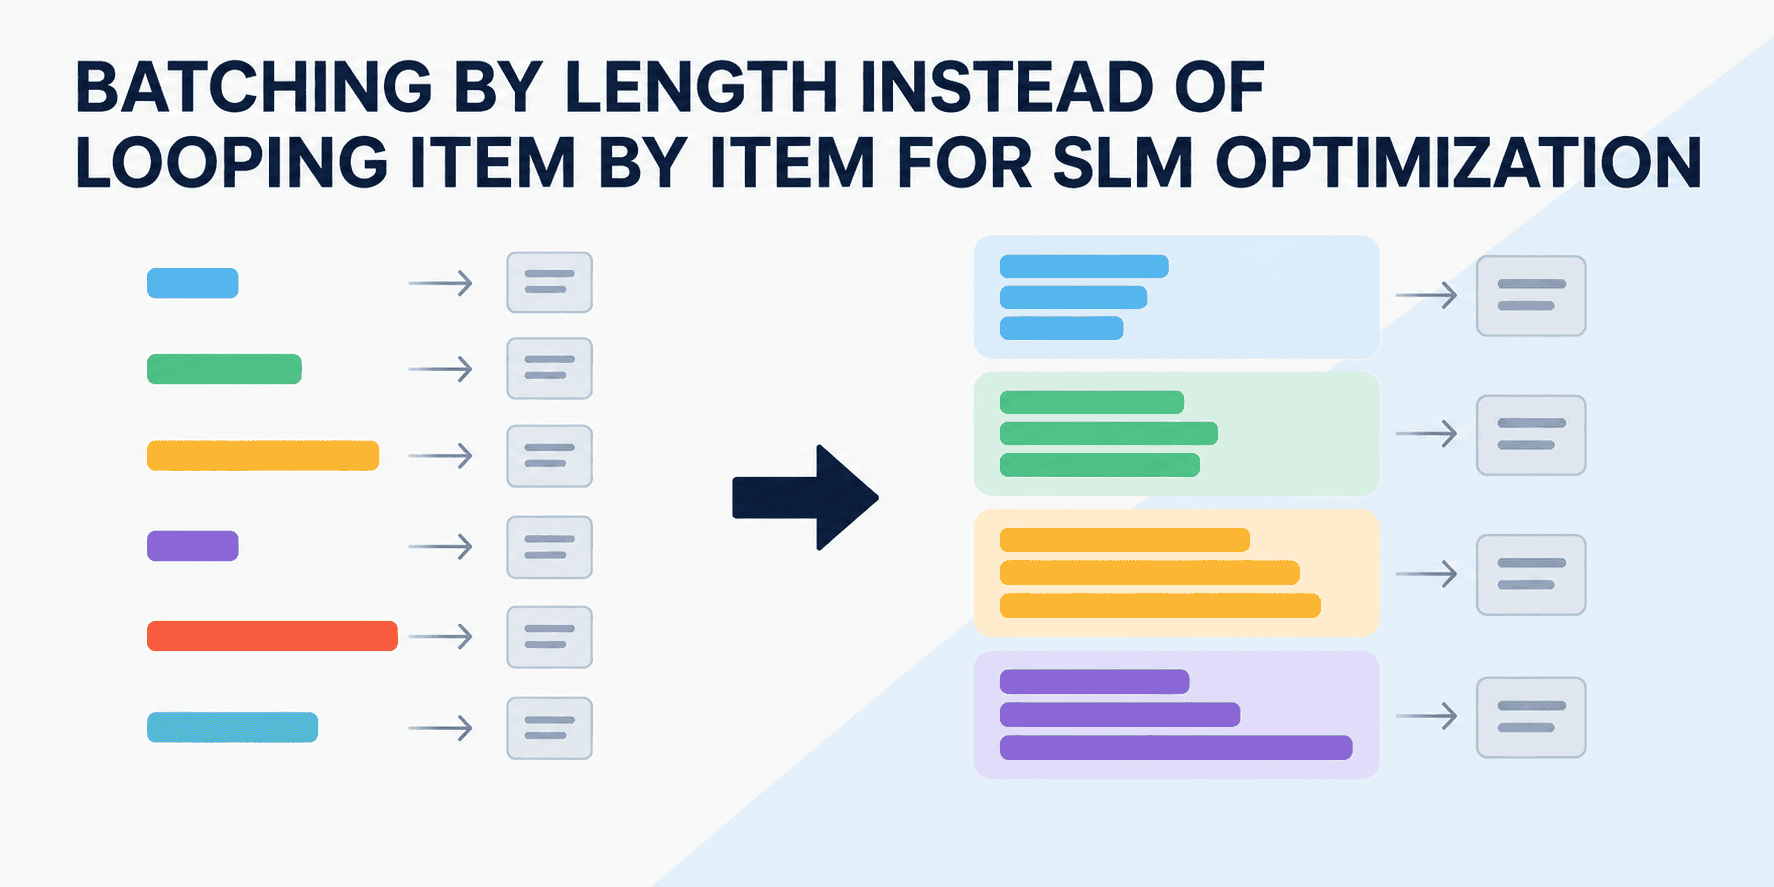
Batching amortizes that weight learn throughout many sequences. However the apparent implementation introduces its personal waste, since sequences in a batch should be padded to a typical size. Actual-world textual content has a protracted tail: if the longest merchandise in your dataset is a number of hundred tokens and the median is effectively underneath 100, padding each batch to the worldwide most means most of what you compute is padding.
The reply is to type by token size earlier than forming batches, so every batch incorporates equally sized objects and pads to its personal native most.
Looping Merchandise by Merchandise
Right here is the per-item baseline on a practical size distribution, with the constrained scoring from the primary article on this sequence carried ahead so that every merchandise prices precisely one ahead cross:
import os
import time
import examine
import torch
import numpy as np
from transformers import AutoTokenizer, AutoModelForCausalLM

MODEL_ID = "Qwen/Qwen2.5-0.5B-Instruct"

torch.set_num_threads(os.cpu_count() or 1)

tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)
if tokenizer.pad_token is None:
    tokenizer.pad_token = tokenizer.eos_token
tokenizer.padding_side = "left"  # retains the final actual token at index -1

mannequin = AutoModelForCausalLM.from_pretrained(MODEL_ID, dtype=torch.float32)
mannequin.eval()

LABELS = ["billing", "technical", "account"]

# constrained scoring, carried over from the primary article on this sequence
label_first_ids = [tokenizer.encode(label, add_special_tokens=False)[0] for label in LABELS]
assert len(set(label_first_ids)) == len(LABELS), (
    "Labels share a primary token; rating full label sequences as an alternative."
)
label_first_ids = torch.tensor(label_first_ids, system=mannequin.system)

# a causal LM returns a logit vector for each place by default; at batch 32 by
# 400 tokens that could be a multi-gigabyte tensor we'd instantly throw away, so
# ask for the final place solely the place the put in model helps it
_forward_params = examine.signature(mannequin.ahead).parameters
if "logits_to_keep" in _forward_params:
    LAST_LOGIT_ONLY = {"logits_to_keep": 1}
elif "num_logits_to_keep" in _forward_params:
    LAST_LOGIT_ONLY = {"num_logits_to_keep": 1}
else:
    LAST_LOGIT_ONLY = {}


def build_prompt(ticket):
    messages = [
        {
            "role": "system",
            "content": "You classify support tickets. Answer with exactly one of: billing, technical, account.",
        },
        {"role": "user", "content": f"Ticket: {ticket}nCategory:"},
    ]
    return tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)


# simulate a long-tailed ticket size distribution: most objects are brief, a number of
# are very lengthy. Every ticket retains an actual, classifiable sentence on the entrance and
# is prolonged with filler, so size varies with out the label sign disappearing.
BASE_TICKETS = [
    "My card was charged twice for the same invoice.",
    "The mobile app crashes whenever I open the settings page.",
    "I need to change the email address on my profile.",
]
FILLER = (
    "I've been ready for a response for a number of days now and would actually "
    "respect an replace on this every time somebody will get an opportunity to take a look at it."
).break up()

rng = np.random.default_rng(0)
target_words = np.clip(rng.lognormal(np.log(60), 0.9, measurement=600), 12, 400).astype(int)


def make_ticket(base, n_words):
    phrases = base.break up()
    whereas len(phrases) < n_words:
        phrases += FILLER
    return " ".be a part of(phrases[:n_words])


tickets_var = [make_ticket(BASE_TICKETS[i % 3], int(n)) for i, n in enumerate(target_words)]

prompts = [build_prompt(t) for t in tickets_var]
token_lengths = [len(tokenizer(p, add_special_tokens=False)["input_ids"]) for p in prompts]

print(
    f"Immediate lengths: min {min(token_lengths)}, "
    f"median {int(np.median(token_lengths))}, "
    f"max {max(token_lengths)} tokens"
)
print(f"Padding each merchandise to the worldwide most would course of "
      f"{max(token_lengths) * len(prompts) / sum(token_lengths):.1f}x the required tokens")

# time inference
baseline_predictions = []
begin = time.time()

for n, immediate in enumerate(prompts, begin=1):

    # this loop runs for minutes on CPU, so report progress somewhat than sitting silent
    if n % 100 == 0:
        print(f"  {n}/{len(prompts)} tickets ({(time.time() - begin) / n:.2f}s every)", flush=True)

    inputs = tokenizer(immediate, add_special_tokens=False, return_tensors="pt").to(mannequin.system)
    with torch.no_grad():
        logits = mannequin(**inputs, **LAST_LOGIT_ONLY).logits[0, -1, :]
    baseline_predictions.append(LABELS[int(logits[label_first_ids].argmax())])

duration_loop = time.time() - begin

# output process metrics
print(f"One after the other: {duration_loop:.2f} seconds ({len(prompts) / duration_loop:.1f} objects/sec)")
Output:
Immediate lengths: min 48, median 94, max 449 tokens
Padding each merchandise to the worldwide most would course of 3.7x the required tokens
  100/600 tickets (0.24s every)
  200/600 tickets (0.23s every)
  300/600 tickets (0.23s every)
  400/600 tickets (0.23s every)
  500/600 tickets (0.24s every)
  600/600 tickets (0.24s every)
One after the other: 144.35 seconds (4.2 objects/sec)
Batching by Size
Now the batched model. It runs the identical information twice: as soon as in arbitrary order, to isolate what batching alone is value, and as soon as sorted by size, to indicate what the sorting provides on high. Each runs observe how a lot of the processed token funds went to padding.
import os
import time
import examine
import torch
import numpy as np
from transformers import AutoTokenizer, AutoModelForCausalLM

MODEL_ID = "Qwen/Qwen2.5-0.5B-Instruct"
BATCH_SIZE = 32

torch.set_num_threads(os.cpu_count() or 1)

tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)
if tokenizer.pad_token is None:
    tokenizer.pad_token = tokenizer.eos_token

# preserve the final actual token at index -1
tokenizer.padding_side = "left"

mannequin = AutoModelForCausalLM.from_pretrained(MODEL_ID, dtype=torch.float32)
mannequin.eval()

LABELS = ["billing", "technical", "account"]
label_first_ids = [tokenizer.encode(label, add_special_tokens=False)[0] for label in LABELS]
assert len(set(label_first_ids)) == len(LABELS), (
    "Labels share a primary token; rating full label sequences as an alternative."
)
label_first_ids = torch.tensor(label_first_ids, system=mannequin.system)

_forward_params = examine.signature(mannequin.ahead).parameters
if "logits_to_keep" in _forward_params:
    LAST_LOGIT_ONLY = {"logits_to_keep": 1}
elif "num_logits_to_keep" in _forward_params:
    LAST_LOGIT_ONLY = {"num_logits_to_keep": 1}
else:
    LAST_LOGIT_ONLY = {}


def build_prompt(ticket):
    messages = [
        {
            "role": "system",
            "content": "You classify support tickets. Answer with exactly one of: billing, technical, account.",
        },
        {"role": "user", "content": f"Ticket: {ticket}nCategory:"},
    ]
    return tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)


BASE_TICKETS = [
    "My card was charged twice for the same invoice.",
    "The mobile app crashes whenever I open the settings page.",
    "I need to change the email address on my profile.",
]
FILLER = (
    "I've been ready for a response for a number of days now and would actually "
    "respect an replace on this every time somebody will get an opportunity to take a look at it."
).break up()

rng = np.random.default_rng(0)
target_words = np.clip(rng.lognormal(np.log(60), 0.9, measurement=600), 12, 400).astype(int)


def make_ticket(base, n_words):
    phrases = base.break up()
    whereas len(phrases) < n_words:
        phrases += FILLER
    return " ".be a part of(phrases[:n_words])


tickets_var = [make_ticket(BASE_TICKETS[i % 3], int(n)) for i, n in enumerate(target_words)]
prompts = [build_prompt(t) for t in tickets_var]
token_lengths = [len(tokenizer(p, add_special_tokens=False)["input_ids"]) for p in prompts]

print(
    f"Immediate lengths: min {min(token_lengths)}, "
    f"median {int(np.median(token_lengths))}, "
    f"max {max(token_lengths)} tokens"
)


def run_batched(order, batch_size):
    predictions = [None] * len(prompts)
    processed_tokens = real_tokens = 0
    begin = time.time()
    for i in vary(0, len(order), batch_size):
        idx = order[i:i + batch_size]
        batch = tokenizer(
            [prompts[j] for j in idx],
            add_special_tokens=False,
            padding=True,
            return_tensors="pt",
        ).to(mannequin.system)
        processed_tokens += batch["input_ids"].numel()
        real_tokens += int(batch["attention_mask"].sum())
        with torch.no_grad():
            logits = mannequin(**batch, **LAST_LOGIT_ONLY).logits[:, -1, :]
        finest = logits[:, label_first_ids].argmax(dim=-1)
        for slot, alternative in zip(idx, finest.tolist(), strict=True):
            predictions[slot] = LABELS[choice]
    return predictions, time.time() - begin, processed_tokens, real_tokens


def classify_one(immediate):
    """Reference path: a single unpadded sequence. Used solely to confirm."""
    inputs = tokenizer(immediate, add_special_tokens=False, return_tensors="pt").to(mannequin.system)
    with torch.no_grad():
        logits = mannequin(**inputs, **LAST_LOGIT_ONLY).logits[0, -1, :]
    return LABELS[int(logits[label_first_ids].argmax())]


order = sorted(vary(len(prompts)), key=lambda i: token_lengths[i])
predictions, duration_batched, processed, actual = run_batched(order, BATCH_SIZE)

print(f"Size-bucketed batching: {duration_batched:.2f} seconds ({len(prompts) / duration_batched:.1f} objects/sec)")
print(f"Padding overhead: {100 * (1 - actual / processed):.1f}% of processed tokens had been padding")

# correctness: padded rows should rating the identical as unpadded ones. test a variety of
# lengths somewhat than all 600, because the level is to catch a padding-side or
# place bug, and such a bug reveals up on the very first padded row.
probe = order[::60]
mismatches = [i for i in probe if classify_one(prompts[i]) != predictions[i]]
print(f"Batched vs unbatched settlement on {len(probe)} probes: {len(probe) - len(mismatches)}/{len(probe)}")
assert not mismatches, f"Batched path disagrees at indices {mismatches}"

# estimate the per-item price on the identical probe set, then scale
begin = time.time()
for i in probe:
    classify_one(prompts[i])
Output:
Loading weights: 100%|████████████████████████████████████████████████████████████████████| 290/290 [00:01<00:00, 252.11it/s]
Immediate lengths: min 48, median 94, max 449 tokens
Size-bucketed batching: 79.60 seconds (7.5 objects/sec)
Padding overhead: 7.6% of processed tokens had been padding
Batched vs unbatched settlement on 10 probes: 10/10
A big throughput improve on similar {hardware} and an similar mannequin, purely from how the work was scheduled. Be aware that the 2 batched runs do the identical arithmetic per actual token and differ solely in how a lot padding they carry, so the hole between them is a direct measurement of what the kind buys you.
- Setting
padding_side = "left"is required right here, not a alternative. With proper padding,logits[:, -1, :]would land on a pad token for each row shorter than the batch most, deceptively producing rubbish predictions. Left padding ensures index-1is the true ultimate token of each sequence. - Left padding does shift every row’s absolute token positions, as a result of a plain
mannequin(**batch)name numbers positions from zero throughout the padded width somewhat than deriving them from the eye masks. For a rotary-embedding mannequin like Qwen2.5 that is innocent, since consideration relies upon solely on the relative distance between tokens and each actual token in a row shifts by the identical quantity. For a mannequin with realized absolute place embeddings it could not be innocent, and also you would want to crossposition_idsconstructed from the masks. Both method, the settlement test in opposition to the per-item loop is what tells you which of them scenario you might be in. - Ask for the final place’s logits solely. By default a causal LM returns a logit vector for each enter place, and the vocabulary right here is round 150k entries: at batch 32 by 400 tokens in float32 that could be a multi-gigabyte tensor allotted and discarded on each single batch.
logits_to_keep=1(namednum_logits_to_keepin older variations of Transformers) suppresses it. That is negligible at batch measurement 1 with a brief immediate, which is why it by no means got here up within the earlier articles, and it dominates all the pieces else when you begin batching lengthy inputs. - Sorting earlier than chunking holds padding overhead to some p.c. The identical information by means of fixed-size batches in arbitrary order pushes it far increased, which is the distinction the script measures immediately somewhat than asserting: each padding token is a token the {hardware} processed for no motive.
- Sorting reorders the information, so preserve the unique indices round and write outcomes again to their correct slots, because the
orderchecklist does above. Shedding the alignment between inputs and predictions is a straightforward and really costly bug, and in contrast to a crash it produces plausible-looking output. - Decide
BATCH_SIZEby measuring, not by instinct, which is what the sweep on the finish of the script is for. Throughput climbs steeply after which plateaus when you saturate compute; previous that time you might be solely rising the chances of an out-of-memory error in your longest bucket. The perfect worth depends upon your {hardware} and in your size distribution, so it’s value re-running the sweep when both modifications.
One caveat: prefix caching and batching want care to mix. The cache we constructed within the earlier article has a batch dimension of 1, so reusing it throughout a batch means increasing each key and worth tensor alongside that dimension to match, and cropping it again appropriately afterwards. It’s value doing when your prefix is lengthy, however do it intentionally and confirm the predictions in opposition to the unbatched path somewhat than assuming the 2 optimizations compose totally free.
Wrapping Up
This has been our third and ultimate try at optimizing SLMs for our slender automation sequence, and our goal method this time was length-bucketed batching. This system replaces a one-item-at-a-time loop with sorted batches that pad to their very own native most, which will get the {hardware} out of the memory-bandwidth-bound regime with out paying for the padding that naive batching would introduce. By implementing it, we course of the identical 600 tickets in a fraction of the wall-clock time, with the identical predictions popping out the opposite finish.
None of those methods makes the mannequin “smarter.” Each was verified by checking that its output was similar to the slower path it changed, and that test is the entire motive to belief the speedup numbers in any respect. An optimization that modifications your predictions is just not an optimization, it’s a regression with a stopwatch hooked up.
To recap the sequence:
- Constrained scoring replaces free-form technology and string parsing with a single ahead cross restricted to the legitimate label set, making malformed output structurally unattainable whereas handing you a confidence rating for routing edge circumstances to people
- Prefix key-value caching computes the static instruction block as soon as as an alternative of as soon as per merchandise, and pays off in proportion to how a lot of your immediate by no means modifications
- Size-bucketed batching will get the {hardware} out of the memory-bandwidth-bound constraint and retains padding overhead close to zero by grouping equally sized inputs collectively
Matthew Mayo (@mattmayo13) holds a grasp’s diploma in laptop science and a graduate diploma in information mining. As managing editor of KDnuggets & Statology, and contributing editor at Machine Studying Mastery, Matthew goals to make complicated information science ideas accessible. His skilled pursuits embrace pure language processing, language fashions, machine studying algorithms, and exploring rising AI. He’s pushed by a mission to democratize data within the information science neighborhood. Matthew has been coding since he was 6 years outdated.