Certainly one of my favourite components of knowledge evaluation and visualization is the storytelling. I perceive that we frequently rush to conclusions as a result of the following steps — whether or not that is making enterprise selections, feeding the info to an ML mannequin, or convincing shareholders the corporate is doing nice — matter. Nevertheless, I really like making an attempt to determine the info’s story, for the sake of the story… or, higher but, to experiment with how we will inform it.
Okay, let’s step again and picture you’re evaluating two new medical remedies, A and B (I’m not inventive with names!). An preliminary evaluation reveals that remedy A has the next success charge than Remedy B. So, you take a look at the numbers, examine the calculations, and conclude that Remedy A is healthier. Appears affordable, proper?
You determine to take your pal’s opinion on the info; they level out that Remedy B has the next total success charge. So, you examine once more. The calculations are nonetheless appropriate.
You begin questioning, “Why is that this taking place?” That makes you look extra carefully and uncover that Remedy A has the next success charge than Remedy B for each affected person sort. And but Remedy B wins total!
Did somebody make a mistake? Is the info damaged? Did Python quietly determine to damage your afternoon? (It does that typically; we’ve all been there.)
No. You may need stumbled throughout one thing referred to as Simpson’s paradox.
It’s a kind of statistical phenomena that feels like a mathematical trick till you notice how simply it may well have an effect on the conclusions we draw from actual knowledge. And probably the most attention-grabbing half? You don’t want to vary a single statement to make the story reverse.
For that to make sense, let’s add extra depth to our remedy instance! Suppose the sufferers for these two remedies fall into these teams:
-
Decrease-risk sufferers, who usually tend to recuperate no matter remedy.
-
Greater-risk sufferers, who’re much less prone to recuperate no matter remedy.
For simplicity, let’s think about the next outcomes.
|
Affected person group |
Remedy A |
Remedy B |
|
Decrease-risk sufferers |
90% |
80% |
|
Greater-risk sufferers |
40% |
30% |
Remedy A wins in each teams.
Amongst lower-risk sufferers, its success charge is 10 share factors increased. Amongst higher-risk sufferers, it is usually 10 share factors increased. In case you had to decide on primarily based on these numbers alone, Remedy A would appear to be the apparent winner!
However let’s add yet one more piece of data (to make issues extra reasonable): what number of sufferers acquired every remedy.
Remedy A was given largely to higher-risk sufferers. Remedy B was given largely to lower-risk sufferers.
Now the outcomes appear to be this:
|
Affected person group |
Remedy A |
Remedy B |
|
Decrease-risk sufferers |
9 successes out of 10 |
80 out of 100 |
|
Greater-risk sufferers |
80 out of 200 |
3 out of 10 |
|
General |
89 out of 210 (42.4%) |
83 out of 110 (75.5%) |
Remedy A has the higher success charge in each teams, however Remedy B has the higher total success charge. The vital factor to our story right here is that the numbers haven’t contradicted one another; somewhat, we have now been evaluating two various things.
Inside every affected person group, Remedy A performs higher. Throughout all sufferers, Remedy B seems to carry out higher as a result of the 2 remedies got to very totally different mixes of sufferers.
The general outcome displays each the remedy outcomes and the composition of the teams being in contrast. That reversal is Simpson’s paradox.
As a lot as I really like an excellent desk, individuals perceive extra after they can visualize it! We will use Python to check success charges inside every group, then examine the general charges.
Have a look at the primary two pairs of bars: remedy A wins in each teams, however within the third pair, the winner modifications. The graph isn’t flawed. The calculations aren’t flawed. However the total comparability hides a vital distinction in who acquired every remedy.
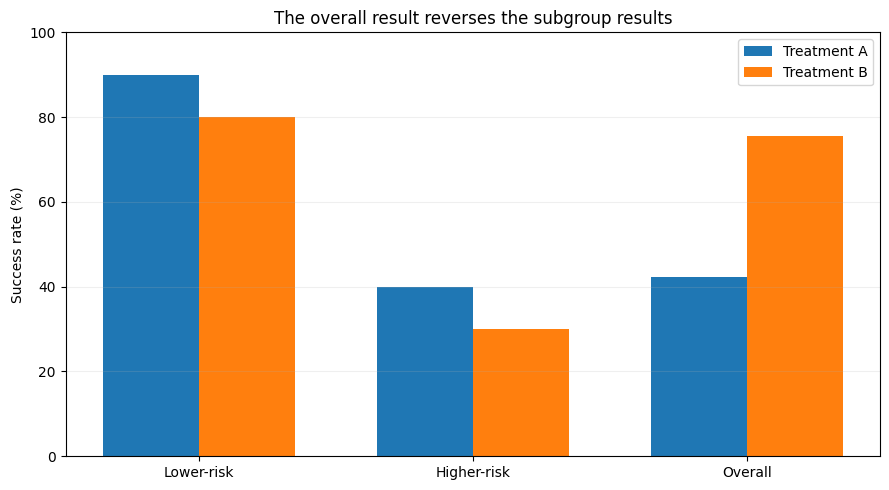
That is why a single abstract statistic could make us miss the story of our knowledge.
A deeper look
An total success charge is a weighted common of the success charges within the particular person teams. In different phrases, every group’s contribution relies upon not solely on its success charge but in addition on what number of sufferers it consists of.
For Remedy A, the general success charge is:
For Remedy B, it’s:
Remedy A’s total result’s closely influenced by its efficiency amongst higher-risk sufferers as a result of most of its sufferers are in that group. Decrease-risk sufferers dominate remedy B’s outcome as a result of most of its sufferers are in that group.
The general charge isn’t merely the common of the 2 percentages. It is a weighted common primarily based on the variety of sufferers in every group.
That is what makes Simpson’s paradox so attention-grabbing: the connection you observe in separate teams does not must match the connection you see while you mix them.
The arithmetic is doing precisely what it ought to. The query is whether or not the comparability solutions the query you truly needed to ask.
After I first discovered about this, I assumed this may be an uncommon scenario, constructed to make statistics look unreliable. Sadly, the identical sample can seem in lots of on a regular basis comparisons.
-
College admissions
A college may need the next admission charge for one group of candidates in each division, but a decrease total admission charge for that group. Why? As a result of candidates could apply to departments with very totally different acceptance charges, and teams could distribute themselves throughout departments in another way.
-
Product efficiency
Think about evaluating two variations of an software. Model A performs higher on each older and newer gadgets. However Model A is used totally on older gadgets, whereas Model B is used totally on newer ones. The general efficiency figures would possibly make Model B look quicker, although Model A performs higher inside every machine class.
-
Faculty grades
A faculty may need higher examination outcomes inside each topic however worse total outcomes as a result of its college students take a distinct mixture of topics, with totally different ranges of problem.
So that you may be questioning now, ought to we all the time break up our knowledge into teams?
Not essentially. I do know it isn’t the reply you’ll hope to listen to, however it’s an attention-grabbing one!
The purpose I’m making an attempt to make right here isn’t that aggregated knowledge is dangerous, or that subgroup evaluation is all the time appropriate. It’s that the way in which we group knowledge ought to match the query we’re making an attempt to reply.
Say you wish to know which remedy has the higher outcomes for comparable sufferers. affected person threat is important as a result of the remedies got to totally different mixes of sufferers. However if you happen to’re a hospital administrator making an attempt to grasp outcomes throughout your total present affected person inhabitants, the general charge additionally issues. It tells you what occurred throughout the sufferers who had been handled.
Each views are helpful, and which one has extra weight is determined by what precisely you are attempting to get from the info.
And there may be one other vital caveat: Simpson’s paradox doesn’t, by itself, inform us which remedy is genuinely higher. Our instance is hypothetical, and in actual medical analysis we would want to think about how sufferers had been assigned to remedies, different variations between them, uncertainty within the estimates, and the standard of the proof.
The paradox tells us to analyze the connection between the teams, to not decide whichever share we want.
So, which inquiries to ask?
You don’t have to change into a statistician each time somebody presents a bar chart. However a number of questions will help you notice when a abstract deserves a better look.
1. What’s being mixed?
Are we individuals, merchandise, departments, nations, or totally different time durations? May these teams behave in another way?
2. Are the teams comparable?
If two remedies, merchandise, or insurance policies are being in contrast, are they being utilized to comparable populations? If not, variations within the populations would possibly affect the outcome.
3. What number of observations are in every group?
A share with out its denominator could be surprisingly uninformative. A 90% success charge from 10 circumstances isn’t the identical sort of proof as a 90% success charge from 10,000 circumstances.
4. Does the conclusion change after I take a look at the subgroups?
If the general outcome factors a technique and the subgroup outcomes level one other, don’t instantly assume one is flawed. Discover out what’s driving the distinction.
5. What query is that this statistic truly answering?
This may be crucial query! A calculation could be completely appropriate and nonetheless be a poor reply to the query you care about.
Ultimate ideas
We frequently think about that statistics offers us an goal reply: put within the knowledge, run the calculation, and get the outcomes out.
However as a knowledge analyst, it’s good to make selections, quite a lot of selections! You determine which observations to incorporate, which teams to check, what to common, and which outcome to current. Every choice can change the story you find yourself with.
Simpson’s paradox is a very memorable instance as a result of it makes that downside unimaginable to disregard. A conclusion can look convincing at one degree of research and reverse at one other, with out both calculation being mathematically incorrect.
The reply isn’t to mistrust each chart, each share, or each common, however to withstand the temptation to deal with a abstract as the entire story. So, the following time somebody reveals you a statistic and says, “The numbers converse for themselves,” ask yet one more query:
Which numbers — and what occurred to the remainder?