

Scott Aaronson photos a hunter-gatherer who has spent a lifetime studying to outlive in a rainforest, solely to discover a resort opening subsequent door, full with heated swimming pools and Airbnbs. The hunter-gatherer adjusts his profession plans:
“alright wonderful, so now my new job is to run wilderness retreats for the vacationers, or one thing.”
That’s Aaronson’s analogy for the temper in arithmetic after OpenAI’s launch. He tells it in The Mathocalypse.
On 6 October 2026, OpenAI launched a group that now accommodates 719 papers in 372 teams of associated outcomes, produced by an unreleased inside mannequin. Some concern acquainted data-science duties: matching messy textual content, selecting consultant observations, producing comparability knowledge and becoming fashions. A proof can set up that a greater methodology is feasible lengthy earlier than anybody has an implementation value utilizing.
Joe Halliwell has explored a number of the launch’s broader sensible penalties. Right here, I take a narrower data-science view: what do a number of of those outcomes truly promise for acquainted computational issues, and what would stand between the theory and one thing we may use? The examples present how decisions about accuracy, distance and randomness decide the computation, storage and knowledge we’d like.
Pc science leads in households; chance leads in pages
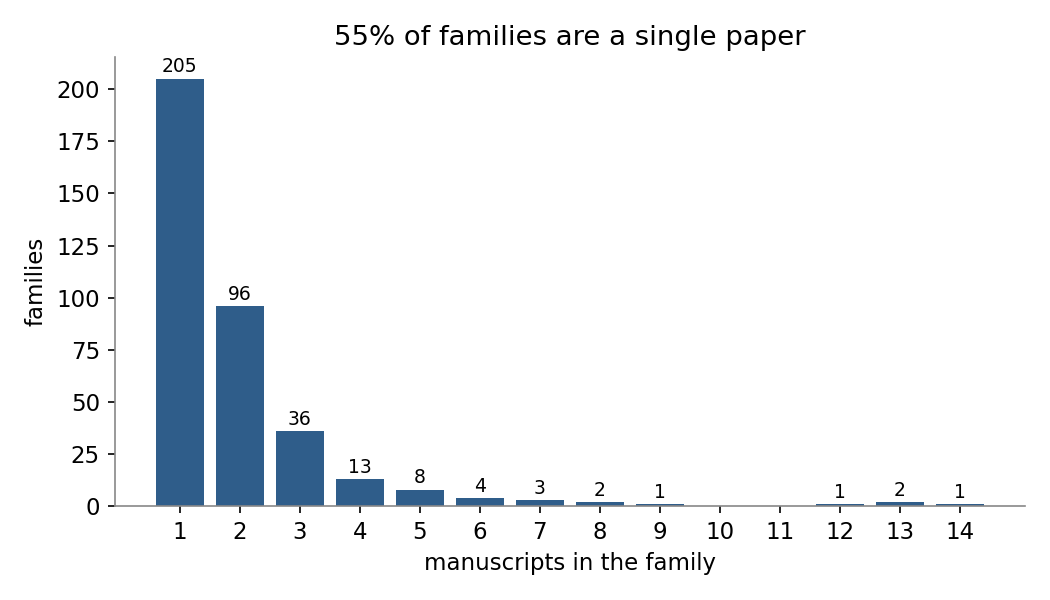
OpenAI calls every group of associated outcomes a consequence household. A household could embrace a number of related outcomes or other ways of proving one consequence. Of the 372 households, 205 comprise one paper and 301 comprise not more than two. The biggest accommodates fourteen.1
The discharge covers seventeen disciplines. Theoretical laptop science has essentially the most households, with 40, about 11% of the whole. Depend pages as a substitute, and chance and statistical mechanics takes the biggest share: 29 households comprise 105 papers and seven,232 pages, about 21% of all pages.
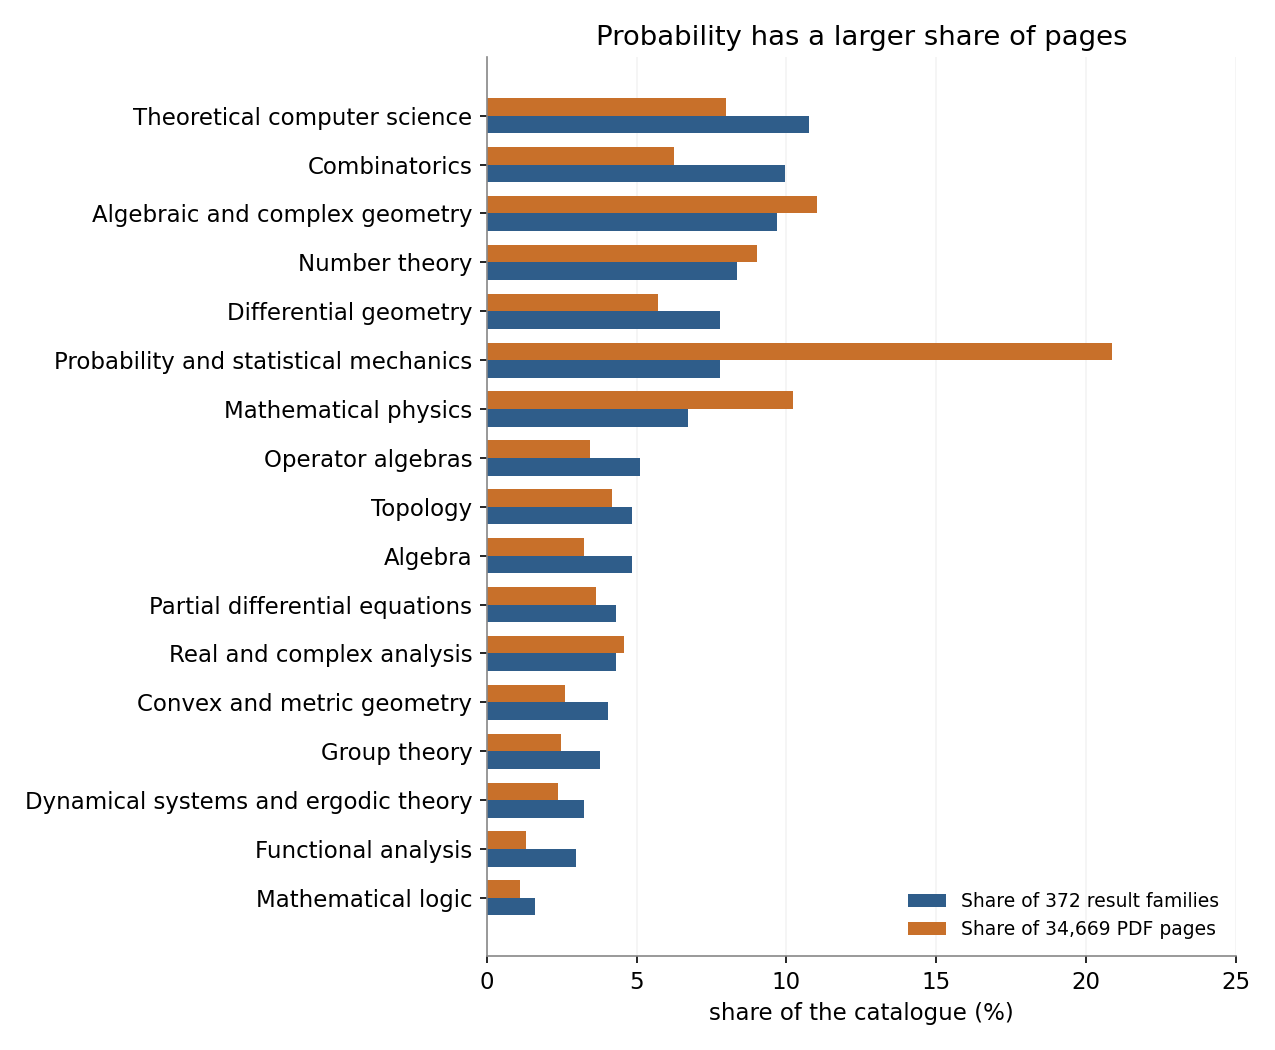
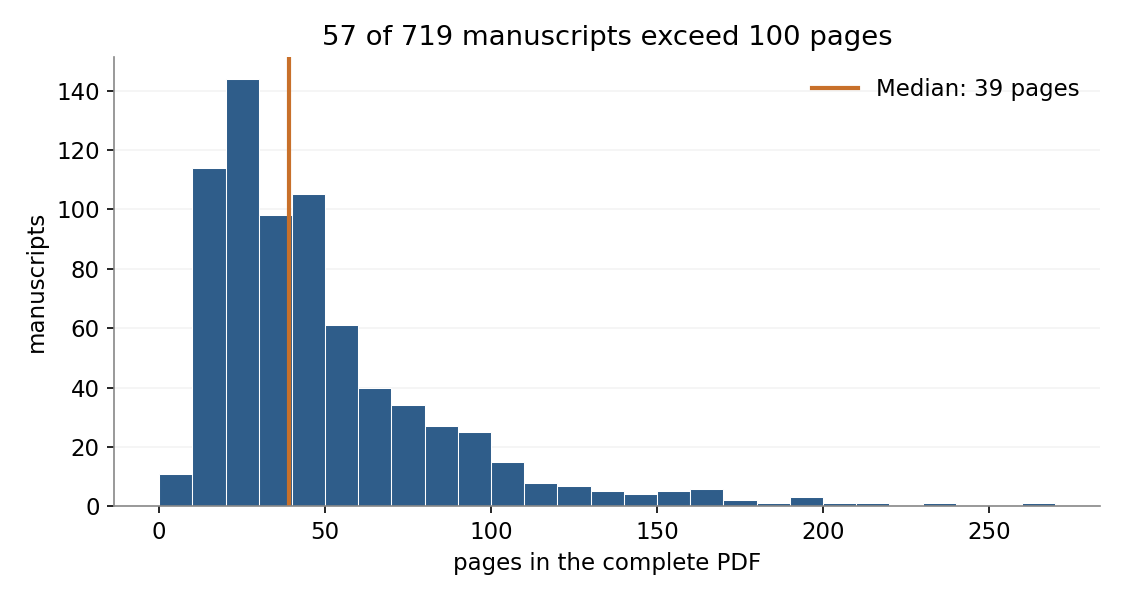
The entire assortment runs to 34,669 pages. The median paper is 39 pages lengthy, and 57 exceed 100. Studying one PDF a day would take virtually two years, assuming a 262-page paper counts as a standard Tuesday.
Some outcomes related to knowledge science sit elsewhere within the catalogue: the consequence about compressing characteristic vectors beneath is filed underneath convex and metric geometry.
Evaluating lengthy strings will get a greater pace assure
Think about two entries in a buyer desk: Jon Smith and John Smyth. A strict textual content match treats them as strangers. To check the spellings, rely the fewest single-character insertions, deletions and replacements wanted to show one into the opposite. Right here, insert an h and exchange i with y: two edits. This rely is edit distance, a helpful ingredient in matching data whose textual content differs barely.
The usual precise calculation builds a grid, with positions in a single string alongside the rows and positions within the different alongside the columns. Every cell data the most affordable technique to match the textual content as much as these positions. Two strings of 10,000 characters give about 100 million cells. Double each lengths and the grid turns into 4 occasions bigger.
The brand new edit-distance paper claims a way whose common work grows virtually in proportion to the whole textual content size, for any mounted share error allowance. Select 1%: if the true distance is 100, a profitable estimate is 100 or 101. The tactic makes use of randomness and guarantees an estimate throughout the allowance at the least two occasions out of three.2 Combining such a small error allowance with almost-linear development improves on the sooner ensures mentioned within the paper.
The printed recipe nonetheless makes use of the precise grid calculation beneath an infinite input-size threshold. Getting its higher development charge to repay at lengths we are able to truly retailer is additional work. Its output is a rating, helpful for rating candidate matches; producing the precise checklist of edits would take one other step.
A greater clustering assure limits the price of a nasty reply
Suppose you have got 1000’s of help tickets and a colleague keen to learn six. The colleague’s willingness is the scarce useful resource. You need these six tickets to symbolize the archive as intently as potential.
Symbolize every ticket as a characteristic vector, with comparable tickets shut collectively. Select some precise tickets and add up each ticket’s distance to its nearest chosen instance. A smaller complete means higher protection underneath your chosen distance measure.
For six factors on a line, 0, 1, 2, 8, 9 and 10, selecting representatives 0 and 10 provides a complete distance of 6. Selecting 1 and 9 provides 4: every serves itself and two neighbours one unit away.
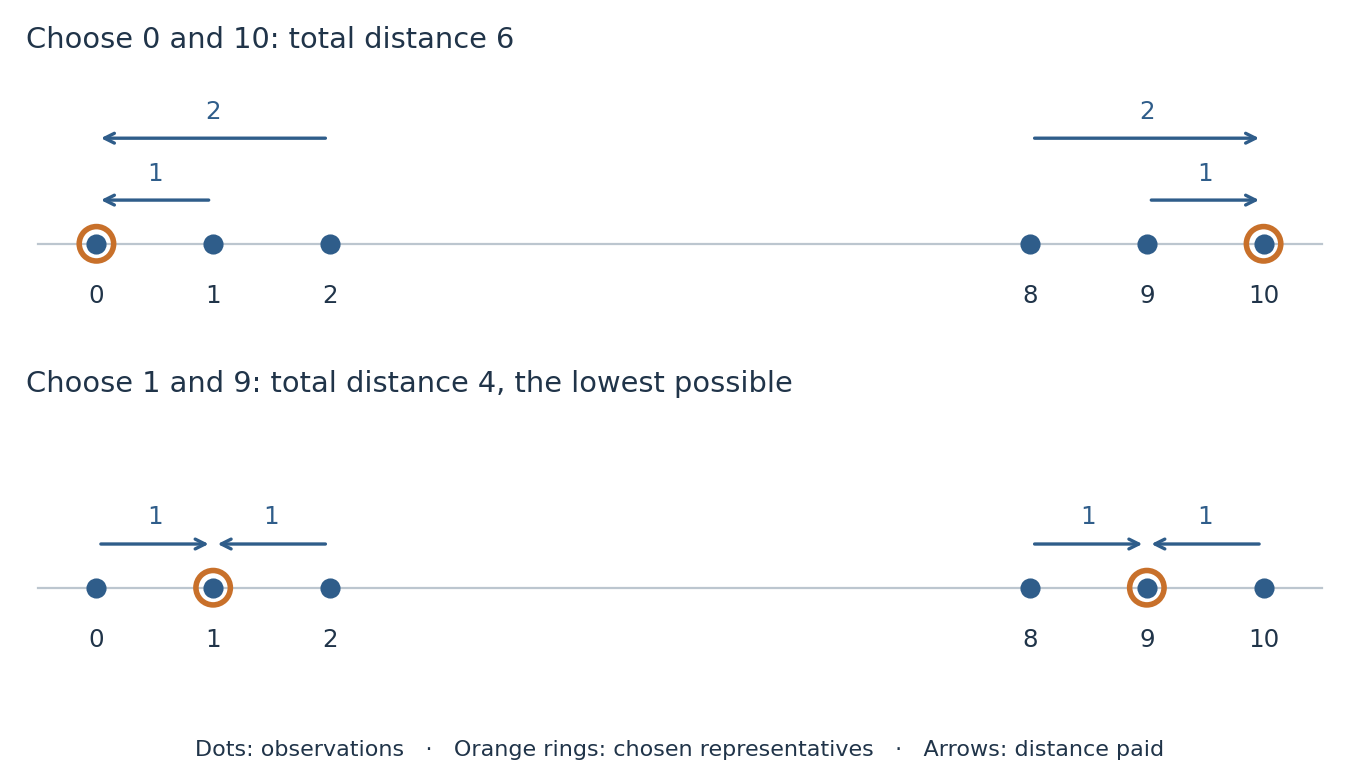
Selecting okay precise observations this manner is named k-medoids. KMeans can put a centre between observations, which is cheap geometry however awkward when your colleague asks to learn the ticket. The broader k-median downside permits a separate checklist of candidate places, similar to depots serving prospects.
The variety of potential alternatives quickly makes checking all of them costly. OpenAI’s k-median paper claims a tighter promise for its algorithm: if one of the best choice prices 100, the earlier normal assure allowed roughly 200; the brand new ceiling approaches 173.6.3This approximation assure covers each allowed dataset. Distances should obey the rule {that a} detour by a 3rd level can’t be shorter than the direct journey.
The algorithm begins with a neater depot plan that allows partial openings. Six places serve buyer pairs AB, BC, AC, DE, EF and DF. Every buyer is distance 1 from its two related places and distance 3 from the remainder. We are able to open three depots. Opening all six midway provides every buyer half its service from every close by location: value 1 per buyer, 6 general. Six half-open depots match the price range, although the constructing contractor might want additional directions.4
Complete depots value at the least 8: selecting AB, BC and DE leaves F travelling distance 3 whereas everybody else travels 1. Giving all six prospects a close-by depot wants 4 openings. The code ready for this put up confirms each optima, 6 and eight.
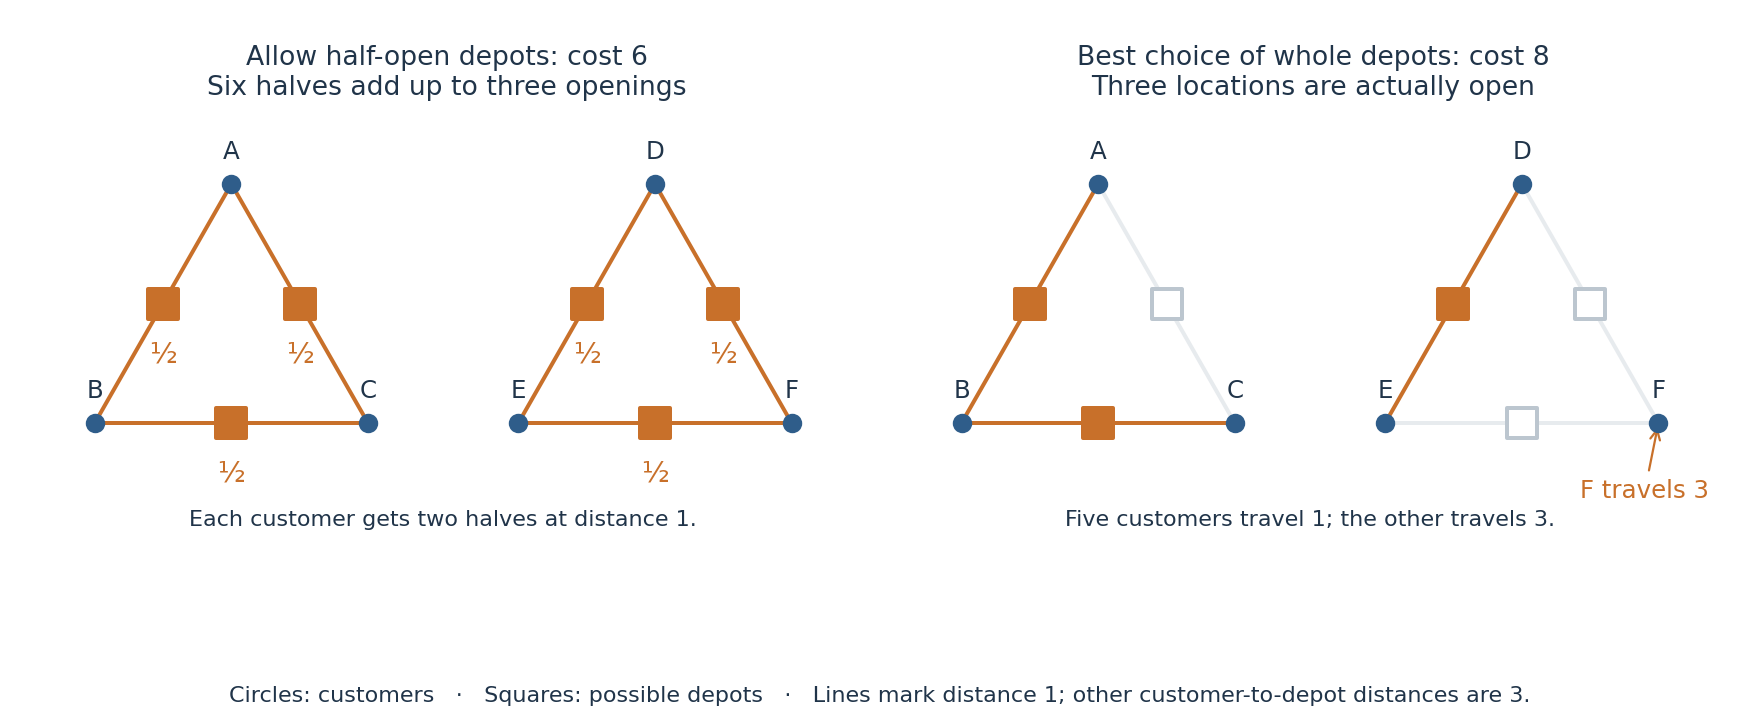
Permitting partial openings can solely make one of the best plan cheaper. Changing that optimistic plan to entire depots is named rounding. Controlling the additional value helps show a assure: an answer costing at most twice the optimistic plan additionally prices at most twice one of the best actual plan.
I needed to benchmark the entire algorithm. Following its printed recipe actually, even for a looser assure, divides one totally open location into greater than 6 × 10²⁸ tiny items. Touching every as soon as at a hypothetical trillion items per second would take almost two billion years.5 A sensible implementation would want to keep away from creating each bit individually.
Acquainted clustering strategies already do effectively on the small take a look at
The present benchmark compares acquainted strategies on fifteen small issues. An optimisation solver established their finest prices inside its numerical tolerances.6 A typical shortcut swaps representatives each time that lowers the fee, stopping when no single swap helps. A bigger rearrangement would possibly nonetheless do higher.
Two variations of this swapping methodology every matched one of the best value on fourteen of fifteen issues; their largest misses had been 0.8% and 0.3%. Changing every KMeans centre with its nearest precise remark was at worst 4.2% above one of the best value.
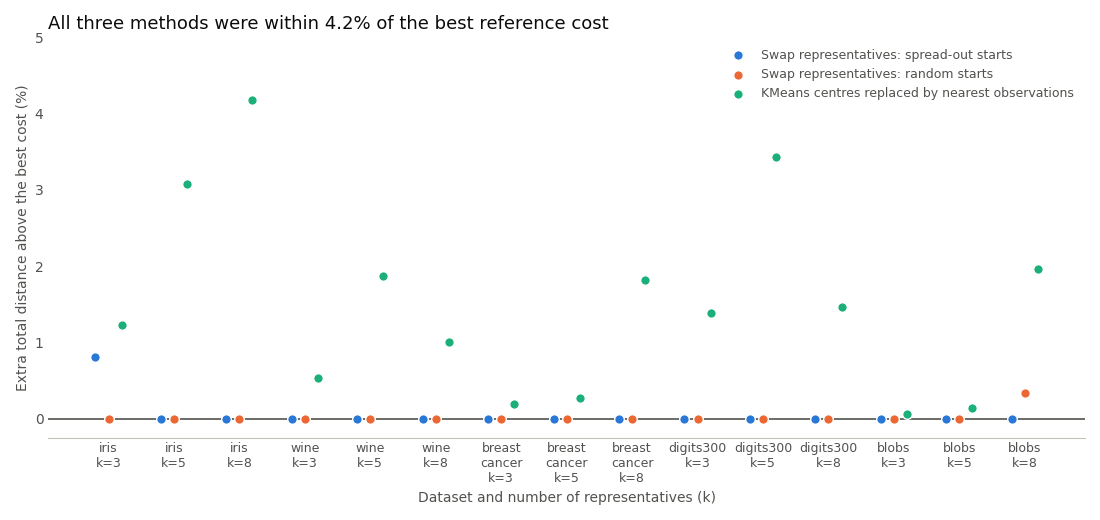
These pretty pleasant datasets go away little room to enhance reply high quality. Evaluating OpenAI’s algorithm will want a working implementation, tougher examples and timings.
Random tables can protect each row and column complete
Suppose you have got counts of tea and occasional gross sales in two areas:
|
Area |
Tea |
Espresso |
Complete |
|---|---|---|---|
|
North |
40 |
10 |
50 |
|
South |
20 |
30 |
50 |
|
Complete |
60 |
40 |
100 |
To check the regional sample, you can generate comparability tables that maintain each units of totals mounted. Every area should nonetheless promote 50 drinks, with 60 teas and 40 coffees general. Giving every area 30 teas and 20 coffees is one various. Shifting a sale between cells forces compensating modifications elsewhere.
This can be a contingency desk: counts break up by two classes. One technique to randomise it provides each desk satisfying the totals an equal probability. In our tiny instance, selecting North’s tea rely determines all three different cells. Bigger tables go away many interdependent decisions.
The brand new sampling paper claims a way that produces precisely this uniform distribution for arbitrary appropriate totals, with each the variety of rows and columns free to develop. Earlier running-time ensures described in its introduction required restrictions, similar to a hard and fast variety of rows. The brand new assure covers very uneven totals too.7
That gives a technique to assemble random knowledge whereas retaining chosen options of the unique. The chance mannequin issues: giving each desk equal weight differs from shuffling particular person gross sales data, which might produce some tables in additional methods than others. I’d determine which comparability matches the evaluation earlier than selecting a sampler.
The paper’s running-time certain is a median over random decisions, with intentionally massive powers within the formulation. Turning that assure right into a helpful data-generation software nonetheless wants implementation and measurement.
Restricted reminiscence can power a learner to make use of extra knowledge
Think about becoming a mannequin as rows arrive, with out holding the dataset. Helpful info from previous rows should survive within the learner’s saved state.
Suppose two unknown numbers, a and b, have sum 3 and distinction 1. Collectively these observations give a = 2 and b = 1. Overlook the sum, and each (2, 1) and (2.5, 1.5) match the remaining info. Extra computation can’t get better the excellence; one other remark may.
With a protracted stream and a hard and fast reminiscence price range, the learner should select what survives. The memory-and-precision paper research usually distributed inputs and labels calculated from the true weights with no noise. Reminiscence contains the bits wanted to retailer numbers precisely.
A hard and fast-size abstract has finitely many states, so completely different histories can go away similar saved info. Finer estimates require extra distinctions between potential weights. Conserving additional digits can protect these distinctions, however makes use of extra reminiscence.
For any abstract inside its said reminiscence price range, the paper bounds the pattern price range the learner have to be allowed. That decrease restrict grows with the variety of occasions you halve the permitted error.8 Computation between observations is limitless.
This connects how a lot knowledge to gather with how a lot info to retain. Even the theory’s very thoughtful dataset, with no mistaken labels in any respect, can’t take away that trade-off.
Accepting a little bit distance error can save many coordinates
A characteristic vector is a row of numbers. To seek out comparable observations, you could want the distances between rows greater than each unique coordinate.
Observations at (0, 0), (3, 4) and (6, 8) have distances 5, 5 and 10. Retailer them as 0, 5 and 10 on one axis, and people distances survive utilizing one quantity per remark. This dimension discount is straightforward as a result of the factors already lie on a line.
Present strategies protect atypical straight-line distances roughly in way more sophisticated datasets. The brand new paper issues different distance guidelines. One provides fourth powers of coordinate variations and takes a fourth root, as a substitute of utilizing squares and a sq. root. From (0, 0), the space to (1, 1) turns into about 1.19 quite than 1.41, whereas (1, 0) stays distance 1. The rule modifications what counts as comparable.
Utilizing the chosen rule earlier than and after compression, preserving distances precisely can require quite a few coordinates that grows because the sq. of the variety of observations. Enable a hard and fast share of error, and the paper’s certain ultimately grows extra slowly than the sq. root of that quantity.9
A ten% allowance signifies that, after multiplying each new distance by the identical quantity, no distance shrinks and none grows by greater than 10%. Nearest neighbours can nonetheless swap order: distances 100 and 101 may develop into 110 and 101.
The proof establishes that such a illustration exists for the provided factors. An environment friendly development and dealing with later observations stay additional work.
The pace data use other ways of counting work
The pace claims for 3 acquainted operations rely upon how work is counted.
|
Activity |
What the paper claims |
What the paper counts |
|---|---|---|
|
A greater development charge for the variety of arithmetic operations as matrices get bigger.10 |
Arithmetic operations. The paper “doesn’t specify a aggressive finite matrix measurement”. |
|
|
Fourier transforms, which break a sign into frequencies |
A small enchancment within the development of the arithmetic work wanted for bigger inputs.11 |
Actual arithmetic operations. Odd FFT software program makes use of rounded calculations. |
|
A greater certain on the variety of requests for operate values and gradients, for a restricted class of distributions.12 |
Requests for values and gradients; computation between requests is unrestricted. |
The sampling consequence makes use of the accounting of a report that counts database queries and regards all of the Python afterwards as a private matter. Ten calls can nonetheless be adopted by a day processing their responses.
A paper on shifting one distribution onto one other finds a weaker stability assure than researchers had conjectured: comparable goal distributions can require much less comparable actions of particular person factors.13 For a data-alignment pipeline, I’d test how observations transfer in addition to how intently the distributions match.
Pc-checked proofs nonetheless want a cautious studying of the declare
A proof checker is a program that checks whether or not an argument’s steps set up a exactly written assertion from its assumptions. Lean is one such program, and journalist Kevin Hartnett tells the story of its growth in The Proof within the Code.
OpenAI experiences computer-checked proofs for the principle ends in 300 of its 719 papers, about 42%. These checks cowl particular outcomes inside every paper. For instance, the quasi-Riemann paper’s computer-checked proof covers its principal consequence, however leaves out the additional conclusions the paper attracts from it.
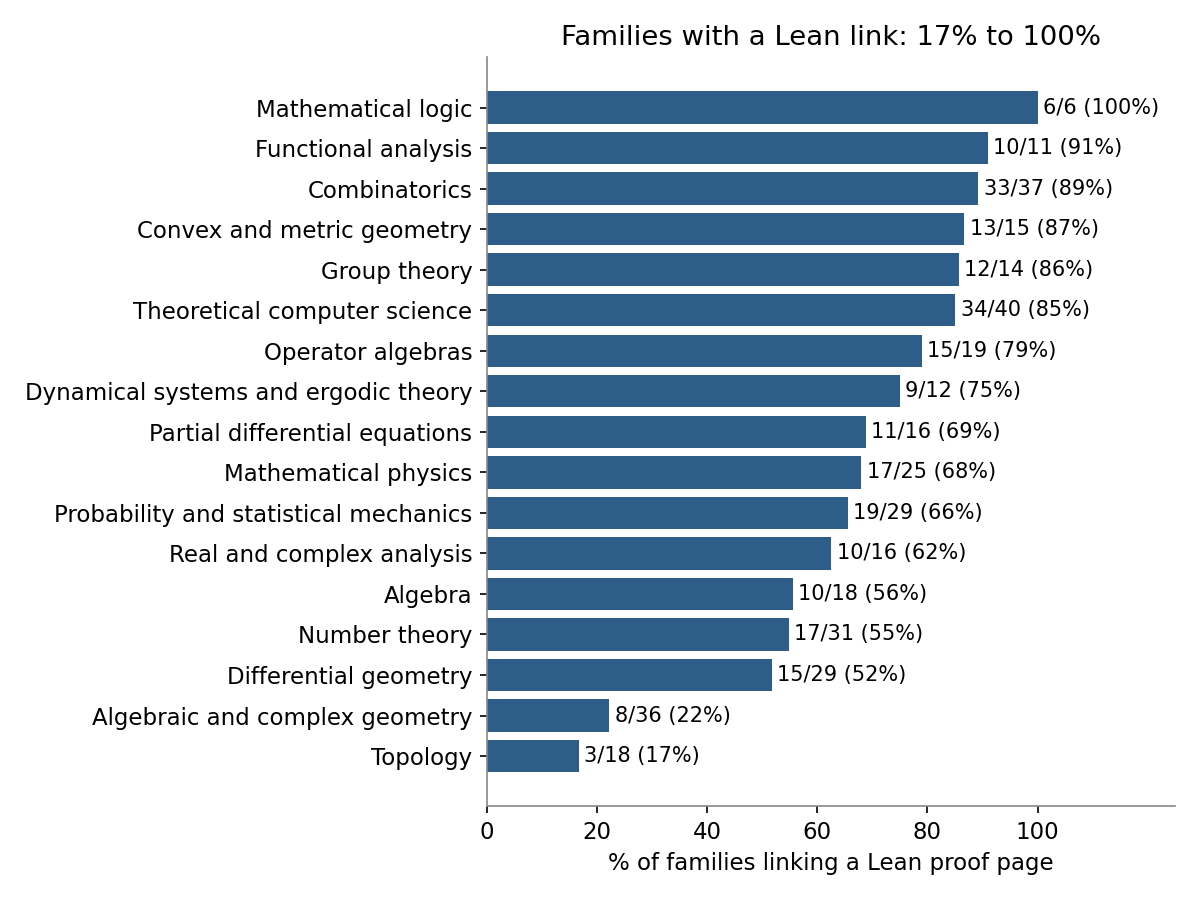
{The catalogue} lets us make a special rely: teams of associated papers that hyperlink to a web page describing a Lean proof. All six mathematical-logic households have such a hyperlink, in contrast with three of eighteen topology households. Total it’s 242 of 372 households, about 65%. Every scope web page specifies which ends its proof covers.
The repository historical past data three withdrawn papers: an indication error invalidated one development and two papers that relied on it.
Consultants are discovering concepts value studying within the unfamiliar proofs
Dana Moshkovitz had spent roughly 20 years engaged on Distinctive Video games, an issue related to limits on how intently algorithms can strategy one of the best reply. Her first response to the brand new proof was confusion. Aaronson quoted her complaints about unexplained steps and complicated citations, and her description of the development as “some alien craziness”.
She requested Astra, an AI assistant, to elucidate the proof interactively. By the next day, Aaronson reported that she largely understood the proof and was amazed by its new concepts.
Within the feedback, Jonathan Baxter suggests {that a} mannequin could deal with an argument scattered throughout ten pages as equal to a clearly organised model. Consider inheriting a pocket book that produces the correct reply, when you uncover that cell 47 has to run earlier than cell 12. Getting it to work and understanding it effectively sufficient to vary it are separate jobs.
Aaronson compares the mannequin to a junior researcher with extraordinary breadth of information, the power to attach strategies throughout fields and strange persistence. Moshkovitz additionally emphasises that the brand new outcomes construct on human communities and earlier work.
I feel it is a purpose to check the discharge even earlier than its algorithms are sensible. A technique that appears unwieldy within the normal proof could comprise an concept we are able to adapt to a narrower job. Understanding the reasoning is what would allow us to determine that concept and test whether or not our adaptation nonetheless works.
There may be one other consequence of creating these outcomes public. Hugging Face has already transformed 369 of OpenAI’s mathematical challenges into reinforcement-learning environments, the place fashions try formal proofs and obtain suggestions from a verifier. This isn’t typical mannequin distillation: no entry to OpenAI’s weights or inside reasoning is required. As an alternative, it presents a type of functionality switch, permitting smaller open fashions to coach in opposition to mathematical issues and verification infrastructure derived from frontier analysis. The present verifier is restricted, nonetheless, and might reject mathematically equal proofs expressed in another way. The attention-grabbing query is whether or not this coaching generalises past reproducing recognized outcomes. May a 7B-parameter mannequin, in the end operating on commodity {hardware}, use what it has discovered to make a genuinely new mathematical discovery? Fixing a Millennium Prize Downside could be a rare demonstration, though there may be nonetheless an infinite distance between these coaching environments and that ambition.
For the k-median paper, the following helpful step is to show its partial-opening plan right into a manageable implementation, determine which guarantees survive any simplification, and evaluate each reply high quality and operating time.
Disclaimer: This was a casual, curiosity-driven challenge undertaken in my private time. The views expressed listed below are my very own and don’t symbolize these of my employer or any affiliated organisation. The content material relies on private expertise and reflection, and shouldn’t be taken as skilled or tutorial recommendation.
···
-
Counts use the groupings, topic labels and PDFs in repository snapshot fd4aeeb, checked on 10 October 2026. All 719 PDFs had been counted, together with references and appendices. Lean protection counts teams with a hyperlink to a web page describing a proper proof.↩︎
-
Every inserted, deleted or changed character prices one. The accuracy allowance stays mounted because the strings get longer. Common work means a median over the algorithm’s random decisions, even for the toughest enter pair of a given size; it contains studying the strings and the remainder of the computation. The consequence estimates the space between a pair of strings, so discovering candidate pairs in a big desk stays a separate job.↩︎
-
The issue is roughly 1.736 plus a small constructive allowance. Selecting an allowance of 0.004 provides an element beneath 1.74; smaller allowances could require way more computation. The sooner roughly-two assure held with excessive chance over random decisions; the brand new algorithm makes use of no randomness. Each ensures concern algorithms whose work grows at most as a hard and fast energy of the enter measurement. The assure covers the overall depot downside, together with instances the place candidate depots and prospects occupy completely different places.↩︎
-
Clients are distance 2 from each other, as are depot places. These distances obey the rule that going through a 3rd level can’t shorten a journey. Every buyer should contribute at the least 1, so the partial-opening complete of 6 is as little as potential. All twenty decisions of three entire depots had been checked.↩︎
-
The calculation follows the proof’s directions for a assure of about 1.836 occasions one of the best value. They require at the least 6.1 × 10²⁸ items. Dividing by a hypothetical trillion items per second, then by the seconds in a 12 months, provides about 1.94 billion years.↩︎
-
The benchmark compares the three present strategies proven within the chart. It makes use of iris, wine, breast most cancers, 300 handwritten-digit examples and 300 artificial factors, every with 3, 5 and eight representatives. Options had been placed on a typical scale. The solver discovered one of the best value for all fifteen instances inside its numerical tolerances. Every swapping methodology saved one of the best of ten begins. Its largest hole was 0.8% with spread-out begins and 0.3% with random begins.↩︎
-
Counts are nonnegative entire numbers, with no forbidden cells or additional cell limits. Anticipated work is polynomial within the row and column counts and the variety of binary digits wanted for the totals. A really uncommon department does exhaustive computation, so the certain applies on common, to not each run.↩︎
-
Reminiscence is measured in bits, so storing extra digits makes use of extra of the price range. The concept permits reminiscence proportional to the sq. of the variety of options. It assumes many options, precise labels and usually distributed inputs. The learner should estimate the route of randomly chosen weights, with at the least a two-thirds probability of success. Error is measured because the angle between the discovered and true instructions.↩︎
-
These distance guidelines add powers of absolute coordinate variations, then take the corresponding root. The ability might be any mounted finite quantity higher than 1. Odd straight-line distance makes use of energy 2 and already has a stronger recognized consequence. The brand new illustration can reshape the information in sophisticated methods; it needn’t be a straight projection.↩︎
-
The paper brings the expansion exponent arbitrarily near 2.25, down from about 2.37. The exponent describes how the work scales as matrices get bigger; fixed multipliers nonetheless matter for any precise calculation.↩︎
-
Ignoring fixed multipliers, the previous and new formulation differ by solely about 4 elements in ten trillion at 2⁶⁴ inputs. The paper assumes arithmetic with out rounding and experiences monumental fixed multipliers. The algorithm is given an actual advanced quantity representing a specified rotation. Multipliers and intermediate values don’t have any measurement restrict.↩︎
-
The paper works with a easy, bowl-shaped operate: the detrimental log-density plus a relentless. In each route, the speed at which its slope modifications should keep between 1 and a pair of. The underside of the bowl is provided. Every request returns the operate’s precise worth and gradient. The samples should match the goal inside a hard and fast error tolerance.↩︎
-
The beginning distribution is uniform over a bounded area in at the least two dimensions. The straight path between any two factors within the area should keep inside it. The goal additionally stays inside a hard and fast bounded area. A goal with simply three potential places is sufficient to present why the stronger proposed assure fails.↩︎