

Of their paper FrugalGPT: The way to Use Giant Language Fashions Whereas Decreasing Price and Enhancing Efficiency, Lingjiao Chen, Matei Zaharia, and James Zou describe 3 ways to chop the price of calling a big language mannequin (LLM). They name these immediate adaptation, LLM approximation, and LLM cascade. The authors report that their cascade tries cheaper fashions first. On the duties they examined, it can match the efficiency of the most effective particular person mannequin with as much as 98 p.c value discount. That quantity belongs to their duties, so an agent that reads rental listings wants its personal measurement.
I constructed a small agent I might examine name by name. It checks house listings in opposition to a renter’s necessities, corresponding to a two bed room in Austin below $1,500 that permits canines. My first model despatched each itemizing to a robust mannequin, even when a metropolis identify or a lease determine already dominated the itemizing out. After I opened the hint, that meant 2,500 mannequin calls to seek out 101 actual matches.
That first model is a straw man, so this text measures three beginning factors as a substitute of 1. The primary sends each pair to the mannequin. The second is an agent that already searches by metropolis. The third runs a database question on metropolis, bedrooms, and lease earlier than any mannequin sees an inventory, which is what a cautious engineer would construct first.
This text reveals what I ran. I took a set pattern of 500 listings from a public dataset of 2019 United States rental adverts. I wrote 5 renter necessities and scored each model of the agent in opposition to the identical solutions. The sturdy mannequin was OpenAI’s gpt-6-sol, which I name Sol, and the cheaper mannequin was gpt-6-luna, which I name Luna.
I traced each name with Weights & Biases (W&B) Weave, the W&B instrument that information every step of an utility. The entire script is within the article, and the logged tables are in a W&B Report.
Towards the database question place to begin, the ultimate model value about 25 instances much less. The estimated value was $0.008 in opposition to $0.20 for a similar 2,500 checks, and the ultimate model returned all 101 matches with no unsuitable ones. Letting code settle the pets subject made up about 44 p.c of that drop, and utilizing the cheaper mannequin with a robust backup made up about 39 p.c. A shorter immediate and reused solutions made up the remaining.
The totals weren’t essentially the most helpful a part of the take a look at. Three findings stunned me, and I stored all of them.
-
Weave’s value column confirmed $0.0000 for each name. The true token counts had been saved within the uncooked report, however the utilization desk displayed zero.
-
Sol missed a match 10 instances out of 10 with the total itemizing, and located it 10 instances out of 10 with solely the title and physique. Sending much less textual content gave a greater reply.
-
Each fashions reported a confidence of 5 on virtually each reply. A rule that escalates beneath 5 virtually by no means fires, so it can’t do a lot work.
The article additionally says the place the take a look at is weak. Solely one of many 101 matches will depend on studying textual content, so the take a look at measures value much better than it measures understanding.
What does the agent learn, and the way did I construct the take a look at?
The agent solutions one sure or no query for every itemizing and every renter requirement. I name one itemizing checked in opposition to one requirement a pair, so 500 listings and 5 necessities make 2,500 pairs.
The listings come from the Condo for Lease Categorized dataset within the College of California, Irvine (UCI) Machine Studying Repository. It holds 10,000 United States rental adverts with 22 fields, together with the title, the physique textual content, facilities, bedrooms, loos, lease, sq. ft, metropolis, state, and pets allowed. The dataset is licensed below Inventive Commons Attribution 4.0, and its itemizing timestamps run from September to December 2019. These are historic adverts, so nothing right here describes right now’s rents.
The pattern has 500 listings chosen with a set random seed of 42. It holds 200 from Austin, 100 from Dallas, 100 from Houston, and 100 from different cities. 5 renter necessities run in opposition to it, and each requirement additionally asks for a spot that permits canines.
-
Austin, 1 bed room, lease as much as $1,300.
-
Austin, 2 bedrooms, lease as much as $1,800.
-
Austin, 2 bedrooms, lease as much as $1,500.
-
Dallas, 2 bedrooms, lease as much as $1,600.
-
Houston, 1 bed room, lease as much as $1,200.
The combination of cities is deliberate, as a result of a feed that covers a number of cities offers a filter one thing to reject. It additionally flatters the filter, and I return to that restrict within the outcomes. The prompts and the traces pass over the road handle, the coordinates, and the supply itemizing ID. Solely a row quantity corresponding to row_3445 identifies an inventory.
How do I do know a match is right, and what counts as value?
A pair is a real match when the itemizing is in the precise metropolis, has the precise variety of bedrooms, prices not more than the lease restrict, and permits canines. The primary three checks use fields with express values. The pets subject says issues like “Cats,Canines” or “Cats”, and that decides the fourth verify each time the sphere is crammed in.
The pets subject is clean on 4,163 of the ten,000 listings, so the textual content has to resolve these. There are 128 sampled listings that go the town, bed room, and lease checks with a clean pets subject. An AI assistant (Claude) learn each title and physique of these listings in opposition to one written rule. The rule says canines are allowed solely when the textual content says canines or pets are allowed. Silence, or a touch that doesn’t say so straight, counts as not confirmed.
The end result was lopsided. One itemizing, row_3445, calls itself “a pet pleasant group” and provides a 25 pound weight restrict, so I depend it as a match. Two listings trace at pets with out saying so. row_1808 lists a “Pet park” and row_8465 mentions “a pet bar on your favourite 4 legged associates”, so each depend as not confirmed. The opposite 125 listings say nothing about pets.
Earlier than this studying, I had written a key phrase seek for phrases corresponding to “pet pleasant” and “no pets”. It agreed with the studying on all 128 listings.
Two limits comply with from this. The labels are one reader’s judgment, and the 2 trace listings are controversial. Additionally, only one of the 101 true matches will depend on studying textual content, as a result of the opposite 100 come from the pets subject. The take a look at due to this fact says far more about value than about how properly a mannequin understands rental adverts.
Precision and recall rating the end result. Precision is the share of returned matches which can be right, and better is best. Recall is the share of true matches that had been returned, and better is best. With 101 true matches, one miss strikes recall by about one share level.
Price right here means API inference value, which is what the supplier fees for tokens. A token is a small chunk of textual content, roughly a brief phrase, and suppliers invoice enter tokens and output tokens at completely different charges. Output tokens embrace the hidden reasoning tokens a mannequin spends considering earlier than it solutions. The OpenAI pricing web page listed these normal charges on September 27, 2026. Sol value $2.00 per million enter tokens and $10.00 per million output tokens, and Luna value $0.10 and $0.50.
Each greenback determine beneath is an estimate from these charges and the token counts every response reported. It isn’t an bill, and it leaves out infrastructure and labor. I additionally report mannequin time, which is the sum of the time each name took.
How do I run the experiment?
The steps beneath work on macOS and Linux. On Home windows, activate the surroundings with .venvScriptsactivate. I ran every little thing with Python 3.9.6 and these bundle variations, weave 0.52.17, openai 2.48.0, pandas 2.3.3, and py7zr 1.0.0. The script wants an OpenAI API key with billing enabled and a free W&B account with its API key. With out the W&B key, the script stops when it calls weave.init, so the traces and the report are unavailable.
Create the working folder, set up the packages, and set each keys within the terminal you’ll use for each command on this article.
The dataset downloads as a zipper file that holds a compressed 7z file. These instructions fetch and unpack it right into a information folder, which leaves information/apartments_for_rent_classified_10K.csv in place.
Save the next script as apartment_agent.py within the apartment-agent-cost folder. It holds every little thing the experiment wants, together with the necessities, the sphere guidelines, the bottom fact labels, the prompts, the cache, and the six configurations. Feedback within the code mark the elements the later sections clarify.
Run the configurations from the apartment-agent-cost folder, one command every. The baseline run makes 2,500 Sol calls and takes a number of minutes, and the others are faster.
Every command saves its full outcomes to an outputs folder and prints a abstract. The block beneath is captured output from a rerun of the luna configuration in a contemporary folder with the precise script above.
The fashions don’t settle for a temperature setting, so each run makes use of the default and solutions can differ from run to run. Your numbers shall be near those on this article and won’t match digit for digit. The rerun above already reveals a distinction, as a result of it made no unsuitable match, and the run I captured for the comparability made one. The part on the cheaper mannequin explains why.
What does the baseline hint present?
The hint of the ship each pair baseline reveals one mannequin name per pair and no signal of which calls had been wanted. Weave information this by wrapping a operate with @weave.op, and the OpenAI integration provides a baby name for each request to the mannequin. Every hint is a tree of calls with inputs, outputs, timing, and token counts, and it really works like a receipt that lists each step the agent took.
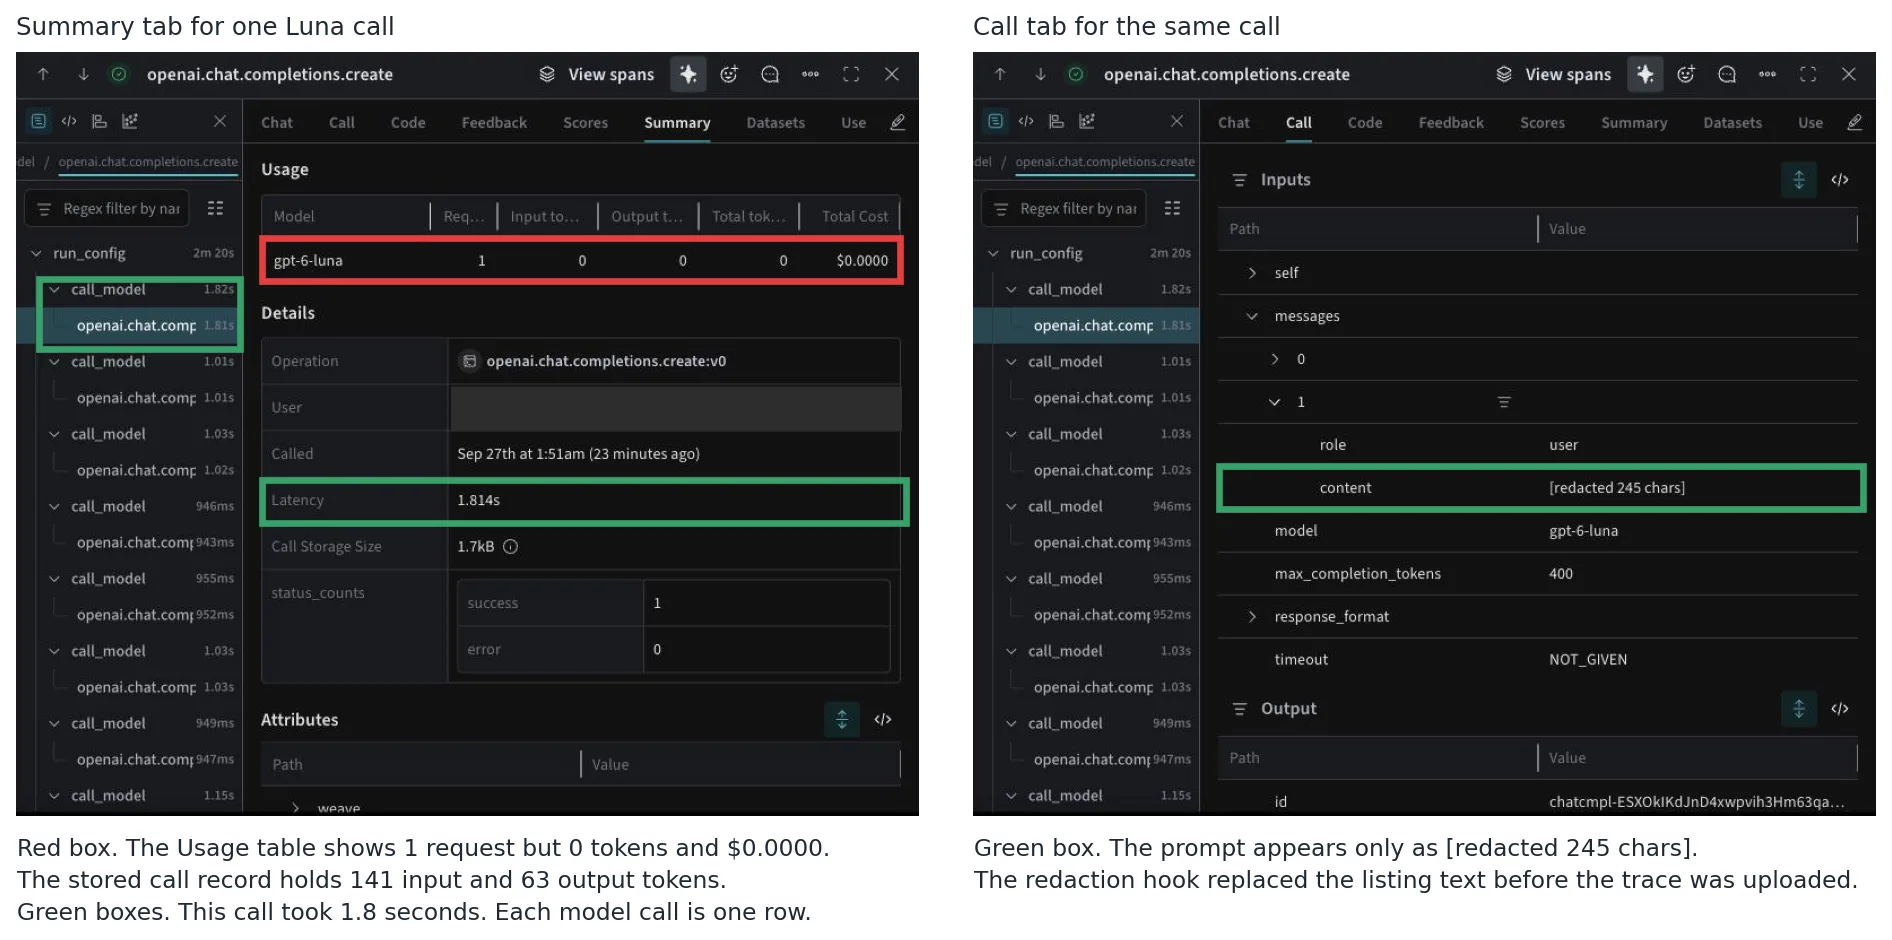
gpt-6-luna name whose Utilization desk reads 0 tokens and $0.0000, although the saved report holds 141 enter and 63 output tokens. The best view reveals the immediate changed by a redaction be aware, so value figures on this article come from saved token counts and the speed card.The left view of the screenshot comprises essentially the most stunning results of the setup. Weave counted the request accurately, but its Utilization desk confirmed zero tokens and a complete value of $0.0000 for each fashions. The Weave value documentation says Weave applies inbuilt pricing for supported integrations. It additionally describes an add_cost() methodology for fashions and not using a worth, and these runs didn’t use it.
A zero isn’t a worth, so I calculated value from the token counts saved in every name report. The one name within the screenshot used 141 enter and 63 output tokens.
The best view reveals the redaction. The script passes a global_postprocess_inputs operate to weave.init, and that operate replaces each immediate with a be aware corresponding to [redacted 245 chars] earlier than the hint uploads. I then searched each saved name within the mission for distinctive itemizing phrases and for 400 avenue addresses from the pattern, and located none.
That first baseline is straightforward to summarize. Sol made 2,500 calls, one per pair, utilizing 618,635 enter tokens and 63,782 output tokens, of which 18,424 had been reasoning tokens. The estimated value was $1.88, and the calls added as much as 2,991 seconds of mannequin time. The baseline ran eight calls directly, so its wall clock time was 376 seconds.
Is sending each itemizing to a mannequin a good place to begin?
No, and a fairer comparability shrinks the financial savings. Sending each pair to Sol is the model I constructed first, and few actual brokers do it. Most slender the feed earlier than a mannequin sees something, so I measured two extra beginning factors on the identical 2,500 pairs with the identical full itemizing immediate.
The second place to begin sends solely pairs whose metropolis matches. It made 796 Sol calls and price an estimated $0.61, so it’s about 3 instances cheaper than sending every little thing. The third runs a database question on metropolis, bedrooms, and lease, then sends every surviving pair to Sol. It made 264 calls and price an estimated $0.20, about 9 instances cheaper than sending every little thing. That question is extraordinary database work and has no mannequin value.
All three runs missed the identical match, row_3445, which the subsequent sections clarify. I measure each later saving in opposition to the $0.20 question place to begin, as a result of a cautious engineer would construct it first. It nonetheless spends mannequin calls on 264 pairs, and people pairs are the place the remainder of the article begins.
Which mannequin calls can the pets subject settle and not using a mannequin?
One other 107 of these 264. A mail room clerk types envelopes by postal code, and the identical clerk may see that some envelopes already carry an approval stamp. The pets subject works like that stamp. When it’s crammed in, it says canines are allowed or it says they don’t seem to be, and no mannequin must learn the itemizing.
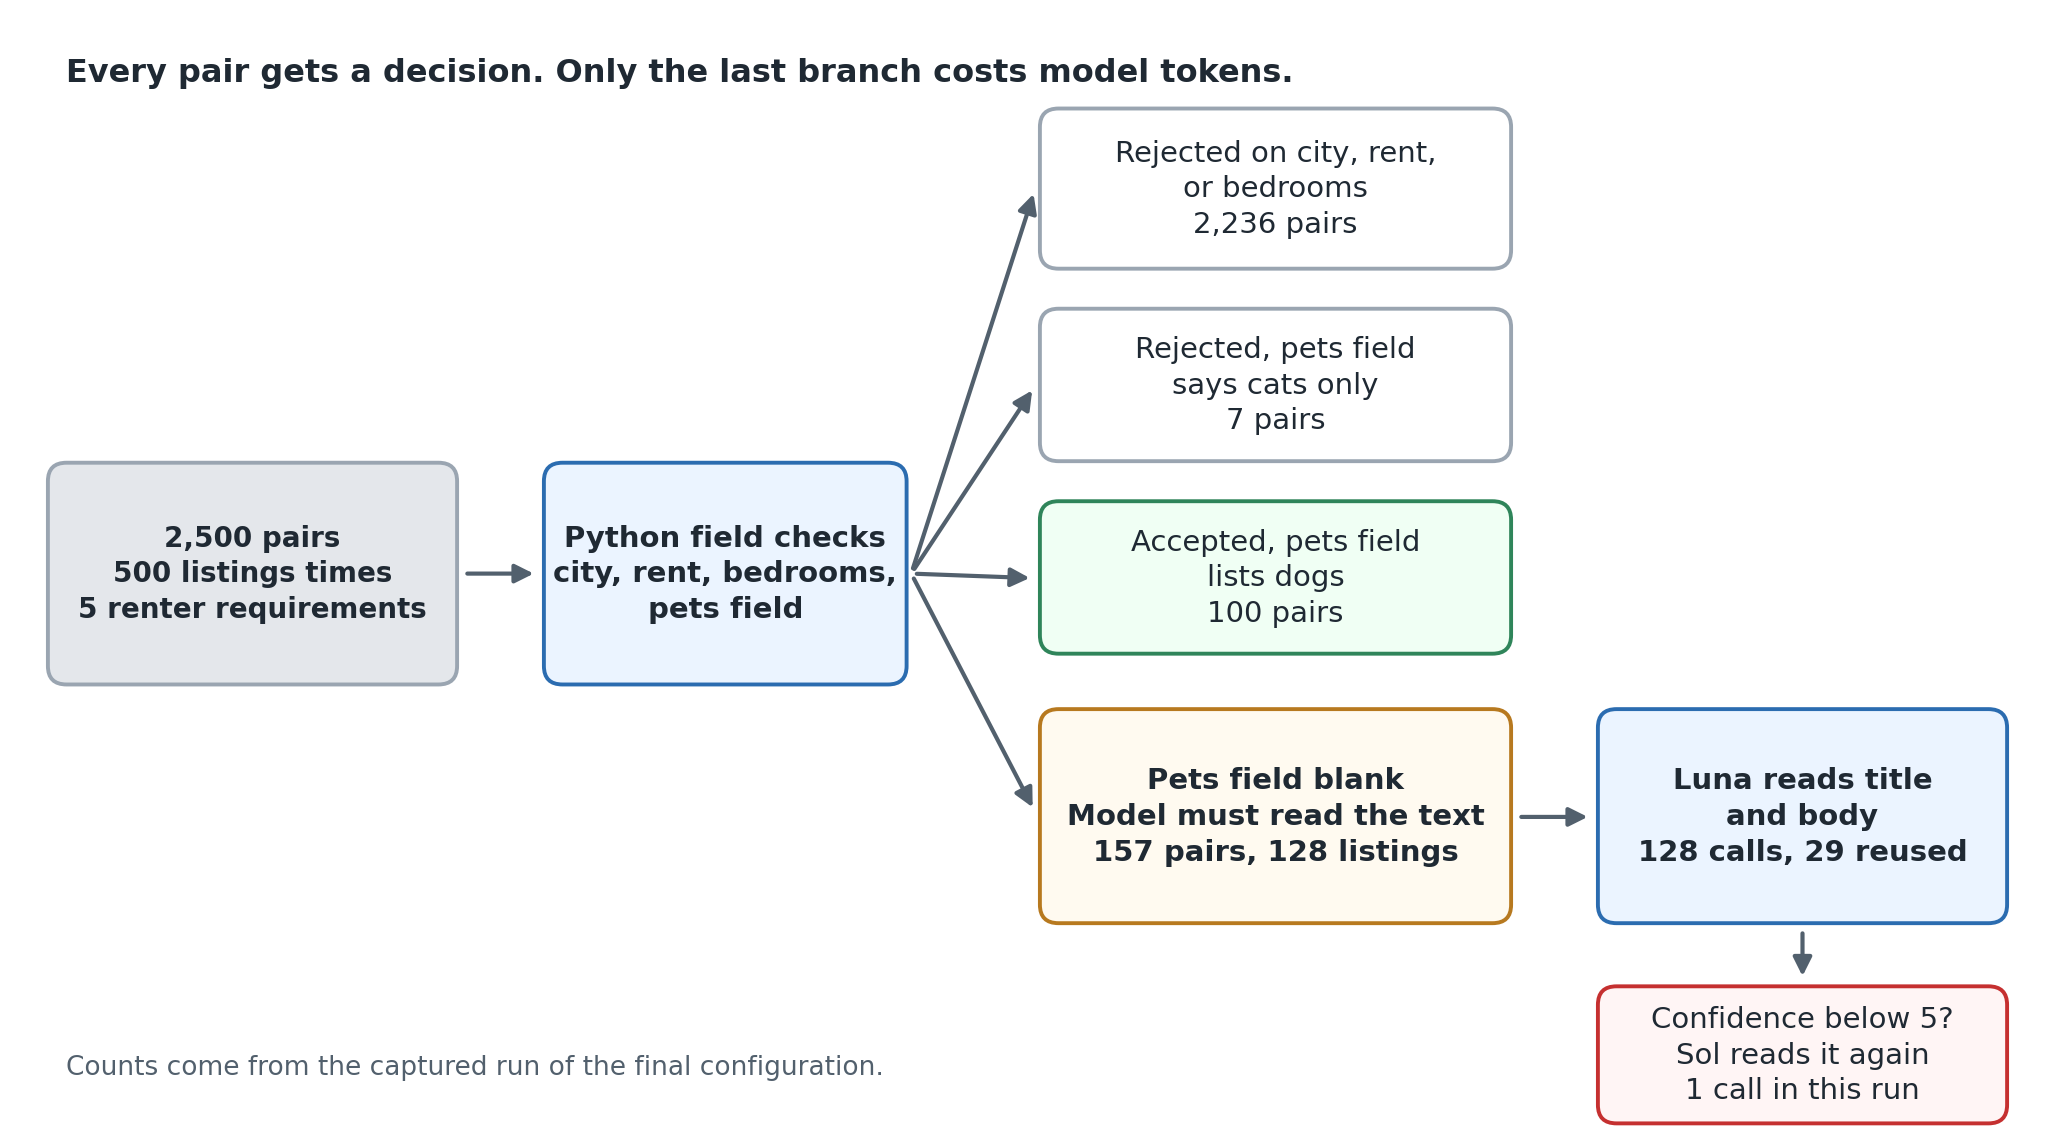
The diagram reveals the place the pairs went. Discipline checks rejected 2,236 pairs, and 1,704 of these had the unsuitable metropolis. That first department is similar work the database question does, and it covers 89 p.c of all pairs in my blended metropolis pattern.
The pets subject settled the subsequent 107 pairs. Seven had been rejected as a result of the sphere stated cats solely, and 100 had been accepted as a result of it listed canines. That left 157 pairs, which cowl 128 completely different listings, for a mannequin to learn.
The filter configuration sends solely these 157 pairs to Sol with the identical full immediate. Its estimated value fell from $0.20 for the question place to begin to $0.11, about 43 p.c decrease, and its mannequin time fell from 352 to 203 seconds. Precision stayed at 1.0 and recall stayed at 0.990, because it missed the identical match because the beginning factors. That’s what an accurate rule ought to do, as a result of it modifications which pairs attain the mannequin and leaves the reply for the remaining pairs alone.
Does sending much less textual content change the reply?
It modified the reply on this take a look at. The diminished configuration asks Sol one query, whether or not the title and physique say canines are allowed. It drops the facilities, lease, metropolis, and different fields, as a result of the sphere checks already dealt with them.
Enter tokens fell from 34,194 to 23,624, about 31 p.c decrease, and the estimated value fell from $0.114 to $0.098. The saving is smaller than the token drop suggests. Output tokens rose from 4,589 to five,039, and every output token prices 5 instances as a lot as an enter token.
The diminished run additionally discovered the match that every one three beginning factors missed. With the total itemizing, Sol answered no for row_3445, the pet pleasant group, with the best confidence. To verify that this was not luck, I requested every model of the query 10 instances. The total itemizing immediate gave 0 right solutions out of 10, and the title and physique immediate gave 10 out of 10.
I have no idea why. One potential cause is that the total immediate reveals a line saying the pets subject isn’t listed, proper subsequent to the instruction that unspoken canines depend as not confirmed. I didn’t take a look at that concept.
The repeat verify additionally lined the second exhausting itemizing, row_8465, the one with the “pet bar”. The desk beneath reveals how lots of the 10 solutions had been right for every mannequin and immediate. For row_8465, an accurate reply isn’t confirmed, following my label.
|
Mannequin |
Immediate |
|
|
|---|---|---|---|
|
Sol |
Full itemizing |
0 |
10 |
|
Sol |
Title and physique solely |
10 |
7 |
|
Luna |
Title and physique solely |
10 |
8 |
Each fashions break up on row_8465, answering sure two or 3 times in ten. That itemizing is a coin flip, and the desk reveals how a lot a single run can depend upon one such itemizing.
Can the agent reuse a solution safely?
Sure, if every saved reply remembers what produced it. A cache is a pocket book of previous solutions, and its threat is studying an previous reply for a query that has modified. The script keys every reply by the mannequin, the itemizing’s title, physique, and pets subject, and a immediate model string. Enhancing an inventory, altering the immediate model, or switching fashions due to this fact modifications the important thing, and the previous reply isn’t discovered.
The renter’s requirement isn’t a part of the important thing, as a result of the pet query doesn’t depend upon the requirement. The query is similar when two renters each desire a canine pleasant place in Austin. That’s the reason the cache helped, because the identical itemizing reveals up below a couple of requirement. It answered 29 of the 157 pairs from reminiscence, so mannequin calls fell from 157 to 128 and the estimated value fell from $0.098 to $0.082.
The cache within the script lives in reminiscence for one run. A manufacturing cache wants an expiry time and a approach to drop entries when an inventory is eliminated or edited. These elements had been exterior this take a look at.
Is the cheaper mannequin protected to make use of?
For this workload, virtually. Luna reads the identical 128 listings with the identical title and physique immediate, and the estimated value fell from $0.082 to $0.005, about 16 instances decrease once more. Within the captured run Luna made one unsuitable match, and in a rerun it made none. It stated sure to the “pet bar” itemizing with a confidence of 4 on a scale from 1 to five, so precision was 0.990 and recall was 1.0.
Escalation offers the agent a second opinion. Like a junior clerk who passes unsure instances to a senior one, Luna solutions first and Sol reads once more solely when Luna’s confidence falls beneath a threshold. Luna answered 5 for 127 of its 128 questions, and Sol answered 5 for all 157 of its questions. The arrogance scores barely range, so a threshold has little to work with.
I’ve to be trustworthy concerning the threshold. I break up the listings right into a growth half and a take a look at half, so I might tune the edge on one half and report on the opposite. The event half had no errors from any configuration, and each exhausting listings fell within the take a look at half. That left nothing to tune on, and I selected a threshold of 5 after seeing which reply had a confidence of 4. The ultimate result’s due to this fact an illustration and never a validated setting.
With that caveat, the ultimate configuration escalated one reply. Sol learn the “pet bar” itemizing once more, stated no with a confidence of 4, and the run had no unsuitable matches. It made 129 calls, 128 to Luna and 1 to Sol, and the estimated value was $0.0079.
The rerun within the setup part provides a warning. Luna alone made no unsuitable match there, and it answered the identical itemizing accurately with a confidence of 5. So one unsuitable match in opposition to none is noise on a coin flip itemizing, and my run can’t present that escalation fastened something.
Yet another value element issues. Luna’s 128 calls used 6,105 output tokens, greater than Sol’s 4,319 for a similar questions, as a result of Luna spent extra tokens on reasoning. About 61 p.c of Luna’s estimated value was output tokens, so limiting reasoning effort is a lever I didn’t take a look at.
A key phrase search would have matched my labels on all 128 clean listings, so is a mannequin price conserving on this loop in any respect? The repeat verify above reveals the place the 2 would differ, and the final part says what I might monitor to resolve.
What did the mixed model value, and what does the proof assist?
The bottom value model that made no errors within the captured runs was Luna with a Sol backup, at an estimated $0.0079 for two,500 pairs. The question place to begin value $0.20 for a similar pairs, about 25 instances extra, and the desk lists each configuration.
|
Configuration |
Mannequin calls |
Estimated value |
Mannequin time |
Outcome |
|---|---|---|---|---|
|
Ship each pair to Sol |
2,500 |
$1.875 |
2,991 s |
1 match missed |
|
Identical metropolis pairs solely |
796 |
$0.613 |
1,072 s |
1 match missed |
|
Metropolis, bedrooms, and lease question |
264 |
$0.199 |
352 s |
1 match missed |
|
Plus pets subject verify |
157 |
$0.114 |
203 s |
1 match missed |
|
Title and physique solely |
157 |
$0.098 |
199 s |
No errors |
|
Reuse solutions |
128 |
$0.082 |
168 s |
No errors |
|
Luna solely |
128 |
$0.005 |
131 s |
1 unsuitable match |
|
Luna with Sol backup |
129 |
$0.008 |
139 s |
No errors |
The interactive model of this desk, the fee chart, and each mannequin name are within the W&B Report.
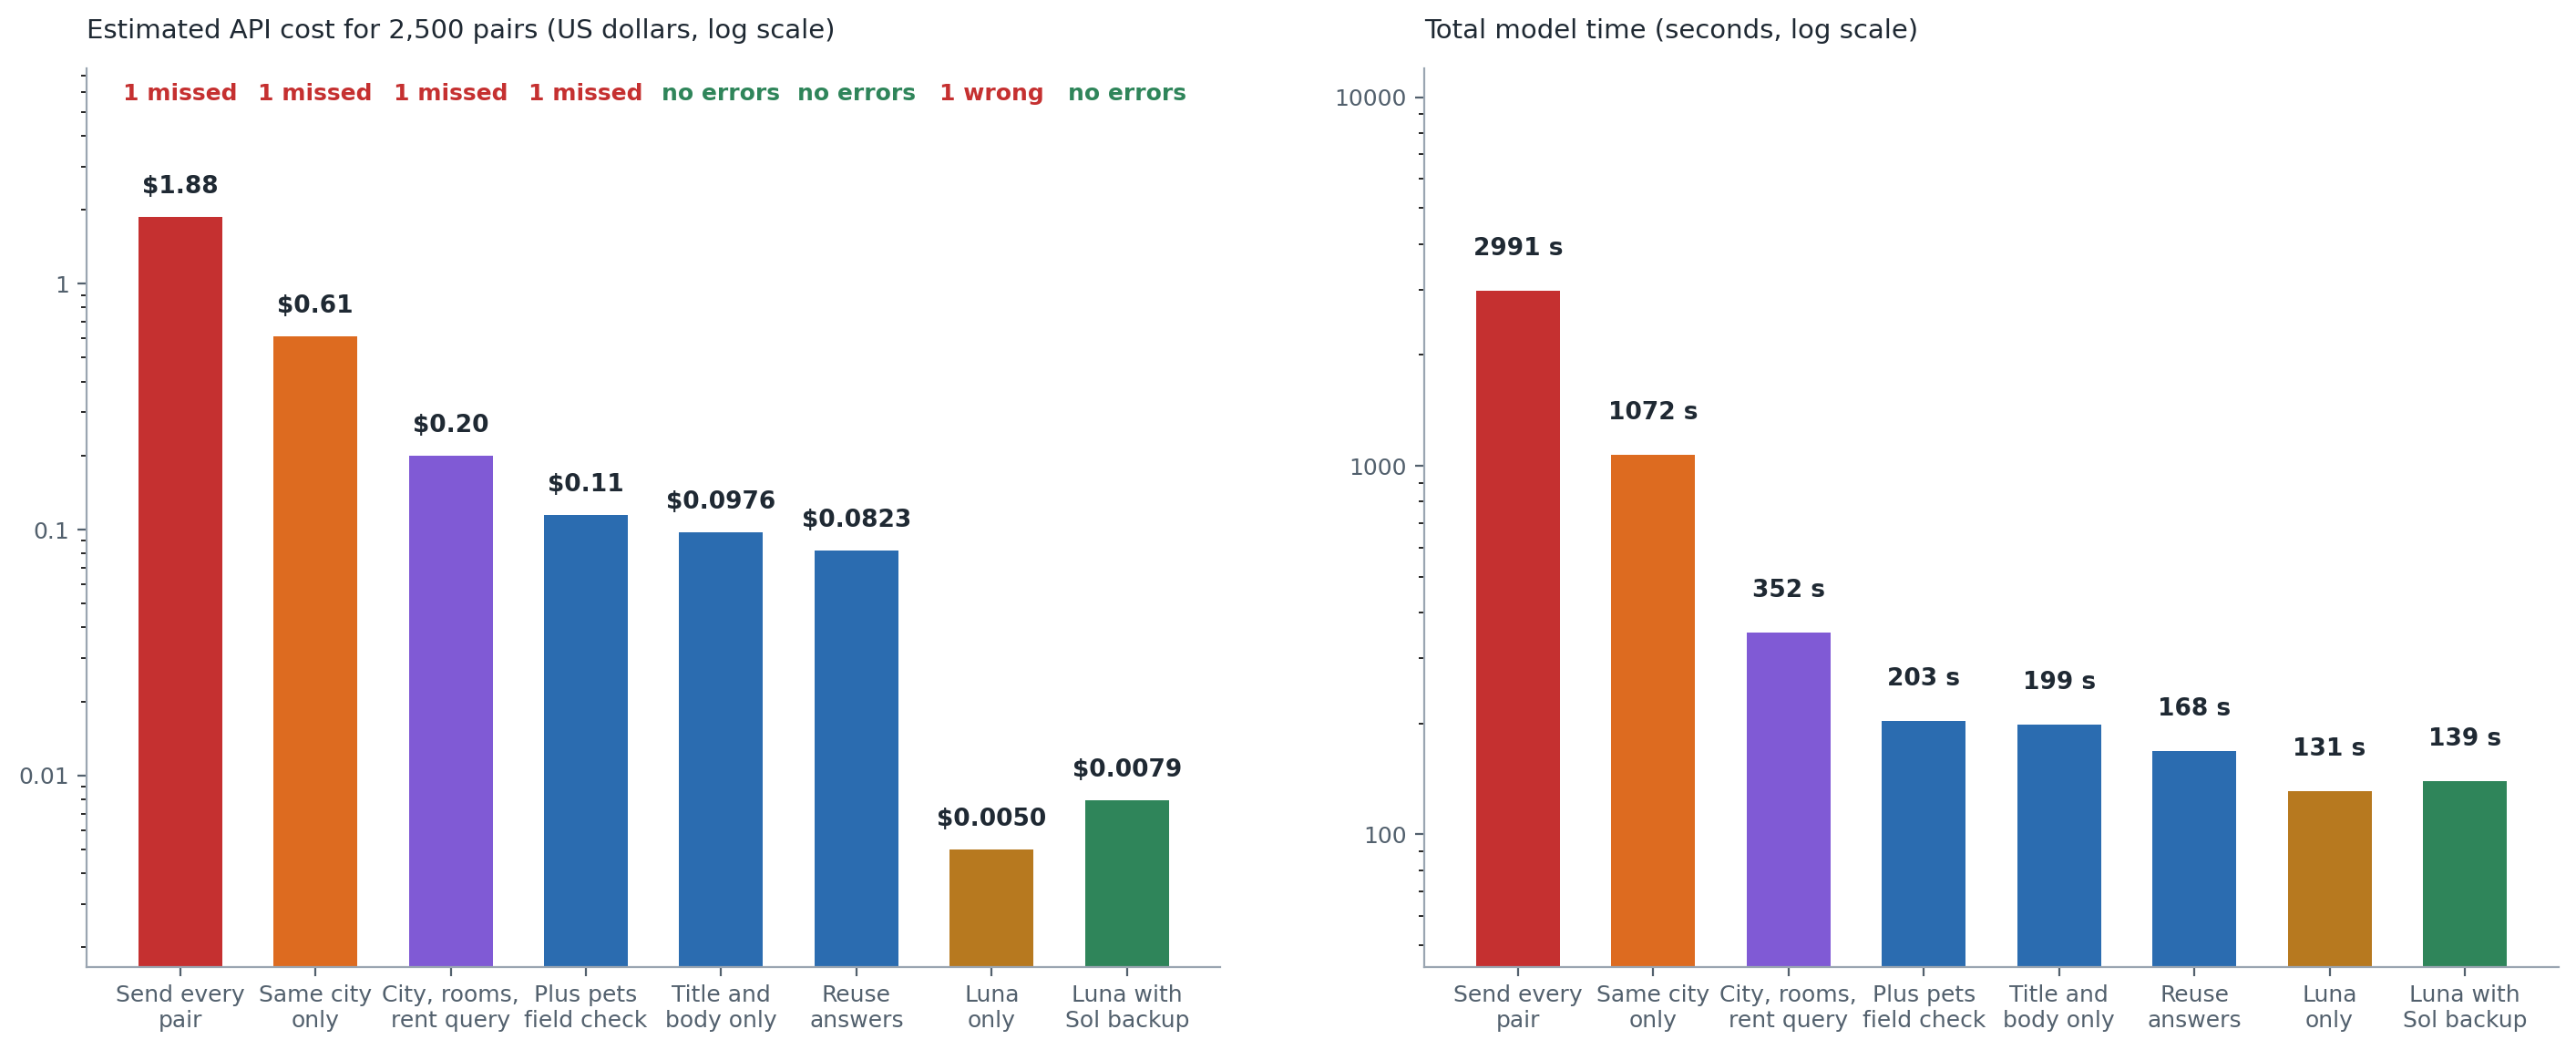
The chart reveals the place the cash went. Ranging from the $0.20 question place to begin, the entire drop was about $0.19. The pets subject verify accounts for 44 p.c of it and the cheaper mannequin with a backup for 39 p.c. The shorter immediate accounts for 9 p.c, and reused solutions for 8 p.c. Mannequin time fell from 352 to 139 seconds.
Per 1,000 pairs, the estimated value went from $0.080 to $0.0032. That’s arithmetic on the speed card, and it doesn’t forecast a invoice for some other feed.
The primary two steps down the chart, from sending every little thing to a metropolis search after which to a full question, are extraordinary question work. They account for a lot of the distance between $1.88 and $0.008, and so they want no mannequin in any respect.
What this take a look at helps is slender. It ranks the fee drivers for one agent on one pattern of two,500 pairs with 101 true matches and one run per configuration. It can’t say how the agent behaves for actual renters, in different cities, on adverts from one other 12 months, or on listings with longer textual content. It additionally can’t decide a common finest setting.
It helps one conclusion. On this agent most mannequin calls had been avoidable, and code might settle most of them. The cheaper mannequin dealt with the remaining at about 4 p.c of the question place to begin’s value.
What ought to preserve working after launch?
A recurring verify ought to watch the identical numbers I used right here. Visitors, prompts, fashions, and retries all transfer value after launch, and a hint makes every of them seen. 4 numbers from this instance are sufficient to start out.
-
Mannequin calls per pair. Sending each pair makes 1.0, the question place to begin makes 0.106, and the ultimate configuration makes 0.052. A soar means extra pairs are reaching the mannequin.
-
The share of pairs the sphere checks settle. It was 93.7 p.c right here, and a drop means the feed or the necessities modified.
-
Tokens per name, together with reasoning tokens. A immediate change or a mannequin change reveals up right here first.
-
Precision and recall on a set set of pairs with recognized solutions. Rerunning these 2,500 pairs with the ultimate configuration prices lower than a cent on the charges above.
Two setup particulars will assist. Register the charges with add_cost() in order that Weave reveals actual numbers in its Utilization desk as a substitute of zero. Hold the immediate model string within the cache key, so a immediate edit can’t reuse an previous reply.
The arrogance scores deserve a watch too. If virtually each reply scores 5, an escalation rule that fires beneath 5 will not often hearth, and the backup mannequin will sit idle whereas the cheaper mannequin carries each determination.
Optimize for helpful matches, not the smallest invoice
The tactic on this article has 4 steps. Hint the run, discover the mannequin calls that code might settle, change one factor, and rating the identical pairs once more. On this agent that sequence lower the estimated value about 25 instances in opposition to a database question place to begin and left the solutions intact. Towards sending each pair, the lower was about 237 instances, however few actual brokers begin there. The identical steps might have uncovered a high quality loss, and the runs had been constructed to indicate one if it appeared.
Open one actual hint from your personal agent and depend the calls {that a} subject verify or a lookup might have answered. Then take a look at the most important value driver first, on a set set of examples with solutions you belief. The subsequent technical query I might ask is whether or not a decrease reasoning effort retains the identical solutions at a cheaper price, since output tokens drove most of Luna’s invoice.
Chosen Sources
-
FrugalGPT: The way to Use Giant Language Fashions Whereas Decreasing Price and Enhancing Efficiency, Lingjiao Chen, Matei Zaharia, and James Zou, 2023. This paper names the three value discount methods and reviews the cascade end result quoted within the opening. Its findings belong to the duties the authors examined.
-
Condo for Lease Categorized, UCI Machine Studying Repository, 2019, DOI 10.24432/C5X623, licensed below Inventive Commons Attribution 4.0. That is the supply of all 10,000 listings and the sphere descriptions.
-
W&B Weave value monitoring documentation. It describes how Weave reads token utilization, applies inbuilt costs for supported integrations, and provides customized prices with
add_cost(). -
OpenAI API pricing, checked on September 27, 2026, for the Sol and Luna normal charges utilized in each value estimate.
-
OpenAI’s mannequin pages for Sol and Luna, checked on September 27, 2026. Sol is described as constructed for complicated coding and agentic workflows, and Luna as essentially the most environment friendly mannequin for centered, excessive quantity duties. The pages checklist
gpt-6-solbecause the default snapshot andgpt-6-lunaas the one snapshot.