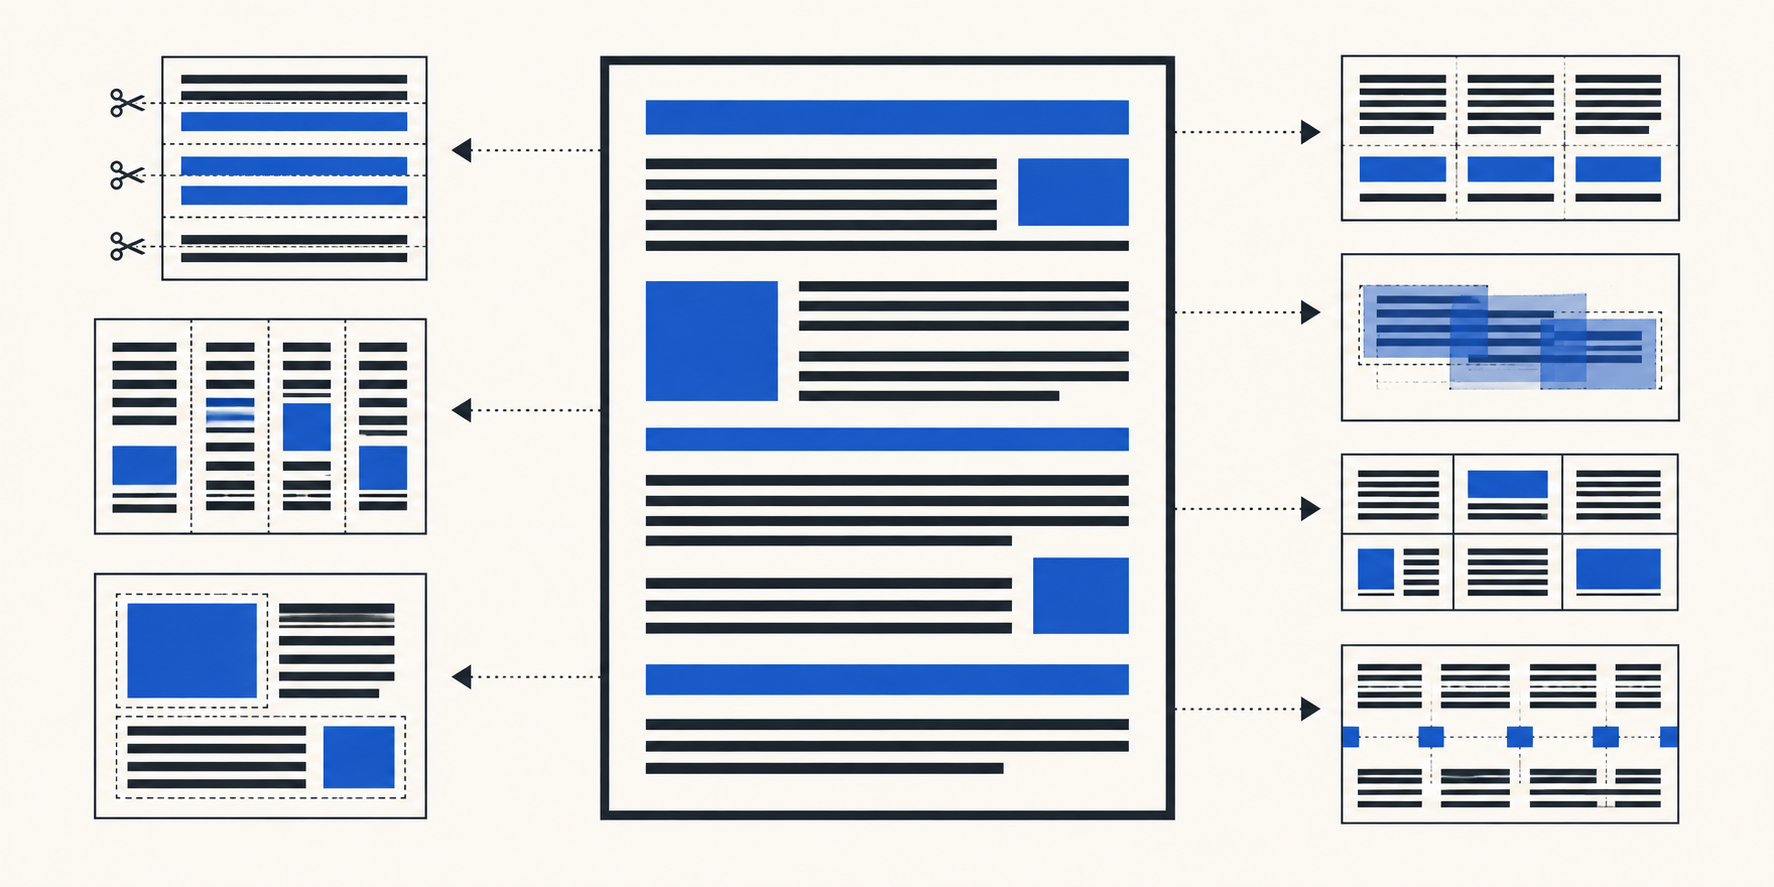
On this article, you’ll be taught seven distinct chunking methods for RAG pipelines, how each works, and when to decide on one over one other in your particular use case.
Subjects we’ll cowl embrace:
- Why naive fixed-size token chunking destroys semantic which means and the way methods like sentence-window retrieval and structural chunking protect it.
- Superior approaches together with semantic chunking, hierarchical chunking, LLM-driven propositional chunking, and multi-modal table-preserving chunking.
- What issues past chunking technique in manufacturing RAG methods, together with index lifecycle administration and chunk deduplication.
The Naive Strategy Doesn’t Work
Dumping unstructured textual content right into a fixed-size token window and calling it a Retrieval-Augmented Era (RAG) pipeline is a recipe for hallucination. RAG is actually giving an AI an open-book take a look at: the system searches a database for related notes, fingers them to the big language mannequin (LLM), and the mannequin synthesizes a solution from these notes. However that database is totally dependent in your chunking technique — the rulebook used to slice an enormous doc into smaller items that an embedding mannequin can learn and retailer.
The naive method of slicing paperwork into static 512-token arrays tears semantic boundaries in half, destroying context earlier than the embedding mannequin (the system that interprets textual content into mathematical arrays) even sees it. Sever a unfavorable qualifier from its topic, or break up a operate definition throughout two vectors, and the retriever is successfully blind, grabbing the unsuitable notes for the LLM’s open-book take a look at.
One factor value clarifying earlier than we dig in: chunking (the deterministic or heuristic splitting of textual content strings) and parsing (extracting logical DOM/AST constructions from uncooked doc codecs) will not be the identical factor. Unhealthy parsing ensures unhealthy chunking, however even excellent parsing wants a stable chunking structure to outlive manufacturing question masses.
1. Fastened-Measurement Token Chunking with Overlap
The Idea: Splitting textual content strictly by uncooked token counts utilizing a sliding window to catch edge-boundary context.
How It Works: A quick tokenizer maps uncooked textual content to an integer array, slices it into uniform blocks (e.g. 512 tokens), and overlaps them by a hard and fast margin (e.g. 50 tokens) earlier than decoding again to textual content strings for the embedding encoder.
Price Noting: It’s structurally blind. You’ll inevitably slice a strive/besides block down the center or separate a pronoun from its antecedent. Overlap mitigates this barely, however will increase vector database bloat and ingestion compute prices linearly with the overlap ratio.
When to Use It: When processing homogenous, unstructured log information or flat textual content streams the place structural boundaries don’t exist and ingestion latency is the highest precedence.
2. Sentence-Window Retrieval (Small-to-Huge)
The Idea: Embedding a granular chunk to maximise vector search precision, then returning the expanded surrounding context to the LLM throughout immediate meeting.
How It Works: At ingestion, paperwork are parsed into particular person sentences. Every sentence is embedded and saved with a metadata pointer to its surrounding ( ok ) sentences. At retrieval time, the vector database returns the top-( n ) nearest sentences, and the middleware swaps them out for his or her expanded textual content home windows earlier than hitting the technology mannequin.
Price Noting: Redundant context injection is an actual danger right here. If two adjoining sentences each clear the top-( ok ) retrieval threshold, your middleware wants graph-based deduplication of the overlapping context home windows. Skip that step, and also you’ll blow out the LLM context window and set off inference latency spikes.
When to Use It: When area information are densely packed and closely nuanced (e.g. medical literature, authorized statutes, and so forth.) the place you want excessive retrieval precision with out dropping surrounding context.
3. Doc-Conscious Structural Chunking
The Idea: Splitting paperwork alongside their logical markdown or DOM boundaries (H1, H2, paragraphs, record gadgets) relatively than arbitrary token limits.
How It Works: The pipeline makes use of parsers to construct a tree of the doc construction, chunks the leaf nodes (paragraphs and lists), and prepends the mum or dad header hierarchy to every chunk (e.g., H1: Q3 Earnings > H2: Danger Elements > [Chunk]). This preserves international context no matter the place the chunk finally ends up spatially.
Price Noting: Node sizes are non-deterministic and range extensively. A big sub-section would possibly nonetheless exceed your embedding mannequin’s most sequence size (usually 512 or 1024 tokens for dense encoders), forcing a fallback to token-based chunking, which dangers breaking the structural integrity you simply paid compute cycles to parse.
When to Use It: When ingesting closely formatted company paperwork, API documentation, or contracts the place the header hierarchy inherently defines the semantic payload.
4. Semantic (Embedding-Based mostly) Chunking
The Idea: Dynamically figuring out chunk boundaries by measuring the gap between sequential sentence vectors and splitting when semantic drift exceeds a threshold.
How It Works: Slide a sentence-level window throughout the textual content, producing light-weight embeddings for every sentence. Calculate the cosine similarity (mathematical closeness) between sentence ( i ) and ( i+1 ). If similarity drops beneath an empirically tuned hyperparameter ( epsilon ), insert a tough chunk boundary. That drop alerts a subject change.
Price Noting: Ingestion latency and value improve considerably. You’re forcing a ahead move by an encoder for each single sentence earlier than you generate the ultimate chunk embedding. And ( epsilon ) is notoriously brittle — practically inconceivable to tune globally throughout heterogeneous doc units.
When to Use It: When coping with transcribed audio, assembly notes, or long-form narrative textual content that lacks structural formatting however accommodates distinct, unpredictable thematic shifts.
5. Hierarchical / Mum or dad-Youngster Chunking
The Idea: Making a tree of chunks the place a number of granular little one nodes map to a single broad mum or dad node. Retrieve sufficient youngsters and also you get the entire mum or dad.
How It Works: Textual content is chunked at a number of granularities (e.g. 256 tokens and 1024 tokens). The 256-token chunks are embedded and mapped to their 1024-token mum or dad by way of metadata international keys within the vector retailer. If ( >x% ) of a mum or dad’s youngsters are retrieved by the Approximate Nearest Neighbor (ANN) search, the question planner executes a merge and swaps the kid chunks for the mum or dad chunk.
Price Noting: Managing the parent-child relational mapping in a distributed vector database will get advanced quick. Deletes and doc updates require cascading invalidations throughout the tree, and the merge logic at retrieval time provides latency to the vital path.
When to Use It: When question scope is very variable — starting from pinpoint factoid extraction to broad summarization of whole doc sections.
6. Agentic (LLM-Pushed) Propositional Chunking
The Idea: Utilizing an instruction-tuned LLM to learn a textual content stream and inject structural breakpoints primarily based on contextual understanding, or to extract atomic propositions.
How It Works: A doc is streamed to a quick LLM with a strict system immediate instructing it to output a JSON array of pure breakpoints or distinct factual propositions. The ingestion pipeline then slices the uncooked doc alongside these synthesized boundaries and embeds the extracted propositions.
Price Noting: This ensures non-deterministic ingestion. The LLM will hallucinate breakpoints, output malformed JSON, or silently drop textual content throughout extraction — any of which causes irrecoverable knowledge loss within the index. It’s additionally considerably slower than programmatic chunking.
When to Use It: For extremely precious, irregular datasets the place chunk high quality drives your complete product’s viability, however solely when ingestion runs in an asynchronous batch queue relatively than a real-time stream.
7. Multi-Modal and Desk-Preserving Chunking
The Idea: Isolating tables, charts, and figures from normal textual content, extracting them as distinct objects, summarizing them for vectorization, and sustaining pointers again to the uncooked tabular knowledge.
How It Works: A deterministic format parser or Imaginative and prescient-Language Mannequin (VLM) identifies a desk. The pipeline extracts the uncooked HTML/Markdown, makes use of an LLM to generate a dense textual content abstract of the desk’s semantic insights, and embeds solely the abstract. The retrieval layer fetches the abstract by way of ANN search however passes the uncooked Markdown desk to the ultimate technology immediate.
Price Noting: If a desk depends on surrounding textual content to make sense (e.g. “Outcomes proven in Desk 1 beneath normalized in opposition to the management group”), isolating it strips away vital grounding and creates phantom references. Broad desk schemas can even exceed the utmost sequence lengths of older technology fashions.
When to Use It: When ingesting monetary experiences, scientific papers, or closely quantitative paperwork the place normal recursive textual content tokenizers destroy spatial column alignment.
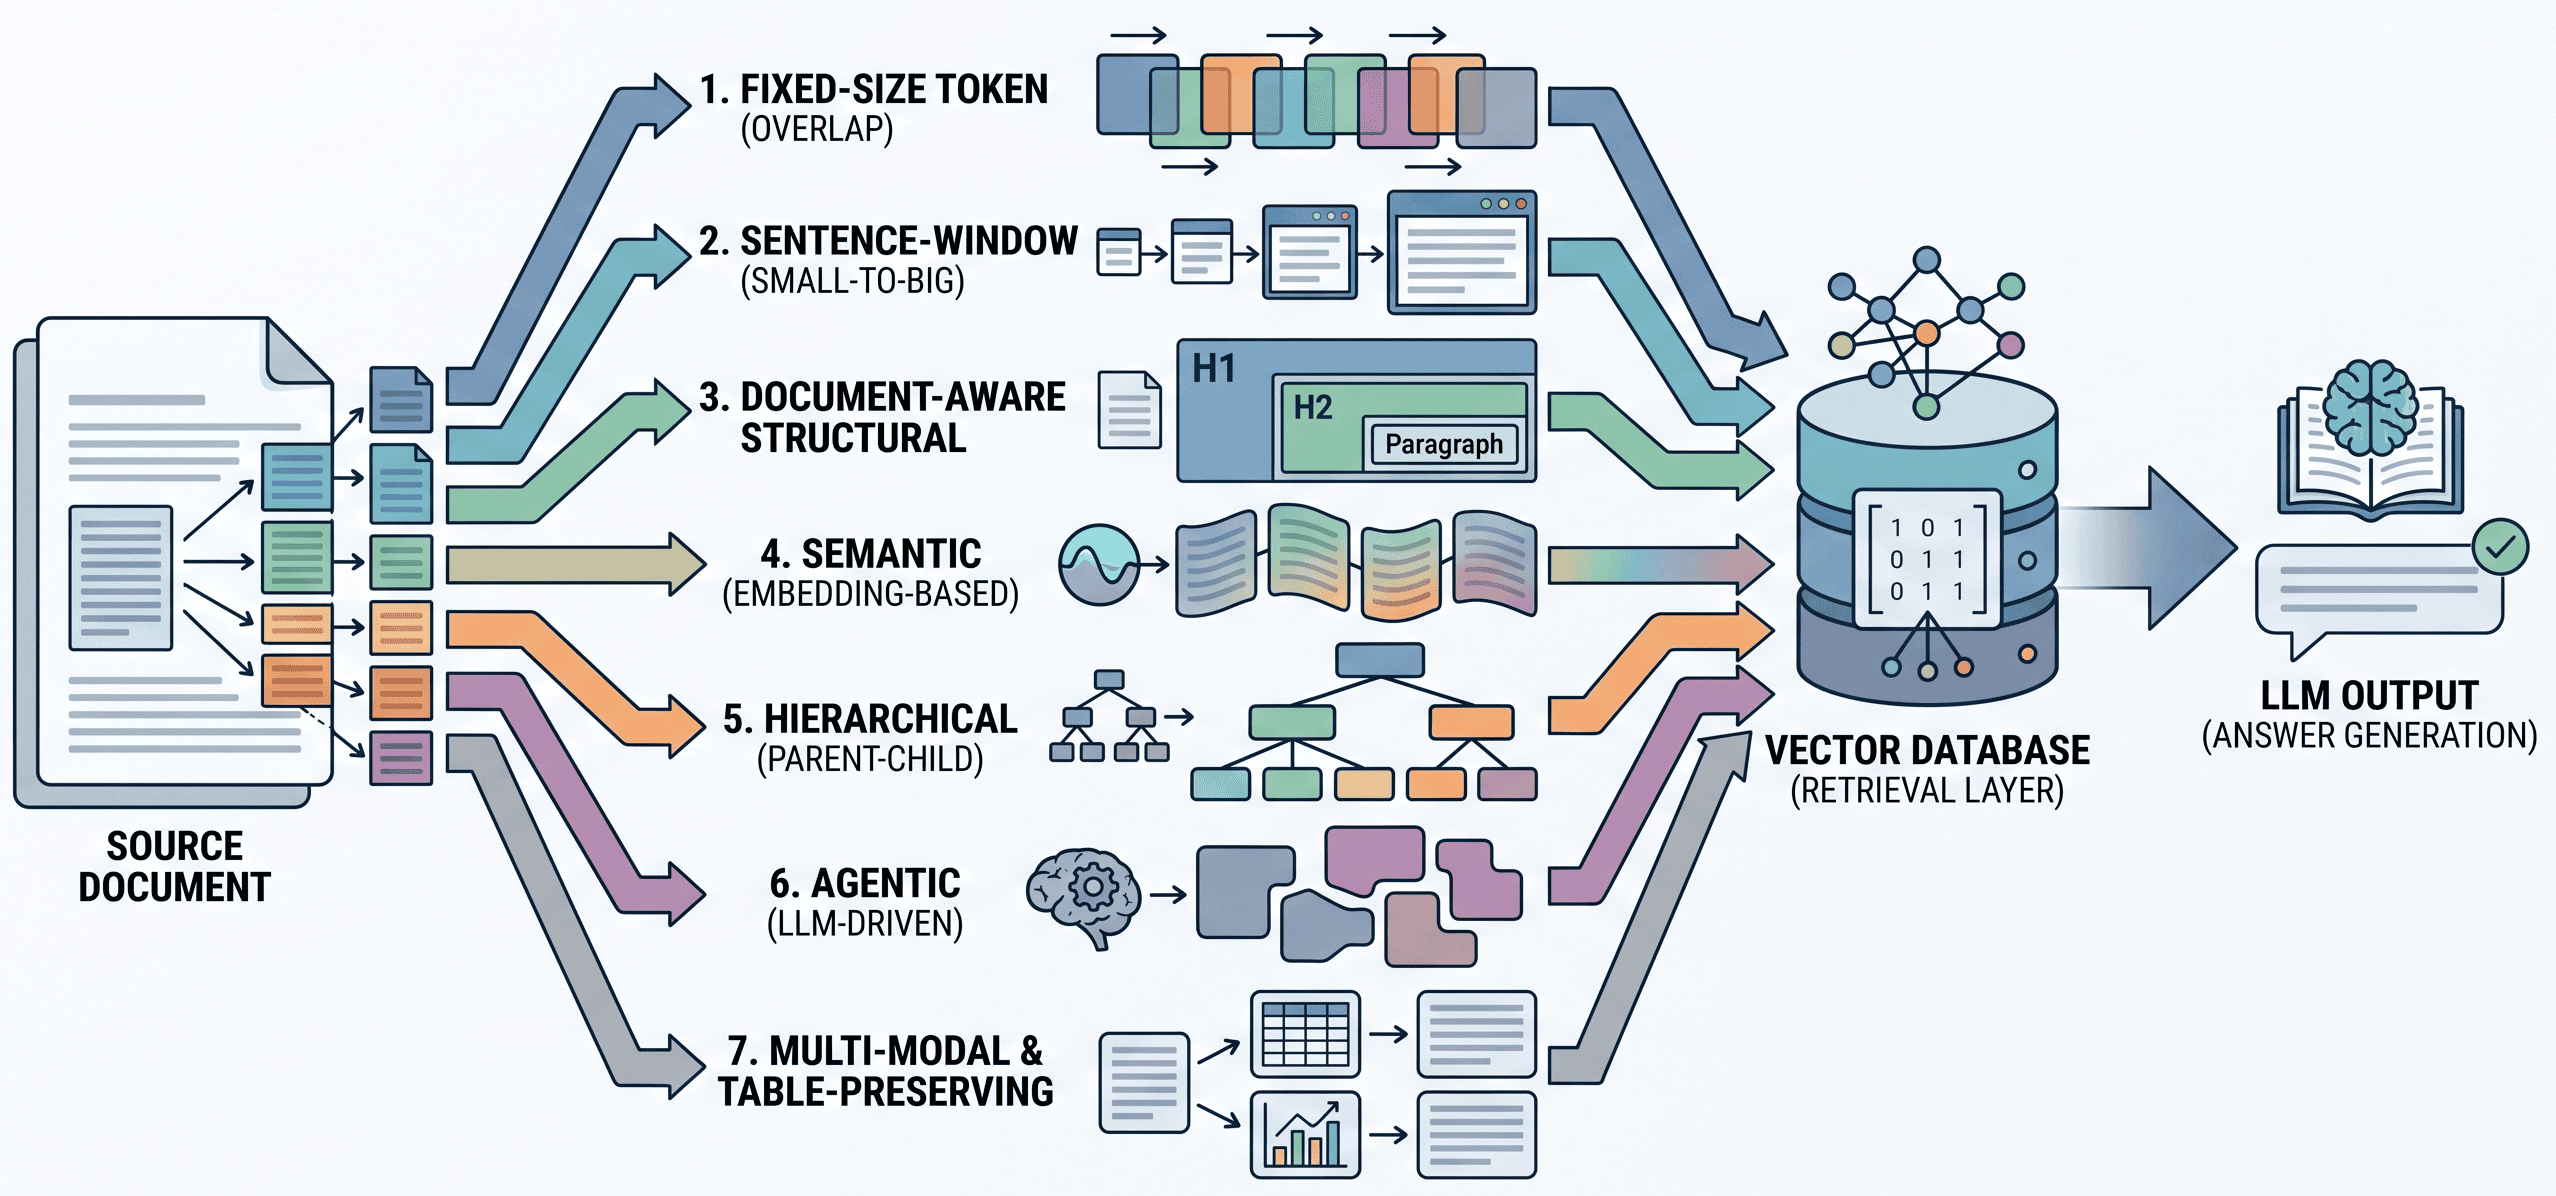
A overview of the 7 RAG chunking methods
Wanting Past Chunking
Day 100 in manufacturing isn’t actually about chunking methods anymore. It’s about index lifecycle administration, state synchronization, and pruning stale knowledge. Doc updates will inevitably create fragmented, orphaned chunks in your database. For those who’re not implementing deterministic UUIDs primarily based on cryptographic content material hashes in your chunks and implementing strict Time-To-Dwell (TTL) insurance policies, your vector database will bloat with outdated textual content blocks. That results in duplicate context injection at retrieval time, which silently degrades the LLM’s reasoning and inflates your token prices.
Cease obsessing over benchmark scores for the most recent embedding mannequin in case your chunking technique is an afterthought. Essentially the most succesful dense retriever on the planet can’t get better semantic which means that was already mangled by a naive ingestion pipeline. Deal with chunking as a foundational knowledge modeling downside, take a look at your boundaries aggressively, and construct your system anticipating structural failure.
On this article, you’ll be taught seven distinct chunking methods for RAG pipelines, how each works, and when to decide on one over one other in your particular use case.
Subjects we’ll cowl embrace:
- Why naive fixed-size token chunking destroys semantic which means and the way methods like sentence-window retrieval and structural chunking protect it.
- Superior approaches together with semantic chunking, hierarchical chunking, LLM-driven propositional chunking, and multi-modal table-preserving chunking.
- What issues past chunking technique in manufacturing RAG methods, together with index lifecycle administration and chunk deduplication.
The Naive Strategy Doesn’t Work
Dumping unstructured textual content right into a fixed-size token window and calling it a Retrieval-Augmented Era (RAG) pipeline is a recipe for hallucination. RAG is actually giving an AI an open-book take a look at: the system searches a database for related notes, fingers them to the big language mannequin (LLM), and the mannequin synthesizes a solution from these notes. However that database is totally dependent in your chunking technique — the rulebook used to slice an enormous doc into smaller items that an embedding mannequin can learn and retailer.
The naive method of slicing paperwork into static 512-token arrays tears semantic boundaries in half, destroying context earlier than the embedding mannequin (the system that interprets textual content into mathematical arrays) even sees it. Sever a unfavorable qualifier from its topic, or break up a operate definition throughout two vectors, and the retriever is successfully blind, grabbing the unsuitable notes for the LLM’s open-book take a look at.
One factor value clarifying earlier than we dig in: chunking (the deterministic or heuristic splitting of textual content strings) and parsing (extracting logical DOM/AST constructions from uncooked doc codecs) will not be the identical factor. Unhealthy parsing ensures unhealthy chunking, however even excellent parsing wants a stable chunking structure to outlive manufacturing question masses.
1. Fastened-Measurement Token Chunking with Overlap
The Idea: Splitting textual content strictly by uncooked token counts utilizing a sliding window to catch edge-boundary context.
How It Works: A quick tokenizer maps uncooked textual content to an integer array, slices it into uniform blocks (e.g. 512 tokens), and overlaps them by a hard and fast margin (e.g. 50 tokens) earlier than decoding again to textual content strings for the embedding encoder.
Price Noting: It’s structurally blind. You’ll inevitably slice a strive/besides block down the center or separate a pronoun from its antecedent. Overlap mitigates this barely, however will increase vector database bloat and ingestion compute prices linearly with the overlap ratio.
When to Use It: When processing homogenous, unstructured log information or flat textual content streams the place structural boundaries don’t exist and ingestion latency is the highest precedence.
2. Sentence-Window Retrieval (Small-to-Huge)
The Idea: Embedding a granular chunk to maximise vector search precision, then returning the expanded surrounding context to the LLM throughout immediate meeting.
How It Works: At ingestion, paperwork are parsed into particular person sentences. Every sentence is embedded and saved with a metadata pointer to its surrounding ( ok ) sentences. At retrieval time, the vector database returns the top-( n ) nearest sentences, and the middleware swaps them out for his or her expanded textual content home windows earlier than hitting the technology mannequin.
Price Noting: Redundant context injection is an actual danger right here. If two adjoining sentences each clear the top-( ok ) retrieval threshold, your middleware wants graph-based deduplication of the overlapping context home windows. Skip that step, and also you’ll blow out the LLM context window and set off inference latency spikes.
When to Use It: When area information are densely packed and closely nuanced (e.g. medical literature, authorized statutes, and so forth.) the place you want excessive retrieval precision with out dropping surrounding context.
3. Doc-Conscious Structural Chunking
The Idea: Splitting paperwork alongside their logical markdown or DOM boundaries (H1, H2, paragraphs, record gadgets) relatively than arbitrary token limits.
How It Works: The pipeline makes use of parsers to construct a tree of the doc construction, chunks the leaf nodes (paragraphs and lists), and prepends the mum or dad header hierarchy to every chunk (e.g., H1: Q3 Earnings > H2: Danger Elements > [Chunk]). This preserves international context no matter the place the chunk finally ends up spatially.
Price Noting: Node sizes are non-deterministic and range extensively. A big sub-section would possibly nonetheless exceed your embedding mannequin’s most sequence size (usually 512 or 1024 tokens for dense encoders), forcing a fallback to token-based chunking, which dangers breaking the structural integrity you simply paid compute cycles to parse.
When to Use It: When ingesting closely formatted company paperwork, API documentation, or contracts the place the header hierarchy inherently defines the semantic payload.
4. Semantic (Embedding-Based mostly) Chunking
The Idea: Dynamically figuring out chunk boundaries by measuring the gap between sequential sentence vectors and splitting when semantic drift exceeds a threshold.
How It Works: Slide a sentence-level window throughout the textual content, producing light-weight embeddings for every sentence. Calculate the cosine similarity (mathematical closeness) between sentence ( i ) and ( i+1 ). If similarity drops beneath an empirically tuned hyperparameter ( epsilon ), insert a tough chunk boundary. That drop alerts a subject change.
Price Noting: Ingestion latency and value improve considerably. You’re forcing a ahead move by an encoder for each single sentence earlier than you generate the ultimate chunk embedding. And ( epsilon ) is notoriously brittle — practically inconceivable to tune globally throughout heterogeneous doc units.
When to Use It: When coping with transcribed audio, assembly notes, or long-form narrative textual content that lacks structural formatting however accommodates distinct, unpredictable thematic shifts.
5. Hierarchical / Mum or dad-Youngster Chunking
The Idea: Making a tree of chunks the place a number of granular little one nodes map to a single broad mum or dad node. Retrieve sufficient youngsters and also you get the entire mum or dad.
How It Works: Textual content is chunked at a number of granularities (e.g. 256 tokens and 1024 tokens). The 256-token chunks are embedded and mapped to their 1024-token mum or dad by way of metadata international keys within the vector retailer. If ( >x% ) of a mum or dad’s youngsters are retrieved by the Approximate Nearest Neighbor (ANN) search, the question planner executes a merge and swaps the kid chunks for the mum or dad chunk.
Price Noting: Managing the parent-child relational mapping in a distributed vector database will get advanced quick. Deletes and doc updates require cascading invalidations throughout the tree, and the merge logic at retrieval time provides latency to the vital path.
When to Use It: When question scope is very variable — starting from pinpoint factoid extraction to broad summarization of whole doc sections.
6. Agentic (LLM-Pushed) Propositional Chunking
The Idea: Utilizing an instruction-tuned LLM to learn a textual content stream and inject structural breakpoints primarily based on contextual understanding, or to extract atomic propositions.
How It Works: A doc is streamed to a quick LLM with a strict system immediate instructing it to output a JSON array of pure breakpoints or distinct factual propositions. The ingestion pipeline then slices the uncooked doc alongside these synthesized boundaries and embeds the extracted propositions.
Price Noting: This ensures non-deterministic ingestion. The LLM will hallucinate breakpoints, output malformed JSON, or silently drop textual content throughout extraction — any of which causes irrecoverable knowledge loss within the index. It’s additionally considerably slower than programmatic chunking.
When to Use It: For extremely precious, irregular datasets the place chunk high quality drives your complete product’s viability, however solely when ingestion runs in an asynchronous batch queue relatively than a real-time stream.
7. Multi-Modal and Desk-Preserving Chunking
The Idea: Isolating tables, charts, and figures from normal textual content, extracting them as distinct objects, summarizing them for vectorization, and sustaining pointers again to the uncooked tabular knowledge.
How It Works: A deterministic format parser or Imaginative and prescient-Language Mannequin (VLM) identifies a desk. The pipeline extracts the uncooked HTML/Markdown, makes use of an LLM to generate a dense textual content abstract of the desk’s semantic insights, and embeds solely the abstract. The retrieval layer fetches the abstract by way of ANN search however passes the uncooked Markdown desk to the ultimate technology immediate.
Price Noting: If a desk depends on surrounding textual content to make sense (e.g. “Outcomes proven in Desk 1 beneath normalized in opposition to the management group”), isolating it strips away vital grounding and creates phantom references. Broad desk schemas can even exceed the utmost sequence lengths of older technology fashions.
When to Use It: When ingesting monetary experiences, scientific papers, or closely quantitative paperwork the place normal recursive textual content tokenizers destroy spatial column alignment.
A overview of the 7 RAG chunking methods
Wanting Past Chunking
Day 100 in manufacturing isn’t actually about chunking methods anymore. It’s about index lifecycle administration, state synchronization, and pruning stale knowledge. Doc updates will inevitably create fragmented, orphaned chunks in your database. For those who’re not implementing deterministic UUIDs primarily based on cryptographic content material hashes in your chunks and implementing strict Time-To-Dwell (TTL) insurance policies, your vector database will bloat with outdated textual content blocks. That results in duplicate context injection at retrieval time, which silently degrades the LLM’s reasoning and inflates your token prices.
Cease obsessing over benchmark scores for the most recent embedding mannequin in case your chunking technique is an afterthought. Essentially the most succesful dense retriever on the planet can’t get better semantic which means that was already mangled by a naive ingestion pipeline. Deal with chunking as a foundational knowledge modeling downside, take a look at your boundaries aggressively, and construct your system anticipating structural failure.