

Over the current previous, as enterprises have realised the transformative potential of generative AI, there was an crucial to launch useful, large-scale AI use circumstances. To that finish, agile squads have been created, mannequin, vibe coding assistants and compute provisioned, and multi-agent demos constructed. However when these methods depart the sandbox and get examined on pre-production, a standard bottleneck exhibits up. The fashions motive positive, however not like the well-formed artificial knowledge utilized in demos, the underlying enterprise knowledge is’nt accessible, clear, or structured sufficient for them to behave on reliably.
Conventional enterprise knowledge platforms have been architected for a essentially completely different set of applied sciences, that of deterministic (BI dashboards) or predictive analytics (ML use circumstances). Knowledge engineering advanced to incorporate ETL pipelines, dimensional star schemas, and Lakehouse Medallion architectures (Bronze -> Silver -> Gold). These platforms have been tuned for backward-looking aggregations, reminiscent of “What was our EMEA churn charge in Q3?” that have been queried by way of inflexible SQL and consumed on BI dashboards.
Autonomous brokers and retrieval-augmented era (RAG) have inverted a number of core premises of the standard knowledge platform:
-
The Ingestion Mismatch: Brokers eat dynamic immediate home windows assembled from unstructured paperwork, operational telemetry, and data graphs slightly than rectangular tables.
-
The Latency Hole: A nightly lakehouse refresh schedule can’t serve an autonomous agent that requires lively cart knowledge, cost dispute standing, and danger indicators computed seconds in the past, to reply person queries or flag potential anomalies in close to real-time.
-
The Entry Management Redesign: Conventional database safety operates on the desk degree. If a confidential doc is ingested right into a shared vector retailer, semantic search will floor that chunk to an unauthorized person if cosine similarity is above a threshold.
-
The Schema Hallucination: Pointing an LLM instantly at uncooked relational tables produces hallucinated joins, miscalculated enterprise definitions, and un-indexed queries that make “talk-to-data” use circumstances unviable.
To get previous lab demos, we now have to cease treating AI as only a immediate engineering problem. It’s a knowledge drawback. In case your knowledge platform cannot hold knowledge recent, clear, and locked down with correct permissions, your brokers will fail in manufacturing
This information supplies a practitioner’s deep dive into six superior architectural patterns for constructing an enterprise AI knowledge basis, with out getting too tactical with code or instruments wanted to implement them.
The 4 Core Pillars of an AI-Prepared Knowledge Material
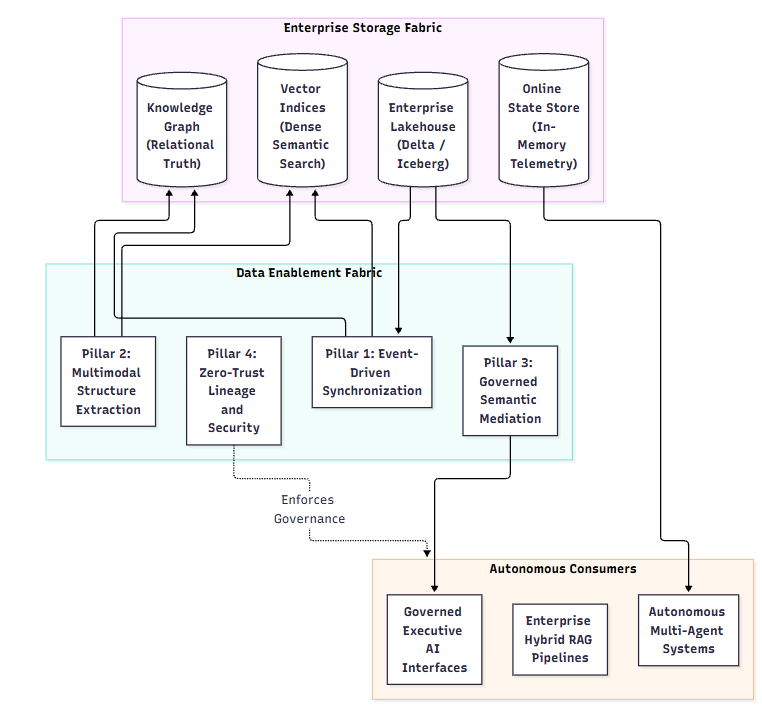
Earlier than analyzing the patterns, we should outline the 4 useful pillars that remodel an enterprise knowledge lakehouse into an AI-ready knowledge material:
-
Occasion-Pushed Synchronization: Shifting from scheduled batch re-indexing to steady, Change Knowledge Seize (CDC)-driven invalidation that stops embedding staleness and silent drift.
-
Multimodal Construction Extraction: Preserving structure geometries, desk relationships, and hierarchical part breadcrumbs from unstructured paperwork slightly than slicing them into arbitrary token chunks.
-
Ruled Semantic Mediation: Inserting licensed metric layers and enterprise ontologies between reasoning fashions and uncooked databases, ensures that enterprise definitions (reminiscent of Annual Recurring Income or churn) are usually not hallucinated and pure language queries are decomposed appropriately to code.
-
Zero-Belief Lineage & Safety: Propagating source-system Entry Management Lists (ACLs) and knowledge classifications instantly into retrieval indices, imposing deterministic pre-query filtering earlier than vector search happens.
Sample 1: The Occasion-Pushed Twin-Pace Pipeline (CDC-Pushed Actual-Time Sync)
How It Works
In normal enterprise architectures, the Knowledge Platform group manages the company Lakehouse, whereas the AI group manages exterior vector indices and data graphs. Usually, a nightly batch job scrapes tables, generates embeddings by way of an LLM API, and bulk-upserts them to the vector retailer.
The Occasion-Pushed Twin-Pace Pipeline replaces batch scraping with real-time Change Knowledge Seize (CDC) working on the write-ahead log (WAL) as depicted within the following diagram:
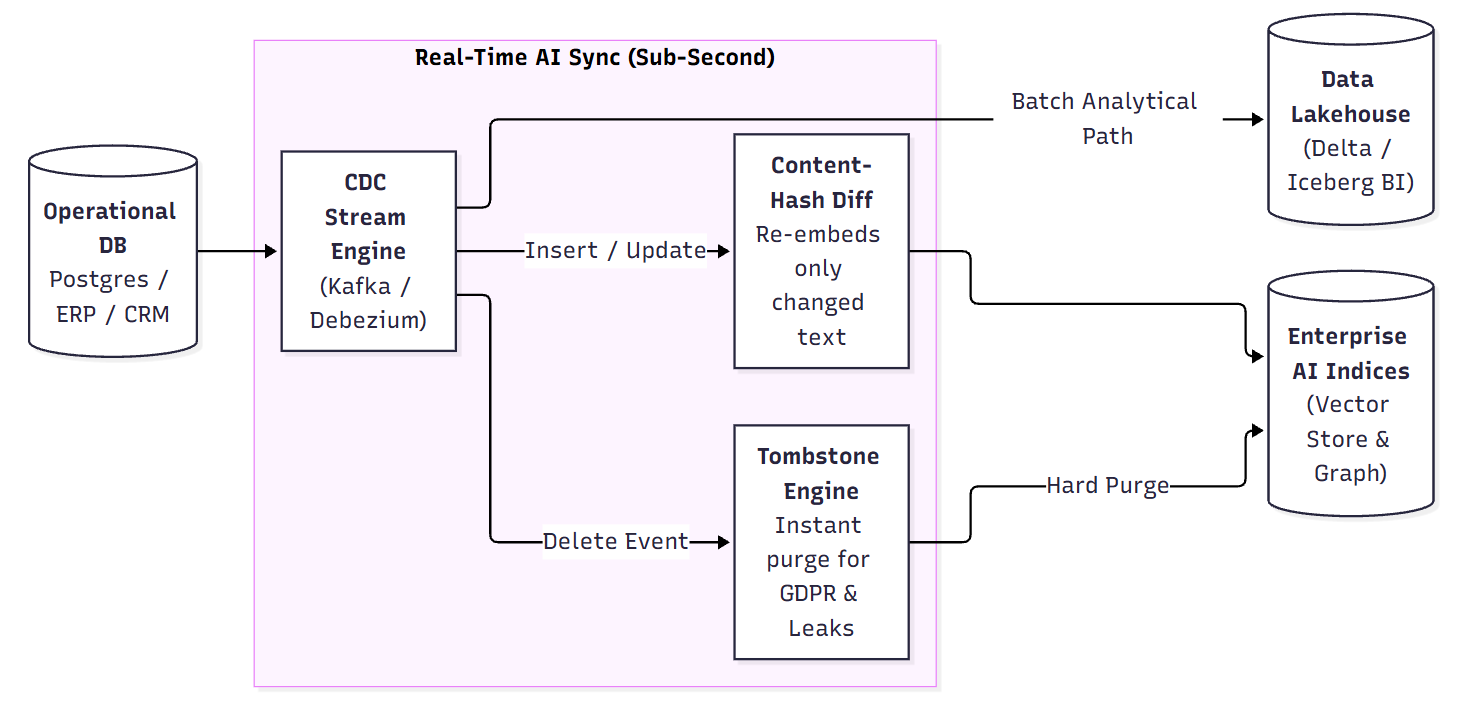
Every time an operational report adjustments, an occasion streams concurrently into the lakehouse and the semantic occasion router.
The router checks the incoming payload towards a distributed content-hash cache (SHA-256 over normalized textual content). If the hash is similar, that means an replace solely modified an inner counter or timestamp, the re-embedding occasion is terminated. If the textual content has modified, solely that particular chunk is re-embedded and atomically upserted.
For instance, when a report or doc is deleted on the supply, reminiscent of HR deleting a confidential severance memo, or an enterprise buyer closing their account, the pipeline emits an instantaneous tombstone occasion. Relatively than forsaking “zombie embeddings” that an AI agent may nonetheless retrieve and leak weeks later, the tombstone engine maps the deleted main key to all little one chunk IDs, hard-purging them from the vector database and severing their relational edges within the data graph inside seconds.
Enterprise Worth Proposition
-
Optimising Re-Embedding Prices: Relatively than working full-corpus batch re-embeddings throughout thousands and thousands of paperwork which may value tens of 1000’s of {dollars} month-to-month in cloud LLM API payments, content-diffing ensures that you just solely embed knowledge that has mutated, slicing prices by 85% to 95%.
-
Stopping Knowledge Leaks from Confidential File Deletions: If an govt deletes a delicate restructuring memo or discontinued pricing sheet, normal batch pipelines depart these chunks within the vector index for days. The tombstone engine ensures that when a file is deleted in SharePoint or Google Drive, it’s rendered unsearchable by downstream AI brokers virtually instantly.
-
Compliance with the “Proper to be Forgotten” (GDPR & CCPA): Beneath GDPR (Article 17) and CCPA, when a person requests full deletion of their private knowledge, that deletion should cascade throughout all company methods. In case your operational database deletes a person however your vector database continues storing their private chat logs or medical historical past in an embedding index, the corporate is in lively regulatory breach. Automated tombstoning creates an auditable assure of authorized deletion compliance throughout all AI storage layers.
Key Benefits & Commerce-Offs
-
Execs: Close to real-time freshness (seconds vs. 24 hours); eliminates duplicate embedding spend; ensures automated deletion consistency with traceability and auditability.
-
Cons & Dangers: Requires streaming infrastructure (Kafka, Debezium, Redis); out-of-order message supply requires engineering loops for monotonic timestamp checks.
-
When to Use: Important for operational and regulatory domains the place underlying data change incessantly: CRM buyer profiles, product pricing, stock, coverage documentation, and ticketing methods.
Sample 2: The Hierarchical Semantic Parser (Unstructured Doc ASTs)
How It Works
Most enterprise RAG failures happen from flattening advanced multi-page PDFs into uncooked ASCII strings and working a sliding-window 512-character token splitter. In real-world enterprise paperwork, this destroys context:
-
Desk Fragmentation: Monetary accounting statements depend on exact column-and-row coordinates. Flat token splitters slice rows in half, changing stability sheets into uninterpretable numbers.
-
Severed Hierarchies: A clause stating “The penalty shall not exceed $10,000” in Subsection 4.2 derives its whole authorized that means from its mum or dad header: “Part 4: Violations of Non-Disclosure”. Blind chunking severs the mum or dad header, creating an ungrounded fragment that semantic search can’t match.
-
The Hierarchical Semantic Parser depicted within the determine above treats paperwork as Summary Syntax Timber (ASTs) slightly than flat textual content. A vision-language structure mannequin identifies headers, paragraphs, multi-column layouts, tables, and figures.
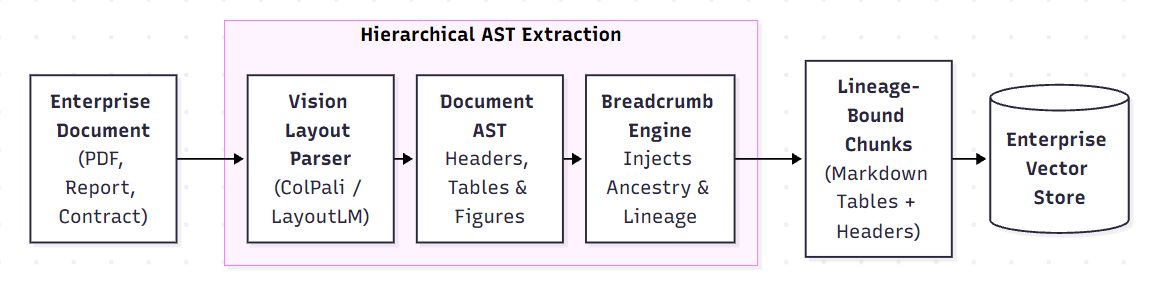
Each little one factor inherits its full ancestral breadcrumb path (e.g., Annual_Report.pdf > Monetary Disclosures > North America > Desk 4.2). Tables are cleanly serialized into Markdown or JSON matrices, whereas charts are summarized by multimodal imaginative and prescient fashions. I’ve mentioned this structure for high-accuracy retrieval at minimal value in my articles on Proxy-Pointer RAG.
Enterprise Worth Proposition
-
Audit-Grade Accuracy on Excessive-Stakes Paperwork: For monetary, authorized, and compliance doc mining, 80% accuracy just isn’t sufficient. Preserving desk buildings ensures monetary numbers are retrieved with 100% relational integrity.
-
Explainability and Provenance: As a result of each chunk carries its precise hierarchical ancestry (Web page, Chapter, Part), human reviewers can confirm the company supply behind an AI declare simply with minimal effort.
-
Unlocking Darkish Knowledge: It pulls clear knowledge out of charts, advanced layouts, and scanned PDFs as a substitute of turning them into garbled textual content. This sectional integrity brings the total semantically related content material into the LLM context, permitting it to offer correct, holistic responses.
Key Benefits & Commerce-Offs
-
Execs: 100% preservation of tabular relationships and accounting logic; excessive retrieval precision by way of prepended breadcrumbs; native multimodal chart comprehension.
-
Cons & Dangers: Ingestion latency is increased (seconds per web page) in comparison with naive textual content extractors; requires GPU-accelerated ingestion infrastructure.
-
When to Use: Important for monetary statements (10-Ks, 10-Qs), scientific trial experiences, authorized contracts, engineering specs, and architectural documentation.
Sample 3: The Ruled Semantic Layer (Metric Shops as AI Guardrails)
Many organizations try and construct “chat together with your knowledge” capabilities by offering an LLM with database desk definitions (CREATE TABLE...) and prompting it to generate uncooked SQL queries.
In enterprise knowledge warehouses, that is typically not sufficient. Actual-world tables comprise cryptic column names, historic flags, and sophisticated enterprise logic. If a monetary analyst asks, “What was our internet annual recurring income final quarter?”, an LLM inspecting uncooked tables has no approach of realizing that enterprise coverage defines “internet recurring income” as:
The mannequin generates an un-governed question that produces an inaccurate determine, adversely impacting govt belief. Worse, an unconstrained LLM can challenge un-indexed multi-table cross joins that overwhelm the warehouse at 100% capability, incurring a big compute value in minutes.
The Ruled Semantic Layer Sample inserts a metric engine (reminiscent of dbt Semantic Layer, Dice, or an enterprise ontology) between the AI mannequin and the info warehouse.
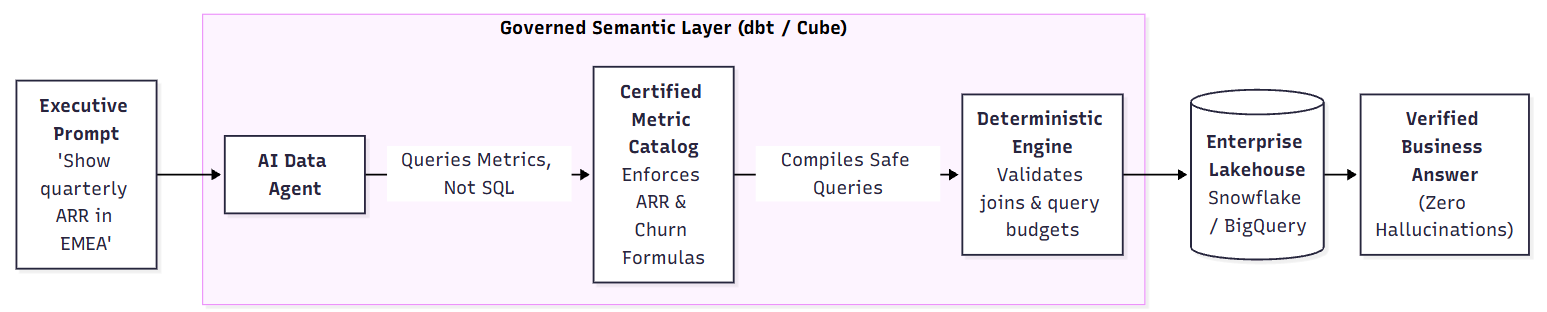
The LLM is prohibited from writing uncooked SQL. As an alternative, it inspects a manifest of allowed Metrics and Dimensions, producing a structured, typed JSON intent. The workload is split between what LLMs do finest (pure language understanding) and what deterministic compilers do finest (mathematical precision and join-graph traversal).
Step 1: The LLM Generates Typed JSON Intent (No SQL)
The agent is supplied with an API manifest containing solely licensed Metrics (e.g., net_arr, churn_rate) and allowed Dimensions (e.g., buyer.area, date.quarter).
When an govt asks about EMEA ARR, the LLM merely interprets pure language right into a structured, validated JSON intent:
Step 2: The Semantic Engine Deterministically Compiles the SQL
The semantic layer is not an AI mannequin. It’s a deterministic compiler holding a pre-modeled graph of tables, verified be part of keys, and audited formulation. As an example:
For our EMEA_ARR question:
-
It appears up
net_arrin its licensed manifest and retrieves the company-approved method:SUM(mrr_usd * 12). -
It appears up
buyer.areaand identifies the verified be part of path betweenfact_subscriptionsanddim_customers. -
It compiles hardened, optimized SQL that injects the necessary enterprise filters (
standing = 'Lively',is_trial = FALSE, and so on.), enforces protectedGROUP BYgrains, and limits question execution budgets.
Lastly, it creates the SQL thereby eliminating the opportunity of LLM hallucinations, duplicate rows or incorrect enterprise logic.
What occurs for adhoc queries?
For instance an person asks a easy question like “How a lot cash did we make final quarter?” that doesn’t have a transparent, unambiguous mapping to a enterprise time period within the manifest. On this case, the LLM maps informal language (“cash”) to licensed catalog metrics (e.g., gross_booked_revenue vs. gaap_recognized_revenue).
If ambiguity exists between a number of licensed metrics, the agent pauses and prompts the person for clarification (“We observe two licensed income figures: Gross Bookings ($14.2M) and GAAP Acknowledged Income ($11.8M). Which might you prefer to evaluate?”).
One other situation is an person asks about uncooked knowledge or area of interest metrics which have by no means been modeled within the semantic layer (e.g., “What’s the common size of buyer assist chat logs in Berlin?”)? In a ruled enterprise structure, the agent doesn’t try and guess or write un-audited SQL towards uncooked tables.
As an alternative, a deterministic guardrail intercepts the request. The agent gracefully halts and redirects the person:
“This question requires knowledge fields that aren’t licensed within the enterprise metric catalog. To make sure accuracy and compliance, I can’t question unverified tables instantly. Please submit a request to the info analytics group to mannequin and certify this metric.”
This refusal is an appropriate function, not a bug. In high-value finance and regulatory compliance queries, an trustworthy refusal is extra precious than a confidently hallucinated question that generates inaccurate numbers.
Enterprise Worth Proposition
-
Imposing a Single Supply of Reality: Ensures that whether or not an govt appears at a Tableau dashboard or asks an AI assistant, the monetary numbers are 100% similar and totally licensed.
-
Eliminating Warehouse Price Spikes: Protects cloud knowledge platforms from runaway, un-indexed cross-join queries generated by probabilistic fashions.
-
Decoupling AI from Schema Migrations: When knowledge engineers refactor warehouse tables, optimize partitions, or rename underlying columns, they solely replace the semantic layer manifest. The agent’s interface stays utterly untouched.
Key Benefits & Commerce-Offs
-
Execs: 0% danger of hallucinated desk joins or invented metric calculations; sub-50ms caching for pre-aggregated metrics; full insulation towards schema adjustments.
-
Cons & Dangers: Requires an current, well-maintained semantic metric layer; can’t reply questions on un-modeled columns outdoors the licensed catalog with out routing by governance evaluate.
-
When to Use: Non-negotiable for enterprise text-to-data, automated BI, govt reporting, or customer-facing analytical brokers.
Sample 4: The Operational Context Retailer (Actual-Time Characteristic Injection)
How It Works
Autonomous brokers don’t simply reply historic questions; they’re required to take operational actions in actual time. For instance, an autonomous fraud-triage agent or buyer retention agent wants up-to-the-second operational state reminiscent of:
-
What number of transactions has this buyer tried within the final quarter-hour?
-
Has this person skilled greater than two software errors of their present session?
-
What’s the real-time stock depend for this SKU on the regional success heart?
Knowledge groups incessantly try to unravel this by both storing operational telemetry in vector databases or querying the cloud knowledge warehouse in the course of the agent’s reasoning loop. Each approaches don’t work effectively:
-
Vector databases are optimized for semantic search over comparatively static textual content. When an replace happens, the database should rewire its HNSW graph index. Overwhelming the database with 1000’s of high-frequency numeric updates triggers fixed background re-indexing, which drains CPU assets and degrades search latency for everybody
-
Querying an analytical warehouse like Snowflake or BigQuery throughout an interactive agent loop incurs a 2- to 5-second round-trip delay. In a 5-step agent loop, database latency alone can improve whole person response time to over 25 seconds.
The Operational Context Retailer Sample integrates an In-Reminiscence On-line Characteristic Retailer (reminiscent of Redis) instantly into the agent’s immediate meeting pipeline.
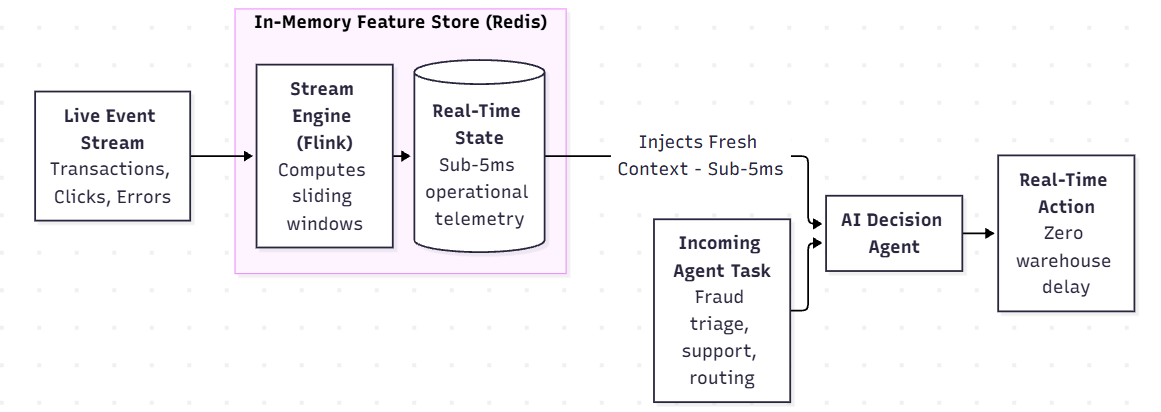
A stream processing engine repeatedly computes sliding-window aggregates and writes them to the in-memory retailer. When the agent is triggered, whether or not by a steady monitoring loop, an occasion threshold, or an incoming person request, the context assembler fetches the goal entity’s lively operational state in beneath 5 milliseconds, after which injects it as a clear, structured context block into the immediate state scratchpad earlier than reasoning begins. This helps the agent to take real-time choices reminiscent of block the cardboard, or direct visitors to a standby server to stop additional software errors within the person’s session.
Enterprise Worth Proposition
-
Actual-Time Operational Autonomy: Empowers AI brokers to behave on what is going on proper now, slightly than what occurred when the info warehouse batch accomplished final evening.
-
Sub-Second Buyer Response Occasions: Optimises agent state-retrieval overhead from seconds to milliseconds, enabling responsive, real-time voice and chat interfaces.
-
Defending Analytical Infrastructure: Directs high-frequency level lookups away from the analytical lakehouse, avoiding costly warehouse computation for operational state queries.
Key Benefits & Commerce-Offs
-
Execs: Sub-5ms state retrieval latency instantly into agent immediate home windows; prevents vector index fragmentation; enforces strict TTL insurance policies to stop stale context.
-
Cons & Dangers: Requires sustaining a devoted streaming pipeline (Kafka/Flink); in-memory infrastructure incurs increased cost-per-gigabyte than object storage.
-
When to Use: Should-have for real-time customer support brokers, automated fraud detection, algorithmic pricing bots, provide chain routing, and lively cybersecurity triage.
Sample 5: The Lineage-Preserving Safety Material (Zero-Belief Retrieval)
How It Works
In conventional enterprise IT, safety is ruled by mature, deterministic frameworks: Function-Based mostly Entry Management (RBAC), Attribute-Based mostly Entry Management (ABAC), and Row-Stage Safety (RLS) embedded inside SQL databases, SharePoint, and Salesforce.
When enterprise knowledge groups construct vector databases and data graphs, they necessitate a redesign of this Entry Management structure. For instance, if HR saves a confidential severance plan in a restricted folder, however the ingestion pipeline strips the ACLs throughout vectorization, an unauthorized worker asking normal severance questions will retrieve the confidential doc as a result of semantic similarity is excessive.
Making an attempt to resolve this with Put up-Retrieval Filtering, reminiscent of retrieving the top-50 chunks by way of vector search and subsequently checking person permissions doesn’t work reliably in manufacturing on account of points reminiscent of:
-
Empty End result Cascades: If essentially the most semantically related chunks are restricted, post-filtering leaves the mannequin with low-relevance remnants, inflicting the agent to hallucinate that no coverage exists.
-
Data Leakage Aspect-Channels: Malicious customers can deduce confidential company initiatives based mostly on response latency variations and system habits.
The Lineage-Preserving Safety Material enforces a Zero-Belief Knowledge Structure. Safety boundaries, entry management lists, and knowledge classifications are extracted instantly from supply methods and connected as immutable metadata to each vector and graph node.
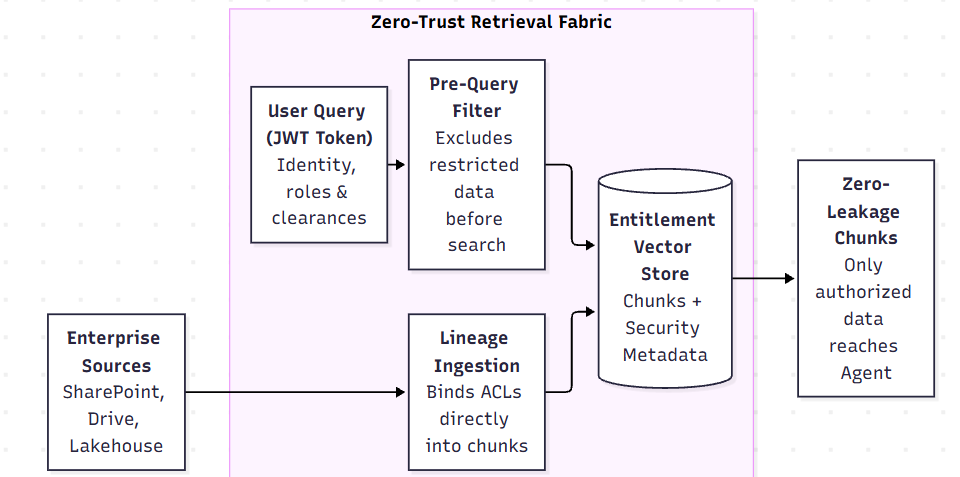
When an agent searches on behalf of a person, the system intercepts the person’s signed token (JWT) to establish verified teams and clearance ranges of the person. The search engine executes Pre-Question Entitlement Filtering, which suggests the search area is mathematically filtered on the index graph degree earlier than vector distance calculations happen. This ends in unauthorized chunks being bodily excluded from the search candidate pool, eliminating knowledge leakage.
Enterprise Worth Proposition
-
CISO and Regulatory Signal-Off: Gives Chief Data Safety Officers (CISOs) and enterprise danger committees with deterministic, verifiable ensures towards inner knowledge exfiltration.
-
Preserving Multi-Tenant SaaS Isolation: Ensures that in multi-tenant environments, one buyer’s proprietary knowledge can by no means be seen to a different tenant, even beneath adversarial prompt-injection assaults.
-
Compliance with Strict Knowledge Governance Mandates: Meets strict regulatory requirements for HIPAA, SOC 2 Sort II, and ISO 27001 by guaranteeing that current knowledge permissions are strictly inherited throughout all AI interfaces.
Key Benefits & Commerce-Offs
-
Execs: 100% mathematical assure towards unauthorized doc retrieval; eliminates empty-result cascades; inherits current enterprise id methods (Okta, Azure AD).
-
Cons & Dangers: Will increase index storage overhead on account of compound metadata buildings; requires engines with native filtered HNSW/IVF indexing to take care of search velocity.
-
When to Use: Necessary for any enterprise assistant responding based mostly on inner communications, HR recordsdata, monetary audits, affected person data, or shared multi-tenant repositories.
Sample 6: The Autonomous Knowledge Curation Flywheel (High quality Pre-Filtering & Artificial Grounding)
How It Works
Simply as any analytical engine, AI methods is not going to magically extract intelligence from a long time of un-curated knowledge lake. Enterprise knowledge lakes are crammed with noise reminiscent of automated out-of-office autoreplies, outdated draft memos containing outmoded numbers, corrupted OCR scrapes, and duplicate Jira tickets.
Feeding this uncooked knowledge into vector shops or data graphs ends in Rubbish-In, Rubbish-Out , ie; low-quality chunks crowding out authoritative documentation throughout semantic retrieval.
Nonetheless, utilizing frontier autoregressive fashions (like GPT-5) to judge and clear each doc in a million-page repository is financially unfeasible, costing 1000’s of {dollars} in token costs. Moreover, paperwork written by engineers typically fail to match the non-technical vocabulary utilized by enterprise executives throughout search.
That is the place Autonomous Curation and Augmentation utilizing a Knowledge Curation Flywheel provides worth.
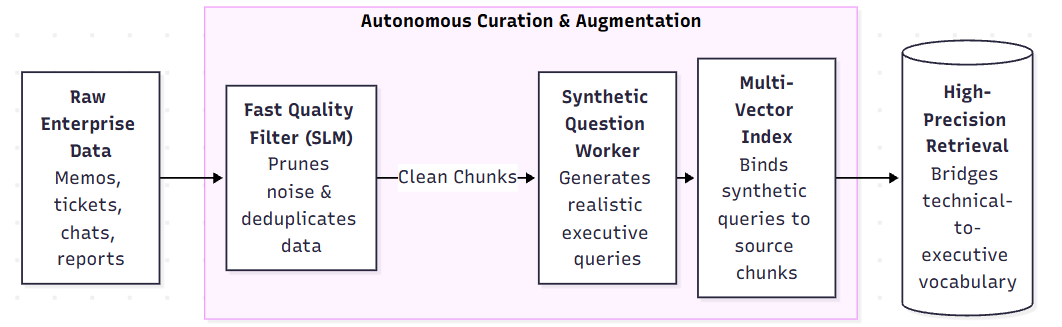
The Autonomous Knowledge Curation Flywheel deploys a tiered method:
-
Tier 1: Excessive-Pace Calibrated High quality Filtering: Uncooked textual content passes by an ultra-fast classification mannequin (a small specialised SLM, or a non-autoregressive resolution mannequin reminiscent of JEV). In a number of milliseconds, the mannequin evaluates informational entropy, grammatical construction, and factual density. Low-value noise (e.g., error logs, calendar invitations) will get dropped on the first gate.
-
Semantic Deduplication: Chunks that cross the standard gate are evaluated towards current corpus entities. If a brand new doc is 95% redundant with an current authoritative web page, the pipeline updates supply lineage metadata slightly than creating duplicate vector factors.
-
Uneven Artificial Augmentation: Authoritative chunks cross to an asynchronous employee working a small fine-tuned mannequin (e.g., an 8B parameter SLM). The mannequin generates 3 to five lifelike questions that this chunk solutions from an person’s perspective (e.g., “What’s our coverage on reimbursement for consumer leisure in APAC?”).
-
Uneven Indexing: The artificial questions are embedded alongside the doc chunk. When an worker asks a query, the vector database matches the person’s question towards the artificial questions slightly than the uncooked textual content, enormously bridging the vocabulary hole and boosting search recall.
Enterprise Worth Proposition
-
Stopping Vector Database Bloat: Prunes as much as 40% of un-curated enterprise noise earlier than it reaches vector indices, optimising cloud storage and search infrastructure prices.
-
Enhance in Retrieval Accuracy: Uneven artificial query matching bridges the terminology divide between technical authors and enterprise customers, enormously growing retrieval precision.
-
Financial Sustainability: Replaces costly frontier mannequin batch processing with quick, calibrated micro-decision fashions and native SLMs, delivering enterprise-scale knowledge curation at a fraction of the fee.
Key Benefits & Commerce-Offs
-
Execs: Eliminates index bloat and duplicate chunk retrieval; solves the vocabulary mismatch between technical documentation and govt prompts; reduces ongoing storage spend.
-
Cons & Dangers: Requires an preliminary offline funding in knowledge analysis rubrics and native SLM internet hosting; artificial query era itself should be monitored and evaluated to make sure the questions are lifelike and artificial hallucinations don’t enter the metadata layer.
-
When to Use: Important for enormous enterprise doc repositories (eg, SharePoint intranets, Confluence areas, legacy buyer assist ticket archives, and shared electronic mail folders).
Architectural Commerce-Off Matrix
When architecting an enterprise AI knowledge basis, no single sample solves each requirement, nor each sample is required for a use case. The matrix beneath evaluates the six patterns throughout the core dimensions which might be vital for enterprise feasibility: Infrastructure Price, Implementation Complexity, Knowledge Freshness, and Governance Rigor.
|
Architectural Sample |
Infrastructure Price |
Implementation Complexity |
Knowledge Freshness Assure |
Governance & Safety Rigor |
|---|---|---|---|---|
|
Sample 1: Twin-Pace CDC Sync |
Reasonable (Kafka, Redis, Micro-embedders) |
Medium (Streaming pipelines) |
Close to Actual-Time (Sub-second to seconds) |
Excessive (Deterministic tombstone pruning) |
|
Sample 2: Multimodal AST Parsing |
Excessive (GPU VLM structure situations) |
Excessive (Visible parsing engines) |
Batch / Occasion (Depending on ingestion) |
Excessive (Preserves hierarchical provenance) |
|
Sample 3: Ruled Semantic Layer |
Low (Semantic proxy layer) |
Medium (Metric catalog modeling) |
Actual-Time (Direct warehouse learn) |
Most (Zero hallucinated joins/metrics) |
|
Sample 4: Operational Context Retailer |
Reasonable (In-memory Redis cluster) |
Excessive (Actual-time stream aggregation) |
Sub-Second (Dwell operational telemetry) |
Reasonable (Schema-validated entity views) |
|
Sample 5: Lineage & Entitlement Filtering |
Low (Metadata indexing overhead) |
Medium (JWT & ACL synchronization) |
Synchronous with Ingestion |
Absolute (Zero-Belief) ({Hardware}-level isolation) |
|
Sample 6: Autonomous Curation Flywheel |
Reasonable (Native SLM employee pool) |
Medium (Multi-vector indexing) |
Asynchronous / Batch |
Excessive (Automated high quality quarantine) |
Frequent Anti-Patterns to Keep away from
It is not uncommon for enterprise deployments to design knowledge platforms utilizing seemingly logical “anti-patterns” that don’t scale with growing complexity of manufacturing. Right here, I’m noting 5 such architectural and organizational anti-patterns:
-
The “Uncooked Desk Dump” Anti-Sample: Pointing an LLM instantly at uncooked relational warehouse tables and anticipating dependable Textual content-to-SQL doesn’t work effectively. Fashions can’t infer unwritten enterprise logic or company accounting definitions. Neither do they all the time generate the right SQL for repetitive advanced queries. All the time insert a Ruled Semantic Layer (Sample 3) to show licensed metrics slightly than uncooked DDLs.
-
The “Batch-Solely Vector Index” Anti-Sample: Counting on scheduled nightly batch scripts to scrape lakehouses and rebuild vector shops ends in silent semantic drift, stale solutions, and enormous re-embedding prices. All the time deploy event-driven CDC with content material hashing (Sample 1) to course of updates incrementally.
-
The “Put up-Question Safety Filter” Anti-Sample: Retrieving vectors throughout a whole firm and filtering unauthorized data in software code causes empty-result cascades and safety leaks. All the time mandate mathematical Pre-Question Entitlement Filtering (Sample 5) instantly inside the retrieval engine.
-
The “Blind Character Splitter” Anti-Sample: Slicing monetary stability sheets and sophisticated contracts with sliding-window character splitters breaks tabular relationships and strips essential mum or dad headers. All the time parse advanced enterprise paperwork into hierarchical Summary Syntax Timber (Sample 2).
-
Storing Dynamic Operational State in Vector Indices: Making an attempt to trace real-time person purchasing carts, lively gadget counters, or rolling fraud scores by repeatedly updating vector factors causes intensive index computations and CPU exhaustion. All the time route high-frequency operational state by an In-Reminiscence Characteristic Retailer (Sample 4).
Conclusion
Enterprise AI just isn’t an train in immediate engineering, neither is it a race to license the most important frontier mannequin. In real-world enterprise manufacturing, synthetic intelligence is a methods engineering self-discipline constructed throughout three interdependent layers:
-
The Motion and Reasoning Layer (Agentic Programs): On the high sits the agentic runtime, which includes autonomous ReAct loops, supervisor-worker hierarchies, and self-correcting resolution swarms (refer my article right here). These brokers are tasked with taking real-world actions, triaging incidents, and reasoning by advanced, multi-step workflows.
-
The Information and Relational Layer (GraphRAG): Within the center sits the relational material, consisting of ontologies, data graphs, and hybrid graph-vector retrievers that join disjointed information throughout disparate enterprise domains and allow deep, multi-hop reasoning (learn extra in my article right here).
-
The Knowledge Enablement Layer (The AI Knowledge Basis): On the base sits the fashionable knowledge platform. Right here resides dual-speed streaming pipelines, hierarchical doc parsers, ruled metric compilers, real-time function caches, and zero-trust safety materials as detailed on this information.
With no disciplined knowledge enablement layer on the base, the higher layers wouldn’t perform. Autonomous brokers hallucinate as a result of they’re equipped uncooked, un-governed warehouse tables. Information graphs change into corrupt as a result of ingestion pipelines fail to propagate deletions and revisions. And safety evaluations fail earlier than manufacturing rollouts as a result of supply permissions have been stripped throughout embedding.
In the end, the reliability of enterprise AI relies upon instantly on the standard and governance of the info pipelines feeding it. By treating knowledge synchronization, doc parsing, metric compilation, and entitlement propagation as core architectural necessities slightly than secondary ingestion duties, organizations set up a sturdy basis for data graphs, vector shops and autonomous resolution methods.
Join with me and share your feedback at www.linkedin.com/in/partha-sarkar-lets-talk-AI