Each time anybody builds ML fashions, the main focus rapidly strikes from general numbers and extremely technical measures of mannequin well being to how assured we’re in every predicted end result. In essence, can my mannequin reliably ship correct outcomes throughout the board? Mixture metrics reminiscent of accuracy, recall, precision, R2, and AUPRC/AUROC are sometimes not sufficient to persuade stakeholders of a mannequin’s real-world efficiency — irrespective of how fastidiously they’re defined.
That is the place Conformal prediction (CP) might assist. Along with a prediction, CP creates an interval across the prediction that quantifies uncertainty. Such uncertainty quantification by means of prediction intervals bridges the hole between technical measures of mannequin efficiency and stakeholder belief. This makes conversations about mannequin reliability far simpler than counting on general mannequin well being. For an in depth rationalization of the mathematics, see Vovk, Gammerman, & Shafer, 2005. For a extra accessible overview, try Angelopoulos & Bates, 2022. Dancker, 2024 explains CP clearly, and Allen, 2023 gives a useful Python code walkthrough.
The CP algorithm is an intuitive concept that’s versatile throughout completely different predictive fashions (regression, boosting/bagging fashions, neural networks, and so on.) and simple to use with out the assistance of any specialised machine studying packages. The CP algorithm wraps a statistical course of round a predictive mannequin to generate prediction interval round every predicted worth. Intuitively, the worth of making use of CP is subsequently to handle the issue of reliability of predictions — a likelihood of buyer buy of 77% is nice, however what if this likelihood may be as little as 50% and as excessive as 97% — such a large band across the predicted likelihood makes the prediction much less dependable, versus saying the expected likelihood will nonetheless be between 70% and 85%.
You could be questioning why CP and why not different well-known uncertainty quantification strategies reminiscent of bootstrapping or dropout strategies used for quantifying uncertainty in neural networks? There are three predominant causes:
1) CP doesn’t require any explicit mannequin specification and works fairly nicely for black-box fashions
2) It’s computationally very low-cost, particularly when in comparison with bootstrapping, which depends on repeated resampling; and
3) Exchangeability: In keeping with Vovk, Gammerman, & Shafer, 1999, exchangeability ensures that calibration (used to compute the prediction interval) and check factors (used to check the computed prediction interval) may be handled as if they arrive from the identical distribution. Because of this, the prediction intervals computed on the calibration set present a sound protection assure. If α proportion of calibration factors fall exterior the interval (and 1−α are inside) for the calibration set on common, then the identical protection stage holds for the check factors on common.
With these in thoughts, let’s stroll by means of the algorithm utilizing the publicly out there On-line Buyers Buying Intention Dataset (Sakar & Kastro, 2018). This dataset is on the market within the UCI Machine Studying repository and is licensed beneath Artistic Commons Attribution 4.0 Worldwide (CC BY 4.0) license, which allows business use. It’s fairly applicable for this instance at hand, as it’s a typical dataset for buyer buy prediction.
First, let’s begin with all the fundamental packages that we want for this train.
Subsequent up, we load the Buyers Buy Intent Dataset. For some cause, I couldn’t make the API name work, so I went to the UCI Machine Studying Repository and downloaded the CSV file as a substitute.
The CP algorithm wants the information break up into three elements:
-
Practice set to be taught a mannequin (e.g., classifier, neural community, and so on.)
-
Calibration set to quantify the mannequin’s uncertainty by means of conformal scores that allow the event of prediction intervals (extra of this in just a little bit)
-
Take a look at set to judge the reliability of the mannequin and its uncertainty quantification.
The above is achieved by means of a 70%/15%/15% break up between the practice/calibration/check units:
Given this pattern design, let’s do that in a step-by-step trend:
Step 1: Practice the mannequin
I start by coaching an XGBoost mannequin to the web buy intent dataset to grasp the impression of all out there options on the likelihood of buy (Income=1 indicating the consumer session resulted in an e-commerce buy and 0 indicating lack of buy). For a parsimonious illustration of the CP algorithm, I don’t do any further function engineering on this article.
Earlier than modeling, let’s first see the distribution of the Income variable to find out whether or not we’ve got any class imbalance.

Based mostly on the distribution of the 1’s and 0’s within the Income variable proven in Determine 1, solely 15% of the information factors belong to the optimistic class (=1). We subsequently want imbalance remedy. Once more, for the sake of parsimonious illustration, I exploit weighted XGBoost, though we might do a extra rigorous choice with different strategies like SMOTE and Random Undersampling too.
Now that we’ve got match the mannequin, let’s see the highest 10 options by significance

Intuitively, the function significance is smart. For instance, the variety of instances the shopper visited the webpage (PageValues) is clearly a very powerful indicator of buy choice, adopted by the month of buy (e.g., Nov could possibly be pushed by the ThanksGiving break). Equally, clients usually go to the product web page a number of instances earlier than making the choice; therefore, VisitorType_Returning_Visitor additionally exhibiting up there is smart.
With the skilled mannequin in place, lets flip to calibrating its uncertainty.
Step 2: Calibrate the mannequin
Calibration helps us measure how far predictions are from actuality, and construct prediction intervals round them. It consists of 4 elements.
-
Predict possibilities on the calibration set p(x)
-
Compute conformal scores, i.e., how far or shut the expected likelihood p (x) is to the true label (y). It could take a number of practical types; I select a easy and intutitive one: |y-p(x)|, the place y is the true label (1 or 0). This ensures that the bigger the rating, the farther away it’s from the true label. You are able to do a psychological math with just a few examples to see this your self. There actually are different choices that may measure the conformal rating, reminiscent of inverse likelihood weights, normalized residuals, and so on. Once more, for issues of parsimony, I select absolutely the residuals right here.
-
Select an appropriate error tolerance α. Consider α because the proportion of observations we’re prepared to simply accept will fall exterior the prediction interval that we’ll go on to compute. Let’s say it’s α = 30%. This may imply that 30% of the predictions will fall exterior the prediction interval. If we flip this argument, it signifies that the prediction interval will comprise at the least 70% of the true labels.
-
Discover the 1-α percentile worth (seventieth percentile) of the conformal scores from above to acquire the conformal quantile (q). We are able to additionally consult with this as prediction interval, which we use to develop confidence bands round predicted possibilities on the check information
I clarify this with a simplistic instance in desk 1 under. For every of the purchasers, we calculated the expected likelihood of buy in addition to the conformal rating based mostly on the distinction with the true label (final column). If we kind the conformal rating in ascending order: [0.1,0.2,0.25,0.35,0.4], the seventieth percentile rating could be 0.35 → the conformal quantile.

Right here is the chunk of code that predicts the possibilities and computes the conformal scores and conformal quantile on the calibration set.
Calibration offers us a quantile-based interval that helps us decide how dependable the predictions can be on unseen (check) information, which is what we do within the subsequent part.
Step 3: Apply to the check set
Step 3.a: Mounted interval method
First, we use the calibration information derived conformal quantile in step 2 on predicted possibilities on the check set to generate prediction intervals. As seen within the earlier step, the conformal quantile was 0.35. I once more draw upon a hypothetical instance illustrated in desk 2 under to develop the prediction interval utilizing predicted possibilities and conformal quantile.
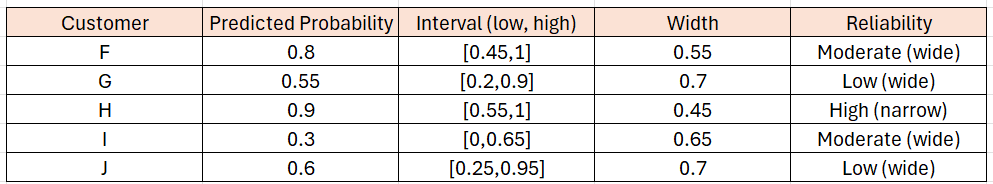
As you’ll be able to see by means of this dummy instance, buyer F has a excessive predicted likelihood of buy (80%) however with a reasonably large prediction interval. This is able to make it a much less dependable prediction in comparison with buyer H, which has a excessive predicted likelihood (90%) in addition to a slender prediction interval.
Discover that I needed to clip the intervals to 0 and 1, as we’re coping with a binary classification mannequin, so the bottom and highest possibilities can not transcend 0 and 1, respectively.
Beneath is the code chunk to use this to the check set and develop prediction interval across the predictions.
The aim behind this train is to look at if every prediction has a distinct prediction interval round it. So, let’s plot every check set information level to see if the prediction interval varies for them in determine 3.

Word that it is a naïve model of the prediction interval — the variance in interval throughout check information factors is because of the clipping at 0 and 1 — in concept, this is able to have been equal to 2q with out clipping. Nonetheless, in spirit, this almost equal prediction interval round every check information level doesn’t assist our authentic downside, which is that every predicted level has a various stage of reliability or confidence. Subsequent, I current an extension of this method which considers domestically adaptive intervals.
Step 3.b: Adaptive interval method
As a substitute of utilizing a hard and fast prediction interval drawn from the calibration pattern, I’ll weigh every calibration level based mostly on its similarity to every check information level. Subsequently, if x represents the set of options of the check information level, and x’ represents the options for the ith calibration set, then we are able to compute the space between them. Let’s use the Gaussian Kernel (Bishop, 2006) outlined under to find out a Euclidean distance, though many different distance measures might have been alternatively utilized right here. Let me additionally take σ because the 25th percentile of the calculated distance. The smaller σ, the extra adaptive your weights are to variation within the calibration information factors.

Let’s think about a easy instance with one variable, PageValues and an illustrative set of buyer information factors proven in desk 3. Suppose we’ve got a check datapoint the place PageValues=45 and the expected likelihood is 0.75. For a set of three clients within the calibration set, with information on their PageValues (Second column) in addition to computed conformal scores (third column). Let’s say the σ was 10. We got down to calculate the Euclidean distance. For every of the three clients, the uncooked distance to the check information level could be (45–20=25), (45–40=5), and (45–60=15). Utilizing the method above, we are able to estimate a uncooked weight of 0.044, 0.882, and 0.324 for every information level. If we normalize these weights with their sum (~1.25), we get the normalized weights within the final column. Naturally, PageValues of 45 are closest to buyer B, which will get 71% of the load, and farthest from buyer A, which will get 4% of the load.
For simplicity, I took just one function (i.e., the PageValues) for this instance. Nonetheless, the Euclidean perform can absorb all of the options within the information to compute the pointwise distances.

Subsequent, if we calculate the cumulative weight by the sorted conformal scores, then it could be buyer A → 0.04, buyer B → 0.75 (0.04 + 0.71), and buyer C → 1 (0.04 + 0.71 + 0.26). Once more, with α = 30%, the 1-α percentile is the smallest rating with cumulative weight better than or equal to 1-α (=70%). This is able to subsequently be 0.2. So the prediction interval for this explicit check information level could be 0.2. If we repeat this course of for every check information level, we’ll get a prediction interval that’s adaptive to that check information level by way of its similarity with the calibration information, somewhat than a single normal quantile that we estimated earlier than.
The chunk of code under would construct the adaptive prediction interval for every of the check information factors:
Much like the mounted prediction interval chart, if we’re to plot these to get a visible sense of the variability of every prediction, we are able to do that:

As you’ll be able to see in determine 4, the numerous variety of spikes signifies that we’re adapting the prediction interval to every information level within the check set.
Step 4: Placing this all collectively for dependable predictions
Let’s get all the way down to estimating the variety of clients who’re more likely to make a purchase order. Suppose we consider a 70% predicted likelihood of buy as an inexpensive cut-off to distinguish doubtless purchasers from non-purchasers.

As we are able to see in determine 5, 305 clients out of 1850 (=16.5%) are what the mannequin predicts could be the doubtless purchasers. However are these dependable estimates?
To reply this query, I first have a look at the prediction interval that we’ve got created for every predicted check information level. Particularly, I attempt to perceive how a lot the prediction interval (i.e., distinction between the higher and decrease quantile) of every predicted level varies throughout the precise predicted likelihood.

Determine 6 signifies that, on common, the prediction interval retains rising till we attain the 50% mark after which decreases once more. This conduct is anticipated, as predictions on the excessive ends of the spectrum will doubtless have a transparent cause for being there. Naturally, the prediction interval could be narrower because the mannequin is assured in predicting clear-cut instances of 1 or 0. It’s the center portion, the place it might go both manner, that the mannequin’s prediction interval additionally will increase (and reliability decreases).
Nonetheless, the essential factor to notice is that for the n=305 information factors with predicted likelihood better than 70%, the prediction interval can range extensively, as proven under in determine 7.

There could possibly be two approaches to decide on probably the most dependable predictions:
-
Possibility A: The bounds of prediction needs to be inside sure share of the prediction itself. Suppose the prediction is 80% and we would like the prediction width to be inside 30% of this prediction. So, we think about a prediction to be dependable if its certain is > 56% and higher certain is lower than or equal to <104%. This is able to qualify 174 observations out of the 305 doubtless purchasers as dependable(=57%).

-
Possibility B: The prediction width is inside a sure cut-off, let’s say 30% → i.e., any doubtless purchaser whose prediction interval width is lower than or equal to 30% is taken into account dependable. On this case, this is able to qualify 129 observations out of the 305 doubtless purchasers as dependable(=37.4%).
-
Possibility C: Prediction width should inside a sure threshold of the expected likelihood. Let’s say we proceed to contemplate a width threshold of 30%. If we think about a predicted likelihood of 80%, then the width mustn’t exceed 24%. On this case, this is able to qualify 103 observations out of the 305 doubtless purchasers as dependable(=29.9%).

Conclusion
As you’ll be able to see, the CP algorithm offers us the added consolation of selecting dependable predictions based mostly on user-defined thresholds that may be extensively (and fairly simply) utilized to most prediction use instances. It tells us how a lot we are able to belief every prediction with out relying solely on the general mannequin well being. From a sensible standpoint, this is usually a nice add-on to the ML mannequin that allows constructing stakeholder belief. Such visibility additionally will increase the actionability of machine studying fashions. The adaptive methodology could possibly be an particularly helpful toolkit for information scientists, though it could not carry the formal protection assure.
As mentioned earlier within the introduction, this isn’t the one methodology to quantify mannequin uncertainty. Relying on the information and context, different strategies may go well with higher. The outcomes proven are experiments, somewhat than proof of mathematical ensures of the CP algorithm. So, please think about this text and the outcomes as a sensible information somewhat than a definitive tackle the topic. Additionally, this displays my very own studying journey, and should you discover errors or have recommendations, I’d welcome your suggestions and ideas.
Disclaimer: Views are my very own and don’t mirror these of any employer.
References:
-
Allen, M. (2023). Conformal Prediction for Machine Studying Classification -From the Floor Up. [Towards Data Science]
-
Angelopoulos, A. N., & Bates, S. (2022). A mild introduction to conformal prediction and distribution-free uncertainty quantification. arXiv preprint arXiv:2107.07511v6
-
Bishop, C. M. (2006). Sample Recognition and Machine Studying. Springer
-
Dancker, J. (2024). All You Want Is Conformal Prediction. [Towards Data Science]
-
Sakar, S., & Kastro, Y. (2018). On-line Buyers Buying Intention Dataset. UCI Machine Studying Repository. https://doi.org/10.24432/C5F88Q. Licensed beneath CC BY 4.0.
-
Vovk, V., Gammerman, A., & Shafer, G. (2005). Algorithmic studying in a random world. Springer