

Someplace in your quantization runbook there may be one line that decides whether or not the int8 construct ships. Within the ten paperwork I surveyed, wherever that line is written down in any respect, it’s a model of the identical sentence. EdgeGate’s gate desk writes it as “INT8 accuracy ≥ FP32 accuracy − 1%”. The oneuptime guidelines reaches for QAT when PTQ “loses greater than 1% accuracy”. A sensible PTQ information says evaluate top-1 and top-5 towards the FP32 baseline. One metric, one comparability, one verdict.
This text is an audit of that line, and it ends by asking you so as to add to it a false-accept and a false-reject charge, measured on the threshold your config file truly holds. Neither is within the line as we speak. That absence just isn’t an oversight.
All pictures, except in any other case famous, are by the creator.
An audit within the type of a depend
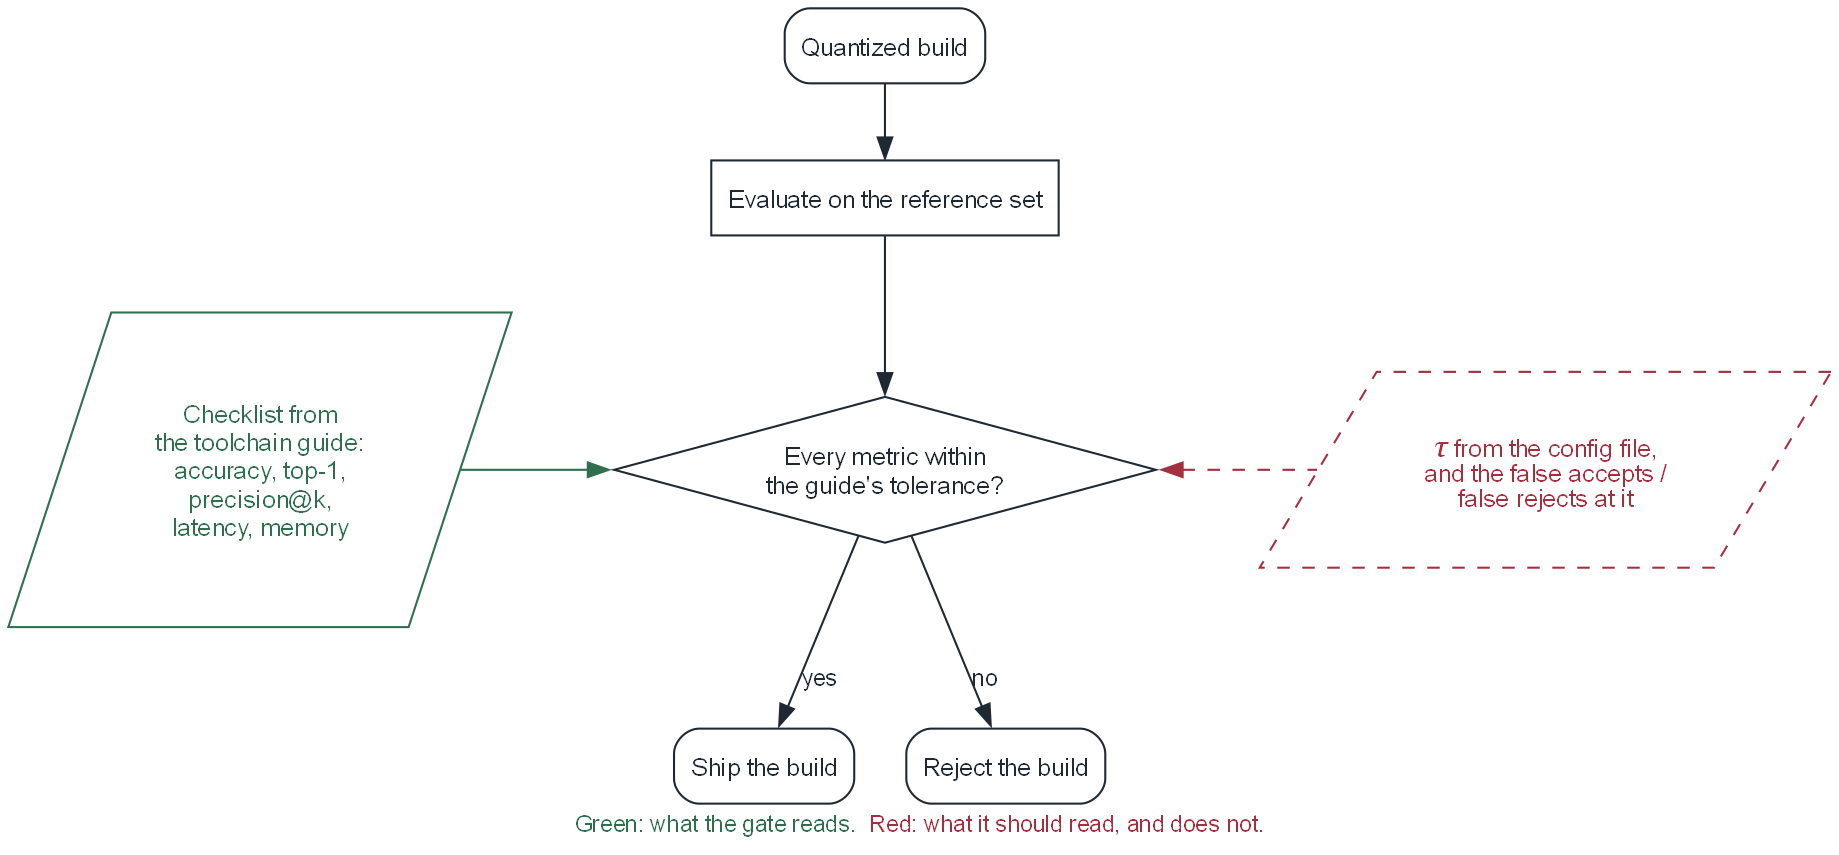
Undergo your acceptance gate and tally the numbers whose worth depends upon the place your resolution threshold sits. Within the ten paperwork I surveyed, the reply is zero — each gate is constructed from accuracy, top-1, top-5, output variance, latency, reminiscence.
The ten are usually not ten gates, and the cut up issues. Two of them title a numeric bar — EdgeGate’s “INT8 accuracy ≥ FP32 − 1%” and oneuptime’s 1% set off for switching to QAT — and each bars are an accuracy delta. 5 extra let you know to check accuracy towards fp32 with out naming a quantity. The final three are the remediation path you observe when that comparability comes out badly. Three genres, one depend: zero. The quantity that decides is an accuracy quantity, the quantity you attain for when it fails is an accuracy quantity, and nowhere alongside that chain does a threshold-dependent one seem.
That zero just isn’t an accident of which paperwork I picked. These metrics grade the mannequin, and the factor that decides an settle for from a reject just isn’t the mannequin: it’s a fixed wrapped round it — a similarity threshold, a confidence cutoff, a reject gate — fitted towards the fp32 scores. Quantization just isn’t a impartial export; it adjustments how scores are produced. A gate made completely of threshold-free numbers can’t ask whether or not that fixed nonetheless lands the place you set it, irrespective of what number of such numbers you add.
The declare, then, just isn’t that the business’s gate is incorrect. It’s that the gate is structurally incapable of seeing a selected, measurable failure, and that seeing it prices two numbers and a day of measurement. The remainder of this piece is the proof: that the failure is actual, that nothing already within the gate would have caught it, and that the restore is reasonably priced however not free.
The seam this text is about
I measured that failure in a single place — face verification, a pretrained ArcFace encoder, an int8 drop constructed by a Hailo toolchain — as a result of that’s the place I might get actual numbers reasonably than a slide-deck declare. The dimensions of the impact beneath belongs to that drop and travels no additional; the restrictions appendix is the total listing of what this measurement doesn’t set up. The depend does journey: it’s a property of what the gate is manufactured from, not of my encoder. The place else the seam runs — closed-set classification, detection, plain retrieval — is a map on the finish of this piece, after the numbers have earned it.
A gap this low cost to shut is value one query: why is it nonetheless open? Not as a result of the underlying truth is obscure. {That a} threshold belongs to a selected mannequin on particular knowledge, and dies when both adjustments, is a typical playbook merchandise in RAG and vector search (Threshold by really feel; the RAG threshold pinned to an absolute rating), the place groups pin cutoffs to a mannequin revision and re-derive them in CI. In biometrics it’s foundational, since false-match and false-non-match charges are outlined towards a threshold. Each halves of the data exist and are written down.
What doesn’t exist is the overlap. Learn what you’re truly handed whereas transport an int8 construct — the compiler person information, the seller’s accuracy-debugging web page, the sting deployment guidelines — and “threshold” seems as an NMS parameter, a compiler cut up, or harness consistency, by no means as “re-derive the working level after quantization” (see the survey desk beneath).
Some groups shut that hole anyway: an organisation below biometric certification re-derives its working level on a schedule of its personal, and this text just isn’t addressed to them. It’s addressed to everybody whose acceptance criterion comes from the toolchain documentation — the place the fixed that turns a rating into a choice lives in a config file the construct course of by no means produces and the gate by no means reads. No person decides to ship an inherited threshold; the brink is just not one of many issues a construct is known to supply. In that setting the individuals who personal the brink are usually not within the room when the construct is accepted, and the doc that accepts the construct has no line for them. That’s the seam this text is about, and it’s why the depend got here out at zero.
What the gate sees
So: the desk the gate reads. Identical encoder in fp32 and int8, the identical analysis pictures, embeddings and metrics facet by facet. The drop seems virtually free:
-
precision@10: 0.978 → 0.972
-
rank-1: 0.990 → 0.985
When you stopped right here — and the gate says it’s possible you’ll — you’d ship.
Now discover what these two numbers have in frequent. Precision@10 and rank-1 each ask who got here again first, not how excessive the rating was. They’re threshold-free by development: no matter occurred to the size the scores dwell on, these are the final metrics it will present up in — and they’re what the acceptance gate is manufactured from. The identical sample — a big share of particular person predictions altering whereas top-1 barely strikes — is documented for quantized picture classifiers [1]; it isn’t a quirk of this drop.
What it can’t see
Listed here are the 2 numbers from the opening — those that by no means made it onto the dashboard. Repair the brink — go away within the config precisely the quantity fp32 was calibrated to on one identification pool — and rating held-out pairs from a disjoint identification pool. Already at fp32 the false-accept depend is 30 out of 10 000 impostor pairs. Apply the identical inherited cutoff to the int8 drop and the depend jumps to 104 (FAR 0.0104): about 3.5× the held-out fp32 charge, FAR delta +0.0074 on the identical impostor pairs (76 reject→settle for flips towards 2 the opposite means). False rejects transfer with them: 582 → 745 out of 10 000 real pairs (FRR 0.0745).
And see what did not occur. You didn’t commerce strictness for laxity. Each error charges acquired worse without delay. That isn’t one working level sliding alongside the identical curve — it’s a totally different curve.
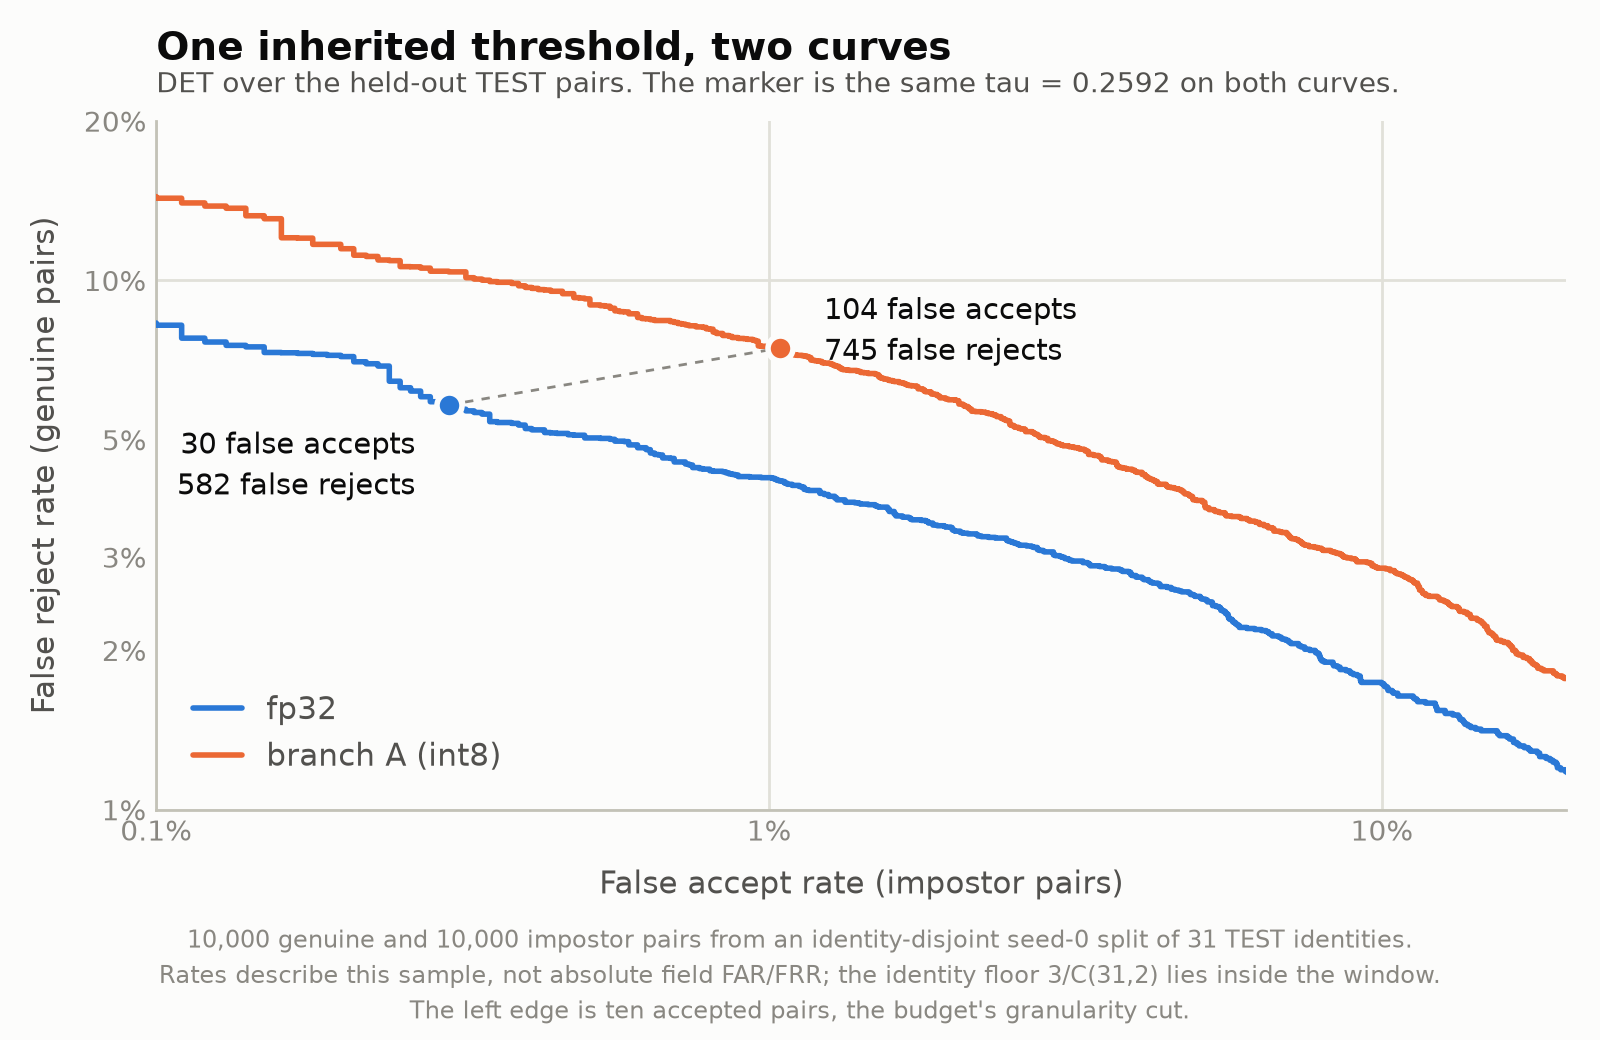
One inherited threshold, two curves. DET for the fp32 reference and the full-int8 construct on the identical held-out TEST pairs, with the inherited τ = 0.2592 marked on every. The curves don’t coincide, and throughout the window proven no selection of threshold places the int8 construct again on the fp32 one. Charges on one fastened pattern of 31 identities, not absolute area FAR/FRR; the determine’s footnote carries the denominators and the window’s left edge.
Trying more durable within the incorrect locations
The apparent defence is that I measured it incorrect. I scored at a set cutoff — the literal quantity derived on fp32 DEV impostors after which held on TEST. That isn’t how the sphere reviews it. The conference is TAR at FAR = 1e-4, a quantity that quietly re-derives the cutoff on the analysis set earlier than printing the consequence. NIST FRVT Half 3 (NISTIR 8280) [2] is blunt about what that conference hides: most educational research, it says, report false adverse charges “at fastened false constructive charges reasonably than at fastened thresholds, thereby hiding excursions in false constructive charges and misstating false adverse charges.” NIST is monitoring excursions throughout demographic teams reasonably than throughout builds, so the transposition is mine — however the premise it rests on is precisely mine too: “the overwhelming majority of biometric techniques are configured with a set threshold towards which all comparisons are made.” A deployed system re-derives nothing. It holds a relentless in a config file till a human edits it. Report this drop the usual means and the failure leaves the desk — the conference hides the identical failure the gate does. That’s the reason for the protocol, not a flaw in it.
The second defence is that I didn’t take a look at sufficient panels. I did look. A fifth of the neighbour listing turned over (recall@10 towards fp32 is 0.81) whereas the gate’s quantity moved by six tenths of a degree — the rating desk survived as a result of the swapped pictures are normally the identical individual. The geometry checks stayed flat: intrinsic dimensionality 269 → 271, distinction 0.596 → 0.567. Not a type of numbers is a perform of the place the cutoff sits. Nor would a wider gate have rescued the scenario. The 2 objects in my survey desk that evaluate int8 outputs towards fp32 immediately — EdgeGate’s output variance, PyTorch’s per-layer SQNR — might nicely have registered that one thing moved. Neither can say which facet of the cutoff it moved to, or how far the fixed now sits from the speed it was fitted for. That’s what threshold-free means, and it’s the complete content material of the depend. 4 inexperienced panels on one drop — two rating numbers, recall towards fp32, the geometry checks — and the one pink one was the panel no one was watching.
The reflex, when you settle for these numbers, is to achieve for the compiler. The knob that appears made for that is defending the primary and final layers with further bits — a heuristic my vendor repeats, and which traces again to a single related-work line in NVIDIA’s integer-quantization paper reporting that different folks do it [3] at sub-8-bit widths. That paper’s personal int8 suggestion is the other: quantize every part, then discover the delicate layers by measuring them. I ran it at 4 scopes — the embedding head (fc1), the pinnacle plus its previous batch-norm, the enter stem (conv1) alone, and first-and-last collectively — and below the identical held-out protocol all 4 left the false-accept depend at 102–104 towards fp32’s 30, indistinguishable from full int8 (a null about this drop, not about selective 16-bit typically — see the restrictions appendix). Which ought to have been the inform. The heuristic by no means promised something in regards to the scale a cosine threshold is measured on: each declare behind it, thinly sourced or not, is a declare about accuracy. I reached for an accuracy instrument as a result of these are the instruments mendacity round — the identical reflex that put an accuracy quantity within the gate.
The place else the seam runs
Faces have been the case I might measure. The magnitude is theirs alone, however the seam is structural: wherever an encoder emits a steady rating and one thing downstream cuts it into a choice, that lower is a continuing fitted to at least one model of the encoder, and nothing within the gate re-checks it. Car gallery matching is sort of isomorphic — identical cosine, identical accept-or-reject. Closed-set classifiers don’t have any similarity cutoff, however they’ve a confidence at which a human will get pulled in, and confidence calibration is what quantization has been proven to maneuver, in quantized classifiers [1] and in VLMs [4] — in both route, relying on whether or not the bottom mannequin was under- or overconfident to start with. That the transfer will be an enchancment just isn’t a reprieve: a cutoff fitted to the outdated scale is incorrect both means, and the accuracy panel won’t let you know which means it went. Detectors have a box-score threshold with a precision-recall curve behind it. Whether or not any of those strikes so far as mine did is an open query in every case — value a measurement, not an assumption. The one place this text doesn’t attain is pure retrieval with nothing to just accept or reject: there the ache is reshuffled neighbours, and no threshold dies as a result of there was by no means one to die.
Which brings us again to the depend. Each panel that got here out inexperienced on this experiment was threshold-free, and each panel that may have caught the failure was absent from the gate — the identical absence the ten paperwork share. Including a fifth inexperienced panel wouldn’t have helped, and neither would the compiler. The one factor that helps is placing FAR and FRR on the threshold τ into the gate. Here’s what it takes to learn them actually.
Including FAR and FRR at τ to the gate
4 strains: one names the working level, two learn the pair — as soon as on the threshold you inherited, as soon as on the threshold the brand new construct earns — and one ships the consequence. Solely the second studying blocks. None of it replaces something in your current gate; it sits subsequent to the accuracy delta.
-
Title the working level the construct is promising — a goal false-accept charge, a confidence at which a human is pulled in, no matter your resolution rule is definitely for. Derive it from what every error route prices; mine is
FAR = 1e-3. -
Report FAR and FRR on the inherited τ — as a diagnostic, not a blocker. That is the pair the depend got here up brief by: it exhibits 104 false accepts towards fp32’s 30, and 745 false rejects towards 582, on a construct the accuracy delta waves by. Learn each halves — NIST calls for the identical [2], for a similar cause: techniques run at a set threshold, so each charges should be reported at that threshold. “That is hardly ever achieved — most reviews are involved solely with false negatives.” Don’t block on it, although. The outdated fixed just isn’t obliged to outlive a brand new construct, and blocking on its demise forbids quantization by definition.
-
Re-derive τ on the quantized mannequin, then gate on FAR and FRR on the new τ — this one blocks. That’s the promise the construct is definitely making, and the criterion is a comparability, not an absolute: fp32 standing at its personal τ towards the quantized construct standing at its personal τ, on the identical held-out pairs, and the construct blocks when both charge has moved additional than the price of that error route permits — the identical reckoning that produced step 1’s goal. An absolute charge can’t be the criterion on a pair price range like mine; the strategies appendix says why. Each halves once more, and right here they transfer in reverse instructions: re-deriving lower my false accepts 104 → 44 whereas elevating my false rejects 745 → 959. Standing every construct at its personal τ, that’s 30 towards 44 on one facet (skinny proof) and 582 towards 959 on the opposite, a far bigger margin. The restore is critical, not enough, and never free; the restrictions appendix carries the proof below every of these three, together with how a lot of the second margin rests on one identification.
-
Ship τ contained in the mannequin artifact, versioned with it — by no means as a world fixed in a config file that outlives the mannequin it was fitted to. “Recalibrate after quantization” is simply too slim a rule to outlive your subsequent pipeline change. The one value protecting is {that a} threshold is an output of a selected construct. Any course of that produces a brand new construct with out producing a brand new threshold is transport a quantity that refers to a mannequin which not exists.
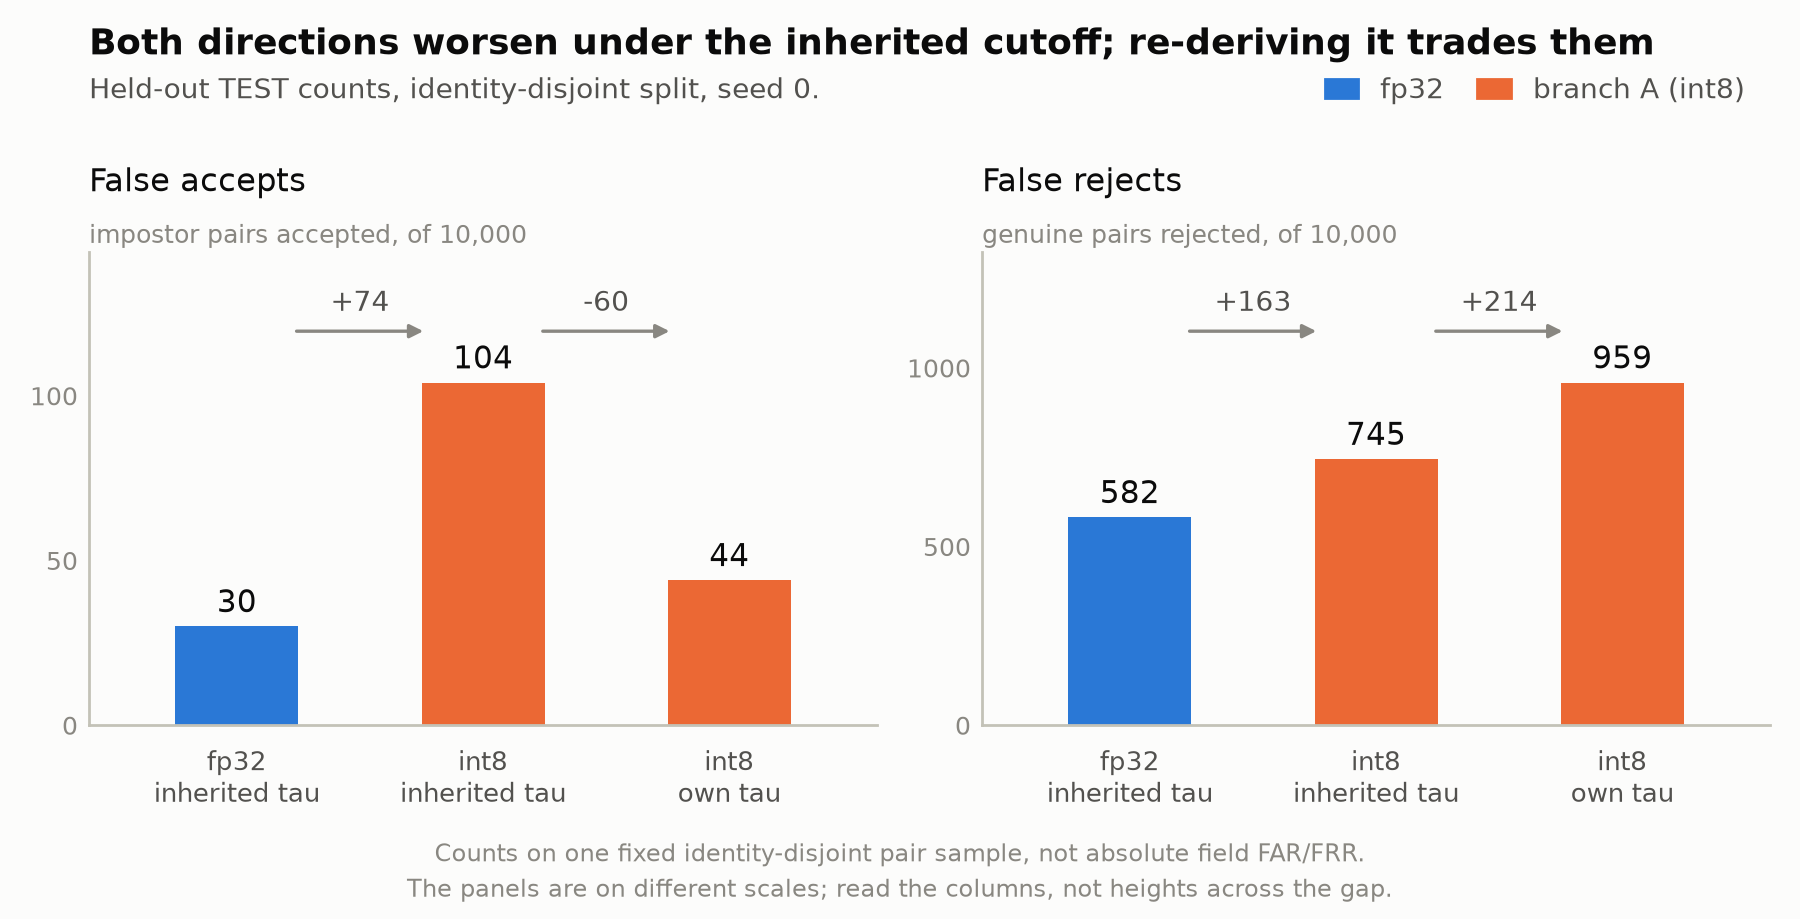
Two error instructions throughout three working factors. Held-out TEST counts on 10 000 real and 10 000 impostor pairs from an identity-disjoint seed-0 cut up. Below the inherited cutoff each instructions transfer the incorrect means without delay; re-deriving the cutoff on the int8 construct’s personal DEV impostors buys again 60 false accepts by spending 214 additional false rejects — the prescribed restore trades one route for the opposite, it doesn’t restore the fp32 working level. The panels are on totally different scales. Counts on one fastened pair pattern of 31 identities, not absolute area FAR/FRR.
Two additional strikes belong to different folks’s playbooks reasonably than my measurement: calibrating scores to possibilities so a cutoff degrades gracefully throughout mannequin swaps, and protecting thresholds in a checked-in file pinned to a mannequin revision with an alarm on gate-rate drift — normal apply within the retrieval playbooks cited earlier. And in case you are measuring FAR and FRR for the primary time, the strategies appendix carries the three traps that value me essentially the most: identity-disjoint splits, a pair price range counted in identities reasonably than pairs, and paired assessments as an alternative of variations of absolute charges.
The one half no one handed me is the anti-checklist — what does not depend as proof the choice rule survived:
-
TAR at a set FAR, taken from a report. The quantity re-derives the brink earlier than printing it; a deployed system doesn’t (see NIST above).
-
Prime-1, rank-1, precision@okay. Threshold-free by development. Wherever the cutoff went, these don’t look there.
-
Intrinsic dimensionality, distinction, or any international geometry examine. Threshold-free too, which is why all of mine stayed inexperienced.
-
“We re-derived τ on DEV.” The act just isn’t the consequence. The result’s FAR and FRR on held-out pairs at that τ.
-
“FAR dropped after we re-derived τ.” Towards the inherited quantity, sure. The identical act raised false rejects. Examine each side.
-
“We hit 1e-3.” Unanswerable on 31 identities — see the pair price range within the strategies appendix. Report counts and ratios as an alternative.
Again to the depend
Ten paperwork, one depend: not one quantity in any of their gates depends upon the place the choice threshold sits. Including extra accuracy panels doesn’t change that, and neither does reaching for the compiler. What adjustments it’s the pair the gate is lacking — false accepts and false rejects on the threshold your config truly holds, learn as soon as on the τ you inherited and as soon as on the τ the brand new construct earns. The road that decides whether or not the int8 construct ships stays one line. It simply has to hold two numbers an accuracy delta can’t stand in for.
Appendix 1: strategies
The physique numbers come from one encoder, one dataset cut up, and an identity-disjoint pair protocol. Dataset: LFW by way of fetch_lfw_people(min_faces_per_person=20, colour=True) — 3023 faces, 62 identities (verified towards that decision). A seed-0 permutation holds out 1024 pictures because the quantization calibration pool; the remaining 1999 are analysis. Mannequin: pretrained ArcFace w600k_r50.onnx, embeddings L2-normalised. Toolchain: Hailo DFC, in-net normalization1, calibset_size=256; the int8 figures are department A (full int8, no precision-mode overrides). Selective 16-bit scopes: B = fc1; C = fc1+batch_norm25; D = conv1; E = conv1+fc1.
Working level (held-out): identity-disjoint seed-0 cut up of the 62 analysis identities — 31 identities / 806 faces DEV, 31 / 1193 TEST; 10 000 real and 10 000 impostor pairs drawn independently in every half. Threshold τ = 0.259203 is the cutoff that leaves precisely 10 of the ten 000 fp32 DEV impostor pairs above it — the 1−1e-3 quantile of these scores, which is a rank on DEV and never a charge this knowledge might confirm. FAR/FRR and uncooked counts are reported on TEST, whose identities DEV by no means noticed. Paired discordance is learn off the identical TEST impostor pairs throughout units. Per-set DEV τ is reported solely as an illustration subsequent to a resampling baseline (±0.0167 at 95% half-width on the identical pair price range); it isn’t the first drift declare.
Three traps sit between “I measured FAR” and “I measured FAR credibly”, and they’re those that value me essentially the most rework. Break up by identification, not by picture: a threshold fitted and scored on the identical pairs is an in-sample quantity, and mine moved by ±0.017 below nothing however resampling. Depend your pair price range in identities: with Okay identities there are C(Okay,2) distinct {couples}, so even a run with zero false accepts helps solely a 95% higher sure of 3/C(Okay,2) — my 31 identities cap that at 0.0065, which is why no absolute FAR declare on this article stands by itself. Declare gaps with a paired check on the identical pairs — discordant counts, χ², and, the place pairs are impartial sufficient to hold one, a bootstrap interval on the delta — by no means because the distinction of two absolute charges. That interval is the one instrument right here I don’t use: resampling pairs treats 10 000 attracts from 31 identities as 10 000 observations, and would report a precision this price range has not acquired. The counts and χ² beside it are untouched by the identical clustering, as a result of they declare nothing past the fastened pair set they have been measured on.
χ² right here is McNemar’s: it’s learn off the discordant pairs alone — those the place the 2 builds disagree, since a pair each builds name the identical means says nothing in regards to the distinction between them — towards a null during which a flip is equally possible both means, so the expectation is a good cut up and the continuity-corrected statistic is roughly the squared variety of normal errors from it. The false-accept consequence’s 76-against-2 sits about eight of these out. That third entice is what separates my two surviving outcomes: the residual FAR hole after recalibration rests on 32 discordant pairs (23/9, χ² 5.3, a bit over two normal errors) — a margin of 14 pairs out of 10 000, which seven flipping again would erase — whereas the FRR value rests on 415 (396/19, χ² ≈ 341), a margin of 377. Identical bar, nothing like the identical footing.
Inexperienced rating / geometry figures (precision@10, rank-1, intrinsic dim, distinction, recall@10 vs fp32) nonetheless come from the sooner single-draw protocol on the total analysis set; they’re threshold-free by development and are usually not blended into the false-accept consequence.
The code behind each quantity above is the companion repository, maxeffectus/quantization-threshold-drift, MIT-licensed. The three held-out working factors will be rechecked with no Hailo licence: the derived embeddings ship as a checksummed Launch asset, and check_eval_release.py verifies the SHA-256 of every array earlier than it reprints the counts this appendix reviews; flip_identity_breakdown.py reproduces the genuine-pair flips identification by identification, and refuses to print a breakdown that doesn’t come to 396 towards 19. What doesn’t ship is the face crops, which the repository doesn’t redistribute, or the int8 rebuild, which wants the Hailo Dataflow Compiler. The launched embeddings are usually not MIT both — they’re biometric templates derived from the encoder weights, and inherit these weights’ non-commercial analysis phrases. The repository’s README states the protocol above and attracts these strains in full; this appendix doesn’t restate them.
Appendix 2: limitations
What follows is the listing of issues this measurement doesn’t set up. It’s longer than the listing of issues it does, which is the conventional ratio for a single-drop experiment, and a lot of the entries sure the numbers within the physique reasonably than threaten them.
Absolutely the error charges are the weakest numbers within the piece.
Ten thousand impostor pairs drawn from 31 identities are usually not ten thousand impartial observations: pairs sharing an identification share its idiosyncrasies, so the efficient pattern is nearer to the identification depend than to the pair depend. The consequence is concrete. With 31 identities there are 465 distinct identification {couples}, so an working level that produced zero false accepts throughout all of them would nonetheless solely assist a 95% higher sure of three/465 ≈ 0.0065 — above the 1e-3 the cutoff was fitted to. Any sentence of the shape “this construct misses 1e-3 in absolute phrases” is subsequently unsupported on this dataset, mine included. What survives is what’s conditioned on the fastened pair set: the uncooked counts, the relative ratios, and the paired discordance (76 pairs flipping reject→settle for towards 2 the opposite means). Learn the false-accept consequence as “×3.5 on the identical pairs”, by no means as “FAR is 0.0104 within the area”.
The goal itself is my selection.
FAR = 1e-3 is hardcoded in my analysis scripts as a result of I needed to decide one thing; it isn’t an business normal, not a product SLA, and never a quantity anyone handed me. An actual working level is derived from the price of every error route. Every thing within the physique is a press release about how a cutoff fitted to at least one goal behaves below quantization, not an argument for that concentrate on.
The edge shift is an illustration, not proof.
Resampling the analysis pairs strikes the fp32 threshold by ±0.017 at 95% half-width. The cosine hole that may restore the fitted FAR on the int8 DEV pool is about +0.025 — barely 1.5× that noise (the in-sample shift of +0.032 I measured earlier fares no higher, at ~1.9×). Below my very own bar that may be a flag, not a discovering, which is why it doesn’t seem within the physique. The drift declare rests on held-out false-accept counts, and nothing else.
One drop of 1 mannequin on one dataset with one toolchain.
No repeated identification splits, no second encoder, no second compiler, no second process. Each halves of the operating-point protocol come from a single seed-0 identification cut up; an identity-level bootstrap over splits is what would put a defensible interval on any of those numbers, and it isn’t one thing I ran. The map of neighbouring domains close to the tip of the article is explicitly a set of hypotheses, and the magnitudes within the physique shouldn’t be carried into any of them.
LFW is a saturated benchmark, and that cuts each methods.
Anybody who works in face recognition will be aware that I measured on a dataset the sphere considers solved. The structural declare doesn’t rely upon the accuracy panels staying inexperienced — a threshold-free quantity tells you nothing about the place the working level went, whether or not it strikes or not — however the demonstration does, and on a more durable benchmark the accuracy delta might need been massive sufficient to cease this construct for the incorrect cause. What saturation buys is the regime that issues: a verification encoder is chosen exactly as a result of it sits close to the ceiling on metrics of that sort, so “accuracy seems nice” is the conventional studying there reasonably than a fortunate one. What it doesn’t purchase is demographic protection. The identical NIST report I quote on fastened thresholds is the one which paperwork how far false-match charges fluctuate throughout demographic teams; 31 LFW identities can’t converse to that, and nothing right here claims the drift I measured is uniform throughout the folks a deployed system would truly see.
The calibration knowledge was pleasant.
These 1024 calibration pictures come from the identical LFW pool because the analysis pictures, so the int8 drop noticed in-distribution knowledge when the compiler set its activation ranges. Actual pipelines calibrate on no matter pictures are handy. My drift is a pleasant case, not a worst case. Relatedly, how many pictures the compiler makes use of is a separate entice — error versus set measurement is U-shaped — and I fastened calibset_size reasonably than sweeping it. The failure mode here’s a resolution threshold left untuned, not an undersized calibration set.
The inexperienced panels come from a unique protocol.
Precision@10, rank-1, recall@10 towards fp32, intrinsic dimensionality and distinction have been computed below the sooner single-draw protocol on the total analysis set, earlier than the identity-disjoint cut up existed. They’re threshold-free by development, which is precisely the purpose being made about them, so the looser protocol prices the argument nothing — however they aren’t drawn from the identical pairs because the FAR figures and shouldn’t be arithmetically mixed with them.
The 16-bit null is a null about this drop.
4 precision-mode scopes left the false-accept depend the place full int8 put it. That refutes “attain for the compiler knob and the working level survives” on this encoder. It says nothing about whether or not selective 16-bit helps elsewhere, and answering that wants a factorial experiment I intentionally didn’t run.
The restore is measured, and it’s neither enough nor free.
Re-deriving the cutoff on the quantized mannequin — the repair the article prescribes — cuts false accepts roughly in half towards the inherited quantity, so the compatibility gate actually is blind to work the restore already does. However the residual hole to fp32 remains to be there: 44 towards 30 on the identical pairs, and whereas a paired check does resolve it, it barely does (χ² 5.3 towards the false-accept consequence’s 68). Deal with the residual as detectable on skinny proof — an order weaker in assist than the compatibility failure, which is a press release about how nicely the hole is established and never about how massive it’s. It’s definitely not “half once more worse”.
The price of the restore sits on the opposite facet of the choice.
On the identical promised working level the int8 construct rejects real pairs 1.6× extra usually (396 flips okay→error towards 19 again, χ² ≈ 341), and that carries a warning for anybody who implements the repair — a gate watching solely false accepts will name the recalibration a hit and by no means discover that professional customers began getting turned away. The identification clustering above applies to this facet too, and extra closely: the identification contributing 79% of the real pairs holds 80% of the flips, so 4 fifths of that χ² is one individual, and the depend is a property of this pair set, not a area charge. It does survive the individual, although. On the 2085 real pairs from the opposite 30 identities the flips run 79 towards 11 (χ² ≈ 50): the identical route, nonetheless nowhere close to a good cut up. Neither is the associated fee a handful of unfortunate faces: the most important identification flips at 4.01% towards a pooled 3.96%, precisely its share, and 13 of the 31 check identities produced no flip in any respect, so the speed just isn’t uniform both. What the breakdown guidelines out is the studying that one or two faces carry the associated fee.
The 377 further rejections cut up, and the cut up is the value of the restore.
On the inherited τ the int8 construct already rejected 745 real pairs towards fp32’s 582, so 163 of the additional rejections are the quantized scores alone, and the opposite 214 are what elevating τ far sufficient to chop false accepts prices. Recalibration buys again 60 false accepts at that value.
Appendix 3: information survey (acceptance gate and “threshold”)
Bounded declare for the opener and the scoping paragraph: ten paperwork from 9 sources, those a practitioner is prone to open whereas transport an int8 drop — the Hailo DFC Consumer Information counted at 3.27 and at 3.30, as a result of the gate line survived the model bump unchanged, plus the eight additional sources beneath. That’s one shelf, and intentionally so: toolchain and edge-deployment documentation. Product-QA manuals and biometric certification protocols are a unique shelf, not sampled right here, which is similar distinction the physique attracts when it says who the article just isn’t addressed to.
Inside the shelf the ten cut up 3 ways. Two title a numeric accuracy bar (EdgeGate, oneuptime). 5 say to check accuracy towards fp32 with out naming a quantity (each DFC sections, the Hailo accuracy-degradation thread, TensorRT, the PTQ information). Three are remediation solely (Hailo Quantization Scheme, the YOLO recall thread, PyTorch accuracy debugging). Not one of the three genres treats re-deriving a verification working level as a part of the quantization acceptance gate. If a counterexample seems, it belongs on this desk — it will sharpen the piece, not collapse it.
|
Supply |
Said acceptance / high quality gate |
The place “threshold” (or equal) seems |
|---|---|---|
|
Hailo DFC Consumer Information 3.27 and three.30 |
Accuracy of the quantized mannequin vs the unique; layer evaluation and optimization ranges because the remediation path |
|
|
Repair under-representation / degradation by way of 16-bit on delicate layers, richer calibration, and so on. |
Layer precision recommendation; no verification τ |
|
|
Evaluate unique and compressed outputs to floor fact with task-specific postprocessing and metric |
Metric left unspecified; silent on fixed-τ vs TAR@FAR |
|
|
Restore recall after compile |
|
|
|
Restore accuracy after PTQ (SQNR / per-layer sensitivity) |
No decision-rule / operating-point gate |
|
|
Appropriate quantized inference; accuracy vs FP32 as the sensible examine |
No verification operating-point recalibration |
|
|
Specific gate desk: latency, reminiscence, accuracy delta INT8 ≥ FP32 − 1%, output variance |
“Threshold” = gate threshold on these metrics; not a similarity cutoff |
|
|
Favor QAT if PTQ loses greater than ~1% accuracy |
No operating-point recalibration step |
|
|
Evaluate top-1 / top-5 to the FP32 baseline |
No operating-point recalibration step |
References
[1] G. Xia, S. Ha, T. Azevedo, P. Maji, An Underexplored Dilemma between Confidence and Calibration in Quantized Neural Networks (2021), arXiv:2111.08163
[2] P. Grother, M. Ngan, Okay. Hanaoka, Face Recognition Vendor Take a look at (FRVT) Half 3: Demographic Results (2019), NISTIR 8280, Nationwide Institute of Requirements and Know-how
[3] H. Wu, P. Judd, X. Zhang, M. Isaev, P. Micikevicius, Integer Quantization for Deep Studying Inference: Rules and Empirical Analysis (2020), arXiv:2004.09602
[4] A. Bouguerra, D. Montoya, A. Gomez-Villa, C. Mraidha, F. Arnez, Much less Exact Can Be Extra Dependable: A Systematic Analysis of Quantization’s Affect on VLMs Past Accuracy (2025), arXiv:2509.21173