

Your coding assistant tells you each check handed. The construct is inexperienced, so that you merge the PR and get again to your backlog.
Three weeks later, a difficulty rolls in. The agent is not round to assist. Possibly your API quota is gone, otherwise you’re caught on a commuter practice with zero bars. The code belongs to you now, and one thing is damaged.
Are you able to truly repair it?
That is the true drawback driving this challenge, and it comes all the way down to sensible possession. On paper, your identify is on the commit. In observe, you solely personal that code if you happen to can hint its logic and patch it fully unaided. Inexperienced assessments solely show that software program works on a very good day. They do not show you perceive it. (To be clear, that is strictly about upkeep. Licenses and copyright usually are not the problem right here.)
I constructed CodeOwnership to check that actual blind spot. It is a light-weight pilot designed to reply one query: does a developer truly perceive the code an AI wrote for them?
How the Loop Works
-
An AI agent writes a function.
-
I write down an sincere score of how effectively I feel I perceive it.
-
A second agent slips in a single, pre-registered bug.
-
I open an incident report with all AI instruments turned off and attempt to monitor down the defect.
What Ships in V0.1
The utility itself is completed. Here’s what is bundled within the repository:
-
A locked spec and static scaffold, secured with hashes so the principles cannot shift mid-run.
-
11 seen assessments alongside 13 hidden acceptance assessments.
-
A mutation spec, paired with a blind verification test that confirms a bug exists with out gifting away its location.
-
A guided CLI command that steps you thru the workflow and saves your state.
-
A report software that intentionally refuses to mash metrics right into a single, meaningless rating.
-
72 inner self-tests to confirm the harness itself.
The harness is completed. My first check run with it’s a separate matter solely.
The First Run
I will be blunt about what occurred after I tried it. I hit a wall, stopped the timer at 8 minutes and 12 seconds, and nonetheless hadn’t discovered the bug.
This is only one developer on a single run, so it does not function a sweeping benchmark for the entire business. However it exhibits how the harness features, the place issues collapse, and what a sensible check for code comprehension seems to be like.
Shifting ahead, I am going to break down the structure, the uncooked numbers, the place I tousled, and the analysis behind why this issues. By the tip, you’ll be able to run the very same diagnostic by yourself AI-assisted initiatives.
Abstract: CodeOwnership evaluates true AI code possession by separating confidence, unaided debugging, and comprehension relatively than collapsing them into one metric.
In my preliminary run, I rated my confidence a 4/5, then stalled out after 8 minutes and 12 seconds with out finding the injected bug. (For the file, it took me about half-hour in a subsequent session to truly monitor it down, although the script nonetheless logged a NOT FIXED standing as a result of I hadn’t utilized a repair.)
What Does CodeOwnership Truly Measure?
By possession, I do not imply something authorized. I imply with the ability to clarify the code and repair it when one thing goes fallacious, even when the agent that wrote it is not accessible. However there’s one other half to this. I would assume I perceive the code and discover out in any other case when I’ve to debug it myself.
That’s the reason CodeOwnership tracks three issues.
-
Perceived understanding. Earlier than debugging begins, I fee my understanding of the code from 1 to five.
-
Debugging efficiency. I get an incident report and as much as 60 minutes to seek out and repair the defect with out the coding agent.
-
Publish-debugging comprehension. As soon as the debugging session is over, I reply 4 questions on how the code works.
I report these individually. A single possession rating is likely to be simpler to learn, however it could pass over the distinction between how effectively I feel I do know the code and what occurs when I’ve to work on it myself.
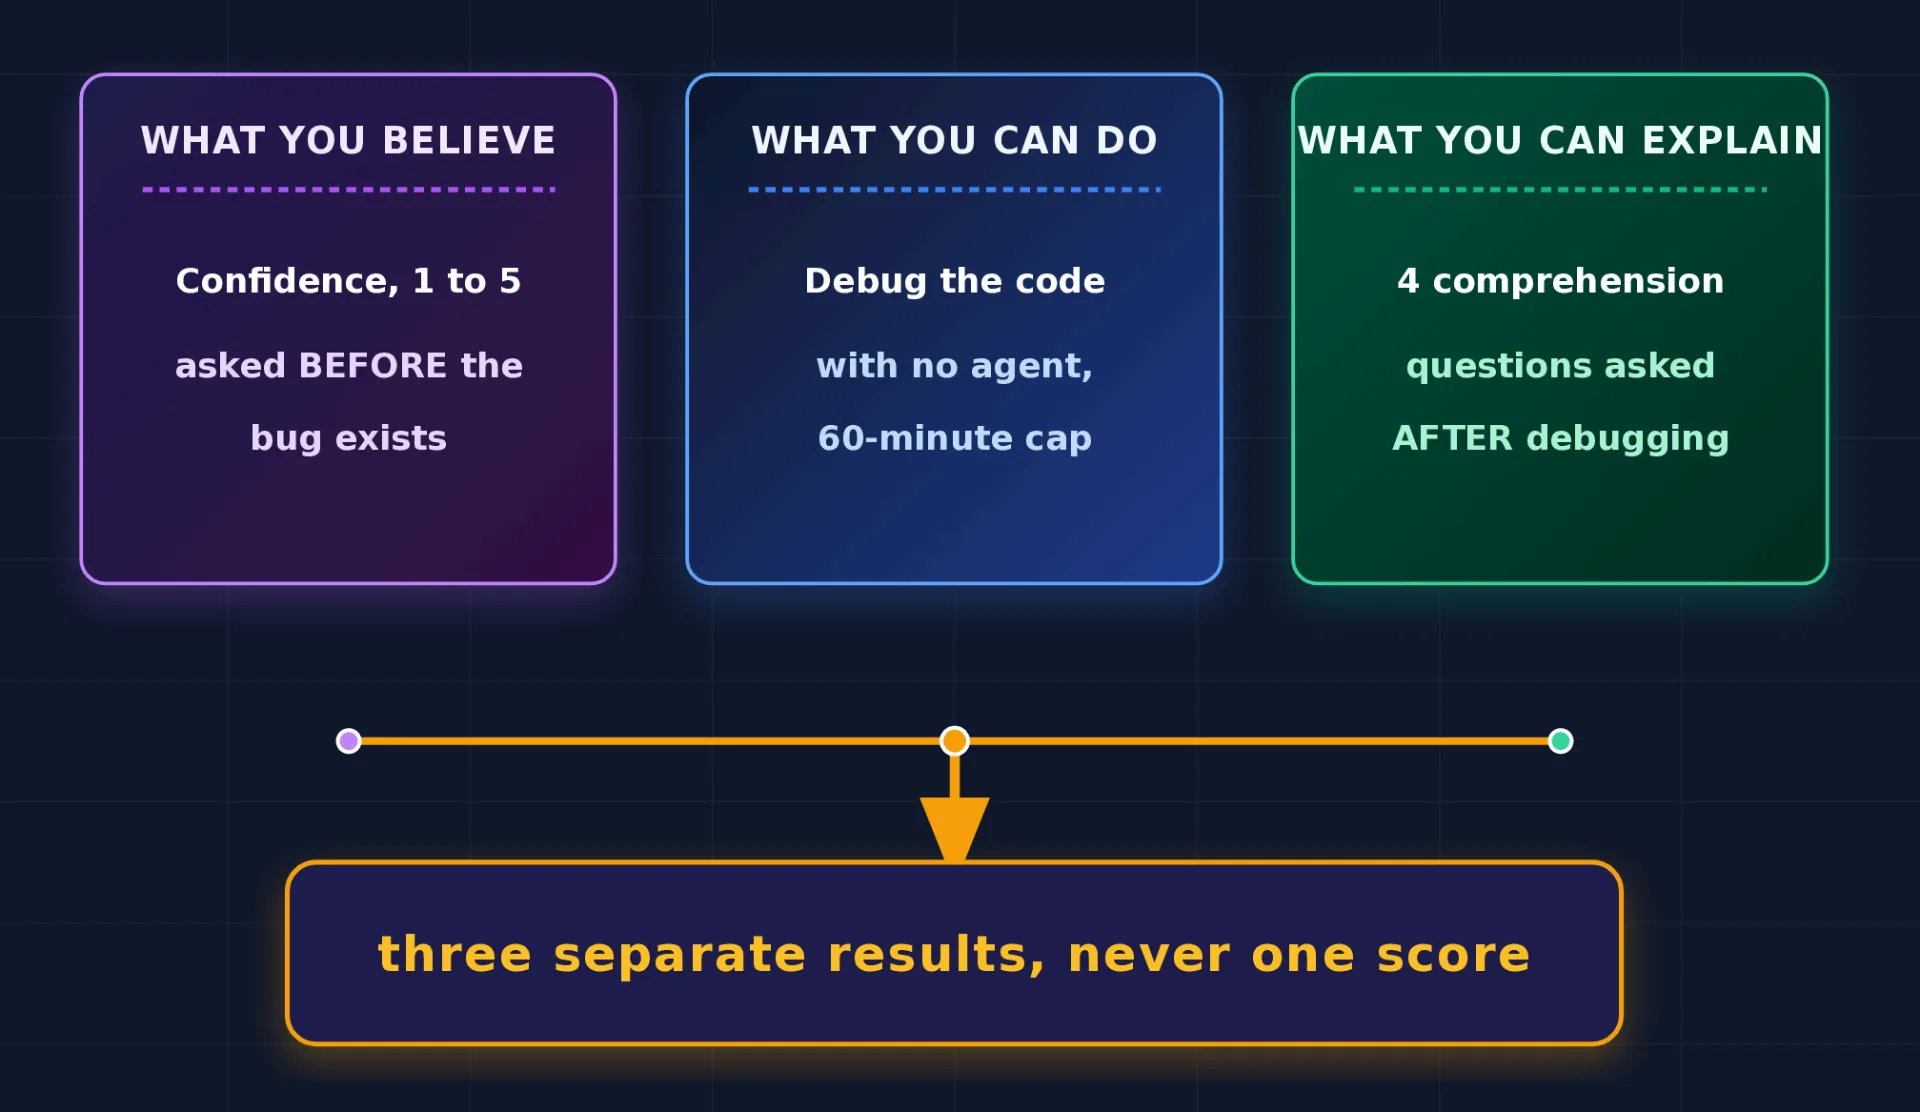
Visible Overview:
A high-contrast visible diagram explaining the core framework of CodeOwnership in AI-assisted software program improvement. The chart breaks down analysis into three distinct, color-coded diagnostic pillars earlier than becoming a member of them right into a unified rule on the backside.
Column 1 — What You Consider (Perceived Understanding):
Header: WHAT YOU BELIEVE
Particulars: Measures confidence on a 1 to five scale, recorded earlier than any bug or system defect is launched. Focuses on developer self-assessment and subjective certainty.
Column 2 — What You Can Do (Debugging Efficiency):
Header: WHAT YOU CAN DO
Particulars: Direct sensible analysis requiring the developer to debug and repair actual code defects with out AI agent help, beneath a strict 60-minute time cap.
Column 3 — What You Can Clarify (Publish-Debugging Comprehension):
Header: WHAT YOU CAN EXPLAIN
Particulars: Evaluates post-incident data utilizing 4 focused comprehension questions answered after the debugging process to confirm true architectural understanding.
Circulate & Conclusion:
Connecting pipeline traces descend from every of the three pillars and converge right into a central junction arrow pointing towards a highlighted takeaway field on the backside.
Core Takeaway: “three separate outcomes, by no means one rating” — emphasizing that combining these metrics hides the essential hole between developer confidence and precise ability.
Take into consideration a driver who at all times depends solely on GPS. Ask them, “Have you learnt the way in which dwelling?” and they’re going to say sure. Then change off the cellphone. Solely now do you study the true reply.
CodeOwnership switches off the cellphone.
The duty I selected
I went with a notes library that helps folders. Nothing difficult on the floor. You possibly can create and retrieve notes, create and delete folders, transfer notes between folders, and checklist the notes inside a folder. The identical word can sit in a number of folders.
Deleting a folder is the place issues get attention-grabbing. The notes should stay. Solely the hyperlinks between these notes and the deleted folder ought to go away. That is the rule I needed the bug to interrupt.
I selected this function as a result of it’s sufficiently small to learn in round ten minutes. There’s additionally a particular behaviour to test, so I can inform whether or not the bug has been mounted as an alternative of relying alone judgement.
The agent will get a hard and fast scaffold and a public interface. It writes the implementation behind them. I test its work with two check teams earlier than introducing the bug:
-
11 seen assessments. These can be found to the agent throughout improvement.
-
13 hidden acceptance assessments. The agent can’t examine these. I run them earlier than planting the bug to test that the unique implementation works.
I wrote the harness utilizing Python’s built-in unittest module (Python documentation). It wants no third-party packages.
Full code: https://github.com/Emmimal/codeownership/
How Does CodeOwnership Preserve the Check Sincere?
I had to think twice concerning the guidelines earlier than operating this experiment. I constructed the software, selected the duty, and ran the check myself. That leaves room for bias, even when I do not intend to affect the end result.
I added checks to the harness to cut back that threat. The concept is to set the principles earlier than the run, hold the bug hidden, and let the assessments report what occurred relatively than rely alone judgement.
Right here is how a run works.
Rule 1: Freeze the principles first
Earlier than I ran the pilot, I hashed the benchmark information and saved the hashes in FROZEN_SHA256.txt. I dedicated the information and tagged that commit v0.1-frozen.
The pilot checks these hashes earlier than it begins. If a frozen file has modified, it refuses to run.
I did this as a result of I did not need to change the principles midway by the experiment, even accidentally. Since I constructed the software and I am the individual being examined, I want a approach to test that the setup hasn’t modified after seeing the outcomes.
That is just like pre-registration in analysis. Researchers file their plans earlier than accumulating or analysing knowledge, making it tougher to vary the story afterwards. Nosek and colleagues talk about this of their paper on bettering the credibility of scientific analysis (learn the paper). I utilized the identical thought to this pilot.
Rule 2: Break the code with a second agent
I did not need to plant the bug myself. If I wrote it, I would keep in mind the place I put it, which might make the debugging check unfair. As a substitute, I used a second agent to make a change primarily based on a rule I had written down earlier than the run.
The rule was:
When a word loses its remaining folder membership as a consequence of deleting a folder, the word is incorrectly faraway from the word retailer. Eradicating a membership by
remove_note_from_foldershould not be modified by this mutation. Notes with remaining folder memberships should not be eliminated by this mutation.
I do know what the bug does, however I do not know the place the agent made the change. That distinction issues. If I knew the situation, I may go straight to it as an alternative of investigating the code.
This a part of the setup borrows from mutation testing. In a 1978 paper, DeMillo, Lipton and Sayward described making small adjustments to a program, referred to as mutants, to see whether or not a check suite may detect them (learn the paper). I am utilizing an analogous thought, however the individual being examined is the developer. Slightly than checking whether or not a check suite catches the fault, I need to see whether or not I can discover and restore it myself.
Rule 3: Management what I’m allowed to see
I additionally had to verify I could not by chance give myself clues through the debugging session. I added just a few restrictions to the harness.
-
The working copy is exported outdoors the repository. It incorporates no Git historical past, specification, hidden assessments, or scoring rubric.
-
The mutation test returns solely a verdict. The detailed outcomes keep in a sealed log till I’ve dedicated my written rationalization.
-
There aren’t any retries. If the baseline fails, the mutation can’t be verified, or the harness refuses to open the debugging view, the pilot stops. I file the failure as an alternative of beginning over.
-
I commit my confidence score earlier than the bug is launched. My rationalization should even be dedicated earlier than any rating is proven.
I wrote 72 self-test checks to verify these restrictions truly work. They cowl circumstances comparable to Home windows line-ending variations and whether or not the required commits occur within the appropriate order.
These checks do not show that the experiment is free from bias. They assist catch particular methods the method may go fallacious, together with methods I would unintentionally see info I am not presupposed to have.
What Occurred After I Ran CodeOwnership?
Right here is how my first run went, from the preliminary implementation to the purpose the place I finished debugging.
First, I obtained the function from ChatGPT. I used the free account, with the mannequin set to Auto and Momentary Chat enabled. ChatGPT could not entry my native information, so I uploaded the scaffold as a ZIP. It returned the implementation, and I copied the 4 supply information into the working folder with out altering them. I used the unique AGENT_PROMPT.md with out enhancing the immediate.
The assessments handed. All 11 seen assessments handed, adopted by all 13 hidden acceptance assessments. The harness printed BASELINE PASSED. At this level, the function was working as anticipated.
I gave myself a confidence score. After studying the code, I rated my understanding at 4 out of 5. The query requested how assured I used to be that I may modify the implementation if one thing broke. I dedicated the score to Git earlier than the mutation was launched.
Then a second agent planted the bug. A recent Claude sub-session utilized the mutation from the specification alone. I noticed no code adjustments. The harness checked the end result and printed MUTATION VERIFIED.
Lastly, I began debugging. I opened the incident report and labored with out AI or outdoors assist. The timer began at 12:45:40.
Eight minutes and twelve seconds later, I finished. I hadn’t discovered the defect.
I used to be drained and annoyed by the setup issues I might handled earlier that day. I made a decision I had had sufficient and ended the session.
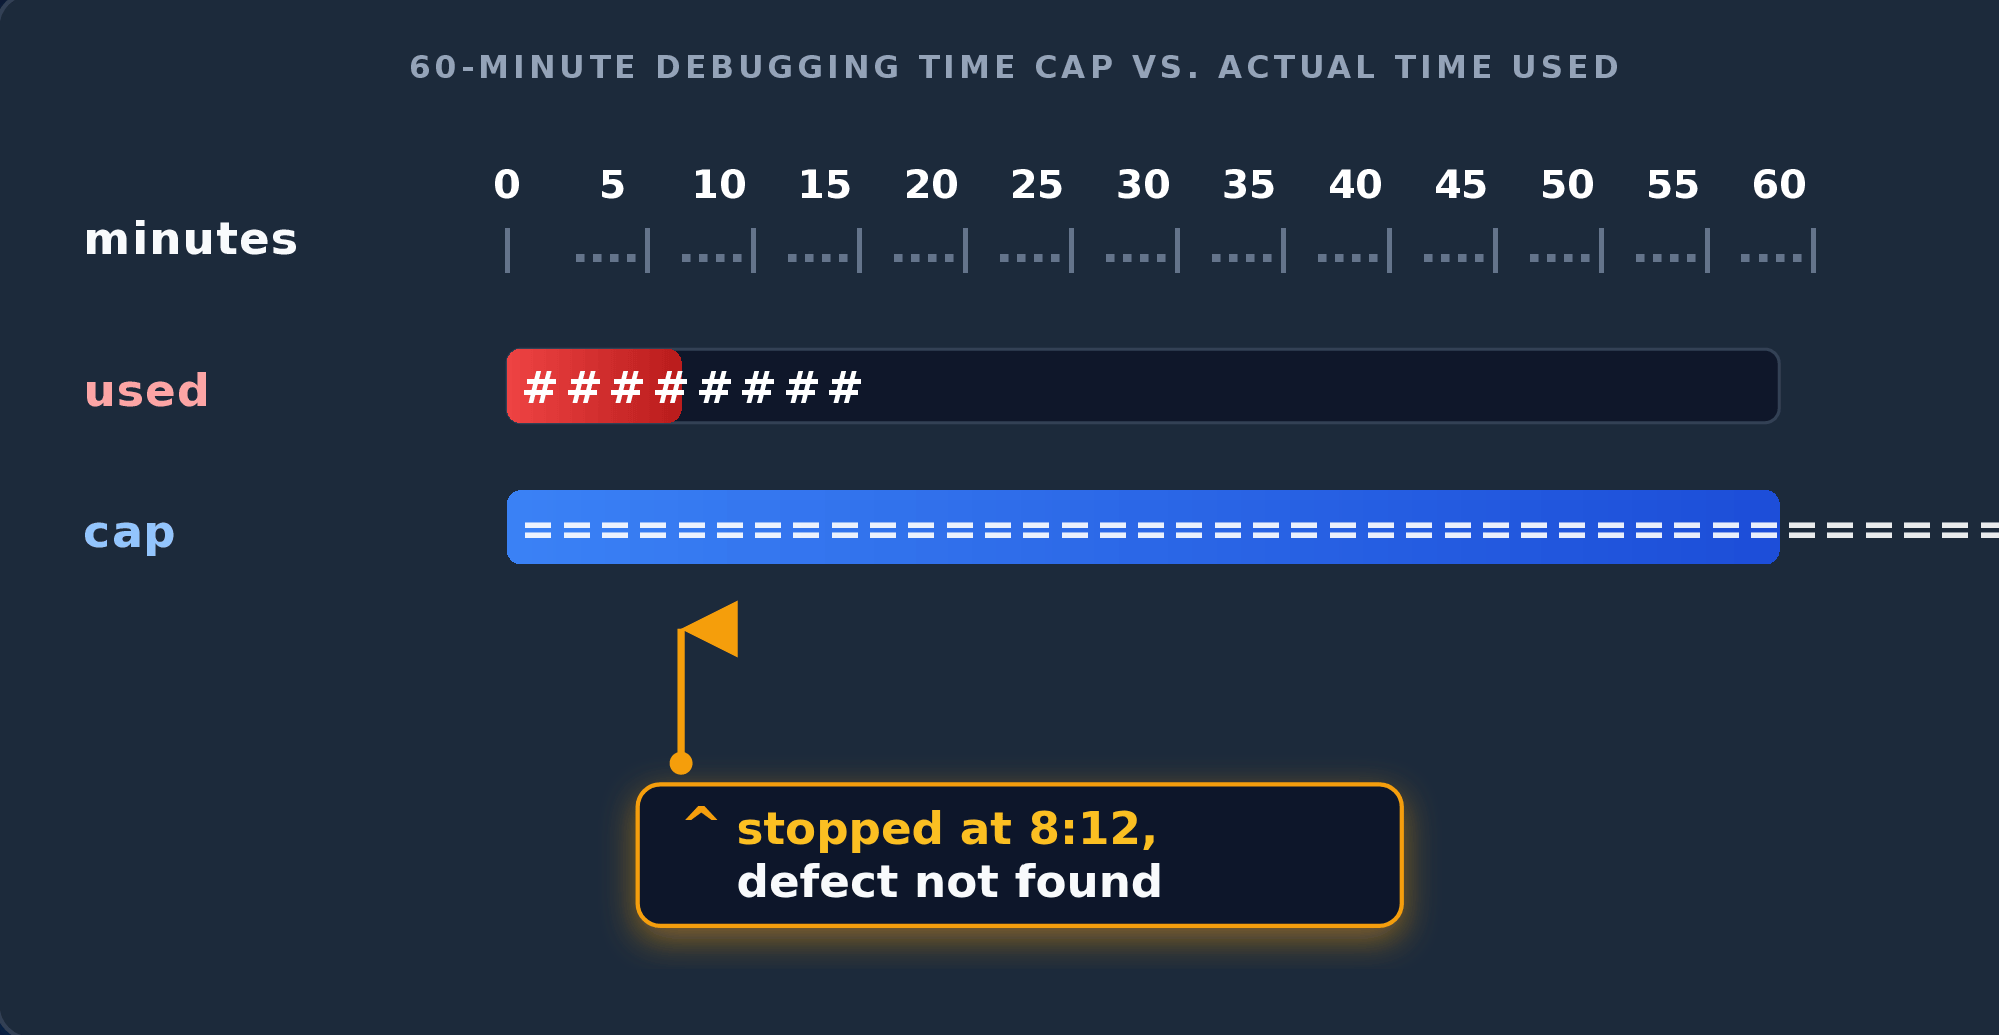
Visible Overview:
A high-contrast timeline chart illustrating the time monitoring log from a CodeOwnership empirical experiment carried out on October 12, 2026. The graphic visualizes developer debugging efficiency beneath time constraints when working with out AI agent help.
Timeline Scale (0 to 60 Minutes):
High axis formatted with ASCII-style tick marks spanning from 0 to 60 minutes in 5-minute increments.
Used Bar (Precise Session Length):
Label: used
Visible: A highlighted pink progress bar extending to roughly 8.2 minutes (represented by ########), monitoring the precise time spent earlier than ending the session.
Cap Bar (Most Allowed Restrict):
Label: cap
Visible: A full-width blue bar extending throughout all the 60-minute ceiling (represented by ====================), representing the experiment’s arduous cutoff restrict.
Session Termination Marker:
Pointer & Field: An highlighted amber indicator arrow factors instantly on the 8:12 mark on the timeline.
Annotation Textual content: “^ stopped at 8:12, defect not discovered” — recording that the debugging try was deserted early attributable to developer fatigue and setup friction relatively than reaching the utmost time cap.
The harness supplied solely two decisions: mounted or cap. I chosen mounted to advance the workflow, despite the fact that I had not repaired the code. That was my enter to the software, not a verified end result. The target test subsequently ran in opposition to my unchanged implementation and returned NOT FIXED. The three failed hidden assessments confirmed that the planted defect remained.
The following morning, I wrote up what had occurred and dedicated my rationalization earlier than the software confirmed me any scores. I recorded that I hadn’t discovered the defect through the timed session, however discovered it on a later try, roughly half-hour in.
The target test informed a unique a part of the story. It ran in opposition to my code and returned NOT FIXED. All 11 seen assessments handed, however 3 of the 13 hidden acceptance assessments failed. The planted bug was nonetheless there, and I hadn’t modified any information.
So there isn’t a verified repair to report. The test additionally can’t affirm my account of discovering the bug later, as a result of I hadn’t utilized a restore when the test ran.
I did not full the 4 comprehension questions both. With out these solutions, the software could not end that a part of the evaluation. The generated report is marked INCOMPLETE, and that is the model I am publishing.
|
Measurement |
What I recorded |
Standing |
|---|---|---|
|
Baseline |
11 of 11 seen, 13 of 13 hidden assessments handed |
Full |
|
Perceived understanding |
4 out of 5, dedicated earlier than the mutation |
Full |
|
Mutation |
Verified by a public-behavior test, verdict solely |
Full |
|
Debugging |
Stopped at 8:12, defect not discovered |
Incomplete |
|
Written rationalization |
Dedicated the following morning. It says I didn’t discover the bug within the timed session and located it on a later try (self-reported) |
Full |
|
Goal repair test |
NOT FIXED: 11 of 11 seen assessments handed, 10 of 13 hidden assessments handed, planted habits nonetheless current |
Full |
|
Comprehension, Q1 to This fall |
Not scored |
Not run |
What this does and doesn’t present
I finished after 8 minutes and 12 seconds. The time restrict was 60 minutes, so I can not say what would have occurred if I might saved going. I selected to cease, and that’s the place the timed session ended.
Earlier than the bug was launched, all 24 assessments had handed. I might additionally rated my confidence at 4 out of 5. However after I needed to examine the planted defect, I could not discover it throughout these eight minutes.
I am not treating that as proof that I could not repair the code. I did not use the complete time allowed, and I by no means accomplished the restore. What I can say is that my confidence score didn’t inform me how I’d carry out after I needed to debug the code myself.
I nonetheless do not know whether or not I may have accomplished the restore throughout the unique 60-minute session. This run does not reply that query.
What was the planted bug?
After my rationalization was dedicated, the change was proven to me. It was two added traces in delete_folder.
The code removes a word from the shop when its final folder membership disappears. That’s the bug. Deleting a folder ought to depart the word alone.
A word in two folders survives as a result of one membership stays. A word in only one folder will get deleted together with its folder. The remove_note_from_folder perform was left untouched.
I did not spot these two traces throughout my timed try. them now, the situation appears affordable at first look. The checklist is empty, so the code deletes the word. However an empty checklist solely tells us that the word has no folder memberships. It doesn’t suggest the word ought to now not exist.
The hidden-test report confirmed three failures out of 13. I haven’t got the names of these assessments, so I can not say precisely which circumstances caught the bug. All 11 seen assessments handed.
One query would have helped me examine: the place on this software is a word truly presupposed to be deleted? I hadn’t thought to hint that duty throughout my first try. The mutation put the deletion in a perform that ought to solely take away folder memberships.
The setup issues have been actual findings too
Truthfully, getting the experiment prepared took most of my day. The debugging half was over in 8 minutes and 12 seconds. Getting all the things to that time was the tougher half.
-
Gemini CLI: I put in it, however could not get the personal-account login to work. Google had modified its sign-in preparations on 18 June 2026, transferring customers in direction of Antigravity (Google’s discover). I misplaced time right here earlier than I may even use the software.
-
ChatGPT and native information: ChatGPT couldn’t open my challenge folder, so I zipped the scaffold and uploaded it. I then copied the 4 supply information it returned into the working folder. That labored, however it’s not the unique plan of an agent working contained in the folder.
-
Git on Home windows: Line endings induced hassle, and so did switching between PowerShell and Command Immediate. Operating
git add -Ainside a folder that sits in one other repository can stage the mother or father’s information, so I added a warning for that to the harness.
None of this proves something about code possession. These have been issues I bumped into whereas constructing and operating the software. However they clarify why the setup took so lengthy, and why I added among the checks that are actually within the repository.
Why Does Code Possession Matter When AI Writes the Code?
My pilot concerned one developer, one process, and one debugging try that I finished early. It could possibly’t inform me whether or not individuals who use AI perceive their code much less effectively.
What it did make me take into consideration is the hole between confidence and with the ability to repair one thing. I rated my understanding at 4 out of 5, however I did not discover the planted bug throughout my timed session. I can not say what one other developer would have executed, and even what I’d have executed with extra time.
There’s already analysis on how AI impacts programming productiveness, studying, and folks’s reliance on automated instruments. I am going to take a look at a few of that work right here. It supplies context for the query I needed to check, but it surely does not validate CodeOwnership or show something from my pilot.
Feeling productive isn’t the identical as being productive
One examine that caught my consideration was printed by METR in July 2025. They requested 16 skilled open-source builders to work on 246 actual points in their very own repositories. The builders may use AI instruments. They ended up taking 19% longer to complete the work.
What makes this end result attention-grabbing to me is what the builders anticipated. Earlier than the examine, they thought AI would make them 24% sooner. After the experiment, they nonetheless believed it had made them 20% sooner. (METR’s examine)
The researchers measured completion time, not how effectively the builders understood their code. I do not need to stretch the discovering past that. Nonetheless, the distinction between what folks anticipated and what the researchers measured is value serious about.
METR now labels these outcomes outdated. A follow-up it started in August 2025 was judged unreliable, and METR says it’s redesigning the experiment (METR, February 2026). I deal with these numbers because of this from that one experiment, not a prediction about as we speak’s instruments.
That is one motive I recorded my confidence score earlier than debugging. I needed to match what I believed I may do with what occurred after I truly tried.
Utilizing AI can scale back what you study
Anthropic printed one other examine in January 2026. It concerned 52 engineers, principally junior builders, who have been studying a Python library referred to as Trio. Some used AI help whereas finishing coding duties; others wrote the code by hand. Everybody took a quiz afterwards.
The AI-assisted group scored 50% on common. The hand-coding group scored 67%, a niche the authors report as statistically vital. The AI group completed about two minutes sooner, however that point distinction was not statistically vital. (Learn Anthropic’s examine)
I discover the quiz outcomes extra related to my query than the time distinction. However there’s a restrict to that comparability. Studying an unfamiliar library isn’t the identical as sustaining a function that an AI agent has written for you.
The examine additionally discusses how folks use AI. Asking for explanations and following up with questions have been related to higher studying outcomes. So I would not take these outcomes to imply that AI prevents folks from studying. The best way somebody makes use of it issues.
There’s one other level value disclosing: Anthropic makes Claude. I used Claude to construct the harness, to use the mutation, and to assist draft this text. That doesn’t invalidate the examine, however readers ought to know the connection.
Neither examine tells me whether or not I can keep the particular code in my repository. That is what I needed to research with CodeOwnership. My pilot is way smaller, and it can’t set up a common end result. It provides me a approach to study the query on a selected piece of code.
Automation takes away the observe you want most
In 1983, Lisanne Bainbridge wrote a paper referred to as “Ironies of Automation”. Her paper is about operators of commercial crops, however aviation exhibits the identical sample. When an autopilot flies the airplane in regular circumstances, the pilot will get much less observe. However when one thing uncommon occurs, the pilot nonetheless has to take over. That is when the dearth of observe can change into an issue.
One thing comparable can occur with software program. An agent writes the code, and I spend much less time studying it or working by bugs myself. If one thing breaks later, I can not at all times ask the agent to repair it. I’ll should determine it out alone.
Code is greater than textual content
In 1985, Peter Naur wrote “Programming as Concept Constructing”. He argued that programming is not nearly writing code. Programmers construct an understanding of how the software program works, and that understanding issues when they should change it.
I hold coming again to 1 query right here. If an agent writes the code and I approve it, how a lot of that understanding do I even have?
The place vibe coding matches
In February 2025, Andrej Karpathy described “vibe coding”. The concept was to just accept what the mannequin produces with out spending a lot time studying the adjustments. He wrote that it was “not too dangerous for throwaway weekend initiatives, however nonetheless fairly amusing.” I’m wondering what occurs when folks work that means on software program they should keep.
Assessments assist, however they do not cowl each doable state of affairs. A bug can present up in a case no person thought to check. At that time, passing assessments will not inform you learn how to repair it. You want to perceive the code.
That is the state of affairs I needed to look at with CodeOwnership.
What Are the Limitations of CodeOwnership V0.1?
My first run did not go the way in which I had deliberate. I need to clarify what occurred earlier than drawing any conclusions from it.
I examined the software on myself, with one process. I additionally designed the check, so there may be an apparent limitation from the beginning. I knew what the planted bug was presupposed to do. I simply did not know the place the defective code was. That’s totally different from being handed an actual bug with out realizing something about its trigger.
The debugging session had a 60-minute restrict. I finished at 8 minutes and 12 seconds. By then, I might already spent hours coping with setup issues, and I used to be bored with combating the entire thing. Possibly I’d have discovered the bug if I might continued. I can not say that I’d have, both.
I later discovered the trigger throughout one other try, however I didn’t time that session or confirm a repair, so I can’t rely it because of this. I by no means accomplished the 4 comprehension questions, so one of many three measurements is lacking.
I can also’t inform how a lot tiredness affected my efficiency. The setup issues have been actual, however that does not imply they clarify why I finished. The check provides me no approach to separate the 2.
The setup itself modified alongside the way in which. I had deliberate to let a coding agent work within the challenge folder and run the assessments. As a substitute, I uploaded the scaffold as a ZIP to a chat assistant, copied its returned information into the challenge, and ran the seen assessments myself. The mannequin setting was Auto, so I can not determine the precise mannequin model.
The instruments weren’t the identical at each stage, both. A Claude session helped with the harness and utilized the bug. One other software generated the implementation. I have not examined whether or not a unique mixture would change the end result, or how a lot the generated code impacts the issue of debugging it.
The hidden assessments and the scoring rubric are public within the repository. That was wanted to make the pilot reproducible. It additionally means a future runner who reads them has misplaced the blind check, and this pilot can’t present how a lot that issues.
The analysis I cite has its personal limits right here. METR measured how lengthy builders took to finish duties. Anthropic studied how folks realized a brand new Python library. Neither examined whether or not builders may restore code written by an AI agent.
So what did this primary run set up? I managed to run the instrument, however I did not full the evaluation or repair the planted bug through the timed session. One run by one developer can’t inform us whether or not AI adjustments debugging skill basically. It does present me what wants consideration earlier than I do this once more.
How Can You Run CodeOwnership on Your Personal AI-Generated Code?
You possibly can do this with out putting in my full harness. Decide a small piece of code an AI agent wrote for you and run a easy drill.
Don’t be concerned if the end result is not what you anticipated. That is the purpose of doing the drill. You may really feel assured and battle to seek out the bug. Otherwise you may repair it sooner than you thought you possibly can. A passing check suite will not inform you both of these issues.
If you wish to attempt the complete model, the repository incorporates the frozen spec, hidden assessments, a 72-check self-test, and a guided command. Begin right here:
On Home windows PowerShell, you should utilize a path comparable to C:co-workr1 for --work.
4 issues I took away from this
-
Fee your self earlier than you begin. As soon as you know the way the debugging session went, it is tougher to recollect how assured you have been beforehand.
-
Passing assessments is not the identical as with the ability to repair the code. The assessments might all go as we speak. That does not assure you may know what to do when a unique drawback seems.
-
Practise earlier than one thing breaks for actual. Pilots practice for emergencies. A brief debugging train provides you an opportunity to seek out gaps in your understanding earlier than you are coping with an precise failure.
-
Ask the agent to clarify its code. Within the Anthropic examine, individuals who requested for explanations or follow-up questions scored larger. The authors describe this as an affiliation, not a trigger. Having the agent do the work with out partaking with the reasoning might depart you with much less understanding.
What I’d change in V0.2
My first run uncovered just a few issues I want to repair earlier than asking different folks to do this.
-
Add a correct
gave upend result. The software ought to present the target test beside the person’s reply as an alternative of forcing a selection betweenmountedandcap. -
Run the debugging session after a break. I do not need hours of setup hassle affecting the following end in the identical means.
-
Use an agent that may work contained in the challenge folder and run the assessments itself. That was the unique plan, and I would like the following run to observe it.
-
Get different builders to attempt the identical course of. My result’s one individual’s expertise. I want extra runs earlier than I can say something about how effectively the instrument works for different folks.
Assets
-
Bainbridge, L. (1983). Ironies of automation. Automatica, 19(6), 775-779. https://doi.org/10.1016/0005-1098(83)90046-8
-
Naur, P. (1985). Programming as idea constructing. Microprocessing and Microprogramming, 15(5), 253-261. https://doi.org/10.1016/0165-6074(85)90032-8
-
DeMillo, R. A., Lipton, R. J., & Sayward, F. G. (1978). Hints on check knowledge choice: Assist for the practising programmer. Laptop, 11(4), 34-41. https://doi.org/10.1109/C-M.1978.218136
-
Nosek, B. A., Ebersole, C. R., DeHaven, A. C., & Mellor, D. T. (2018). The preregistration revolution. Proceedings of the Nationwide Academy of Sciences, 115(11), 2600-2606. https://doi.org/10.1073/pnas.1708274114
-
METR (2025, July 10). Measuring the affect of early-2025 AI on skilled open-source developer productiveness. https://metr.org/weblog/2025-07-10-early-2025-ai-experienced-os-dev-study/
-
METR (2026, February 24). We’re altering our developer productiveness experiment design. https://metr.org/weblog/2026-02-24-uplift-update/
-
Anthropic (2026, January 29). How AI help impacts the formation of coding abilities. https://www.anthropic.com/analysis/AI-assistance-coding-skills
-
Karpathy, A. (2025, February). Publish introducing “vibe coding”, on X. https://x.com/karpathy/standing/1886192184808149383
-
Google. Gemini Code Help for people: deprecation discover. https://builders.google.com/gemini-code-assist/docs/deprecations/code-assist-individuals
-
Python Software program Basis. unittest: Unit testing framework. https://docs.python.org/3/library/unittest.html
-
Alexander, E. P. (2026). CodeOwnership, V0.1 (pilot harness, spec and self-test). GitHub: https://github.com/Emmimal/codeownership/.
Disclosure
Instruments within the experiment. ChatGPT (mannequin set to “Auto”, free account, Momentary Chat) wrote the implementation. A recent Claude sub-session utilized the mutation. I additionally put in Gemini CLI, however its login now not works for private accounts, so it performed no half within the outcomes.
I designed the benchmark and I ran it myself. I didn’t obtain fee, credit, or early entry from any firm named right here. I used free tiers solely. The one knowledge is my single run. No different builders took half, and I don’t mix the outcomes into one rating.
All diagrams on this article, together with the featured picture, have been created by the creator. The featured picture was generated with Google Gemini.