Say a good friend tells you their canine’s title is Biscuit. Later, on the park, a stranger factors at a canine and asks if you recognize whose it’s. If that canine occurs to be Biscuit, you’d in all probability acknowledge it. The very fact “Sam’s canine is called Biscuit” works in your head whichever route somebody approaches it from, and that flexibility feels so fundamental we don’t discover we’re counting on it.
A 2023 paper by Berglund and colleagues [1] argues that language fashions don’t get this without cost. Its opening instance: an individual who learns that Valentina Tereshkova was the primary lady to journey to house can even reply “Who was the primary lady to journey to house?” That appears trivial. However a mannequin educated on the primary sentence, the place the title comes earlier than the outline, might study to reply “Who was Valentina Tereshkova?” and nonetheless fail when the outline comes first. The authors name this the Reversal Curse.
Their proof comes from two locations. They fine-tuned GPT-3 and Llama-1 on invented info and located that accuracy was close to zero every time the query got here within the reverse order from the coaching sentences. They usually examined GPT-4 on actual celebrities: it named a star’s father or mother about 79% of the time, however named the superstar when given the father or mother solely about 33% of the time (the traditional pair is “Who’s Tom Cruise’s mom?” versus “Who’s Mary Lee Pfeiffer’s son?”).
I wished to understand how small and easy a mannequin could possibly be and nonetheless present this blind spot. Not a fine-tuned LLM, however one thing I might construct in a day with nothing however NumPy and watch fail.
Why would we even count on this to work each methods?
Logically, “A is B” and “B is A” are the identical assertion seen from two sides, and a conventional data graph respects that symmetry mechanically. The authors additionally level out that the failure isn’t a scarcity of logic: if “A is B” is sitting within the immediate, GPT-4 can infer “B is A” simply fantastic. The issue exhibits up when the very fact was realized throughout coaching and needs to be recalled later from the opposite facet. That’s what makes it stunning, and it’s what the toy mannequin under lets us have a look at instantly.
Constructing the smallest mannequin that would presumably present this
The unique research used full-scale language fashions, which leaves open whether or not the impact depends upon one thing particular to them: their dimension, their consideration layers, data picked up in pretraining. To strip all of that away, I constructed the only factor that may nonetheless be referred to as a language mannequin: it reads two phrases and predicts a 3rd, with no reminiscence of anything.
In plain phrases: each phrase (right here, each made-up title) is changed into a brief record of numbers referred to as an embedding. Consider it because the mannequin’s non-public notes about that phrase, adjusted just a little every time the phrase is used. To foretell the following phrase, the mannequin provides collectively its notes on the phrases it simply learn and passes the end result by way of another layer of numbers, which produces a rating for each phrase in its vocabulary. The best rating is its guess. A typical conversion referred to as softmax rescales these scores in order that they behave like chances that add as much as 100%. There isn’t a consideration and there are not any hidden layers, so that is nothing like a contemporary transformer.
That’s deliberate, nevertheless it comes with a caveat I’ll return to on the finish: a mannequin this easy can solely present us what one-directional coaching does by itself. It may possibly’t inform us what occurs inside GPT-3.
The experiment
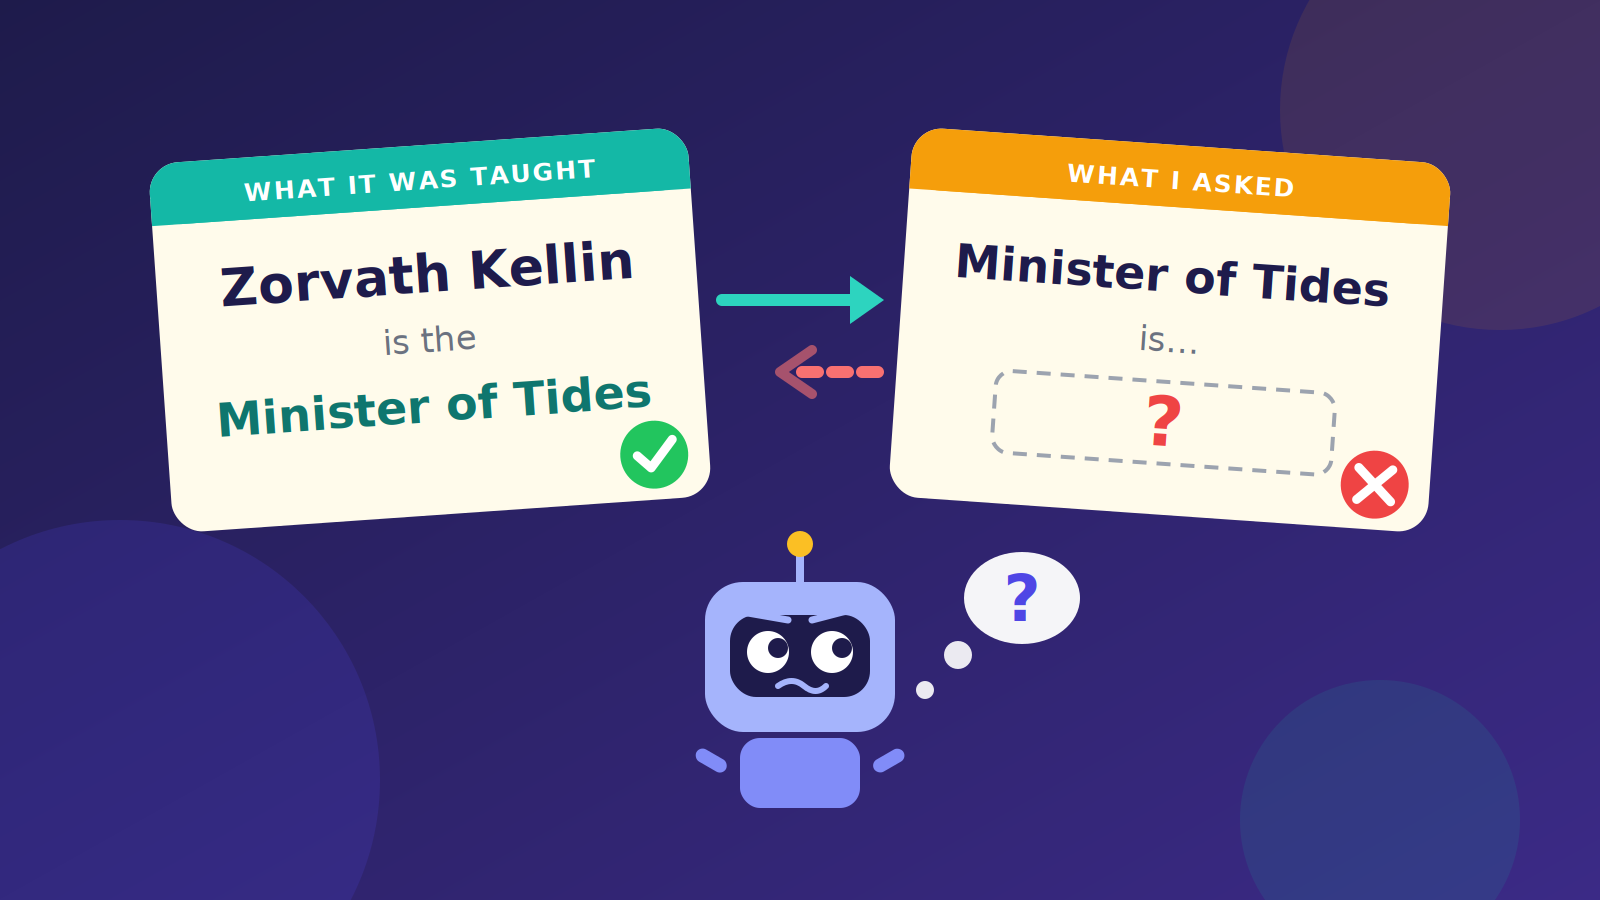
I invented 200 pretend “info,” every pairing two made-up names that seem nowhere else, one thing like “Zorvath Kellin is the Minister of Tides.” Invented names imply the mannequin can’t lean on something it has seen elsewhere; no matter it learns comes solely from the sentences I present it.
For every reality, I flipped a coin to resolve which route to show it in. Half have been taught as “Zorvath Kellin is ___” with the mannequin studying to fill in “Minister of Tides.” The opposite half have been taught backwards, “Minister of Tides is ___,” with the mannequin studying to fill in “Zorvath Kellin.” Each reality was proven in just one route. Then, for each reality, I examined the route the mannequin had by no means seen.
And right here is the mannequin and coaching loop. “X” is the mannequin’s mixed notes on the 2 phrases it simply learn, and “logits” are its uncooked scores for each attainable subsequent phrase. The gradient strains on the backside are the usual replace rule for this type of mannequin (the identical one utilized in logistic regression), written by hand as a substitute of by way of an auto-differentiation library, so there’s nothing hidden.
That one commented line, “replace solely the SUBJECT phrase’s notes,” carries most of this text.
End result: excellent recall a technique, zero the opposite
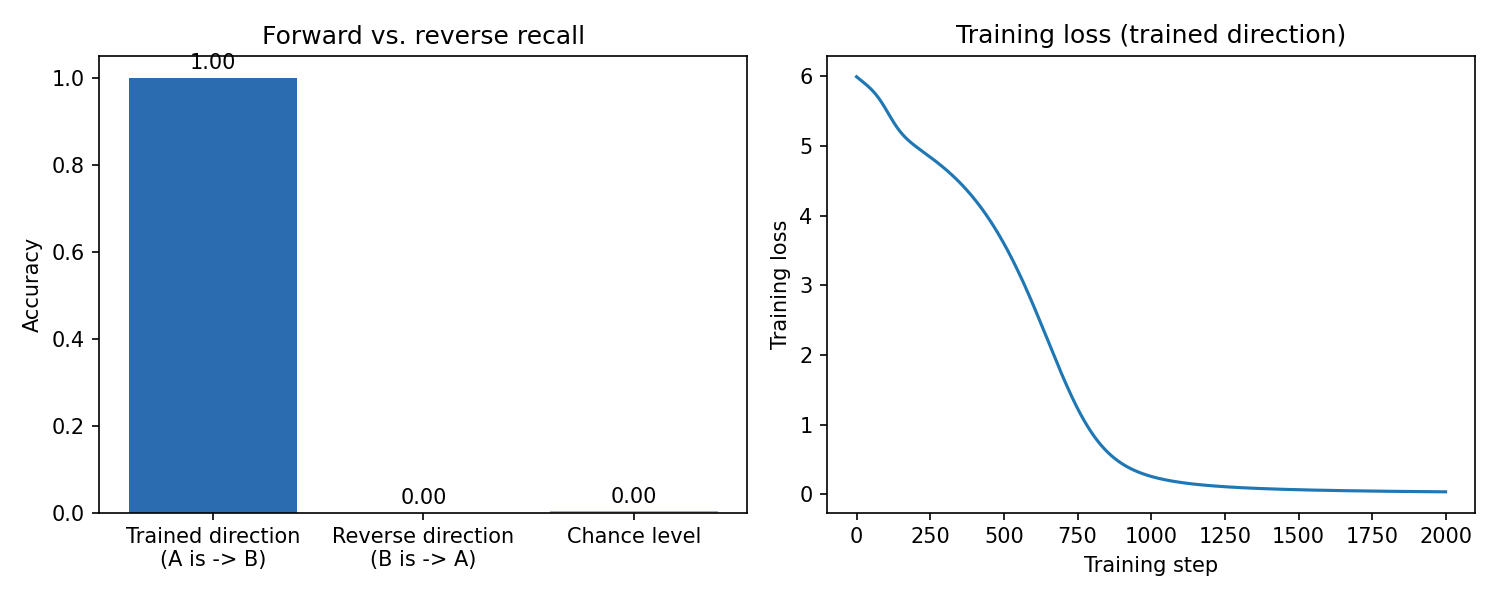
The entire thing trains in just a few seconds on a laptop computer, no GPU wanted. Listed here are the numbers from my run:
Educated-direction accuracy: 1.000 (100% right)
Reverse-direction accuracy: 0.000 (0% right)
For context, every reply had 400 attainable names, so blind guessing would get about 1 in 400 proper. Over 200 questions that’s an anticipated half an accurate reply, so 0 out of 200 is what pure likelihood appears like. The mannequin realized nothing usable within the reverse route. For comparability, the paper studies GPT-3 (175B) at close to 0% within the reverse route in opposition to as much as 96.7% within the educated route [1]. The hole right here is simply as stark.
Does it at the least rank the precise reply larger?
Zero accuracy might nonetheless disguise a partial sign: possibly the proper title is the mannequin’s second or third selection. The paper checks this by evaluating the chance the mannequin offers the proper title in opposition to a random title, and finds no detectable distinction [1]. I ran the identical test, however the best way I first ran it was deceptive, and I believe the error is price displaying.
My first comparability used a random title from the complete pool of 400. By that measure the proper reply regarded a lot worse than a random one: about −11.0 versus about −8.4 in log-probability. That will have made a dramatic story (“the mannequin is actively steering away from the reality”). Nevertheless it was an unfair comparability. The proper reverse reply is a reputation that was solely ever a topic in coaching, and topics are by no means the factor being predicted, so the mannequin learns to provide them low scores throughout the board. Half of the random names got here from the opposite group, which had been pushed up.
Towards a random title of the identical type, the hole disappears utterly:
Appropriate reverse reply: about −10.97
Random title of the identical type: about −10.98
Random title from the entire pool (unfair baseline): about −8.37
So the mannequin offers the precise reply no extra chance than any comparable incorrect one. That matches the paper’s discovering, and it’s a cleaner end result than the dramatic model I virtually reported.
Apparent objection: wouldn’t an even bigger mannequin simply repair this?
My first mannequin’s “notes” per phrase have been solely 32 numbers lengthy. It’s truthful to wonder if the impact is only a small mannequin failing to make the connection, and whether or not an actual LLM’s billions of parameters would discover room for it. I examined this by rerunning the identical experiment eight occasions, with wherever from 4 numbers per phrase as much as 512, a 128-fold enhance, and measuring reverse accuracy every time.
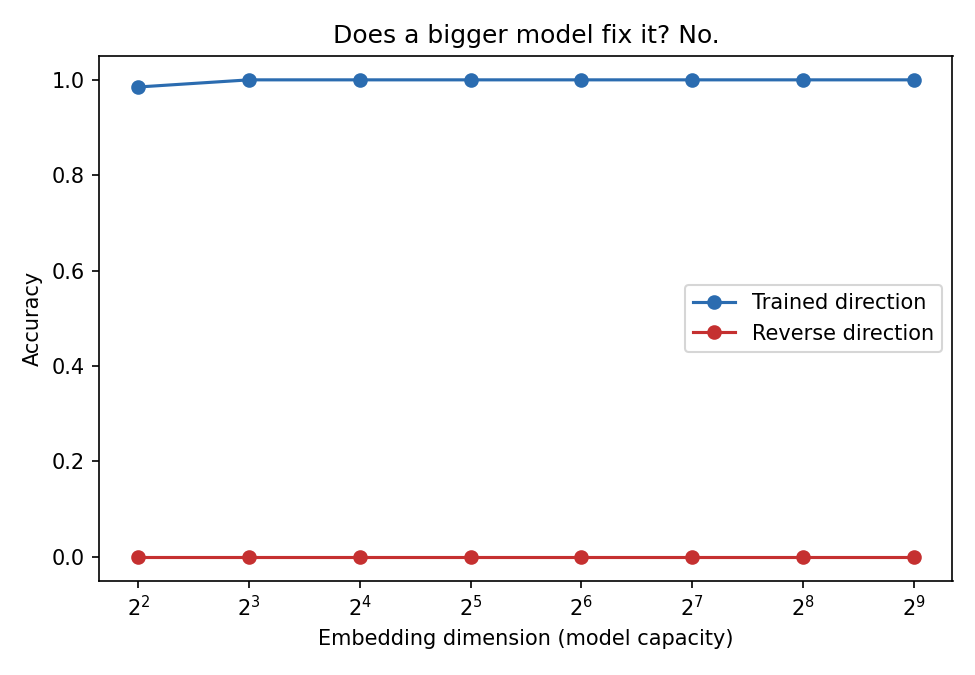
Reverse accuracy stayed at precisely 0% at each dimension. This echoes what the paper discovered at actual scale: the sample was flat throughout GPT-3 sizes from 350M to 175B parameters, and a a lot bigger fine-tuning dataset didn’t assist both [1]. Further room to retailer data doesn’t change something, as a result of the issue was by no means a scarcity of house. It’s about what will get written into that house within the first place.
Why this occurs, mechanically
Again to that one line of code: on every coaching step, solely the topic phrase’s notes get up to date. In on a regular basis phrases:
-
Every time the mannequin sees “Zorvath Kellin is the Minister of Tides,” it rewrites its notes on “Zorvath Kellin” so it will get higher at predicting what follows that title.
-
Its notes on “Minister of Tides” are by no means touched by that sentence, as a result of that phrase was solely ever the reply, by no means the phrase the prediction began from. I checked this instantly: the notes for each title that solely appeared as a solution are precisely what they have been at first of coaching. The change was 0.0.
-
So once I later ask about “Minister of Tides” as if it have been the topic, the mannequin reads notes it by no means educated, nonetheless at their random beginning values, and has nothing to work with.
The paper gives an identical sketch for actual fashions: coaching on “A is B” might change the mannequin’s illustration of A, however the replace depends upon predicting B from A, not on needing to foretell A from B later. The authors name this replace “myopic,” and so they current it as a speculation, leaving the complete rationalization for future work [1]. My toy mannequin exhibits this mechanism is sufficient to produce the impact. It doesn’t present that that is what goes on inside GPT-3.
What this toy mannequin can’t let you know
The zero right here is near assured by building. In a mannequin this easy, a reputation that solely appeared as a solution has notes that have been by no means educated as a topic, so failure in reverse is almost computerized. Actual transformers have many layers and a spotlight, and so they’re pretrained on textual content the place info seem in lots of orders. So this experiment exhibits the mechanism is ample, not that it’s what really causes the impact at scale. It additionally makes use of one dataset and one random seed. The actual-model proof for the Reversal Curse is within the paper, and it’s much more convincing than something a 60-line NumPy mannequin can supply.
What this implies past the toy mannequin
The paper’s authors observe that enormous pretraining units are various sufficient {that a} reality typically exhibits up in a number of orders, which can disguise the curse for well-known entities. However entity mentions comply with an extended tail, so rarer info might seem principally in a single route [1]. That’s the state of affairs the place you’d count on a reversed query to fail.
It’s price studying this subsequent to grokking, the topic of my final piece. Grokking exhibits a mannequin can finally discover a common construction if it retains coaching on a job that rewards one. The Reversal Curse is the alternative case: a hyperlink that by no means varieties, nevertheless lengthy you practice, as a result of nothing within the goal asks for it.
The sensible takeaway for something constructed on LLM “data” is {that a} mannequin isn’t a symmetric reality database. One thing it will probably recall from one facet might not come again if you ask from the opposite, and nothing within the output warns you when that occurs.
···
References
[1] Berglund, L., Tong, M., Kaufmann, M., Balesni, M., Stickland, A. C., Korbak, T., & Evans, O. (2023). The Reversal Curse: LLMs educated on “A is B” fail to study “B is A”. arXiv:2309.12288.