

On this article, you’ll be taught what AI agent observability means, why conventional monitoring instruments fall quick for agentic methods, and the right way to implement structured logging, distributed tracing, and sensible debugging workflows for AI brokers.
Matters we’ll cowl embody:
- Why AI brokers fail in ways in which appear to be success, and why that makes customary monitoring instruments inadequate.
- Learn how to implement structured logging and OpenTelemetry-based tracing for agent runs, instrument calls, and mannequin inference steps.
- Learn how to learn hint waterfalls, monitor token prices with metrics, and use that information to debug actual agent failures.
An agent dealing with buyer assist tickets closes one out with a clear, skilled, totally fallacious reply. It known as the refund-lookup instrument as soon as, then known as it once more with barely totally different arguments a couple of seconds later, then answered confidently based mostly on the second outcome as an alternative of the primary. Nothing crashed. No error fired. The uptime dashboard exhibits inexperienced all the time. The one purpose anybody finds out is a buyer replying two days later, confused, and by then no one can reconstruct what really occurred inside that run.
That failure is the entire purpose this text exists. A standard service both returns an error 200 or throws one thing you possibly can grep for. An agent can do neither and nonetheless be fully fallacious, and the tooling constructed for the primary sort of system is near blind to the second. This text walks by what really wants to alter — logging, tracing, and debugging — one after the other, with actual code.
What AI Agent Observability Truly Means
AI agent observability is the follow of capturing each mannequin name, instrument execution, and reasoning step an agent makes as structured information, in order that when one thing goes fallacious, you possibly can reconstruct precisely what occurred and why, fairly than guessing or re-running the identical immediate and hoping the issue repeats itself.
It borrows from the three pillars observability engineers already know — logs, metrics, and traces — however the purpose it wants its personal identify and its personal self-discipline comes right down to how brokers really fail. Aryan Kargwal, a researcher within the subject, put it plainly in protection from Digital Utilized’s 2026 observability information: agentic methods fail in ways in which appear to be success — incorrect however well-formed outputs, pointless instrument calls, or actions which can be syntactically legitimate however semantically fallacious. None of that journeys an error handler. A well being verify reporting “up” tells you virtually nothing helpful about whether or not the agent really did the proper factor on any given run.
Why Brokers Break the Conventional Monitoring Mannequin
It’s price being particular in regards to the mechanics right here, as a result of “brokers are unpredictable” undersells precisely what modifications.
The identical enter doesn’t reliably produce the identical conduct anymore. Temperature settings, retrieval outcomes, and which instruments occur to be accessible can all shift the trail an agent takes, so the identical immediate can set off a genuinely totally different sequence of instrument calls on two consecutive runs. A single “it labored after I examined it” hint tells you virtually nothing about what the distribution of actual runs really appears like.
Value and latency cease correlating with request depend and begin correlating with tokens as an alternative. A single “gradual” request is perhaps consuming ten occasions the traditional token funds, and a monitoring setup constructed round requests-per-second is structurally blind to that. Multi-step chains compound the issue: one consumer request may set off a number of mannequin calls, a handful of instrument calls, and a few retrieval lookups, and each is an impartial level of failure {that a} single combination error metric can’t distinguish between. And prompts themselves routinely carry actual private or confidential data, which suggests naive logging that dumps full immediate textual content right into a backend creates a real compliance drawback earlier than it has created any debugging worth in any respect.
A side-by-side comparability of the 2 worlds makes the shift concrete:
| Sign | Conventional app | LLM / AI agent |
|---|---|---|
| Latency driver | CPU, I/O, community | Token depend, mannequin dimension, context window |
| Value unit | Requests per second | Tokens consumed |
| Failure mode | Exception, timeout | Hallucination, context overflow, instrument error |
| Debug artifact | Stack hint | Immediate, completion, and the reasoning chain between them |
Logging
Begin with probably the most acquainted pillar, as a result of it’s nonetheless the muse all the things else builds on, simply utilized in a different way. For an agent, the occasions price logging are particular: which instrument obtained known as and with what arguments, what got here again, what number of tokens a given step consumed, how lengthy every hop took, and any error alongside the best way — and all of it structured fairly than written as free-text sentences a human has to parse later.
The element that really makes agent logging helpful is tying each log line again to the precise run it got here from. A log assertion that simply says “instrument name failed” is almost nugatory at 2 am when three totally different customers triggered three totally different runs in the identical minute. Attaching the present hint ID to each log line — one thing OpenTelemetry does mechanically as soon as tracing is ready up — is what turns a pile of scattered log statements into one thing you possibly can filter right down to the precise run that broke.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 |
import logging from opentelemetry import hint
# Normal Python logging, nothing unique right here logger = logging.getLogger(“agent”) logging.basicConfig(stage=logging.INFO)
tracer = hint.get_tracer(“agent-service”)
def call_tool(tool_name: str, arguments: dict): # get_current_span() pulls no matter span is lively proper now, # so the log line beneath might be tied again to the precise hint # and step it occurred inside span = hint.get_current_span() trace_id = format(span.get_span_context().trace_id, “032x”)
logger.information( “tool_call_started”, further={ “trace_id”: trace_id, “tool_name”: tool_name, “arguments”: arguments, }, )
attempt: outcome = execute_tool(tool_name, arguments) logger.information( “tool_call_succeeded”, further={“trace_id”: trace_id, “tool_name”: tool_name, “result_length”: len(str(outcome))}, ) return outcome besides Exception as e: logger.error( “tool_call_failed”, further={“trace_id”: trace_id, “tool_name”: tool_name, “error”: str(e)}, ) elevate |
A number of issues price noticing in that snippet. hint.get_current_span() doesn’t require you to manually go a hint ID down by each perform name — it reads no matter span is lively within the present execution context, which is precisely what makes this sample sensible to sprinkle all through an actual codebase with out threading an ID parameter by each layer.
Logging the arguments and the outcome size, fairly than the total outcome content material, is a deliberate selection, not an oversight; full instrument outputs might be massive and might carry delicate information, and a size or a truncated preview is often sufficient to identify an issue with out turning each log line right into a privateness legal responsibility. And logging each a begin and an finish occasion for a similar instrument name, fairly than simply the result, is what permits you to later measure precisely how lengthy that particular name took — which turns into the uncooked materials tracing formalizes correctly within the subsequent part.
Tracing
Logging tells you what occurred at particular person deadlines. Tracing is what stitches these factors right into a form — a full report of 1 agent run from the primary request to the ultimate reply, with each step nested contained in the step that triggered it. That nested form is the precise reply to “why did the agent try this,” as a result of it exhibits you not simply {that a} instrument was known as, however which reasoning step determined to name it and what occurred instantly earlier than and after.
The vocabulary right here comes from the OpenTelemetry GenAI semantic conventions, which outline a regular set of gen_ai.* span sorts and attributes particularly for this. Moderately than each group inventing their very own span names, the spec defines a handful of operation sorts price realizing: create_agent for when an agent is first outlined, invoke_agent for a single agent run, invoke_workflow for orchestration throughout a number of brokers handing off to one another, execute_tool for a person instrument name, and chat for the precise mannequin inference name itself. Each carries a regular set of attributes — gen_ai.request.mannequin, gen_ai.utilization.input_tokens, gen_ai.utilization.output_tokens, and gen_ai.response.finish_reasons amongst them — so a hint produced by one group’s agent appears structurally the identical as one produced by a totally totally different framework.
Right here’s what manually instrumenting a small tool-calling agent really appears like:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 |
from opentelemetry import hint from opentelemetry.hint import Standing, StatusCode
tracer = hint.get_tracer(“agent-service”)
def run_agent(process: str) -> str: # The basis span for this whole run; each step beneath nests # inside it, which is what produces the parent-child tree with tracer.start_as_current_span(“invoke_agent”) as agent_span: agent_span.set_attributes({ “gen_ai.system”: “openai”, “agent.identify”: “support-agent”, “gen_ai.request.mannequin”: “gpt-4o”, })
messages = [ {“role”: “system”, “content”: “You are a support assistant.”}, {“role”: “user”, “content”: task}, ]
whereas True: # The mannequin name itself will get its personal baby span with tracer.start_as_current_span(“chat”) as chat_span: response = model_client.chat.completions.create( mannequin=“gpt-4o”, messages=messages, instruments=AVAILABLE_TOOLS ) selection = response.selections[0]
chat_span.set_attributes({ “gen_ai.response.mannequin”: response.mannequin, “gen_ai.utilization.input_tokens”: response.utilization.prompt_tokens, “gen_ai.utilization.output_tokens”: response.utilization.completion_tokens, })
if selection.finish_reason != “tool_calls”: agent_span.set_status(Standing(StatusCode.OK)) return selection.message.content material
# Every instrument name will get its personal baby span, nested beneath # the agent run, not beneath the chat span, since a instrument # name is a sibling step, not a sub-step of inference for tool_call in selection.message.tool_calls: with tracer.start_as_current_span(“execute_tool”) as tool_span: tool_span.set_attributes({ “gen_ai.instrument.identify”: tool_call.perform.identify, “gen_ai.instrument.name.id”: tool_call.id, }) attempt: outcome = call_tool(tool_call.perform.identify, tool_call.perform.arguments) besides Exception as e: tool_span.record_exception(e) tool_span.set_status(Standing(StatusCode.ERROR, str(e))) elevate
messages.append({ “function”: “instrument”, “content material”: str(outcome), “tool_call_id”: tool_call.id, }) |
The nesting is doing the true work right here. Each chat span and each execute_tool span opens contained in the with tracer.start_as_current_span(…) block belonging to the run above it, which is precisely what OpenTelemetry makes use of to construct the parent-child relationship mechanically — you by no means manually wire “this span belongs beneath that one,” it’s implicit in how the with blocks are structured in your code. record_exception plus set_status(StatusCode.ERROR, …) on the instrument span is what makes a failed instrument name present up clearly in a hint viewer fairly than silently vanishing into the returned string, which issues immediately for the debugging part later on this article. And separating token utilization attributes onto the chat span particularly, fairly than the top-level invoke_agent span, is what lets a hint viewer later present you token value damaged down per mannequin name inside a single run, not only a single mixed complete for the entire thing.
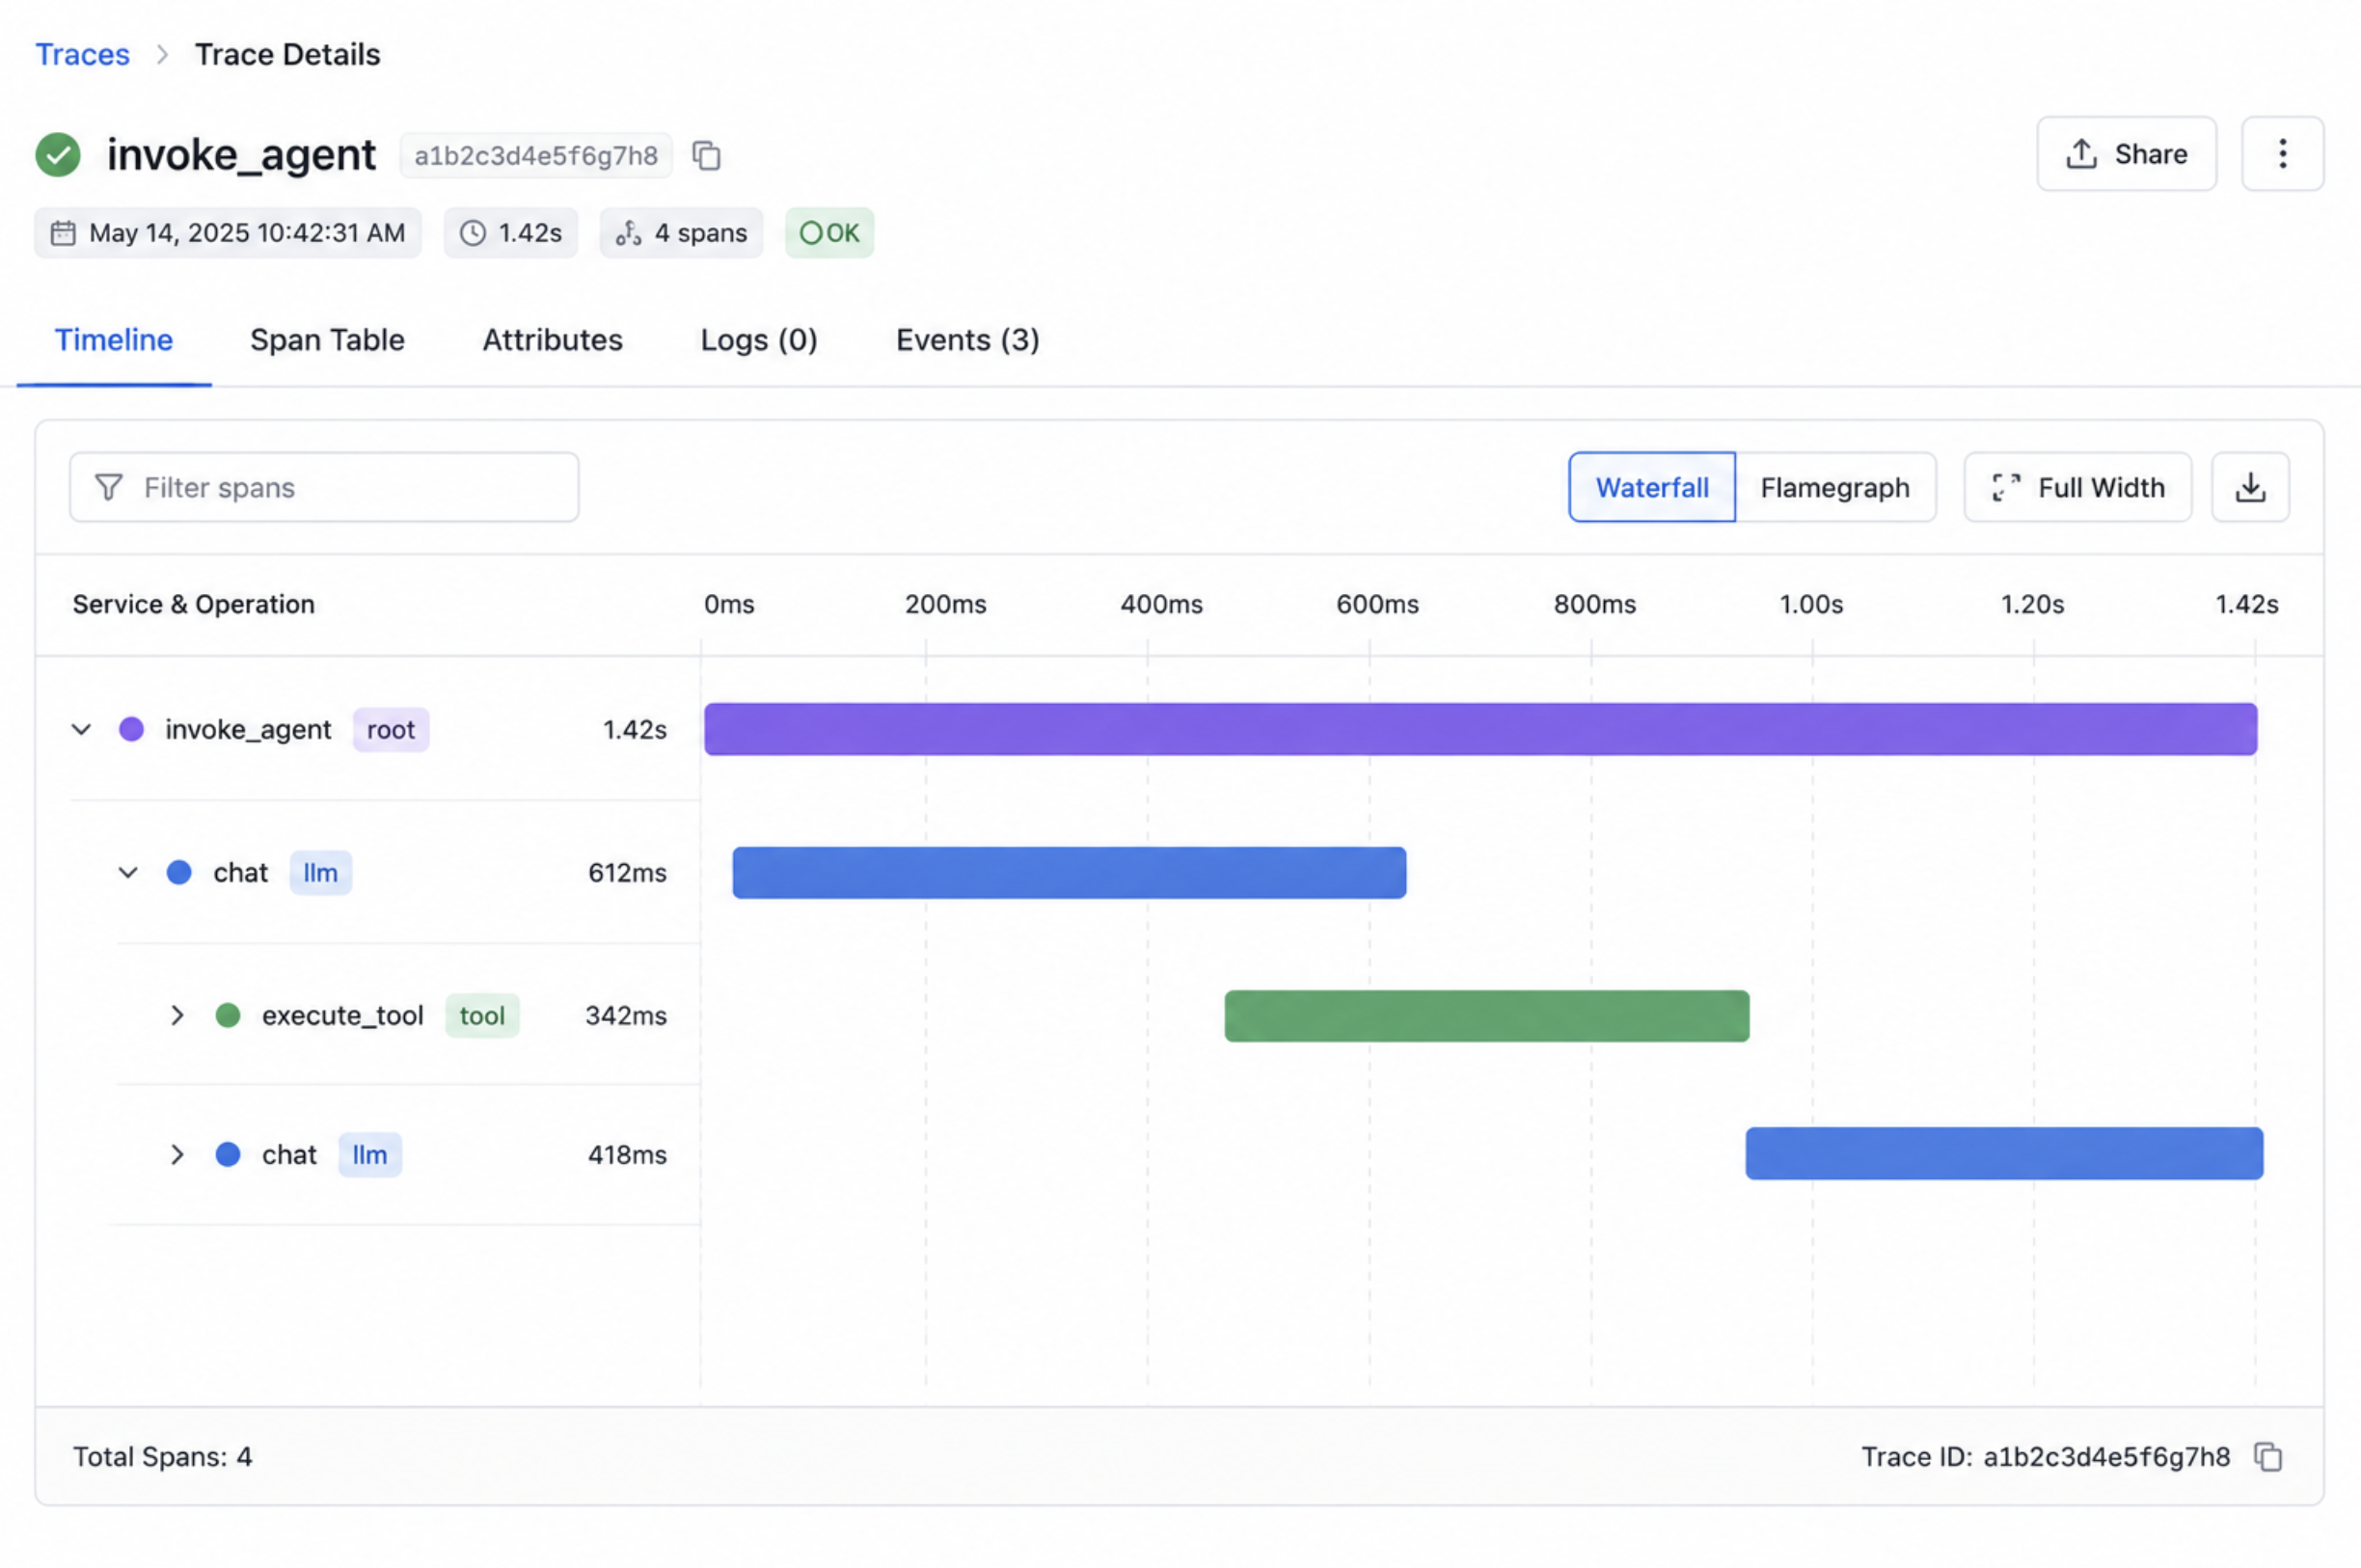
A screenshot of a hint waterfall view in an observability dashboard (click on to enlarge)
Picture by Creator
Chain Visualization: Studying the Hint Waterfall
The spans from the final part don’t imply a lot as a uncooked checklist. What really makes them helpful is a waterfall view — spans stacked by their nesting depth and stretched horizontally by how lengthy each took, so a complete agent run turns into a single image you possibly can scan in seconds. It’s price studying to learn one in plain textual content earlier than ever opening an actual dashboard, for the reason that form is similar both manner:
|
invoke_agent (1850ms) ├── chat (920ms) ← decides to name two instruments │ ├── execute_tool: refund_lookup (310ms) │ └── execute_tool: refund_lookup (295ms) ← known as once more, identical instrument └── chat (530ms) ← closing reply |
That waterfall alone tells you greater than an hour of guessing would. The 2 refund_lookup calls sitting as siblings beneath the identical chat span is precisely the sort of redundant instrument name that brought on the failure this text opened with, and it’s seen at a look fairly than buried in a wall of logs. In an actual dashboard, this identical construction renders as horizontal bars, and the habits price constructing are easy: search for a bar that’s unusually vast relative to its siblings, since that’s the place time and token funds are literally going; search for a instrument name that repeats when it shouldn’t; and search for a chat span the place the mannequin reached for a instrument in any respect when the duty didn’t clearly want one. None of that requires studying a single log line. It’s all seen within the form of the hint itself.
Token Monitoring and Value Metrics
Traces are glorious for understanding one particular run intimately. They’re the fallacious instrument for recognizing a development throughout hundreds of runs, which is what metrics are for. The 2 genuinely load-bearing metrics for an agent, per the OpenTelemetry GenAI conventions, are gen_ai.shopper.token.utilization and gen_ai.shopper.operation.period, tracked as a counter and a histogram respectively.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 |
from opentelemetry import metrics import time
meter = metrics.get_meter(“agent-service”)
token_counter = meter.create_counter( “gen_ai.shopper.token.utilization”, unit=“token”, description=“Tokens consumed, damaged down by mannequin and enter/output”, )
duration_histogram = meter.create_histogram( “gen_ai.shopper.operation.period”, unit=“s”, description=“Period of every mannequin name, in seconds”, )
def tracked_chat_call(messages: checklist, mannequin: str = “gpt-4o”) -> str: attrs = {“gen_ai.system”: “openai”, “gen_ai.request.mannequin”: mannequin} begin = time.time()
attempt: response = model_client.chat.completions.create(mannequin=mannequin, messages=messages)
# Recording enter and output tokens as two separate calls, # not one mixed complete, is what preserves the precise # value construction, since enter and output tokens are # priced in a different way on almost each supplier token_counter.add(response.utilization.prompt_tokens, {**attrs, “gen_ai.token.kind”: “enter”}) token_counter.add(response.utilization.completion_tokens, {**attrs, “gen_ai.token.kind”: “output”})
return response.selections[0].message.content material lastly: duration_histogram.report(time.time() – begin, attrs) |
The selection to report enter and output tokens as two separate counter calls, fairly than one mixed total_tokens worth, issues greater than it appears. A single mixed counter hides precisely the data you’d want to note — as an example, {that a} system immediate has quietly grown so massive it’s dwarfing the precise consumer enter on each single name. Splitting them aside is what makes that seen in a dashboard fairly than buried inside a mean.
With these two metrics flowing, a small set of alert circumstances covers most of what really goes fallacious in manufacturing, per Uptrace’s suggestions:
| Metric | Alert situation | Why it issues |
|---|---|---|
| Token utilization charge | Greater than double the baseline over 10 minutes | Usually a runaway loop or a immediate injection try |
| Operation period, p99 | Above 30 seconds | The mannequin is overloaded, or the context window is just too massive |
| Error charge | Above 2% over 5 minutes | Price limiting or quota exhaustion, price catching earlier than customers do |
| Enter-to-output token ratio | Constantly above 10 to 1 | The system immediate has possible grown bloated and wishes trimming |
Telemetry Pipelines: Getting Traces from Code to a Backend
Every part to date has assumed traces and metrics land someplace helpful, and that plumbing deserves its personal consideration fairly than being an afterthought. In a typical setup, your instrumented utility exports telemetry to an OpenTelemetry Collector — a separate course of that receives it, optionally transforms or filters it, and forwards it on to wherever you’re really storing and viewing traces. That center layer is the place two sensible issues get dealt with with out touching a single line of utility code.
- The primary is sampling. Capturing each single hint at full quantity is cheap in improvement, however LLM calls are gradual and their spans are massive, so full seize in manufacturing will get costly quick with out including proportional worth. The sensible sample is to pattern in a different way relying on the scenario: full seize in improvement, a modest proportion — usually 5 to 10% — of routine profitable manufacturing calls, and 100% seize for something genuinely worthwhile: each error, each high-token request, and each full agent run, since these are precisely the circumstances you’ll really need to look again at.
- The second is privateness, and it deserves to be handled as a first-class design resolution fairly than one thing bolted on later. Immediate and completion content material belongs in span occasions, not span attributes, since attributes are at all times listed and exported with no dimension restrict, whereas occasions might be filtered, truncated, or dropped totally on the Collector stage. A Collector configuration can strip or hash immediate content material from each span crossing the pipeline earlier than it ever reaches a storage backend, which suggests a compliance requirement doesn’t have to show right into a code change scattered throughout each instrumented name web site in your utility.
|
processors: remodel: trace_statements: – context: spanevent statements: # Strips immediate and completion content material from each span # occasion that passes by the Collector, no utility # code modifications required – delete_matching_keys(attributes, “gen_ai.immediate.content material”) – delete_matching_keys(attributes, “gen_ai.completion.content material”) |
MCP Tracing
It is a genuinely latest addition price realizing about particularly, because it closes a niche most current protection of this subject hasn’t caught as much as but. Earlier than OpenTelemetry’s Mannequin Context Protocol semantic conventions, added in spec model 1.39, the precise protocol mechanics beneath an MCP instrument name — which technique obtained invoked, which session it belonged to, and which protocol model was in use — had been successfully invisible in a hint. You could possibly see {that a} instrument ran and what it returned, however not the layer beneath that.
The element price understanding is how these new attributes get hooked up. Moderately than making a second, separate span for the protocol layer, MCP instrumentation enriches the prevailing execute_tool span with attributes like mcp.technique.identify, mcp.session.id, and mcp.protocol.model, layering the additional element onto the span you already had as an alternative of doubling the hint’s noise. For anybody constructing brokers that decision out to a number of MCP servers, that’s the distinction between a hint that stays readable and one which turns right into a wall of near-duplicate spans.
Debugging Workflows
That is the place all the things constructed to date really pays off. An actual debugging workflow, as soon as tracing is in place, tends to observe the identical form whatever the platform behind it: begin from the unhealthy output a consumer reported, pull the hint ID that produced it, open the waterfall, and scan for the span the place the run really went fallacious — an unexpectedly vast chat span, a repeated execute_tool name, an error standing someplace within the tree. When you’ve discovered the step, the span’s attributes and occasions let you know precisely what arguments had been handed and what got here again, which is often sufficient to grasp the error immediately, no re-running required, no guessing.
Two extra superior methods are price realizing as this follow matures. Replay, typically known as time-travel debugging, permits you to re-run an agent session with point-in-time precision — successfully restoring the precise state the agent was in at a given step and persevering with from there, a functionality AgentOps is particularly recognized for. And a more moderen sample price watching is natural-language hint querying, the place as an alternative of manually scanning a waterfall, an engineer can immediately ask a platform one thing like “why did the agent enter this loop” and get a solution generated from analyzing the hint information itself — a functionality LangSmith has constructed immediately into its product. Neither replaces the basics lined above. Each are what these fundamentals make potential as soon as a group has sufficient traces flowing to make asking that sort of query worthwhile.
The Instruments High Groups Truly Use in 2026
Constructing this your self with uncooked OpenTelemetry, as proven all through this text, works and retains you vendor-neutral, however most groups ultimately attain for a platform to retailer, visualize, and question the traces they’re producing. The choice genuinely comes right down to deployment mannequin earlier than it comes right down to options, since that single selection eliminates a lot of the subject by itself, per Digital Utilized’s 2026 breakdown.
Self-hosted platforms — Langfuse and Arize Phoenix amongst them — go well with groups with actual information residency necessities or a necessity for tight value management at scale, at the price of proudly owning the operational overhead your self. Managed SDKs — LangSmith and Braintrust — commerce that possession for velocity: you add an SDK, the seller runs the backend and storage, and also you usually get analysis tooling bundled in from day one. Proxy gateways — Helicone being the clearest instance — sit your visitors behind a routing layer that logs value and utilization throughout a whole lot of fashions with near zero code change, with the tradeoff that the gateway itself turns into a single level of failure price planning actual uptime round.
| Platform | Deployment mannequin | Free tier | OpenTelemetry assist | 2025 to 2026 sign |
|---|---|---|---|---|
| Langfuse | Self-hosted or cloud | Free self-hosting | Sure | Acquired by ClickHouse, January 2026 |
| Arize Phoenix | Self-hosted | Open supply, free | Sure, OTLP-native | Actively rising open-source challenge |
| LangSmith | Managed SDK | 5,000 traces per thirty days | Sure | Pure-language hint querying in-built |
| Braintrust | Managed SDK | 1 million spans per thirty days | Sure | $80M Collection B, February 2026 |
| Helicone | Proxy gateway | 10,000 requests per thirty days | Through gateway | Value monitoring throughout 300+ fashions |
| AgentOps | SDK | Open supply, free | Sure | Identified for time-travel replay debugging |
| Datadog LLM Observability | Managed, extends current APM | 40,000 LLM spans per thirty days | Sure | Payments solely LLM spans, not instrument or retrieval spans |
Placing It Collectively
Right here’s how all the items above mix into one working script, so the ideas on this article don’t keep disconnected. This wires up tracing, token metrics, and structured logging collectively round a single small agent.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 |
import logging import time from opentelemetry import hint, metrics from opentelemetry.hint import Standing, StatusCode
tracer = hint.get_tracer(“agent-service”) meter = metrics.get_meter(“agent-service”) logger = logging.getLogger(“agent”)
token_counter = meter.create_counter(“gen_ai.shopper.token.utilization”, unit=“token”) duration_histogram = meter.create_histogram(“gen_ai.shopper.operation.period”, unit=“s”)
def run_instrumented_agent(process: str) -> str: with tracer.start_as_current_span(“invoke_agent”) as agent_span: trace_id = format(agent_span.get_span_context().trace_id, “032x”) agent_span.set_attributes({“agent.identify”: “support-agent”, “gen_ai.request.mannequin”: “gpt-4o”}) logger.information(“agent_run_started”, further={“trace_id”: trace_id, “process”: process[:100]})
messages = [{“role”: “user”, “content”: task}]
whereas True: with tracer.start_as_current_span(“chat”) as chat_span: begin = time.time() response = model_client.chat.completions.create( mannequin=“gpt-4o”, messages=messages, instruments=AVAILABLE_TOOLS ) duration_histogram.report(time.time() – begin, {“gen_ai.request.mannequin”: “gpt-4o”})
utilization = response.utilization token_counter.add(utilization.prompt_tokens, {“gen_ai.token.kind”: “enter”}) token_counter.add(utilization.completion_tokens, {“gen_ai.token.kind”: “output”}) chat_span.set_attributes({ “gen_ai.utilization.input_tokens”: utilization.prompt_tokens, “gen_ai.utilization.output_tokens”: utilization.completion_tokens, })
selection = response.selections[0]
if selection.finish_reason != “tool_calls”: agent_span.set_status(Standing(StatusCode.OK)) logger.information(“agent_run_completed”, further={“trace_id”: trace_id}) return selection.message.content material
for tool_call in selection.message.tool_calls: with tracer.start_as_current_span(“execute_tool”) as tool_span: tool_span.set_attribute(“gen_ai.instrument.identify”, tool_call.perform.identify) logger.information( “tool_call_started”, further={“trace_id”: trace_id, “tool_name”: tool_call.perform.identify}, ) attempt: outcome = call_tool(tool_call.perform.identify, tool_call.perform.arguments) besides Exception as e: tool_span.record_exception(e) tool_span.set_status(Standing(StatusCode.ERROR, str(e))) logger.error( “tool_call_failed”, further={“trace_id”: trace_id, “tool_name”: tool_call.perform.identify}, ) elevate messages.append({“function”: “instrument”, “content material”: str(outcome), “tool_call_id”: tool_call.id}) |
Run this with a Collector configured to export to whichever backend you’ve picked from the desk above, and a single name to run_instrumented_agent produces a full hint with nested spans for each instrument name, token metrics recorded per mannequin name, and structured log traces carrying the hint ID that ties all the things again collectively — precisely the setup this whole article has been constructing towards.
Conclusion
An unsupervised agent isn’t a smaller threat than an unmanaged net service; it’s a bigger one, exactly as a result of its failures are constructed to look high quality till somebody checks carefully. The refund lookup known as twice, the assured reply constructed on stale information — none of that journeys an alarm by itself. Logging tells you what occurred at every step. Tracing exhibits you ways these steps really related. Debugging is what turns that report into a solution as an alternative of a guess. Construct all three in earlier than an agent is dealing with something that really issues, not after the primary buyer notices one thing went fallacious.
On this article, you’ll be taught what AI agent observability means, why conventional monitoring instruments fall quick for agentic methods, and the right way to implement structured logging, distributed tracing, and sensible debugging workflows for AI brokers.
Matters we’ll cowl embody:
- Why AI brokers fail in ways in which appear to be success, and why that makes customary monitoring instruments inadequate.
- Learn how to implement structured logging and OpenTelemetry-based tracing for agent runs, instrument calls, and mannequin inference steps.
- Learn how to learn hint waterfalls, monitor token prices with metrics, and use that information to debug actual agent failures.
An agent dealing with buyer assist tickets closes one out with a clear, skilled, totally fallacious reply. It known as the refund-lookup instrument as soon as, then known as it once more with barely totally different arguments a couple of seconds later, then answered confidently based mostly on the second outcome as an alternative of the primary. Nothing crashed. No error fired. The uptime dashboard exhibits inexperienced all the time. The one purpose anybody finds out is a buyer replying two days later, confused, and by then no one can reconstruct what really occurred inside that run.
That failure is the entire purpose this text exists. A standard service both returns an error 200 or throws one thing you possibly can grep for. An agent can do neither and nonetheless be fully fallacious, and the tooling constructed for the primary sort of system is near blind to the second. This text walks by what really wants to alter — logging, tracing, and debugging — one after the other, with actual code.
What AI Agent Observability Truly Means
AI agent observability is the follow of capturing each mannequin name, instrument execution, and reasoning step an agent makes as structured information, in order that when one thing goes fallacious, you possibly can reconstruct precisely what occurred and why, fairly than guessing or re-running the identical immediate and hoping the issue repeats itself.
It borrows from the three pillars observability engineers already know — logs, metrics, and traces — however the purpose it wants its personal identify and its personal self-discipline comes right down to how brokers really fail. Aryan Kargwal, a researcher within the subject, put it plainly in protection from Digital Utilized’s 2026 observability information: agentic methods fail in ways in which appear to be success — incorrect however well-formed outputs, pointless instrument calls, or actions which can be syntactically legitimate however semantically fallacious. None of that journeys an error handler. A well being verify reporting “up” tells you virtually nothing helpful about whether or not the agent really did the proper factor on any given run.
Why Brokers Break the Conventional Monitoring Mannequin
It’s price being particular in regards to the mechanics right here, as a result of “brokers are unpredictable” undersells precisely what modifications.
The identical enter doesn’t reliably produce the identical conduct anymore. Temperature settings, retrieval outcomes, and which instruments occur to be accessible can all shift the trail an agent takes, so the identical immediate can set off a genuinely totally different sequence of instrument calls on two consecutive runs. A single “it labored after I examined it” hint tells you virtually nothing about what the distribution of actual runs really appears like.
Value and latency cease correlating with request depend and begin correlating with tokens as an alternative. A single “gradual” request is perhaps consuming ten occasions the traditional token funds, and a monitoring setup constructed round requests-per-second is structurally blind to that. Multi-step chains compound the issue: one consumer request may set off a number of mannequin calls, a handful of instrument calls, and a few retrieval lookups, and each is an impartial level of failure {that a} single combination error metric can’t distinguish between. And prompts themselves routinely carry actual private or confidential data, which suggests naive logging that dumps full immediate textual content right into a backend creates a real compliance drawback earlier than it has created any debugging worth in any respect.
A side-by-side comparability of the 2 worlds makes the shift concrete:
| Sign | Conventional app | LLM / AI agent |
|---|---|---|
| Latency driver | CPU, I/O, community | Token depend, mannequin dimension, context window |
| Value unit | Requests per second | Tokens consumed |
| Failure mode | Exception, timeout | Hallucination, context overflow, instrument error |
| Debug artifact | Stack hint | Immediate, completion, and the reasoning chain between them |
Logging
Begin with probably the most acquainted pillar, as a result of it’s nonetheless the muse all the things else builds on, simply utilized in a different way. For an agent, the occasions price logging are particular: which instrument obtained known as and with what arguments, what got here again, what number of tokens a given step consumed, how lengthy every hop took, and any error alongside the best way — and all of it structured fairly than written as free-text sentences a human has to parse later.
The element that really makes agent logging helpful is tying each log line again to the precise run it got here from. A log assertion that simply says “instrument name failed” is almost nugatory at 2 am when three totally different customers triggered three totally different runs in the identical minute. Attaching the present hint ID to each log line — one thing OpenTelemetry does mechanically as soon as tracing is ready up — is what turns a pile of scattered log statements into one thing you possibly can filter right down to the precise run that broke.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 |
import logging from opentelemetry import hint
# Normal Python logging, nothing unique right here logger = logging.getLogger(“agent”) logging.basicConfig(stage=logging.INFO)
tracer = hint.get_tracer(“agent-service”)
def call_tool(tool_name: str, arguments: dict): # get_current_span() pulls no matter span is lively proper now, # so the log line beneath might be tied again to the precise hint # and step it occurred inside span = hint.get_current_span() trace_id = format(span.get_span_context().trace_id, “032x”)
logger.information( “tool_call_started”, further={ “trace_id”: trace_id, “tool_name”: tool_name, “arguments”: arguments, }, )
attempt: outcome = execute_tool(tool_name, arguments) logger.information( “tool_call_succeeded”, further={“trace_id”: trace_id, “tool_name”: tool_name, “result_length”: len(str(outcome))}, ) return outcome besides Exception as e: logger.error( “tool_call_failed”, further={“trace_id”: trace_id, “tool_name”: tool_name, “error”: str(e)}, ) elevate |
A number of issues price noticing in that snippet. hint.get_current_span() doesn’t require you to manually go a hint ID down by each perform name — it reads no matter span is lively within the present execution context, which is precisely what makes this sample sensible to sprinkle all through an actual codebase with out threading an ID parameter by each layer.
Logging the arguments and the outcome size, fairly than the total outcome content material, is a deliberate selection, not an oversight; full instrument outputs might be massive and might carry delicate information, and a size or a truncated preview is often sufficient to identify an issue with out turning each log line right into a privateness legal responsibility. And logging each a begin and an finish occasion for a similar instrument name, fairly than simply the result, is what permits you to later measure precisely how lengthy that particular name took — which turns into the uncooked materials tracing formalizes correctly within the subsequent part.
Tracing
Logging tells you what occurred at particular person deadlines. Tracing is what stitches these factors right into a form — a full report of 1 agent run from the primary request to the ultimate reply, with each step nested contained in the step that triggered it. That nested form is the precise reply to “why did the agent try this,” as a result of it exhibits you not simply {that a} instrument was known as, however which reasoning step determined to name it and what occurred instantly earlier than and after.
The vocabulary right here comes from the OpenTelemetry GenAI semantic conventions, which outline a regular set of gen_ai.* span sorts and attributes particularly for this. Moderately than each group inventing their very own span names, the spec defines a handful of operation sorts price realizing: create_agent for when an agent is first outlined, invoke_agent for a single agent run, invoke_workflow for orchestration throughout a number of brokers handing off to one another, execute_tool for a person instrument name, and chat for the precise mannequin inference name itself. Each carries a regular set of attributes — gen_ai.request.mannequin, gen_ai.utilization.input_tokens, gen_ai.utilization.output_tokens, and gen_ai.response.finish_reasons amongst them — so a hint produced by one group’s agent appears structurally the identical as one produced by a totally totally different framework.
Right here’s what manually instrumenting a small tool-calling agent really appears like:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 |
from opentelemetry import hint from opentelemetry.hint import Standing, StatusCode
tracer = hint.get_tracer(“agent-service”)
def run_agent(process: str) -> str: # The basis span for this whole run; each step beneath nests # inside it, which is what produces the parent-child tree with tracer.start_as_current_span(“invoke_agent”) as agent_span: agent_span.set_attributes({ “gen_ai.system”: “openai”, “agent.identify”: “support-agent”, “gen_ai.request.mannequin”: “gpt-4o”, })
messages = [ {“role”: “system”, “content”: “You are a support assistant.”}, {“role”: “user”, “content”: task}, ]
whereas True: # The mannequin name itself will get its personal baby span with tracer.start_as_current_span(“chat”) as chat_span: response = model_client.chat.completions.create( mannequin=“gpt-4o”, messages=messages, instruments=AVAILABLE_TOOLS ) selection = response.selections[0]
chat_span.set_attributes({ “gen_ai.response.mannequin”: response.mannequin, “gen_ai.utilization.input_tokens”: response.utilization.prompt_tokens, “gen_ai.utilization.output_tokens”: response.utilization.completion_tokens, })
if selection.finish_reason != “tool_calls”: agent_span.set_status(Standing(StatusCode.OK)) return selection.message.content material
# Every instrument name will get its personal baby span, nested beneath # the agent run, not beneath the chat span, since a instrument # name is a sibling step, not a sub-step of inference for tool_call in selection.message.tool_calls: with tracer.start_as_current_span(“execute_tool”) as tool_span: tool_span.set_attributes({ “gen_ai.instrument.identify”: tool_call.perform.identify, “gen_ai.instrument.name.id”: tool_call.id, }) attempt: outcome = call_tool(tool_call.perform.identify, tool_call.perform.arguments) besides Exception as e: tool_span.record_exception(e) tool_span.set_status(Standing(StatusCode.ERROR, str(e))) elevate
messages.append({ “function”: “instrument”, “content material”: str(outcome), “tool_call_id”: tool_call.id, }) |
The nesting is doing the true work right here. Each chat span and each execute_tool span opens contained in the with tracer.start_as_current_span(…) block belonging to the run above it, which is precisely what OpenTelemetry makes use of to construct the parent-child relationship mechanically — you by no means manually wire “this span belongs beneath that one,” it’s implicit in how the with blocks are structured in your code. record_exception plus set_status(StatusCode.ERROR, …) on the instrument span is what makes a failed instrument name present up clearly in a hint viewer fairly than silently vanishing into the returned string, which issues immediately for the debugging part later on this article. And separating token utilization attributes onto the chat span particularly, fairly than the top-level invoke_agent span, is what lets a hint viewer later present you token value damaged down per mannequin name inside a single run, not only a single mixed complete for the entire thing.
A screenshot of a hint waterfall view in an observability dashboard (click on to enlarge)
Picture by Creator
Chain Visualization: Studying the Hint Waterfall
The spans from the final part don’t imply a lot as a uncooked checklist. What really makes them helpful is a waterfall view — spans stacked by their nesting depth and stretched horizontally by how lengthy each took, so a complete agent run turns into a single image you possibly can scan in seconds. It’s price studying to learn one in plain textual content earlier than ever opening an actual dashboard, for the reason that form is similar both manner:
|
invoke_agent (1850ms) ├── chat (920ms) ← decides to name two instruments │ ├── execute_tool: refund_lookup (310ms) │ └── execute_tool: refund_lookup (295ms) ← known as once more, identical instrument └── chat (530ms) ← closing reply |
That waterfall alone tells you greater than an hour of guessing would. The 2 refund_lookup calls sitting as siblings beneath the identical chat span is precisely the sort of redundant instrument name that brought on the failure this text opened with, and it’s seen at a look fairly than buried in a wall of logs. In an actual dashboard, this identical construction renders as horizontal bars, and the habits price constructing are easy: search for a bar that’s unusually vast relative to its siblings, since that’s the place time and token funds are literally going; search for a instrument name that repeats when it shouldn’t; and search for a chat span the place the mannequin reached for a instrument in any respect when the duty didn’t clearly want one. None of that requires studying a single log line. It’s all seen within the form of the hint itself.
Token Monitoring and Value Metrics
Traces are glorious for understanding one particular run intimately. They’re the fallacious instrument for recognizing a development throughout hundreds of runs, which is what metrics are for. The 2 genuinely load-bearing metrics for an agent, per the OpenTelemetry GenAI conventions, are gen_ai.shopper.token.utilization and gen_ai.shopper.operation.period, tracked as a counter and a histogram respectively.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 |
from opentelemetry import metrics import time
meter = metrics.get_meter(“agent-service”)
token_counter = meter.create_counter( “gen_ai.shopper.token.utilization”, unit=“token”, description=“Tokens consumed, damaged down by mannequin and enter/output”, )
duration_histogram = meter.create_histogram( “gen_ai.shopper.operation.period”, unit=“s”, description=“Period of every mannequin name, in seconds”, )
def tracked_chat_call(messages: checklist, mannequin: str = “gpt-4o”) -> str: attrs = {“gen_ai.system”: “openai”, “gen_ai.request.mannequin”: mannequin} begin = time.time()
attempt: response = model_client.chat.completions.create(mannequin=mannequin, messages=messages)
# Recording enter and output tokens as two separate calls, # not one mixed complete, is what preserves the precise # value construction, since enter and output tokens are # priced in a different way on almost each supplier token_counter.add(response.utilization.prompt_tokens, {**attrs, “gen_ai.token.kind”: “enter”}) token_counter.add(response.utilization.completion_tokens, {**attrs, “gen_ai.token.kind”: “output”})
return response.selections[0].message.content material lastly: duration_histogram.report(time.time() – begin, attrs) |
The selection to report enter and output tokens as two separate counter calls, fairly than one mixed total_tokens worth, issues greater than it appears. A single mixed counter hides precisely the data you’d want to note — as an example, {that a} system immediate has quietly grown so massive it’s dwarfing the precise consumer enter on each single name. Splitting them aside is what makes that seen in a dashboard fairly than buried inside a mean.
With these two metrics flowing, a small set of alert circumstances covers most of what really goes fallacious in manufacturing, per Uptrace’s suggestions:
| Metric | Alert situation | Why it issues |
|---|---|---|
| Token utilization charge | Greater than double the baseline over 10 minutes | Usually a runaway loop or a immediate injection try |
| Operation period, p99 | Above 30 seconds | The mannequin is overloaded, or the context window is just too massive |
| Error charge | Above 2% over 5 minutes | Price limiting or quota exhaustion, price catching earlier than customers do |
| Enter-to-output token ratio | Constantly above 10 to 1 | The system immediate has possible grown bloated and wishes trimming |
Telemetry Pipelines: Getting Traces from Code to a Backend
Every part to date has assumed traces and metrics land someplace helpful, and that plumbing deserves its personal consideration fairly than being an afterthought. In a typical setup, your instrumented utility exports telemetry to an OpenTelemetry Collector — a separate course of that receives it, optionally transforms or filters it, and forwards it on to wherever you’re really storing and viewing traces. That center layer is the place two sensible issues get dealt with with out touching a single line of utility code.
- The primary is sampling. Capturing each single hint at full quantity is cheap in improvement, however LLM calls are gradual and their spans are massive, so full seize in manufacturing will get costly quick with out including proportional worth. The sensible sample is to pattern in a different way relying on the scenario: full seize in improvement, a modest proportion — usually 5 to 10% — of routine profitable manufacturing calls, and 100% seize for something genuinely worthwhile: each error, each high-token request, and each full agent run, since these are precisely the circumstances you’ll really need to look again at.
- The second is privateness, and it deserves to be handled as a first-class design resolution fairly than one thing bolted on later. Immediate and completion content material belongs in span occasions, not span attributes, since attributes are at all times listed and exported with no dimension restrict, whereas occasions might be filtered, truncated, or dropped totally on the Collector stage. A Collector configuration can strip or hash immediate content material from each span crossing the pipeline earlier than it ever reaches a storage backend, which suggests a compliance requirement doesn’t have to show right into a code change scattered throughout each instrumented name web site in your utility.
|
processors: remodel: trace_statements: – context: spanevent statements: # Strips immediate and completion content material from each span # occasion that passes by the Collector, no utility # code modifications required – delete_matching_keys(attributes, “gen_ai.immediate.content material”) – delete_matching_keys(attributes, “gen_ai.completion.content material”) |
MCP Tracing
It is a genuinely latest addition price realizing about particularly, because it closes a niche most current protection of this subject hasn’t caught as much as but. Earlier than OpenTelemetry’s Mannequin Context Protocol semantic conventions, added in spec model 1.39, the precise protocol mechanics beneath an MCP instrument name — which technique obtained invoked, which session it belonged to, and which protocol model was in use — had been successfully invisible in a hint. You could possibly see {that a} instrument ran and what it returned, however not the layer beneath that.
The element price understanding is how these new attributes get hooked up. Moderately than making a second, separate span for the protocol layer, MCP instrumentation enriches the prevailing execute_tool span with attributes like mcp.technique.identify, mcp.session.id, and mcp.protocol.model, layering the additional element onto the span you already had as an alternative of doubling the hint’s noise. For anybody constructing brokers that decision out to a number of MCP servers, that’s the distinction between a hint that stays readable and one which turns right into a wall of near-duplicate spans.
Debugging Workflows
That is the place all the things constructed to date really pays off. An actual debugging workflow, as soon as tracing is in place, tends to observe the identical form whatever the platform behind it: begin from the unhealthy output a consumer reported, pull the hint ID that produced it, open the waterfall, and scan for the span the place the run really went fallacious — an unexpectedly vast chat span, a repeated execute_tool name, an error standing someplace within the tree. When you’ve discovered the step, the span’s attributes and occasions let you know precisely what arguments had been handed and what got here again, which is often sufficient to grasp the error immediately, no re-running required, no guessing.
Two extra superior methods are price realizing as this follow matures. Replay, typically known as time-travel debugging, permits you to re-run an agent session with point-in-time precision — successfully restoring the precise state the agent was in at a given step and persevering with from there, a functionality AgentOps is particularly recognized for. And a more moderen sample price watching is natural-language hint querying, the place as an alternative of manually scanning a waterfall, an engineer can immediately ask a platform one thing like “why did the agent enter this loop” and get a solution generated from analyzing the hint information itself — a functionality LangSmith has constructed immediately into its product. Neither replaces the basics lined above. Each are what these fundamentals make potential as soon as a group has sufficient traces flowing to make asking that sort of query worthwhile.
The Instruments High Groups Truly Use in 2026
Constructing this your self with uncooked OpenTelemetry, as proven all through this text, works and retains you vendor-neutral, however most groups ultimately attain for a platform to retailer, visualize, and question the traces they’re producing. The choice genuinely comes right down to deployment mannequin earlier than it comes right down to options, since that single selection eliminates a lot of the subject by itself, per Digital Utilized’s 2026 breakdown.
Self-hosted platforms — Langfuse and Arize Phoenix amongst them — go well with groups with actual information residency necessities or a necessity for tight value management at scale, at the price of proudly owning the operational overhead your self. Managed SDKs — LangSmith and Braintrust — commerce that possession for velocity: you add an SDK, the seller runs the backend and storage, and also you usually get analysis tooling bundled in from day one. Proxy gateways — Helicone being the clearest instance — sit your visitors behind a routing layer that logs value and utilization throughout a whole lot of fashions with near zero code change, with the tradeoff that the gateway itself turns into a single level of failure price planning actual uptime round.
| Platform | Deployment mannequin | Free tier | OpenTelemetry assist | 2025 to 2026 sign |
|---|---|---|---|---|
| Langfuse | Self-hosted or cloud | Free self-hosting | Sure | Acquired by ClickHouse, January 2026 |
| Arize Phoenix | Self-hosted | Open supply, free | Sure, OTLP-native | Actively rising open-source challenge |
| LangSmith | Managed SDK | 5,000 traces per thirty days | Sure | Pure-language hint querying in-built |
| Braintrust | Managed SDK | 1 million spans per thirty days | Sure | $80M Collection B, February 2026 |
| Helicone | Proxy gateway | 10,000 requests per thirty days | Through gateway | Value monitoring throughout 300+ fashions |
| AgentOps | SDK | Open supply, free | Sure | Identified for time-travel replay debugging |
| Datadog LLM Observability | Managed, extends current APM | 40,000 LLM spans per thirty days | Sure | Payments solely LLM spans, not instrument or retrieval spans |
Placing It Collectively
Right here’s how all the items above mix into one working script, so the ideas on this article don’t keep disconnected. This wires up tracing, token metrics, and structured logging collectively round a single small agent.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 |
import logging import time from opentelemetry import hint, metrics from opentelemetry.hint import Standing, StatusCode
tracer = hint.get_tracer(“agent-service”) meter = metrics.get_meter(“agent-service”) logger = logging.getLogger(“agent”)
token_counter = meter.create_counter(“gen_ai.shopper.token.utilization”, unit=“token”) duration_histogram = meter.create_histogram(“gen_ai.shopper.operation.period”, unit=“s”)
def run_instrumented_agent(process: str) -> str: with tracer.start_as_current_span(“invoke_agent”) as agent_span: trace_id = format(agent_span.get_span_context().trace_id, “032x”) agent_span.set_attributes({“agent.identify”: “support-agent”, “gen_ai.request.mannequin”: “gpt-4o”}) logger.information(“agent_run_started”, further={“trace_id”: trace_id, “process”: process[:100]})
messages = [{“role”: “user”, “content”: task}]
whereas True: with tracer.start_as_current_span(“chat”) as chat_span: begin = time.time() response = model_client.chat.completions.create( mannequin=“gpt-4o”, messages=messages, instruments=AVAILABLE_TOOLS ) duration_histogram.report(time.time() – begin, {“gen_ai.request.mannequin”: “gpt-4o”})
utilization = response.utilization token_counter.add(utilization.prompt_tokens, {“gen_ai.token.kind”: “enter”}) token_counter.add(utilization.completion_tokens, {“gen_ai.token.kind”: “output”}) chat_span.set_attributes({ “gen_ai.utilization.input_tokens”: utilization.prompt_tokens, “gen_ai.utilization.output_tokens”: utilization.completion_tokens, })
selection = response.selections[0]
if selection.finish_reason != “tool_calls”: agent_span.set_status(Standing(StatusCode.OK)) logger.information(“agent_run_completed”, further={“trace_id”: trace_id}) return selection.message.content material
for tool_call in selection.message.tool_calls: with tracer.start_as_current_span(“execute_tool”) as tool_span: tool_span.set_attribute(“gen_ai.instrument.identify”, tool_call.perform.identify) logger.information( “tool_call_started”, further={“trace_id”: trace_id, “tool_name”: tool_call.perform.identify}, ) attempt: outcome = call_tool(tool_call.perform.identify, tool_call.perform.arguments) besides Exception as e: tool_span.record_exception(e) tool_span.set_status(Standing(StatusCode.ERROR, str(e))) logger.error( “tool_call_failed”, further={“trace_id”: trace_id, “tool_name”: tool_call.perform.identify}, ) elevate messages.append({“function”: “instrument”, “content material”: str(outcome), “tool_call_id”: tool_call.id}) |
Run this with a Collector configured to export to whichever backend you’ve picked from the desk above, and a single name to run_instrumented_agent produces a full hint with nested spans for each instrument name, token metrics recorded per mannequin name, and structured log traces carrying the hint ID that ties all the things again collectively — precisely the setup this whole article has been constructing towards.
Conclusion
An unsupervised agent isn’t a smaller threat than an unmanaged net service; it’s a bigger one, exactly as a result of its failures are constructed to look high quality till somebody checks carefully. The refund lookup known as twice, the assured reply constructed on stale information — none of that journeys an alarm by itself. Logging tells you what occurred at every step. Tracing exhibits you ways these steps really related. Debugging is what turns that report into a solution as an alternative of a guess. Construct all three in earlier than an agent is dealing with something that really issues, not after the primary buyer notices one thing went fallacious.