

What’s JEV, and the place and why you want it
Think about you might be constructing a robotic to type mail. You give it a set of straightforward guidelines: if the envelope is small, put it within the “letters” bin; if the envelope is massive, put it within the “packages” bin. That is how conventional laptop programming works. It depends on precise, inflexible guidelines that people write, often within the type of “if-then” statements. Nonetheless, the world is messy, and numerous data doesn’t match neatly into these inflexible guidelines. What occurs when the robotic receives a postcard, a unusually formed padded envelope, or a letter that bought crumpled in transit? The strict “if-then” guidelines fail as a result of they can not perceive the context or nuance of the thing.
To unravel this downside of messy data, programmers began utilizing massive language fashions, like those that energy widespread chatbots. These fashions are extremely sensible and may perceive advanced language, nuance, and intent. As a substitute of a inflexible rule, you possibly can merely ask the mannequin, “What sort of mail is that this?” and it’ll present a considerate reply. However there’s a catch: these massive fashions function like a human having a sluggish, deliberate thought course of. If you happen to ask the chatbot in regards to the mail, it’d reply, “Based mostly on the size and the presence of a stamp, I imagine this merchandise is a letter. Due to this fact, it’s best to place it within the letters bin.” Any such sluggish, reasoned considering is improbable for writing essays or fixing advanced issues, however it’s a horrible approach to shortly type hundreds of items of mail. The robotic has to attend for the entire paragraph to be generated, learn it, after which attempt to extract the precise choice from the center of a sentence. This course of is sluggish, unpredictable, and liable to breaking if the mannequin modifications its phrasing even barely.
This brings us to a basic divide in how AI can assume, just like how human brains work. Psychologist Daniel Kahneman described two techniques of human thought: System 1 and System 2. System 2 is the sluggish, deliberate, reasoning a part of the mind you employ to unravel a math downside or write a fancy essay. That is precisely how most trendy chatbots function; they generate textual content step-by-step to reach at a conclusion. System 1, then again, is quick, automated, and intuitive. It’s the a part of your mind that immediately acknowledges a good friend’s face or is aware of {that a} range is scorching. Till very lately, AI struggled to have a real System 1 course of. Builders had been compelled to make use of sluggish, chatty System 2 fashions for the whole lot, even easy, split-second selections. Kahneman wrote this image of human considering in Pondering, Quick and Gradual (2011). Right here it’s an analogy: one sort of program writes its reply out slowly, and one other sort judges in a single step.
That is the place Jev is available in. Jev is an AI mannequin particularly designed to behave as a System 1 engine for laptop applications. As a substitute of producing paragraphs of textual content, Jev is constructed to have a look at a chunk of messy data and immediately return a clear, structured choice. It takes the intelligence and understanding of a big language mannequin however strips away the conversational facet. As a substitute of claiming, “I imagine it is a letter,” Jev merely outputs a direct, machine-readable command like [CATEGORY: LETTER, CONFIDENCE: 98%]. As a result of it doesn’t must generate conversational fluff, it makes selections extremely shortly.
The principle benefit of Jev is that it permits builders to construct “sensible if-statements.” It acts as a bridge between the inflexible, quick world of conventional programming and the sensible, messy world of AI. In your day by day life as a developer, you want this sort of quick decision-making in every single place. Think about a buyer assist system that receives a brand new message. Earlier than deciding which sluggish, costly AI agent to get up to deal with the request, it’s worthwhile to shortly decide if the message is an pressing technical downside, a billing query, or simply spam. You want a quick, deterministic change to route the data to the precise place. You can’t afford to attend for a chatbot to ponder the query; you want a System 1 choice engine to immediately classify and route the information. Jev offers that dependable, high-speed routing, making automated techniques a lot sooner, cheaper, and fewer liable to breaking when dealing with real-world data.
The structure of JEV
To grasp how Jev makes these lightning-fast selections, we first have to look below the hood of these conventional, chatty AI fashions. At their core, widespread AI chatbots are basically extremely superior autocomplete techniques. For individuals who are unfamiliar with transformer structure: while you give them a immediate, they don’t really “assume” a couple of full reply . As a substitute, they have a look at your sentence, calculate the almost definitely subsequent phrase (in type of tokens), and print it out. Then, they have a look at your authentic sentence plus that new phrase, and calculate the subsequent phrase after that. This step-by-step guessing sport is named “autoregressive technology,” and it occurs on a steady loop till the AI lastly guesses a stopping phrase. Whereas this looping course of is good for writing a poem or a pc program, it creates a large velocity restrict. If you happen to simply need the AI to let you know if an e mail is spam, it nonetheless has to spin that guessing loop repeatedly simply to piece collectively the sentence, “This e mail seems to be spam.”
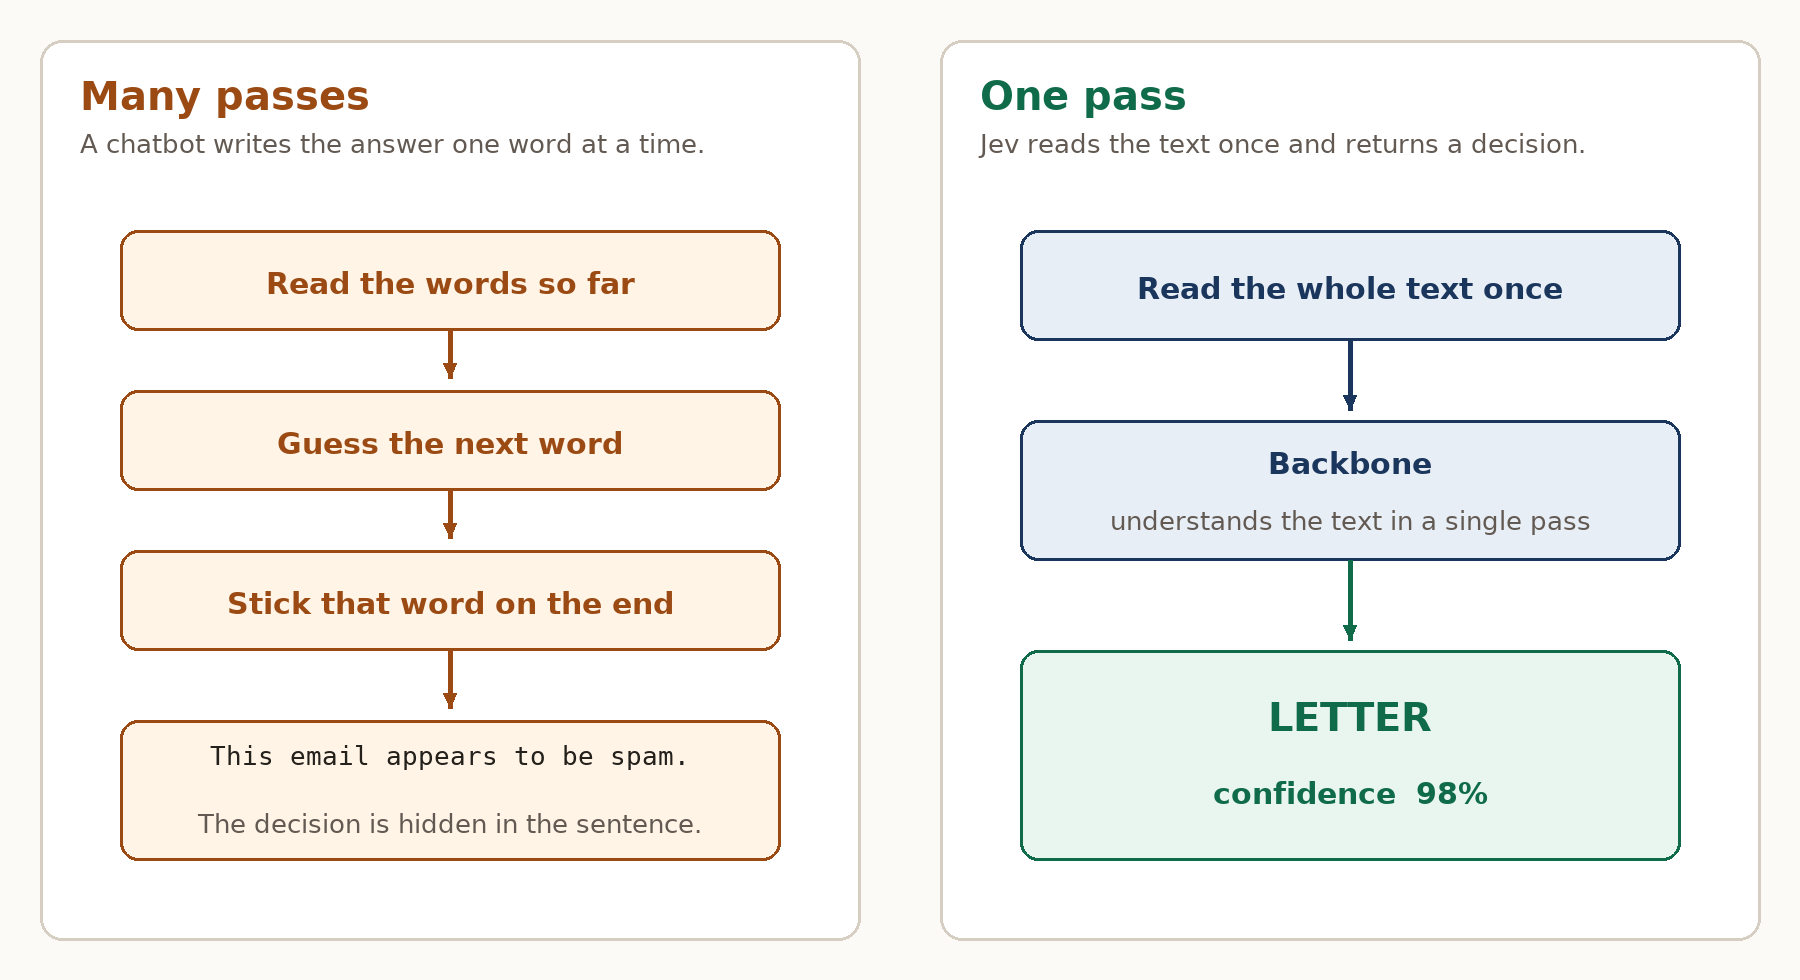
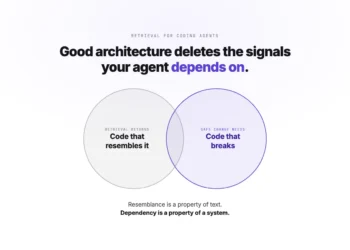
Diagram of autoregressive technology subsequent to a single ahead cross that emits a class and a confidence.
A chatbot guesses the subsequent phrase repeatedly. Jev reads the textual content as soon as and returns a choice.
Since this steady loop is the bottleneck, creating a quick System 1 engine requires utterly altering how the mannequin delivers its remaining reply. To do that, engineers have a look at an AI mannequin as having two distinct elements: a “spine” and a “head.” The spine is the huge, underlying community that truly understands human language, context, and nuance. It has learn tens of millions of books and web sites to learn the way phrases relate to one another. On prime of this spine sits the top, which is the precise half answerable for taking all that deep understanding and translating it right into a remaining output. In a typical chatbot, the top is particularly designed to play that sluggish word-guessing sport. However the great thing about trendy AI structure is that these heads are interchangeable.
To rework a sluggish, chatbot kind of AI into a quick Jev engine, builders carry out a sort of digital mind surgical procedure: they take away the word-guessing head solely. The deep language understanding within the spine stays utterly untouched, that means the AI nonetheless comprehends all of the messy nuances of the human textual content it reads. Nonetheless, as an alternative of attaching a head that generates phrases one after the other, engineers connect a “classification head.” This new head is constructed for a totally completely different job. As a substitute of looping repeatedly to string a sentence collectively, the classification head is designed to have a look at the AI’s understanding of the textual content and immediately push out a mathematical rating throughout a couple of predefined classes, comparable to “True,” “False,” or “Spam.”
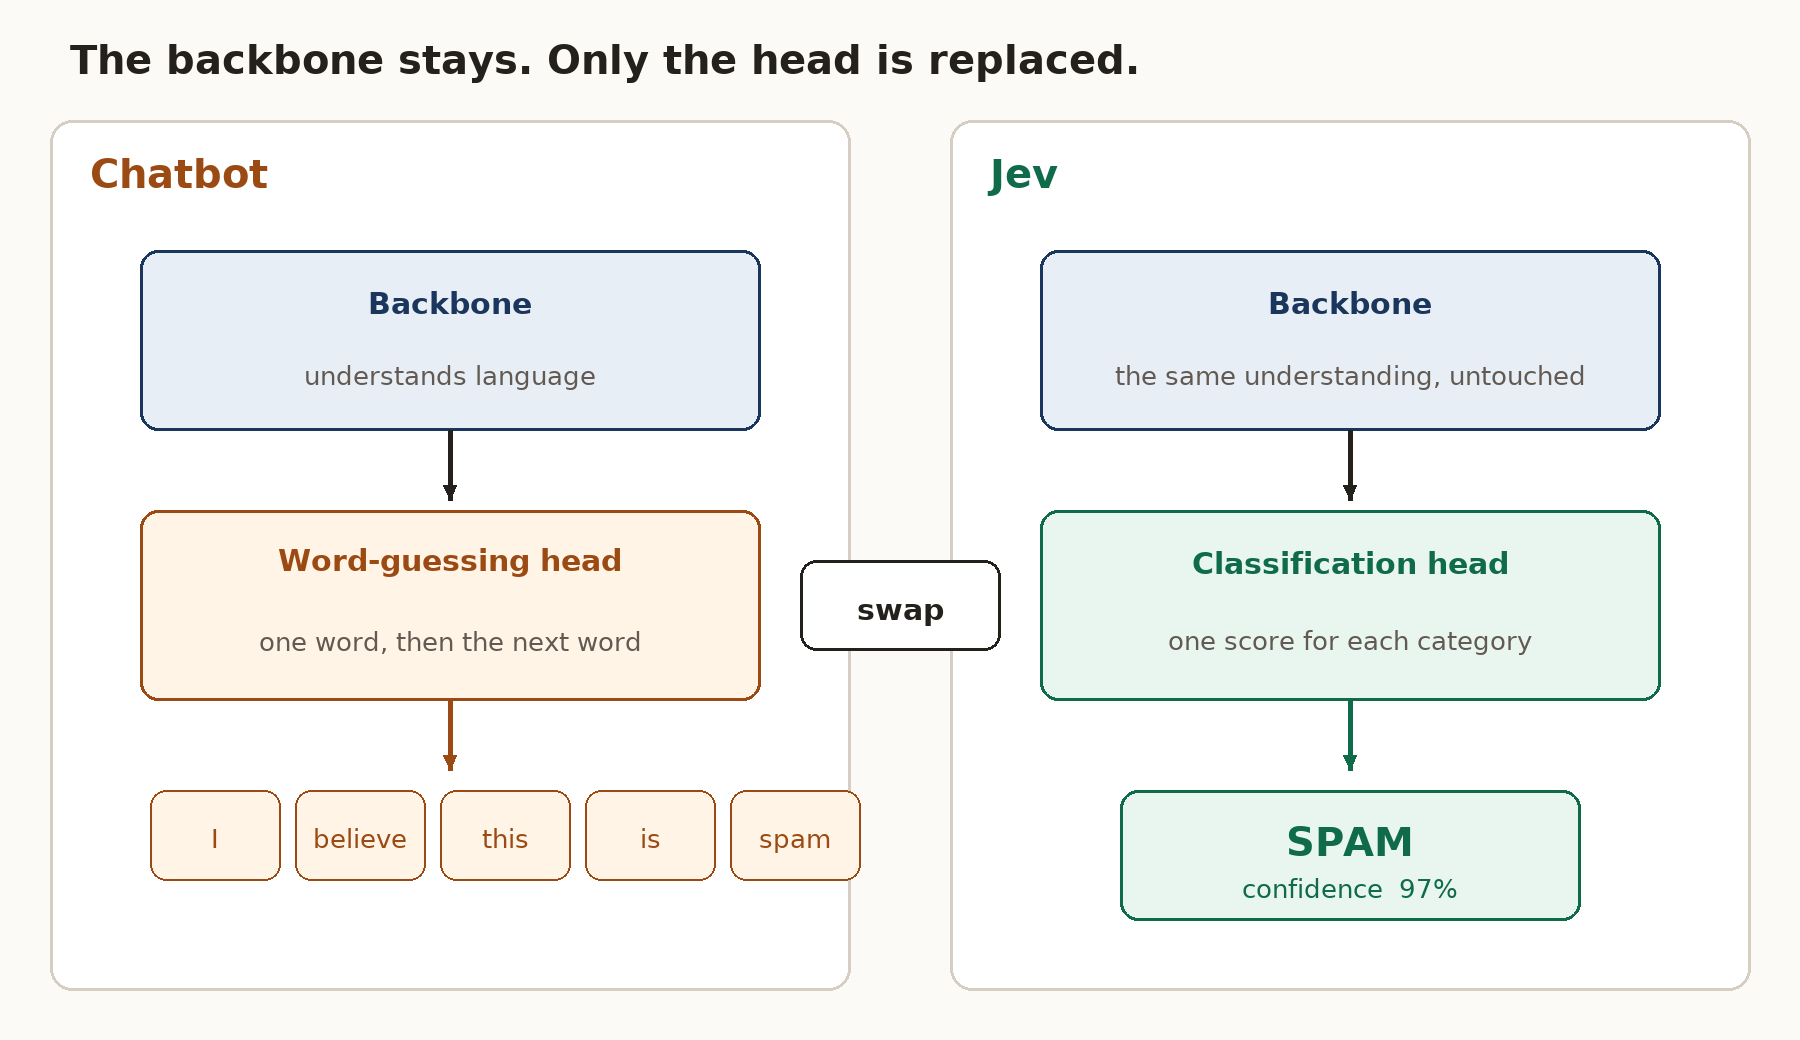
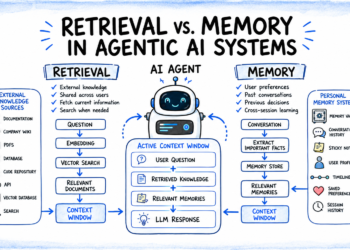
Diagram of the top swap. The language spine is unchanged. The word-guessing head is changed by a classification head.
The spine is identical on each side. The chatbot head guesses phrases. The Jev head returns one rating per class.
By swapping the top, the complete bodily operation of the AI modifications from a sluggish loop to a single, lightning-fast cross. While you feed a chunk of textual content into this newly constructed Jev mannequin, the spine processes the context . Then, the brand new classification head acts like a funnel, forcing that wealthy understanding straight right into a remaining choice with out ever producing a single phrase. As a result of the pc solely has to run by means of its community precisely one time, fairly than looping time and again for each phrase, the choice is made in a fraction of a second. This architectural shift from a looping word-guesser to a single-pass evaluator is the key to Jev’s velocity. It turns a conversational thinker right into a extremely environment friendly, dependable change that conventional software program can rely on immediately.
Implement a {custom} JEV from open-weight fashions
Understanding this bodily head swap is step one towards constructing your individual System 1 engine at residence. To start this building, you want an open-source spine to function your basis. For individuals who have no idea, a mannequin named Qwen is a superb candidate for this job. Created as a household of open-source AI fashions, Qwen is available in very small, light-weight sizes that may simply run on a standard laptop fairly than a large information middle. Because you need your choice engine to be extremely quick and native, beginning with a compact model of Qwen offers the proper steadiness of deep language understanding and speedy efficiency. The one used right here is Qwen2.5-Coder-1.5B-Instruct. It’s small, and it already understands code, which issues for the demonstration on the finish.
The undertaking that follows is three small scripts: mannequin.py, prepare.py, and check_names.py. They want a couple of peculiar Python packages.
Loading Qwen is the obtain. A tokenizer turns your textual content into the small items the mannequin is aware of how one can learn. AutoModel asks for the spine alone. The downloaded bundle nonetheless incorporates the word-guessing head. This name merely doesn’t choose it up. The primary run fetches the information from Hugging Face. Later runs reuse the copy already in your machine.
After getting downloaded your compact Qwen mannequin, you should carry out the digital mind surgical procedure talked about earlier. On this planet of programming, fashions like Qwen are downloaded as a bundle of code and mathematical weights. By default, this bundle contains the word-guessing head, which is often labeled within the code as a language modeling software. You could write a script to load solely the underlying spine, leaving that sluggish word-guessing head behind. As a replacement, you connect a brand new, empty piece of code designed strictly for classification. This new classification head acts as a clean slate, able to output precise mathematical scores for classes like “Sure,” “No,” or “Impartial.”
Right here is that clean slate. The spine is locked: requires_grad = False means these numbers are usually not allowed to alter. self.rating is the brand new head. It has two scores, as a result of this tutorial makes use of two classes, match and mismatch. The width of the top matches the width of the spine’s understanding, so the 2 items can join.
ahead is the one cross. The spine reads the entire snippet from left to proper. By the final actual phrase, it has seen the whole lot, so the top appears to be like solely at that spot and pushes out its two scores. torch.no_grad() tells the pc to not hold notes for altering the spine. Solely the small head is allowed to be taught. No phrase is written out.
Though the spine already understands human language completely, this newly hooked up head is solely untrained. It doesn’t but know how one can join the AI’s deep understanding to your particular classes. To bridge this hole, you should present the mannequin with a transparent set of examples, which programmers name a coaching dataset. In order for you your {custom} Jev to route emails, you’ll present it hundreds of examples of textual content paired with the proper class, comparable to declaring which messages are spam and that are pressing. Throughout this coaching course of, the huge spine stays principally frozen and unchanged, whereas solely the small, new classification head learns how one can map the data into your precise guidelines.
A mailbox router may want hundreds of rows. The form of the lesson is identical with a small desk, so this tutorial makes use of a couple of dozen brief Python capabilities. The label is match when the identify agrees with the physique, and mismatch when it doesn’t. The identical identify seems each methods, so the top has to learn the physique. It can not cheat by treating the phrase add as at all times flawed.
These rows dwell in information/names.csv. One command teaches the top and saves solely that small piece to artifacts/jev_head.pt. The spine stays the place Hugging Face put it.
The guts of prepare.py is brief. Evaluate the top’s two scores with the true label, then take a small step that updates the top alone.
mannequin.rating.parameters() is the brief checklist of numbers allowed to maneuver. The spine is just not on that checklist. When the run finishes, the script prints what number of numbers had been trainable. You need to see a couple of thousand, towards the billion-plus that belong to Qwen and stayed frozen.
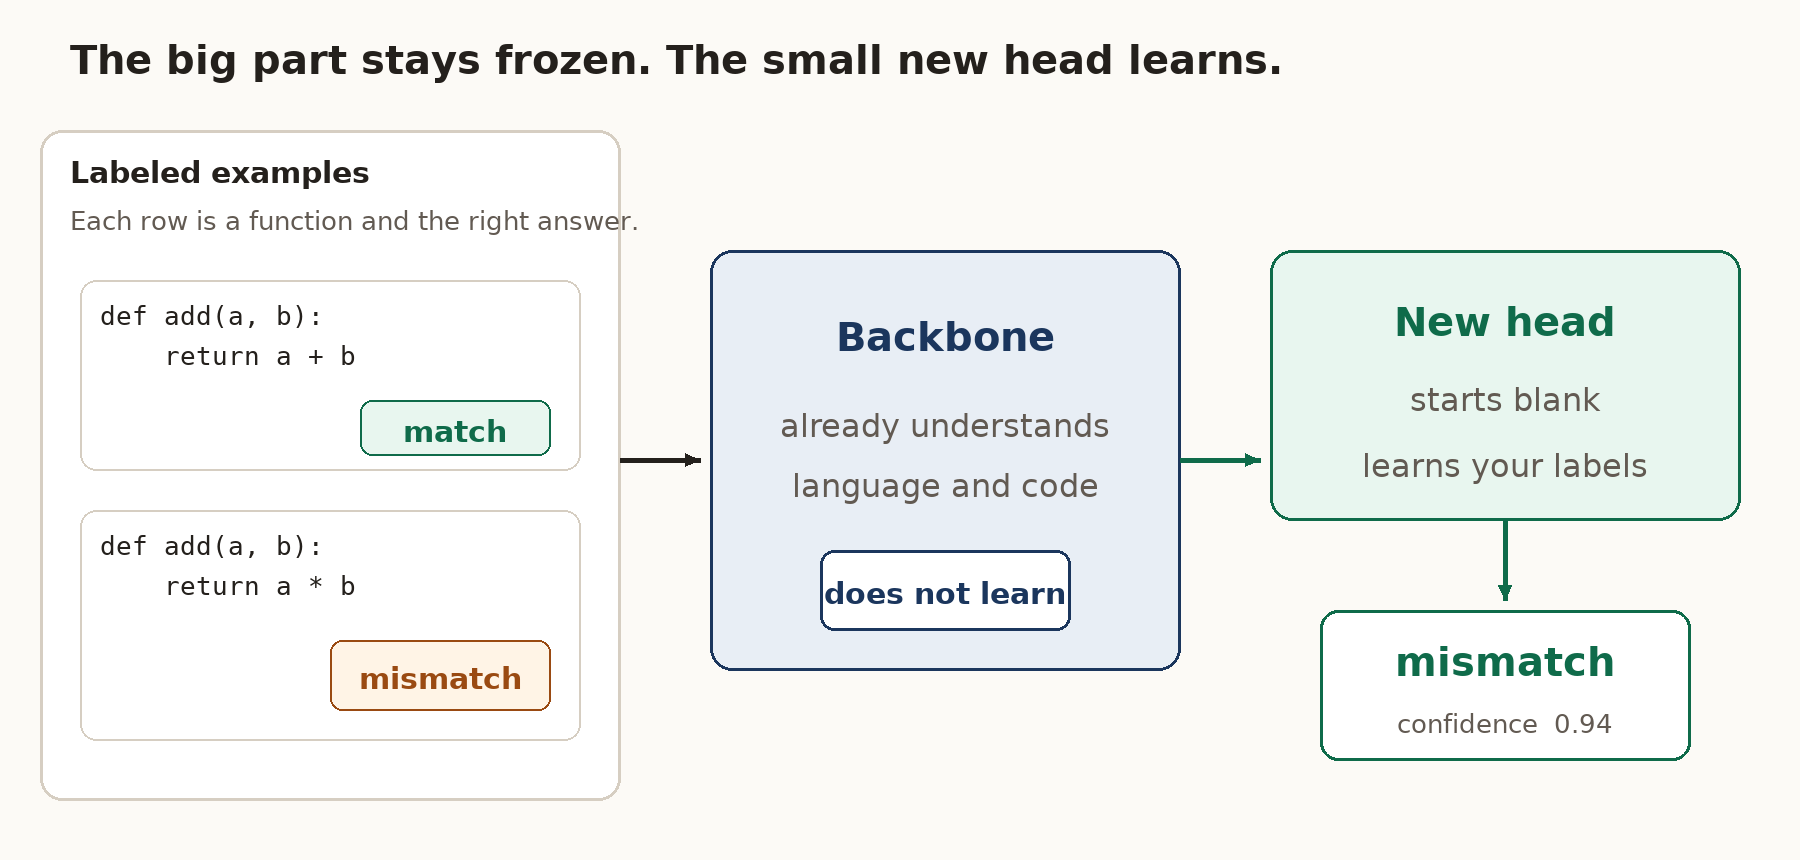
Coaching diagram. Instance capabilities carry the precise solutions. The Qwen spine stays frozen. Solely the brand new classification head is up to date.
The examples carry the precise solutions. The spine doesn’t be taught. The brand new head does, and it solutions with a label and a confidence.
After this coaching is full, there’s one remaining step required to make the mannequin actually helpful for day by day duties. Since AI fashions eat a large quantity of laptop reminiscence, working even a compact Qwen mannequin repeatedly within the background can decelerate your total machine. To unravel this downside, builders use a mathematical trick known as quantization to shrink the bodily dimension of the mannequin. Quantization is like taking a large, high-resolution {photograph} and compressing it right into a smaller file dimension; it’d lose a microscopic quantity of element, but it nonetheless clearly reveals the image whereas taking on a fraction of the cupboard space. By compressing your new, custom-built Jev engine, you guarantee it could actually sit quietly in your laptop’s reminiscence, immediately able to route and determine with out ever slowing down your different necessary software program.
quantize.py is that step. It packs the massive linear layers of the spine right down to 8-bit integers and prints what number of gigabytes you had earlier than and after. This explicit packing runs on the CPU, ranging from the peculiar 32-bit copy of the spine. In a single run that replicate fell from 6.17 GB to 0.93 GB, and def add(a, b): return a * b nonetheless got here again mismatch. The identify verify within the subsequent part nonetheless masses the peculiar spine, so the desk there stays simple to match by yourself machine.
A helpful instance demonstration to your day by day use
Think about you’ve simply completed a small Python file. It is filled with little helpers: add, subtract, is_even, most, and others like them. You wrote them shortly. A couple of of the names don’t inform the reality in regards to the physique beneath them.
add multiplies. is_even checks for an odd quantity. most returns the smaller of the 2 numbers. The file remains to be legitimate Python. Nothing is spelled flawed. There is no such thing as a peculiar if-then rule for this, as a result of the rule must perceive what the identify means and what the physique does.
The entire file is sample_module.py. It has 27 capabilities. Most of them are trustworthy. subtract actually subtracts. is_odd actually checks for odd numbers. Blended in with these are the dishonest ones, plus one peculiar leftover, so you possibly can see what a standard editor notices:
Open that file in VS Code with the Python extension turned on, and have a look at the Issues checklist. The checklist can see the unused import on the prime of the file, and it could actually see unused_note, the scratch line that nothing ever reads. It doesn’t checklist add, is_even, or most. These names disagree with their our bodies, and the editor has no verify for that.
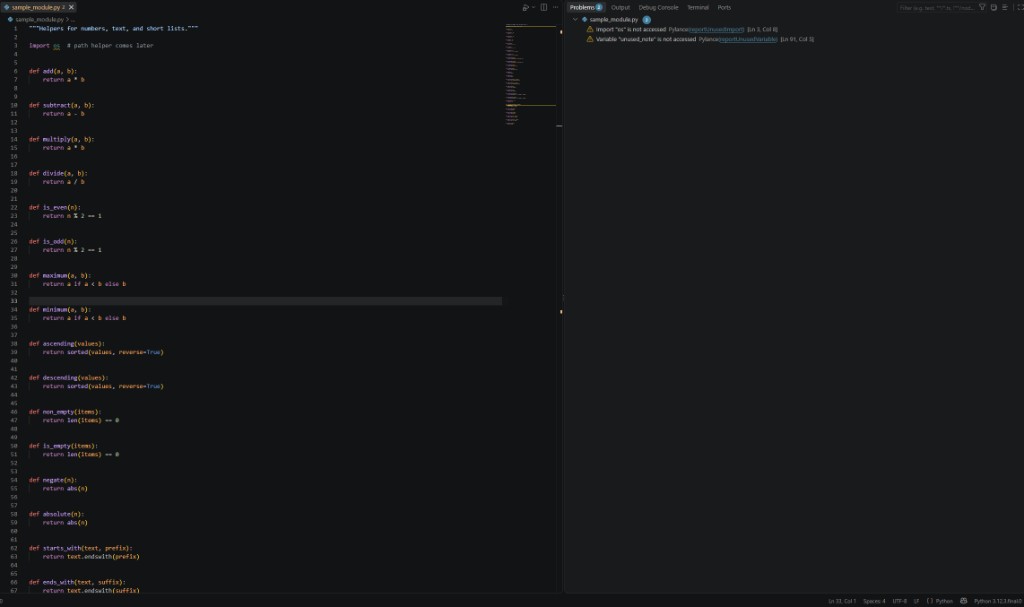
The Issues checklist names the unused import and unused_note. It doesn’t identify add, is_even, or most.
check_names.py is the sensible if-statement. It splits the file into capabilities, provides every one to the educated head, and prints a label with a confidence. It by no means writes a sentence. It solely reads capabilities written on the prime of the file. A operate hiding inside one other operate, or a way sitting on a category, is left alone.
A couple of of the traces appear like this. The complete run flags 10 of the 27 capabilities.
rectangle_area comes again as a match, regardless that the editor complains in regards to the scratch observe. That’s the break up between the 2 instruments. The editor enforces guidelines you possibly can write down, comparable to “this identify isn’t used.” Jev solutions a messier query: does this identify imply what this physique does?
You should utilize the identical command on a module you simply completed.
This system’s exit standing is the change a bigger software can hearken to. Standing 1 means at the least one identify didn’t agree with its physique. Standing 0 means the top agreed with each operate it learn. Put that command within the verify that runs earlier than a commit, and the file is judged in a single cross earlier than you share it. Coaching occurs as soon as. After artifacts/jev_head.pt exists, checking a file solely makes use of the saved head.
···
To entry the entire code for this tutorial, together with the coaching desk, the demo file, and the scripts that load Qwen and prepare the top, go to https://github.com/AnubhabBanerjee/Qwen-jev. All pictures created by the writer.