I spent years learning normal relativity concept because the starting of my PhD scholar life. One of many issues that make GR completely different from traditional mechanics is:
Coordinates are usually not distances.
In GR, you write down coordinates for occasions. However the distance between two occasions is not a perform of their coordinates alone. As an alternative, it would depend upon the metric, which varies from place to position. This put up is about an experiment I designed to search for that distinction inside a language mannequin. It is geared toward anybody who works with transformers and has puzzled whether or not the usual positional encoding captures “place” the way in which our instinct says it ought to. No physics background required because the relativity dialogue is an analogy.
Sooner or later I began questioning whether or not something like that distinction exhibits up inside a language mannequin.
Two paragraphs that look the identical
Now contemplate two texts:
and
A tokenizer would see these as almost the identical enter — similar phrases, similar order, with solely a newline when the paragraph break falls. However you do not. The second model has a pause, a change of native context, a way that what comes subsequent is a brand new unit. It appears like the 2 sentences are additional aside than their token distance suggests.
The query I wished to ask was slim: in case you give a transformer an express paragraph coordinate — separate from the token index — does its consideration change in some way? And if it does, does the change have a form?
Place as a coordinate, and why that is lossy
A normal transformer encodes place as a single quantity: the token’s index within the studying order. RoPE rotates every channel pair by an angle proportional to this index. ALiBi provides a bias proportional to it. Completely different mechanisms, similar object. They work as a result of studying order determines token distances, and token distances are what consideration cares about.
However for us human readers, textual content is not a line. It is a tree or hierarchy construction:
Two tokens on the similar reading-order distance will be in the identical sentence, in numerous sentences of the identical paragraph, or in numerous paragraphs. Taking n tokens, the identical sequence admits 2^(n−1) paragraph segmentations.
So the usual positional encoding could be lossy: it tells the mannequin the place a token is within the sequence, however there may be nothing to with the hierarchy construction. A educated transformer would possibly get better some hierarchical construction implicitly from content material whereas the positional illustration doesn’t have that data
I wished to know what occurs if we do give it that data.
hRoPE: three coordinates as an alternative of 1
I constructed a hierarchical rotary positional encoding, hRoPE, that offers paragraph, sentence, and token indices their very own impartial channels. Every stage rotates its personal block of dimensions, and the blocks do not work together.
The purpose right here is separability. I can change the paragraph coordinate of a token whereas holding the whole lot else — its sentence index, its token index, the complete token sequence — precisely mounted.
I additionally educated a number of variants, matched in parameter rely, depth, schedule, and seeds. Two are the controls that matter:
-
rand_axial: an identical to the hierarchical mannequin, however the paragraph coordinate is a density-matched random label, resampled each coaching step so it could possibly by no means be memorized.
-
period_axial: an identical, however the paragraph coordinate is a mechanical periodic grid on the similar density because the true segmentation.
rand_axial isolates having an additional coordinate from that coordinate carrying actual data. period_axial isolates a coordinate correlated with token distance from one monitoring real boundaries.
The intervention
Now allow us to do two interventions:
-
fake-merge: assign two adjoining actual paragraphs the similar paragraph index p1. The boundary between them disappears from the mannequin’s view.
-
fake-split: assign two halves of 1 actual paragraph completely different p1 values. A boundary seems the place there wasn’t one.
Within the two settings above, we hold similar tokens, similar order, similar token-to-token distances, similar sentence boundaries. So, if consideration modifications, it modified solely due to p1.
To measure such change, we common consideration over layers and heads, take logs. We match the resulted common a linear development towards token distance, and have a look at the residual, which is, the a part of the eye sample that distance alone would not clarify.
The end result is identical in all three corpora (WikiText-2, OpenWebText, and Python supply code). Eradicating an actual boundary lowers cross-paragraph consideration. Inserting a faux boundary raises it. The 2 interventions push consideration in reverse instructions they usually show collectively that the paragraph impacts the eye.
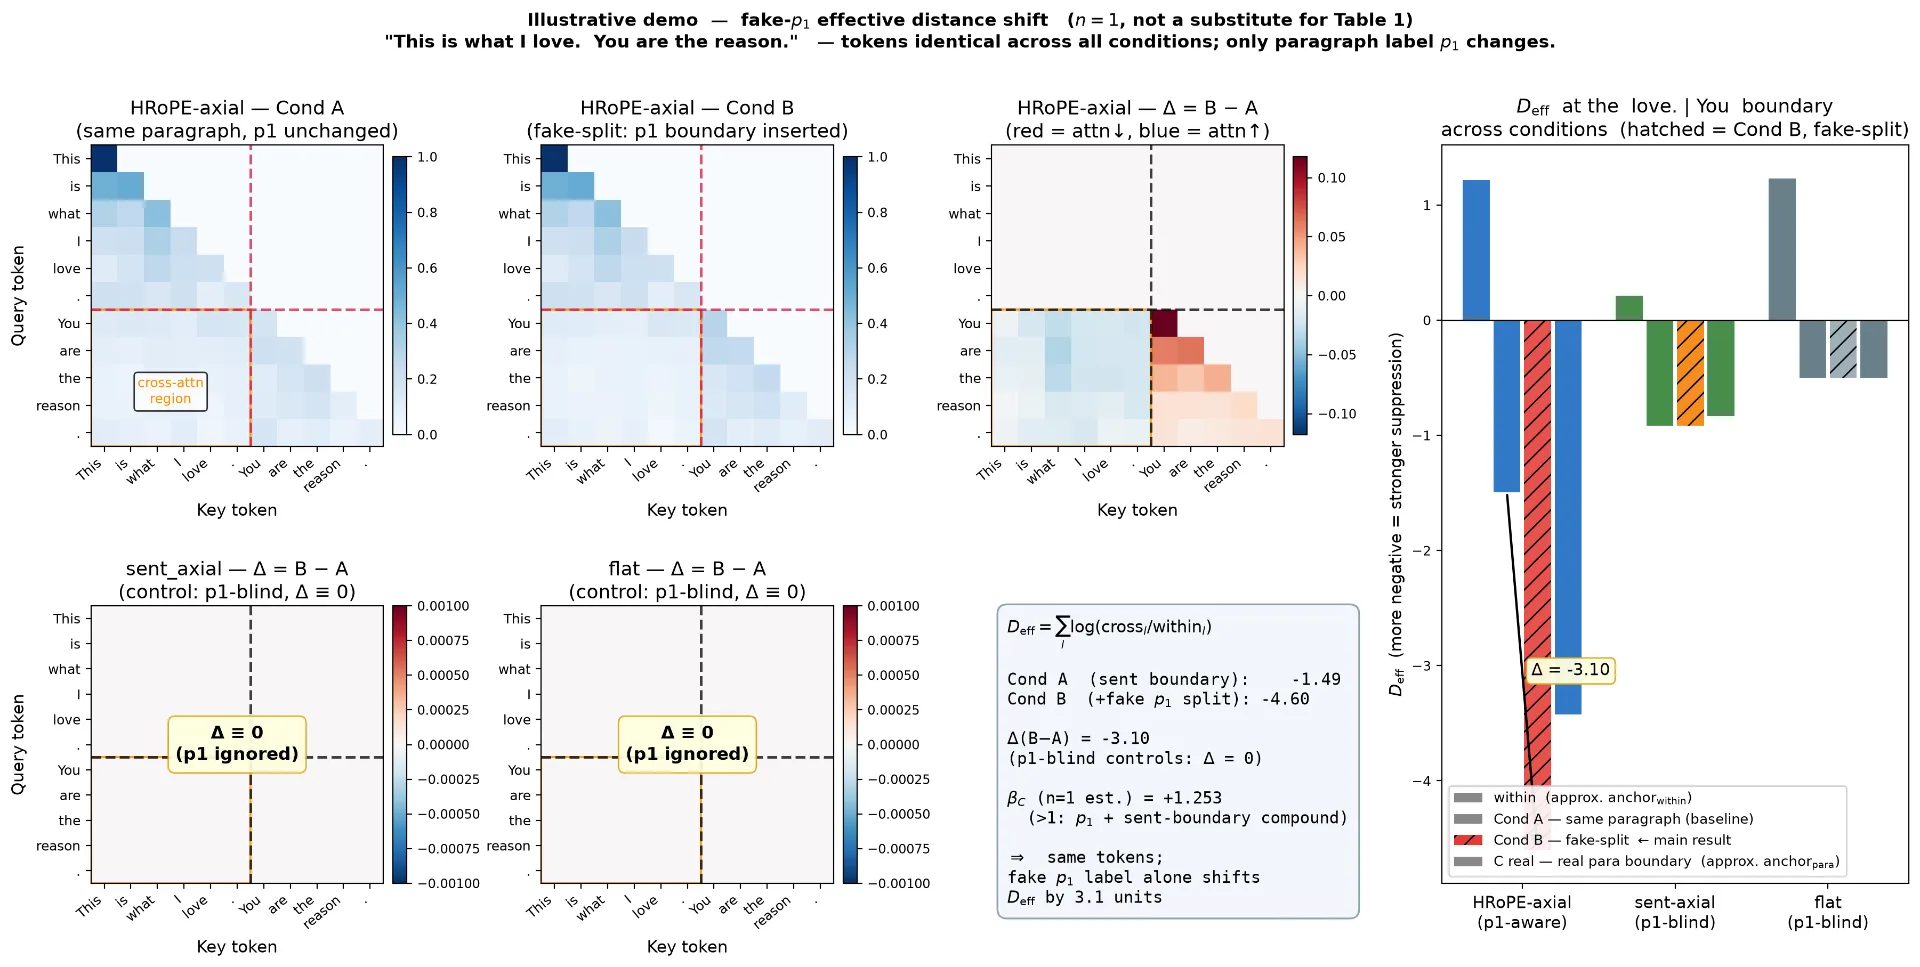
A single instance. We modified solely the paragraph label of “You” — not a single token — and a focus throughout the boundary dropped measurably.
The management that ruins the story
The mannequin whose paragraph index is a random one rand_axial, additionally modifications cross-paragraph consideration, in each corpus. The change is evidently weaker than the hierarchical mannequin’s, however it’s there.
So a change in cross-paragraph consideration isn’t by itself a signature of paragraph construction. Any channel with the appropriate density induces some change. My story doesn’t finish right here.
Depth is the sign
For each pair of tokens that sit in numerous paragraphs, we compute the additional suppression their consideration receives — past what token distance alone predicts. Then we plot that suppression towards paragraph displacement: what number of paragraph boundaries separate the 2 tokens.
For the true mannequin, the suppression grows with displacement as much as about 2–5 paragraphs, then shrinks once more — a properly. The depth of that properly, probably the most detrimental level on the curve, is what we name U*.
The desk under offers U* for 3 corpora. Unfavorable values point out compression. Each fashions compress in each corpus; what differs hrope_axial from rand_axial is the depth, and the depth is corpus-dependent for the true mannequin in a manner the management’s isn’t.
|
Code |
WikiText-2 |
OpenWebText |
|
|---|---|---|---|
|
hrope_axial |
−0.77 |
−0.48 |
−0.31 |
|
rand_axial |
−0.24 |
−0.22 |
−0.33 |
Two of three corpora present a transparent depth hole: Code and WikiText-2, the place the hierarchical mannequin compresses deeper than the management. OpenWebText is an exception, and I am going to come again to it. What issues past the 2 particular person gaps is that the depth itself behaves in a different way throughout corpora within the two rows. The management’s depths sit in a slim band — −0.22 to −0.33, a variety of about 0.11. The hierarchical mannequin’s span −0.31 to −0.77, a variety of about 0.46. The depth is corpus-sensitive for the true mannequin and almost corpus-blind for the management. That distinction, not any single row, is the primary trace that depth carries data.
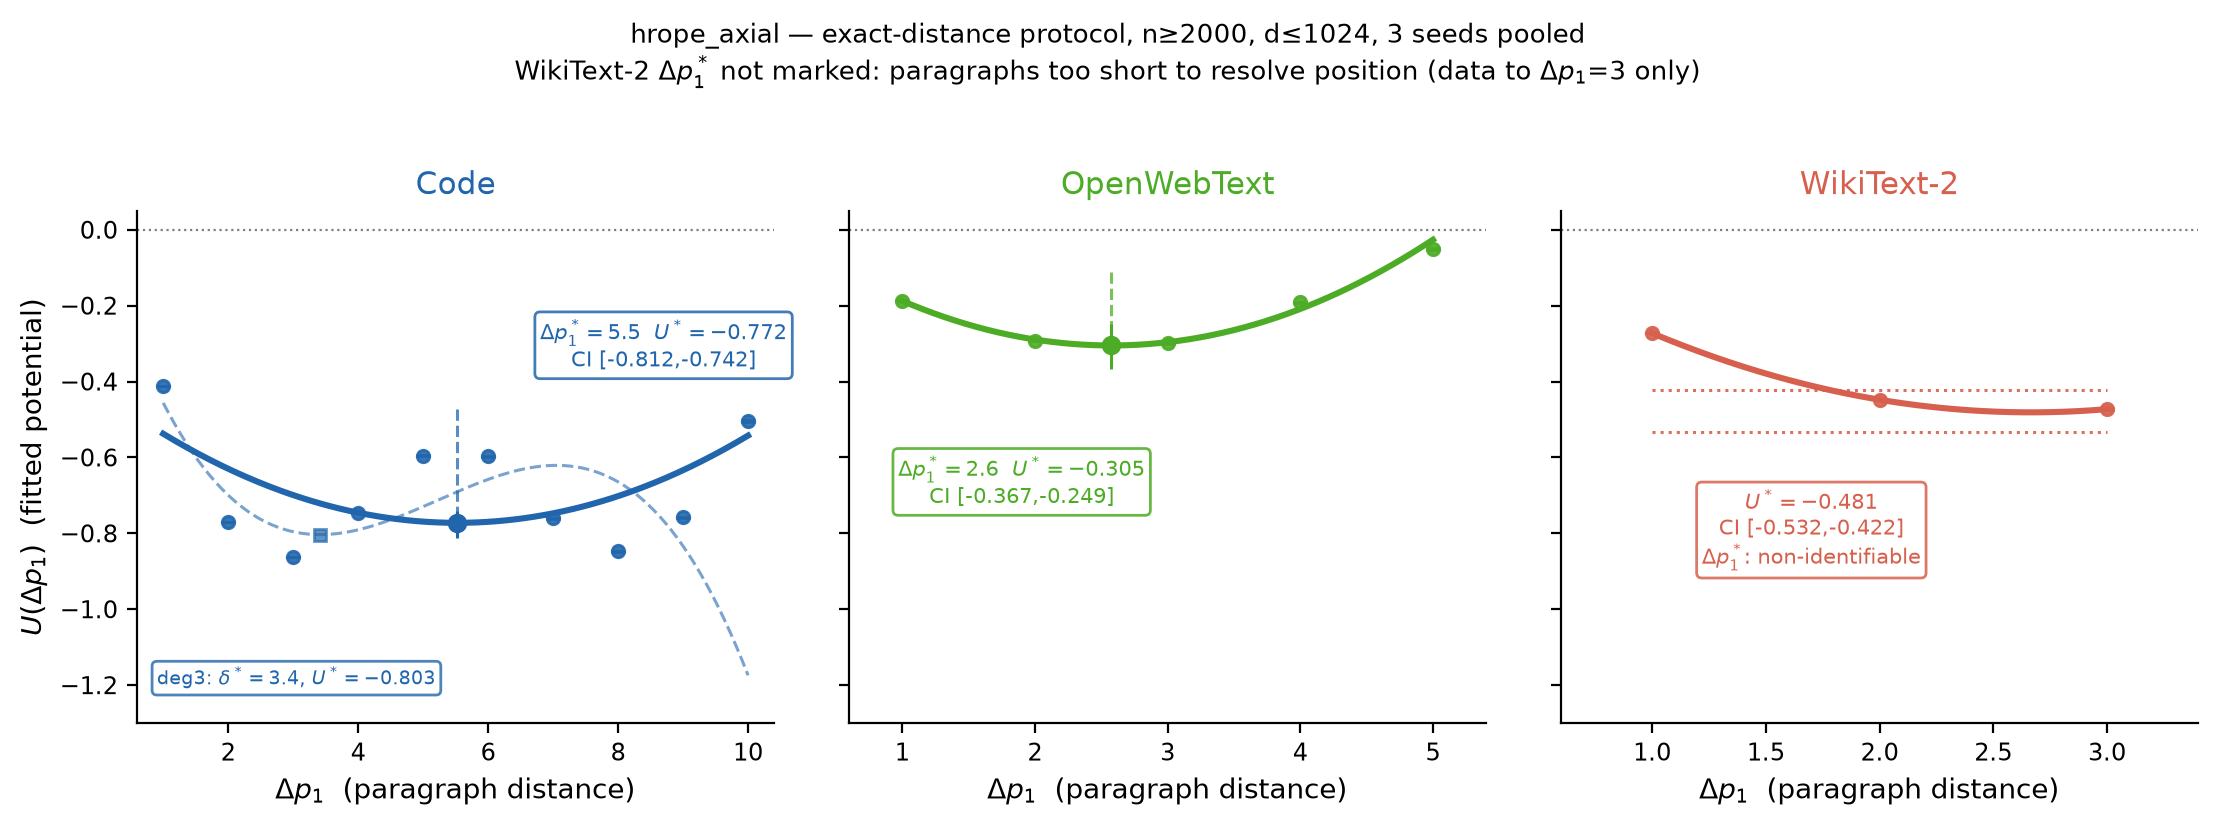
All three corpora present compression ($U<0$) somewhat than a mixture of compression and dilation
The causal take a look at
Cross-corpus correlation alone can’t be proof. So I ran a within-corpus take a look at: shuffle the order of paragraphs in every doc with similar content material, similar lengths keep, and the identical variety of paragraphs stays. Solely their order modifications.
The logic is: if depth displays real paragraph construction, shuffling ought to transfer it. If depth is an artifact of the channel’s density, shuffling ought to do nothing.
The end result seems:
-
hrope_axial: depth modifications in each corpus. Not at all times in the identical path — Code will get shallower, WikiText-2 and OpenWebText get deeper — however the impact is actual and reproducible.
-
rand_axial: depth modifications in no corpus. Each confidence interval consists of zero.
The shuffle modifications the enter for each fashions equally whereas the distinction is what the 2 fashions do with the paragraph coordinate. hrope_axial was educated on actual paragraph order, so shuffling that order strikes its depth. rand_axial was educated on a coordinate that was random from the beginning, so there’s nothing for the shuffle to disturb.
What would not work
I additionally tried to clarify the corpus-dependent depth utilizing corpus-only statistics — computed from uncooked textual content, no mannequin concerned. Three constructs, eight portions: lexical persistence, paragraph size, embedding-based coherence.
None totally reproduces the ordering of U*.
Lexical persistence will get Code proper and swaps the opposite two. Paragraph size swaps Code and WikiText-2. Embedding coherence comes closest — two of three corpus pairs — however leaves one unresolved. It is the candidate I might suggest following up, not a whole rationalization.
This can be a detrimental end result and I am reporting it anyway. The corpus-dependent depth is actual and causally tied to paragraph construction. What within the corpus determines that depth is open and I’m open to any dialogue.
The sincere caveat
As proven above, OpenWebText would not present a depth hole. Actual and random are statistically indistinguishable there. I am unable to separate a real null from an influence limitation on the seed rely I used. It is a corpus the place the depth comparability is not resolvable — not one the place the causal impact disappears. The shuffle take a look at nonetheless distinguishes actual from random there.
And for the dimensions: eight-layer fashions, 512 dimensions, three seeds, three corpora, I’ve restricted useful resource. The phenomenon is reproducible at this scale. Whether or not it persists at manufacturing scale isn’t one thing this paper solutions.
What I feel this implies — and what I do not
Here is the place the GR instinct comes again.
In GR, coordinates and distances are completely different objects. You label occasions with coordinates, however the metric — the factor that tells you how one can measure separation — is a perform of place, not a hard and fast rule. Two occasions with the identical coordinate distinction can have completely different correct distances.
The state of affairs I feel I am taking a look at is structurally comparable. The token index is a coordinate, actual for the linear sequence. However the “distance” that spotlight computes over would not cut back to coordinate distinction: two tokens on the similar coordinate separation appeal to completely different quantities of consideration relying on their hierarchical relationship.
Within the physics vocabulary: the positional coordinate isn’t the metric. The metric is dependent upon the coordinate and on the hierarchy. What I’ve measured is a bit of that dependence — particularly, how consideration weight varies with paragraph displacement, holding token distance mounted.
And when you’re in that body, “potential properly” stops being a metaphor. A properly is what you get whenever you plot efficient interplay towards separation and discover a minimal. That is what the compression curve seems like: a properly in paragraph-displacement house, whose depth is the signature.
The strongest assertion I can defend is that this: consideration reveals a structured, coordinate-dependent response subject over hierarchical textual place, whose qualitative form is in keeping with a metric-like dependence. The properly is actual within the sense that it is reproducible. It’s not actual within the sense that I’ve derived a geometry.
So, the sincere analogy is not “transformers are relativistic.” It is narrower: the coordinate that normal positional encodings provide isn’t the identical object as the space that spotlight really computes over.
What I might need subsequent
Two instructions:
-
Scale. Does the depth signature persist at 1B+ parameters?
-
Extra corpora. Three exhibits the sample exists and is causal; it is not sufficient to say what determines the depth.
The paper is on arXiv: 2609.23551. I might particularly like suggestions on the OpenWebText null.