Introduction
A standard downside with AI brokers is that their efficiency can appear worse after a change, with out anybody realizing what brought about it. The system immediate could have been modified, a instrument description could have been up to date, or the underlying mannequin could have moved to a unique model. Any of those adjustments can have an effect on how the agent behaves. And not using a constant technique to measure these adjustments, it’s simple to finish up guessing and repeating checks manually.
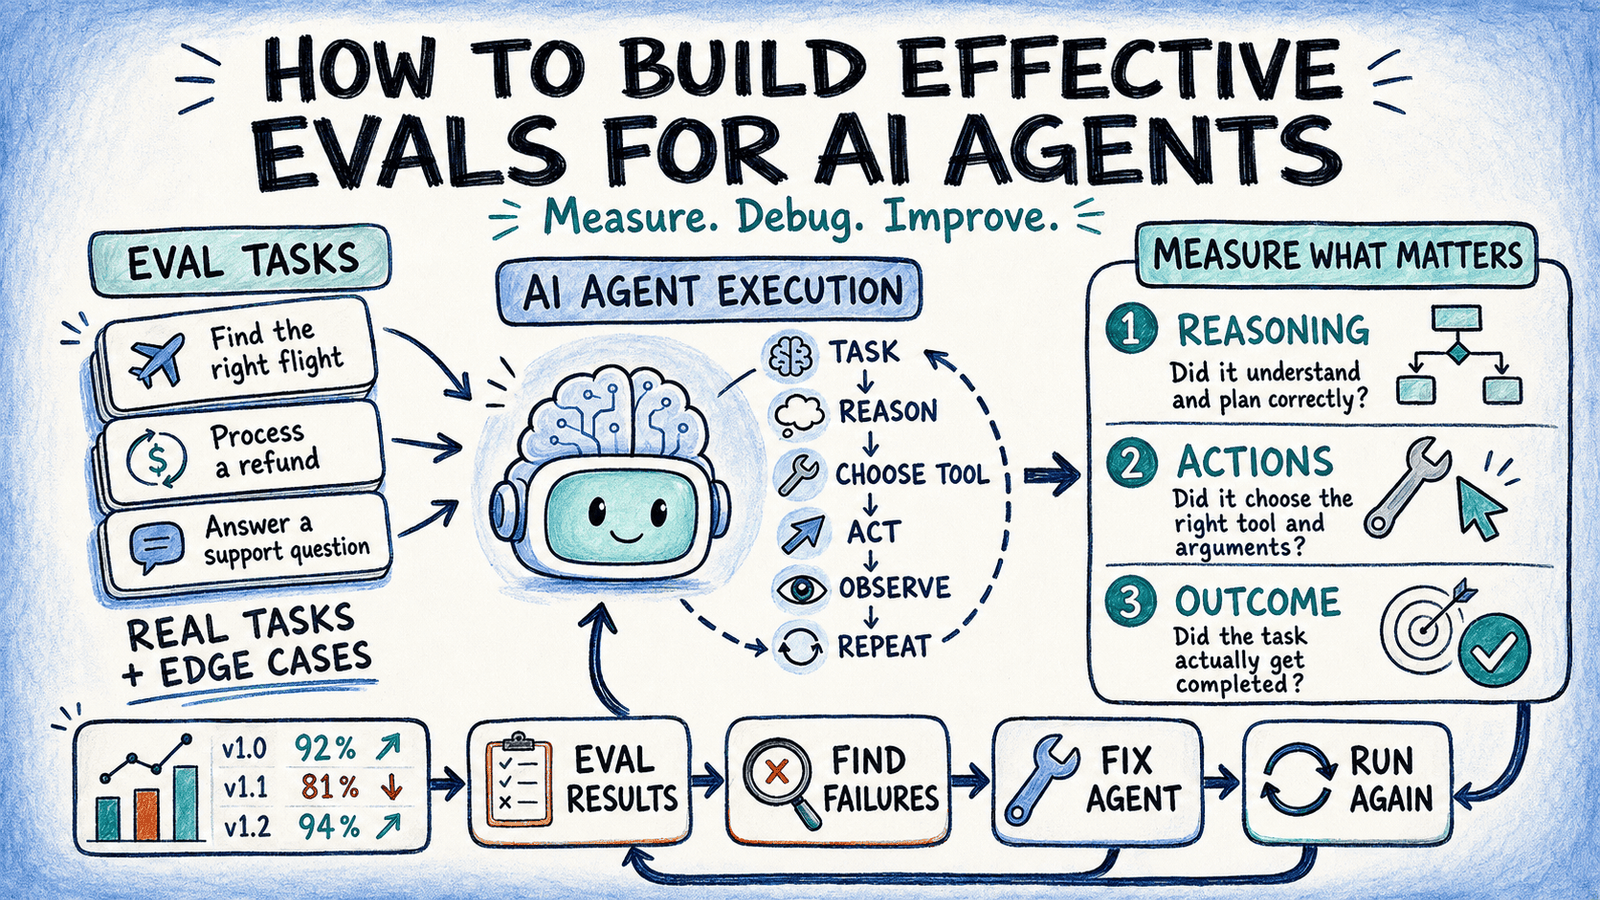
Evals present a technique to measure these adjustments. An eval provides an agent a job, runs it, and checks the outcome towards a set of outlined standards. The identical course of might be repeated throughout completely different variations and adjustments, making it simpler to identify variations. Relatively than making a broad or subjective declare about an agent’s conduct, you possibly can describe the particular, measurable change noticed. This offers you a transparent problem to analyze and a technique to verify whether or not a change improved the outcome.
This text covers:
- Why brokers are more durable to judge than single-turn LLM calls, and the way that impacts check design
- How one can discover and write eval duties with clear outcomes
- Which graders to make use of for reasoning, instrument calls, and remaining outcomes, and when to mix them
- How one can construct a harness that produces helpful outcomes with out pointless noise
- How evals match alongside monitoring
We’ll begin by what makes agent analysis completely different and the way that ought to form the best way you design checks.
Understanding Why Agent Evals Are Completely different
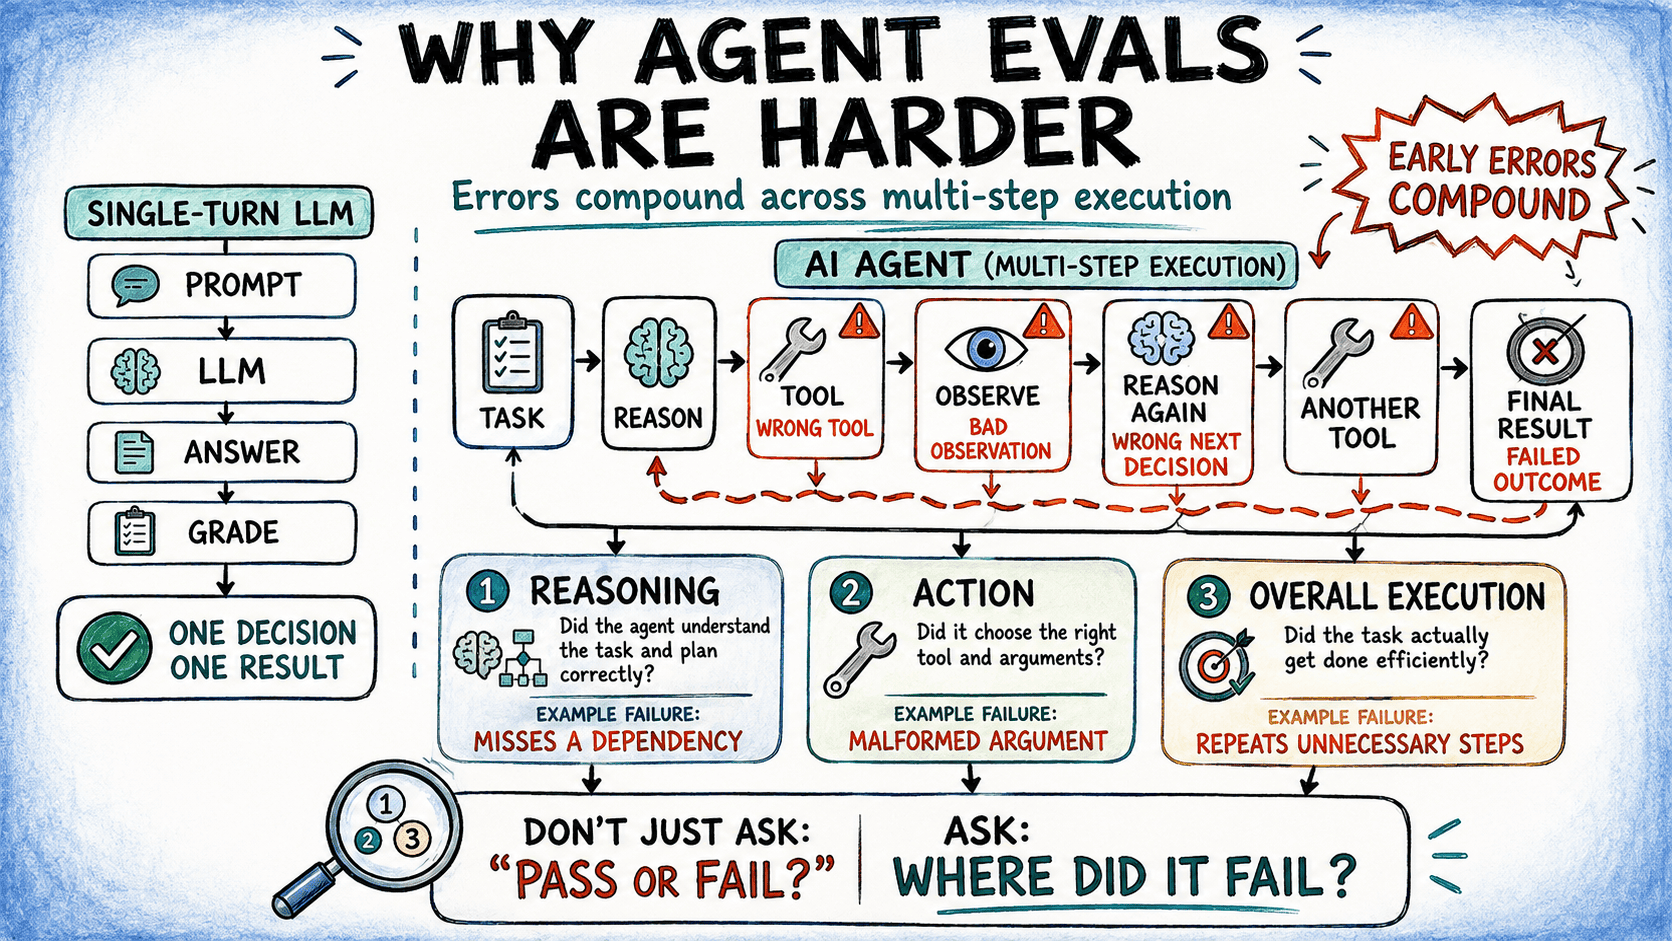
A single-turn eval is simple to cause about: one immediate, one response, a grader checks it towards an anticipated reply. Brokers break that mannequin. An agent causes a couple of job, picks a instrument, acts on it, observes the outcome, and repeats — typically for dozens of turns — and every step can go incorrect independently. A mistake early on adjustments the state each later step causes over, so errors compound as a substitute of staying remoted. This compounding is why it helps to consider an agent’s failures in layers reasonably than as one huge move/fail.
When evaluating an agent, it’s helpful to separate failures into three layers: reasoning, motion, and general execution. For instance, a travel-booking agent could fail by selecting the incorrect sequence of steps, utilizing a instrument incorrectly, or finishing the duty inefficiently.
| Layer | What it covers | A typical failure |
|---|---|---|
| Reasoning | Understanding the duty, breaking it into sub-steps, and choosing the proper order of operations | A journey agent tries to e book a flight earlier than checking whether or not the requested flight is obtainable |
| Motion | Deciding on the correct instrument, offering the proper arguments, and calling it on the proper level within the sequence | The agent makes use of the proper flight-search instrument however passes a metropolis title or airport code the API doesn’t acknowledge |
| General execution | Whether or not the duty was really accomplished, and the way effectively | The agent ultimately books the flight, however calls the identical search instrument thrice for info it already had |
A great eval, due to this fact, ought to inform you which layer failed, not simply that the duty failed.
Frontier fashions additionally make static grading more durable. Given sufficient autonomy, an agent could uncover a legitimate resolution that no person anticipated when the duty was written. A inflexible grader would possibly mark that as a failure though the agent solved the consumer’s downside higher than the anticipated path. Good graders ought to due to this fact consider the end result and the reasonableness of the method, reasonably than requiring one precise sequence of steps.
Sourcing Duties for Your First Eval Set
You do not want lots of of duties to start out. A handful of targeted duties are sometimes sufficient to catch significant adjustments early. It is also simpler to show clear necessities into check instances earlier than the system turns into extra complicated.
The quickest technique to construct your first eval set is to make use of the checks you already carry out manually: widespread workflows, recognized edge instances, and situations you check earlier than a launch. Flip these into repeatable duties as a substitute of testing them from scratch every time.
Hold the set balanced. Embrace instances the place a conduct is anticipated and instances the place it isn’t. For instance, a search eval ought to check each queries that require search and queries that may be answered with out it. This helps measure whether or not the agent is making the correct choice, not merely repeating the identical motion.
Writing Clear, Testable Duties
A great eval job ought to have clear, goal success standards. Two folks reviewing the identical outcome ought to have the ability to attain the identical conclusion about whether or not the agent handed. If the duty is imprecise or leaves necessary particulars open to interpretation, the grader could measure the anomaly reasonably than the agent.
Earlier than including a job, verify that the directions include every thing wanted to finish it. If the grader assumes info that the duty doesn’t present, a failure could replicate the duty design reasonably than the agent.
A reference resolution helps validate each the duty and the grader. If a succesful agent constantly performs poorly, first verify whether or not the duty is solvable and whether or not the grader accurately acknowledges a legitimate outcome. This straightforward verify can stop deceptive analysis outcomes.
Selecting Graders for Every Layer
Not each a part of an agent’s conduct must be measured the identical method. The secret is to match the grader to the layer being evaluated:
| Grader kind | Good for | Predominant limitation |
|---|---|---|
| Deterministic (string match, check suite, database verify) | Quick, low cost, unambiguous outcomes | Not efficient towards legitimate variations it wasn’t constructed to acknowledge |
| Code-based (assertions, API checks, state validation, customized checks) | Useful conduct, instrument calls, structured outputs, and state adjustments | Requires dependable check logic and a well-controlled check surroundings |
| Mannequin-based (LLM scores the transcript towards a rubric) | Subjective or open-ended duties, freeform output | Wants common calibration towards human judgment |
| Human assessment | Judgment calls a script or mannequin should not make alone | Costly, gradual, exhausting to run at scale |
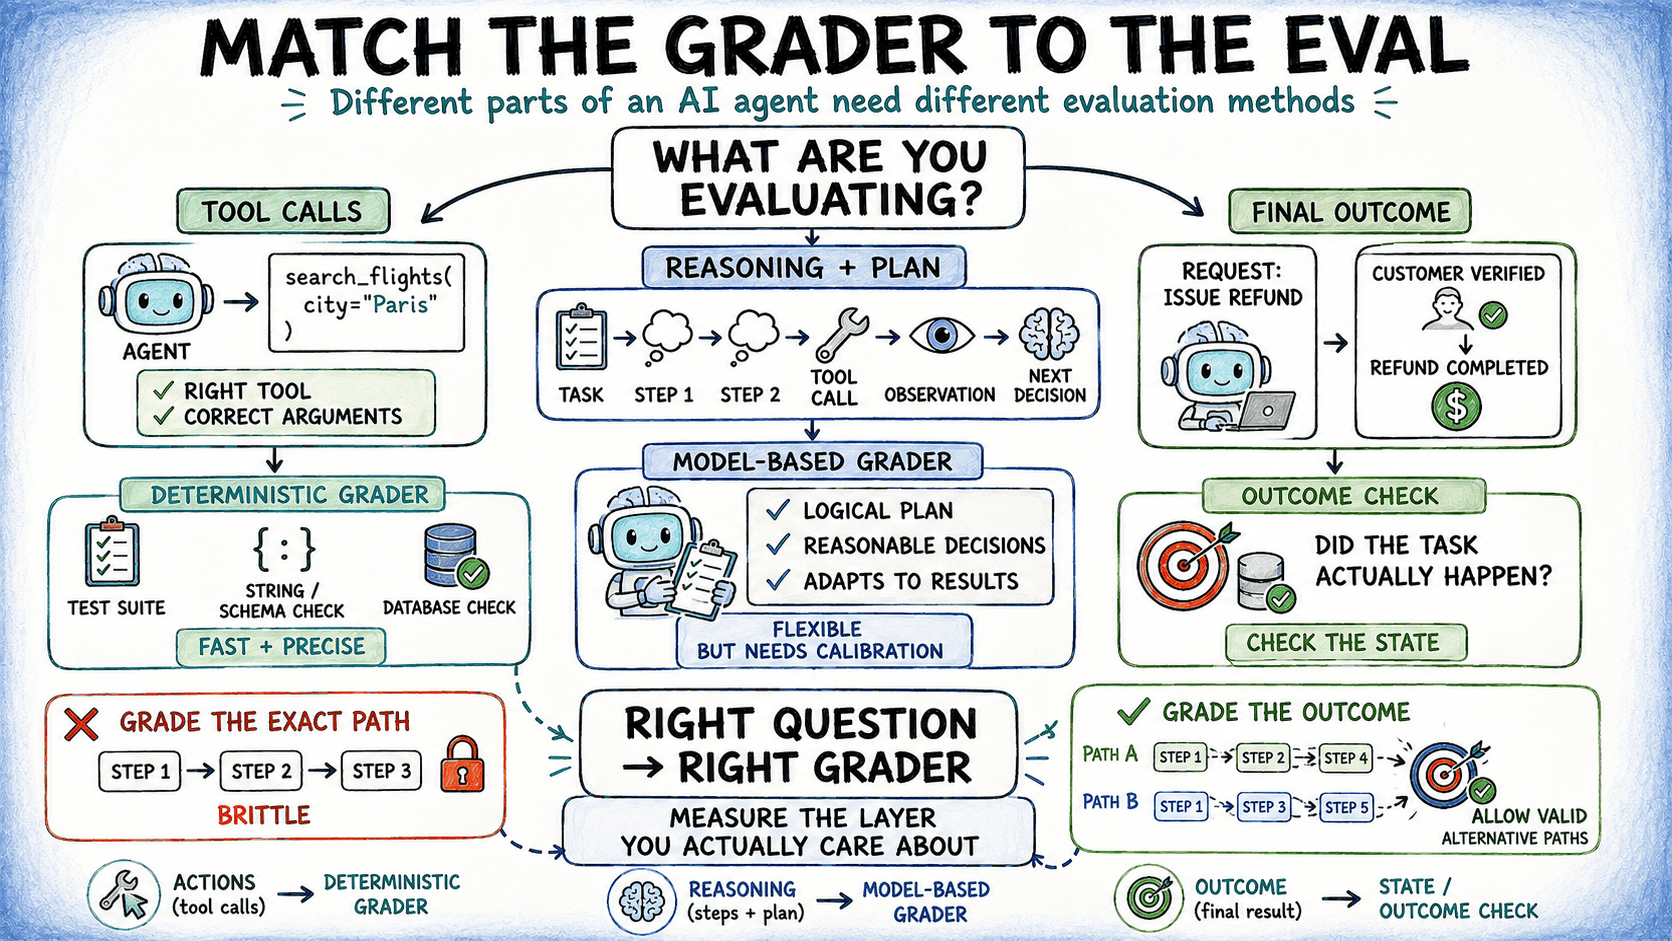
A helpful method to decide on a grader is to match it to what you really have to confirm. Completely different elements of an agent’s conduct name for various analysis strategies:
- Instrument choice and arguments: use deterministic or code-based checks on the level the place the decision is made.
- Plan high quality and adherence: consider the total hint when the sequence of choices issues.
- Activity completion: confirm the ensuing state immediately utilizing code, database checks, or system assertions reasonably than counting on the agent’s abstract.
- Open-ended outputs: use a model-based grader when there is no such thing as a easy anticipated reply.
- Complicated or ambiguous instances: use human assessment when automated grading can’t reliably make the judgment.
Keep away from grading the precise sequence of steps except the order is necessary. An agent could take a unique path and nonetheless produce the proper outcome. Grade the end result by default, and implement particular steps solely when they’re really required.
Constructing an Efficient Agent Harness
An eval is just as reliable as its surroundings. Each trial ought to begin clear and remoted. Leftover recordsdata, cached information, or shared historical past can skew outcomes and make an agent look higher or worse than it truly is.
Use partial credit score as a substitute of treating each job as move or fail. An agent that diagnoses the problem and verifies the shopper however misses the refund is clearly forward of 1 that misunderstands the request fully. Binary scoring hides that distinction.
You will need to deal with non-determinism as brokers not often produce the identical outcome twice, so one trial might be deceptive. Two helpful metrics are:
| Metric | What it measures | Greatest suited to |
|---|---|---|
| move@okay | Probability of not less than one success throughout okay makes an attempt | Duties the place ultimately discovering an answer is sufficient |
| move^okay | Probability that each one okay makes an attempt succeed | Buyer-facing brokers the place consistency issues |
Select the metric that matches your use case. In any other case, a shaky agent can look dependable, or a dependable one can look inconsistent.
Studying Transcripts Earlier than Trusting the Rating
A dashboard rating would not inform you whether or not the eval is measuring the correct factor. Learn a pattern of transcripts to see the agent’s reasoning, instrument calls, and remaining state. When a job fails, the transcript exhibits whether or not the agent really failed or the grader rejected an inexpensive resolution.
This additionally exposes damaged graders and ambiguous duties. Easy string matching can penalize right solutions for minor formatting variations, whereas unclear specs could make duties unimaginable to finish as written. In some instances, fixing grading bugs alone has dramatically improved benchmark scores with out altering the mannequin.
Look ahead to suites the place brokers already move almost every thing. A 98% rating is helpful for regression testing, but it surely will not point out the place the agent can enhance. Hold the suite as a regression guard and add more durable duties to check new capabilities.
Wiring Evals Into Your Improvement Workflow
Evals change into extra helpful after they run mechanically. Hint the agent’s core perform and run the eval suite like unit checks on each pull request. If efficiency regresses, block the merge earlier than the problem reaches customers.
Manufacturing monitoring nonetheless issues. Use evals for quick, repeatable checks, then mix them with consumer suggestions, dwell utilization information, and periodic transcript evaluations to catch edge instances and drift that mounted check suites miss.
Abstract
Efficient evals flip AI agent improvement from guesswork into measurable engineering. As a substitute of counting on subjective judgments after a mannequin, immediate, or instrument change, groups can use repeatable duties and clear graders to measure what improved, what regressed, and why.
Sturdy evals begin small, replicate actual consumer wants, and deal with outcomes reasonably than inflexible motion sequences. They separate reasoning, instrument use, and job completion, whereas remoted environments and repeated trials make outcomes extra dependable. Here is a assessment of what we have mentioned on this article:
| Space | Key takeaway |
|---|---|
| Activity Design | Use clear, practical duties based mostly on failures and consumer wants. |
| Analysis Layers | Measure reasoning, instrument actions, and remaining outcomes individually. |
| Graders | Match deterministic, model-based, and human graders to the duty. |
| Take a look at Harness | Hold trials remoted, reproducible, and free from state leakage. |
| Reliability | Run a number of trials and monitor move@okay or move^okay the place acceptable. |
| Transcript Evaluate | Examine failures to tell apart agent issues from flawed evals. |
| Steady Testing | Run evals with each change and add new failure instances over time. |
| Suggestions | Use noticed failures and consumer suggestions to enhance the eval suite. |
Ultimately, eval suite is greater than a scorecard. It creates a steady suggestions loop: check → measure → diagnose → enhance. By combining repeatable evals with ongoing monitoring and common transcript assessment, groups could make AI brokers extra dependable and catch regressions earlier.
Bala Priya C is a developer and technical author from India. She likes working on the intersection of math, programming, information science, and content material creation. Her areas of curiosity and experience embrace DevOps, information science, and pure language processing. She enjoys studying, writing, coding, and low! At the moment, she’s engaged on studying and sharing her information with the developer group by authoring tutorials, how-to guides, opinion items, and extra. Bala additionally creates partaking useful resource overviews and coding tutorials.