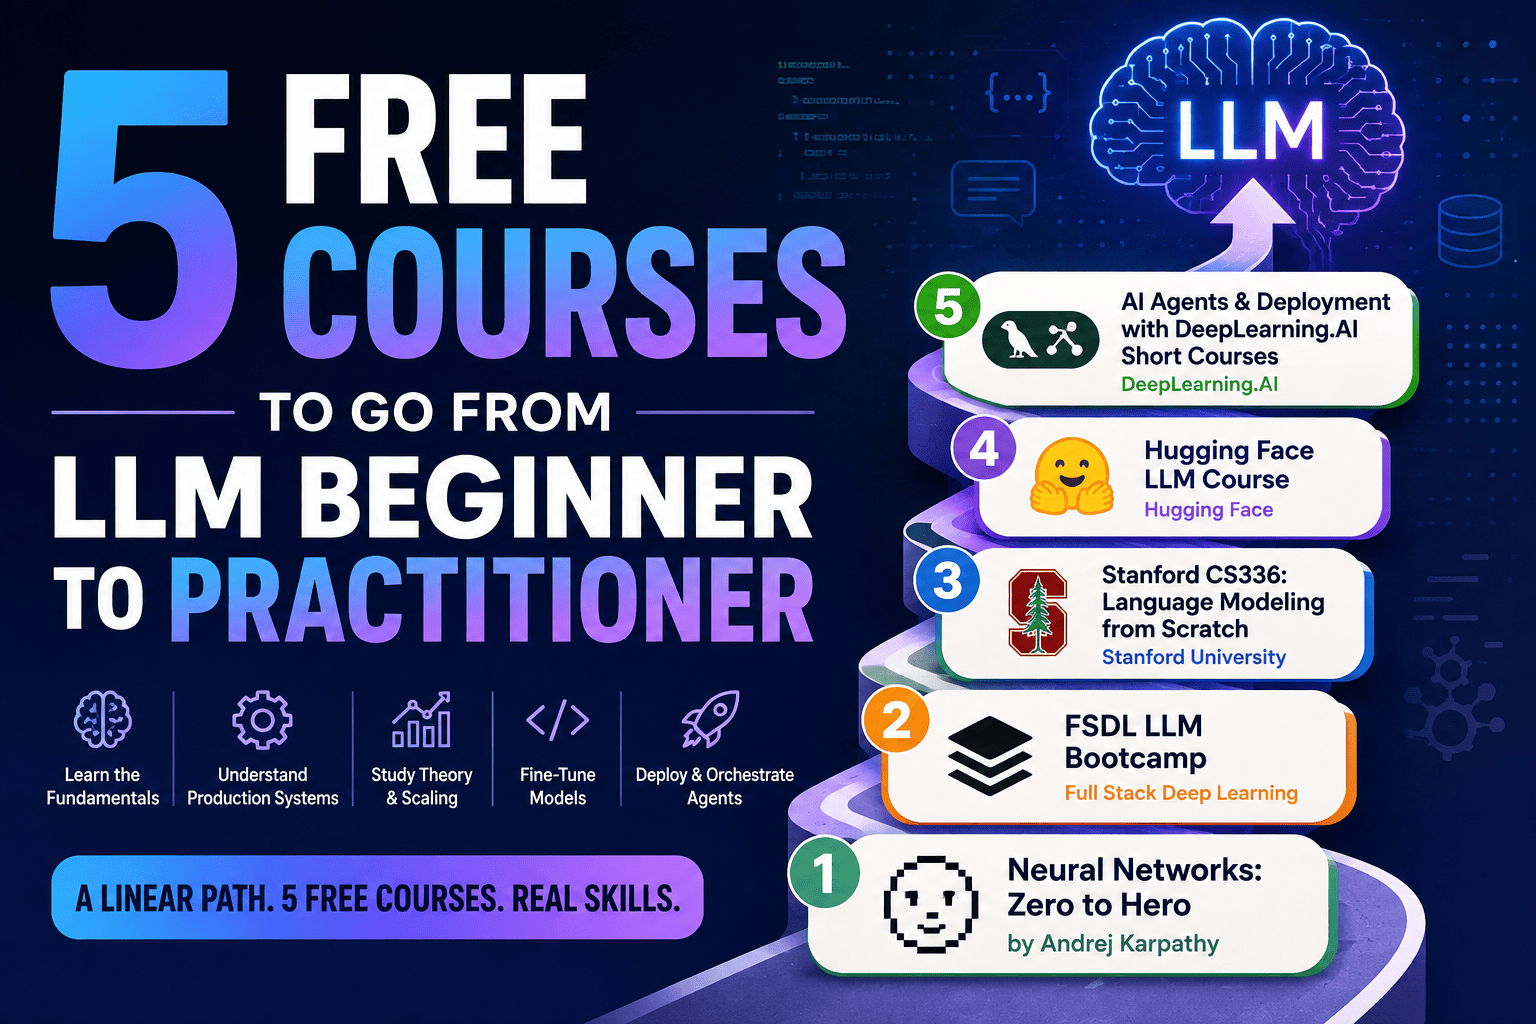
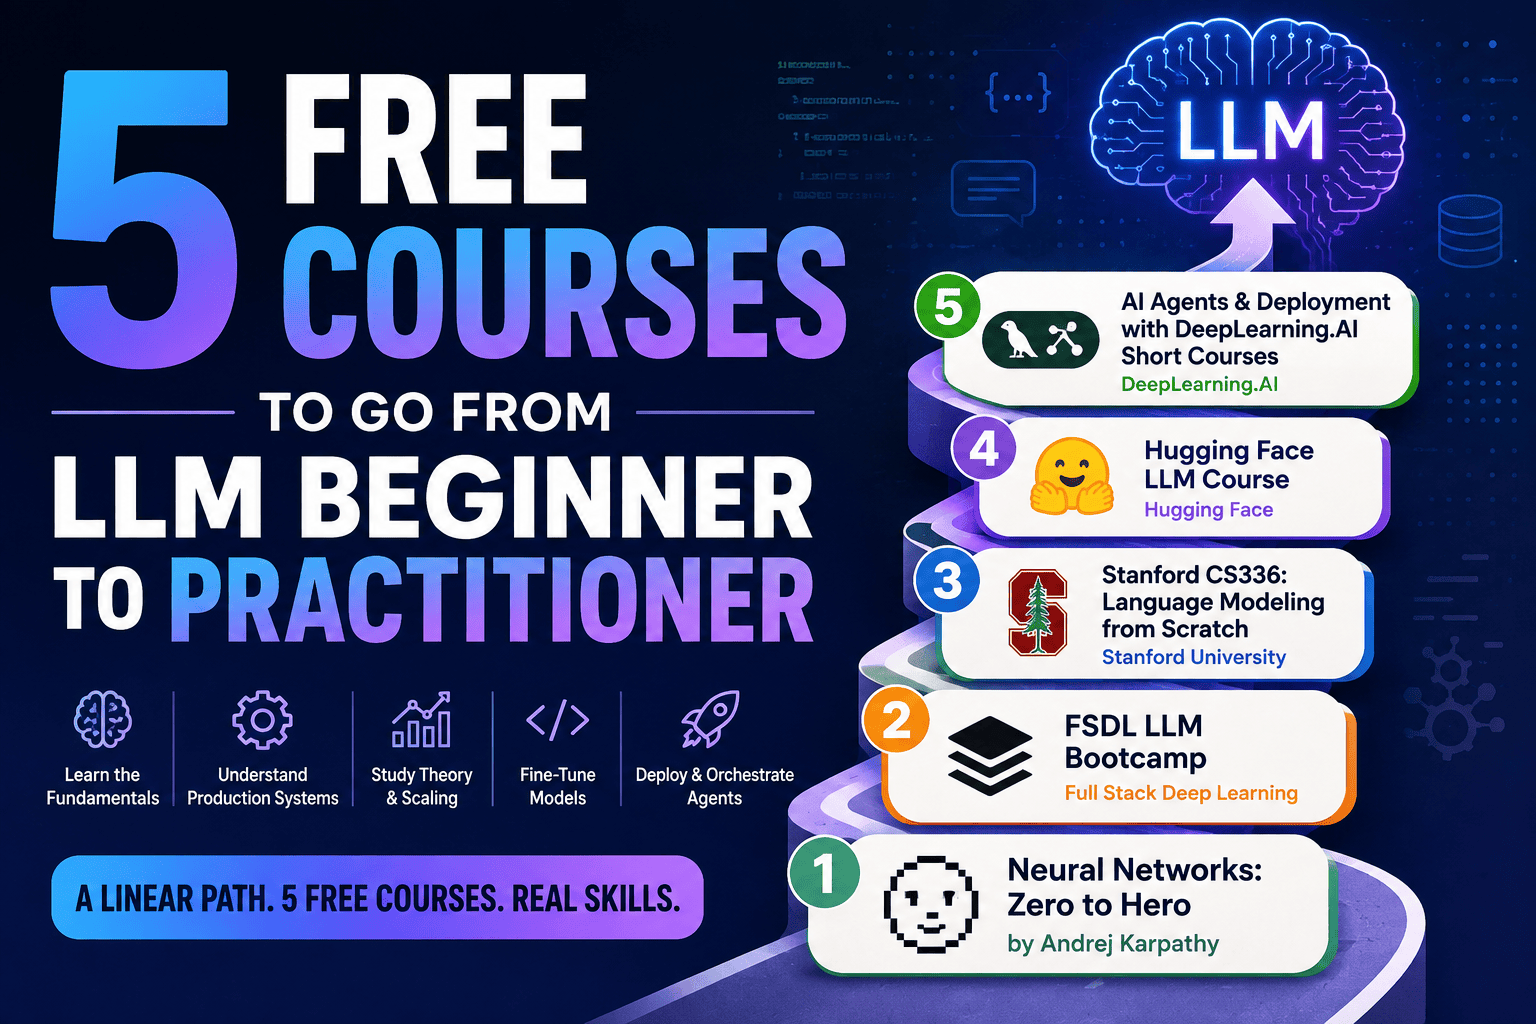
The web is drowning in massive language mannequin (LLM) tutorials. Most are skinny introductions dressed up as complete guides, or outdated walkthroughs written earlier than trendy fine-tuning workflows existed. Discovering 5 programs that kind a real studying pipeline — the place each picks up the place the final left off — is more durable than it sounds. This record solves that downside. Every course under was chosen for a particular function in a linear development: understanding the maths and mechanics of how language fashions are constructed, studying how manufacturing programs are structured, going deep on concept and scaling, creating hands-on fine-tuning abilities, and eventually deploying and orchestrating brokers at scale. Collectively they kind an entire path from newbie to practitioner.
Course 1: Constructing the Basis with Andrej Karpathy’s Neural Networks: Zero to Hero
Earlier than you may work productively with massive language fashions, it’s worthwhile to perceive what they really are beneath the hood. No course does this higher or extra truthfully than Neural Networks: Zero to Hero by Andrej Karpathy, a founding member of OpenAI and former head of AI at Tesla. The course walks you thru constructing neural networks from uncooked Python with no framework shortcuts. You begin by setting up micrograd, a tiny automated differentiation engine, in order that backpropagation stops being an abstraction and turns into one thing you may hint line by line. From there you construct makemore, a character-level language mannequin, and finally arrive at a working GPT-2-scale transformer, together with a byte-pair encoding (BPE) tokenizer constructed from scratch.
What you’ll construct:
- A working autograd engine from scratch
- A bigram and multilayer perceptron (MLP) language mannequin
- A GPT-2 structure educated on actual textual content
- A BPE tokenizer matching OpenAI’s implementation
Stipulations: Strong Python and a passing familiarity with derivatives.
Format: Free YouTube playlist (9 lectures) with companion Jupyter notebooks on GitHub. Anticipate 20 to 30 hours of lively coding time.
Course 2: Studying Manufacturing Structure with the FSDL LLM Bootcamp
When you perceive how language fashions work mechanically, the following query is how they work in manufacturing. The Full Stack LLM Bootcamp by Full Stack Deep Studying (FSDL) addresses precisely this hole. Recorded from a two-day in-person occasion in San Francisco in April 2023 and launched free on YouTube, this bootcamp covers the engineering scaffolding round LLMs: immediate engineering at a programs degree, LLMOps, analysis harness design, latency and value trade-offs, consumer expertise for language interfaces, and LLM-as-a-judge analysis pipelines. The fabric assumes you may already name an API and write Python. Its worth is in displaying you the way these items join right into a deployable, monitored software — together with what breaks in manufacturing and why.
What you’ll study:
- Structuring LLM purposes for reliability and value management
- Designing analysis pipelines, together with model-based analysis
- Deployment monitoring and LLMOps practices
- Sensible immediate engineering past fundamental prompting
Format: Free YouTube playlist with accompanying slides. Notice that that is the 2023 version; some API references are dated, however the architectural rules stay sound.
Course 3: Going Deep on Principle with Stanford CS336
For a rigorous therapy of how language fashions are designed, educated, and evaluated at scale, Stanford’s CS336: Language Modeling from Scratch is probably the most thorough freely accessible educational useful resource on the market. Taught by Percy Liang and Tatsunori Hashimoto, CS336 takes a special method from most programs: as a substitute of educating you to make use of present fashions, it walks you thru constructing one from scratch, protecting knowledge assortment and cleansing, tokenizer building, transformer structure, coaching optimization, and analysis earlier than deployment. The philosophy mirrors working programs programs that construct an OS from scratch to show programs considering. Matters embrace scaling legal guidelines, knowledge provenance and curation, alignment dynamics, and infrastructure issues for coaching at completely different {hardware} scales.
What you’ll research:
- Knowledge assortment, deduplication, and pre-training corpus design
- Transformer structure implementation from scratch
- Coaching optimization together with studying fee schedules and gradient clipping
- Analysis methodology and benchmark design
Format: Lecture slides, assignments, and notes publicly accessible on the course web site. That is graduate-level materials; anticipate it to be demanding.
Notice: CS324 (the 2022 predecessor additionally by Percy Liang) covers related theoretical floor and stays publicly accessible at stanford-cs324.github.io. CS336 is the extra present and implementation-focused successor.
Course 4: Growing High quality-Tuning Expertise with the Hugging Face LLM Course
Principle and structure information want to satisfy sensible tooling, and that is the place the Hugging Face LLM Course is available in. Initially the Hugging Face NLP Course and actively up to date by means of mid-2026, this thirteen-chapter path covers the complete Hugging Face ecosystem: transformer architectures, tokenizers, the Datasets library, supervised fine-tuning (SFT) with TRL, low-rank adaptation (LoRA) through PEFT, and within the latest chapters, constructing reasoning fashions utilizing Group Relative Coverage Optimization (GRPO) within the model of DeepSeek R1. Chapters 10 by means of 12 are price explicit consideration: they cowl dataset curation with Argilla, the SFTTrainer workflow with LoRA, and reinforcement studying from human suggestions (RLHF) options together with direct desire optimization (DPO).
What you’ll construct:
- High quality-tuned fashions utilizing LoRA on customized datasets
- Datasets curated and formatted for instruction tuning
- A reasoning mannequin educated with GRPO
- Gradio demos for sharing mannequin outputs
from trl import SFTTrainer
from peft import LoraConfig

lora_config = LoraConfig(r=16, lora_alpha=32, target_modules=["q_proj", "v_proj"])
coach = SFTTrainer(mannequin=mannequin, train_dataset=dataset, peft_config=lora_config)
coach.prepare()
This five-line sample, coated in depth in Chapter 11, represents the usual LoRA fine-tuning workflow the course builds towards.
Course 5: Deploying and Orchestrating Brokers with DeepLearning.AI Quick Programs
The ultimate stage of the practitioner path is deployment and orchestration: serving fashions effectively, constructing stateful brokers, and connecting language fashions to exterior instruments and reminiscence programs. DeepLearning.AI‘s brief course catalog covers this layer by means of a modular monitor of centered programs. Essentially the most related embrace AI Brokers in LangGraph, which teaches you to construct controllable brokers from scratch after which rebuild them with LangGraph’s stateful graph abstractions, plus programs on vLLM serving, retrieval-augmented technology (RAG) pipeline design, and semantic routing. Every course runs between one and three hours, taught straight by framework creators: Harrison Chase (LangChain/LangGraph) and specialists from Anyscale, Weaviate, and different manufacturing AI infrastructure groups.
What you’ll construct:
- A stateful LangGraph agent with human-in-the-loop checkpoints
- A RAG pipeline with vector retrieval and re-ranking
- A vLLM serving endpoint optimized for throughput and latency
Format: Free on the DeepLearning.AI platform throughout their studying platform beta interval. Test the DeepLearning.AI brief programs web page for present availability earlier than
Find out how to Work Via This Record
The 5 programs map cleanly to a development:
| Stage | Course | Time Estimate |
|---|---|---|
| Mechanics | Karpathy Zero to Hero | 20–30 hours |
| Manufacturing programs | FSDL LLM Bootcamp | 8–10 hours |
| Principle and scaling | Stanford CS336 | 30–40 hours |
| High quality-tuning | Hugging Face LLM Course | 15–20 hours |
| Deployment and brokers | DeepLearning.AI monitor | 10–15 hours |
You need not end every course earlier than shifting to the following. A sensible method: work by means of Karpathy totally (it rewards endurance), skim the FSDL bootcamp for structure instinct, dip into CS336 for the sections most related to your work, then go hands-on with Hugging Face and DeepLearning.AI after you have a mission to construct towards. The distinction between somebody who reads about LLMs and somebody who can construct with them is nearly all the time what number of occasions they’ve run the coaching loop, inspected the loss curve, and debugged a damaged fine-tuning run. These 5 programs provide the reps.
Remaining Ideas
Ten programs would provide you with ten beginning factors and no clear path. 5 programs, chosen for the way they join, provide you with a pipeline. Begin with Karpathy to grasp what you are working with, use FSDL and CS336 to grasp the way it suits into programs and concept, develop sensible abilities with Hugging Face, after which deploy and orchestrate with DeepLearning.AI. By the tip, you will have the vocabulary, the instinct, and the hands-on expertise to work on LLM tasks that transcend prompting a hosted API.
Vinod Chugani is an AI and knowledge science educator who bridges the hole between rising AI applied sciences and sensible software for working professionals. His focus areas embrace agentic AI, machine studying purposes, and automation workflows. Via his work as a technical mentor and teacher, Vinod has supported knowledge professionals by means of ability improvement and profession transitions. He brings analytical experience from quantitative finance to his hands-on educating method. His content material emphasizes actionable methods and frameworks that professionals can apply instantly.