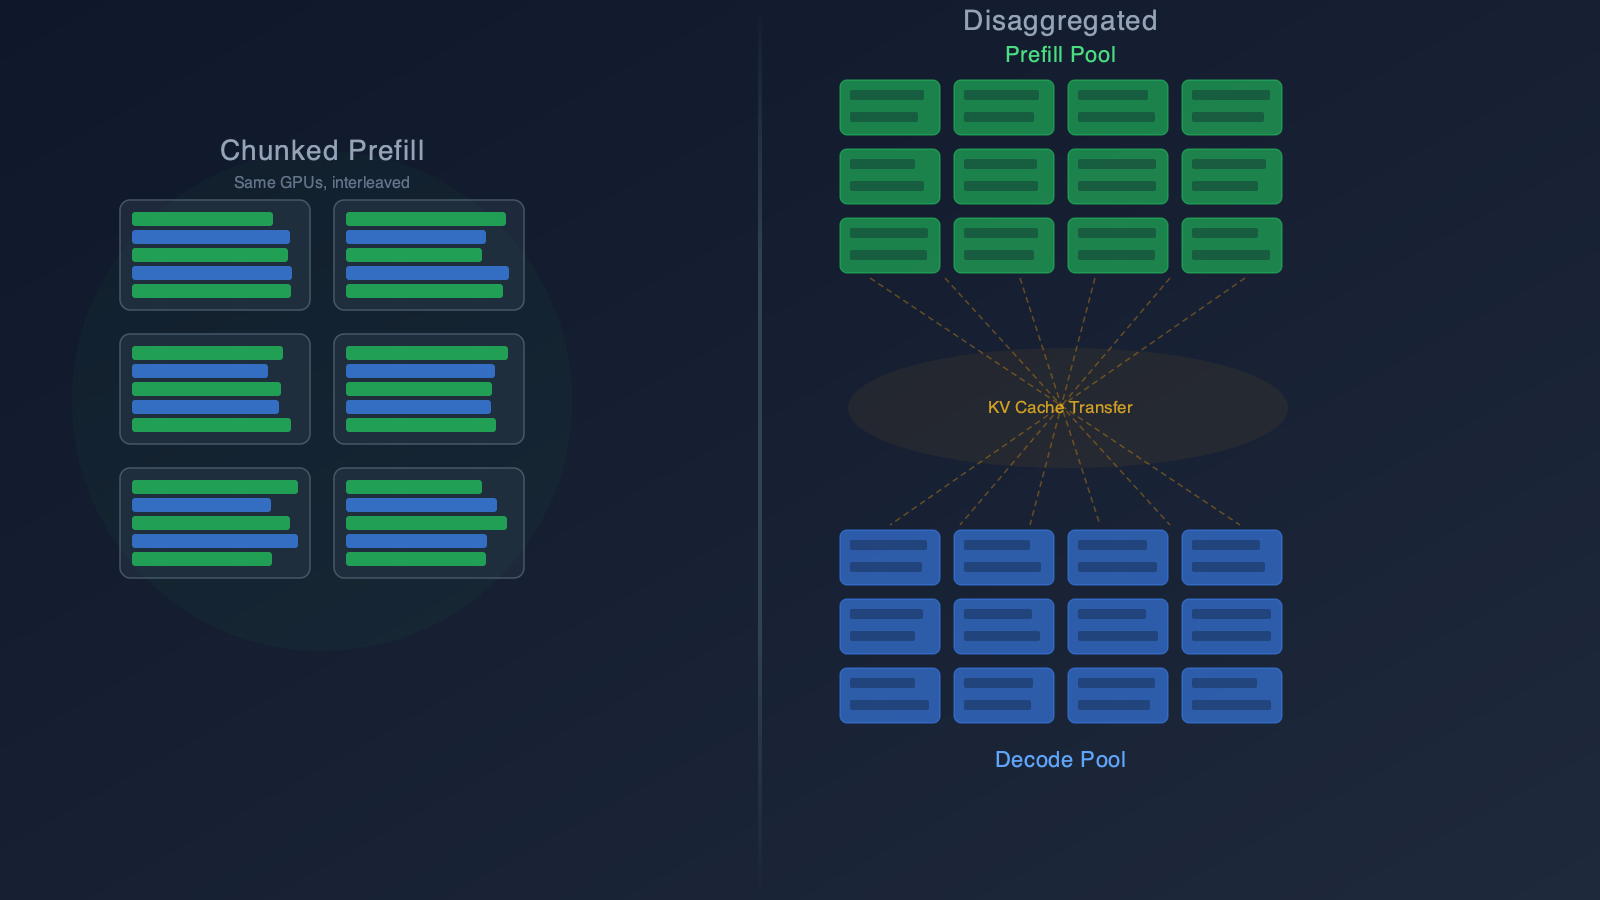
Each main inference framework shipped prefill-decode disaggregation this 12 months. NVIDIA constructed it into Dynamo. SGLang made it the default for large-scale deployments. vLLM added a KV connector API to assist it natively. The consensus is forming quick: cut up your prefill and decode onto separate GPU swimming pools, and throughput improves.
The consensus is unsuitable for many groups.
Doubleword’s evaluation exhibits {that a} balanced disaggregated deployment matches colocated throughput, however at small GPU counts the rounding losses dominate: you’ll be able to’t allocate fractional GPUs, so the specialization beneficial properties get eaten by incomplete employee utilization. The sensible profit at that scale is unbiased SLO tuning, not throughput.
A June 2025 research evaluating tons of of 1000’s of design factors discovered that disaggregation is simplest for prefill-heavy site visitors patterns and bigger fashions. For the mixed-traffic workloads most groups truly run, queueing and inter-node KV cache switch dominated end-to-end latency. The groups that disaggregated moved the bottleneck. They did not take away it.
I bumped into this on an inference workload serving a mid-size classification mannequin. TPOT spiked underneath bursty site visitors, and the primary intuition was to separate prefill from decode. As an alternative, I enabled chunked prefill on the identical GPU pool. TPOT stabilized. The issue was scheduling interference, and chunked prefill dealt with it with out including a community hop.
What Disaggregation Solves: The Interference Downside
Prefill and decode have reverse {hardware} profiles. Prefill is compute-bound: parallel matrix multiplications throughout the total enter sequence, GPU compute utilization at 80 to 95 %. Decode is memory-bandwidth-bound: sequential KV cache reads producing one token at a time, compute utilization beneath 5 % on an H100.
When each share a GPU, they battle over the identical assets. A single massive prefill request arriving mid-decode inflates time-per-output-token by 2 to 30x underneath bursty workloads. The decode batch stalls whereas prefill saturates the compute models.
DistServe proved the repair works at scale: separating prefill and decode onto devoted swimming pools served 7.4x extra requests inside the identical latency constraints. On the scale DistServe benchmarked, disaggregation is unambiguously the precise name.
The diagram beneath exhibits the place the bottleneck sits in every strategy: colocated, disaggregated, and chunked prefill
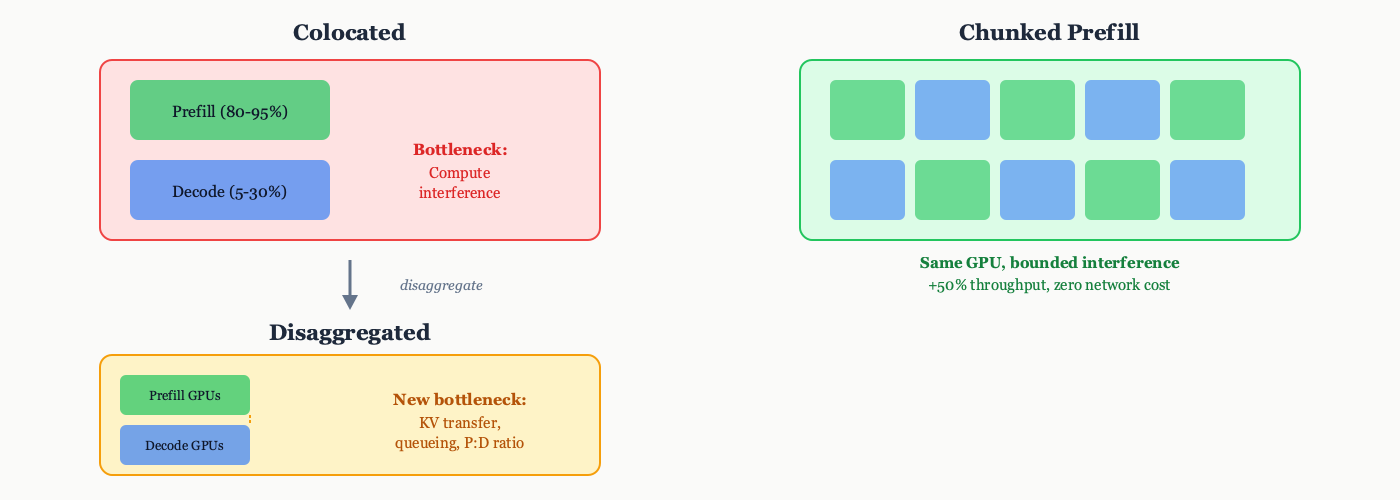
However there’s a less complicated repair that handles a lot of the interference with out the structure change.
Chunked Prefill: The Repair Most Groups Truly Want
Chunked prefill breaks lengthy prefill requests into smaller chunks and interleaves them with decode batches on the identical GPU. No separate node swimming pools. No KV cache switch over the community. No P:D ratio to tune.
TNG Expertise Consulting measured a 50 % enhance in complete token throughput utilizing normal vLLM with chunked prefill enabled. The decode batches nonetheless ran between prefill chunks on the identical {hardware}, however the scheduling interference dropped to a degree most manufacturing workloads can tolerate.
Consider it like a toll plaza on a freeway: as a substitute of closing all lanes for a single outsized truck, chunked prefill lets the truck move via one lane at a time whereas common site visitors retains transferring via the others.
Chunked prefill does not remove interference completely. It bounds it. Every prefill chunk occupies the compute models for a bounded length, then yields to decode. For workloads beneath roughly 50 requests per second with average immediate lengths, that sure is tight sufficient.
Three Prices of Disaggregation: What the Explainers Skip
The explainer articles cowl what disaggregation beneficial properties. They skip what it prices.
The KV switch tax. Each request that finishes prefill should ship its KV cache to a decode node over the community. For a 70B-parameter mannequin, that is roughly 2.6 GB per request.
When prefill and decode share a node, the KV cache stays in GPU reminiscence. When you disaggregate throughout nodes, that switch hits the community interconnect, and the accessible bandwidth drops by orders of magnitude relying in your topology.
It is like splitting a manufacturing facility meeting line into two buildings: the specialization per constructing improves, however now you are trucking half-finished elements between them. With out InfiniBand or NVLink in the identical rack, the trucking value dominates. You may’t disaggregate your approach out of a sluggish community.
The operational floor. Disaggregation doubles your infrastructure administration. You now run separate prefill and decode node swimming pools, every with its personal scaling coverage. The P:D ratio is determined by your workload combine: LMSYS independently evaluated 4 prefill nodes and 9 decode nodes for DeepSeek-R1, and people numbers shift the second your prompt-to-output size ratio modifications.
There isn’t any sleek fallback. If a prefill node goes down, decode nodes can’t fill in. The roles are assigned at launch.
The silent failure cliff. At low concurrency, disaggregated serving works effective. At manufacturing concurrency, it breaks in ways in which produce no errors. SGLang problem #9266 paperwork systematic KV cache switch failures at 64 or extra concurrent requests, returning HTTP 400 to purchasers.
Situation #30233 describes a worse failure: when enter exceeds the utmost request size, the prefill facet aborts however nonetheless transfers a single-token KV cache. The decode facet generates from uninitialized reminiscence. No error surfaces to the caller.
The Resolution Math: Three Situations That Should Maintain
Modular’s inference handbook stories a 20 to 30 % efficiency drop from disaggregation on small or untuned workloads. The overhead is actual and front-loaded: you pay the KV switch value on each request no matter whether or not the throughput achieve materializes.
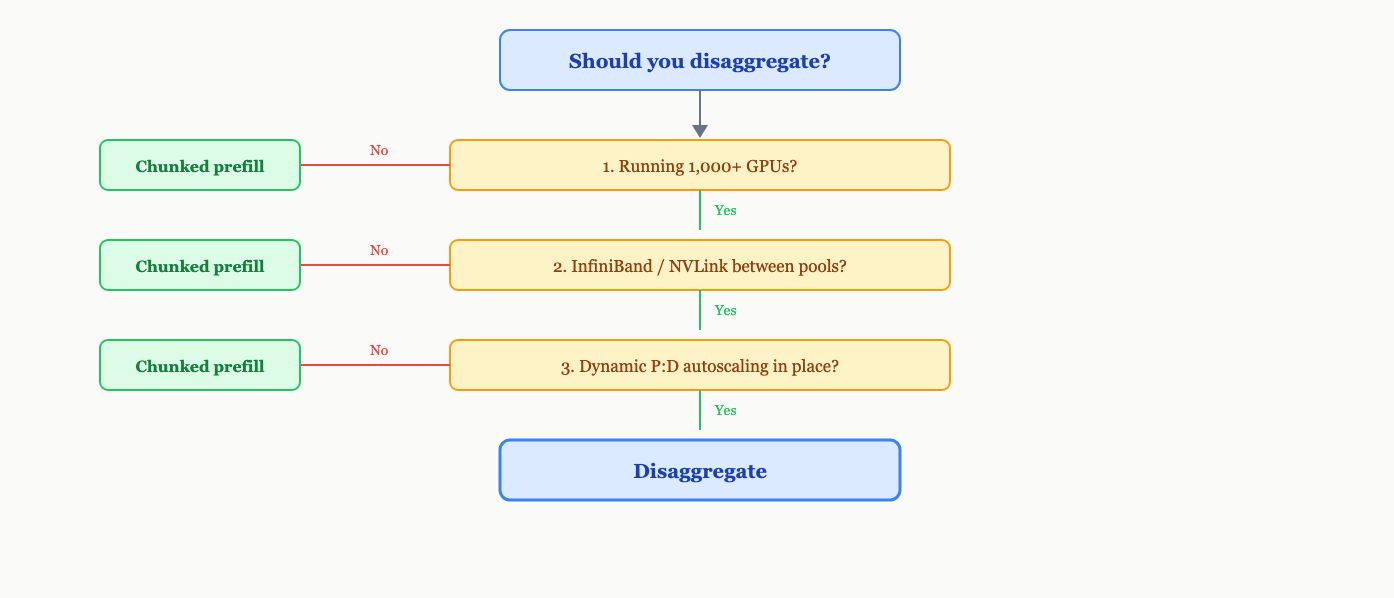
Disaggregation pays for itself solely when three situations maintain concurrently:
-
Sufficient GPUs for clear allocation. DeepSeek wanted 1000’s of GPUs earlier than the P:D ratio produced integer node counts that matched their site visitors combine. At 8 to 16 GPUs, your ratio choices are 1:7 or 2:6, neither of which can suit your workload.
-
Community bandwidth that sustains KV manufacturing price. In case your prefill pool generates KV caches sooner than the interconnect can ship them, decode nodes idle ready for information. The bottleneck migrates from compute interference to community switch.
-
Dynamic autoscaling for shifting site visitors mixes. A chat workload (quick prompts, lengthy decode) wants a distinct P:D ratio than a RAG pipeline (lengthy prompts, quick decode). In case your site visitors combine shifts through the day and your node swimming pools are static, you’re over-provisioned on one facet and starved on the opposite.
If any one in all these situations doesn’t maintain, chunked prefill is the higher default. The choice flowchart beneath maps these three situations to a concrete routing alternative.
|
Dimension |
Chunked Prefill |
Disaggregated |
|
Throughput achieve |
+50% (TNG, vLLM) |
+7.4x at scale (DistServe) |
|
Community requirement |
None (identical GPU) |
InfiniBand or NVLink |
|
Operational overhead |
vLLM flag |
Separate swimming pools, P:D tuning, KV router |
|
Failure modes |
Bounded interference |
Silent KV corruption, concurrency cliffs |
|
Scale threshold |
Any |
~1,000+ GPUs |
|
Multi-turn penalty |
None |
KV state stranded on decode nodes |
Chunked prefill vs. disaggregated serving: throughput, operational value, and failure traits.
What to Measure Earlier than You Resolve
Do not cut up your infrastructure primarily based on structure diagrams. Measure first.
-
TPOT at p95, not p50. The median hides the interference spikes that disaggregation targets. In case your p95 time-per-output-token is inside SLO on chunked prefill, you don’t have the issue that disaggregation solves.
-
Prefill fraction of TTFT. Profile your precise requests. If prefill execution is a small fraction of time-to-first-token, the bottleneck is elsewhere: queueing, scheduling, or community. Disaggregation will not repair these.
-
KV switch reliability at concurrency. Earlier than committing to disaggregation at scale, run it at manufacturing concurrency ranges, not at low QPS solely. The failure modes documented in SGLang’s problem tracker do not seem till you cross a concurrency threshold.
Conclusion: Begin With Chunked Prefill
Default to chunked prefill. It solves the scheduling interference drawback that the majority groups even have, with zero community overhead and no operational floor growth. Benchmark your p95 TPOT. If it holds, cease there.
Disaggregation is the precise structure above roughly a thousand GPUs, with quick interconnect, and with the engineering capability to handle P:D ratio tuning and KV switch reliability. These situations describe hyperscalers and enormous inference suppliers. They don’t describe most manufacturing groups transport LLM options in 2026.
Additional Studying
-
DistServe: Disaggregated Prefill and Decoding for Goodput-optimized LLM Serving (OSDI 2024, the founding paper on disaggregation beneficial properties)
-
When to Disaggregate (Doubleword’s evaluation of situations required for disaggregation to repay)
-
Past the Buzz: A Pragmatic Tackle Inference Disaggregation (June 2025, systematic analysis of disaggregation throughout tons of of 1000’s of design factors)
-
Chunked Prefill on H100 (TNG’s +50% throughput measurement)
-
Modular LLM Inference Handbook (Modular’s 20-30% drop warning and determination standards)
-
The Inference Unbundling (Wing VC’s evaluation of the compute/bandwidth cut up)
···
Thanks for studying. I am Mostafa Ibrahim, founding father of Codecontent, a developer-first technical content material company. I write about agentic techniques, RAG, and manufacturing AI. If you would like to remain in contact or talk about the concepts on this article, you will discover me on LinkedIn right here.