, one of many first design selections now we have to make is:
Workflow or agent?
The workflow paradigm follows a sequence we outline upfront. This makes the applying very simple to grasp, and provides us clear management over how info strikes from one stage to the subsequent. It really works nicely once we know which operation ought to occur at every stage. For extra open-ended questions, nevertheless, the subsequent helpful motion might rely on what the system discovers alongside the way in which.
The agent paradigm, then again, begins with a purpose and decides which actions or instruments to make use of alongside the way in which. This makes it extra versatile when the answer path is unsure. Nonetheless, that flexibility additionally means we quit some management over how the answer unfolds.
However why make this alternative for your entire software?
From what I see, in apply, many purposes include each varieties of labor. Some levels would possibly carry out a recognized transformation, then the workflow paradigm is an effective alternative. Different levels would possibly have to adapt based mostly on intermediate outcomes, which naturally requires the agentic strategy.
For these purposes, a hybrid workflow-agent sample is a greater match.
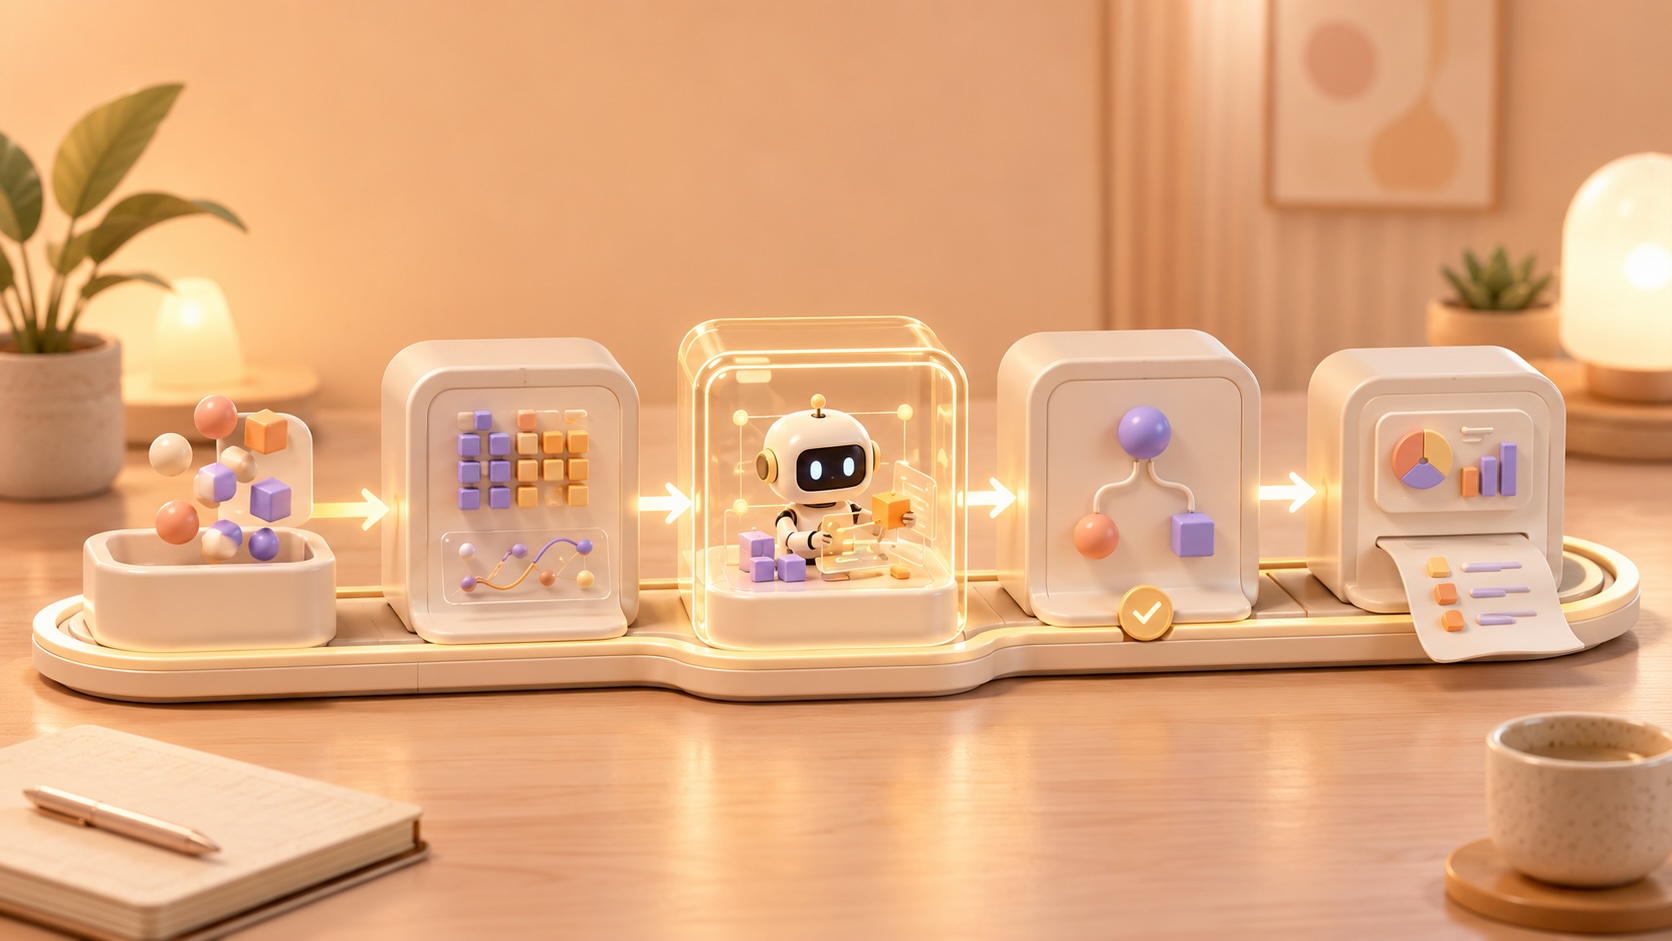
On this publish, we’ll discover this hybrid sample by means of a concrete case examine. The general resolution path will stay fastened, whereas an agent is positioned contained in the stage the place the trail can’t be decided upfront.
On this publish, we configure a easy agent that solely has entry to pre-defined instruments. In case you’d wish to improve your agent with code execution and internet looking capabilities, test my posts right here: Construct an LLM Agent That Can Write and Run Code, and The best way to Give an LLM Agent a Browser.
1. Case Examine: LLM-Assisted Hyperparameter Tuning
For the case examine, let’s construct an LLM software that helps choose algorithms and tune hyperparameters for classification issues.
This software works like this: it first receives a labeled dataset and a plain-language modeling request. It then must run mannequin experiments and advocate one of many examined configurations. Lastly, it summarizes the consequence.
Naturally, we are able to break this work into three levels.
1.1 Put together the Experiment
The aim of this stage is to translate the modeling request into a short that incorporates the target, analysis metric, and cross-validation setup.
Since we already know the enter, the specified operation to carry out, and the anticipated output, a single LLM name is enough for this stage.
1.2 Hyperparameter Tuning
At this stage, we have to run the experiments. Right here, we all know the purpose, i.e., discovering the very best mannequin and the related hyperparameters. However we don’t know the precise sequence of actions required to achieve it. The subsequent helpful experiment ought to rely on the outcomes noticed to this point.
In consequence, this stage is healthier dealt with by an agent, who can dynamically select classifier configurations, consider them, and proceed exploring.
1.3 Summarization and Reporting
Lastly, we have to summarize the finished run. At this stage, the experiment transient, trial historical past, and advice are already accessible. Turning them right into a structured report is a recognized operation, so a single LLM name is once more enough.
As you’ll be able to see, in our supposed LLM software, the general problem-solving sequence is fastened, with preparation, exploration, and reporting. Inside this predefined workflow, we introduce autonomy solely on the center stage to allow adaptive mannequin experimentation.
This manner, we mix the readability of a workflow with the pliability of agentic experimentation.
Within the following, let’s construct these three levels.
2. Constructing the Three-Stage Workflow
The whole software could be expressed in three calls:
experiment_spec = prepare_experiment(
    modeling_request,
    dataset_summary,
)

advice, trial_history = await explore_configurations(
    experiment_spec,
    dataset_summary,
)

report = summarize_run(
    experiment_spec,
    trial_history,
    advice,
)
Now, let’s unpack the three features one after the other.
2.1 Getting ready the Experiment with Structured Output
The primary stage converts the modeling request and dataset abstract right into a compact experiment transient. We use a single structured LLM name to do this.
We have to outline the output schema, the LLM instruction, and the immediate builder for this stage. We begin with the output schema, which is a Pydantic mannequin:
class ExperimentSpec(BaseModel):
    goal: str
    primary_metric: str = Subject(
        description="A sound scikit-learn scoring title"
    )
    cv_folds: int
It has three fields, specifying the data wanted by the experimentation agent, i.e., what it ought to accomplish, how configurations must be evaluated, and what number of cross-validation folds to make use of.
That is the structured output function of the LLM: it makes positive that the LLM’s output follows this predefined construction, thus tremendously simplifying the downstream consumption of the outcomes.
Subsequent, we outline the instruction:
PREPARER_INSTRUCTION = """
Create an experiment transient from the modeling request and dataset abstract.
"""
Then, we outline the builder operate to compose the immediate:
def build_preparer_prompt(request: str, dataset_summary: dict) -> str:
    return f"""Modeling request:
{request}

Dataset abstract:
{json.dumps(dataset_summary, indent=2)}"""
Lastly, we put all the pieces along with a synchronous name to the Responses API:
from openai import AzureOpenAI

llm_client = AzureOpenAI(
    api_key=os.environ["OPENAI_API_KEY"],
    azure_endpoint=os.environ["OPENAI_API_BASE"],
    api_version=os.environ["OPENAI_API_VERSION"],
)

def prepare_experiment(
    request: str,
    dataset_summary: dict,
) -> ExperimentSpec:
    response = llm_client.responses.parse(
        mannequin="gpt-5.4",
        reasoning={"effort": "medium"},
        directions=PREPARER_INSTRUCTION,
        enter=build_preparer_prompt(request, information),
        text_format=ExperimentSpec,
    )

    return response.output_parsed
This provides the subsequent stage an express experimental contract.
2.2 Constructing the Experimentation Agent
The aim of this stage is to discover a robust classifier configuration by working experiments.
A single LLM name gained’t lower it as the subsequent helpful configuration is determined by the scores noticed to this point. Subsequently, we use an agent as an alternative to maximise the adaptivity.
We first configure an asynchronous consumer for powering the agent:
from openai import AsyncAzureOpenAI
from brokers import OpenAIResponsesModel

agent_client = AsyncAzureOpenAI(
    api_key=os.environ["OPENAI_API_KEY"],
    azure_endpoint=os.environ["OPENAI_API_BASE"],
    api_version=os.environ["OPENAI_API_VERSION"],
)

agent_model = OpenAIResponsesModel(
    mannequin="gpt-5.4",
    openai_client=agent_client,
)
We then outline the output schema, instruction, and immediate for the agent:
import json
from pydantic import BaseModel

class AgentRecommendation(BaseModel):
    model_name: str
    hyperparameters_json: str
    rationale: str


AGENT_INSTRUCTION = """
Discover a robust classifier for the equipped downside.
"""


def build_agent_prompt(
    experiment_spec: ExperimentSpec,
    dataset_summary: dict,
) -> str:
    return f"""Experiment transient:
{experiment_spec.model_dump_json(indent=2)}

Dataset abstract:
{json.dumps(dataset_summary, indent=2)}"""
Subsequent, we outline the software the agent can use to run one experiment:
import json
from brokers import function_tool
from sklearn.model_selection import cross_val_score
from sklearn.utils import all_estimators

def build_experiment_tool(
    X,
    y,
    experiment_spec,
    trial_history,
):
    classifiers = dict(
        all_estimators(type_filter="classifier")
    )

    @function_tool
    def run_experiment(
        model_name: str,
        hyperparameters_json: str,
    ) -> str:
        """Consider one scikit-learn classifier configuration."""
        parameters = json.hundreds(hyperparameters_json)
        classifier = classifiers[model_name](**parameters)

        scores = cross_val_score(
            classifier,
            X,
            y,
            cv=experiment_spec.cv_folds,
            scoring=experiment_spec.primary_metric,
        )

        consequence = {
            "model_name": model_name,
            "hyperparameters": parameters,
            "mean_score": spherical(float(scores.imply()), 4),
        }

        trial_history.append(consequence)
        return json.dumps(consequence)

    return run_experiment
This software is deliberately small, and it merely evaluates the classifier configuration equipped by the agent. Additionally, the agent can select classifiers from scikit-learn’s classifier registry and supply constructor arguments as JSON.
Now we are able to flesh out the agentic stage in full:
# pip set up openai-agents
from brokers import Agent, ModelSettings, Runner

async def explore_configurations(
    X,
    y,
    experiment_spec,
    dataset_summary,
):
    trial_history = []

    run_experiment = build_experiment_tool(
        X,
        y,
        experiment_spec,
        trial_history,
    )

    agent = Agent(
        title="Mannequin choice agent",
        directions=AGENT_INSTRUCTION,
        mannequin=agent_model,
        model_settings=ModelSettings(
            reasoning={"effort": "medium"},
            parallel_tool_calls=True,
        ),
        instruments=[run_experiment],
        output_type=AgentRecommendation,
    )

    consequence = await Runner.run(
        agent,
        build_agent_prompt(
            experiment_spec,
            dataset_summary,
        ),
        max_turns=10,
    )

    return consequence.final_output, trial_history
Observe that we set parallel_tool_calls=True. This enables the agent to request a number of configurations concurrently.
That is the one autonomous a part of the workflow.
2.3 Summarizing the Run
The ultimate stage wants to show the finished run right into a concise report. This can be a closed-ended process, due to this fact a single LLM name is enough.
As ordinary, we begin by defining the output schema:
from pydantic import BaseModel

class ModelSelectionReport(BaseModel):
    selected_model: str
    selected_hyperparameters: str
    mean_cv_score: float
    abstract: str
Then, we outline the instruction and immediate builder:
REPORTER_INSTRUCTION = """
Summarize the finished model-selection run.
"""

def build_reporter_prompt(
    experiment_spec: ExperimentSpec,
    trial_history: listing[dict],
    agent_recommendation: AgentRecommendation,
) -> str:
    return f"""Experiment transient:
{experiment_spec.model_dump_json(indent=2)}

Accomplished trials:
{json.dumps(trial_history, indent=2)}

Agent advice:
{agent_recommendation.model_dump_json(indent=2)}"""
Lastly, we wrap the LLM name in a operate:
def summarize_run(
    experiment_spec: ExperimentSpec,
    trial_history: listing[dict],
    agent_recommendation: AgentRecommendation,
) -> ModelSelectionReport:
    response = llm_client.responses.parse(
        mannequin="gpt-5.4",
        reasoning={"effort": "medium"},
        directions=REPORTER_INSTRUCTION,
        enter=build_reporter_prompt(
            experiment_spec,
            trial_history,
            agent_recommendation,
        ),
        text_format=ModelSelectionReport,
    )

    return response.output_parsed
3. Testing the Workflow on Handwritten Digit Classification
To check what now we have constructed, we use scikit-learn’s built-in handwritten digits dataset (CC BY 4.0):
from sklearn.datasets import load_digits

digits = load_digits()

X = digits.information
y = digits.goal

dataset_summary = {
    "n_samples": X.form[0],
    "n_features": X.form[1],
    "n_classes": len(set(y)),
}
Right here is our modeling request:
modeling_request = """
Construct a classifier for handwritten digit photographs.
Use cross-validation to match candidate fashions.
Advocate a robust configuration.
"""
Now we are able to run the three-stage workflow:
experiment_spec = prepare_experiment(
    modeling_request,
    dataset_summary,
)

advice, trial_history = await explore_configurations(
    X,
    y,
    experiment_spec,
    dataset_summary,
)

report = summarize_run(
    experiment_spec,
    trial_history,
    advice,
)
Here’s what the primary LLM name produced in experiment_spec:
{
    "goal": "Construct and consider a classifier for handwritten digit photographs.",
    "primary_metric": "accuracy",
    "cv_folds": 5,
}
The agent then makes use of the experiment software to discover mannequin configurations. In my run, the whole size of trial_history is nineteen, listed below are the primary 5 trials:
[
    {
        "model_name": "LogisticRegression",
        "hyperparameters": {
            "max_iter": 1000
        },
        "mean_score": 0.9132
    },
    {
        "model_name": "RandomForestClassifier",
        "hyperparameters": {
            "n_estimators": 100,
            "max_depth": null
        },
        "mean_score": 0.9382
    },
    {
        "model_name": "SVC",
        "hyperparameters": {
            "C": 1,
            "kernel": "rbf",
            "gamma": "scale"
        },
        "mean_score": 0.9638
    },
    {
        "model_name": "KNeighborsClassifier",
        "hyperparameters": {
            "n_neighbors": 3
        },
        "mean_score": 0.9661
    },
    {
        "model_name": "SVC",
        "hyperparameters": {
            "C": 10,
            "kernel": "rbf",
            "gamma": "scale"
        },
        "mean_score": 0.975
    }
]
Lastly, the final LLM name summarizes the finished run in report:
{
    "selected_model": "SVC",
    "selected_hyperparameters": '{"C": 10, "kernel": "rbf", "gamma": "scale"}',
    "mean_cv_score": 0.975,
    "abstract": "The SVC configuration achieved the strongest cross-validation rating among the many examined candidates and is really helpful as the ultimate classifier.",
}
4. When to Use This Sample
When constructing your subsequent LLM software, you shouldn’t ask your self whether or not the entire software must be a workflow or an agent.
A greater query is: the place does the applying want autonomy?
If a stage has a recognized operation, use a structured LLM name.
If a stage has a transparent purpose, however the subsequent motion is determined by what the system observes, go along with an agent.
Decompose the answer path into levels, and place autonomy solely the place the trail must be found. That’s the way you preserve the readability and management of a workflow whereas utilizing agentic flexibility for more practical downside fixing.