# Introduction
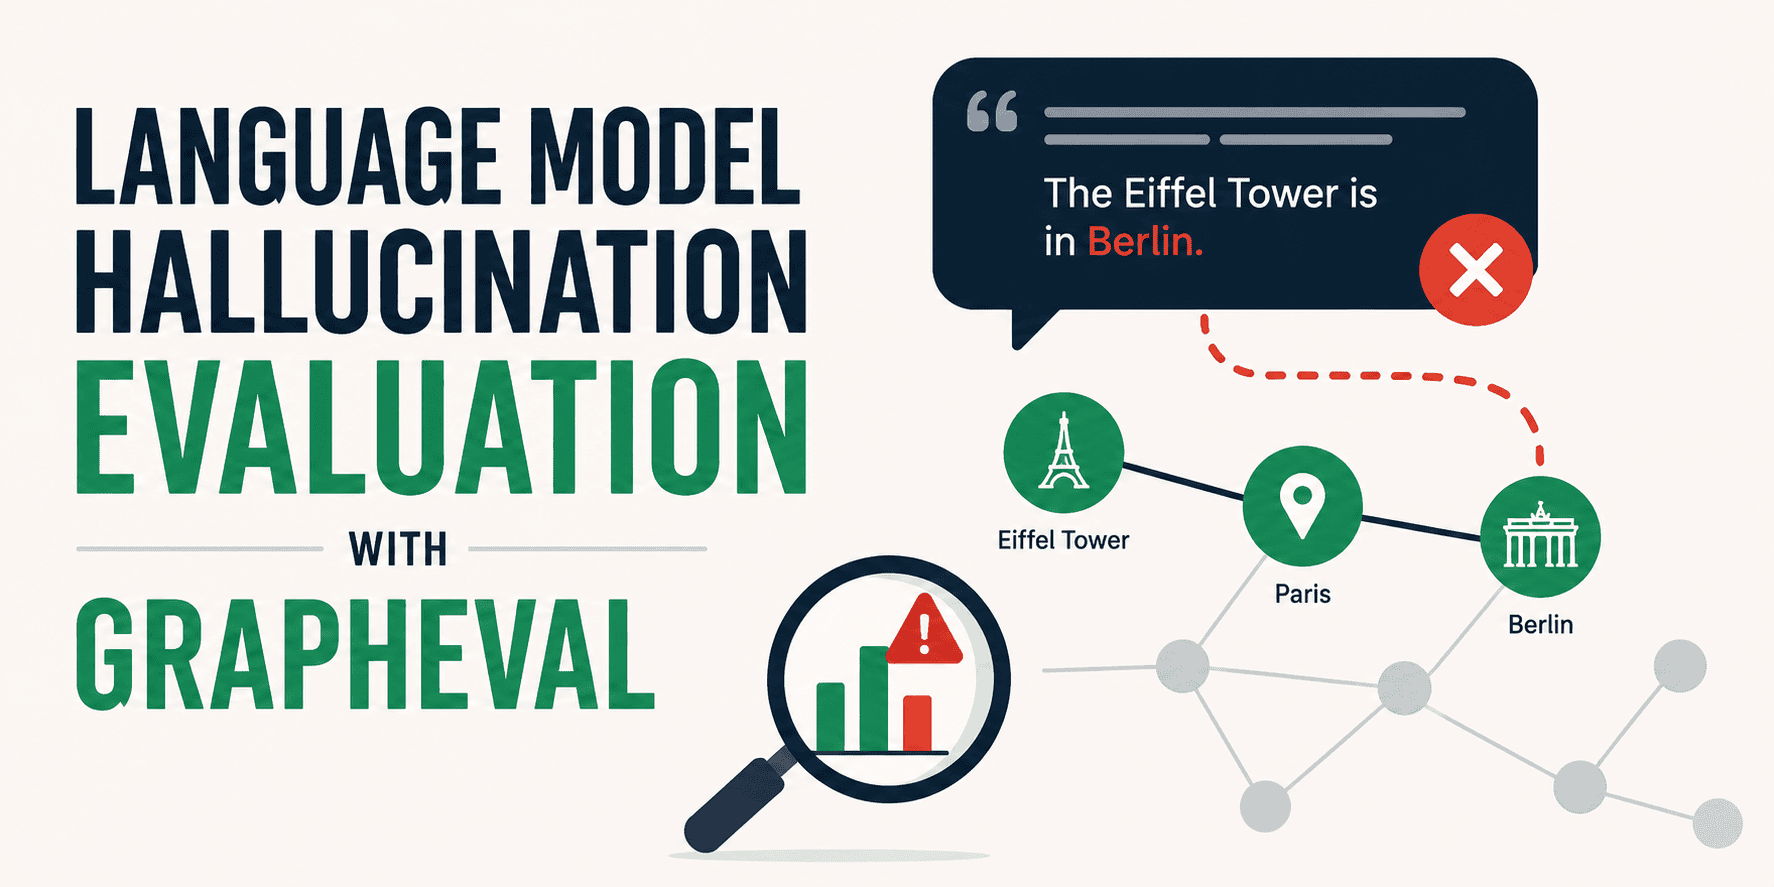
Hallucinations are one of many best-known issues that giant language fashions (LLMs) could expertise when producing responses. They happen when a mannequin produces a response that’s factually incorrect, nonsensical, or just made up, sometimes because of the mannequin’s lack of inner data on the matter.
Whereas many options have arisen in recent times to sort out the issue of mannequin hallucinations, methodological analysis frameworks for internally diagnosing them have been comparatively much less studied. One latest examine by Amazon researchers proposes utilizing data graphs as a method to research and detect hallucinations occurring in LLMs. The framework introduced within the examine is known as GraphEval.
On this article, we are going to take a delicate, sensible method for example the conceptual constructing blocks of GraphEval by a simulation-based, light-weight code instance you can simply attempt in your machine.
# GraphEval in a Nutshell
GraphEval leverages data graphs to establish and sign hallucinations in LLM-generated outputs. In contrast to classical efficiency metrics that present single scores to guage facets like accuracy, certainty, and so forth, GraphEval applies a two-stage analysis course of that emphasizes explainability, particularly, offering insights into the place precisely the hallucination befell.
To do that, GraphEval considers two levels:
- Developing a data graph from the generated mannequin response. The graph consists of semantic triples of the shape (Topic, Relationship, Object), the place topics and objects correspond to nodes, and relationships correspond to the sides connecting these nodes.
- Evaluating every triple within the constructed data graph in opposition to a supply context (a ground-truth physique of information) by a pure language inference (NLI) mannequin. Any triple that can not be entailed by the context in accordance with the NLI engine — as a result of it’s contradictory or impartial — is flagged as a hallucination.
# Illustrating GraphEval By way of a Code Instance
Earlier than beginning the code that simulates the appliance of the GraphEval framework, let’s ensure that we’ve got the mandatory libraries put in:
!pip set up -q transformers networkx matplotlib torch
The aim of the code instance we’re about to stroll by is to demystify how the GraphEval methodology works, so we are going to change the levels that might demand a heavy computational burden in a real-world setting with simulated, light-weight alternate options.
Accordingly, we are going to simulate a ground-truth data base (context) assumed to comprise factual info. In a manufacturing setting, this ground-truth data would stem, as an illustration, from retrieving related paperwork from the vector database of a retrieval-augmented technology (RAG) system. For simplicity, right here we straight create a ground-truth context and retailer it in source_context.
# The bottom-truth context offered to the LLM
source_context = (
    "GraphEval is a hallucination analysis framework primarily based on representing info "
    "in Data Graph (KG) buildings. It acts as a pre-processing step and makes use of "
    "out-of-the-box NLI fashions to detect factual inconsistencies."
)
Now, let’s suppose the next is the unique LLM response to a person immediate like “clarify succinctly what GraphEval is”. To provoke the primary stage of the analysis course of, we might ask an auxiliary LLM to construct the data graph from that response. Each the response and the follow-up immediate used to acquire the data graph are proven under:
# The generated response we need to consider (accommodates a hallucination)
llm_output = (
    "GraphEval is an analysis framework that makes use of Data Graphs. "
    "It requires a extremely costly, enterprise-level server farm to function."
)

# Immediate template that might theoretically be handed to a neighborhood/free LLM (e.g. Mistral-7B)
KG_EXTRACTION_PROMPT = f"""
You're an skilled info extractor. Extract the core info from the next textual content as a Data Graph.
Return the output strictly as a Python record of tuples within the format: (Topic, Relationship, Object).

Textual content: {llm_output}
"""
As soon as once more, for the sake of simplicity and to bypass the in any other case heavy computational load of operating an enormous LLM domestically, let’s suppose the next graph triples are obtained:
# Simulated extraction to bypass the heavy computational load of operating an enormous LLM domestically
extracted_triples = [
    ("GraphEval", "is", "evaluation framework"),
    ("GraphEval", "uses", "Knowledge Graphs"),
    ("GraphEval", "requires", "expensive enterprise server farm")
]

print("Extracted Triples:")
for t in extracted_triples:
    print(t)
Output:
Extracted Triples:
('GraphEval', 'is', 'analysis framework')
('GraphEval', 'makes use of', 'Data Graphs')
('GraphEval', 'requires', 'costly enterprise server farm')
We intentionally added a triple that’s basically a hallucination (no enterprise server farm wanted in any way!), so we are able to show how the following NLI course of utilized to the data graph reveals it.
Sufficient simulated steps for right this moment. Let’s get into the actual motion for the following stage: the NLI course of. The following piece of code is prime to leveraging the concepts behind GraphEval. It makes use of a pre-trained NLI mannequin from Hugging Face — the mannequin is publicly accessible, so no entry token is required to obtain it — to match every triple in opposition to the ground-truth context. If no entailment is “predicted” by the NLI mannequin for a given triple, it’s labeled as a hallucination.
from transformers import pipeline

# Loading the open-source NLI mannequin
print("Loading DeBERTa NLI mannequin...")
nli_evaluator = pipeline("text-classification", mannequin="cross-encoder/nli-deberta-v3-small")

def evaluate_triple(context, triple):
    topic, relation, obj = triple
    speculation = f"{topic} {relation} {obj}"

    # Checking if the context entails the speculation
    outcome = nli_evaluator({"textual content": context, "text_pair": speculation})

    # NLI fashions usually output: 'entailment', 'impartial', or 'contradiction'
    label = outcome['label'].decrease()

    # In GraphEval, something apart from 'entailment' is flagged as a hallucination
    is_hallucinated = label != 'entailment'

    return is_hallucinated, label, speculation

# Working the analysis pipeline
evaluation_results = []

print("n--- GraphEval Outcomes ---")
for t in extracted_triples:
    is_hallucinated, nli_label, speculation = evaluate_triple(source_context, t)
    evaluation_results.append((is_hallucinated, nli_label))

    standing = "🚨 HALLUCINATION" if is_hallucinated else "✅ GROUNDED"
    print(f"{standing} | Triple: {t} | NLI Output: {nli_label}")
Output:
--- GraphEval Outcomes ---
✅ GROUNDED | Triple: ('GraphEval', 'is', 'analysis framework') | NLI Output: entailment
✅ GROUNDED | Triple: ('GraphEval', 'makes use of', 'Data Graphs') | NLI Output: entailment
🚨 HALLUCINATION | Triple: ('GraphEval', 'requires', 'costly enterprise server farm') | NLI Output: impartial
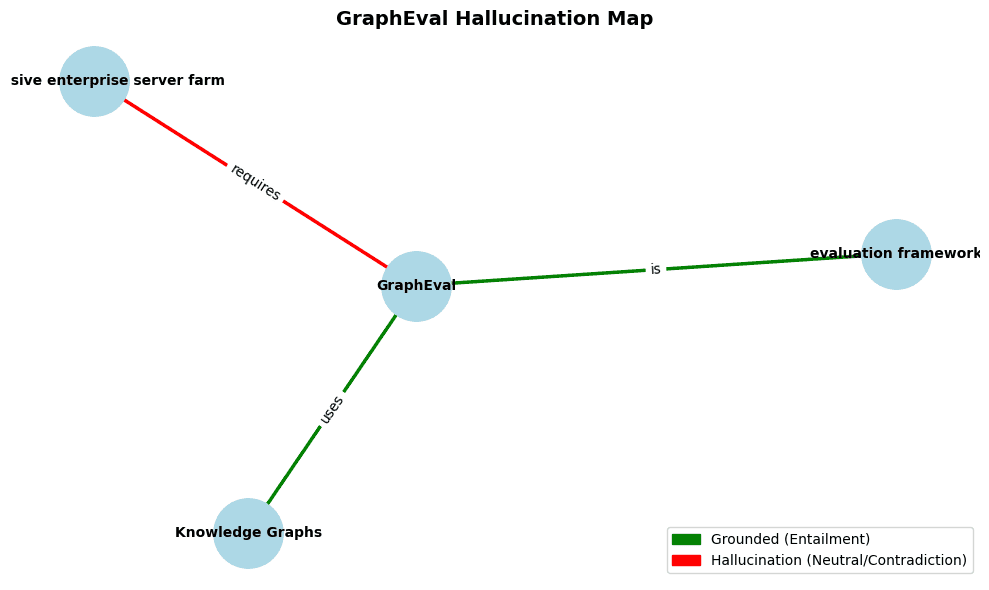
As we anticipated, the final triple within the data graph is detected as a hallucination.
To complete with a visible contact, we are able to additionally show the data graph of the unique LLM response alongside the detection outcomes:
import networkx as nx
import matplotlib.pyplot as plt
import matplotlib.patches as mpatches

def visualize_grapheval(triples, eval_results):
    G = nx.DiGraph()
    edge_colors = []

    for (triple, res) in zip(triples, eval_results):
        sub, rel, obj = triple
        is_hallucinated = res[0]

        G.add_node(sub)
        G.add_node(obj)
        G.add_edge(sub, obj, label=rel)

        # Colour-code the sides primarily based on the NLI analysis
        edge_colors.append('pink' if is_hallucinated else 'inexperienced')

    # Arrange the plot
    plt.determine(figsize=(10, 6))
    pos = nx.spring_layout(G, seed=42)

    # Draw nodes
    nx.draw_networkx_nodes(G, pos, node_color="lightblue", node_size=2500)
    nx.draw_networkx_labels(G, pos, font_size=10, font_weight="daring")

    # Draw edges and labels
    nx.draw_networkx_edges(G, pos, edge_color=edge_colors, width=2.5, arrowsize=20)
    edge_labels = nx.get_edge_attributes(G, 'label')
    nx.draw_networkx_edge_labels(G, pos, edge_labels=edge_labels, font_color="black")

    # Add legend
    green_patch = mpatches.Patch(coloration="inexperienced", label="Grounded (Entailment)")
    red_patch = mpatches.Patch(coloration="pink", label="Hallucination (Impartial/Contradiction)")
    plt.legend(handles=[green_patch, red_patch], loc="decrease proper")

    plt.title("GraphEval Hallucination Map", fontsize=14, fontweight="daring")
    plt.axis('off')
    plt.tight_layout()
    plt.present()

# Render the data graph
visualize_grapheval(extracted_triples, evaluation_results)
Ensuing visualization:
# Closing Remarks
GraphEval is an analysis methodology proposed to assist detect and localize the foundation reason behind hallucinations in LLM outputs. This text turned its key rules and methodological levels right into a simulated sensible situation to raised perceive its usefulness and its key implications for potential implementation in manufacturing techniques.
Iván Palomares Carrascosa is a pacesetter, author, speaker, and adviser in AI, machine studying, deep studying & LLMs. He trains and guides others in harnessing AI in the actual world.
# Introduction
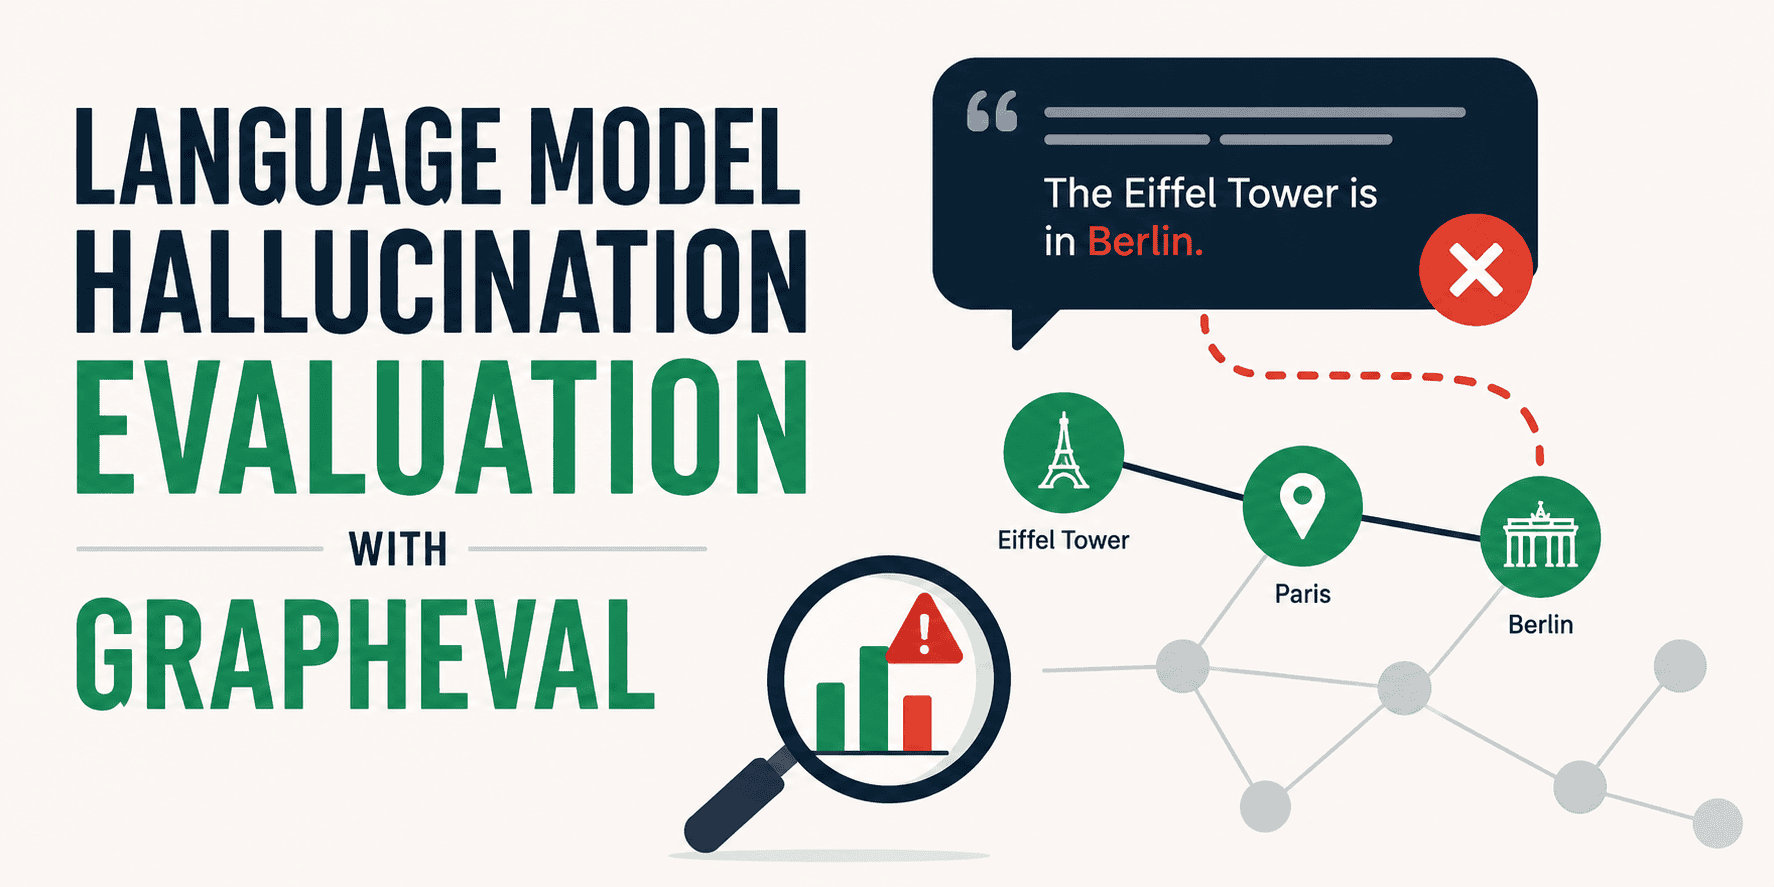
Hallucinations are one of many best-known issues that giant language fashions (LLMs) could expertise when producing responses. They happen when a mannequin produces a response that’s factually incorrect, nonsensical, or just made up, sometimes because of the mannequin’s lack of inner data on the matter.
Whereas many options have arisen in recent times to sort out the issue of mannequin hallucinations, methodological analysis frameworks for internally diagnosing them have been comparatively much less studied. One latest examine by Amazon researchers proposes utilizing data graphs as a method to research and detect hallucinations occurring in LLMs. The framework introduced within the examine is known as GraphEval.
On this article, we are going to take a delicate, sensible method for example the conceptual constructing blocks of GraphEval by a simulation-based, light-weight code instance you can simply attempt in your machine.
# GraphEval in a Nutshell
GraphEval leverages data graphs to establish and sign hallucinations in LLM-generated outputs. In contrast to classical efficiency metrics that present single scores to guage facets like accuracy, certainty, and so forth, GraphEval applies a two-stage analysis course of that emphasizes explainability, particularly, offering insights into the place precisely the hallucination befell.
To do that, GraphEval considers two levels:
- Developing a data graph from the generated mannequin response. The graph consists of semantic triples of the shape (Topic, Relationship, Object), the place topics and objects correspond to nodes, and relationships correspond to the sides connecting these nodes.
- Evaluating every triple within the constructed data graph in opposition to a supply context (a ground-truth physique of information) by a pure language inference (NLI) mannequin. Any triple that can not be entailed by the context in accordance with the NLI engine — as a result of it’s contradictory or impartial — is flagged as a hallucination.
# Illustrating GraphEval By way of a Code Instance
Earlier than beginning the code that simulates the appliance of the GraphEval framework, let’s ensure that we’ve got the mandatory libraries put in:
!pip set up -q transformers networkx matplotlib torch
The aim of the code instance we’re about to stroll by is to demystify how the GraphEval methodology works, so we are going to change the levels that might demand a heavy computational burden in a real-world setting with simulated, light-weight alternate options.
Accordingly, we are going to simulate a ground-truth data base (context) assumed to comprise factual info. In a manufacturing setting, this ground-truth data would stem, as an illustration, from retrieving related paperwork from the vector database of a retrieval-augmented technology (RAG) system. For simplicity, right here we straight create a ground-truth context and retailer it in source_context.
# The bottom-truth context offered to the LLM
source_context = (
    "GraphEval is a hallucination analysis framework primarily based on representing info "
    "in Data Graph (KG) buildings. It acts as a pre-processing step and makes use of "
    "out-of-the-box NLI fashions to detect factual inconsistencies."
)
Now, let’s suppose the next is the unique LLM response to a person immediate like “clarify succinctly what GraphEval is”. To provoke the primary stage of the analysis course of, we might ask an auxiliary LLM to construct the data graph from that response. Each the response and the follow-up immediate used to acquire the data graph are proven under:
# The generated response we need to consider (accommodates a hallucination)
llm_output = (
    "GraphEval is an analysis framework that makes use of Data Graphs. "
    "It requires a extremely costly, enterprise-level server farm to function."
)

# Immediate template that might theoretically be handed to a neighborhood/free LLM (e.g. Mistral-7B)
KG_EXTRACTION_PROMPT = f"""
You're an skilled info extractor. Extract the core info from the next textual content as a Data Graph.
Return the output strictly as a Python record of tuples within the format: (Topic, Relationship, Object).

Textual content: {llm_output}
"""
As soon as once more, for the sake of simplicity and to bypass the in any other case heavy computational load of operating an enormous LLM domestically, let’s suppose the next graph triples are obtained:
# Simulated extraction to bypass the heavy computational load of operating an enormous LLM domestically
extracted_triples = [
    ("GraphEval", "is", "evaluation framework"),
    ("GraphEval", "uses", "Knowledge Graphs"),
    ("GraphEval", "requires", "expensive enterprise server farm")
]

print("Extracted Triples:")
for t in extracted_triples:
    print(t)
Output:
Extracted Triples:
('GraphEval', 'is', 'analysis framework')
('GraphEval', 'makes use of', 'Data Graphs')
('GraphEval', 'requires', 'costly enterprise server farm')
We intentionally added a triple that’s basically a hallucination (no enterprise server farm wanted in any way!), so we are able to show how the following NLI course of utilized to the data graph reveals it.
Sufficient simulated steps for right this moment. Let’s get into the actual motion for the following stage: the NLI course of. The following piece of code is prime to leveraging the concepts behind GraphEval. It makes use of a pre-trained NLI mannequin from Hugging Face — the mannequin is publicly accessible, so no entry token is required to obtain it — to match every triple in opposition to the ground-truth context. If no entailment is “predicted” by the NLI mannequin for a given triple, it’s labeled as a hallucination.
from transformers import pipeline

# Loading the open-source NLI mannequin
print("Loading DeBERTa NLI mannequin...")
nli_evaluator = pipeline("text-classification", mannequin="cross-encoder/nli-deberta-v3-small")

def evaluate_triple(context, triple):
    topic, relation, obj = triple
    speculation = f"{topic} {relation} {obj}"

    # Checking if the context entails the speculation
    outcome = nli_evaluator({"textual content": context, "text_pair": speculation})

    # NLI fashions usually output: 'entailment', 'impartial', or 'contradiction'
    label = outcome['label'].decrease()

    # In GraphEval, something apart from 'entailment' is flagged as a hallucination
    is_hallucinated = label != 'entailment'

    return is_hallucinated, label, speculation

# Working the analysis pipeline
evaluation_results = []

print("n--- GraphEval Outcomes ---")
for t in extracted_triples:
    is_hallucinated, nli_label, speculation = evaluate_triple(source_context, t)
    evaluation_results.append((is_hallucinated, nli_label))

    standing = "🚨 HALLUCINATION" if is_hallucinated else "✅ GROUNDED"
    print(f"{standing} | Triple: {t} | NLI Output: {nli_label}")
Output:
--- GraphEval Outcomes ---
✅ GROUNDED | Triple: ('GraphEval', 'is', 'analysis framework') | NLI Output: entailment
✅ GROUNDED | Triple: ('GraphEval', 'makes use of', 'Data Graphs') | NLI Output: entailment
🚨 HALLUCINATION | Triple: ('GraphEval', 'requires', 'costly enterprise server farm') | NLI Output: impartial
As we anticipated, the final triple within the data graph is detected as a hallucination.
To complete with a visible contact, we are able to additionally show the data graph of the unique LLM response alongside the detection outcomes:
import networkx as nx
import matplotlib.pyplot as plt
import matplotlib.patches as mpatches

def visualize_grapheval(triples, eval_results):
    G = nx.DiGraph()
    edge_colors = []

    for (triple, res) in zip(triples, eval_results):
        sub, rel, obj = triple
        is_hallucinated = res[0]

        G.add_node(sub)
        G.add_node(obj)
        G.add_edge(sub, obj, label=rel)

        # Colour-code the sides primarily based on the NLI analysis
        edge_colors.append('pink' if is_hallucinated else 'inexperienced')

    # Arrange the plot
    plt.determine(figsize=(10, 6))
    pos = nx.spring_layout(G, seed=42)

    # Draw nodes
    nx.draw_networkx_nodes(G, pos, node_color="lightblue", node_size=2500)
    nx.draw_networkx_labels(G, pos, font_size=10, font_weight="daring")

    # Draw edges and labels
    nx.draw_networkx_edges(G, pos, edge_color=edge_colors, width=2.5, arrowsize=20)
    edge_labels = nx.get_edge_attributes(G, 'label')
    nx.draw_networkx_edge_labels(G, pos, edge_labels=edge_labels, font_color="black")

    # Add legend
    green_patch = mpatches.Patch(coloration="inexperienced", label="Grounded (Entailment)")
    red_patch = mpatches.Patch(coloration="pink", label="Hallucination (Impartial/Contradiction)")
    plt.legend(handles=[green_patch, red_patch], loc="decrease proper")

    plt.title("GraphEval Hallucination Map", fontsize=14, fontweight="daring")
    plt.axis('off')
    plt.tight_layout()
    plt.present()

# Render the data graph
visualize_grapheval(extracted_triples, evaluation_results)
Ensuing visualization:
# Closing Remarks
GraphEval is an analysis methodology proposed to assist detect and localize the foundation reason behind hallucinations in LLM outputs. This text turned its key rules and methodological levels right into a simulated sensible situation to raised perceive its usefulness and its key implications for potential implementation in manufacturing techniques.
Iván Palomares Carrascosa is a pacesetter, author, speaker, and adviser in AI, machine studying, deep studying & LLMs. He trains and guides others in harnessing AI in the actual world.