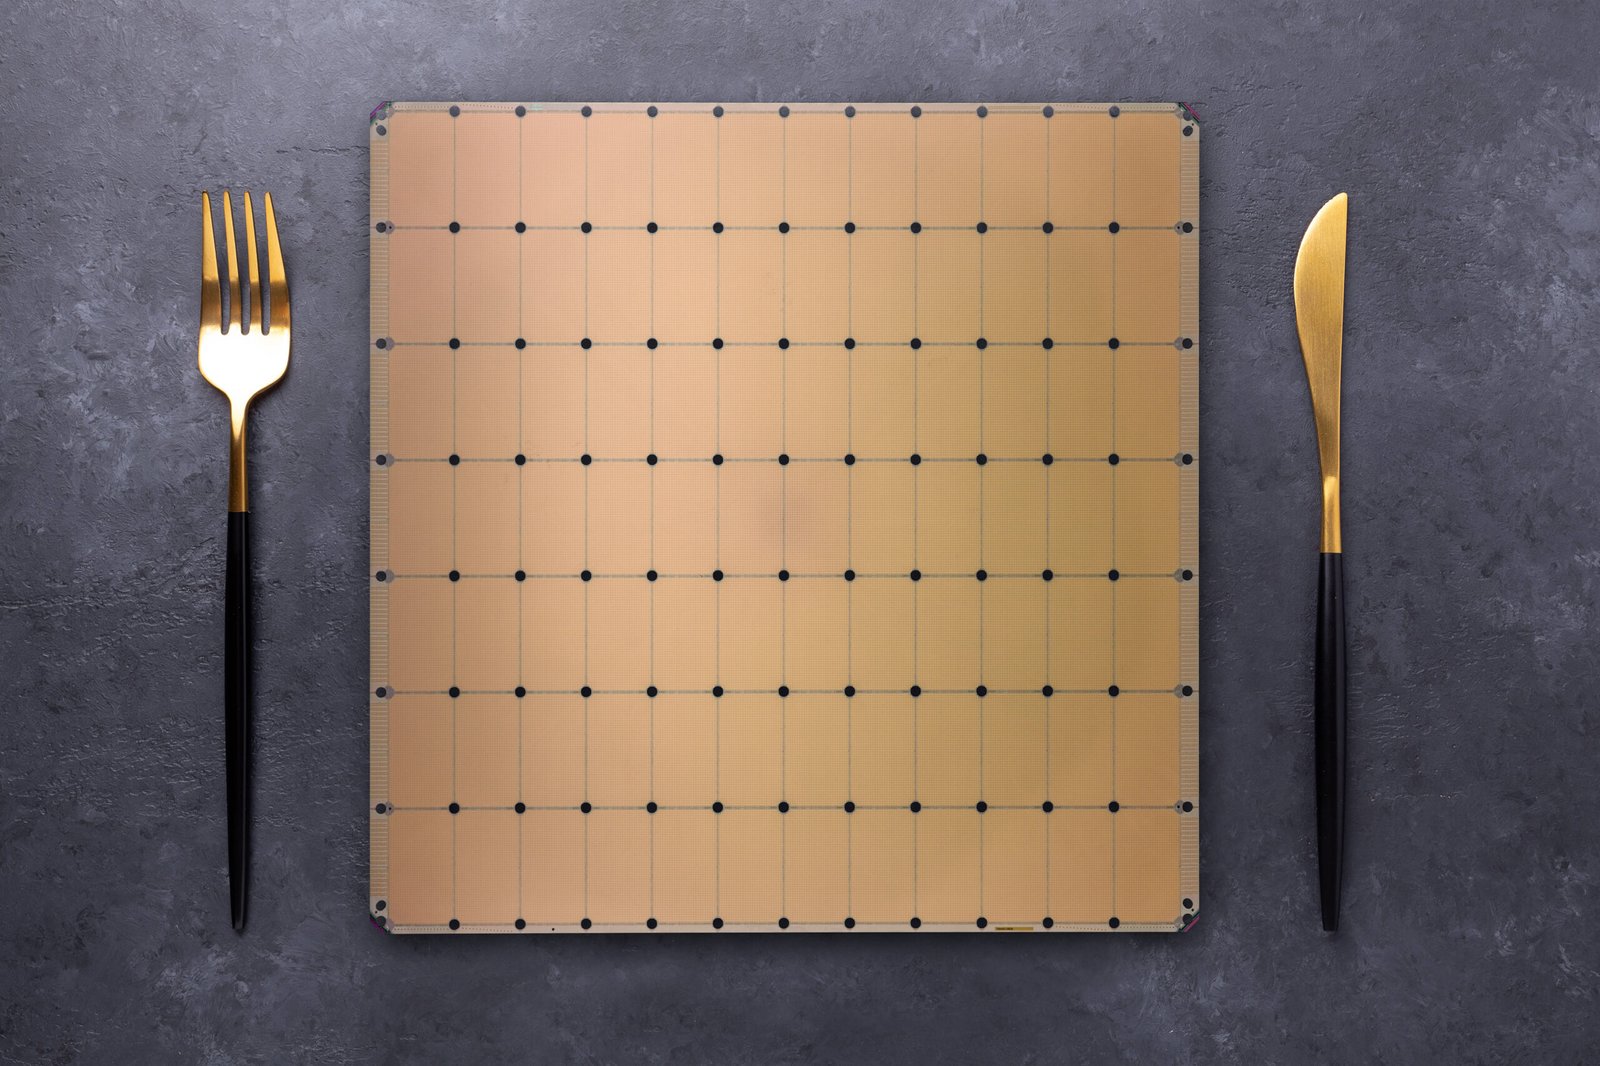
OpenAI says it’ll deploy 750 megawatts price of Nvidia competitor Cerebras’ dinner-plate sized accelerators by 2028 to bolster its inference providers.
The deal, which can see Cerebras tackle the chance of constructing and leasing datacenters to serve OpenAI, is valued at greater than $10 billion, sources accustomed to the matter inform El Reg.
By integrating Cerebras’ wafer-scale compute structure into its inference pipeline, OpenAI can reap the benefits of the chip’s large SRAM capability to hurry up inference. Every of the chip startup’s WSE-3 accelerators measures in at 46,225 mm2 and is provided with 44 GB of SRAM.
In comparison with the HBM discovered on trendy GPUs, SRAM is a number of orders of magnitude quicker. Whereas a single Nvidia Rubin GPU can ship round 22 TB/s of reminiscence bandwidth, Cerebras’ chips obtain almost 1,000x that at 21 Petabytes a second.
All that bandwidth interprets into extraordinarily quick inference efficiency. Working fashions like OpenAI’s gpt-oss 120B, Cerebras’ chips can purportedly obtain single person efficiency of three,098 tokens a second as in comparison with 885 tok/s for competitor Collectively AI, which makes use of Nvidia GPUs.
Within the age of reasoning fashions and AI brokers, quicker inference means fashions can “suppose” for longer with out compromising on interactivity.
“Integrating Cerebras into our mixture of compute options is all about making our AI reply a lot quicker. Once you ask a tough query, generate code, create a picture, or run an AI agent, there’s a loop taking place behind the scenes: you ship a request, the mannequin thinks, and it sends one thing again,” OpenAI defined in a latest weblog put up. “When AI responds in actual time, customers do extra with it, keep longer, and run higher-value workloads.”
Nevertheless, Cerebras’ structure has some limitations. SRAM is not notably area environment friendly, which is why, regardless of the chip’s spectacular dimension, they solely pack about as a lot reminiscence as a six-year-old Nvidia A100 PCIe card.
Due to this, bigger fashions should be parallelized throughout a number of chips, every of that are rated for a prodigious 23 kW of energy. Relying on the precision used, the variety of chips required could be appreciable. At 16-bit precision, which Cerebras has traditionally most well-liked for its higher-quality outputs, each billion parameters ate up 2 GB of SRAM capability. In consequence, even modest fashions like Llama 3 70B required not less than 4 of its CS-3 accelerators to run.
It has been almost two years since Cerebras unveiled a brand new wafer scale accelerator, and since then the corporate’s priorities have shifted from coaching to inference. We suspect the chip biz’s subsequent chip might dedicate a bigger space to SRAM and add help for contemporary block floating level information sorts like MXFP4, which ought to dramatically enhance the scale of the fashions that may be served on a single chip.
Having mentioned that, the introduction of a mannequin router with the launch of OpenAI’s GPT-5 final summer season ought to assist mitigate Cerebras’ reminiscence constraints. The method ensures that the overwhelming majority of requests fielded by ChatGPT are fulfilled by smaller cost-optimized fashions. Solely essentially the most advanced queries run on OpenAI’s largest and most resource-intensive fashions.
It is also attainable that OpenAI might select to run a portion of its inference pipeline on Cerebras’ equipment. Over the previous 12 months, the idea of disaggregated inference has taken off.
In concept, OpenAI might run compute-heavy immediate processing on AMD or Nvidia GPUs and offload token technology to Cerebras’ SRAM packed accelerators for the workload’s bandwidth-constrained token technology section. Whether or not that is truly an possibility will depend upon Cerebras.
“This can be a Cloud service settlement. We construct out datacenters with our gear for OpenAI to energy their fashions with the quickest inference,” an organization spokesperson advised El Reg when requested about the potential of utilizing its CS-3s in a disaggregated compute structure.
This does not imply it will not occur, however it could be on Cerebras to deploy the GPU techniques required to help such a configuration in its datacenters alongside its waferscale accelerators. ®