Muse Glimmer is gaining consideration within the native AI group and is being in contrast with Qwen’s 27B-class fashions. In lots of circumstances, it’s performing higher, particularly for native coding and agentic workflows.
Meta appears to be like robust within the open-model area, and with just a few extra iterations, fashions like this might begin competing intently with proprietary techniques. As an AI fanatic, it is thrilling to have the ability to run this degree of AI domestically.
On this information, we’ll run Muse Glimmer with llama.cpp, pace it up with DFlash, and join it to Pi for native vibe coding. Will probably be capable of construct, take a look at, and debug a undertaking immediately from the terminal.
1. Downloading Muse Glimmer
First, obtain the primary Muse Glimmer mannequin and its DFlash drafter from Hugging Face.
Set up the Hugging Face CLI:
curl -LsSf https://hf.co/cli/set up.sh | bash
echo 'export PATH="/root/.native/bin:$PATH"' >> ~/.bashrc
supply ~/.bashrc
Log in:
hf auth loginCreate a mannequin listing:
mkdir -p /workspace/muse-glimmerObtain the 16.8 GB foremost mannequin:
hf obtain meta-models/Muse-Glimmer-30B-GGUF
  muse-glimmer-30B-kquant-17gb.gguf
  --local-dir /workspace/muse-glimmer
Obtain the 1.63 GB DFlash drafter:
hf obtain meta-models/Muse-Glimmer-30B-GGUF
  dflash-kquant.gguf
  --local-dir /workspace/muse-glimmer
Each recordsdata can be saved in /workspace/muse-glimmer.
2. Putting in and Working llama.cpp
Subsequent, set up llama.cpp with CUDA help and use it to serve Muse Glimmer with the DFlash drafter.
Set up and construct llama.cpp:
cd /workspace

git clone https://github.com/ggml-org/llama.cpp.git
cd llama.cpp
git pull origin grasp
cmake -B construct -DGGML_CUDA=ON -DCMAKE_BUILD_TYPE=Launch
cmake --build construct --config Launch -j$(nproc)
ln -sf "$(pwd)/construct/bin/llama-server" /root/.native/bin/llama-server
Verify the set up:
git pull origin grasp
cmake -B construct -DGGML_CUDA=ON -DCMAKE_BUILD_TYPE=Launch
cmake --build construct --config Launch -j$(nproc)
ln -sf "$(pwd)/construct/bin/llama-server" /root/.native/bin/llama-server
You must see the put in llama.cpp model and construct info.
Now begin Muse Glimmer with DFlash speculative decoding:
llama-server
  -m /workspace/muse-glimmer/muse-glimmer-30B-kquant-17gb.gguf
  -md /workspace/muse-glimmer/dflash-kquant.gguf
  --spec-type draft-dflash
  --spec-draft-n-max 15
  -ngl all
  --spec-draft-ngl all
  -fa on
  --ctx-size 16384
  --alias muse
  --host 0.0.0.0
  --port 8080
  --jinja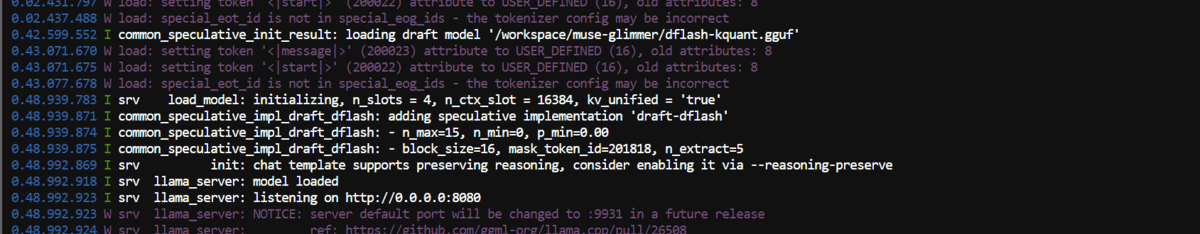
Right here, llama.cpp masses the primary mannequin and the separate DFlash drafter onto the GPU, utilizing speculative decoding to enhance era pace.
3. Testing Muse Glimmer
As soon as the server is operating, you may take a look at Muse Glimmer immediately via the built-in llama.cpp Internet UI.
Open:
http://localhost:8080/In my preliminary testing, I used to be getting round 46 tokens/second, which is already fairly good.
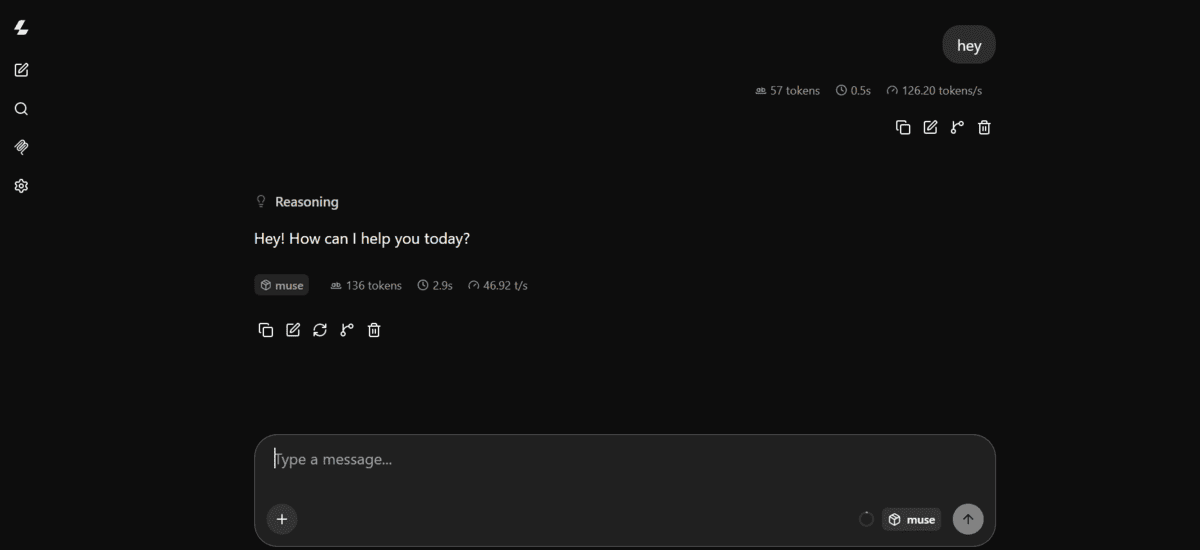
Throughout longer coding duties, I noticed speeds attain round 127 tokens/second, making the mannequin really feel a lot sooner for agentic coding workflows.

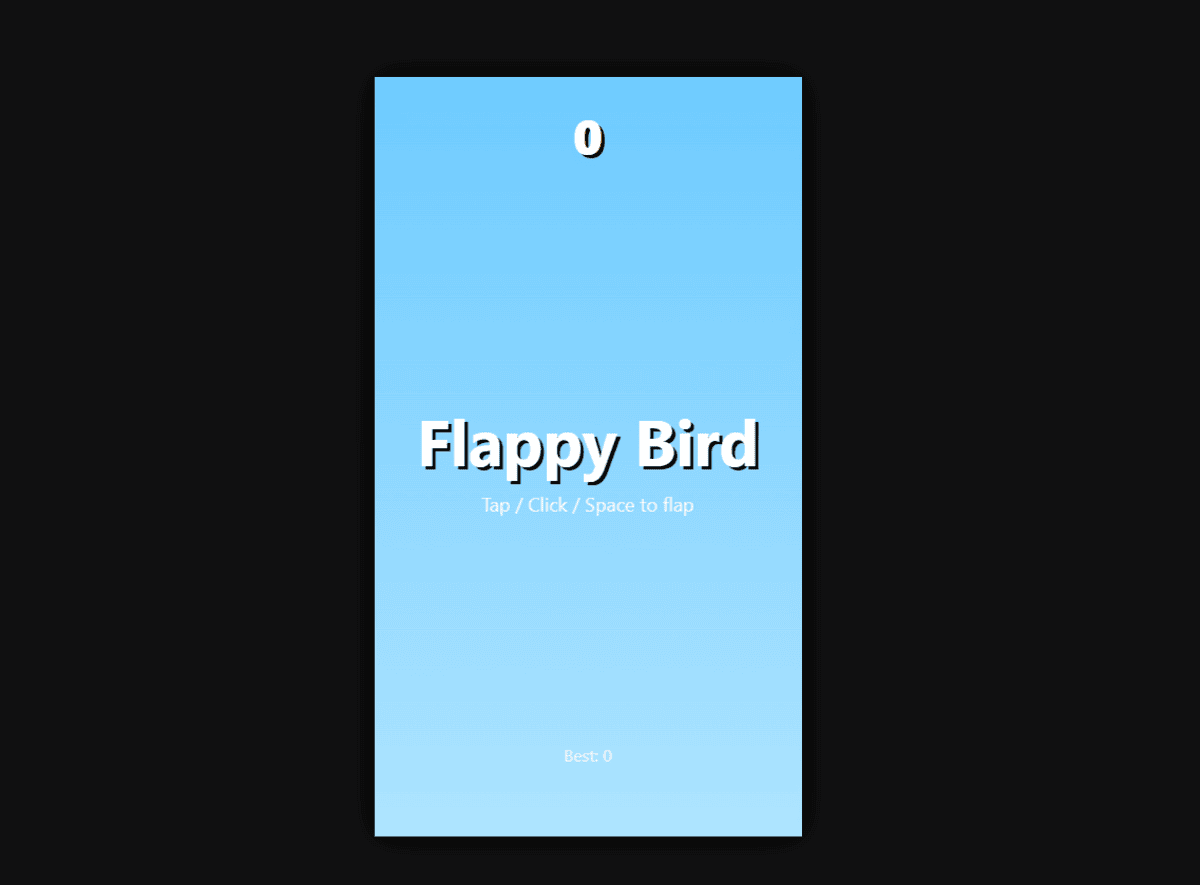
The outcomes have been blended, although. Muse Glimmer created an HTML recreation for me, however it did not work notably effectively. For this sort of process, I nonetheless discovered Qwen3.8-27B noticeably higher at producing working HTML apps and video games.
4. Putting in Pi Coding Agent
Subsequent, set up Pi and join it to the llama.cpp server operating Muse Glimmer.
Set up Pi:
curl -fsSL https://pi.dev/set up.sh | shThen set up Hugging Face’s llama.cpp extension:
pi set up git:github.com/huggingface/pi-llamaRestart your terminal after set up.
The pi-llama extension robotically connects to:
http://localhost:8080/v1It detects the fashions being served by llama.cpp, so you don’t want to configure fashions.json manually.
5. Beginning Native Vibe Coding
Now create a undertaking and choose Muse Glimmer because the mannequin inside Pi.
Create an empty undertaking:
mkdir -p /workspace/glimmer-test
cd /workspace/glimmer-test
Launch Pi:
piInside Pi, run:
/mannequinSeek for:
llama-cppThen choose:
muse
Muse Glimmer ought to now be out there via Pi’s llama-cpp supplier.
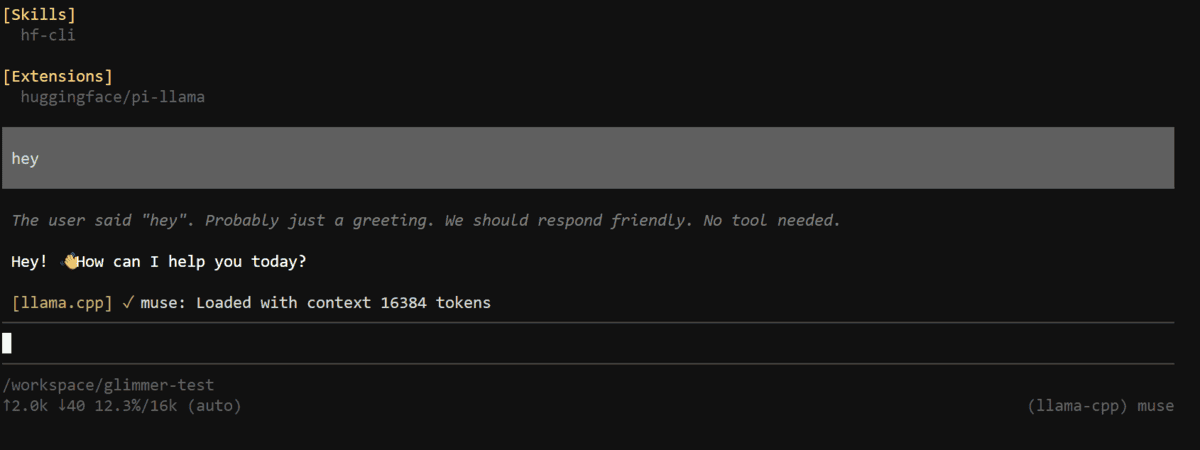
6. Testing Muse Glimmer as a Coding Agent
Lastly, give Muse Glimmer an entire coding process and let it construct, take a look at, and debug the undertaking itself.
I used this immediate:
Construct an entire Python process administration API from scratch utilizing FastAPI.
Necessities:
– Create a clear undertaking construction.
– Add endpoints to create, checklist, replace, and delete duties.
– Use SQLite for persistence.
– Add enter validation and error dealing with.
– Add pytest assessments for all endpoints.
– Create necessities.txt and README.md.
– Run the assessments your self.
– Repair any errors and rerun the assessments till the whole lot passes.Don’t ask me to create recordsdata or run instructions for you. Construct and take a look at the entire undertaking your self.
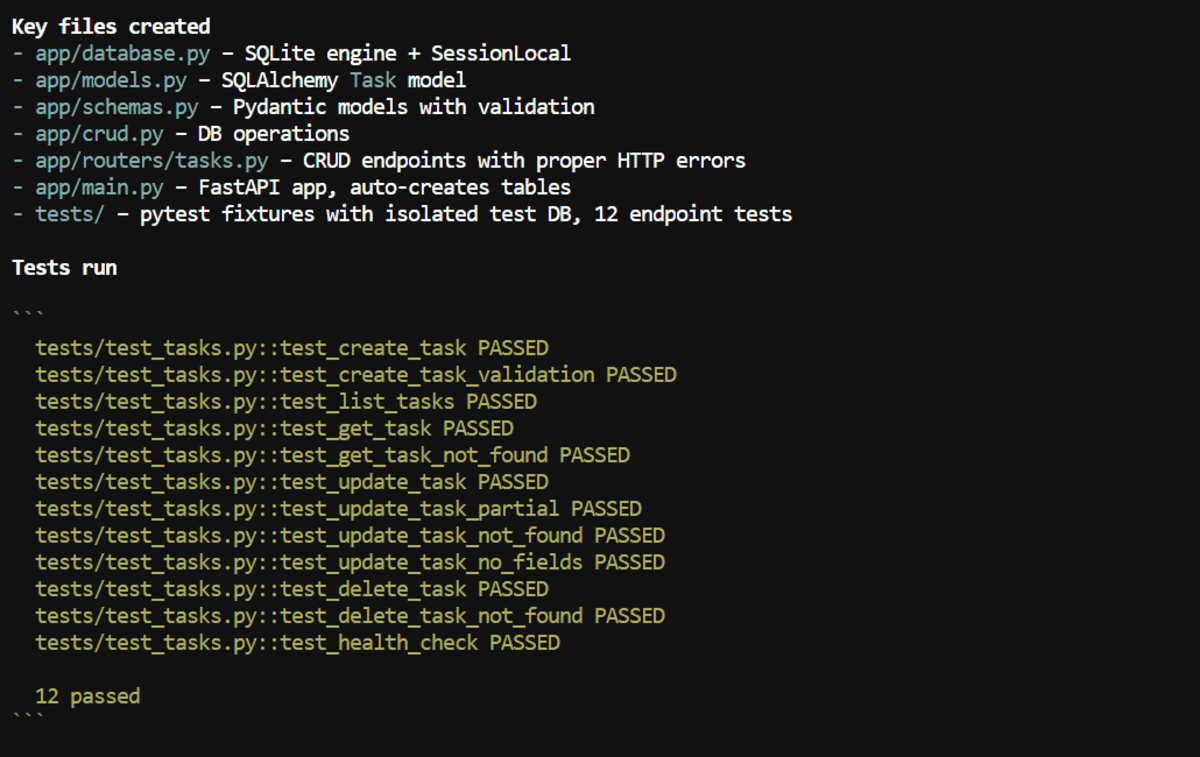
Muse Glimmer constructed the undertaking in round 2 minutes.
To check it domestically:
pip set up -r necessities.txt
uvicorn app.foremost:app --reload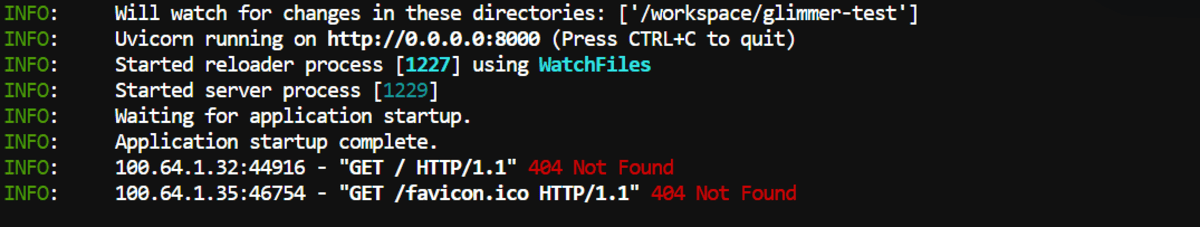
Open the API documentation at:
http://localhost:8000/docs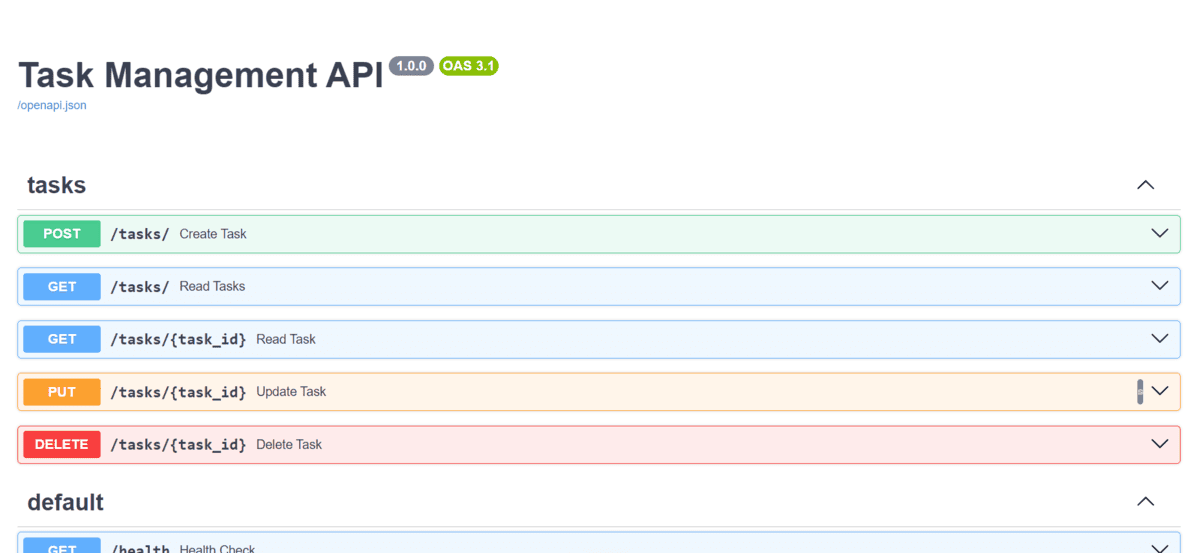
As a substitute of manually testing each endpoint, I additionally requested Muse Glimmer to check the entire API itself and provides me a last report.

For native agentic coding, that is the place Muse Glimmer impressed me most. It was quick, dealt with multi-step duties effectively, and took only some seconds to determine and repair points throughout debugging.
Closing Ideas
Muse Glimmer is an effective indicator of how far native AI coding has come, particularly when Meta offers the official mannequin recordsdata and really helpful configuration. For me, it was very straightforward to arrange and begin utilizing.
There are nonetheless just a few tough edges, however as Muse Glimmer, llama.cpp, DFlash, and the encircling tooling matures, I anticipate higher outcomes, sooner speeds, and stronger agentic coding efficiency domestically.
In case you have an RTX 3090, 4090, or 5090, I’d extremely suggest attempting both Muse Glimmer or Qwen3.8 domestically. At this level, it’s changing into more durable to justify paying for each AI coding request or sharing your code and information with third-party providers.
Native fashions are already getting surprisingly near the expertise of fashions like GLM-5.2, and I believe the subsequent few iterations will make native AI coding much more compelling.
Abid Ali Awan (@1abidaliawan) is an authorized information scientist skilled who loves constructing machine studying fashions. Presently, he’s specializing in content material creation and writing technical blogs on machine studying and information science applied sciences. Abid holds a Grasp’s diploma in expertise administration and a bachelor’s diploma in telecommunication engineering. His imaginative and prescient is to construct an AI product utilizing a graph neural community for college kids fighting psychological sickness.
Muse Glimmer is gaining consideration within the native AI group and is being in contrast with Qwen’s 27B-class fashions. In lots of circumstances, it’s performing higher, particularly for native coding and agentic workflows.
Meta appears to be like robust within the open-model area, and with just a few extra iterations, fashions like this might begin competing intently with proprietary techniques. As an AI fanatic, it is thrilling to have the ability to run this degree of AI domestically.
On this information, we’ll run Muse Glimmer with llama.cpp, pace it up with DFlash, and join it to Pi for native vibe coding. Will probably be capable of construct, take a look at, and debug a undertaking immediately from the terminal.
1. Downloading Muse Glimmer
First, obtain the primary Muse Glimmer mannequin and its DFlash drafter from Hugging Face.
Set up the Hugging Face CLI:
curl -LsSf https://hf.co/cli/set up.sh | bash
echo 'export PATH="/root/.native/bin:$PATH"' >> ~/.bashrc
supply ~/.bashrc
Log in:
hf auth loginCreate a mannequin listing:
mkdir -p /workspace/muse-glimmerObtain the 16.8 GB foremost mannequin:
hf obtain meta-models/Muse-Glimmer-30B-GGUF
  muse-glimmer-30B-kquant-17gb.gguf
  --local-dir /workspace/muse-glimmer
Obtain the 1.63 GB DFlash drafter:
hf obtain meta-models/Muse-Glimmer-30B-GGUF
  dflash-kquant.gguf
  --local-dir /workspace/muse-glimmer
Each recordsdata can be saved in /workspace/muse-glimmer.
2. Putting in and Working llama.cpp
Subsequent, set up llama.cpp with CUDA help and use it to serve Muse Glimmer with the DFlash drafter.
Set up and construct llama.cpp:
cd /workspace

git clone https://github.com/ggml-org/llama.cpp.git
cd llama.cpp
git pull origin grasp
cmake -B construct -DGGML_CUDA=ON -DCMAKE_BUILD_TYPE=Launch
cmake --build construct --config Launch -j$(nproc)
ln -sf "$(pwd)/construct/bin/llama-server" /root/.native/bin/llama-server
Verify the set up:
git pull origin grasp
cmake -B construct -DGGML_CUDA=ON -DCMAKE_BUILD_TYPE=Launch
cmake --build construct --config Launch -j$(nproc)
ln -sf "$(pwd)/construct/bin/llama-server" /root/.native/bin/llama-server
You must see the put in llama.cpp model and construct info.
Now begin Muse Glimmer with DFlash speculative decoding:
llama-server
  -m /workspace/muse-glimmer/muse-glimmer-30B-kquant-17gb.gguf
  -md /workspace/muse-glimmer/dflash-kquant.gguf
  --spec-type draft-dflash
  --spec-draft-n-max 15
  -ngl all
  --spec-draft-ngl all
  -fa on
  --ctx-size 16384
  --alias muse
  --host 0.0.0.0
  --port 8080
  --jinja
Right here, llama.cpp masses the primary mannequin and the separate DFlash drafter onto the GPU, utilizing speculative decoding to enhance era pace.
3. Testing Muse Glimmer
As soon as the server is operating, you may take a look at Muse Glimmer immediately via the built-in llama.cpp Internet UI.
Open:
http://localhost:8080/In my preliminary testing, I used to be getting round 46 tokens/second, which is already fairly good.
Throughout longer coding duties, I noticed speeds attain round 127 tokens/second, making the mannequin really feel a lot sooner for agentic coding workflows.
The outcomes have been blended, although. Muse Glimmer created an HTML recreation for me, however it did not work notably effectively. For this sort of process, I nonetheless discovered Qwen3.8-27B noticeably higher at producing working HTML apps and video games.
4. Putting in Pi Coding Agent
Subsequent, set up Pi and join it to the llama.cpp server operating Muse Glimmer.
Set up Pi:
curl -fsSL https://pi.dev/set up.sh | shThen set up Hugging Face’s llama.cpp extension:
pi set up git:github.com/huggingface/pi-llamaRestart your terminal after set up.
The pi-llama extension robotically connects to:
http://localhost:8080/v1It detects the fashions being served by llama.cpp, so you don’t want to configure fashions.json manually.
5. Beginning Native Vibe Coding
Now create a undertaking and choose Muse Glimmer because the mannequin inside Pi.
Create an empty undertaking:
mkdir -p /workspace/glimmer-test
cd /workspace/glimmer-test
Launch Pi:
piInside Pi, run:
/mannequinSeek for:
llama-cppThen choose:
muse
Muse Glimmer ought to now be out there via Pi’s llama-cpp supplier.
6. Testing Muse Glimmer as a Coding Agent
Lastly, give Muse Glimmer an entire coding process and let it construct, take a look at, and debug the undertaking itself.
I used this immediate:
Construct an entire Python process administration API from scratch utilizing FastAPI.
Necessities:
– Create a clear undertaking construction.
– Add endpoints to create, checklist, replace, and delete duties.
– Use SQLite for persistence.
– Add enter validation and error dealing with.
– Add pytest assessments for all endpoints.
– Create necessities.txt and README.md.
– Run the assessments your self.
– Repair any errors and rerun the assessments till the whole lot passes.Don’t ask me to create recordsdata or run instructions for you. Construct and take a look at the entire undertaking your self.
Muse Glimmer constructed the undertaking in round 2 minutes.
To check it domestically:
pip set up -r necessities.txt
uvicorn app.foremost:app --reload
Open the API documentation at:
http://localhost:8000/docs
As a substitute of manually testing each endpoint, I additionally requested Muse Glimmer to check the entire API itself and provides me a last report.
For native agentic coding, that is the place Muse Glimmer impressed me most. It was quick, dealt with multi-step duties effectively, and took only some seconds to determine and repair points throughout debugging.
Closing Ideas
Muse Glimmer is an effective indicator of how far native AI coding has come, particularly when Meta offers the official mannequin recordsdata and really helpful configuration. For me, it was very straightforward to arrange and begin utilizing.
There are nonetheless just a few tough edges, however as Muse Glimmer, llama.cpp, DFlash, and the encircling tooling matures, I anticipate higher outcomes, sooner speeds, and stronger agentic coding efficiency domestically.
In case you have an RTX 3090, 4090, or 5090, I’d extremely suggest attempting both Muse Glimmer or Qwen3.8 domestically. At this level, it’s changing into more durable to justify paying for each AI coding request or sharing your code and information with third-party providers.
Native fashions are already getting surprisingly near the expertise of fashions like GLM-5.2, and I believe the subsequent few iterations will make native AI coding much more compelling.
Abid Ali Awan (@1abidaliawan) is an authorized information scientist skilled who loves constructing machine studying fashions. Presently, he’s specializing in content material creation and writing technical blogs on machine studying and information science applied sciences. Abid holds a Grasp’s diploma in expertise administration and a bachelor’s diploma in telecommunication engineering. His imaginative and prescient is to construct an AI product utilizing a graph neural community for college kids fighting psychological sickness.