of my knowledge engineering journey collection. Partly one, I shared my 12-month roadmap for transitioning from knowledge analyst to knowledge engineer. That is the place the precise constructing begins.
Once I printed my first article documenting my knowledge engineering journey, one thing sudden occurred. Individuals resonated with it. I had strangers reaching out saying they had been excited to observe alongside. That felt good.
However it additionally got here with stress.
All of a sudden this wasn’t only a private aim I may quietly abandon if issues received arduous. Individuals had been watching. Individuals had been in the identical boat. And that accountability, actually, is a part of why you’re studying this proper now.
So I needed to transfer. And like anybody beginning a brand new talent, the very first thing I did was search for sources. There are numerous tutorials on the web for knowledge engineering. YouTube movies, programs, written guides. Greater than you may ever end.
However I couldn’t carry myself to only devour idea. I wanted to construct one thing. One thing actual, with actual knowledge, that truly labored on the finish.
So I closed the tutorials and opened a Google Colab pocket book as an alternative. I discovered the GitHub API documentation and determined I used to be going to construct my first ETL pipeline from scratch. No hand-holding. Simply me, some Python, and a aim.
This text is that have documented in full. The code, the confusion, the small wins, and what I really discovered by doing it.
First, what’s ETL?
Earlier than I get into what I constructed, let me shortly clarify what ETL really means as a result of I needed to look this up myself not too way back.
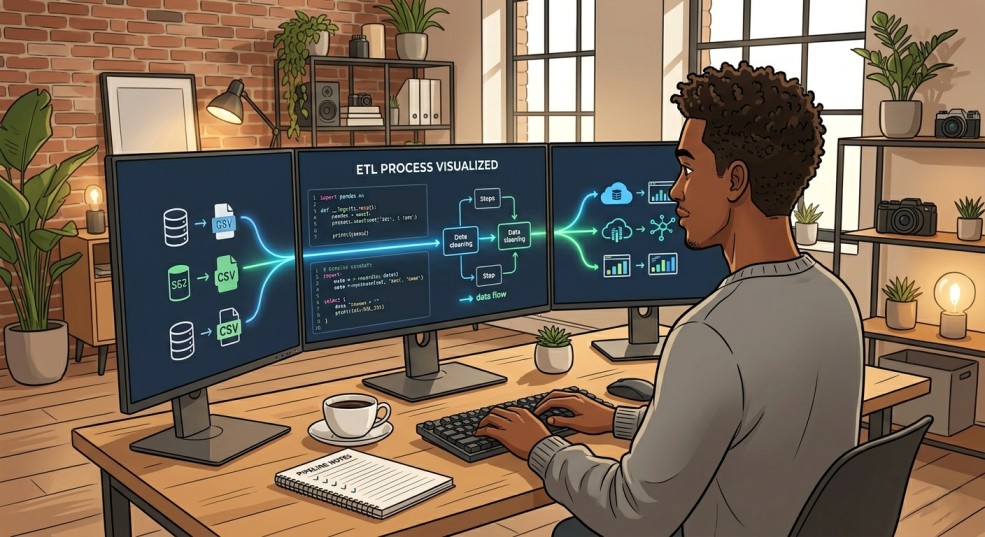
ETL stands for Extract, Rework, Load. It’s one of the basic ideas in knowledge engineering.
- Extract means going someplace to get knowledge. An API, a database, an internet site, a file. You’re pulling uncooked data from a supply.
- Rework means cleansing and shaping that knowledge. Eradicating unhealthy rows, including new columns, restructuring it so it’s really helpful.
- Load means saving the cleaned knowledge someplace. A database, an information warehouse, a easy CSV file.
That’s it. These three steps, carried out in sequence, are what an information pipeline is. All the pieces else in knowledge engineering, Airflow, Spark, Databricks, is simply extra subtle methods of doing those self same three issues at scale.
I’m initially of my roadmap, so I stored it easy. Pure Python, no orchestration instruments but. However the form of the issue is similar.
What I constructed
I extracted knowledge from the GitHub API, particularly probably the most starred Python repositories created within the final 30 days. I then cleaned it, added a brand new column, and saved the output as a CSV file.
Easy. Actual. Fully mine.
Right here’s the way it went.
Step 1: Extract
The very first thing I needed to do was determine tips on how to discuss to the GitHub API. An API is principally a door that an organization or platform opens in order that builders can request knowledge from it programmatically, with out having to manually copy and paste something.
GitHub has a free, public API. No account or paid plan wanted for fundamental searches.
Right here’s the code I wrote to extract the info:
import requests

url = "https://api.github.com/search/repositories"

params = {
    "q": "language:python created:>2025-04-22",
    "type": "stars",
    "order": "desc",
    "per_page": 30
}

response = requests.get(url, params=params)
knowledge = response.json()

print(response.status_code)
print(knowledge.keys())
I’ll be trustworthy. This block confused me at first. The requests library was new to me. The params dictionary with that q syntax felt alien. I didn’t instantly know what .json() was doing or why I wanted it.
Let me break it down merely.
requests.get()is the way you knock on GitHub’s door and ask for one thing. Theurlis the handle of what you’re asking for. Theparamsdictionary is the precise query you’re asking. On this case: “give me Python repos, sorted by stars, created after April 22, present me 30 outcomes.”.json()converts GitHub’s response from uncooked textual content right into a Python dictionary that you would be able to really work with.
Once I ran it, I received this:
200
dict_keys(['total_count', 'incomplete_results', 'items'])
The 200 means success. That’s the web’s method of claiming “your request labored.” For those who see 403 or 404, one thing went fallacious.
The dictionary has three keys. total_count tells you what number of repos matched the search. incomplete_results tells you if GitHub needed to minimize something brief. And objects is the place the precise knowledge lives.
I then ran a second block to peek inside:
print("Complete matches on GitHub:", knowledge['total_count'])
print("Repos returned:", len(knowledge['items']))

first_repo = knowledge['items'][0]
print("nFirst repo title:", first_repo['name'])
print("Stars:", first_repo['stargazers_count'])
print("Language:", first_repo['language'])
print("URL:", first_repo['html_url'])
Output:
Complete matches on GitHub: 9228201
Repos returned: 30

First repo title: expertise
Stars: 139136
Language: Python
URL: https://github.com/anthropics/expertise
The primary outcome was an Anthropic repo with 139k stars. Actual knowledge. Dwell. Pulled by code I wrote.
That’s Extract carried out.
Step 2: Rework
Now I had 30 repos sitting in a Python checklist, each a nested dictionary with dozens of fields. Most of which I didn’t want. The Rework step is the place you are taking that uncooked, messy knowledge and form it into one thing clear and purposeful.
First I pulled out solely the fields I cared about and loaded them right into a Pandas dataframe:
import pandas as pd

repos = []

for repo in knowledge['items']:
    repos.append({
        "title": repo['name'],
        "proprietor": repo['owner']['login'],
        "stars": repo['stargazers_count'],
        "forks": repo['forks_count'],
        "language": repo['language'],
        "description": repo['description'],
        "url": repo['html_url'],
        "created_at": repo['created_at']
    })

df = pd.DataFrame(repos)
df.head()
Seeing that dataframe seem was a correct “wow” second. I went from a wall of JSON to a clear, readable desk with labelled columns in just a few strains.
Then I did three transformations:
# Drop rows the place description is lacking
df_clean = df.dropna(subset=['description'])

# Add a viral flag for repos with over 50k stars
df_clean = df_clean.copy()
df_clean['viral'] = df_clean['stars'].apply(lambda x: 'Sure' if x > 50000 else 'No')

# Kind by stars descending
df_clean = df_clean.sort_values('stars', ascending=False).reset_index(drop=True)

print("Earlier than cleansing:", len(df))
print("After cleansing:", len(df_clean))
Output:
Earlier than cleansing: 30
After cleansing: 29
One repo had no description and received dropped. The viral column confirmed up cleanly. The info was now sorted and structured.
That’s Rework carried out.
Step 3: Load
The ultimate step. Take the clear knowledge and put it aside someplace. I stored this straightforward and loaded it right into a CSV file:
df_clean.to_csv('github_trending_repos.csv', index=False)

print("Pipeline full. File saved.")
print(f"{len(df_clean)} repos loaded into github_trending_repos.csv")
Output:
Pipeline full. File saved.
29 repos loaded into github_trending_repos.csv
I downloaded the file and opened it. A clear spreadsheet with 29 rows and 9 columns. Actual GitHub knowledge, formed and saved by a pipeline I constructed from scratch.
That’s Load carried out.
What this really felt like
Earlier than this, at any time when I needed knowledge to work with, I’d go on the lookout for a public dataset somebody had already cleaned and uploaded. Kaggle, Google Dataset Search, wherever. I used to be all the time a client of information that another person had ready.
This modified one thing for me.
The second I realised I may simply level Python at an API I used to be interested by and extract reside knowledge myself, the probabilities felt fully completely different. I’m not restricted to datasets that exist already. I can construct the pipeline that creates the dataset.
That’s a special form of energy. And it’s one of many issues that drew me towards knowledge engineering within the first place.
What’s subsequent
This pipeline is straightforward by design. I’m at the beginning of my roadmap and I’m not going to fake I’m utilizing Airflow or Spark but. However the basis is actual. Extract, Rework, Load. It really works. I constructed it. I perceive it.
The following step is to make it extra strong. Schedule it to run every day. Retailer the output in a SQLite database as an alternative of a flat CSV. Begin monitoring how repos development over time.
And finally, orchestrate the entire thing with Airflow. However that’s a future article.
For now, an important factor I proved to myself is that constructing teaches you issues that watching by no means will. I spent weeks in tutorial land and barely moved. I spent one afternoon really constructing, and I perceive ETL higher than any video made it really feel.
Cease watching. Begin constructing.
That is half two of my ongoing knowledge engineering collection. Comply with alongside as I doc each step of the journey, together with the elements that don’t go easily. Be happy to take a look at my extra in-depth ETL tackle my YouTube channel beneath.