

Giant language fashions are outstanding textual content mills, however they’ve a well-documented weak spot: they hallucinate. With out entry to verified, up-to-date data, they confidently produce plausible-sounding solutions which can be factually incorrect. Retrieval-Augmented Era (RAG) emerged as the usual answer, grounding mannequin outputs in exterior information sources and dramatically lowering hallucinations throughout enterprise purposes.
However as organizations push these programs into extra advanced workflows, a brand new drawback has surfaced. Normal RAG pipelines are linear — they retrieve as soon as, cross these outcomes to the mannequin, and generate a solution. When the question is easy and the information base is well-structured, this works tremendous. When the question requires multi-step reasoning, cross-referencing a number of sources, or synthesizing data that does not exist in a single doc, the pipeline begins to crack.
That is the place Agentic RAG is available in. Quite than treating retrieval as a single, fastened step, it provides the system the flexibility to motive about the best way to search, consider what it finds, and iterate till it reaches a satisfying reply.
We’ll break down how each architectures work, have a look at the place commonplace RAG hits its limits, and stroll by means of the particular capabilities that make agentic programs higher suited to advanced duties. By the tip, you may have a transparent framework for deciding which method matches your subsequent undertaking.
The Baseline: Understanding Naive RAG
Earlier than inspecting the place retrieval programs are going, it helps to be exact about the place they began.
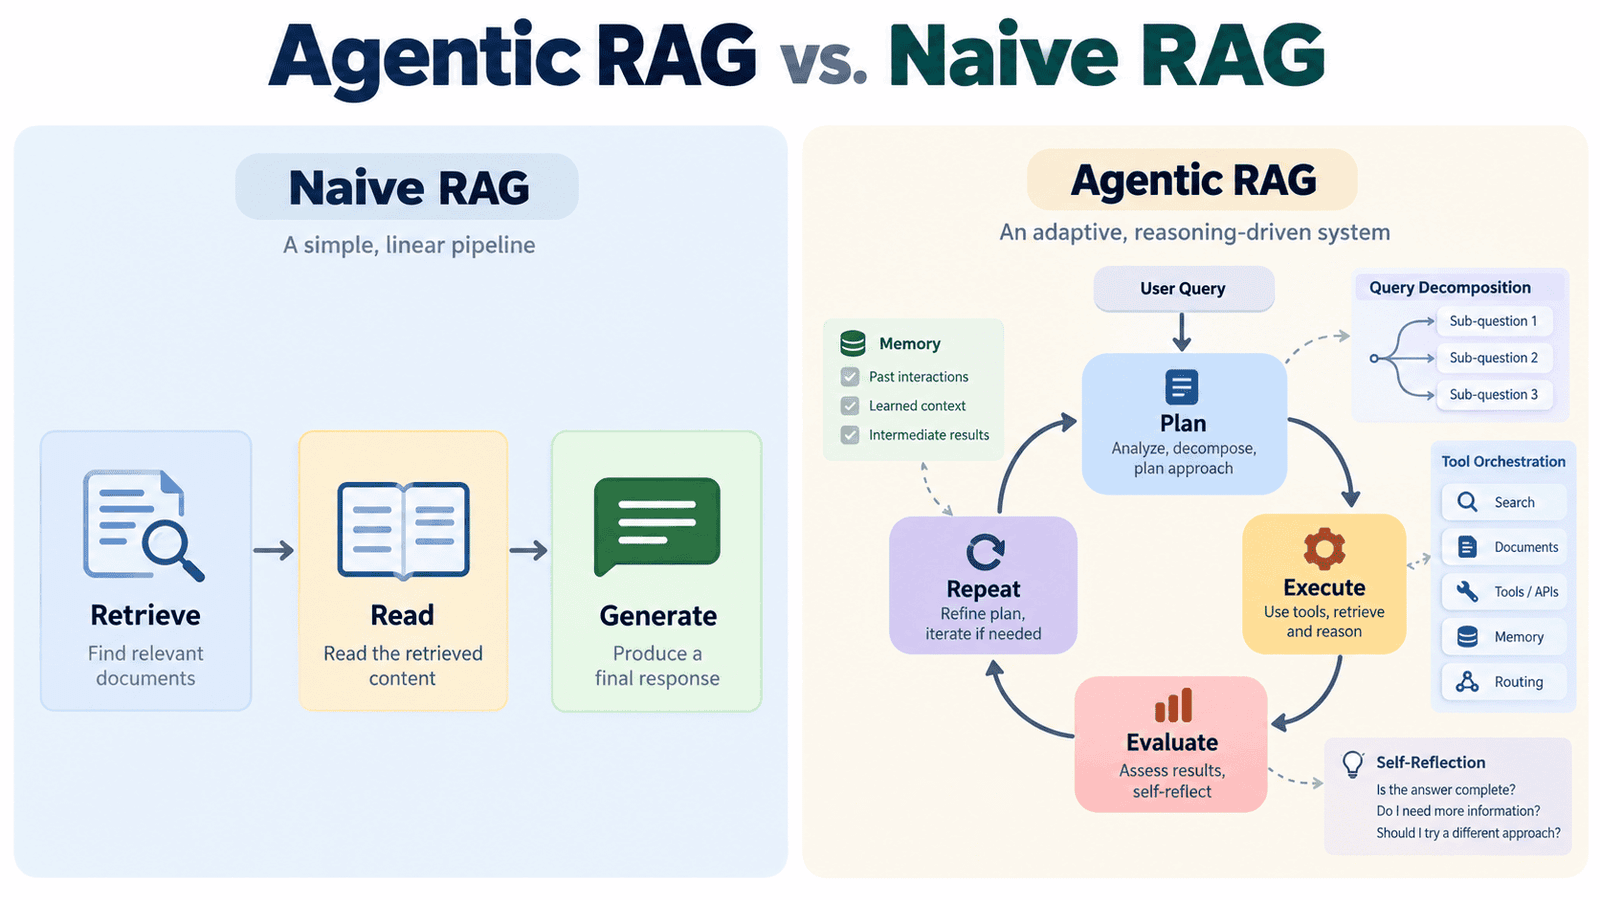
Naive RAG — additionally referred to as commonplace RAG — follows a inflexible three-stage pipeline: Retrieve → Learn → Generate. A person submits a question, the system converts it right into a vector embedding, runs a similarity search towards a vector database, retrieves the top-k most related doc chunks, and passes these chunks to the big language mannequin (LLM) as context. The mannequin then generates a response primarily based on what was retrieved.
Consider it like a scholar making ready for an examination in a big library. Naive RAG is the scholar who sorts a single key phrase into the catalog, grabs the primary three books on the shelf, and writes an essay primarily based solely on what’s in entrance of them — with out stopping to test whether or not these sources truly reply the query.
Underneath the hood, this is what occurs. When paperwork are ingested, they’re cut up into chunks and transformed into dense vector representations utilizing an embedding mannequin. These vectors are saved in a database optimized for approximate nearest-neighbor search. At inference time, the person’s question is embedded utilizing the identical mannequin, and the database returns the chunks whose vectors are closest in high-dimensional house. These chunks are then injected into the LLM’s context window as a reference.
This was a real breakthrough. Naive RAG made it attainable to construct enterprise Q&A programs, inner information assistants, and doc summarizers that stayed grounded in verified sources. For a lot of purposes, it stays a wonderful and cost-effective selection.
The Bottleneck: The place Naive RAG Breaks Down
The structure’s core weak spot is its linearity. A single retrieval cross both succeeds or it would not. If the preliminary question is poorly fashioned, if the related data is unfold throughout a number of paperwork, or if the reply requires reasoning throughout a number of steps, the pipeline has no approach to recuperate.
The Single-Go Limitation
Naive RAG will get one shot at retrieval. If the question’s embedding would not return the suitable chunks, the mannequin is left producing a response from incomplete or irrelevant context. It could’t acknowledge that the retrieval failed, and it might probably’t strive a unique method.
Multi-Hop Reasoning Failures
Think about a question like: “What regulatory insurance policies does the corporate that acquired WhatsApp comply with within the European Union?”
Answering this accurately requires at the least two steps:
- Determine that Meta acquired WhatsApp.
- Retrieve Meta’s EU regulatory insurance policies.
A single vector search towards “WhatsApp EU regulatory insurance policies” will doubtless fail to bridge that connection — particularly if these two items of data reside in separate paperwork. Naive RAG has no approach to decompose this into sequential sub-questions, retrieve the intermediate reply, after which use it to tell a second search.
Susceptibility to Unhealthy Retrieval
When the top-k outcomes are genuinely irrelevant to the question, the LLM faces an unimaginable state of affairs. It both generates a response that ignores its grounding context (which produces hallucinations) or outputs an sincere however unhelpful “I haven’t got sufficient data to reply.” In high-stakes enterprise settings, neither final result is appropriate.
Agentic RAG: Giving the System a Mind
Agentic RAG reframes the retrieval drawback fully. As a substitute of treating the LLM as a passive textual content generator that receives context and produces output, it treats the LLM as an autonomous reasoning engine that actively orchestrates your complete retrieval course of.
The place Naive RAG is a pipeline, Agentic RAG is a loop: Plan → Execute → Consider → Repeat.
Again to the library analogy. A devoted analysis assistant would not simply seize the primary three books and begin writing. They learn the preliminary sources, discover a key piece of proof is lacking, open a unique database, cross-reference two conflicting claims, and solely sit down to write down as soon as they’re assured their sources are ample. Agentic RAG builds that habits into the retrieval system itself.
The LLM is now not a shopper of retrieved context — it is the orchestrator, deciding what to retrieve, the place to retrieve it from, whether or not the outcomes are ok, and what to do if they don’t seem to be. This transforms retrieval from a set pre-processing step right into a dynamic, self-correcting course of.
The core shift: in Naive RAG, the mannequin sees the retrieved context as soon as. In Agentic RAG, the mannequin causes concerning the retrieval itself, deciding when to look, what to seek for, and when it has sufficient data to generate a dependable reply.
4 Mechanisms That Make RAG Agentic
The distinction between a naive and agentic pipeline is not a single design selection — it is the buildup of 4 distinct mechanisms, every addressing a selected failure mode that linear retrieval cannot deal with by itself.
Question Routing
Not all questions belong to the identical knowledge supply. A monetary evaluation question is likely to be finest answered by querying a structured SQL database. A coverage query would possibly name for semantic search throughout unstructured paperwork. A request for present occasions would possibly want a reside internet search.
Question routing provides the system the flexibility to determine the place to look earlier than executing the search. The LLM examines the incoming question and selects the suitable instrument or knowledge supply from a predefined registry. This prevents the frequent failure mode of forcing each question by means of a single retrieval mechanism no matter whether or not it matches.
Question Decomposition
Complicated questions virtually at all times comprise a number of sub-questions, and an agentic system handles this by breaking the unique immediate into smaller, independently answerable parts earlier than executing any retrieval in any respect.
Again to the WhatsApp instance: the system would not seek for “WhatsApp EU regulatory insurance policies” as a single phrase. As a substitute, it first asks which firm acquired WhatsApp, retrieves that reply (Meta), after which makes use of that intermediate consequence to assemble a second, extra exact question about Meta’s EU regulatory obligations. Every reply informs the subsequent search, constructing towards a whole response by means of a sequence of focused retrievals quite than a single broad one. This sequential reasoning is exactly what naive pipelines cannot do.
Self-Reflection and Critique
That is probably the most consequential functionality within the agentic toolkit — and the one that almost all clearly separates it from commonplace pipelines. After retrieval, the system would not instantly ahead the outcomes to the technology step. It pauses and evaluates: do these retrieved chunks truly reply the query? Are they related, or did the search floor noise?
If the mannequin determines that the retrieved context is inadequate, contradictory, or off-target, it rewrites the question and initiates a brand new retrieval cross. This evaluation-and-retry loop continues till the system reaches a passable confidence threshold or hits a predefined iteration restrict — which prevents runaway loops from inflating value and latency. The result’s a system that may catch its personal retrieval failures in actual time, quite than silently passing unhealthy context to the generator.
Software Use and Perform Calling
Agentic RAG programs aren’t restricted to querying textual content databases. By perform calling, the LLM can invoke exterior instruments mid-reasoning: a calculator for arithmetic, a reside internet search API for present occasions, a SQL executor for structured knowledge, or a customized inner API for domain-specific lookups. The mannequin decides which instrument is suitable for every sub-task and invokes it as a part of the identical reasoning loop.
This can be a significant enlargement of what a retrieval system can do. Quite than a doc retriever that arms off to a generator, an agentic system turns into a general-purpose reasoning engine — one that may mix retrieved textual content with reside computation, structured database queries, and real-time knowledge in a single coherent response. The obtainable instruments, not the question kind, decide what the system can reply.
Making the Selection: When to Use Which
The choice between Naive RAG and Agentic RAG comes right down to a trade-off between value and functionality.
Naive RAG entails a single embedding operation and one LLM name. Latency is low, prices are predictable, and the system is straightforward to debug. Agentic RAG entails a number of LLM reasoning steps, every of which provides latency and token value. A question that requires three retrieval iterations and two instrument calls will value considerably greater than a single-pass retrieval.
Select Naive RAG when:
- The queries are well-defined and single-hop in nature
- Pace is the first person expectation (consumer-facing chatbots, inner FAQ programs)
- The information base is well-structured and a single semantic search reliably surfaces the suitable data
- Funds constraints make a number of LLM calls per question unsustainable at scale
Select Agentic RAG when:
- Queries require reasoning throughout a number of paperwork or knowledge sources
- The use case calls for excessive accuracy over quick responses (monetary evaluation, authorized analysis, medical literature assessment)
- Customers will ask advanced, open-ended questions that may’t be anticipated at design time
- The system must work together with exterior instruments, APIs, or reside knowledge alongside a static information base
- Incorrect solutions carry important enterprise or reputational threat
For a lot of manufacturing programs, a hybrid method is smart: route easy, high-volume queries by means of a quick naive pipeline, and reserve the agentic loop for queries that the system flags as advanced or high-stakes.
Advisable Studying Assets
For readers who wish to go deeper on RAG architectures and agentic programs, these are strong beginning factors:
- LangChain and LlamaIndex documentation: Each frameworks have intensive guides on constructing naive and agentic RAG pipelines, together with implementations of question routing, question decomposition, and self-reflection loops.
- “RAG Survey” by Gao et al. (2023): A tutorial overview of RAG architectures, protecting naive, superior, and modular variants with empirical comparisons.
- DeepLearning.AI‘s “Constructing and Evaluating Superior RAG” brief course: A sensible, code-first introduction to shifting past primary retrieval pipelines.
- Anthropic and OpenAI perform calling documentation: Important studying for implementing instrument use in agentic programs.
Closing Ideas
The excellence between Naive RAG and Agentic RAG maps onto a broader sample in system design: the distinction between a inflexible pipeline and an adaptive loop.
Naive RAG retrieves. Agentic RAG investigates. To be used circumstances the place a single, well-formed search reliably surfaces the suitable reply, the easier structure is the suitable selection. To be used circumstances involving multi-step reasoning, heterogeneous knowledge sources, or excessive accuracy necessities, the added complexity of an agentic loop pays for itself.
The frameworks to construct these programs are mature, well-documented, and accessible. The appropriate place to begin is solely understanding which drawback you are truly attempting to unravel.
Vinod Chugani is an AI and knowledge science educator who bridges the hole between rising AI applied sciences and sensible utility for working professionals. His focus areas embrace agentic AI, machine studying purposes, and automation workflows. By his work as a technical mentor and teacher, Vinod has supported knowledge professionals by means of ability growth and profession transitions. He brings analytical experience from quantitative finance to his hands-on instructing method. His content material emphasizes actionable methods and frameworks that professionals can apply instantly.