

A spike at 7
A chart has just lately gone viral on X. It asks one easy query, “choose a quantity between 1 and 10”, and compares three sorts of solutions: a real random generator, people, and a big language mannequin. Random is a flat line at 10%, each quantity equally probably. People kind a bumpy hill that peaks at 7. The LLM is a single needle at 7, as if it had by no means heard of some other quantity.
The writer’s caption: that is the least shocking graph on the planet in the event you perceive how gradient descent works. It is half proper, which is essentially the most harmful technique to be proper.
The quick model: gradient descent decides the place the height is, not how sharp it’s. Pretraining copies people, and people love 7, so the height lands on 7, however as a mild hill just like the human one. The needle comes later, from post-training and from the way in which we pattern solutions. The remainder of this piece walks by means of each.
A small observe earlier than we begin: the chart is an artist’s impression. No y-axis, no pattern dimension, no uncertainty. In any mannequin overview, it will value its writer a compulsory, two-hour company coaching on ‘Find out how to Use Seaborn’ whereas all the workforce watches. However, the phenomenon is actual, and additional down we construct our personal chart from precise calculations.
People first: why 7?
People are horrible random quantity mills too. In a YouGov survey, 33% of Britons picked 7, whereas the numbers on the edges (1, 2, 9, 10) have been left nearly empty (YouGov). The impact even has a reputation, the “blue-seven” phenomenon, as a result of once you ask for a color most individuals say blue.
Whenever you ask somebody for a “random” quantity, they do not draw from a uniform distribution. They search for the quantity that feels random. That is a very totally different query:
-
1 and 10 are the sides, so “predictable”.
-
5 is the center, too apparent.
-
Even numbers look tidy, like they’re carrying an ironed shirt.
-
7 is odd, prime, neither center nor edge, and culturally loaded (7 days, 7 wonders, 7 sages). It is the quantity that attire casually so it would not appear to be it tried.
So 7 wins as a result of all of us attempt to be unpredictable in the identical manner. Camus would have discovered this completely cheap.
The half that is proper: what gradient descent really does
Gradient descent explains why the height is at 7. It would not clarify why it is a needle although, and to see why, let’s go and observe the coaching step-by-step.
Step 1: the mannequin has ten dials. For “choose a quantity between 1 and 10”, the mannequin holds one dial per quantity, every saying how probably it thinks that quantity is. Name them collectively they add as much as 100%.
Step 2: coaching measures shock. We present the mannequin actual human solutions, one by one, and ask: how shocked have been you? If it gave 7 a 30% likelihood and a human says 7, it is mildly shocked. If it gave 3 a 5% likelihood and a human says 3, it is very shocked. Shock is measured as : small when q is giant, large when q is close to zero.
Common that shock over every part people say (is how typically people choose ok) and also you get the cross-entropy:
In phrases: for every quantity, how typically people say it, instances how shocked the mannequin is once they do. Coaching desires this as small as attainable.
Step 3: gradient descent turns the dials. After every reply, the mannequin nudges each dial just a little. The scale of the nudge for quantity ok seems to be remarkably easy:
The mannequin’s guess minus the truth. An excessive amount of on 7? Flip it down. Too little on 3? Flip it up. The nudging stops solely when each dial matches how typically people say that quantity. Overshooting is rarely rewarded: likelihood given to 7 past its share is taken from 3, and the mannequin pays for it the subsequent time somebody says 3.
Checkpoint #1: coaching on shock produces a copy, not a caricature or a spike. The human hill comes out as a hill. A well-trained base mannequin ought to say 7 about as typically as individuals do, and base fashions are certainly fairly properly calibrated. The needle wants two extra suspects to be totally defined.
Suspect #1: post-training
Publish-training adjustments the sport from “do not be shocked” to “please the decide”, and that turns the hill right into a taller hill.
Step 4: a brand new aim. A pretrained mannequin is an excellent autocomplete, not but a useful assistant. So it goes by means of a second section, normally RLHF (Reinforcement Studying from Human Suggestions) or a detailed relative of that. People evaluate pairs of solutions and say which one they like; a reward mannequin learns to foretell these preferences; and the LLM is then skilled to provide solutions that rating excessive, whereas a leash retains it from drifting too removed from what it discovered in pretraining. The absolute best mannequin below this rule has a easy form:
Begin from what you already believed, and multiply by a bonus for what the decide likes. The tighter the leash, the smaller the bonuses.
If that appears acquainted, it ought to: it is Bayes’ rule. The pretrained mannequin performs the prior, the decide’s bonus performs the probability, and the post-trained mannequin is the posterior. RLHF is, fairly actually, a Bayesian replace of the bottom mannequin on a extra human style.
Step 5: the wealthy get richer. Raters are inclined to favor the standard, no matter “sounds proper”. However the typical reply is strictly the one the mannequin already finds almost certainly. So the largest bonus goes to the largest dial: 7 grows, every part else shrinks.
If the bonus merely grows with how probably a solution already is, the result’s an influence of the previous distribution:
Checkpoint #2: that’s precisely what reducing the temperature does (see the chart beneath). A desire for the standard, handed by means of RL, is a thermostat turned down completely contained in the mannequin’s weights. This is named mode collapse, and it exhibits up as misplaced calibration: the GPT-4 technical report discovered the bottom mannequin much better calibrated than the ultimate one. Take a second to test it out:
Suspect #2: decoding
Even with no coaching in any respect, the way in which we choose a solution from the mannequin is sufficient to flip a hill right into a needle.
Step 6: the mannequin would not reply, we pattern. The mannequin by no means says “7”. It arms over its ten dials, say 30% for 7, 12% for 3, and so forth, and one thing has to show these into one reply. That one thing is named decoding and the only model is a weighted die: roll it, and seven comes up 30% of the time.
Step 7: the temperature knob. Earlier than rolling, most methods modify the die with a setting known as temperature, T. Every likelihood is raised to the facility 1/T, then every part is rescaled so as to add as much as 100% once more:
-
T = 1: the die because the mannequin constructed it.
-
T < 1: the favorite will get extra favoured. With T = 0.5, the facility is 1/T = 2, so each likelihood will get squared. Take 7 (30%) and three (12%): 7 leads by 30 / 12 = 2.5×. Squared, they grow to be 900 and 144, and the lead turns into 900 / 144 ≈ 6×. Do that for all ten numbers, the squares add as much as 1,544, and dividing by that complete offers the brand new chances: 7 → 900 / 1,544 ≈ 58%, 3 → 144 / 1,544 ≈ 9%.
-
T → 0: all the time choose the favorite (“grasping” decoding). The hill turns into a single bar.
Why does this work, and the place does the identify “temperature” come from? It is the Boltzmann distribution from statistical physics, which I unpacked in Find out how to Decode the Temperature Parameter in LLMs.
Chat apps typically run beneath T = 1, or trim the unlikely solutions altogether (tips known as top-k and top-p), as a result of it makes solutions extra coherent. For “choose a random quantity”, it does the alternative of what you needed.
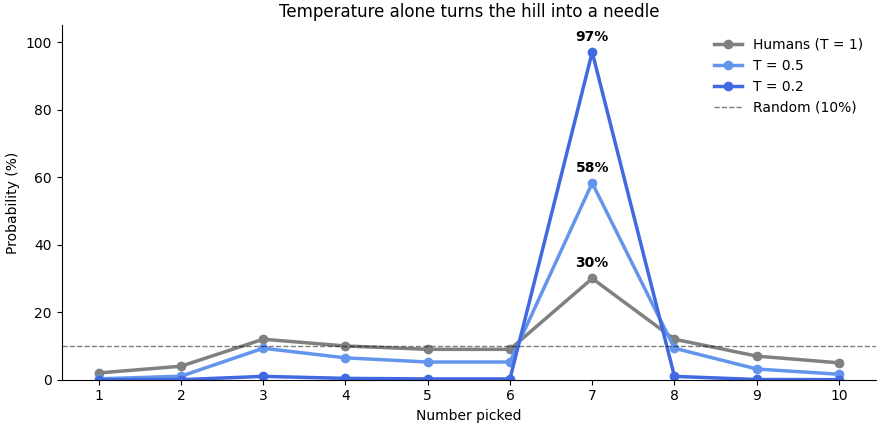
How I made this chart: No LLM was known as and nothing was skilled. We began from an assumed human distribution, with 7 at 30% (surveys report 20–33%), and utilized the temperature system above. The numbers, in %:
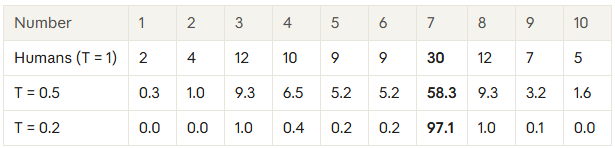
In actual fashions post-training has already narrowed the distribution (Step 5), so even at T = 1 there is not a lot left within the tails. Decoding then finishes the job.
One individual, a thousand instances
The comparability is a bit unfair: the human curve is a inhabitants, the LLM curve is one particular person.
The human distribution comes from many alternative individuals, every with their very own historical past, favorite quantity, and grandmother born on the 4th of the month. The LLM distribution comes from one mannequin requested time and again, every time in a contemporary chat, with no reminiscence.
When you cloned the identical individual a thousand instances and requested them in precisely the identical temper, they’d most likely provide you with one thing a lot spikier too. Heraclitus stated you’ll be able to’t step into the identical river twice; properly, the LLM steps into the identical river a thousand instances, and each time it says “7”.
So, is the tweet proper?
About the place the height is, sure. About its form, no.
|
Query |
Reply |
|---|---|
|
Why is the height at 7? |
Pretraining (with gradient descent) learns from people, and people love 7. |
|
Why a spike and never a hill? |
Principally post-training (mode-seeking optimisation, raters preferring the standard) and decoding. Not simply gradient descent. |
|
Is it the least shocking graph on the planet? |
For anybody who is aware of what post-training and temperature do to a distribution, sure. For everybody else, it is glorious viral tweet materials. |
Find out how to really get a random quantity from an LLM
Depart randomness to one thing constructed for randomness.
-
Ask it to write down and run code (
random.randint(1, 10)). The best manner. -
Ask for the distribution, not a pattern: “Give me 5 attainable solutions with chances”. This typically unlocks way more selection, as a result of the mannequin describes the distribution as a substitute of falling into its mode.
-
Increase the temperature, in case you have API entry. It helps just a little, but it surely will not resurrect tails that post-training already buried.
Epilogue
The LLM is not a foul random quantity generator as a result of it is “dumb”. It is a dangerous one as a result of we skilled it to be excellent at giving the reply we count on. And once you ask “choose a random quantity”, what most of us secretly count on to listen to is 7.