Python builders have had entry to a code profiler for a very long time. cProfile ships with Python, data each operate name and tells you precisely how usually every operate ran. That makes it helpful for scripts and batch jobs whose execution you management.
It’s much less handy for conditions you possibly can’t management. For instance, when an online service is already operating and begins behaving badly. You may’t simply connect cProfile to that operating course of to see what’s occurring. Restarting the service below a profiler could make the issue disappear, and the tracing overhead can change the behaviour you’re making an attempt to measure in any case.
Python 3.15 introduces another choice. The brand new profiling.sampling module, often known as Tachyon, can begin a program itself or connect to a course of that’s already operating. It reads the method externally, so the appliance doesn’t must import a profiling library or restart.
Tachyon may also look at each thread, distinguish CPU work from ready, present which code holds the GIL and mark execution inside native extensions. If a course of seems caught, it might probably print every thread’s present stack with out operating a full profile.
On this article, we’ll attempt every characteristic towards a small HTTP service. Each profiler command has an identical endpoint, so the outcomes are seen and apparent.
Python now has two built-in profilers
Python 3.15 locations its profiling instruments below a brand new bundle:
profiling.tracing is the deterministic profiler beforehand uncovered via cProfile. It data each operate name, return and exception. The ensuing name counts are precise, together with capabilities that end in a couple of microseconds.
profiling.sampling checks this system’s name stacks at common intervals. A operate that seems in lots of samples might be accountable for a big share of the execution time.
These two approaches reply totally different questions.
Sampling doesn’t report each occasion, so its timings are estimates. If a operate accounts for 10% of the samples, it in all probability accounts for roughly 10% of the sampled time. Outcomes can fluctuate barely between runs.
Tracing is precise, however the profiler has to course of each name. That additional work can develop into noticeable in an software that calls many small Python capabilities.
The Python documentation recommends statistical sampling for many investigations and deterministic tracing when precise name counts matter. The present cProfile module stays accessible as an alias for profiling.tracing. The outdated pure-Python profile module is deprecated and is because of be eliminated in Python 3.17.
Organising a dev setting and putting in Python 3.15
Earlier than writing any code, let’s arrange a growth setting to maintain the challenge remoted. I take advantage of the uv instrument for this, however use whichever methodology you recognize greatest.
The model I used for these examples is Python 3.15.0rc1. It isn’t the completed product, however it’s unlikely extra language options will likely be added at this stage. Python 3.15.0 is due in October this 12 months.
If a more moderen 3.15 launch is out there if you learn this, set up that model as an alternative if you’d like.
Preserve this digital setting lively whereas following the remainder of the article. From this level onwards, the python command refers to Python 3.15 with out changing or interfering together with your regular Python set up.
Create a service we will profile
The instance makes use of solely Python’s customary library. This avoids attainable compatibility issues with third-party packages whereas Python 3.15 continues to be a prerelease.
slow_server.py runs a small threaded HTTP server on localhost:8000 and prints its course of ID so you possibly can connect the profiler. Its two endpoints create totally different efficiency issues on objective:
The server has two sorts of labor (endpoints):
-
/report– mixes ready with CPU-heavy Python code. -
/native– performs a protracted calculation in compiled code.
Create a file known as slow_server.py and add these traces to it:
Begin the server:
It prints the tackle and its course of ID, for instance:
Generate site visitors to the server
We have to train every endpoint whereas the profiler is gathering samples, so in a brand new terminal, create the next generate_load.py file.
The primary argument selects the endpoint. The opposite two set the length and variety of staff. For instance, this command would ship site visitors to the server’s /report endpoint for 30 seconds utilizing six threads:
Whereas the server continues to be operating, open a second terminal, activate your Python 3.15 setting, and run the load generator with the command above.
With the slow_server and load generator operating, open a 3rd terminal, activate the Python 3.15 setting, and run the next command.
The -a flag consists of each thread, -d 20 data for 20 seconds, and -o names the output file. Together with each thread issues as a result of ThreadingHTTPServer handles requests outdoors the principle server thread.
The server wasn’t began by the profiler. Tachyon connects to the present course of, collects samples for 20 seconds and disconnects. The server retains operating.
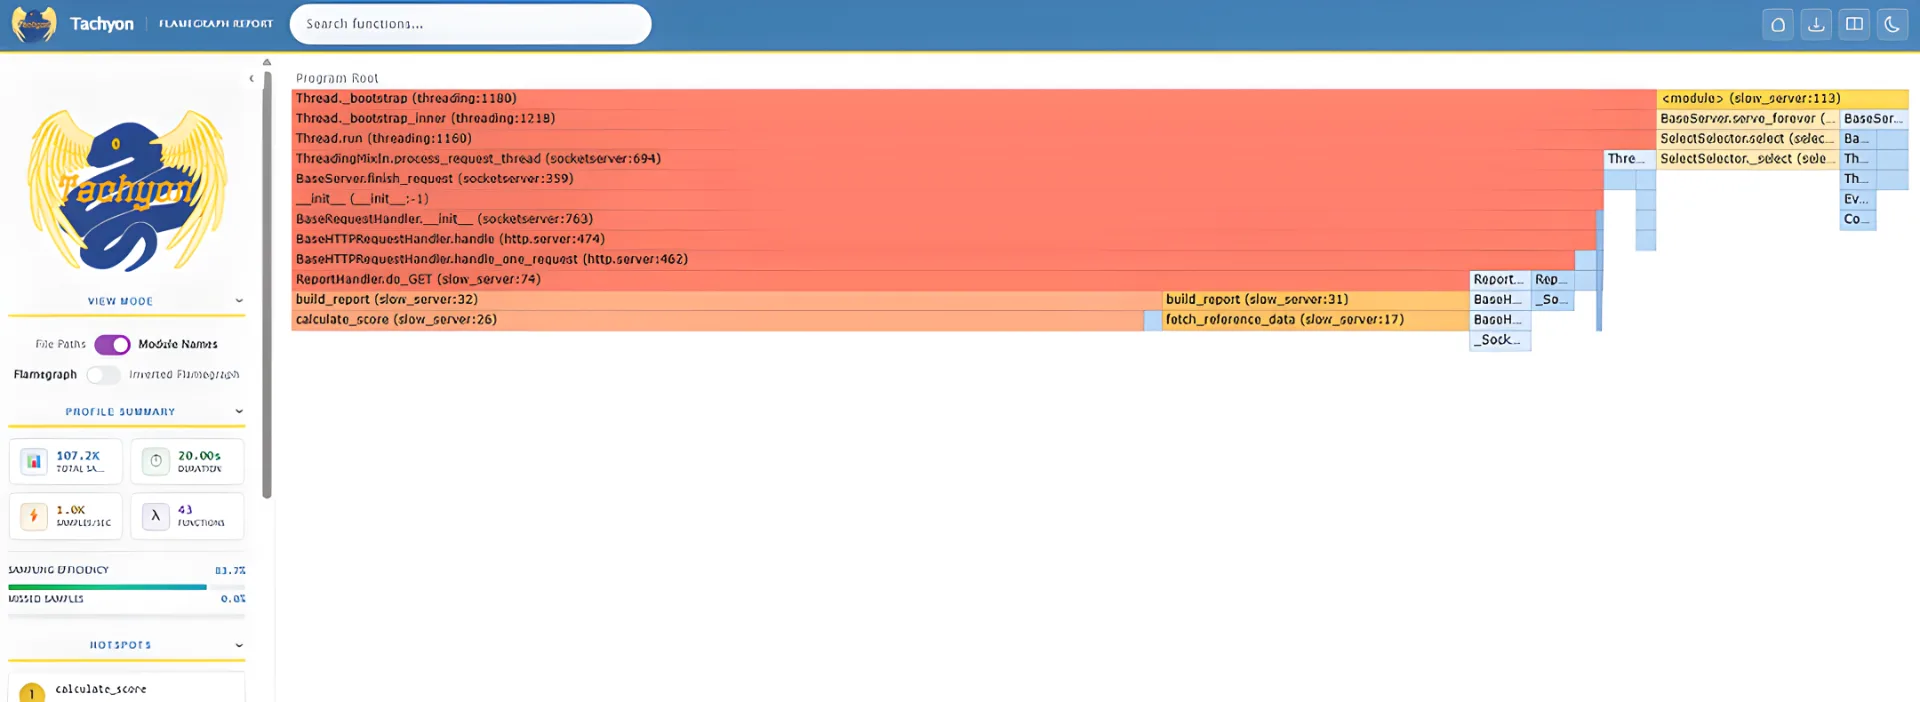
Open report-wall.html in a browser. The generated file is self-contained, so it doesn’t want a separate viewer or web connection. By default it produces a flame graph. Right here’s what mine appeared like.
The containers aren’t organized horizontally by time. The color scale makes hotter and colder frames simpler to identify.
Deciphering flame graphs
In flame graphs, the decision stack runs from high to backside. A field sitting under one other field represents a operate known as by the one above it. The width is the vital half: the broader the field, the extra steadily that operate appeared within the samples and, subsequently, the extra execution time it accounted for.
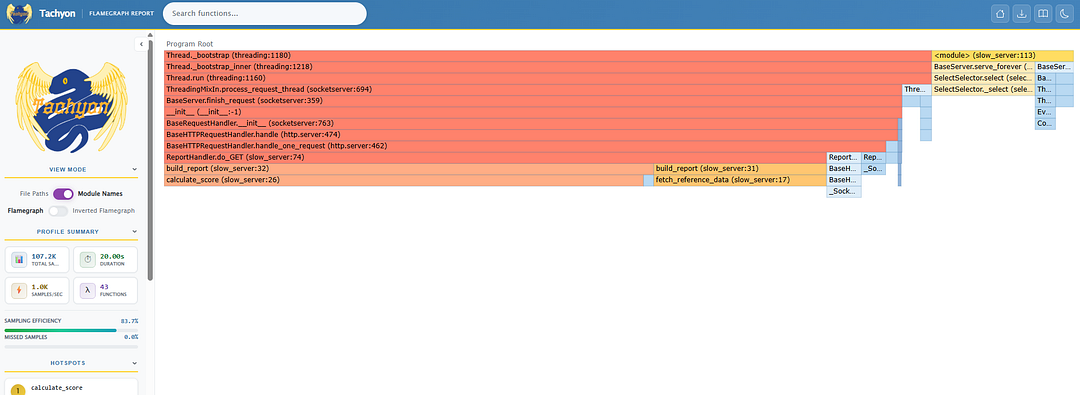
Picture by WriterRight here, the vital name path is:
calculate_score stands out instantly as a result of it’s the widest leaf within the graph. A lot of the request time is subsequently being spent inside that nested Python calculation.
There may be additionally a sizeable block for fetch_reference_data. That operate incorporates time.sleep(0.04), so the profiler nonetheless data these 40 milliseconds despite the fact that the method is ready relatively than actively utilizing the CPU. This occurs as a result of the profile is predicated on wall-clock time.
The group on the best, ending in SelectSelector.choose, is the server’s principal thread ready for an additional connection. That’s regular and isn’t one thing it’s worthwhile to optimise. General, the graph exhibits that /report spends most of its time calculating the rating, with a smaller however seen delay whereas fetching its faux reference information.
Separating ready from computation
The primary profile used Tachyon’s default wall-clock mode. It data no matter a thread is doing when the pattern is taken. That features executing Python, sleeping, ready for I/O and ready for a lock.
That is helpful as a result of customers expertise elapsed time. A sluggish database question nonetheless makes a request sluggish even when the Python course of consumes little CPU whereas it waits.
In our server, fetch_reference_data() sleeps for 40 milliseconds to signify an exterior name. calculate_score() performs repeated calculations. Each ought to seem within the wall-clock profile.
Now gather a CPU-only profile. Begin the load generator once more:
Whereas the load generator is operating, run,
CPU mode discards samples taken whereas a thread is sleeping, blocked or ready for I/O.
Open report-cpu.html and evaluate it with the wall-clock profile.
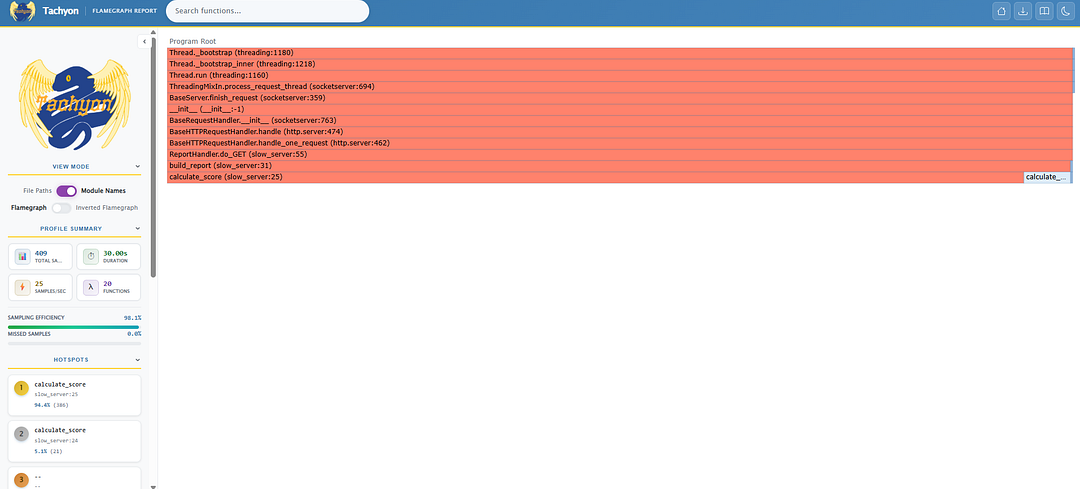
Picture by Writercalculate_score() is now dominating with a 94% HotSpot rating. fetch_reference_data() disappeared as a result of its delay comes from time.sleep(), not CPU work.
If a operate is large within the wall-clock graph however small within the CPU graph, it’s in all probability ready. Rewriting its Python code gained’t take away a database delay, community spherical journey or lock wait.
A operate that seems prominently in each profiles is consuming processor time. That’s the place algorithm adjustments, native libraries or process-based parallelism could assist.
Discovering code that holds the GIL
The server handles requests in a number of threads, however calculate_score() continues to be Python code. On a traditional CPython construct, just one thread can execute Python bytecode at a time.
Run the load generator as earlier than:
Whereas it is operating, gather a GIL profile,
GIL mode retains samples solely whereas a thread holds the International Interpreter Lock. Sleeping threads and most native operations that launch the GIL don’t dominate this view.
Search the ensuing graph – report-gil.html – for calculate_score(). Its nested loops execute Python bytecode and maintain the GIL. A number of employee threads could have requests able to course of, however they’ll’t all execute these loops without delay.
Including extra threads subsequently gained’t make this a part of the service scale in proportion to the thread rely. Potential fixes embody doing much less work, altering the algorithm, transferring the calculation to a course of pool or utilizing a local library that may launch the GIL.
Discover time spent outdoors Python
The /native endpoint is doing one thing barely totally different. It calls hashlib.pbkdf2_hmac() with a intentionally excessive iteration rely, which pushes many of the work into compiled native code relatively than Python itself.
That makes it a helpful take a look at case for the profiler: the decision runs lengthy sufficient to indicate up clearly, despite the fact that Python isn’t doing many of the precise computation.
Begin a smaller load take a look at:
Whereas the load generator continues to be operating, gather a CPU profile with native frames enabled:
Open native.html and seek for run_native_hash. It ought to dominate the profile as a result of Tachyon attributes the time spent in hashlib.pbkdf2_hmac() to its Python caller. With —- native, the report may comprise artificial run_native_hash.
Producing a supply heatmap
A flame graph preserves the decision hierarchy. Generally you already know which operate is dear and need to discover the traces accountable. That’s the place a heatmap might be helpful.
Run the /report load yet one more time:
Accumulate a heatmap whereas the load generator continues to be operating:
The output is a listing relatively than a single HTML file. Open report-heatmap/index.html, then choose slow_server.py.
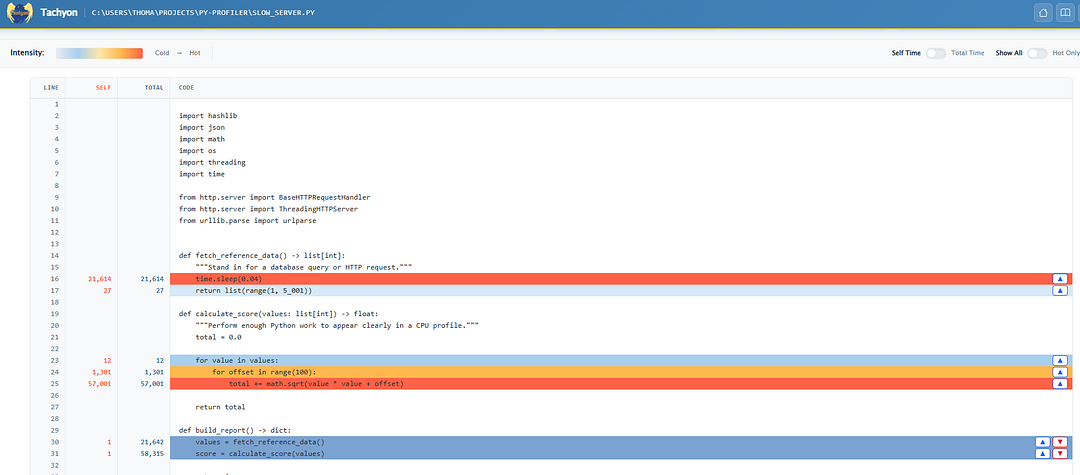
The web page can show both self time or complete time. Self time counts samples attributed on to a line. On this instance, it ought to make the calculation inside calculate_score() stand out. Whole time additionally consists of work carried out by capabilities known as from a line. Change to that view and the calls to fetch_reference_data() and calculate_score() inside build_report() develop into extra helpful, as a result of their totals embody the work performed inside these capabilities.
The color runs from chilly to scorching. A warmer line appeared in additional samples for the chosen view. The figures on the high present the variety of self and cumulative samples, what number of traces have been hit and the file’s share of the entire profile.
If the heatmap comes again virtually empty, the only rationalization is that the server wasn’t doing a lot whereas the profiler was operating. Seeing server.serve_forever() gather samples by itself often means the method was simply sitting there ready for requests.
I’d verify the timing first. Be certain the load take a look at is definitely operating concurrently the profiler, then seize the heatmap once more.
One factor to observe for with Tachyon is the output listing. If report-heatmap already exists, Tachyon gained’t overwrite it. As an alternative, the brand new report could find yourself in a subdirectory corresponding to report-heatmap/heatmap_18472.
If that occurs, open probably the most not too long ago created index.html. I often discover it less complicated to provide every run a contemporary output listing.
The place cProfile stays helpful
Tachyon doesn’t make cProfile out of date.
Sampling can miss very brief capabilities that start and end between two samples. Suppose a parser calls a small conversion operate two million instances. No particular person name lasts lengthy, so the operate could not stand out in a statistical profile.
A deterministic profiler data each name. If it’s worthwhile to confirm {that a} refactoring diminished the decision rely from two million to twenty thousand, tracing is the higher selection.
Python 3.15 permits you to run the deterministic profiler via its new identify:
The acquainted command additionally stays accessible:
Tracing additionally fits brief scripts that end earlier than a sampling profiler can gather sufficient observations.
Don’t confuse profiling with benchmarking. A profiler tells you the place this system spends time. It isn’t the best instrument for deciding whether or not one implementation is quicker than one other.
There’s all the time a little bit of noise in sampling outcomes, so small variations aren’t essentially significant. Tracing has the other downside: it data all the pieces, however the additional instrumentation can sluggish Python code down greater than native code.
If I wished to know whether or not one implementation was 2% sooner than one other, I’d cease profiling and put each variations via the timeit or pyperf utilities. That small a distinction is well misplaced in sampling noise.
Conclusion
cProfile stays helpful if you want precise name counts or need to examine a brief program from starting to finish, however it was by no means designed to reply each efficiency query.
It gained’t assist a lot with a service that has already been operating for some time and instantly turns into sluggish. It will probably additionally miss work occurring in different threads, relying on how it’s used, and tracing each operate name adjustments the efficiency of this system when you are measuring it.
Python 3.15’s sampling profiler covers these instances. It will probably examine the method that’s operating now, present what its threads are doing and separate computation from ready.
Now, simply utilizing the usual library Python 3.15 can look at a reside course of whereas the issue is going on, with out first rewriting or restarting it.
For extra info on profiling in Python 3.15, take a look at the official documentation at,
https://docs.python.org/3.15/library/profiling.html#choosing-a-profiler