JSON is likely one of the commonest codecs for storing and exchanging knowledge in Python purposes. For small recordsdata, Python’s built-in json module works completely nicely:
import json

with open("knowledge.json") as f:
    knowledge = json.load(f)
The issue begins when the file turns into giant.
json.load() parses all the JSON doc and creates the corresponding Python objects in reminiscence earlier than you can begin processing the info. A file that occupies a couple of hundred megabytes on disk can due to this fact require way more reminiscence as soon as transformed into Python dictionaries, lists, strings, and numbers.
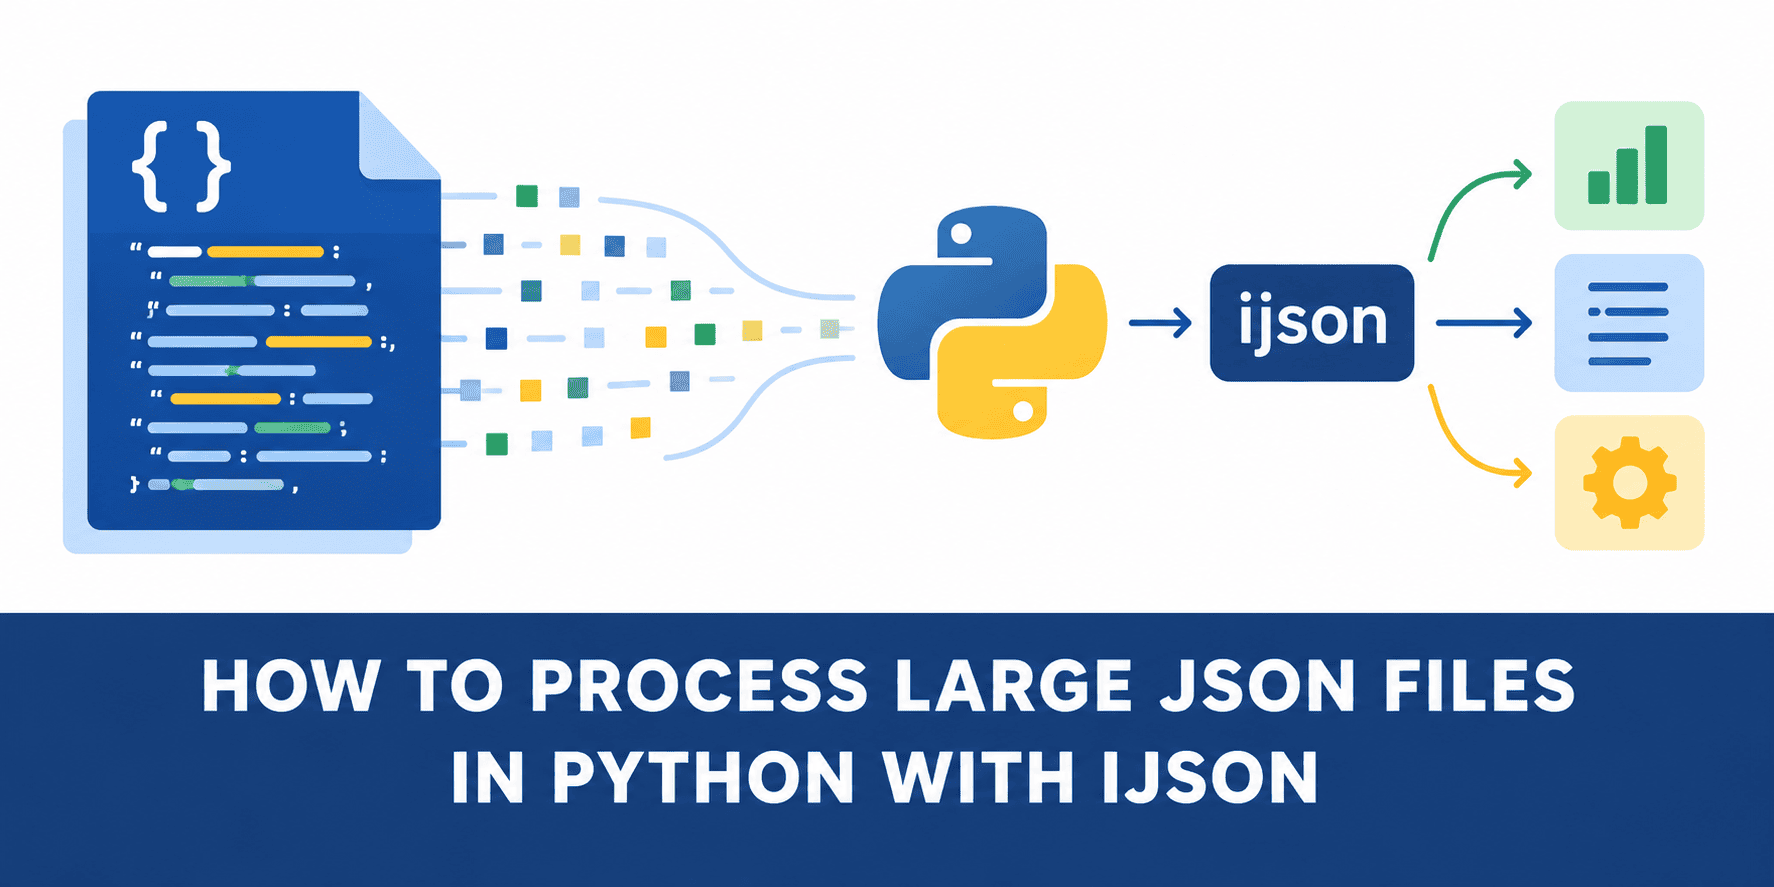
A greater choice for this sort of workload is ijson, an iterative JSON parser that permits you to course of knowledge incrementally. On this tutorial, we’ll use a big JSON file containing San Francisco land-parcel knowledge. We’ll first course of it with json.load(), measure what occurs to reminiscence, after which remedy the identical activity with ijson.
Step 1: Downloading a Massive JSON Dataset
For this experiment, we’ll use the San Francisco Metropolis Heaps dataset. I’m utilizing Google Colab for this text. Obtain it utilizing:
curl -L
https://uncooked.githubusercontent.com/zemirco/sf-city-lots-json/grasp/citylots.json
-o citylots.json
You may examine its dimension with:
ls -lh citylots.jsonThe dataset is 181 MB in dimension, making it giant sufficient to show the distinction between loading and streaming JSON. The file follows the usual GeoJSON FeatureCollection construction. You may examine it utilizing this code:
import json

with open("citylots.json", "r") as f:
    knowledge = json.load(f)

print(knowledge.keys())
knowledge["features"][0]
Output:
dict_keys(['type', 'features'])

{'sort': 'Characteristic',
 'properties': {'MAPBLKLOT': '0001001',
  'BLKLOT': '0001001',
  'BLOCK_NUM': '0001',
  'LOT_NUM': '001',
  'FROM_ST': '0',
  'TO_ST': '0',
  'STREET': 'UNKNOWN',
  'ST_TYPE': None,
  'ODD_EVEN': 'E'},
 'geometry': {'sort': 'Polygon',
  'coordinates': [[[-122.42200352825247, 37.80848009696725, 0.0],
    [-122.42207601332528, 37.808835019815085, 0.0],
    [-122.42110217434863, 37.808803534992904, 0.0],
    [-122.42106256906727, 37.80860105681815, 0.0],
    [-122.42200352825247, 37.80848009696725, 0.0]]]}}
The essential half for us is the options array.
Every characteristic represents one parcel and accommodates two foremost sections:
characteristic
├── properties
│   ├── BLKLOT
│   ├── BLOCK_NUM
│   ├── LOT_NUM
│   └── STREET
│
└── geometry
    └── coordinates
Our evaluation solely wants a couple of values below properties. Nevertheless, if we use the usual JSON parser, Python nonetheless has to load the entire geometry coordinates as nicely.
Step 2: Processing the File With json.load()
Let’s first use the strategy most Python builders would naturally attempt. Create a file referred to as standard_json.py:
import json
import time

begin = time.perf_counter()

with open("citylots.json", "r") as f:
    knowledge = json.load(f)

options = knowledge["features"]

market_count = 0
first_five = []

for characteristic in options:

    properties = characteristic["properties"]

    if properties.get("STREET") == "MARKET":

        market_count += 1

        if len(first_five) < 5:
            first_five.append(
                properties.get("BLKLOT")
            )

elapsed = time.perf_counter() - begin

print(f"Complete parcels: {len(options):,}")
print(f"Market Avenue parcels: {market_count:,}")
print(f"First 5 parcel IDs: {first_five}")
print(f"Time: {elapsed:.2f} seconds")
The code is easy and completely legitimate.
The issue is that this line:
knowledge = json.load(f)Earlier than our loop can course of even one parcel, Python has to:
Learn the whole file
        ↓
Parse each JSON object
        ↓
Create all Python dictionaries
        ↓
Create all lists and coordinates
        ↓
Retailer all the things in reminiscence
        ↓
Begin our evaluation
Which means that despite the fact that we solely want STREET and BLKLOT, we additionally load each polygon and coordinate from the dataset. This is the output that I received:
Complete parcels: 206,560
Market Avenue parcels: 808
First 5 parcel IDs: ['0265003', '0265004', '0265005', '0290012', '0291001']
Time: 4.01 seconds
Step 3: Measuring the Reminiscence Utilization
As a substitute of merely saying that json.load() consumes lots of reminiscence, let’s measure it.
One simple choice is memory-profiler.
Set up it:
pip set up memory-profilerNow change the code inside it with this:
from memory_profiler import profile
import json

@profile
def process_file():

    with open("citylots.json", "r") as f:
        knowledge = json.load(f)

    options = knowledge["features"]

    market_count = 0

    for characteristic in options:

        if (
            characteristic["properties"]
            .get("STREET") == "MARKET"
        ):
            market_count += 1

process_file()
Run:
python -m memory_profiler standard_json.pyThe important thing line to observe is knowledge = json.load(f):
Line #    Mem utilization    Increment  Occurrences   Line Contents
=============================================================
     5     43.4 MiB     43.4 MiB           1   @profile
     6                                         def process_file():
     7
     8    808.9 MiB      0.0 MiB           2       with open("citylots.json", "r") as f:
     9    808.9 MiB    765.5 MiB           1           knowledge = json.load(f)
    10
    11    808.9 MiB      0.0 MiB           1       options = knowledge["features"]
    12
    13    808.9 MiB      0.0 MiB           1       market_count = 0
    14
    15    808.9 MiB      0.0 MiB      206561       for characteristic in options:
    16
    17                                                 if (
    18    808.9 MiB      0.0 MiB      413120               characteristic["properties"]
    19    808.9 MiB      0.0 MiB      206560               .get("STREET") == "MARKET"
    20                                                 ):
    21    808.9 MiB      0.0 MiB         808               market_count += 1
    22
    23    808.9 MiB      0.0 MiB           1       print("Complete parcels:", len(options))
    24    808.9 MiB      0.0 MiB           1       print("Market Avenue parcels:", market_count)
You may see a noticeable enhance in reminiscence consumption at this level.
Why can reminiscence utilization be a lot bigger than the unique JSON file?
As a result of JSON resembling:
{
  "STREET": "MARKET"
}
turns into a number of Python objects:
dictionary
   ↓
Python string key
   ↓
Python string worth
The identical occurs for nested geometry arrays and numeric coordinates.
The file dimension on disk is due to this fact not the identical as its reminiscence footprint as soon as parsed.
This offers us a baseline to check towards ijson.
Step 4: Streaming the JSON File With ijson
Now let’s remedy the identical drawback with out loading the whole doc.
Set up ijson:
pip set up ijsonThe important thing operate we’ll use is:
ijson.gadgets()Our dataset has this hierarchy:
root
│
├── sort
│
└── options
     ├── merchandise
     ├── merchandise
     ├── merchandise
     └── ...
Subsequently, we are able to ask ijson to offer us every characteristic individually:
import ijson

with open("citylots.json", "rb") as f:

    for characteristic in ijson.gadgets(
        f,
        "options.merchandise"
    ):

        print(characteristic)
        break
The prefix:
options.merchandisemeans:
Enter the
optionsarray and return every merchandise inside it.
As a substitute of making one huge record of parcels, ijson provides us information one by one.
Conceptually:
Characteristic 1
   ↓
course of
   ↓
discard

Characteristic 2
   ↓
course of
   ↓
discard

Characteristic 3
   ↓
course of
   ↓
discard
This modifications the reminiscence necessities dramatically.
Step 5: Performing the Identical Evaluation With ijson
Now let’s repeat precisely the identical activity.
Create stream_json.py:
import ijson
import time

begin = time.perf_counter()

complete = 0
market_count = 0
first_five = []

with open("citylots.json", "rb") as f:

    for characteristic in ijson.gadgets(
        f,
        "options.merchandise"
    ):

        complete += 1

        properties = characteristic["properties"]

        if properties.get("STREET") == "MARKET":

            market_count += 1

            if len(first_five) < 5:
                first_five.append(
                    properties.get("BLKLOT")
                )

elapsed = time.perf_counter() - begin

print(f"Complete parcels: {complete:,}")
print(f"Market Avenue parcels: {market_count:,}")
print(f"First 5 parcel IDs: {first_five}")
print(f"Time: {elapsed:.2f} seconds")
Output:
Complete parcels: 206,560
Market Avenue parcels: 808
First 5 parcel IDs: ['0265003', '0265004', '0265005', '0290012', '0291001']
Time: 4.58 seconds
We now not have:
knowledge = json.load(f)or:
options = knowledge["features"]As a substitute, this system processes every characteristic instantly from the parser:
for characteristic in ijson.gadgets(
    f,
    "options.merchandise"
):
At any second, we primarily want reminiscence for:
present characteristic
+
ijson's parser buffer
+
small counters
+
5 saved IDs
We don’t want reminiscence for the whole dataset.
Run the identical reminiscence check:
Output:
Line #    Mem utilization    Increment  Occurrences   Line Contents
=============================================================
     5     43.8 MiB     43.8 MiB           1   @profile
     6                                         def process_file():
     7
     8     43.8 MiB      0.0 MiB           1       complete = 0
     9     43.8 MiB      0.0 MiB           1       market_count = 0
    10
    11     46.1 MiB      0.0 MiB           2       with open("citylots.json", "rb") as f:
    12
    13     46.1 MiB      2.2 MiB      206562           for characteristic in ijson.gadgets(
    14     43.8 MiB      0.0 MiB           1               f,
    15     43.8 MiB      0.0 MiB           1               "options.merchandise"
    16                                                 ):
    17
    18     46.1 MiB      0.0 MiB      206560               complete += 1
    19
    20                                                     if (
    21     46.1 MiB      0.1 MiB      413120                   characteristic["properties"]
    22     46.1 MiB      0.0 MiB      206560                   .get("STREET") == "MARKET"
    23                                                     ):
    24     45.8 MiB      0.0 MiB         808                   market_count += 1
    25
    26
    27     46.1 MiB      0.0 MiB           1       print("Complete parcels:", complete)
    28     46.1 MiB      0.0 MiB           1       print("Market Avenue parcels:", market_count)
Now examine the height reminiscence utilization with the outcome from json.load().
| Method | Enter File | Peak Reminiscence | Processing Mannequin |
|---|---|---|---|
json.load() |
181 MB | 808.9 MiB | Load all the things |
ijson.gadgets() |
181 MB | 46.1 MiB | Stream information |
| Distinction | Identical file | ~762.8 MiB much less reminiscence | Extra environment friendly processing |
The essential habits ought to stay the identical: ijson is primarily helpful due to this extra steady reminiscence footprint.
This does not essentially imply ijson will at all times be quicker. If sufficient RAM is out there, json.load() could generally parse a doc in a short time. The principle benefit of ijson is that reminiscence consumption now not must develop with the scale of the whole JSON doc.
Wrapping Up
Massive JSON recordsdata don’t essentially require giant quantities of reminiscence.
The issue is commonly not the JSON format itself however how we select to course of it.
On this tutorial, we used an actual San Francisco land-parcel dataset of roughly 181 MB.
With Python’s commonplace:
json.load(f)the whole dataset needed to be parsed into Python objects earlier than our evaluation might start.
That included hundreds of nested dictionaries, lists, property values, polygons, and coordinates that our explicit activity didn’t even want.
Utilizing:
ijson.gadgets(
    f,
    "options.merchandise"
)
modified the processing mannequin utterly.
As a substitute of:
load all the things → course ofwe used:
learn → course of → discardThe important thing takeaway is easy:
In case your activity solely requires one file at a time, there may be normally no purpose to load each file without delay.
Kanwal Mehreen is a machine studying engineer and a technical author with a profound ardour for knowledge science and the intersection of AI with medication. She co-authored the book “Maximizing Productiveness with ChatGPT”. As a Google Era Scholar 2022 for APAC, she champions variety and educational excellence. She’s additionally acknowledged as a Teradata Range in Tech Scholar, Mitacs Globalink Analysis Scholar, and Harvard WeCode Scholar. Kanwal is an ardent advocate for change, having based FEMCodes to empower girls in STEM fields.